
Copula Mixed-Membership Stochastic Blockmodel
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 1462-1467.
Abstract
The Mixed-Membership Stochastic Blockmodels (MMSB) is a popular framework for modelling social relationships by fully exploiting each individual node's participation (or membership) in a social network. Despite its powerful representations, MMSB assumes that the membership indicators of each pair of nodes (i.e., people) are distributed independently. However, such an assumption often does not hold in real-life social networks, in which certain known groups of people may correlate with each other in terms of factors such as their membership categories. To expand MMSB's ability to model such dependent relationships, a new framework - a Copula Mixed-Membership Stochastic Blockmodel - is introduced in this paper for modeling intra-group correlations, namely an individual Copula function jointly models the membership pairs of those nodes within the group of interest. This framework enables various Copula functions to be used on demand, while maintaining the membership indicator's marginal distribution needed for modelling membership indicators with other nodes outside of the group of interest. Sampling algorithms for both the finite and infinite number of groups are also detailed. Our experimental results show its superior performance in capturing group interactions when compared with the baseline models on both synthetic and real world datasets.
- [Airoldi et al., 2008] Airoldi, E., Blei, D., Fienberg, S., and Xing, E. (2008). Mixed-Membership Stochastic Block- models. The Journal of Machine Learning Research, 9:1981-2014.
- [Eagle and (Sandy) Pentland, 2006] Eagle, N. and (Sandy) Pentland, A. (2006). Reality mining: sens- ing complex social systems. Personal Ubiquitous Comput., 10(4):255-268.
- [Fan et al., 2015] Fan, X., Cao, L., and Xu, R. Y. (2015). Dynamic Infinite Mixed-Membership Stochastic Block- model. Neural Networks and Learning Systems, IEEE Transactions on, 26(9):2072-2085.
- [Fan et al., 2016a] Fan, X., Li, B., Wang, Y., Wang, Y., and Chen, F. (2016a). The Ostomachion Process. In AAAI Conference on Artificial Intelligence.
- [Fan et al., 2016b] Fan, X., Xu, R. Y., Cao, L., and Song, Y. (2016b). Learning nonparametric relational models by conjugately incorporating node information in a network. IEEE Transactions on Cybernetics, PP(99):1-11.
- [Fortunato, 2010] Fortunato, S. (2010). Community detec- tion in graphs. Physics Reports, 486(3):75-174.
- [Fox et al., 2008] Fox, E. B., Sudderth, E. B., Jordan, M. I., and Willsky, A. S. (2008). An hdp-hmm for systems with state persistence. In Proceedings of the 25th International Conference on Machine Learning (ICML), pages 312-319, New York, NY, USA. ACM.
- [Girvan and Newman, 2002] Girvan, M. and Newman, M. (2002). Community structure in social and biological net- works. Proceedings of the National Academy of Sciences, 99(12):7821-7826.
- [Kemp et al., 2006] Kemp, C., Tenenbaum, J. B., Griffiths, T. L., Yamada, T., and Ueda, N. (2006). Learning systems of concepts with an infinite relational model. In Proceed- ings of the 21st AAAI Conference on Artificial Intelligence (AAAI), volume 3, pages 381-388.
- [Kim et al., 2012] Kim, D. I., Hughes, M., and Sudderth, E. B. (2012). The nonparametric metadata dependent re- lational model. In Langford, J. and Pineau, J., editors, Proceedings of the 29th International Conference on Ma- chine Learning (ICML), pages 1559-1566, New York, NY, USA. ACM.
- [Koutsourelakis and Eliassi-Rad, 2008] Koutsourelakis, P. and Eliassi-Rad, T. (2008). Finding mixed-memberships in social networks. In Proceedings of the 2008 AAAI spring symposium on social information processing, pages 48-53.
- [Lazega, 2001] Lazega, E. (2001). The collegial phe- nomenon: The social mechanisms of cooperation among peers in a corporate law partnership. Oxford University Press on Demand.
- [Li et al., 2009] Li, B., Yang, Q., and Xue, X. (2009). Trans- fer learning for collaborative filtering via a rating-matrix generative model. In Proceedings of the 26th Annual Inter- national Conference on Machine Learning (ICML), pages 617-624.
- [Liu, 1994] Liu, J. S. (1994). The collapsed gibbs sampler in bayesian computations with applications to a gene regula- tion problem. Journal of the American Statistical Associ- ation, 89(427):958-966.
- [McNeil and Nešlehová, 2009] McNeil, A. J. and Nešlehová, J. (2009). Multivariate archimedean cop- ulas, d-monotone functions and l 1 -norm symmetric distributions. The Annals of Statistics, pages 3059-3097.
- [Miller et al., 2009] Miller, K., Griffiths, T., and Jordan, M. (2009). Nonparametric latent feature models for link pre- diction. Advances in Neural Information Processing Sys- tems, 22:1276-1284.
- [Nelsen, 2006] Nelsen, R. (2006). An introduction to copu- las. Springer.
- [Nowicki and Snijders, 2001] Nowicki, K. and Snijders, T. A. B. (2001). Estimation and prediction for stochastic blockstructures. Journal of the American Statistical As- sociation, 96(455):1077-1087.
- [Palla et al., 2012] Palla, K., Ghahramani, Z., and Knowles, D. A. (2012). An infinite latent attribute model for network data. In Langford, J. and Pineau, J., editors, Proceedings of the 29th International Conference on Machine Learning (ICML), pages 1607-1614. ACM, New York, NY, USA.
- [Schwarz, 1978] Schwarz, G. (1978). Estimating the dimen- sion of a model. The Annals of Statistics, 6(2):461-464.
- [Sethuraman, 1991] Sethuraman, J. (1991). A constructive definition of dirichlet priors. Technical report, DTIC Doc- ument.
- [Tang and Liu, 2010] Tang, L. and Liu, H. (2010). Commu- nity detection and mining in social media. Synthesis Lec- tures on Data Mining and Knowledge Discovery, 2(1):1- 137.
- [Teh et al., 2006] Teh, Y. W., Jordan, M. I., Beal, M. J., and Blei, D. M. (2006). Hierarchical dirichlet pro- cesses. Journal of the American Statistical Association, 101(476):1566-1581.
- [Wang et al., 2015] Wang, Y., Li, B., Wang, Y., and Chen, F. (2015). Metadata Dependent Mondrian processes. In Pro- ceedings of the 32nd International Conference on Machine Learning (ICML), pages 1339-1347.
- [Xing et al., 2010] Xing, E., Fu, W., and Song, L. (2010). A state-space mixed membership blockmodel for dynamic network tomography. The Annals of Applied Statistics, 4(2):535-566.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Community modeling is an important but challenging topic which has seen applications in various settings including social-media recommendation [Tang and Liu, 2010][Li et al., 2009], customer partitioning [Wang et al., 2015], discovering social networks [Fan et al., 2015][Fan et al., 2016b], and partitioning protein-protein interaction networks [Girvan and Newman, 2002][Fortunato, 2010]. Quite a few models have been proposed in the last few years to address these problems; some earlier examples include stochastic blockmodel [Nowicki and Snijders, 2001], and its infinite community case - infinite relational model (IRM) [Kemp et al., 2006], both assume that each node has one latent variable to directly indicate its community membership, dictated by a single distribution of communities. Their aim is to partition a network of nodes into different communities based on the pair-wise, directional binary observations.
A typical need and challenge in community modeling is to capture the complex interactions amongst the nodes in different applications. Accordingly, several variants of IRM were proposed, including the mixed membership stochastic blockmodel (MMSB) [Airoldi et al., 2008], in which multiple roles (membership indicators) can possibly be played by one node. Each node has its own "membership distribution", and its relation with all other nodes is generated from it. For any two nodes, having determined their corresponding membership indicator pair, their (directional) interactions are generated from a so-called, "role-compatibility matrix" with its row and column indexed by this pair. One mentionable development of MMSB is the nonparametric metadata dependent relational model (NMDR) [Kim et al., 2012], which modifies MMSB by incorporating each node's metadata information into the membership distribution.
However, all of the MMSB-typed models make the assumption that, for each relation between two nodes, their corresponding membership indicator pairs were determined independently. This may limit the way membership indicators can be distributed. In fact, under many social network settings, certain known group members may have higher correlated interactions towards the ones within the same group. For instance, in a company, IT support team members tend to co-interact with each other more than with employees of other departments. Another example is that teenagers may have similar "likes" or "dislikes" on certain topics, compared with the views they may hold towards people of other age groups. MMSB-typed models overlook such interactions within a group and thus cannot fully capture the intrinsic interactions within a network.
In reality, within a social networking context, it is important to incorporate group member interactions (here called intra-group correlations) into the modeling of membership indicators. After introducing these intra-group correlations, it is important that at the same time, we do not alter membership indicators' distributions themselves, so that their interactions to people outside of the known subgroups are unaffected.
Accordingly, in this paper, a Copula function [Nelsen, 2006][McNeil and Neˇslehov´a, 2009] is introduced to MMSB, forming a copula Mixed-Membership Stochastic Blockmodels (cMMSB), for modeling the intra-group correlations. With cMMSB, we can flexibly apply various Copula functions towards different subsets of pairs of nodes while maintaining the original marginal distribution of each of the membership indicators. We develop ways in which a bivariate Copula can be used for two distributions of indicators, enjoying infinitely possible values. Under the framework, we can incorporate different choices of Copula functions to suit the need of the applications. With different Copula functions imposed on the different groups of nodes, each of the Copula function's parameters will be updated in accordance with the data. What is more, we also give two analytical solutions to calculate the conditional marginal density to the two indicator variables, which plays a crucial role in our likelihood calculation and also creates a new way of calculating a deterministic relationship between multiple variables in a graphical model.
2 Preliminary knowledge on CopulaModel
Here we describe very briefly a bivariate copula function C(u↪ v), which is a Cumulative Distribution Function over the interval [0↪ 1] ⇥ [0↪ 1] with the uniform marginal distribution [Nelsen, 2006]. This correlation representation is extremely useful since we have the following theorem:
THEOREM 1. Sklar's Theorem: Let X and Y be random variables with distribution functions F and G respectively and joint distribution function H. Then there exists a Copula C such that for all (x↪ y) 2 R⇥R:
C is unique if F and G are continuous, then the joint probability density function is:
Here c(u↪ v) = @ 2C(u↪ v)◁@u@v is noted for the copula density function.
Sklar's theorem ensures the uniqueness of copula function C(F(x)↪ G(y)) once the joint distribution h(x↪ y) and its two marginal distributions f(x) and g(y) are known. The modification of a Copula function does not change the marginal distributions, which serves the purpose of this paper.
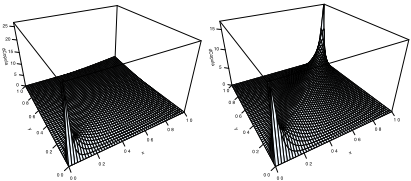
The popularity of copula models from various applications also meant the availability of different choices of copula functions to suit various applications. The commonly used copula function includes Gaussian Copula, Archimedean Copula (Clayton, Gumbel, Frank, etc.). We have visualized the probability density function for Clayton Copula and Gaussian Copula in Figure 1. For a comprehensive survey of copula functions, please refer to [Nelsen, 2006].
3 CopulaMixedMembership Stochastic Blockmodel (cMMSB)
3.1 Notations
The notations and their meanings to be used in this paper are presented in Table 1.
| Table 1: Notations for cMMSB | |
| n | number of nodes |
| K | number of discovered communities |
| eij | directional, binary interactions |
| γ↪ ↵ | concentration parameters for HDP |
| sij | sender's (from i to j) membership indicator |
| rij | receiver's (from j to i) membership indicator |
| ⇡i | mixed-membership distribution for node i, it generates si1↪ · · · ↪ sin↪ r1i↪ · · · ↪ rni |
| ⇡ik | the "significance" of community k for node i |
| B | role-compatibility matrix |
| Bk↪l | compatibilities between communities k and l |
| mk↪l | number of links from community k to l i.e. mik = #¶ij : sij = k↪ rij = l▷♦ |
| m1k↪l | part of mk↪l where the corresponding eij = 1 i.e. m1k↪l = Psij=k↪rij=l eij |
| m0k↪l | part of mk↪l where the corresponding eij = 0 m0k↪l = mk↪l -m1k↪l |
| Nik | number of times that a node i has participated in community k (either sending or receiving) i.e. Nik =#¶j : sij = k♦+#¶j : rji = k♦ |
| ✓ | parameter associated with any Copula function |
3.2 Graphical Model Description
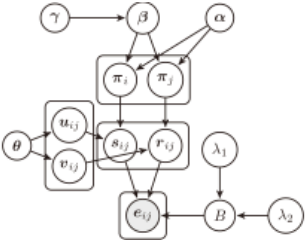
The generative process of graphical modeling is illustrated below:
C2: ¶⇡i♦ni=1 ⇠ DP(↵ · β)
Here gij = 1 in C3 denotes that the node pair (i↪ j) belongs to the sub-group of interest, i.e., sij↪ rij are implicitly correlated, while gij = 0 means (sij↪ rij) are modelled using traditional MMSB. In C4, ⇧-1 i (uij) = ¶mink : Pkq=1 ⇡iq ≥ uij♦ denotes the interval of ⇡i that uij belongs into, and similar notation is applied to ⇧-1 j (vij) = ¶mink : Pkq=1 ⇡jq ≥ vij ♦.
For a simplified illustration, we divide the generative model into three sub-models: (1) "mixed membership distribution modelling", (2) "copula incorporated membership indicator pair" and (3) "binary observation modelling", with their details elaborated in the following sections.
Mixed Membership Distribution Modeling
C1-C2 are for the generation of each node's mixed membership distribution. The number of communities, i.e., k is an important factor in mixed membership distribution models. Therefore, we consider two possibilities here. The first is to use a fixed k. As the graphical model in Fig. 2 shows, for all the mixed-membership distributions ¶⇡i♦ni=1 , there is a common parent node β, where β typically has a "noninformative" symmetric Dirichlet prior, i.e., (β1↪ ▷ ▷ ▷ ↪ βk) ⇠ Dir(γ↪ ▷ ▷ ▷ ↪ γ) [Airoldi et al., 2008]. The appropriate choice of k is determined by the model selection method, such as the BIC criterion [Schwarz, 1978], which is commonly used in [Airoldi et al., 2008][Xing et al., 2010][Fan et al., 2016a].
The second solution is applicable for the uncertain number of communities, which is often the case under many social network settings. The usual approach is to use the Hierarchical Dirichlet Process (HDP) [Teh et al., 2006] prior with β distributed from a GEM(γ), i.e., β is obtained via a stickbreaking construction [Sethuraman, 1991] with each of its components βk = uk Qk-1 l=1 (1 - ul)↪ ul ⇠ Beta(1↪ γ).
After obtaining their parent's node β, we can sample our mixed-membership distribution ¶⇡i♦ independently from [Airoldi et al., 2008][Koutsourelakis and Eliassi-Rad, 2008]: ⇡i ⇠ ⇢ Dir(↵ · β)↪ fixed k; DP(↵ · β)↪ uncertain k▷ For the notational clarity, we concentrate our discussion on the uncertain k case without delicately mentioning its finite counterpart, as the fi-
nite k case can be trivially derived.
Copula Incorporated Membership Indicator Pair
Our main work of c-MMSB is displayed in phases C3-C4. We consider two cases in this paper for the intra-group correlation modeling: full correlation and partial correlation.
Full correlation: i.e., intra-group correlation for all the nodes. We assume each pair of nodes, i.e., all relations of the entire population are using the same Copula function. As we will see in the experimental section that, flexible modelling can still be achieved under this assumption, as parameters of a Copula can vary to support various form of relations.
Partial correlation: i.e., intra-group correlation are applied to only a subset of the nodes. With a definition of one subgroup, we use the Copula function on this specific subgroup and the others remain unchanged.
For traditional MMSB, the corresponding membership indicators within one pair (sij↪ rij) are independently sampled from their membership distributions, i.e., sij ⇠ ⇡i↪ rij ⇠ ⇡j . Using the definition of ¶⇧-1 i (·)♦ni=1 from Section 3.2, this is equivalently expressed as:
As discussed in the introduction, we are motivated by examples within social network settings, in which membership indicators from a node may well be correlated with other membership indicators in an intra-group point of view. People's interactions with each other within the group may more likely (or less likely) belong to the same category, i.e., (sij↪ rij) has higher (or lower) density in some regions of the discrete space (1↪ 2↪ ▷ ▷ ▷ ↪1)2 , which may not be well described by using only the two independent marginal distributions.
We propose a general framework by employing a Copula function to depict the correlation within the membership indicator pair. This is accomplished by the joint sampling of uniform variables (uij↪ vij) (in Eq. (3).) from the Copula function, instead of from two independent uniform distributions. More precisely, the membership indicator pair is obtained using:
Using various Copula priors over the pair (uij↪ vij), we are able to more appropriately express the way in which the membership indicator pair ¶sij↪ rij♦ is distributed, given the different scenarios we are facing. Taking the Gumbel Copula (with larger parameter values) [Nelsen, 2006] as an instance, for certain membership indicator pairs (gij = 1), it generates (uij↪ vij) values that more likely have positive correlation, i.e., within [0↪ 1]2 space, which promotes sij = rij . Also, the Gaussian Copula (✓ = -1) encourages the (sij↪ rij) pair to be different.
Binary Observation Modeling
C5-C6 model the binary observation, which directly follows the previous work [Nowicki and Snijders, 2001][Kemp et al., 2006] etc. Due to the beta-bernoulli conjugacy, B can be marginalized out and the likelihood of binary observation becomes as follows:
here beta(λ1↪ λ2) denotes the beta function with parameters λ1 and λ2, m1k↪l and m0k↪l are defined in Table 1.
4 Inference &Further Discussion
Let K be the discovered number of communities, a formal and concise representation of Eq. (4), i.e. the probability of
(sij↪ rij), is:
Unfortunately, we cannot bring Pr(sij↪ rij) to an analytical form without any integrals present. However, with some mathematical design, we found that, conditioning on the explicit sample of either (uij↪ vij) or (⇡i↪ ⇡j), it is possible to obtain a marginalised conditional density in which sij↪ rij is conditioned on either (uij↪ vij) or (⇡i↪ ⇡j), but not both. Additionally, having a set of variables "collapsed" from the Gibbs sampling, it results in a faster mixing on Markov chains [Liu, 1994]. Therefore, two corresponding inference schemes are needed. To be more concentrated, we present the key parts of these two inference algorithms here (the rest follows the standard procedures as in [Fox et al., 2008]), and name them Marginal conditional on ⇡ only method and the Marginal conditional on u↪ v only respectively:
4.1 Marginal Conditional on ⇡ only: cMMSB⇡
In the Marginal conditional on ⇡ only (cMMSB⇡ for short) method, the variables of interest include ¶⇡i♦↪ ¶sij↪ rij♦↪ β. As mentioned before, we describe the formulation using the infinite communities (uncertain k) case only, its counterpart in the finite communities (fixed k) case can be trivially derived.
Sampling ⇡i
When a Copula is introduced, p(⇡i) and Pr(sij♣⇡i) are no longer a conjugate pair. Therefore, we resort to the use of Metropolis-Hastings (M-H) Sampling in each (⌧)-th MCMC iteration.
For each node i, ⇡i's posterior distribution is formed as Eq. (7), where psijrij ij (⇡i↪ ⇡j) is defined in Eq. (4).
The Corresponding proposal distribution of ⇡i for the above M-H is a posterior Dirichlet distribution in the form of (i.e., ⇡i's posterior distribution under the MMSB framework):
Then the acceptance ratio becomes:
Sampling sij and rij
As eij is dependent on both ¶sij↪ rij♦, a joint sampling of ¶sij↪ rij♦ is implemented as:
On the likelihood, we have
On the first term of the r.h.s. in Eq. (11), we define pkl ij (⇡i↪ ⇡j) ⌘ Pr(sij = k↪ rij = l♣⇡i↪ ⇡j↪ ✓)↪ 8gij = 1, and let C(uij↪ vij♣✓) be the chosen Copula cumulative distribution function (c.d.f.) with parameter ✓. Given the explicit values of ⇡i↪ ⇡j , we can integrate over all uij ↪ vij to compute the probability mass of the indicator pair (sij = k↪ rij = l)↪ k↪ l 2 ¶1↪ · · · ↪K +1♦:
Since ¶⇡i♦ni=1 are piecewise functions, we can easily calculate the probability mass in this "rectangular" area. In other cases of ¶gij = 0♦, i.e., interaction data eij falls outside of the correlated relation group, we have pkl ij (⇡i↪ ⇡j ) = ⇡ik⇡jl.
It is noted that, using the properties of a Copula function, the marginal distributions of Pr(sij = k↪ rij = l♣⇡i↪ ⇡j↪ ✓) remain ⇡i and ⇡j respectively, which becomes that of:
4.2 Marginal Conditional on u and v only: cMMSBuv
In Marginal conditional on u↪ v only method ( cMMSBuv for short), the variables of interest include ¶uij ↪ vij♦↪ ¶sij ↪ rij♦↪ β, and an auxiliary variable m.
Sampling uij and vij
We have used the M-H Sampling for (uij↪ vij)↪ 8i↪ j 2 ¶1↪ ▷ ▷ ▷ ↪ n♦, due to the nonconjugacy issue. The Copula function is used as its proposal, and therefore, its corresponding acceptance ratio becomes that of:
Here hki ↪ ˆhki 's definitions are the same as in Eq. (7), assuming sij = k↪ rij = l.
Sampling sij and rij
An alternative "collapsed" sampling method is to integrate over ¶⇡i♦ni=1 while we explicitly sample the values of ¶(uij ↪ vij )♦i↪j .
Similar as Eq. (11), we obtain:
From Eq. (4), given ¶(uij↪ vij)♦i↪j's values, the probabilities sij = k and rij = l can be computed independently. The Copula function leaves marginal distributions of sij and rij invariant, which remains the same as the classical MMSB, i.e., ⇡i♣↵↪ β↪ ¶N -ij ik ♦Kk=1 ⇠ Dir(↵β1 + N -ij i1 ↪ · · · ↪ ↵βK + N -ij iK ↪ ↵βK+1). Therefore, having the knowledge of F(⇡i♣↵↪ β↪ ¶N -ij ik ♦Kk=1 ), given uij, our calculation of Pr(sij = k) is equal to computing the probability of uij falling in ⇡i's kth interval, i.e. Pr(Pk-1 d=1 ⇡id uij < Pkd=1 ⇡id) (similar case with vij to ⇡jl). This can be obtained from the fact that the set ¶uij 2 [0↪ 1]♣ Pk-1 d=1 ⇡id uij♦ can be decomposed into two disjoint sets:
where Pkd=1 ⇡id ⇠ Beta(Pkd=1 ↵βd +Nid↪ PK+1 d=k+1 ↵βd + Nid). (A similar result was also found in page 10 of [Teh et al., 2006]). Therefore, we have:
Here hki = Pkd=1 ↵βd + Nid↪ ˆhki = PK+1 d=k+1 ↵βd + Nid; Iu(a↪ b) denotes the Beta c.d.f. value with parameter a↪ b on u. The existence and non-negativity of Iuij (uk-1↪ ˆuk-1) - Iuij (uk↪ ˆuk) is guaranteed by the fact that ¶uij 2 [0↪ 1]♣ Pkd=1 ⇡id uij♦ ✓ ¶uij 2 [0↪ 1]♣ Pk-1 d=1 ⇡id uij♦ on the same ⇡i.
4.3 Computational Complexity Analysis
We estimate the computational complexity for each graphical model and present the result in Table 2. Compared to the classical models (especially the MMSB), our cMMSB⇡ involves an additional O(Kn) term which refers to the sampling of the mixed membership distributions. Note that the computational time varies for different Copulas. cMMSBuv requires an extra O(n2 ) term for the u↪ v's sampling for each membership indicator. Each operation requires a Beta c.d.f. in a tractable form. In the experimental part, we have observed that our model runs slower (in a linear way) than the original MMSB. The reason might be the additional calculation of the Copula function or the Beta c.d.f.
| Models | Computational Complexity |
|---|---|
| IRM | lO(K2n) [Palla et al., 2012] |
| LFRM | O(K2n2 ) [Palla et al., 2012] |
| MMSB | O(Kn2 ) [Kim et al., 2012] |
| cMMSB⇡ | O(Kn2 +Kn) = O(Kn2 ) |
| cMMSBuv | +n2 ) = ) |
cMMSBuv O(Kn2 +n2 ) = O(Kn2 )
5 Experiments
Here, our cMMSB's performance is compared with the classical Mixed-Membership Stochastic Blockmodels (MMSB)- type methods, including the original MMSB [Airoldi et al., 2008] and the infinite mixed-membership model (iMMM) [Koutsourelakis and Eliassi-Rad, 2008]. Additionally, we also compare it with other non-MMSB approaches including the infinite relational model (IRM) [Kemp et al., 2006], the latent feature relational model (LFRM) [Miller et al., 2009] and the nonparametric metadata dependent relational model (NMDR) [Kim et al., 2012].
We independently implement the above benchmark algorithms to the best of our understanding. In order to provide a common ground for all comparisons, we make the following small variations to these algorithms: (1) In iMMM, instead of having an individual ↵i value for each ⇡i as used in the original work, we use a common ↵ value for all the mixed-membership distributions ¶⇡i♦ni=1 ; (2) In LFRM [Miller et al., 2009]'s implementation, we do not incorporate the metadata information into the interaction data's generation, but use only the binary interaction information.
5.1 Real-world Datasets for Link Prediction
We analyse three real-world datasets: the NIPS Coauthorship dataset, the MIT Reality Mining dataset [Eagle and (Sandy) Pentland, 2006] and the Lazega-lawfirm dataset [Lazega, 2001].
Table 3: Model Performance (Mean ⌥ Standard Deviation) on Real-world Datasets.
cMMSBuv 0▷0276⌥0▷0043
| Dataset | Train error | Test error | Test log likelihood | AUC | |
|---|---|---|---|---|---|
| NIPS co-author | IRM LFRM MMSB iMMM cMMSB⇡ cMMSBuv | 0▷0317⌥0▷0004 0▷0473⌥0▷0794 0▷0132⌥0▷0042 0▷0061⌥0▷0019 0▷0066⌥0▷0038 0▷0097⌥0▷0047 | 0▷0423⌥0▷0014 0▷0540⌥0▷0735 0▷0301⌥0▷0064 0▷0253⌥0▷0035 0▷0231⌥0▷0043 | -135▷0467⌥7▷3816 -105▷2166⌥179▷5505 -86▷2134⌥10▷1258 -83▷4264⌥9▷4293 -83▷4261⌥9▷4280 -83▷4257⌥9▷4292 | 0▷8901 ⌥ 0▷0162 0▷9348⌥0▷1667 0▷9524 ⌥ 0▷0215 0▷9574 ⌥ 0▷0155 0▷9569 ⌥ 0▷0159 0▷9581⌥0▷0153 |
| MIT reality | IRM LFRM MMSB iMMM NMDR cMMSB⇡ cMMSBuv | 0▷0627⌥0▷0002 0▷0397⌥0▷0017 0▷0263⌥0▷0105 0▷0297⌥0▷0055 0▷0386⌥0▷0040 0▷0246⌥0▷0016 | 0▷0240⌥0▷0065 0▷0665⌥0▷0004 0▷0629⌥0▷0037 0▷0716⌥0▷0043 0▷0625⌥0▷0015 0▷0668⌥0▷0013 0▷0489⌥0▷0016 | -133▷8037⌥1▷1269 -143▷6067⌥10▷0592 -129▷4354⌥7▷6549 -126▷7876⌥3▷4774 -139▷5227⌥2▷9371 -125▷3876⌥3▷2689 | 0▷8261 ⌥ 0▷0047 0▷8529 ⌥ 0▷0179 0▷8561 ⌥ 0▷0176 0▷8617 ⌥ 0▷0124 0▷8569 ⌥ 0▷0138 0▷8794⌥0▷0159 |
| Lazega lawfirm | IRM LFRM MMSB iMMM NMDR cMMSB⇡ cMMSBuv | 0▷0283⌥0▷0035 0▷0987⌥0▷0003 0▷0566⌥0▷0024 0▷0391⌥0▷0071 0▷0487⌥0▷0068 0▷0640⌥0▷0055 0▷0246⌥0▷0050 | 0▷0438⌥0▷0015 0▷1046⌥0▷0012 0▷1051⌥0▷0064 0▷0913⌥0▷0030 0▷1096⌥0▷0026 0▷1133⌥0▷0018 0▷1023⌥0▷0056 | -123▷3876⌥3▷1254 -201▷7912⌥3▷3500 -222▷5924⌥16▷1985 -212▷1256⌥3▷2145 -202▷7148⌥5▷3076 -207▷7188⌥3▷4754 -201▷0154⌥5▷2167 | 0▷8738⌥0▷0364 0▷7056 ⌥ 0▷0167 0▷8170 ⌥ 0▷0197 0▷7989 ⌥ 0▷0102 0▷8074 ⌥ 0▷0141 0▷8285 ⌥ 0▷0114 0▷8273⌥0▷0148 0▷8215 0▷0167 |
NIPS Co-authorship Dataset
We use the co-authorship as a relation from the proceeding of the Neural Information Processing Systems (NIPS) conference for the years 2000-2012. Due to the sparse nature of the co-authorships, we observe the authors' activities in all the 13 years (i.e. regardless of the time factor) and set the relational data to 1 if the two corresponding authors have coauthored for no less than 2 papers, which remove some of the "by chance" co-authorships. Further, the author with less than 4 relationships with others are considered "inactive" and hence have been manually removed. Thus, a 92 ⇥ 92 symmetric and binary matrix is obtained.
On this dataset, no pre-defined group information is obtained in advance. Thus, we consider it as full-correlation case and use one Gumbel Copula function to model all the interactions.
MIT Reality Dataset
From the MIT Reality Mining [Eagle and (Sandy) Pentland, 2006], we use the subjects' proximity dataset, where weighted links indicate the average proximity from one subject to another at work. We then "binarize" the data, in which we set the proximity value larger than 10 minutes per day as 1, and 0 otherwise. Therefore, a 94 ⇥ 94 asymmetric and binary matrix is obtained.
The dataset are roughly divided into four groups: Sloan Business School students (Sloan), lab faculty, senior students with more than 1 year in the lab and junior students. In our experiment, we only apply the Gumbel Copula function to the Sloan portion of the students to encourage similar mixture membership indicators.
Lazega Law Dataset
The lazega-lawfirm dataset [Lazega, 2001] is obtained from a social network study of corporate located in the north-eastern
0▷1143⌥0▷0019 -204▷0289⌥9▷5460
0▷8215 ⌥ 0▷0167
part of U.S. in 1988 - 1991. The dataset contains three different types of relations: co-work network, basic advice network and friendship network, among the 71 attorneys, of which the element are labeled as 1 (exist) or 0 (absent).
Since no group information is obtained in this dataset, we use the same setting as in NIPS co-authorship dataset as one Gumbel Copula function is used for all the interactions.
General Performance
From these reported statistics as shown in Table 3, we can see that our methods (cMMSB⇡ , cMMSBuv ) obtain the best performance in these 3 datasets, amongst all other models. Although iMMM can achieve smallest train error in the NIPS co-author dataset, our cMMSB's predictability is better than iMMM and the others. On the MIT reality and Lazegalawfirm datasets, our cMMSB can achieve at least 1% improvement on the AUC score. On the performance comparison of our two different sampling schemes cMMSB⇡ and cMMSBuv , we find they achieve similar results, which is within our expectation. Our cMMSB⇡ , cMMSBuv beat both MMSB-liked models and non-MMSB models since a hidden intra-group correlation has been adaptively utilized here.
6 Conclusions
The principal contribution of our proposed model is the introduction of the Copula function into MMSB, which represents the correlation between the pair of membership indicators, while keeping the membership indicators' marginal distribution invariant. The results show that, using both synthetic and real data, our Copula-incorporated MMSB, i.e., cMMSB, is effective in learning the community structure and predicting the missing links.
@inproceedings{ijcai2016p210,
  title     = {Copula Mixed-Membership Stochastic Blockmodel},
  author    = {Fan, Xuhui and Xu, Richard Yi Da and Cao, Longbing},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {1462--1467},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/210},
}
TY - CPAPER TI - Copula Mixed-Membership Stochastic Blockmodel AU - Fan, Xuhui AU - Xu, Richard Yi Da AU - Cao, Longbing T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 1462 EP - 1467 UR - https://ijcai.org/proceedings/2016/210 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





