
A Distributed and Scalable Machine Learning Approach for Big Data
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 1512-1517.
Abstract
With the rapid development of data sensing and collection technologies, we can easily obtain large volumes of data (big data). However, big data poses huge challenges to many popular machine learning techniques which take all the data at the same time for processing. To address the big data related challenges, we first partition the data along its feature space, and apply the parallel block coordinate descent algorithm for distributed computation; then, we continue to partition the data along the sample space, and propose a novel matrix decomposition and combination approach for distributed processing. The final results from all the entities are guaranteed to be the same as the centralized solution. Extensive experiments performed on Hadoop confirm that our proposed approach is superior in terms of both testing errors and convergence rate (computation time) over the canonical distributed machine learning techniques that deal with big data.
- [Bai et al., 1996] Zhaojun Bai, Gark Fahey, and Gene Golub. Some large-scale matrix computation problems. Journal of Computational and Applied Mathematics, 74(12):71 -89, 1996.
- [Boyd and Vandenberghe, 2004] Stephen Boyd and Lieven Vandenberghe. Convex Optimization. Cambridge Univer- sity Press, 2004.
- [Boyd et al., 2011] Stephen Boyd, Neal Parikh, Eric Chu, Borja Peleato, and Jonathan Eckstein. Distributed Opti- mization and Statistical Learning via the Alternating Di- rection Method of Multipliers. Now Publishers Inc., 2011.
- [Bradley et al., 2011] Joseph K. Bradley, Aapo Kyrola, Danny Bickson, and Carlos Guestrin. Parallel coordinate descent for l1-regularized loss minimization. In Proc. of ICML, 2011.
- [Burges, 1998] Christopher J. C. Burges. A tutorial on sup- port vector machines for pattern recognition. Data Mining and Knowledge Discovery, 2(2):121-167, 1998.
- [Buza, 2014] Krisztian Buza. Feedback prediction for blogs. In Myra Spiliopoulou, Lars Schmidt-Thieme, and Ruth Janning, editors, Data Analysis, Machine Learning and Knowledge Discovery. Springer, 2014.
- [Csanky, 1976] L. Csanky. Fast parallel matrix inversion al- gorithms. SIAM Journal on Computing, 5(4):618-623, 1976.
- [Defazio et al., 2014] Aaron J. Defazio, Tibrio S. Caetano, and Justin Domke. Finito: A faster, permutable incre- mental gradient method for big data problems. In Proc. of ICML, 2014.
- [El Ghaoui et al., 2011] L. El Ghaoui, G.-C. Li, V.-A. Duong, V. Pham, A. Srivastava, and K. Bhaduri. Sparse machine learning methods for understanding large text corpora. In Proc. of the Conference on Intelligent Data Understanding, 2011.
- [Forero et al., 2010] Pedro A. Forero, Alfonso Cano, and Georgios B. Giannakis. Consensus-based distributed sup- port vector machines. JMLR, 11:1663-1707, 2010.
- [Gopal and Yang, 2013] Siddharth Gopal and Yiming Yang. Distributed training of large-scale logistic models. In Proc. of ICML, 2013.
- [Graf et al., 2011] Franz Graf, Hans-Peter Kriegel, Matthias Schubert, Sebastian Polsterl, and Alexander Cavallaro. 2D image registration in CT images using radial image de- scriptors. In Proc. of Int. Conf. on Medical Image Com- puting and Computer-Assisted Intervention, 2011.
- [Joaquin Torres-Sospedra, 2014] Adolfo Martinez-Uso Tomar J. Arnau Joan P. Avariento Mauri Benedito- Bordonau Joaquin Huerta Joaquin Torres-Sospedra, Raul Montoliu. UJIIndoorLoc: A new multi-building and multi-floor database for WLAN fingerprint-based indoor localization problems. In Proc. of Int. Conf. on Indoor Positioning and Indoor Navigation, 2014.
- [Lee et al., 2006] Su-In Lee, Honglak Lee, Pieter Abbeel, and Andrew Y. Ng. Efficient L1 regularized logistic re- gression. In Proc. of AAAI, 2006.
- [Ma et al., 2009] Justin Ma, Lawrence K. Saul, Stefan Sav- age, and Geoffrey M. Voelker. Identifying suspicious urls: An application of large-scale online learning. In Proc. of ICML, 2009.
- [Mairal, 2013] Julien Mairal. Stochastic majorization- minimization algorithms for large-scale optimization. In Proc. of NIPS 26, 2013.
- [Mairal, 2014] Julien Mairal. Incremental majorization- minimization optimization with application to large-scale machine learning. In Proc. of ICML, 2014.
- [Mateos et al., 2010] Gonzalo Mateos, Juan Andrs Baz- erque, and Georgios B. Giannakis. Distributed sparse lin- ear regression. IEEE Transactions on Signal Processing, 58(10):5262-5276, 2010.
- [Mayer-Schnberger, 2013] Viktor Mayer-Schnberger. Big Data: A Revolution That Will Transform How We Live, Work and Think. Viktor Mayer-Schnberger and Kenneth Cukier. John Murray Publishers, 2013.
- [Sontag et al., 2010] David Sontag, Amir Globerson, and Tommi Jaakkola. Introduction to Dual Decomposi- tion for Inference. Optimization for Machine Learning, 45(1):977-1014, 2010.
- [Tibshirani, 1994] Robert Tibshirani. Regression shrinkage and selection via the lasso. Journal of the Royal Statistical Society, Series B, 58:267-288, 1994.
- [Tseng, 2001] P. Tseng. Convergence of a block coordinate descent method for nondifferentiable minimization. Jour- nal of Optimization Theory and Applications, 109(3):475- 494, 2001.
- [Wang et al., 2013] Huahua Wang, Arindam Banerjee, Cho- Jui Hsieh, Pradeep K Ravikumar, and Inderjit S Dhillon. Large scale distributed sparse precision estimation. In Proc. of NIPS 26, 2013.
- [Yin et al., 2013] Junming Yin, Qirong Ho, and Eric Xing. A scalable approach to probabilistic latent space inference of large-scale networks. In Proc. of NIPS, 2013.
- [Zhang, 2004] Xian-Da Zhang. Matrix Analysis and Appli- cations. Tsinghua University Press, 2004.
- [Zhu et al., 2008] Kaihua Zhu, Hao Wang, Hongjie Bai, Jian Li, Zhihuan Qiu, Hang Cui, and Edward Y. Chang. Paral- lelizing support vector machines on distributed computers. In Proc. of NIPS 20, 2008.
- [Zinkevich et al., 2010] Martin A. Zinkevich, Alex Smola, Markus Weimer, and Lihong Li. Parallelized stochastic gradient descent. In Proc. of NIPS 23, 2010.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Machine Learning (ML) has been a hot research area in the past few decades. Traditionally, a bottleneck that prohibits the development of more intelligent systems is the limited amount of data. Without enough data, computers can hardly make intelligent decisions as human beings do. However, this situation has changed with the rapid growth of data sensing and collection technologies in recent years. This has opened a wide range of new opportunities, both because the best algorithm for a given problem may change dramatically as more data becomes available [Mayer-Schnberger, 2013], and because such a wealth of data promises solutions to problems that could not be previously approached.
Besides opportunities, challenges are also coming along. Big data not only changes the tools that can be used for intelligent decision making, but also changes our entire way of thinking about knowledge extraction and interpretation. Many of the traditional machine learning algorithms require the loading of the entire data set into one computer; this step becomes impossible when data sets are incredibly large. Therefore, big data is driving the need for scalable, parallel and online intelligent algorithms.
In this paper, we propose a novel matrix decomposition and combination approach combined with the parallel block coordinate descent (PBCD) algorithm to make the computation effort distributed for several of the most popular machine learning algorithms, e.g., support vector machine (SVM) [Burges, 1998], and logistic regression [Lee et al., 2006]. After applying our proposed approach to these machine learning algorithms, they can be readily used to solve problems involving big data. To be more specific, the key challenge in big data processing is that both feature space and sample space are very large. In our proposed approach, we first decompose the feature space of the data and use the PBCD algorithm to iteratively compute the optimal solution. However, since the data sample space is also large, we still cannot process the whole data at the same time. In this case, we continue to separate the data along the sample space, and apply our novel matrix decomposition and combination approach to generate the final results.
Experimental results on large data sets verify that our approach achieves better convergence rate than four other canonical distributed or big data machine learning algorithms, on both regression and classification tasks.
2 RelatedWork
There are two popular groups of distributed machine learning algorithms. The first group decompose/distribute the firstorder derivative information, i.e., gradient, so as to make the canonical machine learning algorithms distributed [Zinkevich et al., 2010; Mateos et al., 2010; Gopal and Yang, 2013; Forero et al., 2010; Zhu et al., 2008]. When faced with various coupled constraints, they usually apply distributed optimization techniques like dual decomposition [Sontag et al., 2010], alternating direction method of multipliers (ADMM) [Boyd et al., 2011] to unify the constraints into objectives and perform decomposition thereafter. For example, Mateos et al. [2010] propose a distributed algorithm for sparse linear regression. They first formulate the LASSO [Tibshirani, 1994] linear regression as a convex optimization problem, and then apply ADMM to make the computation process distributed.
The second group investigate the special (usually sparse) structure of the problem, and propose efficient distributed algorithms accordingly [Defazio et al., 2014; El Ghaoui et al., 2011; Wang et al., 2013; Mairal, 2013; Yin et al., 2013;
Mairal, 2014]. For example, Defazio et al. [2014] propose a permutable incremental method for big data processing. They target at a specific problem which is to minimize the summation of squares. The specific problem nature (finite summation of squares) allows to take advantage of its strong convexity. EL Ghaoui et al. [2011] make use of the sparse connection information within high-dimensional data, and revise the principal component analysis (PCA) and graphical computation methods to their respective sparse version. The algorithm has been applied to understand text information.
In summary, making use of the first order information, i.e., the gradient information, can be general in terms of application domains. However, since the higher-order information of a problem is completely ignored, this kind of algorithms usually do not guarantee a high convergence rate. In the worst case, some of the algorithms (when using dual decomposition) only guarantee convergence in infinity. On the other hand, making use of the specific structure of the problem (i.e., sparsity) usually has very good convergence performance. However, since they are exploiting the specific nature of the problem, the generality of the algorithm is limited. Our proposed approach is trying to bridge the gap between the two groups. On one hand, our approach makes use of both the first order information and the second order information which is the inverse of the Hessian matrix, thus performs faster than the algorithms in the first group, as will be demonstrated in Section 5. On the other hand, our approach does not exploit the specific structure (i.e., sparsity) of specific problems, hence has a wider application compared to the algorithms in the second group.
As will be shown in the next section, we are, in essence, proposing an efficient matrix manipulation approach for large scale matrix inversion. Hence, we provide the brief literature review on large scale matrix inversion. The bottleneck of many large scale problems attributes to the efficient computation of the inverse of large scale matrices [Bai et al., 1996]. Csanky [1976] summarizes the canonical parallel computation methods for the large scale matrix inversion problem and gives the theoretical lower bounds of the computation complexities of such methods. Our proposed matrix inversion approach actually reaches that lower bounds.
3 Our DistributedML Approach
In this section, we propose a distributed and efficient approach to solve the following mathematical problem:
where X 2 Rm⇥n and Y 2 Rm. The most challenging part of this problem is that both m and n are large (i.e., in the scale of millions), which cannot be solved by default centralized solutions. In fact, for most supervised machine learning algorithms, when the data size (m) and data dimension (n) are very large, the key challenging computation step is also how to calculate β out of the problem formulated in Eq. 1. For example, in SVM, the key step is to solve Kβ = Y, where K is the kernel matrix; in linear discriminative analysis (LDA) and logistic regression, Hβ = Y, where H is the Hessian of the respective objective functions; and for linear regression, Xβ = Y, where X 2 Rm⇥n is the data matrix.
Since the challenging problem in the aforementioned machine learning algorithms share the similar nature, we only illustrate how to solve the general problem in Eq. 1 in a distributed and efficient manner.
We first clarify the mainly used symbols here: 1) m: the size of data (the number of data samples); 2) n: the number of features of the raw data; 3) N1: the number of computation entities for column (feature space) separation; 4) N2: the number of computation entities for row (data size) separation; 5) mi: the number of data samples in computer i; 6) nj: the number of features in computer j; 7) X 2 Rm⇥n : the (transformed) data matrix with m data samples and n features; 8) Y 2 Rm: The label information of the data; 9) β 2 Rn : the parameters to be learned by the machine learning algorithm.
3.1 Divide and Conquer Strategy
We consider the case where both the data size (m) and feature space (n) are very large. In this case, we perform the divideand-conquer strategy as demonstrated in the parallel block coordinate descent (PBCD) algorithm [Bradley et al., 2011]. More specifically, we first partition the data matrix X along its column, and represent it as X = (X1↪X2↪ ▷ ▷ ▷ ↪XN1 ) where Xi 2 Rm⇥ni ; we then partition β along its row accordingly, and have β = (β1>↪ β2>↪ ▷ ▷ ▷ ↪ βN1 >)> where βi 2 Rni .
The idea of the parallel block coordinate descent method is that at each iteration, we update the block parameter (βi) by a little bit assuming that all the other block parameters are not changing. The update rule is as follows:
where we superscript with k to denote the value of the scripted quantity at iteration k.
The convergence proof and convergence rate of PBCD have been provided in [Tseng, 2001]. The key extensive computation part of Eq. 2 is (Xi>Xi)-1 . Since Xi is only large in one dimension (m), we will use our proposed matrix decomposition and combination approach to solve it.
3.2 Matrix Decomposition and Combination
Here we introduce a novel approach to compute the inverse of Xi>Xi in an efficient and distributed manner. Note that Xi 2 Rm⇥ni , and m is very large, therefore it is impossible to store the matrix Xi in one computer's memory. In this case, (Xi>Xi)-1 is only a conceptual representation. However, note that ni is within a reasonable range, because we already divide the data along its feature space in Section 3.1.
Suppose we have N2 computers, each of which stores a subset of the data samples. Then, we partition Xi into N2 parts, and each part contains mi samples. For each of the mi samples, the computer contains its whole feature space of Xi.
Now, in essence, we have partitioned the data into N2 parts, so the matrix Xi can be represented as:
(Xi>Xi)-1 can then be represented as:
So, the key computation step is to obtain the result of (P N2 j=1 (Xji )>Xji )-1 in a distributed and efficient manner, where Xji is an mj ⇥ ni matrix. In order to refer to this term easily, we define it as M. Therefore, we have:
Since ni is not very large, each computer is able to perform the singular value decomposition (SVD) [Zhang, 2004] over its data matrix (Xji ), which can then be represented as:
whereUji is anmj⇥mj orthogonal matrix, ⌦ji is anmj⇥ni rectangle diagonal matrix with non-negative real numbers on the main diagonal, and (Vj i )> is an nj ⇥ nj orthogonal matrix. Here, an orthogonal matrix is a square matrix with real entries whose columns and rows are orthogonal unit vectors.
Substituting Eq. (6) into Eq. (5), we can get:
Since Uji is an orthogonal matrix, and we define ⇤ji = (⌦ji )>⌦ji , then, we can continue from Eq. (7) and get:
where Vj i is an nj ⇥ nj orthogonal matrix, and ⇤ji is an nj ⇥nj diagonal matrix with non-negative diagonal elements.
Now, the inverse of each to-be-summed element in Eq. (8) is very easy to compute. Considering the fact that Vj i is an orthogonal matrix, we have
The computation process of (⇤ji )-1 is just to compute the inverse of each diagonal element of matrix ⇤ji . However, computing the inverse of Mwhich is the summation of those terms, is not a trivial task. It will be addressed next.
Matrix Merging Process
Ideally, if we can represent M in such a form:
where V is an orthogonal matrix, and ⇤ is a diagonal matrix with positive diagonal values, then, it is easy to compute the inverse of M. Before transforming Eq. (8) into the form of Eq. (10) directly, we start with an easier step by merging two matrices. The problem is to represent Vj1 i ⇤j1 i (Vj1 i )> + Vj2 i ⇤j2 i (Vj2 i )> into the form of Eq. (10). Let us define:
Since both of the two terms in Eq. (11) are symmetric positive definite matrices, according to Theorem 1 below, there exists an invertible matrix P, such that P>Vj1 i ⇤j1 i (Vj1 i )>P = I, and P>Vj2 i ⇤j2 i (Vj2 i )>P = diag(λ1↪ λ2↪ ▷ ▷ ▷ ↪ λni ). This conclusion means that P satisfies the following equation:
After simple deduction, we can get that:
Continuing to apply the singular value decomposition to the second half of Eq. (13), which is (P-1 )>diag(λ1 + 1↪ λ2 + 1↪ · · · ↪ λni + 1)P-1 , we can represent Mij as: Mij = Vij⇤ijV> ij .
Next, we first propose and prove a theorem for the existence of such a P matrix, and then deliver the method for computing P -1 .
Here, Sn++ refers to symmetric positive definite n ⇥ n matrices and Sn refers to symmetric n ⇥ n matrices. Suppose that A and B are both n ⇥ n matrices, A is positive definite, and B is symmetric. Then, there exists an invertible matrix P, which makes A congruent to the identity matrix [Zhang, 2004] and in the meantime, makes B diagonal. Here, the symbol I denotes the identity matrix.
Proof. Since A is positive definite, then A is congruent to the identity matrix. A 2 Sn++ ) 9P1, s.t. P1>AP1 = I. Since P1>BP1 is symmetric, then we can orthogonally diagonalize it to a diagonal matrix. B 2 S ) P1>BP1 2 S ) 9P2 s.t. (1) P2>P2 = P2P2> = I; (2) P2>P1>BP1P2 = diag(λ1↪ λ2↪ ▷ ▷ ▷ ↪ λn). Defining P = P1P2, we then have P>AP = I, in the meanwhile, we have P>BP = diag(λ1↪ λ2↪ ▷ ▷ ▷ ↪ λn).
Now, we have finished the merging process of the matrices. The merged matrix (Mij) is also represented in the same form as that before the merge. We can continue with the merging process when Mij 'meets' another matrix. Thus, the key computation step now is to find matrix P-1 .
The Computation Process of P-1
In Eq. (11), ⇤j1 i is a diagonal matrix with all positive diagonal elements. So, suppose ⇤j1 i = diag(λ1↪ λ2↪ ▷ ▷ ▷ ↪ λL) and define ⇣⇤j1 i ⌘- 12 = diag(λ- 12 1 ↪ λ- 12 2 ↪ ▷ ▷ ▷ ↪ λ- 1 2 L ), P1 = ⇣⇤j1 i ⌘- 12 V> i , then:
Multiplying Eq. (11) by P1 from the left and by P>1 from the right, then we can obtain:
Here, we define ⇣⇤j2 i ⌘12 = diag(λ 12 1 ↪ λ 12 2 ↪ ▷ ▷ ▷ ↪ λ 12L ), and then Eq. (15) can be further transformed to:
Define Q = ⇣⇤j1 i ⌘- 12 V> i Vj ⇣⇤j2 i ⌘1 2 , then Eq. (16) is simplified as
Applying singular value decomposition on Q, we can get:
where Uq and Vq are orthogonal matrices, and ⇤q is a diagonal matrix. Replacing Q in Eq. (17) by Eq. (18), we get:
Solving Eq. (19) for Mij and replacing P-1 1 by Eq. (14),
So, the inverse of the matrix P as described in Eq. (12) can be directly calculated out as:
Transforming Merged Matrix into Standard Form
Now, we know P-1 , and then the merged matrix can be represented as:
Mij is an n⇥n matrix. Applying singular value decomposition over Mij , we can represent it as:
where Vij is an orthogonal matrix and ⇤ij is diagonal matrix with all positive diagonal elements.
So far, we are able to merge two matrices, each of which is of the form as represented in Eq. (10), and continue to represent the merged matrix in the form of Eq. (10). As the process goes on, we will in the end reach the final representation also in the form of Eq. (10).
4 Analysis of Computation Complexity
In this section, we only analyze in detail the computation complexity of our proposed matrix manipulation (decomposition and combination) approach, as for the PBCD part, it has been well analyzed in [Tseng, 2001]. The number of iterations needed for PBCD to converge is O(N1), where N1 is the number of blocks. Within each iteration, the computation complexity mainly relies on how to compute the inverse of X>i Xi. Thus, if the computation complexity of X>i Xi is C, then the overall computation complexity is C ⇥ O(N1).
4.1 Analysis of MatrixManipulation Approach
Before analyzing the matrix manipulation approach's computation complexity, we first lay down the evaluation metric.
Flops and Computation Complexity on Basic Operations
The computation cost of an operation can often be expressed through the number of floating-point operations (flops). A flop is defined as an addition, subtraction, multiplication or division of two floating-point numbers [Boyd and Vandenberghe, 2004]. To evaluate the complexity of an approach, we count the total number of flops, express it as a function (usually a polynomial) of the dimensions of the matrices and vectors involved, and simplify the expression by ignoring all terms except the leading terms. So, we can express the computation complexity of an SVD operation over a matrix A 2 Rm⇥n as O(m2n + n3 ). The computation complexity of a matrix-matrix product M = AB, where A 2 Rm⇥n and B 2 Rn⇥p , is O(mnp).
Worst Case Complexity over a Single Computer
Since we are developing a distributed approach, computing the overall computation complexity is not meaningful. So, we here analyze the computation complexity over one single computer. Since the data size is not necessarily the same, and the computation process for one computer may end before the approach exits, we consider the computation complexity of the 'worst' computer. Here, the term 'worst computer' refers to the computer performing the most complex computation over the whole process.
Examining the approach flow process, we can see that we are required to perform SVD over matrices Xi, which needs O(m2i nj + n3j ) flops. Since we are considering the 'worst computation unit', the computation complexity can be expressed as O(maxi (m2i )maxj nj +maxj (n3j )). Then, the approach requires the computation of Uq and P-1 . The computation of Uq requires three steps of maxj nj ⇥ maxj nj matrix-matrix multiplication, and one step of SVD over a maxj nj ⇥ maxj nj matrix, and the computation complexity of the matrix-matrix multiplication and SVD are both O(maxj (n3j )). Thus, the computation complexity of calculating Uq is O(maxj (n3j )). Likewise, the computation of P-1 requires two steps of maxj nj ⇥ maxj nj matrixmatrix multiplication, and thus the computation complexity is O(maxj (n3j )). Multiplying the matrices together involves two steps of maxj nj ⇥ maxj nj matrix-matrix multiplication, and hence the computation complexity is also O(maxj (n3j )). Performing SVD over the final maxj nj ⇥ maxj nj matrix requires O(maxj (n3j )). Summing together, and dropping the constant terms, we can conclude that the computation complexity is O(maxj (n3j )). The above computation complexity is for one matrix merge operation. Now we need to count how many operations of matrix merge we actually need. We have N2 computation units. After one round of two-computer merge, we are left with d N2 2 e computers, where dxe is the ceiling operator returning the smallest integer which is larger than x. So, after at most dlog2 N2e operations of matrix merge process, the approach ends.
In summary, the computation complexity for the worst computer is O(maxi (m2i )maxj nj + maxj (n3j ) + dlog2 N2emaxj (n3j )). Dropping constant terms, we can reach O(maxi (m2i ) maxj (nj ) + dlog2 N2e maxj (nj 3 )).
4.2 The Overall Computation Complexity
To sum up, the overall computation complexity of the proposed matrix manipulation approach together with PBCD, is O(N1(maxi (m2i )maxj (nj) + dlog2 N2emaxj (n3j ))). If we assume a uniform division among the data feature space among N1, and also a uniform division among data samples over N2 (which is suggested), the worst case computer's computation complexity would be O(N1(d m N2 e2 d n N1 e + dlog2 N2ed n N1 e3 )).
5 Experimental Evaluation
We evaluate the proposed approach through answering the following common questions: 1) How accurate is our distributed approach? Are we computing the same results as the centralized algorithm? 2) How fast is our approach? Is it (much) faster than canonical distributed machine learning methods that deal with big data?
5.1 Experimental Settings
In order to test the efficiency of the inherently distributed algorithm, we implement it in a distributed computation framework (Hadoop). Experimental settings are as follows: amazon instance category-r3 large; number of instances-5; operating system-Red Hat Enterprise Linux7.1(HVM)-64bit; RAM-15GB; Number of virtual CPUs for each instance-2
We test the performance of our algorithm and two benchmark algorithms on both regression and classification tasks. For classification, we select two data sets. One is the URL
Reputation data set [Ma et al., 2009] from the UCI machine learning repository. The total number of instances is 2,396,130 and the total number of attributes is 3,231,961. We name this data set as classification data set 1. The other one is the UJIIndoorLoc data set [Joaquin Torres-Sospedra, 2014]. The number of instances is 21,048, and the number of features is 529. We name the data set as classification data set 2. For regression, the first data set is the Relative location of CT slices on axial axis data set [Graf et al., 2011] from the UCI machine learning repository. The total number of instances is 53,500 and the total number of attributes is 386. We name the data set as regression data set 1. The second data set we choose is the BlogFeedback data set [Buza, 2014]. The number of data samples is 60,021, and number of features is 281. We name it as regression data set 2.
For the classification task, we apply our approach on support vector machines, and compare it with two other stateof-the-art algorithms, namely Consensus-Based Distributed Support Vector Machines (CB-DSVM) [Forero et al., 2010] and Parallelizing Support Vector Machines on Distributed Computers (P-SVM) [Zhu et al., 2008]. For the regression problem, we apply our proposed distributed machine learning approach on linear regression, and compare the performance with two canonical distributed linear regression algorithms, namely distributed sparse linear regression (DS-LR) [Mateos et al., 2010], and Finito [Defazio et al., 2014]. It is worth noting here that Finito was not proposed specifically for making linear regression algorithms distributed. However, since Finito targets at distributing the optimization problem of minimizing summation of squares, it is straightforward to apply it to linear regression algorithms.
Since almost all canonical distributed machine learning algorithms, including our proposed approach, guarantee to converge to the optimum, i.e., the same result as the corresponding centralized machine learning algorithm, the key performance index is then the convergence rate, i.e., how fast these approaches can converge.
5.2 Experimental Results
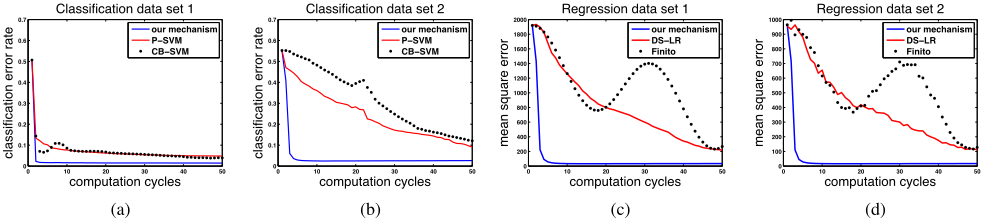
We implement all the competing distributed machine learning algorithms in the same environmental context (i.e., the same number of machines, the same configuration of Hadoop and EC2, the same training and testing data set, the same cross validation scheme (10-fold cross validation)), and compare the testing error decreasing curves in Fig. 1a to Fig. 1d. In these four figures, we bring about a concept called cycle. We define a cycle as the time point, in which all the computers have finished one round of computation. The average computation time needed for one cycle for our approach as well as the other four algorithms (two for classification and two for regression) is given in Table 1. Note that for both classification and regression data sets, it is impossible to perform the centralized machine learning algorithm, thus there is no performance measurement being plotted in the figures.
| Classification | Ours | P-SVM | CB-SVM |
|---|---|---|---|
| Data Set 1 | 6.46 | 18.56 | 25.85 |
| Data Set 2 | 2.10 | 4.89 | 5.70 |
| Regression | Ours | Finito | DS-LR |
| Data Set 1 | 0.53 | 4.55 | 2.43 |
| Data Set 2 | 0.48 | 4.42 | 2.58 |
As shown in all the four figures in Fig. 1, our algorithm achieves better testing error performance in every cycle. It means that, given time constraint, if we have to stop the algorithm at an arbitrary time point, our approach would yield better performance. Here, we wish to point out (details are explained in [Defazio et al., 2014]) that the regression error might increase as the number of iterations (cycles in our figure) increases, because the underlying random sampling approach might temporarily drive the parameters further away from the optimum. This phenomenon appears in Fig. 1c and Fig. 1d in our experimentation.
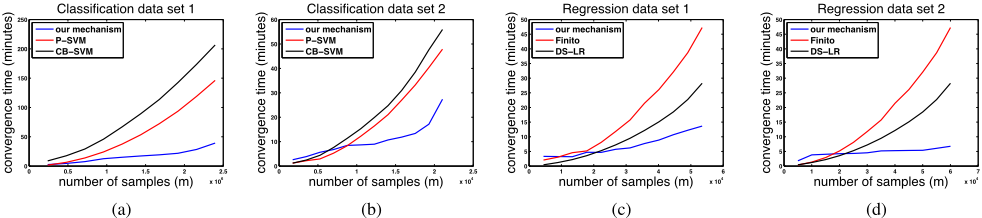
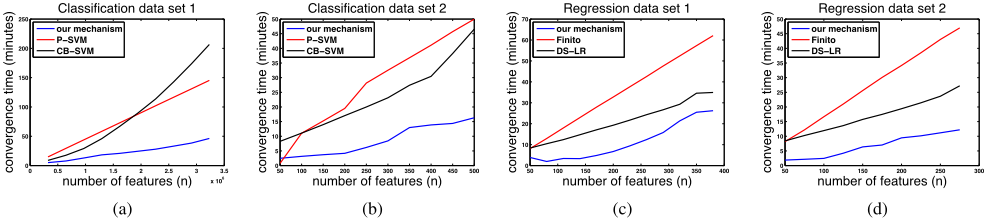
Now, we further evaluate how the computation time of our approach changes when the size of the data (m) and the number of features (n) vary. We argue that this evaluation process is quite important in that it verifies the scalability of our approach with respect to data size and feature space.
Fig. 2a to Fig. 2d show how the system convergence time changes as we change the number (m) of data samples for different data sets and different tasks, i.e., classification and regression. Likewise, Fig. 3a to Fig. 3d show how the system convergence time changes as we change the number (m) of data samples for different data sets and different tasks. Here, the system converges if the computed error at the current cycle is the same as the error at the previous cycle. The total time consumed (for the 'worst' computer) till the end of the current cycle is defined as system convergence time. We can see that our approach has better scalability performance when the number of data samples (m) and the number of features (n) increase.
6 Conclusion and FutureWork
This paper proposes a distributed approach for large scale machine learning. We show the performance comparison of our approach when applied to SVM and linear regression with four other canonical distributed or big data machine learning algorithms. Experimental results verify that our approach achieved better convergence rate. In the future, we will further investigate the PBCD part of our approach, since it still requires a lot of computation efforts.
Acknowledgments
This work is supported by the MOE AcRF Tier 1 funding (M4011261.020) awarded to Dr. Jie Zhang.
@inproceedings{ijcai2016p217,
  title     = {A Distributed and Scalable Machine Learning Approach for Big Data},
  author    = {Guo, Hongliang and Zhang, Jie},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {1512--1517},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/217},
}
TY - CPAPER TI - A Distributed and Scalable Machine Learning Approach for Big Data AU - Guo, Hongliang AU - Zhang, Jie T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 1512 EP - 1517 UR - https://ijcai.org/proceedings/2016/217 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





