
Asynchronous Accelerated Stochastic Gradient Descent
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 1853-1858.
Abstract
Stochastic gradient descent (SGD) is a widely used optimization algorithm in machine learning. In order to accelerate the convergence of SGD, a few advanced techniques have been developed in recent years, including variance reduction, stochastic coordinate sampling, and Nesterov's acceleration method. Furthermore, in order to improve the training speed and/or leverage larger-scale training data, asynchronous parallelization of SGD has also been studied. Then, a natural question is whether these techniques can be seamlessly integrated with each other, and whether the integration has desirable theoretical guarantee on its convergence. In this paper, we provide our formal answer to this question. In particular, we consider the asynchronous parallelization of SGD, accelerated by leveraging variance reduction, coordinate sampling, and Nesterov's method. We call the new algorithm asynchronous accelerated SGD (AASGD).Theoretically, we proved a convergence rate of AASGD, which indicates that (i) the three acceleration methods are complementary to each other and can make their own contributions to the improvement of convergence rate; (ii) asynchronous parallelization does not hurt the convergence rate,and can achieve considerable speedup under appropriate parameter setting. Empirically, we tested AASGD on a few benchmark datasets. The experimental results verified our theoretical findings and indicated that AASGD could be a highly effective and efficient algorithm for practical use.
- [Agarwal and Duchi, 2012] Abhishek Agarwal and John C Duchi. Distributed delayed stochastic optimization. In De- cision and Control (CDC), 2012 IEEE 51st Annual Con- ference on, pages 5451-5452. IEEE, 2012.
- [Avron et al., 2014] Haim Avron, Alex Druinsky, and Arpan Gupta. Revisiting asynchronous linear solvers: Provable convergence rate through randomization. In Parallel and Distributed Processing Symposium, 2014 IEEE 28th Inter- national, pages 198-207. IEEE, 2014.
- [Bousquet and Bottou, 2008] Olivier Bousquet and Léon Bottou. The tradeoffs of large scale learning. In Advances in Neural Information Processing Systems (NIPS), pages 161-168, 2008.
- [Defazio et al., 2014] Aaron Defazio, Francis Bach, and Si- mon Lacoste-Julien. Saga: A fast incremental gradient method with support for non-strongly convex composite objectives. In Advances in Neural Information Processing Systems (NIPS), pages 1646-1654, 2014.
- [Hu et al., 2009] Chonghai Hu, Weike Pan, and James T Kwok. Accelerated gradient methods for stochastic opti- mization and online learning. In Advances in Neural Infor- mation Processing Systems (NIPS), pages 781-789, 2009.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In Advances in Neural Information Processing Systems (NIPS), pages 315-323, 2013.
- [Langford et al., 2009] John Langford, Alexander Smola, and Martin Zinkevich. Slow learners are fast. arXiv preprint arXiv:0911.0491, 2009.
- [Lee et al., 2015] Jason Lee, Tengyu Ma, and Qihang Lin. Distributed stochastic variance reduced gradient methods. arXiv preprint arXiv:1507.07595, 2015.
- [Lian et al., 2015] Xiangru Lian, Yijun Huang, Yuncheng Li, and Ji Liu. Asynchronous parallel stochastic gradient for nonconvex optimization. In Advances in Neural Informa- tion Processing Systems (NIPS), pages 2719-2727, 2015.
- [Nemirovski et al., 2009] Arkadi Nemirovski, Anatoli Judit- sky, Guanghui Lan, and Alexander Shapiro. Robust stochastic approximation approach to stochastic program- ming. SIAM Journal on Optimization, 19(4):1574-1609, 2009.
- [Nesterov, 2004] Yurii Nesterov. Introductory lectures on convex optimization, volume 87. Springer Science & Busi- ness Media, 2004.
- [Nesterov, 2012] Yu Nesterov. Efficiency of coordinate de- scent methods on huge-scale optimization problems. SIAM Journal on Optimization, 22(2):341-362, 2012.
- [Nitanda, 2014] Atsushi Nitanda. Stochastic proximal gra- dient descent with acceleration techniques. In Advances in Neural Information Processing Systems (NIPS), pages 1574-1582, 2014.
- [Rakhlin et al., 2012] Alexander Rakhlin, Ohad Shamir, and Karthik Sridharan. Making gradient descent optimal for strongly convex stochastic optimization. In Proceedings of the 29th International Conference on Machine Learning (ICML-12), pages 449-456, 2012.
- [Recht et al., 2011] Benjamin Recht, Christopher Re, Stephen Wright, and Feng Niu. Hogwild: A lock-free approach to parallelizing stochastic gradient descent. In Advances in Neural Information Processing Systems (NIPS), pages 693-701, 2011.
- [Reddi et al., 2015] Sashank J Reddi, Ahmed Hefny, Suvrit Sra, Barnabás Póczos, and Alex J Smola. On variance re- duction in stochastic gradient descent and its asynchronous variants. In Advances in Neural Information Processing Systems (NIPS), pages 2629-2637, 2015.
- [Richtárik and Takáč, 2014] Peter Richtárik and Martin Takáč. Iteration complexity of randomized block- coordinate descent methods for minimizing a composite function. Mathematical Programming, 144(1-2):1-38, 2014.
- [Roux et al., 2012] Nicolas Le Roux, Mark Schmidt, and Francis Bach. A stochastic gradient method with an ex- ponential convergence rate for finite training sets. arXiv preprint arXiv:1202.6258, 2012.
- [Shalev-Shwartz and Tewari, 2011] Shai Shalev-Shwartz and Ambuj Tewari. Stochastic methods for l 1-regularized loss minimization. The Journal of Machine Learning Research, 12:1865-1892, 2011.
- [Shalev-Shwartz and Zhang, 2013] Shai Shalev-Shwartz and Tong Zhang. Stochastic dual coordinate ascent methods for regularized loss. The Journal of Machine Learning Re- search, 14(1):567-599, 2013.
- [Shamir et al., 2014] Ohad Shamir, Nati Srebro, and Tong Zhang. Communication-efficient distributed optimization using an approximate newton-type method. In Proceed- ings of the 31st International Conference on Machine Learning (ICML-14), pages 1000-1008, 2014.
- [Zhang et al., 2013] Shanshan Zhang, Ce Zhang, Zhao You, Rong Zheng, and Bo Xu. Asynchronous stochastic gradi- ent descent for dnn training. In Acoustics, Speech and Sig- nal Processing (ICASSP), 2013 IEEE International Con- ference on, pages 6660-6663. IEEE, 2013.
- [Zhao et al., 2014] Tuo Zhao, Mo Yu, Yiming Wang, Raman Arora, and Han Liu. Accelerated mini-batch randomized block coordinate descent method. In Advances in Neu- ral Information Processing Systems (NIPS), pages 3329- 3337, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Stochastic gradient descent (SGD) is a widely used optimization technology in many applications, due to its simplicity and good empirical performances [Bousquet and Bottou, 2008; Rakhlin et al., 2012; Nemirovski et al., 2009]. In this paper, we focus on the adoption of SGD to solve the following empirical risk minimization problem, whose objective is the sum of smooth and convex loss functions, i.e.
⇤This work was done when the author was visiting Microsoft Research Asia.
Please note that the loss function fi(x) may take different forms in different applications. For example, suppose we have a set of training data (a1↪ b1)↪ · · · ↪ (an↪ bn), where ai 2 Rd is an input feature vector and bi 2 R is its output. Then loss function fi is usually defined as a least square function fi(x) = 12 (aTi x- bi)2 for regression, and a logistic function fi(x) = log(1 + exp(-biaTi x)) for classification.
SGD exploits the additive nature of the empirical risk function F (x), and randomly samples an instance at each iteration to calculate the gradient and updates the model towards the direction of negative gradient. Theoretical study on SGD has revealed that it has a sublinear convergence rate, meaning that the total number of component gradient evaluations required by SGD method to find an ✏-accurate solution is O(1◁✏). In recent years, people have been working on accelerating the convergence of SGD, by proposing new methods or leveraging existing methods in the literature of optimization. Representative acceleration methods include:
(1) Variance Reduction (VR) [Johnson and Zhang, 2013; Defazio et al., 2014]: Besides computing the gradient of one randomly sampled instance in each iteration, the VR technique computes the full gradient in a periodical manner and uses this full gradient for multiple iterations in order to reduce the sampling variance. It can be proven that the convergence rate of SGD can become linear by using the VR technique, under the condition of strong convexity.
(2) Stochastic Coordinate Sampling (SC) [Nesterov, 2012; Richt´arik and Tak´aˇc, 2014]: In addition to randomly sample training instances, the SC technique also performs random sampling over the feature dimensions. In particular, it randomly samples a block of coordinates, computes the partial gradients with respect to the features in the sampled block, and updates the solution only over this block. It clear that, since the computation of partial gradients are much faster, by using SC, SGD can become more efficient, especially when the number of coordinate blocks is relatively large.
(3) Nesterov's Acceleration (NA) [Nesterov, 2004]: The NA technique introduces one or multiple auxiliary variables, and updates the parameter according to the gradient at the auxiliary variable. Usually, the auxiliary variable is a slide of the current parameter leaning a little towards its own momentum. It can be proven that the convergence rate of SGD is improved by using the NA technique [Hu et al., 2009].
In addition to the above efforts on accelerating the convergence of SGD, there is another line of research, which speeds up the SGD algorithm by performing asynchronous parallelization. This is mainly motivated by the availability of very big training data, which makes sequential SGD very inefficient. In asynchronous parallel SGD [Recht et al., 2011; Agarwal and Duchi, 2012], multiple workers compute stochastic gradients in parallel, and update the centralized model without a synchronization with each other.
Given the above literature, a natural question to ask is whether these techniques can be seamlessly integrated with each other, and whether the integration has desirable convergence property. In this paper, we will provide our formal answer to this question. In particular, we study the asynchronous parallelization of SGD, accelerated by the VR, SC, and NA techniques. We call the corresponding algorithm asynchronous accelerated SGD (or AASGD for short), and perform both theoretical and empirical investigations on it.
First, we prove that: 1) the three acceleration techniques are complementary to each other and can make their own contributions to the convergence rate of AASGD; 2) the asynchronous parallelization does not hurt the convergence, and one can achieve square root speed up in certain situations.
Second, we tested AASGD on a few benchmark datasets. Our experimental results show: 1) the combination of VR, SC, and NA with SGD really leads to faster convergence rate as compared to conventional SGD; 2) Thanks to the asynchronous parallelization, AASGD can achieve promising speedup when running on multiple workers. These results verified our theoretical findings and indicated that AASGD could be a effective and efficient algorithm for practical use.
The remaining paper is organized as follows. In Section 2, we introduce SGD, its acceleration methods, and other related works. In Section 3, we propose the AASGD algorithm, and present our convergence analysis. Our empirical study is given in Section 4. We conclude the paper in the last section.
2 Backgrounds
2.1 SGD and its AccelerationMethods
SGD is a widely used algorithm to solve the empirical risk minimization problem (1), whose update rule is as follows:
where fik is a randomly sampled component of F. It has been proven that, SGD has sublinear convergence rate when a decreasing learning rate is used [Rakhlin et al., 2012].
In recent years, variance reduction, stochastic coordinate sampling, and Nesterov's acceleration method have been used to accelerate the convergence of SGD. In the following paragraphs, we will give them a brief introduction.
Variance Reduction (VR): It is well known that the variance introduce by stochastic sampling prevents us from adopting a constant learning rate in SGD (which makes SGD have a slower convergence rate than full gradient descent). To remedy this problem, a few variance reduction methods have been proposed to improve SGD [Johnson and Zhang, 2013; Roux et al., 2012; Shalev-Shwartz and Zhang, 2013]. In this paper, we focus on the method proposed in [Johnson and Zhang, 2013], which follows a multi-stage scheme and computes the full gradient periodically to regularize the stochastic gradients. Specifically, at the beginning of stage s, we compute the full gradient rF(˜xs), and then run an inner loop (k = 1↪ · · · ↪K) according to the following update formula:
The regularized gradient vk becomes an unbiased estimate of rF(xk-1), and its variance is much smaller than fik (xk-1) which is used in SGD.
Stochastic Coordinate Sampling (SC): When the data is high-dimensional, even for one sampled instance, the computation of the gradient over all the dimensions is still timeconsuming. To solve this problem, people have leveraged the stochastic coordinate sampling method used in stochastic coordinate descent (SCD) [Nesterov, 2012; Richt´arik and Tak´aˇc, 2014; Shalev-Shwartz and Tewari, 2011]. That is, instead of computing the gradient over all the dimensions, with SC, we only compute the partial gradients over a sampled coordinate block, as shown below:
where l is the coordinate index, Ck(k 2 ¶1↪ ▷▷▷↪m♦) is the coordinate block randomly sampled in iteration k and rlF is the partial gradient of F for coordinate l.
Nesterov's Acceleration (NA): Nesterov proposed an acceleration method for gradient methods in [Nesterov, 2004]. The basic idea is to consider the momentum when updating the parameters. In particular, Nesterov introduced one or several auxiliary parameters to record the current parameter plus its latest momentum. Then, the parameter is updated by the gradient at the value of the auxiliary variable. To be specific, with NA, the update rule becomes:
2.2 Existing Convergence Analysis
First, it has been shown that the three acceleration methods introduced above can make SGD converge faster. For example, [Johnson and Zhang, 2013], considered the integration of VR with SGD, and [Lee et al., 2015] integrated both VR and NA with SGD. However, to our best knowledge, it is unknown what will happen if we simultaneously combine all the three acceleration methods with SGD. Please note that, it is non-trivial to combine SC and NA with the involvement of VR, and the update rule of the combined method makes the theoretical analysis very difficult.
Second, as mentioned in the introduction, asynchronous parallelization of SGD and its convergence rate has been studied in recent years. For example, in [Recht et al., 2011; Lian et al., 2015; Agarwal and Duchi, 2012; Langford et al., 2009; Zhang et al., 2013; Avron et al., 2014], the convergence rate of asynchronous SGD was studied in different settings. In [Reddi et al., 2015] the asynchronous parallelization of SVRG was investigated. However, as far as we know, the asynchronous parallelization of SGD accelerated by VR, SC, and NA has not been studied yet. This is exactly what we are going to do in this paper.
3 Asynchronous Accelerated SGD
In this section, we propose a novel algorithm, which integrates all the techniques mentioned in the introduction to improve SGD. That is, it is an asynchronous parallel SGD algorithm, and accelerated by VR, SC, and NA at the same time. For ease of reference, we call this algorithm AASGD, whose details can be found in Algorithm 1.
Assume there are P workers and one master in the computational cluster. The workers are making updates to the master in an asynchronous manner. Each worker has full access to the data, and stores a non-overlapping partition Sp (p = 1↪ ▷▷▷↪ P) of the data index. In addition, the features are also partitioned into m non-overlapping blocks, denoted as ¶C1↪C2↪ ▷▷▷↪Cm♦. .
Worker: Read parameter xk from the master, randomly sample a mini-batch of data Ik of size b without replacement and a block of coordinates Ck, compute the VR-regularized gradient uk based on lk over Ck, and then send uk to the master.
The AASGD algorithm works in a multi-stage manner. At the beginning of stage s, each worker calculates the gradient over all its local data, i.e., Pi2Sp rfi(˜xs), and then sends it to the master. The master averages these updates and sends the full gradient back to the workers. After that, the workers and the master update the global vector for K rounds (k = 1↪ · · · ↪K) according to the following rules:
Master: Update parameter xk and auxiliary parameters yk and zk according to steps (5)-(7) in Algorithm 1.
The following steps in Algorithm 1 are related to the acceleration technique: (i) the full gradient calculation in step (1) is used by VR; (ii) the master's actions in steps (5)-(7) and the mini-batch sampling in step (2) are used by NA 1 ; (iii) the coordinate sampling in step (3) is used by SC.
Please note that the workers run the above procedures in parallel, without synchronization with each other. As a consequence, the master will receive delayed gradients. Specifically, in Algorithm 1, the regularized gradient uk in Step (4) is calculated with respect to a delayed parameter xk-⌧k . In practical, ⌧k is a random variable, dependent of the computational cluster (e.g., the heterogeneity of the computational nodes and their inter-connections). It is clear that, the delay is linearly increasing with the number of workers.
4 Convergence Analysis
In this section, we analyze the convergence rate of SASGD and AASGD. To this end, we make the following assumptions, which are commonly used in previous works [Agarwal and Duchi, 2012; Zhao et al., 2014; Recht et al., 2011].
Assumption 1 (Smoothness): The components ¶fi(x); i 2 [n]♦ of F(x) are differentiable and have Lipschitz continuous Algorithm 1 Asynchronous Accelerated SGD (AASGD)
1 It has been proved in [Nitanda, 2014], the mini-batch strategy is necessary for the faster convergence of SGD with NA.
Require: initial vector [˜x0↪ ⌘↪ β↪ b↪K↪ S]
Ensure: ˜xS
For local worker p: calculate rFp(x0) = Pi2Sp rfi(x0) and send it to the center.
For local worker p: read xk and calculate uk as below: (2) Randomly select a mini-batch of data Ik with size b,
- Randomly select a coordinate block Cjk ,
- Calculate uk+1↪l = rlfIk (xk-⌧k ) - rlfIk (x0) + rlF(x0) if l 2 Cjk ; uk+1↪l = 0 if l ◁2 Cjk and send it to the master.
For master: update the parameters as below:
- yk↪l = xk↪l - ⌘uk↪l if l 2 Cjk ; yk↪l = yk-1↪l if l ◁2 Cjk .
- zk = zk-1 - ↵uk
end for
partial gradients. That is to say, there exists a positive constant Lmax, such that 8i 2 [n]↪ j 2 [d], for 8x↪ y 2 Rd with xj 6= yj, we have
Therefore, the components fi(x) have Lipschitz continuous gradients, as shown below:
Assumption 2 (Convexity): F(x) is strongly convex with convexity parameter θ, i.e.,
Assumption 3 (Sparseness): The sparseness in mini-batch setting is defined as follows 3 :
where I denotes the indicator function and Iv denotes the mini-batch with index v which is a subset of [n]. Intuitively, the sparseness measures the maximal frequency for arbitrary coordinate appears in the mini-batch inputs. It is commonly assumed that the sparseness is upper bounded.
Assumption 4 (Bounded Delay): The delays ⌧1↪ ⌧2↪ ▷▷▷ are independent random variables, and ⌧k ⌧ for all k.
Based on above assumptions, we proved two theorems. The first one is for the sequential version of SGD accelerated by VR, SC, and NA (which we call SASGD sequential accelerated SGD), and the second one is regarding its asynchronous parallelization. In order to distinguish the parameters for SASGD and AASGD, we use subscript 0 to denote parameters for SASGD (and parameters without subscript for AASGD).
2 In this paper, if there is no specification, k · k is the L2-norm.
3 In this paper, for simplicity and without confusion, we omit the mini-batch size b in sparseness.
Theorem 4.1 Under Assumptions 1-3, if we set step size ⌘0 1 Lmax , β0 = ⌘0 ⌘0+m↵ , and K sufficiently large so that
where 0 < ↵0 < 1A and A = 4Lres(n-b) b(n-1) , then SASGD algorithm has geometric convergence in expectation:
Proof: First, we take expectation of the VR-regularized gradients vk+1 with respect to Ik↪ jk as below,
Then, for the auxiliary parameter z, we have:
Therefore,
According to the smoothness of partial gradients, we have the following:
EIk ↪jk F (yk+1) F (xk+1) - ⌘0EIk ↪jk rF (xk+1)T vk+1 (4) + Lmax⌘2 0 2 EIk↪jk kvk+1k2 = F (xk+1) - ⌘0m krF (xk+1)k2 + Lmax⌘2 0 2 EIk↪jk kvk+1k2 ▷ Thus, we have the following inequality: 0 m↵0 ⌘0 (F (xk+1) - EIk ↪jk F (yk+1)) - ↵0krF (xk+1)k2 + Lmaxm⌘0↵0 2 EIk↪jk kvk+1k2 ▷
After that, by following the proof of Theorem 3 in [Lee et al., 2015], we proved this theorem. ⇤
Based on Theorem 4.1, we have the following corollary for the complexity of SASGD, which is defined as how many partial gradients we need to calculate so as to guarantee the optimization error less than ✏.
Corollary 4.2 Under Assumptions 1-3, and the parameter setups in Theorem 4.1, if we set ↵0 = min¶ 1 3A ↪ 1 pLmaxθ ♦, and the mini-batch size b = 12np1 (n-1)+12p1 , then the SASGD can achieve its optimal overall complexity,which is
where 1 = L2res Lmaxθ and 2 = Lmax θ .
Proof: For SASGD, by setting ↵0 = min¶ 1 3A ↪ 1 pLmaxθ ♦, ⌘0 = 1 Lmax , we can get ⇢0 < 1 2◁3 ⇣ mp2 K + m θ↵0K + 13 ⌘. Choosing mini-batch size b = 12np1 (n-1)+12p1 , then we can get 1 3A = 1 pLmaxθ . Putting ↵0 = 1 pLmaxθ in ⇢0, then ⇢0 = 1 2◁3 ⇣ 2mp2 K + 13 ⌘. Then we can choose K = O(mp2). Then the overall complexity (number of partial gradients evaluation) is O(nm+ bmp2). Putting b = 12np1 (n-1)+12p1 in O(nm+ bmp2) can get the result. ⇤
Remarks: (1) The convergence rate of SASGD in Theorem 4.1 is linear, much faster than the sublinear convergence rate of SGD. This clearly demonstrates the advantages of adopting the acceleration techniques.
(2) From the complexity of SASGD in Theorem 4.1 and Corollary 4.2, we can observe the complementary contributions of three acceleration methods. As we know, the complexity of SGD with a decreasing step size ⌘k = 1◁θk is O(1◁✏θ)[Rakhlin et al., 2012]. Comparing the complexity of SASGD to that of SGD, i) VR method improves the complexity from O(1◁✏θ) to O ((nm+mLres◁θ) log 1✏ ); ii) NA method improves the coefficient in the complexity from (nm+mLres◁θ) to ✓nm+ nmLres◁θ n+pLres◁θ ◆; iii) SCD method improve the coefficient from nmLres◁θ n+pLres◁θ to nmLres◁θ n+pLres◁θpLres◁Lmax , which is faster since Lres ≥ Lmax.
Next, the following Theorem states the convergence rate after introducing asynchronous parallelization to SASGD.
Theorem 4.3 Under Assumptions 1-4, and ∆ satisfies p∆ < min¶θ↪ 14 ♦, if we set the step size ⌘ 1 2Lmax⌧ , β = ⌘ m↵+⌘ , and K is sufficiently large so that
where 0 < ↵ < 1 AD ↪ A = 4Lres(n-b) b(n-1) ↪D = 2(1- p∆ 2 ), then AASGD algorithm has geometric convergence in expectation:
Proof: At stage s, let vk+1 and uk+1 be two vectors whose l-th dimension defined as follows: vk+1↪l = rlfIk (xk+1) -rlfIk (˜xs-1) +rlF(˜xs-1) if l 2 Cjk ; otherwise, vk+1↪l = 0. uk+1↪l = rlfIk (xk+1-⌧k ) -rlfIk (˜xs-1) +rlF(˜xs-1) if l 2 Cjk ;otherwise,uk+1↪l = 0. Let ¯ vk+1 = rfIk (xk+1) - rfIk (˜xs-1) + rF (˜xs-1) and ¯uk+1 = rfIk (xk+1-⌧k ) - rfIk (˜xs-1) + rF (˜xs-1). According to Inequality (6) and Inequality (7) in paper [Lee
et al., 2015], we have:
Let EIk↪jk be the conditional expectations conditioned on ¶xs↪ ys↪ zs♦s=0↪1↪▷▷▷↪k in stage s. Since zk+1 -zk = -↵uk+1, and EIk↪jk uk+1 = 1m rF(xk+1-⌧k ), we can get:
According to the smoothness of F , we have:
The difference between AASGD and SASGD mainly lies in the communication delay ⌧. To characterize its influence on the convergence rate, we take the following three steps.
Step 1: Due to the delay, Equation (5) has an extra term EIk (¯ vk+1 - ¯uk+1)T (zk -x⇤ ) as compared with Equation (3). According to the fact that zk = xk+1 - 1-β β (yk -xk+1) and the Cauthy-Schwarz inequality, we have
where kxkIk denote the norm of x with respect to the union of non-zero coordinates of ai 2 Ik, i.e., kxkIk = (Pdl=1 ♣xl♣2 I[9ai2Iks▷t▷ail6=0]) 12 . Using the AM-GM inequality, the sparseness condition and xk+1 is independent of Ik, we can obtain:
Since we also have EIk↪jk kuk+1k2 = EIk k¯uk+1k2 , and EIk↪jk kvk+1k2 = EIk k¯uk+1k2 , Equation (5) can be re-written
Step 2: Due to the delay, Inequality (6) has an extra term ⌘m EIk rF (xk+1)T (¯ vk+1 - ¯uk+1) as compared with Equation (4). We bound this term using the same technique as Step 1.
Then Inequality (6) can be re-written as
By multiplying 2d↵ ⌘ on both sides of (8) and adding in (7), we can get:
Step 3: Let 1-β β = 2↵m ⌘ . We take expectation with respect to ⌧k. Under the assumption p∆ < θ, by summing inequality (9) over k = 0↪ ▷▷▷↪ K - 1, we can get: PK-1 k=0 F(xk+1)-F(x⇤ ) m 2↵ kz0-x⇤ k2 +PK-1 k=0 ↵HEIk k¯ukk2 - PK-1 k=0 ↵DkrF(xk+1)k2 + 2m↵ ⌘ (F(y0) -F(x⇤ )), where H = 2⌧ h⇣ Lmax⌘ 2 + p∆⌘ + ⇣ 1 2⌧ + mp∆ ⌘ ⌘i and D = 2 ⇣1 - p∆ 2 ⌘. According to Inequality (12) in paper [Lee et al., 2015], under the condition D ≥ H, we can get:
As for Theorem 4.2, we have the following discussions. The introduction of asynchronous parallelization does hurt the convergence of SASGD by a little (mainly due to the communication delay). However, when we run the AASGD algorithm on multiple machines, we can still achieve significant speed up under certain conditions, as shown in the following corollary.
Corollary 4.4 Assume p∆ < min¶θ↪ 14 ♦. If we set the step size ⌘ = 1 2Lmax⌧ ,↵ = min¶ 1 6A ↪ 1 pLmaxθ⌧ ♦ and select the block size m < 1 16Lmax∆1◁4 , then AASGD will achieve at least square root speedup with respect to the number of workers when ⌧ < 1 4∆1◁8 .
Proof: Compared with SASGD, the convergence rate in The-
orem 4.2 is slower due to the delay. In order to get speedup for AASGD, the order of inner loop K cannot be ⌧ times larger than SASGD. The order of K is related to two parameters ⌘ and ↵. In SASGD, ⌘0 = 1 Lmax . For AASGD, we set ⌘ = 1 2Lmax⌧ . Here we are interested in the situation where the ∆ ⌧ 1. Considering p∆ < min¶θ↪ 14 ♦, the condition ⇣1- p∆ 2 ⌘ > ⌧ ⇣ Lmax⌘ 2 + p∆+ 1 2⌧ + mp∆ ⌘ ⌘ can be satisfied with m < 1 16Lmax∆1◁4 and ⌧ < 1 4∆1◁8 . For AASGD, we set ↵ = min¶ 1 pLmaxθ⌧ ↪ 1 6A ♦ and b = 24np1◁⌧ (n-1)+24p1◁⌧ , the inner loop K is in the same order of O ✓✓nm+ nmp2p1 n+p1◁⌧ ◆ log 1✏ ◆. Compared with SASGD, it
Remark: Data sparsity serves as a condition for the speedup. If the data is sparse, the condition is more likely to hold, and we will get the speed-up.
is at most p⌧ larger but the computing time is ⌧ times smaller. The full gradient calculation can be distributed to multiple machine to get P times speedup. As a result, AASGD can achieve at least pP times speedup since ⌧ is in proportion to the number of local worker P. ⇤
5 Experiments
In this section, we report our experimental results to demonstrate the efficiency of AASGD, and validate our theoretical findings. We conducted binary classification tasks on three benchmark dataset: rcv1, real-sim, news20, where rcv1 is the densest dataset and news20 is of the highest dimension. The detailed information about the three datasets can be found from LibSVM website. The objective function used in our experiments is the L2-regularized logistic regression loss. We mainly compared AASGD, SASGD, and standard SGD algorithms, in terms of their convergence properties. In the AASGD algorithm, we set the number of block partitions as m = d◁100, the mini-batch size as pn◁pP (P is the number of threads), and the inner loop K = 2mn. The stopping criterion in our experiments is the training error smaller than 10-10 (i.e., F(xk) -F(x⇤ ) < 10-10 ). For the datasets we used, Lmax = Lres < 0▷25 since the input data is normalized [Reddi et al., 2015], ⌧ ⇡ P, θ = 1◁pn = 0▷01 [Shamir et al., 2014]. In SASGD and AASGD, we set stepsizes ⌘0 = 0▷2 and ⌘ = 0▷1◁P , which satisfy our assumptions in the theorems and corollaries.
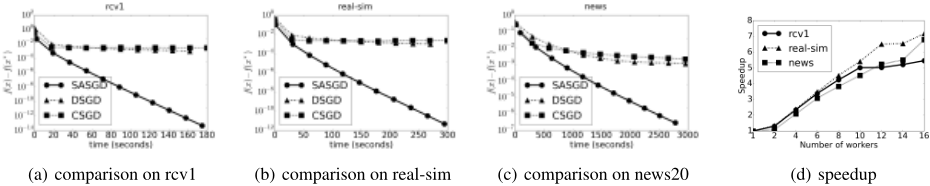
First, we investigate the SASGD algorithm. We compare it with standard SGD with different step sizes: a constant step size (denoted as C-SGD) and a decreasing step size as 1◁pk where k is the iteration [Reddi et al., 2015](denoted as DSGD). We plot the training curves of SASGD, C-SGD, and D-SGD in Figure 1(a),1(b),and 1(c)(for the three datasets respectively). From the figure, we have the following observations: D-SGD and C-SGD are faster than SASGD when we want to get a low-precise solution,i.e., ✏ < 10-2 . As the training process continues, SASGD converges much faster than D-SGD and C-SGD on all the three datasets when we want to get a high-precise solution. This is consistent with our theoretical results (complexity analysis).
Second, we examine the benefit of AASGD by running on multiple workers (when there is only one local worker, AASGD reduces to SASGD). We implement AASGD with 2,4,..,16 workers, and plot its speedups in Figure 1(d) (for the three datasets respectively). The speedup is defined as the ratio of the runtime with a single thread to the runtime with P threads. From these figures, we have the following observations:(1) on all the three datasets, AASGD has considerable speedup with respect to the number of workers, in an order lower than linear but higher than square root; (2) the smallest speedup is observed on rcv1. This is consistent with our theoretical results, since rcv1 is the densest dataset. [Reddi et al., 2015; Recht et al., 2011] get a similar result on rcv1.
6 Conclusions
In this paper, we focus on asynchronous SGD with acceleration methods, such as variance reduction, Nesterov's acceleration, and stochastic coordinate sampling. We prove the convergence rate for AASGD, and analyze the conditions for its speedup with respect to the number of workers. Our experiments on benchmark datasets well validated our theoretical findings. In the future, we will investigate the convergence rate of SGD with more acceleration methods, and AASGD in distributed network architectures.
@inproceedings{ijcai2016p265,
  title     = {Asynchronous Accelerated Stochastic Gradient Descent},
  author    = {Meng, Qi and Chen, Wei and Yu, Jingcheng and Wang, Taifeng and Ma, Zhiming and Liu, Tie-Yan},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {1853--1858},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/265},
}
TY - CPAPER TI - Asynchronous Accelerated Stochastic Gradient Descent AU - Meng, Qi AU - Chen, Wei AU - Yu, Jingcheng AU - Wang, Taifeng AU - Ma, Zhiming AU - Liu, Tie-Yan T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 1853 EP - 1858 UR - https://ijcai.org/proceedings/2016/265 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





