
Distance-Preserving Probabilistic Embeddings with Side Information: Variational Bayesian Multidimensional Scaling Gaussian Process
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 2011-2016.
Abstract
Embeddings or vector representations of objects have been used with remarkable success in various machine learning and AI tasks — from dimensionality reduction and data visualization, to vision and natural language processing. In this work, we seek probabilistic embeddings that faithfully represent observed relationships between objects (e.g., physical distances, preferences). We derive a novel variational Bayesian variant of multidimensional scaling that (i) provides a posterior distribution over latent points without computationally-heavy Markov chain Monte Carlo (MCMC) sampling, and (ii) can leverage existing side information using sparse Gaussian processes (GPs) to learn a nonlinear mapping to the embedding. By partitioning entities, our method naturally handles incomplete side information from multiple domains, e.g., in product recommendation where ratings are available, but not all users and items have associated profiles. Furthermore, the derived approximate bounds can be used to discover the intrinsic dimensionality of the data and limit embedding complexity. We demonstrate the effectiveness of our methods empirically on three synthetic problems and on the real-world tasks of political unfolding analysis and multi-sensor localization.
- [Bakker and Poole, 2013] Ryan Bakker and Keith T Poole. Bayesian metric multidimensional scaling. Political Anal- ysis, 21(1):125-140, 2013.
- [Borg and Groenen, 2005] Ingwer Borg and Patrick JF Groe- nen. Modern multidimensional scaling: Theory and appli- cations. Springer, 2005.
- [Hashimoto et al., 2015] Tatsunori B. Hashimoto, David Alvarez-Melis, and Tommi S. Jaakkola. Word, graph and manifold embedding from Markov processes. In NIPS 2015 Workshop on Nonparametric Methods for Large Scale Representation Learning, 2015.
- [Hensman et al., 2013] James Hensman, Nicolo Fusi, and Neil D Lawrence. Gaussian Processes for Big Data. In Uncertainty in Artificial Intelligence (UAI-13), 2013.
- [Hinton and Roweis, 2002] Geoffrey E Hinton and Sam T Roweis. Stochastic neighbor embedding. In NIPS, pages 833-840, 2002.
- [Iyyer et al., 2014] Mohit Iyyer, Jordan L Boyd-Graber, Leonardo Max Batista Claudino, Richard Socher, and Hal Daumé III. A neural network for factoid question answer- ing over paragraphs. In EMNLP, pages 633-644, 2014.
- [Lawrence and Quinonero-Candela, 2006] Neil D Lawrence and Joaquin Quinonero-Candela. Local distance preserva- tion in the GP-LVM through back constraints. In Proc. of the 23rd Intl. Conf on Machine learning, pages 513-520, 2006.
- [Lawrence, 2005] Neil Lawrence. Probabilistic non-linear principal component analysis with gaussian process latent variable models. The Journal of Machine Learning Re- search, 6:1783-1816, 2005.
- [Lim and Teh, 2007] Yew Jin Lim and Yee Whye Teh. Vari- ational Bayesian Approach to Movie Rating Prediction. Proceedings of KDD Cup and Workshop, pages 15-21, 2007.
- [Lowe and Tipping, 1997] David Lowe and Michael E Tip- ping. Neuroscale: novel topographic feature extraction us- ing RBF networks. In Advances in Neural Information Processing Systems (NIPS), pages 543-549, 1997.
- [Mathai and Provost, 1992] Arakaparampil M Mathai and Serge B Provost. Quadratic forms in random variables: theory and applications. Journal of the American Statisti- cal Association, 1992.
- [Mikolov et al., 2013] Tomas Mikolov, Quoc V Le, and Ilya Sutskever. Exploiting similarities among languages for machine translation. arXiv preprint arXiv:1309.4168, 2013.
- [Moore et al., 2004] David Moore, John Leonard, Daniela Rus, and Seth Teller. Robust distributed network local- ization with noisy range measurements. In Proc. of the 2nd Intl. Conf. on Embedded Networked Sensor Systems, pages 50-61. ACM, 2004.
- [Pennington et al., 2014] Jeffrey Pennington, Richard Socher, and Christopher D Manning. GloVe: Global Vectors for Word Representation. Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing, pages 1532-1543, 2014.
- [Salakhutdinov and Mnih, 2008] R Salakhutdinov and A Mnih. Probabilistic Matrix Factorization. NIPS, pages 1257-1264, 2008.
- [Sammon, 1969] John W Sammon. A nonlinear mapping for data structure analysis. IEEE Trans. on Computers, 18(5):401-409, 1969.
- [Shang et al., 2003] Yi Shang, Wheeler Ruml, Ying Zhang, and Markus PJ Fromherz. Localization from mere con- nectivity. In Proc. of the 4th ACM Int. Symp. on Mobile ad hoc networking & computing, pages 201-212. ACM, 2003.
- [Shepard, 1980] Roger N Shepard. Multidimensional scal- ing, tree-fitting, and clustering. Science, 210(4468):390- 398, 1980.
- [Tenenbaum et al., 2000] Joshua B Tenenbaum, Vin De Silva, and John C Langford. A global geomet- ric framework for nonlinear dimensionality reduction. Science, 290(5500):2319-2323, 2000.
- [Titsias and Lawrence, 2010] Michalis K Titsias and Neil D Lawrence. Bayesian Gaussian Process Latent Variable Model. In AISTATS, pages 844-851, 2010.
- [Titsias, 2009] Michalis Titsias. Variational Learning of In- ducing Variables in Sparse Gaussian Processes. In AIS- TATS, pages 567-579, 2009.
- [Torgerson, 1952] Warren S Torgerson. Multidimensional scaling: I. Theory and method. Psychometrika, 17(4):401- 419, 1952.
- [Van der Maaten and Hinton, 2008] Laurens Van der Maaten and Geoffrey Hinton. Visualizing data using t-SNE. JMLR, 9(2579-2605):85, 2008.
- [Venna and Kaski, 2006] Jarkko Venna and Samuel Kaski. Local multidimensional scaling. Neural Networks, 19(6):889-899, 2006.
- [Vilnis and McCallum, 2015] Luke Vilnis and Andrew Mc- Callum. Word Representations via Gaussian Embedding. In ICLR, 2015.
- [Whitehouse and Culler, 2006] Kamin Whitehouse and David Culler. A robustness analysis of multi-hop ranging- based localization approximations. In Proc. of the 5th Intl. Conf. on Information Processing in Sensor Networks, pages 317-325. ACM, 2006.
- [Zhou et al., 2012] Tinghui Zhou, H Shan, A Banerjee, and Guillermo Sapiro. Kernelized Probabilistic Matrix Factor- ization: Exploiting Graphs and Side Information. In SIAM International Conference on Data Mining (SDM), pages 914-925, 2012.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recent achievements in multiple AI domains have been spearheaded by embeddings discovered by models trained on data. For example, word representations have been profitably applied to machine translation [Mikolov et al., 2013] and question-answering [Iyyer et al., 2014]. Embeddings of other entities (e.g., robots, products, and people) are also used to great effect in domains such as sensor localization [Shang et al., 2003], recommender systems [Salakhutdinov and Mnih, 2008], and political analysis [Bakker and Poole, 2013].
In many applications, embeddings appear to require several properties in order to be useful. One of these properties is distance preservation-close objects in the original space should be similarly close in the embedding, and far objects similarly distant. Intuitively, this requirement arises when observed distances/similarities have intrinsic meaning (e.g., physical distances, preferences, and word counts) indicating the relationship between entities that we seek to capture.
In this work, we focus on learning probabilistic embeddings with this property. Although point-based embeddings are widely used, probabilistic representations offer distinct advantages. For example, uncertainty estimates in localization are essential for autonomous navigation, and Gaussian word embeddings can capture concept ambiguity and asymmetric relationships [Vilnis and McCallum, 2015].
To frame our contribution, we first discuss a general modeling framework-Bayesian Multidimensional Scalingthat encompasses methods that perform pairwise distance/similarity matching. As we will see, popular models such as Probabilistic Matrix Factorization [Salakhutdinov and Mnih, 2008] and word embedding [Hashimoto et al., 2015] can be cast as specialized models within this framework.
Under this umbrella structure, we contribute a specific distance-preserving MDS model that (i) produces probabilistic embeddings under a log-normal likelihood, (ii) utilizes multiple, noisy distance measurements to derive more accurate representations, and (iii) can leverage side information. The last feature is particularly significant since side information is available in many domains, e.g., in political surveys, candidates are associated with news articles. However, this extra information is typically unavailable for all points (e.g., survey respondents are anonymized) and may have a nontrivial relationship to the embedding. Our model naturally handles such situations by using sparse GPs [Titsias, 2009] on point subsets to induce correlations and learn nonlinear mappings that can project new points to the embedding. These mappings enable "out-of-sample" predictions, e.g., for coldstart recommendations where ratings are not yet available.
To perform inference, we derive efficient approximate variational lower-bounds that allow us to (i) obtain posteriors missing from maximum a posteriori (MAP) solutions, and (ii) perform intrinsic dimensionality selection to limit embedding complexity. Empirical results on synthetic datasets and two real-world tasks demonstrate that our method produces useful embeddings and learns mappings at reasonable cost. In particular, our model was able to project political candidates absent from survey data to a coherent layout using side information (Wikipedia entries), and in a localization task, to pin-point new sensors quickly using beacon signals.
1.1 Multidimensional Scaling: A Brief Review
MDS encompasses a range of techniques that constrain embeddings to have pair-wise distances as close as possible to the data space. MDS has had a rich history, from its early beginnings in 1930s psychometrics at Chicago and Princeton [Shepard, 1980] to recent probabilistic incarnations [Bakker and Poole, 2013]. What is now known as classical metric MDS was developed by [Torgerson, 1952], and has since been extended to handle non-metric spaces and nonlinear projections, yielding techniques such as Sammon mapping [Sammon, 1969], Isomap [Tenenbaum et al., 2000] and SNE [Hinton and Roweis, 2002]. MDS has become a significant research area and we refer interested readers to [Borg and Groenen, 2005] for a more comprehensive treatment.
In brief, the essence of MDS lies in the minimization of loss functions (historically called stress or strain), defined on pairwise distances dij . The loss function and distances can be varied to induce different lower-dimensional representations. In classical metric MDS (CMDS), the distances are Euclidean dij = kxi - xjk for data elements xi 2 X with the loss function being the residual sum of squares:
where zi 2 Z are the embedded points. Note that solving this minimization problem is equivalent to performing principal components analysis (PCA); the minimum configuration is the eigen-decomposition of the Gram matrix XX>.
In Sammon mapping, the distances remain Euclidean but the loss function is altered:
which causes small distances to be emphasized. In Isomap, the canonical stress function is used but the dij's are geodesic distances, which are estimated using the shortest-path distances on a neighborhood graph where each point xi is connected to its k nearest neighbors.
2 Probabilistic BayesianMDS Framework
Classic MDS methods, while effective, do not provide probabilistic embeddings, but as will see, can be extended with the Bayesian framework. Recently, [Bakker and Poole, 2013] presented a Bayesian metric MDS model with MCMC inference. We take this approach one-step further and discuss how this perspective relates to a broader class of models.
From a probabilistic viewpoint, our primary problem is finding latent coordinates zi 2 Z given observed relationships between entities, D = ¶ok = (ik↪ jk↪ dk)♦. Each observation ok comprises point labels, ik and jk, and the measurement dk. Unlike the classical MDS setting, we do not assume access to the data space (i.e., node features from which the distances are computed). Furthermore, the dataset need not contain all pairs and there can be multiple (noisy) observations for any two points. Conventionally, we work with distances, but the measurement dk can also reflect attraction/similarity.
Let N = ♣D♣ and to simplify notation, we drop the k subscript from the point labels. Adopting the Bayesian paradigm and assuming independent observational noise,
where we see the main elements comprise the likelihood p(dk♣fk), the pairwise function fz(zi↪ zj), and prior p(Z). Applying this Bayesian MDS framework to a particular domain requires specification of these three ingredients, which control the qualitative and quantitative aspects of the embedding, and leads to contrasting models. For example,
- ÷ A Gaussian likelihood p(dk♣fk) = QNk=1 N(dk♣ˆzk↪ σ2n ) with priors p(Z) = QNi N(0↪ σ2 i ), and a Euclidean distance link function, fk = fz(zi↪ zj) = kzi -zjk defines a probabilistic version of classical metric MDS;
- ÷ If the measurements dk are ratings and we change the Gaussian model above slightly by letting fz(zi↪ zj) = z>i zj (a similarity function), we recover the popular Probabilistic Matrix Factorization (PMF) model [Salakhutdinov and Mnih, 2008] for collaborative filtering;
- ÷ A negative binomial likelihood, p(dk♣zk) = QNk=1 NegBin(dk♣✓↪ ✓f -1 k ) with link function fz = exp(-kzi - zjk2 ◁2), specifies co-occurance metric recovery [Hashimoto et al., 2015], which is intimately linked to the successful word embedding method GLoVe [Pennington et al., 2014].
Under the probabilistic MDS framework, we can interpret the above models to be performing distance/similarity matching under an assumed noise distribution. Moreover, we can compose new models in this family by selecting an appropriate likelihood, pairwise function and priors. If additional parameters are required, priors (e.g., GPs) can be placed over these variables. Applying the relevant Bayesian machinery allows us to perform inference to obtain the latent distributions, and to control model complexity, which can impact generalizability and predictive performance.
3 Log-Normal Distance-PreservingMDS
In this section, we specify a Bayesian MDS model that forms the foundation for our GP-model in Section 4. Similar to the above models, we use Gaussian priors p(Z) = Q♣Z♣ i N(θ0↪ σ0I). The Gaussian likelihood is popular due to its tractability, but is inappropriate for distance measurements. Thus, we specify the less conventional, but more realistic, log-normal, as advocated by [Bakker and Poole, 2013],
and a log Euclidean distance function,
3.1 Variational Inference for Log-Normal MDS
Variational Bayes is a "middle-ground" approach that allows us to obtain confidence estimates missing from the MAP solution, but at a much lower computational cost compared to MCMC. It transforms approximate inference into an optimization problem, and our goal will be to derive a lower bound (the objective function to maximize).
Obtaining the lower bound for the log-normal Bayesian MDS model is challenging due to its expression, which contains nonlinear transformations of random variables. Here, we provide a step-by-step derivation of an approximate lower bound and demonstrate practical techniques that should prove useful in the development of future variational Bayesian MDS models. To begin, we adopt a mean-field variational approximation:
With the above factorization, the variational lower-bound is:
We see that L1 consists of two components: the expectation of the log-likelihood under the variational distribution and the negative Kullback-Leibler (KL) divergence between the prior and variational distributions for Z (multivariate normals).
Computing E[log p(D♣Z)]: We first simplify the expression by introducing ˆzk = zi - zj. Since both zi and zj are normal, ˆzk ⇠ N(ˆθk = θi -θj↪ ˆ⌃k = ⌃i +⌃j),
where the first two terms on the RHS are readily obtained, but the third requires additional effort- the unresolved expectation lacks a closed-form expression and typical solutions involve deriving an analytical approximation, or numerical estimation. In this work, we derive a second-order Taylor approximation,
where gk(x) = (log dk - 12 logx)2 . To obtain the necessary moments, the key "trick" is to recognize kˆzkk2 as a quadratic form of ˆzk and introduce the random variable yk = kˆzkk2 = ˆz>k ˆzk. Although the distribution for yk is complex, it has a tractable moment generating function M(t) [Mathai and Provost, 1992]:
where the λl's are the eigenvalues of ˆ⌃k and a = ˆ⌃- 12 k ˆθk. The corresponding derivatives of M(t) at t = 0 yield simple equations for the mean and variance,
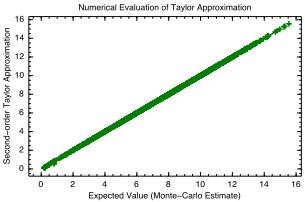
and completes our approximation. Numerical experiments (where ˆzk was randomly sampled across a wide range of values) showed the approximation to be fast and to have lowerror (Fig. 1). If higher precision is required, more costly numerical methods such as quadrature can be applied.
Combining the aforementioned elements and separating out the constants leads to the objective function L2 ⇡ L1,
Maximizing L2 (or equivalently, minimizing -L2) using an off-the-shelf optimizer gives us the variational posterior over the latent coordinates Z, and can also be used to estimate the intrinsic dimensionality of the embedding (demonstrated in the experiments). For large distance datasets or on-line settings, L2 can be optimized using stochastic gradient ascent.
4 Using Side Information with Sparse GPs
At this point, our variational Bayesian MDS (VBMDS) model represents each point as an individual distribution, which may prove troublesome for large datasets. It also lacks a mapping function-given new data points, we would have to re-optimize L2 to obtain the latent coordinates. In this section, we extend our model using sparse GPs that can leverage on any existing side information to learn a non-linear mapping of points to latent coordinates. This enhancement can also lead to a more compact model, since some points are presented indirectly.
Consider that Z is split into two mutually exclusive sets, Z = Z p [ Z x . Without loss of generality, assume that only points in zxi 2 Z x possess side information xi 2 X 1 . Employing the variational inducing input scheme proposed by [Titsias, 2009] and [Hensman et al., 2013], we introduce a set of r inducing variables U = ¶u1↪ ▷ ▷ ▷ ur♦ (one for each embedding dimension), and specify new priors,
where kij = k(xi↪ xj), ki = [k(xi↪ xj)]mj=1 and K-1 l = [k(xi↪ xj)]mi↪j=1 . The inducing inputs introduce conditional independencies between the latent function variables. As before, we use a mean-field variational approximation,
where q(ul) = N(ml↪ Sl) and q(zj) = N(θj↪⌃j). The associated variational lower-bound is
where p(Z♣U) inside the logarithm cancels out. The sparse GPs are assumed independent across the latent dimensions, which facilitates the derivation of the lower bound, and we have new variational parameters parameters ml and Sl associated with the inducing variables (in addition to any GP kernel hyperparameters).
Again, the principal challenge is in computing the expectation of the likelihood, E[p(D♣Z p ↪ Z x )]. Fortunately, we can re-use the derivations in the previous section, except that we now compute the moments E[yk] and V[yk] with respect to q(Z p )p(Z x ♣U)q(U) instead of q(Z). Specifically, this approach results in four possible cases, each requiring expectations over different subsets of variables:
and similarly for the variances. Case 1 arises when both points are in Z p and thus, the moments are those presented in the previous section, i.e., eqns. (9) and (10).
Case 2: Here, both points have side information and are represented by the GPs. Starting from (9),
1 Extensions to more than two subsets (e.g., when points come from multiple domains) is straightforward, but we restrict our description to a two-subset model for expositional simplicity.
with ˆ⌃k = Diag([ˆσ2 kl ]rl=1 )) and ˆσ2 kl = kii-k>i K-1 l ki+kjjk>j K-1 l kj. It turns out that ˆθk = [ˆθkl = (θil -θjl)]rl=1 , is normally distributed; recall that θil = k>i K-1 l ul and hence,
where b>kl = (ki -kj)>K-1 l . Since each ul is Gaussian, ˆθk is also a Gaussian specified by,
As in the previous section, the moments of the quadratic form ˆθ>k ˆθk are easily obtained via M(t),
The first moment is substituted into (17) to give,
Turning our attention to the variance and using same reasoning as above (with some algebraic manipulation),
Cases 3 and 4: The third and fourth cases arise when the points come from each set Z x and Z p , and can be treated similarly. We build upon Case 2 by noting that
where ˆσ2 il = kii-k>i K-1 l ki. This leads to a slightly different Gaussian distribution for ˆθk = N(ˆβk↪ ˆ⇤k) where
In the case that ˆzk = zpi - zxj , the signs in the mean are flipped, ˆβk = θj - ⇥b>klml ⇤rl=1 . The above equations for ˆβk and ˆ⇤k (along with ˆ⌃k) can be plugged into (20) and (21) derived in Case 2 to give the required central moments of yk.
To complete L4 ⇡ L3, we replace the moments E[yk] and V[yk] in L2 (11), depending on the cases encountered (16). This extended model, the VBMDS-GP, completely generalizes the VBMDS since either set Z x and Z p can be empty. Distinct from L2, there are no separate distributions for elements of Z x . Instead, the latent coordinates are represented indirectly using the sparse GPs, which enables prediction of latent coordinates using side information.
4.1 Relationship to other models
The VBMDS-GP builds upon a wide body of work and finds connections to a variety of models that also perform distance matching. For example, it is related to Neuroscale [Lowe and
10
1
1
1
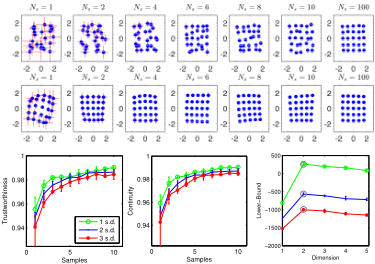
0 5 10 0.94 0.96 0.98 Samples Continuity 0 5 10 0.985 0.99 0.995 Samples Continuity 0 5 10 0.98 0.985 0.99 0.995 Samples Continuity Figure 2: 2D-lattice embeddings obtained by individual distributions (top) and using the sparse GPs (middle). The point variances were initially large, reflecting the embedding impreciseness, but gradually decreased with more observations. (bottom) Both scores improved with the number of samples across the three noise levels, and the maximum L4 value matched the intrinsic dimensionality of the data r = 2.
Tipping, 1997], that optimizes a RBF network using MDS stress. But unlike Neuroscale, the VBMDS-GP is probabilistic in nature, giving uncertainties over latent coordinates.
As previously mentioned, our Bayesian MDS framework is related to PMF, which has a variational version [Lim and Teh, 2007]. Similar to the VBMDS-GP, Kernel Probabilistic Matrix Factorization (KPMF) [Zhou et al., 2012], assumes a GP prior over the columns of the matrices (latent dimensions), which permits for the inclusion of side information. In addition to the difference in the likelihood and choice of fz, KPMF uses MAP inference, whilst we provide a variational solution with a sparse GP model. Our model is also related to probabilistic generative dimensionality-reduction models such as GPLVM [Lawrence, 2005]. Modern variational GPLVM variants also use sparse GPs [Titsias and Lawrence, 2010] but attempt to find probabilistic embeddings that reproduce high-dimensional observed features (or matrices)-the GPLVM mapping is in the opposite direction Z ! X compared to VBMDS-GP, and does not use side information, nor constrain distances unless back constraints are applied [Lawrence and Quinonero-Candela, 2006].
5 Experiments
In this section, we present empirical results, beginning with synthetic datasets to validate the approach, followed by two applications in political unfolding analysis and multi-sensor localization. VBMDS-GP source code is available at https: //github.com/haroldsoh/vbmds.
5.1 Embeddings with Noisy Distances
In this first experiment, we validated our model by examining the embeddings generated given noisy distance observations. We used the 2D-lattice (5⇥5 grid), 3D-lattice (5⇥5⇥5 grid) and Oilflow (100 points, 12 dimensions) datasets. The 2D and 3D lattices are simple "toy" datasets with a well-defined shape-which simplified visual comparison-while Oilflow is a widely-used benchmark. The distances were corrupted
Trustworthiness
Continuity
3
Oilflow
0
5
10
x 10 4
1
2
0.995
1
0
-1
0.99
0.985
-2
-3
-4
Samples
3D-lattice
2
3
5
Dimension
4
5
Samples
0.5
0
-0.5
-1
-1.5
-2
-2.5
10
1
2
3
4
5
Dimension
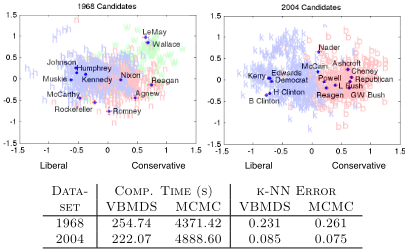
Figure 3: Political unfolding VBMDS-GP configurations for the 1968 (left) and 2004 (right) elections are visually similar to MCMC; the political figures are lined up along their main political philosophies and surrounded by their respective voters. (Bottom table) 10-NN errors are comparable to MCMC, but with up to a 22-fold speedup.
with three log-normal noise levels corresponding to one, two and three times the standard deviation of the inter-point distance distribution. As quantitative measures, we use Trustworthiness and Continuity scores [Venna and Kaski, 2006].
Fig. 2 shows sample embeddings for the 2D-lattice under moderately high noise as more observations were provided. Note the high embedding uncertainty when N = 1, suggesting the embedding is imprecise and inaccurate. As N increased, embedding uncertainty decreased and the layout became more accurate, as reflected in the higher Trustworthiness and Continuity scores. Very similar plots were obtained for 3D-lattice and Oilflow (data not shown due to space constraints). If no artificial noise is introduced on the Oilflow dataset, the scores obtained by VBMDS-GP (99.92, 99.94) are better than variational-GPLVM (99.72, 99.86), indicating the effect of distance preservation as an objective. Lastly, the highest values for L4 correspond to the true intrinsic dimensionality of the datasets; two and three for the 2D and 3D lattices respectively, and three/four for oilflow, in agreement with previous studies [Titsias and Lawrence, 2010]. This result motivates its use in selecting embedding complexity.
5.2 Political Unfolding Analysis
Next, we applied VBMDS-GP to political unfolding where there are two sets of points-one set of respondents and one set of stimuli (political figures)-with distance information only available between inter-set points. We used thermometer datasets-subjective preferences on a scale from zero to a hundred-for the 1968 (20,076 observations) and 2004 (15,644 observations) US elections.
The configurations obtained (Fig. 3) are visually similar to those obtained via slice-sampling [Bakker and Poole, 2013]; the candidates spread along a main axis of their political philosophies, with liberals on one end and conservatives on the other. The uncertainties give us additional indications of the "spread" along these axes. The optimized L4 values indicated the datasets are best described by two dimensional embeddings. As a quantitative comparison, the nearest-neighbor errors for the respondents (vote choices) are
Lower-Bound
1
0.995
0.99
0.985
0.98
0.975
0.98
1
0
Lower-Bound similar (error ⇡ 1 - 3%), but MCMC (a C program provided by the authors) required more than 70 mins, while VBMDSGP took only 3-4 minutes (10,000 iterations in MATLAB).
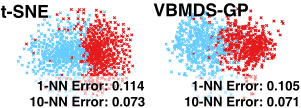
To investigate cluster separation, we transformed the distances into probabilities via exp(-dij◁σ2 p ) with σ2 p = 30 for comparison to t-SNE [Van der Maaten and Hinton, 2008]. Under this transformation, both methods produced comparable embeddings (Fig. 4); t-SNE's embedding was visually more symmetrical, but VBMDS-GP achieved lower k-NN errors. Unlike t-SNE, VBMDS-GP also produced point uncertainties, which when used to compute the 1-NN error (via expected distance) gave a lower error of 0.098.
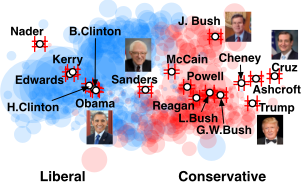
We constructed side information for each political figure consisting of PCA-reduced Bag-of-Words (BoW) features from Wikipedia entries, and used the VBMDS-GP to embed politicians that were not included in the 2004 survey. Although simple BoW features may only weakly indicate opinions on key issues, Fig. 5 shows the resultant embedding to be remarkably coherent: President Obama and Senator Sanders are close to their liberal base, while Jeb Bush, Senator Cruz, and Donald Trump are projected to the conservative region.
5.3 Multi-sensor Localization
The problem of multi-sensor localization arises in healthcare/environment monitoring where wireless ad-hoc sensor networks are deployed in a target areas without GPS (that can be too power-hungry, and perform poorly indoors). We applied VBMDS-GP to the Cricket dataset [Moore et al., 2004], which comprises range readings from real-world Cricketshardware platforms with ultrasonic transmitter and receivers. We used the ranging dataset as provided (5 clusters with missing and repeated distance readings) but filtered-out clearly erroneous readings, leaving a total of 35,312 distances. For side information, eight beacon nodes were associated with a signal propagationmodel sbi = log Ab (1000+dbi)↵b where Ab is the raw signal strength for beacon b, dbi is the distance between the nodes, and ↵b is the decay. These parameters were varied across the beacons and assumed unknown.
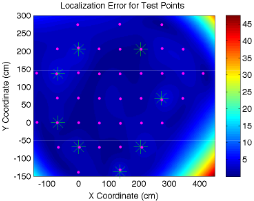
The localization error achieved by VBMDS-GP was 3.1 cm (no sparsity) and 3.19 cm (GPs using 20 inducing inputs), compared to 6.73 cm using robust quadrilaterals [Moore et al., 2004] and 6.63 cm for MDS-MAP [Shang et al., 2003]. Combining all the clusters and training with VBMDS-GP leads to a lower error of 2.21 cm, which we posit was due to the elimination of the cluster stitching which tends to increase error [Whitehouse and Culler, 2006]. To further evaluate the learnt mapping, we localized ⇡ 68k nodes in the target area only using the beacon features (Fig. 6). The average error was 3.47 cm; near the original sensor nodes, the error < 3 cm, with greater error and predictive uncertainty further away from the inducing inputs. The time required to localize all 68k nodes was 2.52s (3▷7⇥10-5 s per prediction). As such, the VBMDS-GP can be used for new or mobile nodes; once a mapping is obtained, precise localization with uncertainty estimation can be performed at low computational cost.
6 Summary and Conclusion
This paper presented a computationally efficient variational Bayesian MDS model that leverages upon side information and produces distance-preserving probabilistic embeddings. In the political unfolding task, VBMDS-GP produced embeddings comparable to MCMC at a fraction of the computational cost, and projected novel political candidates coherently to the embedding using only side information. Positive results were also observed for the localization task where the VBMDS-GP errors were half that of competing methods.
Given appropriate distance data, VBMDS-GP is applicable to a variety of tasks with side information, e.g., collaborative filtering with product description and user profiles, social network visualization with node attributes, and document/image clusteringwithmeta-data. In general, we expect VBMDS-GP to perform well when the distance observations (plus discrepancy due to dimensionality difference) are approximately lognormal. As future work, alternative likelihoods can be used within the Bayesian MDS framework to better suit other domains and to induce embeddings of different flavors.
Acknowledgments
Thank you to Scott Sanner for his helpful and constructive comments.
@inproceedings{ijcai2016p287,
  title     = {Distance-Preserving Probabilistic Embeddings with Side Information: Variational Bayesian Multidimensional Scaling Gaussian Process},
  author    = {Soh, Harold},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {2011--2016},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/287},
}
TY - CPAPER TI - Distance-Preserving Probabilistic Embeddings with Side Information: Variational Bayesian Multidimensional Scaling Gaussian Process AU - Soh, Harold T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 2011 EP - 2016 UR - https://ijcai.org/proceedings/2016/287 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





