
Budgeted Multi-Armed Bandits with Multiple Plays
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 2210-2215.
Abstract
We study the multi-play budgeted multi-armed bandit (MP-BMAB) problem, in which pulling an arm receives both a random reward and a random cost, and a player pulls L( ≥ 1) arms at each round. The player targets at maximizing her total expected reward under a budget constraint B for the pulling costs. We present a multiple ratio confidence bound policy: At each round, we first calculate a truncated upper (lower) confidence bound for the expected reward (cost) of each arm, and then pull the L arms with the maximum ratio of the sum of the upper confidence bounds of rewards to the sum of the lower confidence bounds of costs. We design 0-1 integer linear fractional programming oracle that can pick such the L arms within polynomial time. We prove that the regret of our policy is sublinear in general and is log-linear for certain parameter settings. We further consider two special cases of MP-BMABs: (1) We derive a lower bound for any consistent policy for MP-BMABs with Bernoulli reward and cost distributions. (2) We show that the proposed policy can also solve conventional budgeted MAB problem (a special case of MP-BMABs with L = 1) and provides better theoretical results than existing UCB-based pulling policies.
- [Agrawal et al., 2010] R Agrawal, M Hegde, and D Teneket- zis. Multi-armed bandit problems with multiple plays and switching cost. 2010.
- [Anantharam et al., 1987] Venkatachalam Anantharam, Pravin Varaiya, and Jean Walrand. Asymptotically effi- cient allocation rules for the multiarmed bandit problem with multiple plays-part i: Iid rewards. Automatic Control, IEEE Transactions on, 32(11):968-976, 1987.
- [Audibert et al., 2009] Jean-Yves Audibert, Rémi Munos, and Csaba Szepesvári. Exploration-exploitation tradeoff using variance estimates in multi-armed bandits. Theor. Comput. Sci., 410(19):1876-1902, 2009.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine learning, 47(2-3):235-256, 2002.
- [Auer, 2003] Peter Auer. Using confidence bounds for exploitation-exploration trade-offs. The Journal of Ma- chine Learning Research, 3:397-422, 2003.
- [Badanidiyuru et al., 2013] Ashwinkumar Badanidiyuru, Robert Kleinberg, and Aleksandrs Slivkins. Bandits with knapsacks. In FOCS. IEEE, 2013.
- [Bubeck and Cesa-Bianchi, 2012] Sébastien Bubeck and Ni- colo Cesa-Bianchi. Regret analysis of stochastic and non- stochastic multi-armed bandit problems. arXiv preprint arXiv:1204.5721, 2012.
- [Chen et al., 2013] Wei Chen, Yajun Wang, and Yang Yuan. Combinatorial multi-armed bandit: General framework and applications. In Proceedings of the 30th International Conference on Machine Learning, pages 151-159, 2013.
- [Ding et al., 2013] Wenkui Ding, Tao Qin, Xu-Dong Zhang, and Tie-Yan Liu. Multi-armed bandit with budget con- straint and variable costs. In Twenty-Seventh AAAI Con- ference on Artificial Intelligence, 2013.
- [Garivier and Cappé, 2011] Aurélien Garivier and Olivier Cappé. The kl-ucb algorithm for bounded stochastic ban- dits and beyond. arXiv preprint arXiv:1102.2490, 2011.
- [Ghosh and Hummel, 2013] Arpita Ghosh and Patrick Hum- mel. Learning and incentives in user-generated content: Multi-armed bandits with endogenous arms. In Proceed- ings of the 4th conference on Innovations in Theoretical Computer Science, pages 233-246. ACM, 2013.
- [Honda and Takemura, 2010] Junya Honda and Akimichi Takemura. An asymptotically optimal bandit algorithm for bounded support models. In COLT, pages 67-79. Citeseer, 2010.
- [Komiyama et al., 2015] Junpei Komiyama, Junya Honda, and Hiroshi Nakagawa. Optimal regret analysis of thomp- son sampling in stochastic multi-armed bandit problem with multiple plays. In ICML, 2015. [Kveton et al., 2015] Branislav Kveton, Zheng Wen, Azin Ashkan, and Csaba Szepesvári. Tight regret bounds for stochastic combinatorial semi-bandits. AISTATS, 2015.
- [Li et al., 2010] Lihong Li, Wei Chu, John Langford, and Robert E Schapire. A contextual-bandit approach to per- sonalized news article recommendation. In WWW, pages 661-670. ACM, 2010.
- [Liu and Zhao, 2010] Keqin Liu and Qing Zhao. Decentral- ized multi-armed bandit with multiple distributed players. In Information Theory and Applications Workshop (ITA), 2010, pages 1-10. IEEE, 2010.
- [Lueker, 1975] George S Lueker. Two NP-complete prob- lems in nonnegative integer programming. Princeton Uni- versity. Department of Electrical Engineering, 1975.
- [Mohri and Munoz, 2014] Mehryar Mohri and Andres Munoz. Optimal regret minimization in posted-price auctions with strategic buyers. In Advances in Neural Information Processing Systems, pages 1871-1879, 2014.
- [Seerengasamy and Jeyaraman, 2013] V Seerengasamy and K Jeyaraman. An alternative method to find the solution of zero one integer linear fractional programming problem with the help of ✓-matrix. International Journal of Scien- tific and Research Publications, 2013.
- [Tran-Thanh et al., 2010] Long Tran-Thanh, Archie Chap- man, Enrique Munoz de Cote, Alex Rogers, and Nicholas R. Jennings. Epsilon-first policies for budget lim- ited multi-armed bandits. In AAAI, 2010.
- [Tran-Thanh et al., 2012] Long Tran-Thanh, Archie C Chap- man, Alex Rogers, and Nicholas R Jennings. Knapsack based optimal policies for budget-limited multi-armed bandits. In AAAI, 2012.
- [Tran-Thanh et al., 2014] Long Tran-Thanh, Lampros C Stavrogiannis, Victor Naroditskiy, Valentin Robu, Nicholas R Jennings, and Peter Key. Efficient regret bounds for online bid optimisation in budget-limited sponsored search auctions. pages 809-818, 2014.
- [Vanchinathan et al., 2015] Hastagiri P Vanchinathan, An- dreas Marfurt, Charles-Antoine Robelin, Donald Koss- mann, and Andreas Krause. Discovering valuable items from massive data. In KDD. ACM, 2015.
- [Xia et al., 2015a] Yingce Xia, Wenkui Ding, Xu-Dong Zhang, Nenghai Yu, and Tao Qin. Budgeted bandit prob- lems with continuous random costs. In The 7th Asian Con- ference on Machine Learning, 2015.
- [Xia et al., 2015b] Yingce Xia, Haifang Li, Tao Qin, Neng- hai Yu, and Tie-Yan Liu. Thompson sampling for budgeted multi-armed bandits. In 24th International Joint Confer- ence on Artificial Intelligence, pages 3960-3966, 2015. IJCAI
- [Xia et al., 2016] Yingce Xia, Tao Qin, Nenghai Yu, and Tie- Yan Liu. Best action selection in a stochastic environment. In 15th International Conference on Autonomous Agents and Multiagent Systems, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Multi-armed bandits (MAB) are a typical sequential decision problem, in which a player receives a random reward by playing one of K arms from a slot machine at each round and wants to maximize her cumulated reward. Multiple real world applications have been modeled as MAB problems, such as auction mechanism design [Mohri and Munoz, 2014], search advertising [Tran-Thanh et al., 2014], UGC mechanism design [Ghosh and Hummel, 2013], and personalized recommendation [Li et al., 2010]. Many policies have been designed for MAB problems and studied from both theoretical and empirical perspectives, including UCB1, ✏n-GREEDY [Auer et al., 2002], LinRel [Auer, 2003], UCB-V [Audibert et al., 2009], DMED [Honda and Takemura, 2010], and KLUCB [Garivier and Capp´e, 2011]. A good survey on MAB can be found in [Bubeck and Cesa-Bianchi, 2012].
⇤This work was conducted at Microsoft Research Asia.
Recently, budgeted MABs have attracted much research attention. In budgeted MABs, playing an arm needs to pay a cost while receiving a reward, and the player targets at maximizing her cumulative reward under a budget constraint for the total costs. Different settings of costs have been studied in budgeted MABs. Deterministic costs were studied in [TranThanh et al., 2012]. [Vanchinathan et al., 2015] attacked an MAB related problem by taking both deterministic costs and the diversity of the selected items into consideration. UCB based algorithms were adapted to the random discrete cost setting [Ding et al., 2013] and random continuous cost setting [Xia et al., 2015a]. Thompson sampling algorithm for budgeted MAB was studied in [Xia et al., 2015b]. Besides minimizing the regret, the best arm identification problem for budgeted MAB was studied in [Xia et al., 2016].
Multiple-play MABs, in which the player pulls multiple arms at each round, have been studied in conventional settings without considering budget [Anantharam et al., 1987; Agrawal et al., 2010; Komiyama et al., 2015; Liu and Zhao, 2010; Chen et al., 2013]. In some applications, a decision maker needs to take multiple actions at each round and consider a budget constraint. For example, consider an advertiser who creates an ad campaign to promote her products in a search engine. To participate in search ad auctions, she needs to choose multiple keywords for her campaign and set a monthly/quarterly budget. Since each keyword (together with a bid price) can be regarded as an arm [Ding et al., 2013], this keyword selection and bid optimization problem can be modeled as a budgeted MAB with multiple plays. In this work, we study this new setting, the Multiple-Play Budgeted Multiarmed Bandit (denote as MP-BMAB) problem. For simplicity, we refer the simple case of the budgeted MAB, playing a single arm at each round, as Single-Play Budgeted Multiarmed Bandit (denoted as SP-BMAB).
Consider a bandit with K arms in total and the player needs to pull L ≥ 1 different arms at each round. There are (KL ) different ways of pulling L different arms, and the number could be of order O(2K ) in the worst case. Therefore, we need to carefully design policies that can efficiently deal with large number of possible pullings. Our work can be summarized from the following three aspects:
Policy Design: Intuitively, a good policy for MP-BMABs should try to pull the L arms with the maximum ratio of the sum of the expected rewards to the sum of the expected costs. Since the reward and cost distributions of all the arms are unknown, the policy needs to allocate necessary explorations to all the arms. We design an efficient policy for the MP-BMAB problem, called Multiple Ratio Confidence Bound policy (denoted as MRCB), which works as follows. For each arm, we introduce a truncated upper confidence bound for the estimated expected reward and a truncated lower confidence bound for the estimated expected cost. A hyper parameter is introduced to the confidence bound, which brings flexibility to the policy. At each round, we pull the L arms with the maximum ratio of the sum of the upper bounds of rewards to the sum of the lower bounds of costs. How to find such L arms with the maximum ratio is an 0-1 integer linear fractional program (denoted as 0-1 ILFP) [Seerengasamy and Jeyaraman, 2013]. We design an efficient algorithm that can find the optimal solution of the 0-1 ILFP in our setting within polynomial time.
Theoretical Analysis: We conduct theoretical analysis on MRCB, and show that it enjoys a sublinear regret bound with respect to budget B. By properly setting the hyper parameter, we show that the policy theoretically achieves a log-linear regret. Comparing with conventional MABs, there are two challenges to analyze MRCB: (1) One needs to pull L different arms at each round (for simplicity, we say any L different arms constitute a super arm) and there are exponential number of possible super arms, which might bring the combinatorial number into the regret bound and make the bound very loose. (2) The randomness of both the rewards and costs brings difficulties when decomposing the probabilities that suboptimal super arms are pulled 1 . To address the first challenge, we carefully divide the exponential number of suboptimal super arms into K subsets and design intermediate events related to the pulling time of each super arm in each subset. Doing so we can eliminate the affects brought by the exponential number of super arms. To address the second one, we introduce the δ-gap in Eqn.(11a), based on which we can separate the ratio related terms which depend on both rewards and costs into terms that depend on rewards only and costs only.
Special Cases: We further study two special cases of MPBMABs. First, for Bernoulli MP-BMABs (whose rewards and costs are either 0 or 1), we give a lower bound to any consistent policy and show that our proposed policy can match the lower bound in terms of the order of B. Second, for conventional budgeted MABs (i.e., SP-BMABs), we show that our policy can be directly applied and achieves a better regret bound than existing UCB based policies [Ding et al., 2013]. We also provide a lower bound for SP-BMABs, which is missing in the literature.
1 The super arms which do not have the maximum ratio of the sum of the expected rewards to the sum of expected costs are suboptimal.
2 The Problem
An MP-BMAB problem can be described as follows. Given a slot machine with K arms (K ≥ 2), at each round, the player needs to pull L(≥ 1) different arms of the bandit. Denote the set of arms pulled at round t as It. For each pulled arm i 2 [K] at round t (let [K] denote the set ¶1↪ 2↪ · · · ↪K♦), she needs to pay a random cost ci(t) and receives a random reward ri(t). Both ci(t) and ri(t) are drawn from distributions supported in [0↪ 1]. We study the semi-bandit setting [Kveton et al., 2015], in which the player can only observe ri(t) and ci(t) for pulled arms, i.e., for all i 2 It. The player can keep pulling until her budget, B, runs out. B is a positive number and does not need to be known to the player in advance.
Following the common practice in standard MABs, we assume the independence between arms and rounds: the rewards and costs of an arm are independent of any other arm, and the rewards (and costs) of arm i at different rounds are independently drawn from the same distribution with expectation θri (and θci ). For ease of reference, denote the vector (θr1 ↪ θr2 ↪ · · · ↪ θrK ) as θr , and so for θc . Note that we do not assume that the rewards of an arm are independent of its costs. Without loss of generality, we assume 0 < θri ↪ θci < 1 for all i 2 [K]. The player wants to minimize the regret, which is usually defined as the differences between R⇤ , the maximum expect cumulative reward that a pulling policy can obtain when the reward/cost distributions of all the arms are known, and the expected reward that a policy can obtain, both under the budget constraint. Mathematically,
where Bt is the remaining budget at round t, i.e., Bt = B - Pts=1 Pi2Is ci(s), and I¶·♦ is the indicator function. I¶E♦ = 1 if the event E is true; otherwise, 0.
3 Pulling Policy
It is hard to find the optimal policy for MP-BMABs. Even for a simplified setting, in which the reward and cost of each arm are deterministic and L = 1, the problem is an unbounded knapsack problem, which is NP-hard [Lueker, 1975]. For the semi-bandit setting, this problem becomes even harder. To solve the MP-BMAB problem, in this section, we first consider a simple case with known reward and cost distributions for all the arms, and show that a simple greedy policy Mg can obtain almost the same expected reward as R⇤ . Then we design a pulling policy for the setting with unknown reward and cost distributions by leveragingMg.
3.1 Mg for Known Distributions
Remind that any L different arms from the K candidates constitute a super arm. Let CK L denote the set of all the super arms, which is mathematically defined as follows.
Without loss of generality, assume I⇤ is unique. Define %⇤L as (Pk2I⇤ θrk )◁(Pk2I⇤ θck ).
The greedy policyMg is shown in Algorithm 1. Lemma 1 shows that Mg is close to the optimal policy for the case with known reward/cost distributions, and therefore we call I⇤ the nearly-optimal super arm.
Algorithm 1: Mg for Known Distributions
- 2 For any arm i 2 [K], calculate the expected reward θri and expected cost θci ; find the I⇤ of the bandit in (2);
- 1 Input: The reward and cost distributions of the K arms; the budget B; L 2 [K];
- 3 Keep pulling the L arms in I⇤, until the budget runs out.
Lemma 1 When the reward and cost distributions of all the arms are known, we have R⇤ (B + L)%⇤L and the expected reward ofMg is at least (B -L)%⇤L.
Due to space limitations, we leave the proof of Lemma 1 to Appendix 2 A. Lemma 1 tells that the gap between R⇤ and the expected reward of Mg is at most 2L%⇤L, which is very small when B is sufficiently large.
Step 2 of Algorithm 1 needs to find the I⇤ defined in (2), which is actually a 0-1 Integer Linear Fractional Programming problem defined as follows.
where a and b are K-element vectors with the i-th element ai > 0↪ bi ≥ 0 for any i 2 [K]. We design a 0-1 ILFP Oracle O(a↪ b↪ L) that can efficiently solve the optimization problem in (3). The oracle is shown in Algorithm 2.
Algorithm 2: 0-1 ILFP Oracle O(a↪ b↪ L)
- 2 Boundary Cases: Denote Z0 = ¶i♣bi = 0↪ 8i 2 [K]♦. If ♣Z0♣ ≥ L, then randomly return L elements in Z0; Else if L is 1, return argmaxi (ai◁bi) for any i 2 [K] directly; Else, go to the next step;
- 1 Input: Vectors a and b with ai > 0↪ bi ≥ 08i 2 [K]; L 2 [K];
- 3 Solve the LP problem marked with (4) by Interior Point Method. Denote the solution as y⇤ and z⇤ .
- 4 Let I = ¶i♣y⇤ i = z⇤ ; i 2 [K]♦↪F = ¶i♣0 < y⇤ i < z⇤ ; i 2 [K]♦; If ♣I♣ = L, return I; otherwise, pick any L- ♣I♣ elements fromF forming F 0 and return I [F 0 .
Lemma 2 The O(a↪ b↪ L) in Algorithm 2 can output the optimal solution of (3) within polynomial time 3 .
The proof of Lemma 2 is constructive: (1) Relax the 0-1 integer constraints to continuous ones, (2) solve the relaxed linear fractional programming, and then (3) convert the fractional solutions to integer ones. Complete proof is in Appendix B.
2 All the appendices are included in the online full version of this work, which is at http://goo.gl/ewyX9c.
3 We follow the common practice in combinatorial optimization literature that the "polynomial time" means "polynomial time in the number of bits of precision in which the inputs are specified".
3.2 Multiple Ratio Confidence Bound Policy
Now we turn to the MP-BMAB problem with unknown reward/cost distributions. We can only observe the rewards/costs of the pulled arms at each round. Our idea is simple and straightforward: We estimate the expected reward/cost of each arm using historical observations and then apply Algorithm 2 with estimated expected rewards/costs as input to select the pulled arms at each round.
For any i 2 [K], let Ti(t), ˆθri (t), ˆθci (t) and E i↪t denote the number of pulling rounds, the empirical average reward and cost, and a confidence term of arm i at round t respectively:
where is a positive hyper parameter, which brings flexibility 4 to our policy.
Note that for each arm, we do not directly replace the expected reward and cost by the empirical average reward and cost. Instead, we take the uncertainty of the estimation into consideration. Define ˜θri (t) and ˜θci (t) as the truncated upper confidence bound for the empirical average reward (see (5)) and truncated lower confidence bound for the empirical average cost (see (6)) respectively.
Our proposed policy, Multiple Ratio Confidence Bound policy (briefly denoted as MRCB), is shown in Algorithm 3, in which ˜θr (t) is a K-dimensional vector 5 with the i-th element ˜θri (t), and so for ˜θc (t).
Algorithm 3: Multiple Ratio Confidence Bound (MRCB)
- 1 Input: hyper parameter > 0, the budget B; L 2 [K]; 2 for t ! 1 : dK◁Le do 3 Pull arms ¶([(t-1)L+j -1] mod K)+1♣j 2 [L]♦; 4 for t ! dK◁Le +1 : 1do 5 Update the Ti(t), ˆθri (t), ˆθci (t), ˜θri (t), ˜θci (t) for any i; 6 Pull the arms output by O(˜θr (t)↪ ˜θc (t)↪ L); update Bt; if Bt ≥ 0, obtain the reward; else, return;
4 Theoretical Analysis
In this section we theoretically analyze and upper bound the regret of the MRCB policy.
We first define some notations. (1) Let Cs denote CK L ∩¶I⇤♦. (2) For any i 2 [K], let Si denote ¶I♣I 2 Cs↪ i 2 I♦. (3) For any i 2 [K], define
4 This trick has also been used in [Li et al., 2010].
5 Keep in mind that both ˜θr (t) and ˜θc (t) depend on the .
Define B = ¶i♣i 2 [K]↪ ∆imin > 0♦. (4) TL(B) = b2B◁(Lθcmin )c, where θcmin = mini2[K] θci . (5) XL(B) = O([B◁(Lθcmin )] exp¶-(Bθcmin )◁2♦).
The above notations can be interpreted as follows. (1) Cs can be regarded as the set of all suboptimal super arms, since it is very likely that these arms are not as good as the nearoptimal arm I⇤ in terms of the ratio of expected rewards to expected costs. (2) Si is the collection of suboptimal super arms containing arm i. (3) ∆imin and ∆imax are two gaps measuring the suboptimality of the super arms in Si. B is a collection of "bad" arms, which can lead to regret after pulling. (4) TL(B) can be seen as the pseudo stopping time of the bandit, since when B is large, the probability that the pulling rounds of an MP-BMAB can exceed TL(B), bounded by XL(B), is very small. Mathematically,
Define ⇣(TL(B)) = PTL(B) t=1 (log2(t) +1)t- ▷ One can verify that when > 1, ⇣(TL(B)) can be bounded by a term depending on only; when = 1, ⇣(TL(B)) is of order O(ln2 (B)); when < 1, ⇣(TL(B)) is of order O(B1- ln(B)◁(1 - )). (See Appendix D for details.)
Note XL(B) decreases exponentially w.r.t. B. The proof of the above inequality is left in Appendix C. In our MP-BMAB problem, the stopping time is not given in advance like those in [Auer et al., 2002; Badanidiyuru et al., 2013]; instead, the stopping time is controlled by the budget B. To leverage the proof techniques from conventional bandits, we introduce the pseudo stopping time TL(B). We will see how to use it later.
We can upper bound the regret of our policy as follows.
Theorem 3 The regret of MRCB is upper bounded by
When 2 (0↪ 1), the regret shown in (9) can be written as 'sT 1- L (B) ln(TL(B))◁(1 - ) + o(TL(B)), which is sublinear in terms of TL(B), and thus B. When > 1, the regret improves to '◆ ln TL(B)+O(1), which is of order O( ln B). Proof outline: The proof of Theorem 3 is quite technical. Here we only give a proof sketch. The omitted derivation details are left in Appendix E.
where '◆ = (%⇤L + 1)2L2 (p + 1)2 Pi2B (2◁∆imin - 1◁∆imax ), 's = 2L Pi2B ∆imax , and '0 = 0▷5(L - 1)'◆ ln K + 's + L%⇤LXL(B) + 2L%⇤L + 2 Pi2B ∆imax .
◦ Step 1: Bridge the regret and the expected pulling number of each suboptimal super arm. With some derivations, we can get that the regret can be bounded as
where for any I 2 Cs, ∆I is defined as (Pk2I θck )[%⇤L - (Pk2I θrk )◁(Pk2I θck )], NI is the pulling number of super arm I from round 1 to round TL(B). The insight behind (10) is very intuitive: if the player pulls a suboptimal super arm I once, the expected cost is Pk2I θck ; if she spends such cost on the near optimal super arm, she can gain ∆I more reward. (10) frees us from the randomness of the stopping time, and allows us to only consider the expected pulling number of suboptimal arms before round TL(B), which is deterministic (even though the budget might run out before it).
◦ Step 2: Bridge the regret and each arm. It is not convenient to work on the super arms directly. Therefore, we need to further decompose (10).
Let Ki denote that number of super arms in Si for any i 2 [K], and S(i↪ j) denote one super arm in Si indexed by j 2 [Ki]. Assume the super arms in Si are sorted by the order ∆S(i↪1) ≥ ∆S(i↪2) ≥ · · · ≥ ∆S(i↪Ki) . For simplicity of use, denote ∆S(i↪j) as ∆i↪j .
For any suboptimal super arm S(i↪ j), define the δ-gap δi↪j (γ) in Eqn.(11-a), which can be seen as a weighted version of ∆i↪j . We can verify that the gap satisfies Eqn.(11-b).
In the analysis of the upper bound of the regret, we only need to consider the case of 6 γ = 1. For ease of reference, let δi↪j denote δi↪j (1).
Define fi↪j = L2 (p + 1)2 ln[pKL-1TL(B)]◁(δi↪j )2 . According to [Chen et al., 2013], the PI2Cs ∆I E¶NI♦ of (10) can be bounded by Pi2B Ri, in which Ri is
where t0 = dK◁Le + 1.
◦ Step 3: Bound the E¶·♦ in (12). For ease of reference, let Ui↪j(t) denote the event ¶It = S(i↪ j)↪ 8k 2 It Tk(t - 1) > bfi↪jc♦ in (12). Define the event Qo(t) as:
Accordingly, the E¶·♦ in (12) can be decomposed as:
where Qo(t) means that the event Qo(t) does not hold. Step 3-1: Bound (14). Since Ui↪j(t) are disjoint for different j 2 [Ki], we have that PKi j=1 I¶Ui↪j (t)↪ Qo(t)♦ I¶Qo(t)♦. Since we do not need to consider the randomness of the stopping time, we can apply Hoeffding's maximal inequality and union bound, and obtain that
Thus, (14) is bounded by 2L∆imax ⇣(TL(B)). Step 3-2: Bound (15). If super arm S(i↪ j) is pulled where i 2 B and j 2 [Ki], conditioned on Qo(t), we know that P¶Ui↪j(t)↪ Qo(t)♦ is upper bounded by With some derivations, for any k 2 S(i↪ j), we have
6 The case of γ 6= 1 will be considered when analyzing the lower bound of MP-BMAB in the next section.
Therefore, P¶Ui↪j(t)↪Qo(t)♦ (2L)◁[KL-1TL(B)]. Accordingly, (15) can be bounded by 2L∆imax .
According to the above three steps, by combining (10), (12), the bound of (14) in Step 3-1, and the result of (15) in Step 3-2, we can eventually get Theorem 3. ⇤
5 Special Cases
In this section, we consider two special cases of MP-BMABs: the Bernoulli MP-BMABs, in which the reward and cost distributions of all the arms are Bernoulli, and the SP-BMABs, in which the player can only pull L = 1 arm at each round.
5.1 Bernoulli MP-BMABs
In this subsection, we present a lower bound for the regret of any consistent policy (defined later) for Bernoulli MPBMABs and compare it with the regret of MRCB.
For any policy w, let Γ w k (T) denote the pulling number of arm k 2 [K] in the first T rounds, and Γ w I (T) for super arm I 2 CK L , where T 2 Z+. If PI2Cs E¶Γ w I (T)♦ = o(T a ) holds for any a 2 (0↪ 1) and any bandit, we say policy w is consistent. According to the analysis in Section 4, we can get that the regret of any consistent policy is sublinear to the pseudo stopping time TL(B), and so to the budget B.
Since the costs are no larger than 1, the stopping time of a policy is at least B◁L (assume B◁L is an integer for simplicity). The regret of the first B◁L rounds is certainly a lower bound of the total regret, thus we will only consider the regret in these rounds. Let kl(x↪ y) denote the KL divergence of two Bernoulli distributions with parameters x and y:
For ease of reference, define δimin (γ) = minj2[Ki] δi↪j (γ) for any i ◁2 I⇤. Define the following optimization problem:
As shown in Appendix F.1 and F.2, we can prove that: (1) the feasible set of (19) is non-empty; (2) the optimal solution of (19) is an interior point of its constraint set. Thus, the optimal value exists and is strictly positive. Denote the optimal value of (19) as L⇤i .
Theorem 4 For Bernoulli MP-BMABs, if the rewards are independent to the costs for each arm, for any consistent policy w (i.e., PI2Cs E¶Γ w I (T)♦ = o(T a ) holds for any a 2 (0↪ 1) and T 2 Z+), we have that for any i ◁2 I⇤ and ✏ > 0,
and liminfB!1E[Γ w i (B◁L)]◁[ln(B◁L)] ≥ 1◁L⇤i .
From Theorem 4, we can get that for Bernoulli MP-BMABs, the pulling time of arm i ◁2 I⇤ for any consistent policy is at least ⌦(ln(B◁L)◁L⇤i ). After some derivations, we can get that the regret is ⌦(Pi◁2I⇤ (∆imin ◁L⇤i ) ln(B◁L)). The theorem can be proved by using the change-of-measure techniques and large number laws, as shown in Appendix F.3.
First, we can see that, for Bernoulli bandits, the upper bound of the regret of MRCB is O( lnB) when > 1, which matches the lower bound in terms of the order of B.
Second, we make some discussion about the coefficients of lnB. We specify MRCB by setting = 2. For ease of reference, denote the upper bound and lower bound as O(o lnB) and ⌦(! lnB) respectively. Similar to the UCB-based policies for conventional MABs (without budget constraints), our MRCB cannot match the lower bound perfectly, i.e., o > !. The following example shows that o in the upper bound of MRCB and ! in the lower bound share similar trends.
Example 5 We study the relationship between the regret and the ratio gap ∆imin 8i 2 B for an MP-BMAB. Suppose p 2 (0↪ 0▷5). Consider a Bernoulli bandit with θrj ↪ θcj 2 [p↪ 1 - p] 8j 2 [K] and ∆imin < p◁2 8i 2 B. In this case, we have
5.2 Single-Play BudgetedMAB
(a) o = Pi2B L2 ◁(p2∆imin ); (b) ! = Pi◁2I⇤ p2 ◁∆imin . That is, the coefficients of lnB in both the upper and lower bounds of the regret are linear to Pi◁2I⇤ 1◁∆imin .
Since SP-BMABs are a special case of MP-BMABs with L = 1, our MRCB policy (Algorithm 3) can be directly applied.
While applying Algorithm 3 to the SP-BMAB problem, I⇤ degenerates to the arm with the maximum ratio of the expected reward to the expected cost, i.e., i⇤ = argmaxi2[K] θri ◁θci and %⇤1 = θri⇤ ◁θci⇤ . For any i 6= i⇤, (a) ∆imax equals ∆imin and we denote them as ∆i = θci %⇤1 - θri ; (b) δimin (γ) degenerates to δi (γ) = ∆i ◁(γ%⇤1 + 1); (c) the optimization problem of (19) degenerates as follows:
One can verify the existence of the optimal solution and optimal value of (20). Denote the optimal value as L⇤⇤ i . Theorem 3 and 4 degenerate to the following two corollaries:
Corollary 6 For SP-BMABs, the regret of MRCB is upper bounded by
+4 Pi6=i⇤ ∆i + [2 + X1(B)]%⇤1 , where the T1(B) and X1(B) are obtained by setting the L's in TL(B) and XL(B) (defined at the beginning of Section 4) as 1.
Corollary 7 For Bernoulli SP-BMABs, if the rewards are independent to the costs for each arm, for any consistent policy w (i.e., Pi6=i⇤ E¶Γ w i (T)♦ = o(T a ) holds for any a 2 (0↪ 1) and T 2 Z+), we have that for any i 6= i⇤ and ✏ > 0,
Corollary 7 tells that the regret for Bernoulli SP-BMAB is at least ⌦(Pi6=i⇤ (∆i ◁L⇤⇤ i ) lnB). So far as we know, it is the first non-trivial lower bound for SP-BMABs. Similar to the Example 5, for SP-BMABs, the coefficients of lnB in both the upper bound of MRCB's regret and the lower bound of the regret of any consistent policy are linear to Pi6=i⇤ 1◁∆i .
SP-BMABs with random costs have been studied in [Ding et al., 2013]. Compared with the above literature, MRCB has two advantages: (1) Since there is a hyper parameter of our policy, by carefully setting the parameter, the empirical performance of our policy can outperform previous algorithms (see Section 6). (2) The theoretical guarantees of our policy are better than previous UCB-based policies. For example, Corollary 6 outperforms the regret bound in [Ding et al., 2013]. (See Appendix G for the details.)
6 Empirical Evaluations
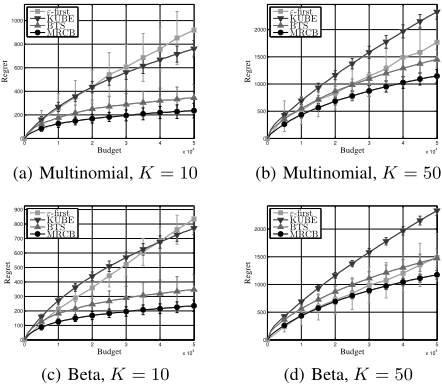
We conducted a set of numerical simulations to test the empirical performance of our policy. We compared with the following baselines. (1) The "-first policy first pulls the arms one by one when the spent budget is less than "B; after that we have two schemes to recommend L arms: Scheme T always pulling the top L arms with the largest average reward to average cost ratio, and Scheme R always pulling the L arms with the maximum ratio of the sum of average rewards to the sum of average costs. We followed the practice in [Tran-Thanh et al., 2010; Xia et al., 2015b] to set " = 0▷1. (2) Fractional KUBE [Tran-Thanh et al., 2012] with both schemes T and R. (3) BTS policy [Xia et al., 2015b] with schemes T and R. (4) the UCB-BV1 [Ding et al., 2013] with scheme T only, since the confidence term is added to the ratio of the average rewards to average costs, which makes it hard to be associated with scheme R. For "-first, we set the budget as ¶5K↪ 10K↪ 15K↪ · · · ↪ 50K♦; for the other policies, we set the budget as 50K and record the regret at each budget.
We simulated the bandit with two distributions: one with multinomial distribution, and the other with beta distribution. For each distribution, we simulated a 10-armed bandit and a 50-armed bandit. Detailed parameters of the distributions are left in Appendix H.1 due to limited space. We individually run each policy under each setting for 100 times and report the average regret and standard derivation over the 100 runs.
MRCB has a hyper parameter . We searched the in the set ¶2-10 ↪ 2-7 ↪ 2-4 ↪ 21 ♦ and found that = 2-4 worked well for most cases. Therefore, we fix 2-4 in the following experiments. Though asymptotically MRCB enjoys log-linear regret when > 1, it is not good to set large values for since B is limited in our experiments.
The results of the first three baselines with different schemes are shown in Table 1. It is obvious that Scheme R is better than Scheme T. Thus, in the following experiments, we will only show the results for Scheme R. We will not show the regrets for UCB-BV1 neither since they are too large.
The average regret and the standard deviation of each policy w.r.t different K and different reward/cost distributions are shown in Figure 1. We can see that our MRCB has clear advantages over the 3 baselines: It achieves smaller regrets and lower standard derivations. When the number of arms increases from 10 to 50, the regrets of all the policies increase. This is in accord with our intuition, since more candidate arms can make the nearly-optimal super arm harder to be found.
| "-first | KUBE | BTS | UCB-BV1 | |
|---|---|---|---|---|
| Scheme T | 1159▷0 | 831▷3 | 568▷5 | 2273▷8 |
| Scheme R | 919▷4 | 760▷8 | 344▷3 | - - - |
We also tested the performance of MRCB under the SPBMAB setting (i.e., L = 1). The results are in Table 2, which are carried out on the bandits with multinomial reward/cost distributions and B = 50K. The average regrets and the standard derivations are reported. Again, MRCB performs the best, which shows the MRCB can handle the SP-BMAB. Additional experiments can be found at Appendix H.2.
| 10-armed bandit | 50-armed bandit | |
|---|---|---|
| "-first | 2183▷5◦51▷9 | 2403▷8 ◦ 54▷9 |
| KUBE | 552▷9◦34▷4 | 2722▷3 ◦ 66▷9 |
| BTS | 226▷9 ◦ 38▷3 | 1182▷0 ◦ 93▷6 |
| MRCB |
MRCB 103▷3◦13▷5 521▷9◦31▷1
7 Conclusion and FutureWork
In this work, we studied the MP-BMAB problem and proposed a policy for it. The policy theoretically enjoys a sublinear regret (log-linear under some conditions) and empirically outperforms several baselines in different settings.
There are several aspects to study in the future for MPBMABs. (1) multi-play budgeted linear/contextual bandit, in which each arm is associated with a multi-dimensional feature vector, is an attractive topic; (2) the distribution-free upper/lower bound of MP-BMABs is still unknown and remains to be explored.
Acknowledgments
This work is partially supported by National Natural Science Foundation of China (NSFC, NO.61371192).
@inproceedings{ijcai2016p315,
  title     = {Budgeted Multi-Armed Bandits with Multiple Plays},
  author    = {Xia, Yingce and Qin, Tao and Ma, Weidong and Yu, Nenghai and Liu, Tie-Yan},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {2210--2215},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/315},
}
TY - CPAPER TI - Budgeted Multi-Armed Bandits with Multiple Plays AU - Xia, Yingce AU - Qin, Tao AU - Ma, Weidong AU - Yu, Nenghai AU - Liu, Tie-Yan T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 2210 EP - 2215 UR - https://ijcai.org/proceedings/2016/315 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





