
Exploiting Problem Structure in Combinatorial Landscapes: A Case Study on Pure Mathematics Application
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 2683-2688.
Abstract
In this paper, we present a method using AI techniques to solve a case of pure mathematics applications for finding narrow admissible tuples. The original problem is formulated into a combinatorial optimization problem. In particular, we show how to exploit the local search structure to formulate the problem landscape for dramatic reductions in search space and for non-trivial elimination in search barriers, and then to realize intelligent search strategies for effectively escaping from local minima. Experimental results demonstrate that the proposed method is able to efficiently find best known solutions. This research sheds light on exploiting the local problem structure for an efficient search in combinatorial landscapes as an application of AI to a new problem domain.
- [Ansótegui et al., 2015] C. Ansótegui, F. Didier, and J. Gabas. Exploiting the structure of unsatisfiable cores in MaxSAT. In IJCAI, pages 283-289, 2015. IJCAI
- [Benton et al., 2010] J. Benton, K. Talamadupula, P. Eye- rich, et al. G-value plateaus: A challenge for planning. In ICAPS, pages 259-262, 2010.
- [Billinger et al., 2014] S. Billinger, N. Stieglitz, and T. R. Schumacher. Search on rugged landscapes: An experi- mental study. Organization Science, 25(1):93-108, 2014.
- [Bjorner and Narodytska, 2015] N. Bjorner and N. Narodyt- ska. Maximum satisfiability using cores and correction sets. In IJCAI, pages 246-252, 2015. IJCAI
- [Bonet and Geffner, 2001] B. Bonet and H. Geffner. Plan- ning as heuristic search. Artificial Intelligence, 129(1):5- 33, 2001.
- [Cheeseman et al., 1991] P. Cheeseman, B. Kanefsky, and W. M. Taylor. Where the really hard problems are. In IJCAI, pages 331-340, 1991. IJCAI
- [Clark and Jarvis, 2001] David Clark and Norman Jarvis. Dense admissible sequences. Mathematics of Computa- tion, 70(236):1713-1718, 2001.
- [Collins, 2006] M. Collins. Finding needles in haystacks is harder with neutrality. Genetic Programming and Evolv- able Machines, 7(2):131-144, 2006.
- [Culberson and Gent, 2001] J. Culberson and I. Gent. Frozen development in graph coloring. Theoretical Computer Science, 265(1):227-264, 2001.
- [Dubois and Dequen, 2001] O. Dubois and G. Dequen. A backbone-search heuristic for efficient solving of hard 3- SAT formulae. In IJCAI, pages 248-253, 2001. IJCAI
- [Ford et al., 2015] K. Ford, J. Maynard, and T. Tao. Chains of large gaps between primes. arXiv:1511.04468, 2015.
- [Frank et al., 1997] J. Frank, P. Cheeseman, and J. Stutz. When gravity fails: Local search topology. Journal of Ar- tificial Intelligence Research, 7:249-281, 1997.
- [Friesen and Domingos, 2015] A. L. Friesen and P. Domin- gos. Recursive decomposition for nonconvex optimiza- tion. In IJCAI, pages 253-259, 2015.
- [Goldston et al., 2009] D. A. Goldston, J. Pintz, and C. Y. Yíldírím. Primes in tuples I. Annals of Mathematics, 170(2):819-862, 2009.
- [Gomes and Selman, 2001] C. P. Gomes and B. Selman. Al- gorithm portfolios. Artificial Intelligence, 126(1):43-62, 2001.
- [Gordon and Rodemich, 1998] D. Gordon and G. Rodemich. Dense admissible sets. In International Symposium on Al- gorithmic Number Theory, pages 216-225, 1998.
- [Hensley and Richards, 1974] D. Hensley and I. Richards. Primes in intervals. Acta Arithmetica, 4(25):375-391, 1974.
- [Hoffmann, 2001] J. Hoffmann. Local search topology in planning benchmarks: An empirical analysis. In IJCAI, pages 453-458, 2001. IJCAI
- [Hoos and Stützle, 2004] H. H. Hoos and T. Stützle. Stochastic Local Search: Foundations & Applications. Elsevier, 2004.
- [Hutter et al., 2011] F. Hutter, H. H. Hoos, and K. Leyton- Brown. Sequential model-based optimization for general algorithm configuration. In LION, pages 507-523. 2011.
- [Kirkpatrick et al., 1983] S. Kirkpatrick, C. D. Gelatt, M. P. Vecchi, et al. Optimization by simulated annealing. Sci- ence, 220(4598):671-680, 1983.
- [Maynard, 2015] J. Maynard. Small gaps between primes. Annals of Mathematics, 181(1):383-413, 2015.
- [Mears and de la Banda, 2015] C. Mears and M. G. de la Banda. Towards automatic dominance breaking for con- straint optimization problems. In IJCAI, pages 360-366, 2015. IJCAI
- [Nowicki and Smutnicki, 1996] E. Nowicki and C. Smut- nicki. A fast taboo search algorithm for the job shop prob- lem. Management science, 42(6):797-813, 1996.
- [Polymath, 2014a] D. H. J. Polymath. New equidistribu- tion estimates of Zhang type. Algebra & Number Theory, 8(9):2067-2199, 2014.
- [Polymath, 2014b] D. H. J. Polymath. Variants of the selberg sieve, and bounded intervals containing many primes. Re- search in the Mathematical Sciences, 1(1):1-83, 2014.
- [Reidys and Stadler, 2002] C. Reidys and P. Stadler. Combi- natorial landscapes. SIAM Review, 44(1):3-54, 2002.
- [Schiavinotto and Stützle, 2007] T. Schiavinotto and T. Stützle. A review of metrics on permutations for search landscape analysis. Computers & Operations Research, 34(10):3143-3153, 2007.
- [Slaney and Walsh, 2001] J. Slaney and T. Walsh. Back- bones in optimization and approximation. In IJCAI, pages 254-259, 2001. IJCAI
- [Sutherland, 2015] A. V. Sutherland. Narrow Admissible Tu- ples. http://math.mit.edu/ ⇠ primegaps, 2015. Link
- [Sutton et al., 2010] A. Sutton, A. Howe, and L. Whitley. Di- rected plateau search for MAX-k-SAT. In Annual Sympo- sium on Combinatorial Search, pages 90-97, 2010.
- [Tayarani-N and Prugel-Bennett, 2014] M.-H. Tayarani-N and A. Prugel-Bennett. On the landscape of combi- natorial optimization problems. IEEE Transactions on Evolutionary Computation, 18(3):420-434, 2014.
- [Watson et al., 2003] J.-P. Watson, J. Beck, A. Howe, and L. Whitley. Problem difficulty for tabu search in job-shop scheduling. Artificial Intelligence, 143(2):189-217, 2003.
- [Zhang, 2004] W. Zhang. Phase transitions and backbones of the asymmetric traveling salesman problem. Journal of Artificial Intelligence Research, 21:471-497, 2004.
- [Zhang, 2014] Y. Zhang. Bounded gaps between primes. An- nals of Mathematics, 179(3):1121-1174, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
AI techniques have shown their advantages on solving different combinatorial optimization problems, such as satisfiability [Sutton et al., 2010; Dubois and Dequen, 2001; Bjorner and Narodytska, 2015; Ans´otegui et al., 2015], traveling salesman problem [Zhang, 2004], graph coloring [Culberson and Gent, 2001], job shop scheduling [Watson et al., 2003], and automated planning [Bonet and Geffner, 2001].
These problems can be generalized into the concept of combinatorial landscapes [Reidys and Stadler, 2002; Schiavinotto and St¨utzle, 2007; Tayarani-N and Prugel-Bennett, 2014], and problem solving can be cast to a search over a space of states. Such problems often are very hard [Cheeseman et al., 1991]. In order to pursue an efficient search, it is vital to develop techniques to identify problem features and of exploiting the local search structure [Frank et al., 1997; Hoffmann, 2001; Hoos and St¨utzle, 2004]. In particular, it is important to reduce and decompose the problem preserving structural features that enable heuristic search and with the effective problem size factored out [Slaney and Walsh, 2001; Mears and de la Banda, 2015]. It is also significant to tackle ruggedness [Billinger et al., 2014] and neutrality (plateaus) [Collins, 2006; Benton et al., 2010] in the landscapes.
In number theory, a k-tuple Hk is admissible if φp(Hk) < p for every prime p, where Hk = (h1↪ ▷ ▷ ▷ ↪ hk) is a strictly in- Zun-Jing Wang WIOMAX LLC, USA
wang@wiomax.com
creasing sequence of integers, and φp(H) denotes the number of distinct residue classes modulo p occupied by the elements in Hk [Goldston et al., 2009]. The objective is to minimize the diameter of Hk, i.e., d(Hk) = hk - h1, for a given k.
The early work [Hensley and Richards, 1974; Gordon and Rodemich, 1998; Clark and Jarvis, 2001] to compute narrow admissible tuples has been motivated by the incompatibility of the two long-standing Hardy-Littlewood conjectures.
Admissible sets have been used in the recent breakthrough work to find small gaps between primes. In [Goldston et al., 2009], it was proved that any admissible Hk0 contains at least two primes infinitely often, if k0 satisfies some arithmetic properties. In [Zhang, 2014], it was proved that a finite bound holds at k0 ≥ 3▷5⇥106 . The bound was then quickly reduced to d⇤ (H105) = 600 [Maynard, 2015] and d⇤ (H50) = 246 [Polymath, 2014b], and wider ranges of k0 also were obtained on bounded intervals containing many primes [Polymath, 2014b]. Moreover, admissible sets have been used to find large gaps between primes [Ford et al., 2015].
Most of the existing techniques to find narrow admissible tuples are sieve methods [Hensley and Richards, 1974; Clark and Jarvis, 2001; Gordon and Rodemich, 1998; Polymath, 2014a; 2014b], although a few local optimizations were proposed recently [Polymath, 2014a; 2014b].
In this paper, we formally model this problem into a combinatorial optimization problem, and design search strategies to tackle the landscape, by utilizing the local search structure. Our solver is systematically tested to show its effectiveness.
2 Search ProblemFormulation
For a given k, a candidate number set V with ♣V♣ ≥ k can be precomputed, and a required prime set P, where each prime p k, can be determined. Each H is obtained by selecting the numbers from V, and the admissibility is tested using P.
For convenience, V, P, and H are assumed to be sorted in increasing order. We denote H as Hk if ♣H♣ = k, as ˜H if it is admissible, and as ˜Hk if it satisfies both of the constraints.
Definition 1 (Constraint Optimization Model). For a given k, and given the required V and P, the objective is to find a number set H ✓ V with the minimal d(H) value, subject to the constraints ♣H♣ = k and H is admissible.
Given V and P = (p1↪ · · · ↪ pi↪ · · · ↪ p♣P♣), the following three data structures are defined for facilitating the search:
Definition 2 (Residue Array Rv). For v 2 V, Rv is calculated on P: its ith row is rv↪i = vmodpi for i 2 [1↪ ♣P♣].
Definition 3 (Occupancy Matrix M). M is an irregular matrix, in which each row i contains pi elements corresponding to the residue classes modulo pi. For any given number set H ✓ V, there is mi↪j = Pv2H (j ⌘ rv↪i + 1) for j 2 [1↪ pi], which means the count of numbers in H occupying each residue class modulo pi.
Definition 4 (Count Array F). F is an array, in which each row i gives the count of zero elements in the ith row of M.
Figure 1 gives the example for an admissible set ˜H7 = (0↪ 2↪ 8↪ 12↪ 14↪ 18↪ 30) with d( ˜H7) = 30, the full prime set P, Rv for each v 2 ˜H7, and the correspondingMand F.
Property 1. The space requirements for ¶Rv♣v 2 V♦, M, F are respectively ♣V♣ · ♣P♣, Pi2[1↪♣P♣] pi, and ♣P♣.
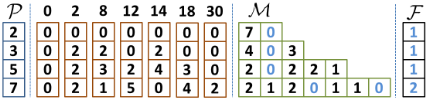
H and its corresponding M and F have a few properties:
There is a constraint violation at row i if fi = pi-φpi ⌘ 0. The total violation count should be 0 for each ˜H.
Property 2 (Admissibility). H is admissible if fi > 0, 8i.
Property 3. Let Wi↪j = ¶v 2 H♣rv↪i ⌘ j-1♦, it contains all numbers occupying (i↪ j) of M, and there is ♣Wi↪j ♣ = mi↪j .
There are two basic properties based on an admissible ˜Hk:
Property 4. For each row i, there is Pj2[1↪pi] mi↪j = ♣H♣.
Property 5 (Offsetting). For any c 2 Z, H[c] k = (h1 + c↪ ▷ ▷ ▷ ↪ hk + c) is admissible, and there is d(H[c] k ) = d( ˜Hk).
Properties 5 and 6 were observed in [Polymath, 2014b]. Offsetting can be seen as rotating of residue classes at each row in M; and subsetting does not decrease each row of F.
Property 6 (Subsetting). Any subset of ˜H is admissible.
Defining a compact V is nontrivial for reducing the size of problem space, which is exponential in ♣V♣.
One plausible way is to let V include all numbers in [0↪ U], and set h1 = 0. Let dLB k and dUB k be the best-so-far lower and upper bounds of the optimal value of d( ˜Hk). During the search, ♣V♣ = U can be bounded by dUB k . However, it appears that dUB k is very close to bk log k + kc [Polymath, 2014b], which might still be very large when k is big.
Based on Property 4, as pi is small, the average mi↪j would be large. For the rows with fi = 1, it would be difficult to find a useful heuristic for changing the unoccupied column j at row i. Intuitively, each unoccupied location (i↪ j) in M can be assumed to be unchanged during the search. Thus, sieving can be applied to remove any numbers in [0↪ U] that occupy those unoccupied locations, which could
Algorithm 1 Obtain V and P
- 1: PC = ¶p k♦; PR = ¶p < pk log k♦ // Let pm = pk log k
Require: k, [0↪U]
- 2: V = [0↪ U] sieving all v with rv↪i ⌘ 1 for pi 2 PR
- 4: PL = ¶pi 2 PC♣fi > 0♦; P = PC - PL
- 3: Obtain M and F for H = V using P = PC
- 5: return V, P
be found using Property 3, for a set of the smallest primes PR 2 P. After sieving, the proportion of remaining numbers is ↵ ⇡ 1- Qpi2PR (1-1◁pi). The completeness of the problem space on the other combinations in M can be retained using a sufficiently large U, based on the principle behind Property 5, i.e., offsetting as a choice of residue classes.
Remark 1. The original problem can be converted into a list of subproblems, where each subproblem takes each v 2 [0↪ U -dLB k ]\V as the starting point h1 to obtain the minimal diameter for each ˜Hk ✓ Vv = [v↪ v+dUB k ]\V. The optimal solution is then the best solution among all subproblems.
Decomposition [Friesen and Domingos, 2015] has been successfully used in AI for solving discrete problems. The new perspective of the problem has two features. First, each subproblem has a much smaller state space, as ♣Vv♣ ⇡ ↵·dUB k . Second, for totally around ↵ · (U - dLB k ) subproblems, the good solutions of neighboring subproblems might share a large proportion of elements, providing a very useful heuristic clue for efficient adaptive search in this dimension.
Let PC contain all primes p k. In theory, P = PC, but we can reduce it to an effective subset. Based on Property 4, if pi is large, the average mi↪j would be small. Some rows of F would always have fi > 0, even for H = V. The set of corresponding primes, named PL, thus can be removed from P, without any loss of the completeness for testing the admissibility. The effective prime set would be P = PC-PL.
Algorithm 1 gives the specific realization for obtaining V and P. Here PR in Line 1 and V in Line 2 are obtained using the setting in the greedy sieving method [Polymath, 2014b].
3 Search Algorithm
In this section, the basic operations on auxiliary data structures are first introduced. Some search operators are then realized. Finally, we describe the overall search algorithm.
3.1 Operations on Rv,Mand F
For every v 2 V, Rv is calculated in advance. For H ✓ V, the corresponding M and F are synchronously updated locally. The space requirements are given in Property 1.
There are two elemental 1-move operators, i.e., adding v ◁2 H into H to obtain H = H + ¶v♦, and removing v 2 H from H to obtain H = H - ¶v♦, for given H ✓ V and v 2 V.
Property 7 (Connectivity). The two elemental 1-move operators possess the connectivity property for each H 2 V.
The connectivity property [Nowicki and Smutnicki, 1996] states that there exists a finite sequence of such moves to achieve the optimum state from any state in the search space.
Algorithm 2 Update M and F as adding v ◁2 H into H
- 1: for i 2 [1↪ ♣P♣] do
Require: Rv,M, F
- 2: j = rv↪i +1; mi↪j =mi↪j +1
- 3: if mi↪j ⌘ 1 then fi = fi -1
- 5: return M, F
- 4: end for
Algorithm 3 Update M and F as removing v 2 H from H
- 1: for i 2 [1↪ ♣P♣] do
Require: Rv,M, F
- 2: j = rv↪i +1; mi↪j =mi↪j -1
- 4: end for
- 3: if mi↪j ⌘ 0 then fi = fi +1
- 5: return M, F
For H ⌘ ?, there are mi↪j = 0 for each i↪ j, fi = pi for each i, based on Definitions 3 and 4. The M and F for any H can be constructed by adding each v 2 H using Algorithm 2. For any two states HA and HB, HA can be changed into HB by adding each v 2 HB - HA and by removing each v 2 HA -HB. The total number of 1-moves is L = ♣HA [ HB♣ - ♣HA \ HB♣, i.e., which can be seen as the distance [Reidys and Stadler, 2002] between two states. The shorter the distance, the more similar the two states are.
Algorithms 2 and 3 respectively give the operations of updatingMand F for the two elemental 1-move operators.
In the following realizations, we will focus on the search transitions between ˜H states. The admissibility testing (Property 2) on each ˜H is not explicitly applied. Instead, VioCheck in Algorithm 4 is used to check ∆, i.e., the violation count to be increased, if adding v into H, using Rv, M and F.
Property 8 (Time Complexity). Algorithms 2 and 3 have the time complexity O(♣P♣) in updating M and F.
3.2 Search Operators
We first realize some elemental and advanced search operators to provide the transitions between admissible states.
Side Operators
Let Side=¶Left, Right♦ define the two mutually reverse sides of H. For an admissible state ˜H, each side operator tries to add or remove a number at the given side of ˜H to obtain the admissible tuple with a diameter as narrow as possible.
SideRemove just removes the element at the given Side from ˜H, and its output is admissible, according to Property 6.
Algorithm 5 defines the operation SideAdd for adding a number v into ˜H. To retain the admissibility, the number to be added is tested using Algorithm 4 to ensure the admissibility.
Repair Operator
The Repair operator repairs ˜H into ˜Hk using side operators: While ♣ ˜H♣ < k, the SideAdd operator is iteratively applied on each side of ˜H, and the better one is kept; While ♣ ˜H♣ > k, the SideRemove operator is iteratively applied on each side of ˜H, and the better one is kept. Finally, ˜Hk is obtained as ♣ ˜H♣ = k.
Algorithm 4 VioCheck: Get the change of the violation count
Require: v, H // Include Rv and correspondingMand F 1: ∆= 0 2: for i 2 [1↪ ♣P♣] do 3: if mi↪rv↪i+1 ⌘ 0 and fi ⌘ 1 then ∆=∆+1 4: end for 5: return ∆ // The change of the violation count
Algorithm 5 SideAdd: For adding a number into ˜H
- Require: ˜H, Side // Include ¶Rv♦ and correspondingMand F 1: if Side ⌘Left then v = h1 else v = h♣ ˜H♣ // Get side value 2: l = GetIndex(v↪ V) // Obtain the index l of v in V 3: while l 2 [1↪ ♣V♣] do 4: if Side ⌘ Left then l = l -1 else l = l +1 5: ∆=VioCheck(vl, ˜H) // Use Algorithm 4 to add the lth number in V 6: if ∆⌘ 0 return ˜H = ˜H[ ¶vl♦ // Ensure the admissibility 7: end while 8: return ˜H // The original H is unchanged
Shift Search
Algorithm 6 gives the realization of the ShiftSearch operator. The side is selected at random (Line 2). Each shift [Polymath, 2014a] is realized by combining SideRemove and SideAdd (Line 4), leading to a distance of 2 to the original state. Starting from ˜HO, we applies totally up to NL shifts (Line 3) unless SideAdd fails (Line 5), and the best state is kept as ˜HN (Line 6). The state ˜HN is accepted immediately if dN dO, or with a probability otherwise (Line 8), following the same principle as in simulated annealing [Kirkpatrick et al., 1983].
Insert Moves
Algorithm 7 gives the realization of the InsertMove operator to work on the input ˜H for obtaining an admissible output.
The operator is realized in three levels, as defined by the parameter Level 2 ¶0↪ 1↪ 2♦. For each v in a compact set Vin = [h1↪ h♣ ˜H♣ ] \ V - ˜H (Line 2), the violation count ∆ is calculated using Algorithm 4 (Line 3). At level 0, the value v is immediately inserted into ˜H if ∆ ⌘ 0 (Line 4). Otherwise, if Level > 0 and ∆ ⌘ 1, the violation row i is found using VioRow (Line 5), which is simply realized by returning i as the conditions are satisfied at Line 3 of Algorithm 4, and then v is stored into the set Qi (Line 5) starting from ? (Line 1).
At levels 1 and 2, we compare ♣Qi♣ and mi↪sb, where sb is the second best location in row i of M. Based on Property 3, ♣Wi↪sb♣ = mi↪sb. Note that the admissibility is retained after adding elements in Qi and removing elements in Wi↪sb.
Remark 2. For ˜H=InsertMove( ˜H), d( ˜H) is non-increasing at all levels. ♣ ˜H♣ is respectively increased by 1 and ♣Qi♣ - mi↪sb at levels 0 and 1, and keeps unchanged at level 2.
In general, InsertMove is successful if it can increase ♣ ˜H♣. However, the neighborhood might contains too many infeasible moves, as many 1-moves would trigger multiple violations. It might be inefficient to use systematic adjustments [Polymath, 2014a]. Our implementation targets on feasible moves intelligently by utilizing the violation check clues.
Algorithm 6 ShiftSearch: Combine side moves on ˜H
Require: ˜HO
2: Side=RND(¶Left, Right♦) RSide =Reverse of Side
- // Parameter: NL ≥ 1, β ≥ 0 1: ˜H = ˜HO; kO = ♣ ˜H♣; dO = d( ˜H); dN =1; ˜HN = ˜H
- 3: for l 2 [1↪NL] do
- 5: if ♣ ˜H♣ < kO break // Stop search if SideAdd fails
- 4: ˜H =SideRemove( ˜H, RSide); ˜H=SideAdd( ˜H, Side)
- 6: if d( ˜H) < dN then dN = d( ˜H); ˜HN = ˜H
- 8: if dN dO or 0▷5 (dN-dO)β >RND(0, 1) return ˜HN
- 7: end for
- 9: return ˜HO // The original H is unchanged
Local Search
Algorithm 8 gives the realization of the LocalSearch operator. We will only focus on the case of improving the input state with ♣ ˜H♣ = k. Let the input have d0 = d( ˜H). The SideRemove operator is first applied for NS times (Lines 1-3). Its output has ♣ ˜H♣ < k, and d1 = d( ˜H) < d0. The InsertMove operator is then applied for up to NI times (Lines 4-6). Based on Remark 1, the output has d2 = d( ˜H) d1. If this step leads to ♣ ˜H♣ ≥ k, the final output after repairing definitely has a lower diameter than d0. Otherwise, it is still possible to produce a better output as the state is being repaired (Line 7).
3.3 Region-based Adaptive Local Search (RALS)
The region-based adaptive local search (RALS) is realized to tackle the problem decomposition as described in Remark 1.
Let us consider the problem along the dimension of the numbers in V. For each ˜Hk, it can be indexed by (h1↪ d( ˜Hk)). Let f ⇤ (v) be the optimal diameter for all ˜Hk with h1 = v, we can form a set of points ¶(v1↪ f ⇤ (v1))↪ · · · ↪ (v♣V♣↪ f ⇤ (v♣V♣)♦. It can be seen as a one-dimensional fitness landscape representing the fitness function f ⇤ (v) on the discrete variable from v 2 V. Note that the optimal solution on this fitness landscape is the optimal solution of the original problem.
Essentially, we would like to focus the search on those promising regions where f ⇤ (v) has higher quality. Nevertheless, early search can provide some clues for narrowing down promising regions, even though the fitness landscape itself is not explicit at the beginning, as f ⇤ (v) at each v can be revealed through extensive local search.
Database Management
We use a simple database, denoted by DB, to keep the highquality solutions ˜Hk found during the search, and index each of them as (v↪ f(v)), where v = h1, and f(v) = d( ˜Hk) for each ˜Hk. For each v, only the best-so-far solution and the corresponding f(v) is kept. Here f(v) plays the role of a virtual fitness function that is updated during the search process to approximate the real fitness function f ⇤ (v).
The database is managed in a region-based mode. Specifically, the total range [0↪ U] of the numbers in V is divided into NR regions. There are three basic operations for DB.
The DBInit operator is used for providing the initialization. The greedy sieve [Polymath, 2014b] is applied to generate a state ˜Hk in each region for forming the initial f(v).
Algorithm 7 InsertMove: Local moves in [h1↪ h♣ ˜H♣ ] of ˜H
Require: ˜H
// Parameter: Level 2 ¶0↪ 1↪ 2♦
- 2: for v 2 Vin = [h1↪ h♣ ˜H♣ ] \V - ˜H do
- 1: Initialize ¶Qi = ?♣i 2 [1↪ ♣P♣]♦
- 3: ∆=VioCheck(v, ˜H)
// Use as Level > 0
// Algorithm 4
- 5: if ∆⌘ 1 then i = VioRow(v↪ ˜H); Qi = Qi [ ¶v♦
- 4: if ∆⌘ 0 return ˜H = ˜H[ ¶v♦ // Level 0: Insert one number
- 6: end for
- 8: if ♣Qi♣ >mi↪sb return ˜H = ˜H+Qi -Wi↪sb // Level 1 9: end for
- 7: for Level > 0 and i 2 [1↪ ♣P♣] do
- 10: for Level > 1 and i 2 [1↪ ♣P♣] (In RandomOrder) do
- 12: end for
- 11: if ♣Qi♣ ⌘mi↪sb > 0 return ˜H = ˜H+Qi -Wi↪sb
// The original H is unchanged
- 13: return ˜H
Algorithm 8 LocalSearch: Remove & insert to improve ˜Hk
- 7: return ˜Hk =Repair( ˜H)
- Require: ˜H, NS, NI 1: for n 2 [1↪NS] do
- 3: end for
// Parameters: NS ≥ 1, NI ≥ 1
- 2: Side=RND(¶Left,Right♦); ˜H=SideRemove( ˜H, Side)
- 4: for n 2 [1↪NI] do
- 6: end for
- 5: ˜H =InsertMove( ˜H); if ♣ ˜H♣ ≥ k break
The DBSelect operator is used for selecting one incumbent state to apply the search operation. In the region-based mode, there are two steps to provide the selection. In the first step, each region provides one candidate. In this paper, we greedily choose the best solution in each region. In the second step, the incumbent state is selected from the candidates provided by all regions. We consider the following implementation. At the probability γ, the candidate is selected at random. Otherwise, tournament selection is applied to select the best solution among totally NT randomly chosen candidates.
The DBSave operator simply stores each ˜Hk into DB, and updates f(v) internally. Dominated solutions are discarded.
Algorithm Realization
Algorithm 9 gives the implementation of RALS to obtain H⇤k for a given k. First, V and P are initialized using Algorithm 1, using U = d1▷5 · (k log k + k)e for the range [0↪ U] (Line 1) to ensure U > dUB k . Afterward, the database DB with NR regions is initiated using the DBInit operator (Line 2).
The search process runs T iterations in total. In each iteration, we first select one incumbent solution ˜Hk from DB using the DBSelect operator (Line 4). Then the actual search tackles two parts of the problem. The ShiftSearch operator is used to search on the virtual fitness landscape f(v) (Line 5). The LocalSearch operator is then applied to improve f(v) locally (Lines 6-7). For each search operator in Lines 5-7, the DBSave operator is applied to store newly generated solutions. Finally, the best solution H⇤ in DB is returned.
Algorithm 9 RLAS algorithm to obtain H⇤k for a given k
9: return H⇤ in DB
| 1: | Intialize V and P using Algorithm 1 // U = 1▷5 · dk log k+ke |
| 2: | DB=DBInit(NR) // Initiate DB with NR regions |
| 3: | for t 2 [1↪ T] do |
| 4: | ˜Hk =DBSelect(DB) // Select one incumbent solution fromDB |
| 5: | ˜Hk =ShiftSearch( ˜Hk); DBSave( ˜Hk, DB) |
| 6: | ˜Hk =LocalSearch( ˜Hk, 1, NI1); DBSave( ˜Hk, DB) |
| 7: | ˜Hk =LocalSearch( ˜Hk, 2, NI2); DBSave( ˜Hk, DB) |
| 8: | end for |
| 9: | return in DB // Return the best solution stored in DB |
4 Results and Discussion
We now turn to the empirical evaluation of the proposed algorithm. For the benchmark instances, we refer to an online database [Sutherland, 2015] that has been established and extensively updated to contain the narrowest admissible ktuples known for all k 5000. The algorithm is coded in Java, and our experiments were run on AMD 4.0GHz CPU. For each instance, 100 independent runs were performed.
4.1 Results by ExistingMethods
Most existing techniques to solve this problem are constructive and sieve methods [Polymath, 2014a; 2014b]. The sieve methods are realized by sieving an integer interval of residue classes modulo primes p < k and then selecting an admissible k-tuple from the survivors. The easiest way to construct a narrow ˜Hk is using the first k primes past k [Zhang, 2014]. As an optimization, the sieve of Eratosthenes takes k consecutive primes, to search starting from p < k, in order to select one among the admissible tuples that minimize the diameter.
The Hensley-Richards sieve [Hensley and Richards, 1974] uses a heuristic algorithm to sieve the interval [-x◁2↪ x◁2] to obtain ˜Hk, leading to the upper bound [Polymath, 2014b]:
The Schinzel sieve, as also considered in [Gordon and Rodemich, 1998; Clark and Jarvis, 2001], sieves the odd rather than even numbers. In the shifted version [Polymath, 2014b], it sieves an interval [s↪ s + x] of odd integers and multiples of odd primes p pm, where x is sufficient large to ensure at least k survivors, and m is sufficient large to ensure that the survivors form ˜H, s 2 [-x◁2↪ x◁2] is the starting point to choose for yielding the smallest final diameter.
As a further optimization, the shifted greedy sieve [Polymath, 2014b] begins as in the shifted Schinzel sieve, but the minimally occupied residue class are greedily chosen to sieve for primes p > ⌧ pk log k, where ⌧ is a constant. Empirically, it appears to achieve the bound [Polymath, 2014a]:
Table 1 lists the upper bounds obtained by applying a set of existing techniques, including k primes past k, Eratosthenes (Zhang) sieve, Hensley-Richards sieve, Schinzel and Shifted Schinzel sieve, by running the code 1 provided in [Polymath, 2014b], on k = ¶1000↪ 2000↪ 3000↪ 4000↪ 5000♦. The best known results are retrieved from [Sutherland, 2015].
1 http://math.mit.edu/⇠drew/ompadm v0.5.tar
4.2 Results by RALS algorithm
Table 2 lists the average results of different versions of the proposed RALS algorithm. The "BaseVer" version is defined with the following settings. For the database DB, we use NR = 20. For its DBSelect operator, there are γ = 0▷01 and NT = 4. For the search loop, we consider T = 1000 iterations. For the ShiftSearch operator, we set NL = 10 and β = 1. For the InsertMove operator, there is Level = 2. For the parameters of LocalSearch in Algorithm 9, we set NI1 = 500 and NI2 = 0. The other versions are then simply the "BaseVer" version with different parameters.
With T = 0, the algorithm returns the best results obtained by the shifted greedy sieve [Polymath, 2014a; 2014b] in the NR regions. The results are significantly better than the sieve methods in Table 1. The search operators in RALS show their effectiveness as all RALS versions with T > 0 perform significantly better than the version with T = 0.
Note that "BaseVer" has Level = 2, we can compare the RALS versions with different levels ¶0↪ 1↪ 2♦ in the InsertMove operator of LocalSearch. On the performance, the version with a higher level produces better results than that of a lower level. With greedy search only, the first LocalSearch works as an efficient contraction process [Polymath, 2014a]. As described in Remark 2, InsertMove performs greedy search at levels 0 and 1, but performs plateau moves at level 2, from the perspective of updating ♣ ˜H♣. At level 0, the search performs elemental 1-moves. At level 1, the search can be in a very large neighborhood although it has a low time complexity. Plateau moves is used at level 2 to find exits, as remaining feasible moves are more difficult to check. Finding exits to leave plateaus [Hoffmann, 2001; Frank et al., 1997] has been an important research topic about the local search topology on many combinatorial problems [Bonet and Geffner, 2001; Benton et al., 2010; Sutton et al.,
2010]. From the viewpoint of the LocalSearch operator, the plateau moves on the part solved by InsertMove help escaping from local mimina in the landscape of the subproblem.
We compare the RALS versions with different NI1 2 ¶100↪ 500↪ 1000♦, as "BaseVer" has NI1 = 500. Especially for k 2 ¶3000↪ 4000♦, the improvements of using higher NI1 are extremely significant as NI1 increases from 100 to 500, but are less significant as NI1 further increases to 1000.
In "BaseVer", the second LocalSearch in Line 7 of Algorithm 9 is actually not used if it has NI2 = 0. As we increase NI2 to 10, the instance k = 1000 can be fully solved to the best known solution, and the instance k = 5000 can also be solved to obtain a significantly better result.
Lines 1-3 of Algorithm 8 might be viewed as perturbation, an effective operator in stochastic local search [Hoos and St¨utzle, 2004] to escape from local minima on rugged landscapes [Tayarani-N and Prugel-Bennett, 2014; Billinger et al., 2014]. In RALS, the second LocalSearch essentially applies a larger perturbation than the first LocalSearch.
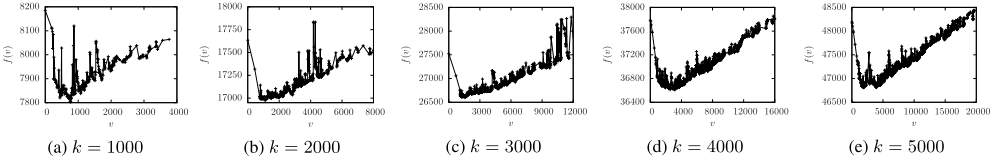
Table 2 also gives the comparison for RALS with γ 2 ¶0▷001↪ 0▷01↪ 0▷1↪ 1♦ for selecting the incumbent state in DBSelect. The larger the γ, the more random the selection is. The best performance is achieved as γ = 0▷1, neither too greedy nor too random. We can gain some insights from a typical snapshot of the virtual fitness landscape f(v), as shown in Figure 2. It is easy to spot the valley with highquality solutions, as they provide significant clues for adaptive search. Meanwhile, the noises on the fitness landscape might reduce the effectiveness of pure greedy search. Thus, there is a trade-off between greedy and random search.
Tables 3 lists the performance measures, including the average, the successful rate of finding best known solutions (SuccRate), and the calculating time, by the "BaseVer" version with both γ = 0▷1 and NI2 = 10, as T = 100 and T = 1000. This version achieves high SuccRate for k 2 ¶1000↪ 2000↪ 3000♦, and moderate SuccRate for k 2 ¶4000↪ 5000♦, as T = 1000. It also reaches reasonable good SuccRate as T = 100, with a lower execution time.
Finally, we apply RLAS to compare the results for k 2 [2500↪ 5000] in [Sutherland, 2015]. In Table 4, we list the new upper bound H⇤k and the improvement on the diameter δd for each k of the 48 instances. Eight instances among them have δd ≥ 10. Thus, AI-based methods might make further contributions to pure mathematics applications.
5 Conclusions
We presented a region-based adaptive local search (RALS) method to solve a case of pure mathematics applications for finding narrow admissible tuples. We formulated the original problem into a combinatorial optimization problem. We showed how to exploit the local search structure to tackle the combinatorial landscape, and then to realize search strategies for adaptive search and for effective approaching to highquality solutions. Experimental results demonstrated that the method can efficiently find best known and new solutions.
There are several aspects of this work that warrant further study. A deeper analysis might be applied to better identify properties of the local search topology on the landscape. One might also apply advanced AI strategies, e.g., algorithm portfolios [Gomes and Selman, 2001] and SMAC [Hutter et al., 2011], to obtain an even greater computational advantage.
@inproceedings{ijcai2016p381,
  title     = {Exploiting Problem Structure in Combinatorial Landscapes: A Case Study on Pure Mathematics Application},
  author    = {Xie, Xiao-Feng and Wang, Zun-Jing},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {2683--2688},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/381},
}
TY - CPAPER TI - Exploiting Problem Structure in Combinatorial Landscapes: A Case Study on Pure Mathematics Application AU - Xie, Xiao-Feng AU - Wang, Zun-Jing T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 2683 EP - 2688 UR - https://ijcai.org/proceedings/2016/381 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





