
Probabilistic Inference Modulo Theories
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 3591-3598.
Abstract
We present SGDPLL(T), an algorithm that solves (among many other problems) probabilistic inference modulo theories, that is, inference problems over probabilistic models defined via a logic theory provided as a parameter (currently, propositional, equalities on discrete sorts, and inequalities, more specifically difference arithmetic, on bounded integers). While many solutions to probabilistic inference over logic representations have been proposed, SGDPLL(T) is simultaneously (1) lifted, (2) exact and (3) modulo theories, that is, parameterized by a background logic theory. This offers a foundation for extending it to rich logic languages such as data structures and relational data. By lifted, we mean algorithms with constant complexity in the domain size (the number of values that variables can take). We also detail a solver for summations with difference arithmetic and show experimental results from a scenario in which SGDPLL(T) is much faster than a state-of-the-art probabilistic solver.
- Armin Biere, Marijn Heule, Hans van Maaren, and Toby Walsh, editors, Handbook of Satisfiability, volume 185 of Frontiers in Artificial Intelligence and Applications, pages 825-885. IOS Press, 2009.
- [Bayardo, Jr. and Pehoushek, 2000] R. J. Bayardo, Jr. and J. D. Pehoushek. Counting Models Using Connected Components. In Proceedings of the Seventeenth Na- tional Conference on Artificial Intelligence, pages 157- 162, Austin, TX, 2000. AAAI Press.
- [Belle et al., 2015a] Vaishak Belle, Andrea Passerini, and Guy Van den Broeck. Probabilistic inference in hybrid domains by weighted model integration. In Proceedings of 24th International Joint Conference on Artificial Intel- ligence (IJCAI), 2015. IJCAI
- [Belle et al., 2015b] Vaishak Belle, Guy Van den Broeck, and Andrea Passerini. Hashing-based approximate proba- bilistic inference in hybrid domains. In Proceedings of the 31st Conference on Uncertainty in Artificial Intelligence (UAI), 2015.
- [Bistarelli et al., 1997] Stefano Bistarelli, Ugo Montanari, and Francesca Rossi. Semiring-based constraint satisfac- tion and optimization. J. ACM, 44(2):201-236, March 1997.
- [Chavira and Darwiche, 2008] M. Chavira and A. Darwiche. On probabilistic inference by weighted model counting. Artificial Intelligence, 172(6-7):772-799, 2008.
- [Davis et al., 1962] M. Davis, G. Logemann, and D. Love- land. A machine program for theorem proving. Commu- nications of the ACM, 5:394-397, 1962.
- [de Moura et al., 2007] Leonardo de Moura, Bruno Dutertre, and Natarajan Shankar. A tutorial on satisfiability modulo theories. In Computer Aided Verification, 19th Interna- tional Conference, CAV 2007, Berlin, Germany, July 3-7, 2007, Proceedings, volume 4590 of Lecture Notes in Com- puter Science, pages 20-36. Springer, 2007.
- [de Salvo Braz, 2007] R. de Salvo Braz. Lifted First-Order Probabilistic Inference. PhD thesis, University of Illinois, Urbana-Champaign, IL, 2007. IJCAI
- [Dechter, 1999] R. Dechter. Bucket elimination: A unifying framework for reasoning. Artificial Intelligence, 113:41- 85, 1999.
- [Eén and Sörensson, 2003] N. Eén and N. Sörensson. An Extensible SAT-solver. In SAT Competition 2003, volume 2919 of Lecture Notes in Computer Science, pages 502- 518. Springer, 2003.
- [Ganzinger et al., 2004] Harald Ganzinger, George Hagen, Robert Nieuwenhuis, Albert Oliveras, and Cesare Tinelli. DPLL( T): Fast Decision Procedures. 2004.
- [Getoor and Taskar, 2007] L. Getoor and B. Taskar, editors. Introduction to Statistical Relational Learning. MIT Press, 2007.
- [Gogate and Dechter, 2011] V. Gogate and R. Dechter. Sam- pleSearch: Importance sampling in presence of determin- ism. Artificial Intelligence, 175(2):694-729, 2011.
- [Gogate and Domingos, 2010] V. Gogate and P. Domingos. Formula-Based Probabilistic Inference. In Proceedings of the Twenty-Sixth Conference on Uncertainty in Artificial Intelligence, pages 210-219, 2010.
- [Gogate and Domingos, 2011] V. Gogate and P. Domingos. Probabilistic Theorem Proving. In Proceedings of the Twenty-Seventh Conference on Uncertainty in Artificial Intelligence, pages 256-265. AUAI Press, 2011.
- [Goodman et al., 2012] Noah D. Goodman, Vikash K. Mansinghka, Daniel M. Roy, Keith Bonawitz, and Daniel Tarlow. Church: a language for generative models. CoRR, abs/1206.3255, 2012.
- [Knuth, 1993] Donald E. Knuth. Johann Faulhaber and Sums of Powers. Mathematics of Computation, 61(203):277- 294, 1993.
- [Marić, 2009] Filip Marić. Formalization and implementa- tion of modern sat solvers. Journal of Automated Reason- ing, 43(1):81-119, 2009.
- [Mateescu and Dechter, 2008] R. Mateescu and R. Dechter. Mixed deterministic and probabilistic networks. Annals of Mathematics and Artificial Intelligence, 54(1-3):3-51, 2008.
- [Poole, 2003] D. Poole. First-Order Probabilistic Inference. In Proceedings of the Eighteenth International Joint Con- ference on Artificial Intelligence, pages 985-991, Aca- pulco, Mexico, 2003. IJCAI
- [Morgan Kaufmann. Sang et al., 2005] T. Sang, P. Beame, and H. A. Kautz. Heuristics for Fast Exact Model Counting. In Eighth Inter- national Conference on Theory and Applications of Satis- fiability Testing, pages 226-240, 2005.
- [Sanner and Abbasnejad, 2012] Scott Sanner and Ehsan Ab- basnejad. Symbolic variable elimination for discrete and continuous graphical models. In Proceedings of the Twenty-Sixth AAAI Conference on Artificial Intelligence, 2012.
- [Van den Broeck et al., 2011] G. Van den Broeck, N. Taghipour, W. Meert, J. Davis, and L. De Raedt. Lifted Probabilistic Inference by First-Order Knowledge Compilation. In Proceedings of the Twenty Second International Joint Conference on Artificial Intelligence, pages 2178-2185, 2011. IJCAI
- [Zhang and Poole, 1994] N. Zhang and D. Poole. A simple approach to Bayesian network computations. In Proceed- ings of the Tenth Biennial Canadian Artificial Intelligence Conference, 1994.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
High-level, general-purpose uncertainty representations as well as fast inference and learning for them are important goals in Artificial Intelligence. In the past few decades, graphical models have made tremendous progress towards achieving these goals, but even today their main methods can only support very simple types of representations such as tables and weight matrices that exclude logical constructs such as relations, functions, arithmetic, lists, and trees. For example, consider the following conditional probability distributions, which would need to be either automatically expanded into large tables (a process called propositionalization), or manipulated in a manual, ad hoc manner, in order to be processed by mainstream probabilistic inference algorithms from the graphical models literature:
- ÷ P (x > 10 ♣ y 6= 98 _ z 15) = 0▷1, for x↪ y↪ z 2 ¶1↪ ▷ ▷ ▷ ↪ 1000♦
- ÷ P (x 6= Bob ♣ friends(x ↪ Ann)) = 0▷3
Rina Dechter U. of California, Irvine
Irvine, CA, USA
Early work in Statistical Relational Learning [Getoor and Taskar, 2007] offered more expressive languages that used relational logic to specify probabilistic models but relied on conversion to conventional representations to perform inference, which can be very inefficient. To address this problem, lifted probabilistic inference algorithms [Poole, 2003; de Salvo Braz, 2007; Gogate and Domingos, 2011; Van den Broeck et al., 2011] were proposed for efficiently processing logically specified models at the abstract first-order level. However, even these algorithms can only handle languages having limited expressive power (e.g., function-free firstorder logic formulas). More recently, several probabilistic programming languages [Goodman et al., 2012] have been proposed that enable probability distributions to be specified using high-level programming languages (e.g., Scheme). However, the state-of-the-art of inference over these languages is essentially approximate inference methods that operate over a propositional (grounded) representation.
We present SGDPLL(T), an algorithm that solves (among many other problems) probabilistic inference on models defined over higher-order logical representations. Importantly, the algorithm is agnostic with respect to which particular logic theory is used, which is provided to it as a parameter. We have so far developed solvers for propositional, equalities on categorical sorts, and inequalities, more specifically difference arithmetic, on bounded integers (only the latter is detailed in this paper, as an example). However, SGDPLL(T ) offers a foundation for extending it to richer theories involving relations, arithmetic, lists and trees. While many algorithms for probabilistic inference over logic representations have been proposed, SGDPLL(T) is simultaneously (1) lifted, (2) exact 1 and (3) modulo theories. By lifted, we mean algorithms with constant complexity in the domain size (the number of values that variables can take).
SGDPLL(T) generalizes the Davis-Putnam-LogemannLoveland (DPLL) algorithm for solving the satisfiability problem in the following ways: (1) while DPLL only works on propositional logic, SGDPLL(T) takes (as mentioned) a logic theory as a parameter; (2) it solves many more problems than satisfiability on boolean formulas, including summations over real-typed expressions, and (3) it is symbolic, accepting input with free variables (which can be seen as constants with unknown values) in terms of which the output is expressed.
1 Our emphasis on exact inference, which is impractical for most real-world problems, is due to the fact that it is a needed basis for flexible and well-understood approximations (e.g., RaoBlackwellised sampling).
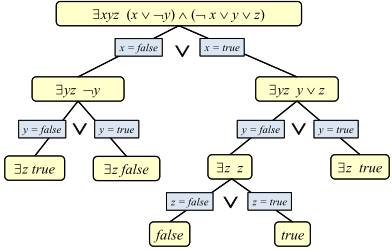
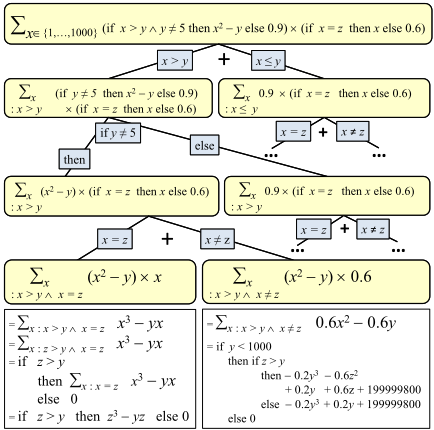
Generalization (1) is similar to the generalization of DPLL made by Satisfiability Modulo Theories (SMT) [Barrett et al., 2009; de Moura et al., 2007; Ganzinger et al., 2004], but SMT algorithms require only satisfiability solvers of their theory parameter to be provided, whereas SGDPLL(T) may require solvers for harder tasks (including model counting). Figures 1 and 2 illustrate how both DPLL and SGDPLL(T ) work and highlight their similarities and differences.
Note that SGDPLL(T) is not a probabilistic inference algorithm in a direct sense, because its inputs are not defined as probability distributions, random variables, or any other concepts from probability theory. Instead, it is an algebraic algorithm defined in terms of expressions, functions, and quantifiers. However, probabilistic inference on rich languages can be reduced to tasks that SGDPLL(T) can efficiently solve, as shown in Section 5.
The rest of this paper is organized as follows: Section 2 describes how SGDPLL(T) generalizes DPLL and SMT algorithms Section 3 defines T -problems and T -solutions, Section 4 describes SGDPLL(T) that solves T-problems, Section 5 explains how to use SGDPLL(T ) to solve probabilistic inference modulo theories, Section 6 describes a proof-of-concept experiment comparing our solution to a state-of-the-art probabilistic solver, Section 7 discusses related work, and Section 8 concludes. A specific solver for summation over difference arithmetic and polynomials is described in Appendices A and B.
2 DPLL, SMT and SGDPLL(T)
The Davis-Putnam-Logemann-Loveland (DPLL) algorithm [Davis et al., 1962] solves the satisfiability (or SAT) problem. SAT consists of determining whether a propositional formula F, expressed in conjunctive normal form (CNF), has a solution or not. A CNF is a conjunction (^) of clauses where a clause is a disjunction (_) of literals. A literal is either a proposition (that is, a Boolean variable) or its negation. A solution to a CNF is an assignment of values from the set ¶TRUE↪ FALSE♦ to all propositions in F such that at least one literal in each clause in F is assigned to TRUE.
Algorithm 1 shows a simplified, non-optimized version of DPLL which operates on CNF formulas. It works by recursively trying assignments for each proposition, one at a time, simplifying the CNF, until F is a constant (TRUE or FALSE), and combining the results with disjunction. Figure 1 shows an example of the execution of DPLL. DPLL is the basis for modern SAT solvers which improve it by adding sophisticated techniques such as unit propagation, watch literals, and clause learning [E´en and S¨orensson, 2003; Mari´c, 2009].
Satisfiability Modulo Theories (SMT) algorithms [Barrett et al., 2009; de Moura et al., 2007; Ganzinger et al., 2004] generalize DPLL and can determine the satisfiability of a Boolean formula expressed in first-order logic, where some Algorithm 1 A version of the DPLL algorithm.
DPLL(F ) F: a formula in CNF. 1 if F is a boolean constant 2 return F 3 else v pick a variable in F 4 Sol1 DPLL(simplify(F♣ v)) 5 Sol2 DPLL(simplify(F♣≻v)) 6 return Sol 1 _ Sol 2function and predicate symbols have specific interpretations. Examples of predicates include equalities, inequalities, and uninterpreted functions, which can then be evaluated using rules of real arithmetic. SMT algorithms condition on the literals of a background theory T, looking for a truth assignment to these literals that satisfies the formula. While a SAT solver is free to condition on a proposition, assigning it to either TRUE or FALSE regardless of previous choices (truth values of propositions are independent from each other), an SMT solver needs to also check whether a choice for one literal is consistent with the previous choices for others, according to T . This is done by a theory-specific model checker, provided as a parameter.
SGDPLL(T) is, like SMT algorithms, modulo theories but further generalizes DPLL by being symbolic and quantifier-parametric (thus "Symbolic Generalized DPLL(T )"). These three features can be observed in the problem being solved by SGDPLL(T ) in Figure 2:
In this example, the problem being solved requires more than propositional logic theory since equality, inequality and other functions are involved. The problem's quantifier is a summation, as opposed to DPLL and SMT's existential quantification 9. Also, the output will be symbolic in y and z because these variables are not being quantified, as opposed to DPLL and SMT algorithms which implicitly assume all variables to be quantified.
Before formally describing SGDPLL(T), we will further comment on its three key generalizations.
1. Quantifier-parametric. Satisfiability can be seen as computing the value of an existentially quantified formula; the existential quantifier can be seen as an indexed form of disjunction, so we say it is based on disjunction. SGDPLL(T) generalizes SMT algorithms by solving any quantifier L based on an associative operation ⊕, provided that a corresponding theory-specific solver is available for base case problems, as explained later. Examples of (L, ⊕, ) pairs are (8,^), (9,_), (P,+), and (Q,⇥). Therefore SGDPLL(T) can solve not only satisfiability (since disjunction is associative), but also validity (using the 8 quantifier), sums, products, model counting, weighted model counting, maximization, among others, for propositional logic-based, and many other, theories.
- Modulo Theories. SMT generalizes the propositions in SAT to literals in a given theory T, but the theory connecting these literals remains that of boolean connectives. SGDPLL(T) takes a theory T = (TC↪ TL), composed of a constraint theory TC and an input theory TL. DPLL propositions are generalized to literals in TC in SGDPLL(T), whereas the boolean connectives are generalized to functions in TL. In the example above, TC is the theory of difference arithmetic on bounded integers, whereas TL is the theory of +↪⇥, boolean connectives and if then else . Of the two, TC is the crucial one, on which inference is performed, while TL is used simply for the simplifications after conditioning, which takes time at most linear in the input expression size.
- Symbolic. Both SAT and SMT can be seen as computing the value of an existentially quantified formula in which all variables are quantified, and which is always equivalent to either TRUE or FALSE. SGDPLL(T) further generalizes SAT and SMT by accepting quantifications over any subset of the variables in its input expression (including the empty set). The non-quantified variables are free variables, and the result of the quantification will typically depend on them. Therefore, SGDPLL(T)'s output is a symbolic expression in terms of free variables. Section 3 shows an example of a symbolic solution.
Being symbolic allows SGDPLL(T) to conveniently solve a number of problems, including quantifier elimination and exploitation of factorization in probabilistic inference, as discussed in Section 5.
3 T-Problems and T-Solutions
SGDPLL(T ) receives a T -problem (or, for short, a problem) of the form M x:F (x↪y) E(x↪ y)↪ (1)
where x is an index variable quantified by L and subject to constraint F(x↪ y) in TC, with possibly the presence of free variables y, and E(x↪ y) an expression in TL. F(x↪ y) is a conjunction of literals in TC, that is, a conjunctive clause. An example of a problem is
for x↪ y↪ z bounded integer variables in, say, ¶1↪ ▷ ▷ ▷ ↪ 20♦. The index is x whereas y↪ z are free variables.
A T -solution (or, for short, simply a solution) to a problem is simply a quantifier-free expression in TL equivalent to the problem. Note that solution will often contain literals and conditional expressions dependent on the free variables. For example, the problem
has an equivalent conditional solution
For more general problems with multiple quantifiers, we simply successively solve the innermost problem until all quantifiers have been eliminated.
4 SGDPLL(T)
In this section we provide the details of SGDPLL(T), described in Algorithm 2 and exemplified in Figure 2.
4.1 Solving Base Case T-Problems
A problem, as defined in Equation (1), is in base case if E(x↪ y) contains no literals in TC.
Therefore, a base case problem for this theory is of the form Px:F(x↪y) P(x↪ y), where x is the index, y is a tuple of free variables, F(x↪ y) is a conjunction of difference arithmetic literals, and P(x↪ y) is a polynomial over x and y. We show how to fully solve difference arithmetic base cases in Appendices A and B.
In this paper, T = (TC↪ TL) where TL is polynomials over bounded integer variables, and TC is difference arithmetic [de Moura et al., 2007], with atoms of the form x < y or x y + c, where c is an integer constant. Strict inequalities x < y+c can be represented as x y+c-1 and the negation of x y + c is y x - c - 1. From now on, we shorten a x ^ x b to a x b.
4.2 Solving Non-Base Case T-Problems
Non-base case problems (that is, those in which E(x↪ y) of Equation (1) contains literals in TC) are solved by reduction to base-case ones. While base cases are solved by theoryspecific solvers, the reduction from non-base case problems to base case ones is theory-independent. This is significant as it allows SGDPLL(T) to be expanded with new theories by providing a solver only for base case problems, analogous to the way SMT solvers require theory solvers only for conjunctive clauses, as opposed to general formulas, in those theories.
The reduction mirrors DPLL, by selecting a splitter literal L present in E(x↪ y) to split the problem on, generating two simpler problems:
- ÷ quantifier-splitting applies when L contains the index x. Then two sub-problems are created, one in which L is added to F(x↪ y), and another in which ≻L is. Their solution is then combined by the quantifier's operation (+ for the case of P). For example, consider:
To remove the literal from E(x↪ y), we add the literal (x > 4) and its negation (x 4) to the constraint on x, yielding two base-case problems:
- ÷ if-splitting applies when L does not contain the index x. Then L becomes the condition of an if then else expression and the two simpler sub-problems are its then and else clauses.
For example, consider
Splitting on y > 4 reduces the problem to
containing two base-case problems.
The algorithm terminates because each splitting generates sub-problems with one less literal in E(x↪ y), eventually obtaining base case problems. It is sound because each transformation results in an expression equivalent to the previous one.
To be a valid parameter for SGDPLL(T), a (T↪⊕)- solver ST for theory T = (TL↪ TC) must, given a problem Lx:F(x↪y) E(x↪ y), recognize whether it is in base form and, if so, provide a solution baseT (Lx:F(x↪y) E(x↪ y)).
The algorithm is presented as Algorithm 2. Note that it does not depend on difference arithmetic theory, but can use a solver for any theory satisfying the requirements above.
If the (T↪⊕)-solver implements the operations above in polynomial time in the number of variables and constant time in the domain size (the size of their types), then it follows that SGDPLL(T), like DPLL, will have time complexity exponential in the number of literals and, therefore, in the number of variables, and be independent of the domain size. This is the case for the solver for difference arithmetic and will typically be the case for many other solvers.
Algorithm 2 Symbolic Generalized DPLL (SGDPLL(T)), omitting pruning, heuristics and optimizations.
4.3 Optimizations
In the simple form presented above, SGDPLL(T) may generate solutions such as ifx = 3 thenifx 6= 4 theny elsez elsew in which literals are implied (or negated) by the context they are in, and are therefore redundant. Redundant literals can be eliminated by keeping a conjunction of all choices (sides of literal splittings) made at any given point (the context) and using any SMT solver to incrementally decide when a literal or its negation is implied, thus pruning the search as soon as possible. Note that a (T↪⊕)- solver for SGDPLL(T ) appropriate for 9 can be used for this, although here there is the opportunity to leverage the very efficient SMT systems already available.
Modern SAT solvers benefit enormously from unit propagation, watched literals and clause learning [E´en and S¨orensson, 2003; Mari´c, 2009]. In DPLL, unit propagation is performed when all but one literal L in a clause are assigned FALSE. For this unit clause, and as a consequence, for the CNF problem, to be satisfied, L must be TRUE and is therefore immediately assigned that value wherever it occurs, without the need to split on it. Detecting unit clauses, however, is expensive if performed by naively checking all clauses at every splitting. Watched literals is a data structure scheme that allows only a small portion of the literals to be checked instead. Clause learning is based on detecting a subset of jointly unsatisfiable literals when the splits made so far lead to a contradiction, and keeping it for detecting contradictions sooner as the search goes on. In the SGDPLL(T) setting, unit propagation, watched literals and clause learning can be generalized to its not-necessarily-Boolean expressions; we leave this presentation for future work.
5 Probabilistic Inference Modulo Theories
Let P(X1 = x1↪ ▷ ▷ ▷ ↪Xn = xn) be the joint probability distribution on random variables ¶X1↪ ▷ ▷ ▷ ↪Xn♦. For any tuple of indices t, we define Xt to be the tuple of variables indexed by the indices in t, and abbreviate the assignments (X = x) and (Xt = xt) by simply x and xt, respectively. Let ¯ t be the tuple of indices in ¶1↪ ▷ ▷ ▷ ↪ n♦ but not in t.
The marginal probability distribution of a subset of variables Xq is one of the most basic tasks in probabilistic inference, defined as
which is a summation on a subset of variables occurring in an input expression, and therefore solvable by SGDPLL(T).
If P(x) is expressed in the language of input and constraint theories appropriate for SGDPLL(T) (such as the one shown in Figure 2), then it can be solved by SGDPLL(T), without first converting its representation to a much larger one based on tables. The output will be a summation-free expression in the assignment variables xq representing the marginal probability distribution of Xq .
Let us show how to represent P(x) with an expression in TL through an example. Consider a hypothetical generative model involving random variables with bounded integer values and describing the influence of variables such as the number of terror attacks, the Dow Jones index and newly created jobs on the number of people who like an incumbent and an challenger politicians:
attacks ⇠ Uniform(0▷▷20) newJobs ⇠ Uniform(0▷▷100000) dow ⇠ Uniform(11000▷▷18000) likeChallenger ⇠ Uniform(0▷▷N) P(likeIncumbent 2 0▷▷N♣dow↪ newJobs↪ attacks) = 8>>>>>>>>>>>>>>>>>>>>>>>><>>>>>>>>>>>>>>>>>>>>>>>>: 0▷4 b0▷7Nc , if dow > 16000 ^ newJobs > 70000) ^ likeIncumbent < b0▷7Nc 0▷6 N+1-b0▷7Nc , if dow > 16000 ^ newJobs > 70000) ^ likeIncumbent ≥ b0▷7Nc 0▷8 b0▷5Nc , if dow < 13000 ^ newJobs < 30000) ^ likeIncumbent < b0▷5Nc 0▷2 N+1-b0▷5Nc , if dow < 13000 ^ newJobs < 30000) ^ likeIncumbent ≥ b0▷5Nc 0▷9 b0▷6Nc , none of the above and (attacks 4) ^ likeIncumbent < b0▷6Nc 0▷1 N+1-b0▷6Nc , none of the above and (attacks 4) ^ likeIncumbent ≥ b0▷6Nc 1 N+1 , otherwiseThe joint probability distribution
which indicates that, if the Dow Jones index is above 16000 or there were more than 70000 new jobs, then there is a 0▷4 probability that the number of people who like the incumbent politician is below around 70% of N people (and that probability is uniformly distributed among those b0▷7Nc values), with the remaining 0▷6 probability mass uniformly distributed over the remaining N + 1 - b0▷7Nc values. Similar distributions hold for other conditions. Note that N is a known parameter and the actual representation will contain the evaluations of its expressions. For example, for N = 108 , 0▷8◁b0▷5Nc is replaced by 1▷6 ⇥ 10-8 .
P (attacks ↪ newJobs ↪ dow ↪ likeChal lenger ↪ likeIncumbent )
is simply the product of P(attacks), P(newJobs) and so on. P(attacks) can be expressed by
because of its distribution Uniform(0▷▷20), and the other uniform distributions are represented analogously. P (likeIncumbent ♣dow↪ newJobs↪ attacks) is represented by the expression
again noting that N is fixed and the actual expression contains the constants computed from b0▷7Nc, 0▷4 b0▷7Nc , and so on.
Other probabilistic inference problems can be also solved by SGDPLL(T). Belief updating consists of computing the posterior probability of Xq given evidence on Xe, which is defined as
We can also use SGDPLL(T) to compute the most likely assignment on Xq, defined by maxxq P(x), since max is an associative operation.
which can be computed with two applications of SGDPLL(T): first, we obtain a summation-free expression S for P(xq↪ xe), which is Px(q↪e) P(x), and then again S for Pxq P(xq↪ xe), which is Pxq S.
Applying SGDPLL(T) in the manner above does not take advantage of factorized representations of joint probability distributions, a crucial aspect of efficient probabilistic inference. However, it can be used as a basis for an algorithm, Symbolic Generalized Variable Elimination Modulo Theories (SGVE(T)), analogous to Variable Elimination (VE) [Zhang and Poole, 1994; Dechter, 1999] for graphical models, that exploits factorization. SGVE(T) works in the exact same way VE does, but using SGDPLL(T ) whenever VE uses marginalization over a table. Note that SGDPLL(T)'s symbolic treatment of free variables is crucial for the exploitation of factorization, since typically only a subset of variables is eliminated at each step. Also note that SGVE(T), like VE, requires the additive and multiplicative operations to form a semiring [Bistarelli et al., 1997].
Finally, because of SGDPLL(T) and SGVE(T) symbolic capabilities, it is also possible to compute symbolic query results as functions of uninstantiated evidence variables. For the election example above with N = 108 , we can compute P (likeIncumbent > likeChallenger ♣newJobs) without providing a value for newJobs, obtaining the symbolic result
without iterating over all values of newJobs. This result can be seen as a compiled form to be used when the value of newJob is known, without the need to reprocess the entire model.
6 Experiment
We conduct a proof-of-concept experiment comparing our implementation of SGDPLL(T)-based SGVE(T) (available from the corresponding author's web page) to the state-ofthe-art probabilistic inference solver variable elimination and conditioning (VEC) [Gogate and Dechter, 2011], on the election example described above. The model is simple enough for SGVE(T ) to solve the query P (likeIncumbent > likeChallenger ♣newJobs = 80000 ^ dow = 17000) exactly in around 2 seconds on a desktop computer with an Intel E52630 processor, which results in 0▷6499 for N = 108 . The run time of SGVE(T) is constant in N; however, the number of values is too large for a regular solver such as VEC to solve exactly, because the tables involved will be too large even to instantiate. By decreasing the range of newJobs to 0▷▷100, of dow to 110▷▷180 and N to just 500, we managed to use VEC but it still takes 51 seconds to solve the problem.
7 Related work
SGDPLL(T) is related to many different topics in both logic and probabilistic inference literature, besides the strong links to SAT and SMT solvers.
SGDPLL(T) is a lifted inference algorithm [Poole, 2003; de Salvo Braz, 2007; Gogate and Domingos, 2011], but lifted algorithms so far have concerned themselves only with relational formulas with equality. We have not yet developed the theory solvers for relational representations required for SGDPLL(T ) to do the same, but we intend to do so using the already developed modulo-theories mechanism available. On the other hand, we have presented probabilistic inference over difference arithmetic for the first time in the lifted inference literature.
[Sanner and Abbasnejad, 2012] presents a symbolic algorithm for hybrid graphical models described by piecewise polynomials. SGDPLL(T) is similar, but explicitly separates the generic and theory-specific levels, and is able to deal with general logic formulas instead of just conjunctive clauses. Also, we present a theory solver for sums over bounded integers, while that paper describes an integration solver for continuous numeric variables (which can be adapted as an extra theory solver for SGDPLL(T)). [Belle et al., 2015a; 2015b] extend [Sanner and Abbasnejad, 2012] for general formulas by using conditioning on literals and an SMT solver to prune away unsatisfiable branches. While more general in this regard, this work does not discuss the symbolic treatment of free variables and its role in factorization, and does not focus on the generic level (modulo theories) of the algorithm.
SGDPLL(T ) generalizes several algorithms that operate on mixed networks [Mateescu and Dechter, 2008] - a framework that combines Bayesian networks with constraint networks, but with a much richer representation. By operating on richer languages, SGDPLL(T) also generalizes exact model counting approaches such as RELSAT [Bayardo, Jr. and Pehoushek, 2000] and Cachet [Sang et al., 2005], as well as weighted model counting algorithms such as ACE [Chavira and Darwiche, 2008] and formula-based inference [Gogate and Domingos, 2010], which use the CNF and weighted CNF representations respectively.
8 Conclusion and FutureWork
We have presented SGDPLL(T ) and its derivation SGVE(T ), algorithms formally able to solve a variety of problems, including probabilistic inference modulo theories, that is, capable of being extended with solvers for richer representations than propositional logic, in a lifted and exact manner.
Future work includes additional theories and solvers of interest, mainly among them algebraic data types and uninterpreted relations; modern SAT solver optimization techniques such as watched literals, unit propagation and clause learning, and anytime approximation schemes that offer guaranteed bounds on approximations that converge to the exact solution.
Acknowledgments
We gratefully acknowledge the support of the Defense Advanced Research Projects Agency (DARPA) Probabilistic Programming for Advanced Machine Learning Program under Air Force Research Laboratory (AFRL) prime contracts no. FA8750-14-C-0005 and FA8750-14-C-0011, and NSF grant IIS-1254071. Any opinions, findings, and conclusions or recommendations expressed in this material are those of the author(s) and do not necessarily reflect the view of DARPA, AFRL, or the US government.
A Solver for Sum and Difference Arithmetic
This appendix describes a T-solver for the base case Tproblem Px:F(x↪y) P(x↪ y) for T = (TC↪ TL) where TC is difference arithmetic and TL is the language of polynomials, x is a variable and y is a tuple of free variables. Because this is a base case, P(x↪ y) is a polynomial and contains no literals. F(x↪ y) is a conjunctive clause of difference arithmetic literals.
The solver also receives, as an extra input, a conjunctive clause C(y) (a context) on free variables only, and its output is a quantifier-free T-solution S(y) such that C(y) ) S(y) = Px:F(x↪y) P(x↪ y). In other words, C(y) encodes the assignments to y of interest in a given context, and the solution needs to be equal to the problem only when y satisfies C(y). The context starts with TRUE but is set to more restrictive formulas in the solver's recursive calls. 2
We assume an SMT (Satisfiability Modulo Theory) solver that can decide whether a conjunctive clause in the background theory (here, difference arithmetic) is satisfiable or not.
The intuition behind the solver is gradually removing ambiguities until we are left with a single lower bound, a single upper bound, and unique disequalities on index x. For example, if the index x has two lower bounds (two literals x > y and x > z), then we split on y > z to decide which lower bound implies the other, eliminating it. Likewise, if there are two literals x 6= y and x 6= z, we split on y = z, either eliminating the second one if this is true, or obtaining a uniqueness guarantee otherwise. Once we have a single lower bound, single upper bound and unique disequalities, we can solve the problem more directly, as detailed in Case 8 below.
Let Sum(x↪ F(x↪ y)↪ P(x↪ y)↪C(y)) be the result of invoking the solver its inputs, and ↵, β stand for any expression. The following cases are applied in order:
Case 0 if C(y) is unsatisfiable, return any expression (say, 0).
2 The use of a context here is similar to the one mentioned as an optimization in Section 4.3, but while contexts are optional in the main algorithm, it will be seen in the proof sketch of Theorem A.1 that they are required in this solver to ensure termination.
Case 1 if any literals in F(x↪ y) are trivially contradictory, such as ↵ 6= ↵, ↵ < ↵, ↵ 6= β for ↵ and β two distinct constants, return 0.
Case 2 if any literals in F(x↪ y) are trivially true, (such as ↵ = ↵ or ↵ ≥ ↵), or are redundant due to being identical to a previous literal, return Sum(x↪ F 0 (x↪ y)↪ P(x↪ y)↪C(y)), for F 0 (x↪ y) equal to F(x↪ y) after removing such literals.
Case 3 if F(x↪ y) contains literal x = ↵, return Sum(x↪ F 0 (x↪ y)↪ P(x↪ y)↪C(y)), for F 0 (x↪ y) equal to F (x↪ y) after replacing every other occurrence of x with ↵.
Case 4 if any literal L in F(x↪ y) does not involve x, return the expression
for F 0 (x↪ y) equal to F(x↪ y) after removing L.
Case 5 if F(x↪ y) contains only literal x = ↵, return P (↵↪ y).
Case 6 if F(x↪ y) contains literals x ≥ ↵ or x < β, return Sum(x↪ F 0 (x↪ y)↪ P(x↪ y)↪C(y)), for F 0 (x↪ y) equal to F(x↪ y) after replacing such literals by x > ↵ - 1 and x β+1, respectively. This guarantees that all lower bounds for x are strict, and all upper bounds are non-strict.
Case 7 if F(x↪ y) contains literal x > ↵ (↵ is a strict lower bound), and literal x > β or literal x 6= β, let literal L be ↵ < β. Otherwise, if F(x↪ y) contains literal x ↵ (↵ is a non-strict upper bound), and literal x ≥ β or literal x 6= β, let literal L be β ↵. Otherwise, if F(x↪ y) contains literal x 6= ↵ and literal x 6= β, let L be ↵ = β. Otherwise, if F(x↪ y) contains literal x > ↵ and literal x β, let L be ↵ < β. Then, if C(y)^L and C(y)^≻L are both satisfiable (that is, C(y) does not imply ↵ = β either way), return the expression
Case 8 At this point, F(x↪ y) and C(y) jointly define a single strict lower bound l and non-strict upper bound u for x, and ¶β1↪ ▷ ▷ ▷ ↪ βk♦ such that x 6= βi and l < βi u for every i 2 ¶1↪ ▷ ▷ ▷ ↪ k♦. If C(y) implies u - l < k, return 0. Otherwise, return FH (Px:l<xu P(x↪ y)) - P(β1↪ y) - · · · - P(βk↪ y), where FH is an extended version of Faulhaber's formula [Knuth, 1993]. The extension is presented in Appendix B and only involves simple algebraic manipulation. The fact that Faulhaber's formula can be used in time independent of u - l renders the solver complexity independent of the index's domain size.
Theorem A.1
Given x, F(x↪ y), P(x↪ y), C(y), the solver computes Sum(x↪ F(x↪ y)↪ P(x↪ y)↪C(y)) in time independent 3 of the domain sizes of x and y, and
Proof. (Sketch) Cases 0-2 are trivial (Case 0, in particular, is based on the fact that any solution is correct if C(y) is false).
Cases 3 and 4 cover cases in which x is bounded to a value and successively eliminate all other literals until trivial Case 5 applies. The left lower box of Figure 2 exemplifies this pattern.
Case 6 and 7 gradually determine a single strict lower bound l and non-strict upper bound u for x, determine that l < u, as well as which expressions βi constrained to be distinct from x are within l and u, and are distinct from each other. This provides the necessary information for Case 8 to use Faulhaber's formula and determine a solution. The right lower box of Figure 2 exemplifies this pattern.
B Computing Faulhaber's extension FH
We now proceed to explain how FH can computed the sum
where x is an integer index and ti are monomials, possibly including numeric constants and powers of free variables.
Faulhaber's formula [Knuth, 1993] solves the simpler sum of powers problem Pnk=1 kp :
where Bj is a Bernoulli number defined as
The original problem can be reduced to a sum of powers in the following manner, where t↪ r↪ s↪ v↪w are families of monomials (possibly including numeric constants) in the free variables:
3 Strictly speaking, the complexity is logarithmic in the domain size, if arbitrarily large numbers and infinite precision are employed, but constant for all practical purposes.
= w0 +w1 + · · · +wn0 (since n is a known constant)
where n0 is function of n in O(n4 ) (the time complexity for computing Bernoulli numbers up to Bn is in O(n2 )).
Because the time and space complexity of the above computation depends on the initial degree n and the degrees of free variables in the monomials, it is important to understand how these degrees are affected. Let dl be the initial degree of the variable present in l in t monomials. Its degree is up to n in r monomials (because of the binomial expansion with i being up to n), and thus up to dl +n in s monomials (because of the multiplication of ti and rq). The variable has degree up to n + 1 in monomials v, with degree up to dl + 2n + 1 in the final polynomial. The variable in u keeps its initial degree du until it is increased by up to n + 1 in v, with final degree up to du + n + 1. The remaining variables keep their original degrees. This means that degrees grow only linearly over multiple applications of the above. This combines with the O(n4 ) per-step complexity to a O(n5 ) overall complexity for n the maximum initial degree for any variable. Note how this time complexity is constant in x's domain size.
@inproceedings{ijcai2016p506,
  title     = {Probabilistic Inference Modulo Theories},
  author    = {Braz, Rodrigo de Salvo and O'Reilly, Ciaran and Gogate, Vibhav and Dechter, Rina},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {3591--3598},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/506},
}
TY - CPAPER TI - Probabilistic Inference Modulo Theories AU - Braz, Rodrigo de Salvo AU - O'Reilly, Ciaran AU - Gogate, Vibhav AU - Dechter, Rina T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 3591 EP - 3598 UR - https://ijcai.org/proceedings/2016/506 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





