
Toward a Robust and Universal Crowd-Labeling Framework
Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence. Pages 4006-4006.
Abstract
One of the main challenges in crowd-labeling is to control for or determine in advance the proportion of low-quality/malicious labelers. We propose methods that estimate the labeler and data instance related parameters using frequentist and Bayesian approaches. All these approaches are based on expert-labeled instance (ground truth) for a small percentage of data to learn the parameters. We also derive a lower bound on the number of expert-labeled instances needed to get better quality labels.
- [Asuncion and Newman, 2007] A. Asuncion and D.J Newman. UCI machine learning repository. In University of California, Irvine. School of Information and Computer Sciences, 2007.
- [Bradley and Terry, 1952] Ralph Allan Bradley and Milton Terry. Ranking analysis of incomplete block design: I. the method of paired comparisons. In Biometrika, pages 324-345, 1952.
- [Dawid and Skene, 1979] A. P. Dawid and A. M. Skene. Maximum likelihood estimation of observer error-rates using the EM algo- rithm. Applied Statistics, 28:20-28, 1979.
- [Huang et al., 2006] Tzu-Kuo Huang, Chih-Jen Lin, and Ruby C. Weng. Ranking individuals by group comparisons. In Inter- national Conference on Machine Learning (ICML), ICML '06, pages 425-432, New York, NY, USA, 2006.
- [Karger et al., 2014] David R. Karger, Sewoong Oh, and Devavrat Shah. Budget-optimal task allocation for reliable crowdsourcing systems. Operations Research, 62(1):1-24, 2014.
- [Khattak and Salleb-Aouissi, 2011] Faiza Khan Khattak and Ansaf Salleb-Aouissi. Quality control of crowd labeling through ex- pert evaluation. In NIPS 2nd Workshop on Computational Social Science and the Wisdom of Crowds, Granada, Spain., 2011.
- [Khattak and Salleb-Aouissi, 2013] Faiza Khan Khattak and Ansaf Salleb-Aouissi. Robust crowd labeling using little expertise. In Sixteenth International Conference on Discovery Science, Singa- pore, 2013.
- [Khattak and Salleb-Aouissi, 2015] Faiza K. Khattak and Ansaf Salleb-Aouissi. An item response theory (IRT) like approach to crowd-labeling. In Workshop for Women in Machine Learning (WiML 2015) held in conjunction with NIPS, Montreal, Canada. 2015., 2015.
- [Khattak and Salleb-Aouissi, 2016] Faiza K. Khattak and Ansaf Salleb-Aouissi. Robust Crowd Labeling using Expert evaluation and Pairwise Comparison. Submitted to Journal of Artificial In- telligence. Special Track on Human Computation and AI, 2016.
- [Liu et al., 2012] Qiang Liu, Jian Peng, and Alex Ihler. Variational inference for crowdsourcing. In NIPS, 2012.
- [Lord, 1952] F. Lord. A Theory of Test Scores. Psychometric Mono- graph No. 7, 1952.
- [Whitehill et al., 2009] Jacob Whitehill, P. Ruvolo, T. Wu, J. Bergsma, and J. Movellan. Whose vote should count more: Optimal integration of labels from labelers of unknown expertise. In NIPS, pages 2035-2043, 2009.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Crowd-labeling is the process of having a human crowd label a large dataset. It is well-known that the precision and accuracy of labeling can vary due to differing skill sets. The labelers can be good/experienced, random/careless or even malicious. If the proportion of malicious labelers grows too high, there is often a phase transition leading to a steep, nonlinear drop in labeling accuracy as noted by [Karger et al., 2014]. We propose methods for a robust and accurate crowdlabeling system that delays the phase transition. Our hypothesis is that using some expert-labeled instances (ground truth) can help us get insight about the labeler-ability as well as instance-difficulty, which can help in improving the accuracy of the aggregated final label. We propose a frequentist and a Bayesian approaches to learn these parameters.
2 Frequentist Approach
Based on our hypothesis, we propose the first version of Expert Label Injected Crowd Estimation (ELICE) [Khattak and Salleb-Aouissi, 2011]. We estimate the labeler-ability ↵ and instance-difficulty β based on a few (usually 0.1% -10% of the whole dataset) expert-labeled instances as:
↵j = 1n Pni=1 [1(Li = lij) - 1(Li 6= lij)]↪ βi = 1M PMj=1 [1(Li = lij)]↪ where Li is the true label for instance i↪ lij is the label given by labeler j to instance, i↪ j = 1↪ ▷ ▷ ▷ ↪M and i = 1↪ ▷ ▷ ▷ ↪ n▷ Next β's for the rest of
Label aggregation is done by using logistic function (σ).
ELICE 1 [Khattak and Salleb-Aouissi, 2011] is efficient as well as effective. It assigns high weights to the good labelers' annotation to identify the correct final labels. To further squeeze information, even from the malicious labelers, we proposed ELICE 2 [Khattak and Salleb-Aouissi, 2013]. In this method, we introduce entropy as a way to estimate the uncertainty of labeling. This provides an advantage of differentiating between good, random and malicious labelers. The aggregation method for ELICE version 2 flips the label (for binary classification case) provided by the malicious labeler thus utilizing the information that is generally discarded by other labeling methods. We define labeler-ability (↵) and instance-difficulty (β) as:
ILi = sign( 1M PMj=1 σ(↵jβi) ⇤ lij)
Ai = sign(PMj=1 σ(♣c↵jβi♣) ⇤ Lij ⇤ sign(↵jβi)) The βs for the rest of the data are estimated using equation 1. Here c is the scaling factor and sign(↵β) is used to flip the label provided by the malicious labeler i.e., when ↵ is negative. Both versions of ELICE have a cluster-based variant in which rather than making a random choice of instances from the whole dataset, clusters of data are first formed using any clustering approach e.g., K-means.
βi = (p0i - q0i )(1 - E0 i ) +1↪ E0 i = -p0i log(p0i ) - q0i log(q0i ) where p0i = M+ i M ↪ q0i = 1-p0i , p0i is the probability of getting a correct label for instance i, from the crowd labeler andM + i is the number of correct labels given to the instance i. All these values are calculated using the expert labeled instances. Then ↵↪ β are used for label aggregation as follows:
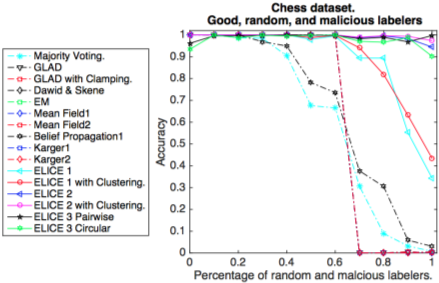
The motivation behind developing the third version of ELICE [Khattak and Salleb-Aouissi, 2016] was to further improve the accuracy by using the crowd-labels, which unlike expertlabels, are available for the whole dataset and may provide a more comprehensive view of the labeler ability and instance difficulty. This is especially helpful for the case when the domain experts do not agree on one label and ground truth is not known for certain. Therefore, incorporating more information beyond expert-labels can provide better results. Besides taking advantage of expert-labeled instances, the third version of ELICE, incorporates pairwise/circular comparison of labelers to labelers and instances to instances. In this variant of ELICE, we use a generalization of the model in [Bradley and Terry, 1952; Huang et al., 2006]. We show empirically that our approaches are robust even in the presence of a large proportion of low-quality labelers in the crowd (Figure 1). Furthermore, we derive a lower bound of the number of expert labels needed [Khattak and Salleb-Aouissi, 2013].
3 Bayesian Approach
Currently, we are exploring Bayesian method for parameter estimation. Our new approach [Khattak and Salleb-Aouissi, 2015] is inspired by Item Response Theory (IRT) [Lord, 1952]. IRT aims to design and analyze test scoring strategies by modeling student ability, question difficulty, question clarity and probability of correctness of the answer to the question. Similarly in crowd-labeling, we model labeler ability, instance difficulty, clarity of the question about the instance and probability of correctness of label. The crowd-labeling scenario is more challenging, as unlike IRT model, the parameters as well as final labels are unknown. To deal with this challenge, we use expert-labeled instance (ground truth) for a small percentage of data to learn the parameters. These parameters are used for aggregation of multiple crowd-labels for the rest of the dataset with no ground truth available. Our newmodel is as follows:
P [c♣yij = c↪ γc↪ βi↪ δi↪ ⇡(j) c ] = [logit-1 (δi(γc + ⇡(j) c - βi))] where c 2 ¶-1↪ 1♦: class/category, yij: Label provided by labeler j to instance i↪ ⇡(j) c : per-class ability of labeler j↪ βi : difficulty of instance i↪ γc: prevalence of class c, δi : clarity of question asked about instance i▷ Experiments are ongoing.
4 Conclusion
We propose a set of methodologies to advance the state-ofthe-art in crowd-labeling methods using a handful expertlabeled instances. Our future plans include developing methodologies for analyzing and modeling labeler's variable performance due to fatigue, stress and boredom. We hope that it will help in further improving crowd-labeling accuracy.
@inproceedings{ijcai2016p577,
  title     = {Toward a Robust and Universal Crowd-Labeling Framework},
  author    = {Khattak, Faiza Khan},
  booktitle = {Proceedings of the Twenty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-16}},
  publisher = {AAAI Press / International Joint Conferences on Artificial Intelligence},
  editor    = {Subbarao Kambhampati},
  pages     = {4006--4006},
  year      = {2016},
  month     = {7},
  url       = {https://ijcai.org/proceedings/2016/577},
}
TY - CPAPER TI - Toward a Robust and Universal Crowd-Labeling Framework AU - Khattak, Faiza Khan T2 - Proceedings of the Twenty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-16 PB - AAAI Press / International Joint Conferences on Artificial Intelligence PY - 2016 SP - 4006 EP - 4006 UR - https://ijcai.org/proceedings/2016/577 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





