
Scalable Semi-Supervised SVM via Triply Stochastic Gradients
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2364-2370.
https://doi.org/10.24963/ijcai.2019/328
Keywords
- Machine Learning: Data Mining
- Machine Learning: Classification
Abstract
Semi-supervised learning (SSL) plays an increasingly important role in the big data era because a large number of unlabeled samples can be used effectively to improve the performance of the classifier. Semi-supervised support vector machine (S3VM) is one of the most appealing methods for SSL, but scaling up S3VM for kernel learning is still an open problem. Recently, a doubly stochastic gradient (DSG) algorithm has been proposed to achieve efficient and scalable training for kernel methods. However, the algorithm and theoretical analysis of DSG are developed based on the convexity assumption which makes them incompetent for non-convex problems such as S3VM. To address this problem, in this paper, we propose a triply stochastic gradient algorithm for S3VM, called TSGS3VM. Specifically, to handle two types of data instances involved in S3VM, TSGS3VM samples a labeled instance and an unlabeled instance as well with the random features in each iteration to compute a triply stochastic gradient. We use the approximated gradient to update the solution. More importantly, we establish new theoretic analysis for TSGS3VM which guarantees that TSGS3VM can converge to a stationary point. Extensive experimental results on a variety of datasets demonstrate that TSGS3VM is much more efficient and scalable than existing S3VM algorithms.
- [Bennett and Demiriz, 1999] Kristin P Bennett and Ayhan Demiriz. Semi-supervised support vector machines. In Advances in Neural Information processing systems, pages 368-374, 1999.
- [Cai and Cherkassky, 2012] Feng Cai and Vladimir Cherkassky. Generalized smo algorithm for svm- based multitask learning. IEEE transactions on neural networks and learning systems, 23(6):997-1003, 2012.
- [Carratino et al., 2018] Luigi Carratino, Alessandro Rudi, and Lorenzo Rosasco. Learning with sgd and random fea- tures. In Advances in Neural Information Processing Sys- tems, pages 10213-10224, 2018.
- [Chang and Lin, 2011] Chih-Chung Chang and Chih-Jen Lin. LIBSVM: A library for support vector machines. ACM Transactions on Intelligent Systems and Technology, 2:27:1-27:27, 2011.
- [Chapelle and Zien, 2005] Olivier Chapelle and Alexander Zien. Semi-supervised classification by low density sepa- ration. In AISTATS, volume 2005, pages 57-64. Citeseer, 2005.
- [Chapelle, 2007] Olivier Chapelle. Training a support vector machine in the primal. Neural computation, 19(5):1155- 1178, 2007.
- [Collobert et al., 2006] Ronan Collobert, Fabian Sinz, Jason Weston, and Léon Bottou. Large scale transductive svm- s. Journal of Machine Learning Research, 7(Aug):1687- 1712, 2006.
- [Dai et al., 2014] Bo Dai, Bo Xie, Niao He, Yingyu Liang, Anant Raj, Maria-Florina F Balcan, and Le Song. Scalable kernel methods via doubly stochastic gradients. In Ad- vances in Neural Information Processing Systems, pages 3041-3049, 2014.
- [Drineas and Mahoney, 2005] Petros Drineas and Michael W Mahoney. On the nyström method for approximating a gram matrix for improved kernel- based learning. journal of machine learning research, 6(Dec):2153-2175, 2005.
- [Ghadimi and Lan, 2013] Saeed Ghadimi and Guanghui Lan. Stochastic first-and zeroth-order methods for non- convex stochastic programming. SIAM Journal on Opti- mization, 23(4):2341-2368, 2013.
- [Gu et al., 2018a] Bin Gu, Zhouyuan Huo, Cheng Deng, and Heng Huang. Faster derivative-free stochastic algorithm for shared memory machines. In International Conference on Machine Learning, pages 1807-1816, 2018.
- [Gu et al., 2018b] Bin Gu, Yingying Shan, Xiang Geng, and Guansheng Zheng. Accelerated asynchronous greedy co- ordinate descent algorithm for svms. In IJCAI, pages 2170-2176, 2018. IJCAI
- [Gu et al., 2018c] Bin Gu, Miao Xin, Zhouyuan Huo, and Heng Huang. Asynchronous doubly stochastic sparse k- ernel learning. In Thirty-Second AAAI Conference on Ar- tificial Intelligence, 2018.
- [Gu et al., 2018d] Bin Gu, Xiao-Tong Yuan, Songcan Chen, and Heng Huang. New incremental learning algorithm for semi-supervised support vector machine. In Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining, pages 1475-1484. ACM, 2018.
- [Huo et al., 2018] Zhouyuan Huo, Bin Gu, and Heng Huang. Training neural networks using features replay. In Ad- vances in Neural Information Processing Systems, pages 6659-6668, 2018.
- [Joachims, 1999] Thorsten Joachims. Transductive inference for text classification using support vector machines. In Icml, volume 99, pages 200-209, 1999.
- [Le et al., 2016] Trung Le, Phuong Duong, Mi Dinh, Tu D- inh Nguyen, Vu Nguyen, and Dinh Q Phung. Budgeted semi-supervised support vector machine. In UAI, 2016.
- [Li et al., 2017] Xiang Li, Bin Gu, Shuang Ao, Huaimin Wang, and Charles X Ling. Triply stochastic gradients on multiple kernel learning. In UAI, 2017.
- [Lopez-Paz et al., 2014] David Lopez-Paz, Suvrit Sra, Alex Smola, Zoubin Ghahramani, and Bernhard Schölkopf. Randomized nonlinear component analysis. Computer Science, 4:1359-1367, 2014.
- [Rahimi and Recht, 2008] Ali Rahimi and Benjamin Recht. Random features for large-scale kernel machines. In Ad- vances in neural information processing systems, pages 1177-1184, 2008.
- [Wang et al., 2007] Junhui Wang, Xiaotong Shen, and Wei Pan. On transductive support vector machines. Contem- porary Mathematics, 443:7-20, 2007.
- [Wendland, 2004] Holger Wendland. Scattered data approx- imation, volume 17. Cambridge university press, 2004.
- [Xie et al., 2015] Bo Xie, Yingyu Liang, and Le Song. Scale up nonlinear component analysis with doubly stochastic gradients. In Advances in Neural Information Processing Systems, pages 2341-2349, 2015.
- [Yuille and Rangarajan, 2002] Alan L Yuille and Anand Rangarajan. The concave-convex procedure (cccp). In Advances in neural information processing systems, pages 1033-1040, 2002.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Semi-supervised learning (SSL) plays an increasingly important role in the big data era because a large number of unlabeled samples can be used effectively to improve the performance of the classifier. Semi-supervised support vector machine (S3VM) [Bennett and Demiriz, 1999] is one of the most appealing methods for SSL. Specifically, S3VM enforces the classification boundary to go across the less-dense regions in the reproducing kernel Hilbert space (RKHS), while keeping the labeled data correctly classified. Unfortunately, this will lead to a non-convex optimization problem. It is well known that solving a non-convex optimization problem is normally difficult than solving a convex one like standard support vector machine. Under this arduous challenge, a wide spectrum of methods for S3VM have been proposed in the last two decades. Generally speaking, these methods can be roughly divided into three groups, i.e., methods with self-labeling heuristics, concave-convex procedure (CCCP) methods and gradient-based methods. We give a brief review of these representative S3VM methods in Section 2 and Table 1.
∗To whom all correspondence should be addressed.
Unfortunately, these traditional S3VM methods are inefficient due to increased complexity introduced by the cost of kernel computation as well as non-convexity. Specifically, the kernel matrix needs O(n2d) operations to be calculated and O(n2 ) memory to be stored, where n denotes the size of training samples and d denotes dimension of the data [Gu et al., 2018b]. Essentially, gradient-based S3VMmethods have O(n3 ) complexity due mainly to the operations on the kernel matrix. Even though a convex kernel problem can be solved by a state-of-the-art solver (e.g. LIBSVM), O(nκ ) computation is still needed where 1 < κ < 2.3 [Chang and Lin, 2011]. While to handle the non-convexity of S3VM, the methods using self-labeling heuristics and CCCP-based algorithms need to solve multiple convex sub-problems to guarantee that they finally converge [Yuille and Rangarajan, 2002]. As a result, these methods scale as O(tnκ ), where t denotes the number of solving sub-problems. We summarize the computational complexities and memory requirements of the representative S3VMmethods in Table 1. As pointed in [Gu et al., 2018d], scaling up S3VM is still an open problem.
Recently, a novel doubly stochastic gradient (DSG) method [Dai et al., 2014] was proposed to achieve efficient and scalable training for kernel methods. Specifically, in each iteration, DSG computes a doubly stochastic gradient by sampling a random data sample and the corresponding random features to update the solution. Thus, DSG avoids computing and storing a kernel matrix, while enjoying nice computational and space complexities. Xie et al. [2015] used DSG to scale up nonlinear component analysis. To the best of our knowledge, [Xie et al., 2015] is the only work based on DSG to solve a non-convex problem.
However, existing algorithms and theoretical analysis of DSG cannot be applied to S3VM due to the following two reasons. 1) Multiple data distributions: S3VM minimizes the training errors coming from two different sources. One is the expected error on the unlabeled data, and the other one is the mean error on the labeled data whose size is normally significantly smaller than the one of unlabeled data. However, DSG only considers the expected error on the labeled data. 2) Non-convexity analysis: The theoretical analysis in [Xie et al., 2015] is based on a strong assumption (i.e., the initialization needs to be close to the optimum). However, such an assumption is rarely satisfied in practice. Besides, they focus on the nonlinear component analysis instead of general nonconvex problems. Thus, it is infeasible to extend the analysis of [Xie et al., 2015] to S3VM.
| Algorithm | Reference | Method | Computational Complexity | Space Complexity |
|---|---|---|---|---|
| S3VMlight NTS3VM BGS3VM BLS3VM ILS3VM TSGS3VM | [Joachims, 1999] [Chapelle, 2007] [Le et al., 2016] [Collobert et al., 2006] [Gu et al., 2018d] Our | Self-labeling heuristics Gradient-based Gradient-based CCCP-based CCCP-based TSG | O(tnκ ) O(n3 ) O(n3 ) O(tnκ ) ≈ O(T n2 ) O(mT 2 ) | O(n2 ) O(n2 ) O(n2 ) O(n2 ) O(n2 ) O(T ) |
To address this challenging problem, we first propose a new and practical formulation of S3VM. Then, we develop a new triply stochastic gradient algorithm (TSGS3VM) to solve the corresponding optimization problem. Specifically, to handle two types of data instances involved in S3VM, TSGS3VM samples a labeled instance and an unlabeled instance as well with their random features in each iteration to compute a triply stochastic gradient (TSG). We then use the TSGs to iteratively update the solution. A critical question is whether and how fast this optimization process with multiple randomness would converge. In addressing this concern, we establish new theoretic analysis for TSGS3VM which guarantees that TSGS3VM can converge to a stationary point with a sublinear convergence rate for a general non-convex learning problem under weak assumptions. Extensive experimental results demonstrate the superiority of TSGS3VM.
Novelties. We summary the main novelties of this paper as follows.
- To scale up S3VM, we propose a practical formulation of S3VM and develop a novel extension of DSG that could solve optimization problems with multiple data sources.
- We have established the new theoretic analysis of TSGS3VM algorithm for a general non-convex learning problem which guarantees its convergence to a stationary point. To the best of our knowledge, it is the first work offering non-convex analysis for DSG-like algorithms without initialization assumption.
2 RelatedWorks
We give a brief review of kernel approximation methods as well as the representative S3VMmethods.
Kernel Approximation. There are many kernel approximation methods proposed to address the scalability issue of kernel methods. For instance, low-rank factors are used to approximate the kernel matrix in [Drineas and Mahoney, 2005]. Rahimi & Recht [2008] provided another method that uses random features to approximate the map function explicitly. However, as analyzed in [Drineas and Mahoney, 2005; Lopez-Paz et al., 2014], the rank for low-rank and the number of random features need to be O(n) to obtain a good generalization ability. To further improve the random features method, Dai et al. [2014] proposed DSG descent algorithm. Carratino et al. [2018] proved that DSG only need O(√n) random features to obtain a good result. However, existing DSG methods [Li et al., 2017; Gu et al., 2018c] can not be used for S3VM as discussed previously.
S3VM Methods. As mentioned above, traditional S3VM methods can be roughly divided into three types, i.e., the method of self-labeling heuristics, the concave-convex procedure (CCCP) method, and the gradient-based method. For the method of self-labeling heuristics, Joachims [1999] proposed a S3VMlight algorithm which uses self-labeling heuristics for labeling the unlabeled data, then iteratively solve this standard SVM until convergence. CCCP-based methods were proposed to solve S3VM in [Chapelle and Zien, 2005; Wang et al., 2007]. The basic principle of CCCP is to linearize the concave part of S3VM's objective function around a solution obtained in the current iteration so that subproblem is convex. Then the CCCP framework solves a sequence of the convex sub-problem iteratively until decision variable converges. Based on CCCP framework, Gu et al. [Gu et al., 2018d] proposed an incremental learning method for S3VM which is suitable for the online scenario. For gradient-based methods, Chapelle and Zien [2005] approximate the kernel matrix K using low-rank factors, then using gradient descent to solve S3VM on the low-rank matrix. BGS3VM [Le et al., 2016] uses budgeted SGD to limit the model size to two predefined budgets Bl and Bu.
3 Preliminaries
In this section, we first give a general non-convex learning problem for S3VM, and then give a brief review of random feature approximation.
3.1 S3VMOptimization Formulation
Given the training dataset X constituted with nl labeled examples L := {(xi, yi)}nl i=1 and nu unlabeled examples U :=
| Name | u(r) | u′ (r) |
|---|---|---|
| SHG | max{0, 1- |r|} | { 0 if |r| ≥ 1 -1 if |r| < 1 |
| SSHG | 12 max{0, 1- |r|}2 | { 0 if |r| ≥ 1 |r| - 1 if |r| < 1 |
| Ramp DA | H1(r) -Hs(r) exp(-5r2 ) | H′1(r) - H′s(r) -10r · exp(-5r2 ) |
{xi}ni=nl+1 , where n = nl +nu , xi ∈ Rd , and yi ∈ {1, -1}. Traditional S3VM solves the following problem.
where C and C ∗ are regularization parameters, || · ||H denotes the norm in RKHS, l(r, v) = max(0, 1-vr) is the hinge loss, its subgradient l′ (r, v) = 0, if rv ≥ 1, else l′ (r, v) = -v, u(r) is the non-convex loss function which enforce unlabeled data away from the discrimination hyperplane. We summarize the commonly used non-convex S3VM losses and its subgradient u′ (r) in Table 2.
For S3VM problems, however, the volumes of labeled and unlabeled data are usually quite different. Because of the labeling cost, the labeled dataset is often very small, while a large amount of unlabeled data can be obtained relatively easily. Taking this into consideration, we propose to solve a novel S3VM formulation as follows.
where P(x) denotes the target data distribution. Notice that we use the empirical mean error on the labeled dataset, while using the expected error on the whole distribution for the unlabeled data.
3.2 RandomFeature Approximation
Random feature is a powerful technique to make kernel methods scalable. It uses the intriguing duality between kernels and stochastic processes. Specifically, according to the Bochner theorem [Wendland, 2004], for any positive definite PD kernel k(·, ·), there exists a set Ω, a probability measure P and a random feature map φω(x), such that k(x, x′ ) = ∫Ω φω(x)φω(x′ )dP(ω). In this way, the value of the kernel function can be approximated by explicitly computing random features φω(x) = [ 1 √m φω1 (x), 1 √m φω2 (x), · · · , 1 √m φωm (x)], i.e.,
where m is the number of random features. Using Gaussian RBF kernel as a concrete example, it yields a Gaussian distribution P(ω) over random feature maps of Fourier basis functions φωi (x) = √2cos(ωT i x + b) to compute its feature mapping, where ωi is drawn from P(ω) and b is drawn uniformly form [0, 2π]. Moreover, many random feature construction methods have been proposed for various kernels, such as dotproduct kernels and Laplacian kernels.
The theory of RKHS provides a rigorous mathematical framework for studying optimization problems in the functional space. Specifically, we know that every PD kernel k(x, x′ ) has a corresponding RKHS H. An RKHS H has the reproducing property, i.e., ∀x ∈ X, ∀f ∈ H, we always have 〈f(·), k(x, ·)〉H = f(x). Besides, functional gradient in RKHS H can be computed as ∇f(x) = k(x, ·) and ∇||f ||2H = 2f .
4 Triply Stochastic S3VM
The above section has introduced the basic theoretic tools for triply stochastic functional gradient descent. Now we introduce how to utilize these tools to solve the S3VM problem.
4.1 Triply Stochastic Gradient
From Eq. (1), it is not hard to notice that R(f) involves two different data sources. Taking into consideration the distribution of random features ω ∼ P(ω) would give us three sources of possible randomness. Here we will show how to explicitly compute the stochastic gradient with these three sources of randomness.
Stochastic Functional Gradients. Naturally, to iteratively update f in a stochastic manner, we need to sample instances from the labeled dataset as well as the whole distribution. Different from DSG, we here randomly sample a pair of data points, from the labeled and the unlabeled data distributions, respectively. Then we can obtain stochastic functional gradients for R(f) with these two data points as follow,
where ξ(·) is the gradient contributed by the loss from both labeled and unlabeled data. It can be computed using the chain rule
where xl , xu are sampled from the labeled dataset and unlabeled distribution P(x) respectively. Next we will plugging the random feature approximation technique described in the previous section.
Random Feature Approximation. According to Eq. (2), when we use stochastically generated random feature ω, we can further approximate ξ(·) as:
note that ξ(·) = Eω[ζ(·)]. This leads to an unbiased estimator of the original functional gradient with three layers of stochasticity, i.e.,
Since three random events occur per iteration, i.e. xl , xu , ω, we call our approximate functional gradient as triply stochastic functional gradient.
Update Rules. In the t-th iteration, the triply stochastic (functional) gradient update rule for f is:
where γ denotes the step size and the initial value f1(·) = 0. It is straight forward to calculate that ait = -γi ∏tk=i+1 (1 - γk). Ideally, if we could somehow compute the stochastic (functional) gradients ξj(·), the update rule becomes:
where we have used ht+1 instead of ft+1 to distinguish from the triply stochastic (functional) gradient update rule and h1(·) = 0. However, to avoid the expense of kernel computation, our algorithm will use the triply stochastic update rule Eq. (7) instead of Eq. (8).
4.2 Algorithm
Based on the above triply stochastic gradient update rules (7), we provide the TSGS3VM training and prediction procedures in Algorithms 1 and 2 receptively. Notice that directly computing all the random features still needs a large amount of memory. Following the pseudo-random number generators setting of [Dai et al., 2014], our random feature generator is initialized by a predefined seed according to iteration. Thus, TSGS3VM does not need to save the random feature matrix which makes it more memory friendly. In the i-th iteration, our method will execute the following steps.
- Sample data pair (lines 2-3 in Algorithm 1): Stochastically sample a labeled sample (xli , yl i ) and an unlabeled sample xui from different distribution respectively.
- Sample random features (line 4 in Algorithm 1): Stochastically sample ωi ∼ P(ω) with seed i and generate random features.
- Update coefficients (lines 5-8 in Algorithm 1): Evaluate function value and update f according to Eq. (7).
Remark 1 For each iteration, TSGS3VM needs O(mT) operations to evaluate function value, since evaluating the function value needs generating m random features (O(m)) for T times. Thus, the total computational complexity of TSGS3VM is O(mT 2 ). Due to the use of random features and pseudorandom method, TSGS3VM only requires O(T) memory, where T is the iteration number.
5 Theoretical Guarantees
We follow the common goal of non-convex analysis [Ghadimi and Lan, 2013; Gu et al., 2018a; Huo et al., 2018] to bound E||∇R(f)||2 , which means that the objective function will converge (in expectation) to a stationary point f∗. When we use the hypothetical update rule (8), ht will always be inside
Algorithm 1 TSGS3VM Train
Input: L, P(x), P(ω), φω(x), u(f(x)),C,C ∗
- 1: for i = 1, · · · , T do
- 2: Sample (xli , yl i ) ∼ L
- 3: Sample xui ∼ P(x)
- 4: Sample ωi ∼ P(ω) with seed i
- 5: f(xli ) = Predict(xli , {αj}i-1 j=1 )
- 6: f(xui ) = Predict(xui , {αj}i-1 j=1 )
- 7: αi = -γi(Cl′ (f (xli ), yl i )φωi (xli ) + C ∗u′ (f(xui ))φωi (xui ))
- 8: αj = (1 -γi)αj, for j = 1, · · · , i -1
- 9: end for
Output: {αi}Ti=1 .
Algorithm 2 TSGS3VM Predict
Input: P(ω), φω(x), x, {αi}Ti=1
- 1: Set f(x) = 0
- 2: for i = 1, · · · , T do
- 3: Sample ωi ∼ P(ω) with seed i
- 4: f(x) = f(x) +αiφωi (x)
- 5: end for
Output: f(x)
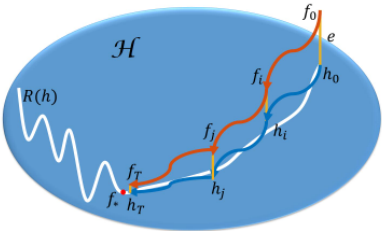
of H. However, because we could only use random features to approximate ht with ft, we face the risk that functional ft could be outside of H. As a consequence, E||∇R(f)||2H = 0 is not the stationary point of the objective function (1). From Eq. (7) and Eq. (8), it is obvious that every update of ht happens implicitly with an update of ft(x). According to this relationship, we proposed to divide the analysis in two parts. As illustrated in Fig. 1, for a general non-convex optimization problem R(h), we prove that the ht+1 converges to a stationary point f∗ (i.e., E||∇R(ht+1)||2H < ϵ1) firstly. Then we prove that ft+1(x) keeps close to its hypothetic twin ht+1(x) for any x ∈ X (i.e., |ft+1(x) - ht+1(x)|2 < ϵ2).
Our analysis is built upon the following assumptions which are standard for the analysis of non-convex optimization and DSG [Dai et al., 2014].
Assumption 1 (Lipschitzian gradient) The gradient function
| Dataset | Dimensionality | Samples | Source |
|---|---|---|---|
| CodRNA | 8 | 59,535 | LIBSVM |
| W6a | 300 | 49749 | |
| IJCNN1 | 22 | 49,990 | |
| SUSY | 18 | 5,000,000 | |
| Skin | 3 | 245,057 | |
| Higgs | 28 | 1,100,000 | |
| Dota2 | 16 | 102,944 | UCI |
| HEPMASS | 28 | 10,500,000 |
∇R(f) is Lipschitzian, that is to say
Assumption 2 (Lipschitz continuity) l(r, v) is L′ -Lipschitz continuous in terms of its 1st argument. u(r, v) is U ′ - Lipschitz continuous in terms of its 1st argument. We further denote M ′ = CL′ + C ∗U ′ .
Assumption 3 (Bound of derivative) The derivatives are bounded: |l′ | < M l and |u′ | < M u , where l′ and u′ is the derivative of l(r, v) and u(r) w.r.t. the 1st argument respectively. We further denote M = CM l + C ∗M u .
Assumption 4 (Bound of kernel and random features) We have an upper bound for the kernel value, k(x, x′ ) ≤ κ. There is an upper bound of random feature norm, i.e., |φω(x)φω(x′ )| ≤ φ.
Suppose the total number of iterations is T , we introduce our main theorems as below. All the detailed proofs are provided in our Appendix 1 .
Theorem 1 For any x ∈ X, fix γ = θ T 3/4 with 0 < θ ≤ T 3/4 , we have
Remark 2 The error between ft+1 and ht+1 is mainly induced by random features. Theorem 1 shows that this error has the convergence rate of O(1/√T) with proper step size.
Theorem 2 For fixed γ = θ T 3/4 , 0 < θ ≤ T 3/4 , we have that
1 The Appendix is available at https://drive.google.com/open?id= 1iVE5hMJ-DbA87K9skuvL4c250OMBD4EG.
where E = 1 θ [R(h1) - R∗ ] + θM 2M ′ (√κ + √φ)κ, F = 2θM 2Lκ, R∗ denotes the optimal value of (1).
Remark 3 Instead of using the convexity assumption in [Dai et al., 2014], Theorem 2 uses Lipschitzian gradient assumption to build the relationship between gradients and the updating functions ht+1. Thus, we can bound each error term of Exl ,xu ,ωt [||∇R(ht)||2H] as shown in Appendix. Note that compared to the strong assumption (i.e., the good initialization) used in [Xie et al., 2015], the assumptions used in our proofs are weaker and more realistic.
6 Experiments and Analysis
In this section, we will evaluate the practical performance of TSGS3VM when comparing against other state-of-the-art solvers.
6.1 Experimental Setup
To show the advantage our TSGS3VM for large-scale S3VM learning, we conduct the experiments on large scale datasets to compare TSGS3VM with other state-of-the-art algorithms in terms of predictive accuracy and time consumption. Specifically, the compared algorithms in our experiments are summarized as follows 2 .
- BLS3VM [Collobert et al., 2006]: The state-of-art S3VM algorithm based on CCCP and SMO algorithm [Cai and Cherkassky, 2012].
- S3VMlight [Joachims, 1999]: The implementation in the popular S3VMlight software. It is based on the local combinatorial search guided by a label switching procedure.
- BGS3VM[Le et al., 2016]: Our implementation of BGS3VM in MATLAB.
- FRS3VM: Standard SGD with fixed random features.
- TSGS3VM: Our proposed S3VM algorithm via triply stochastic gradients.
Implementation. We implemented the TSGS3VM algorithm in MATLAB. For the sake of efficiency, our TSGS3VM implementation also uses a mini-batch setting. We perform experiments on Intel Xeon E5-2696 machine with 48GB RAM. The Gaussian RBF kernel k(x, x′ ) = exp(-σ||x - x′ ||2 ) and the loss function u = max{0, 1-|r|} was used for all algorithms. 5-fold cross-validation was used to determine the optimal settings (test error) of the model parameters (the regularization factor C and the Gaussian kernel parameter σ), the parameters C ∗ was set to C nl nu . Specifically, the unlabeled dataset was divided evenly to 5 subsets, where one of the subsets and all the labeled data are used for training, while the other 4 subsets are used for testing. Parameter search was done on a 7×7 coarse grid linearly spaced in the region {log10 C, log10 σ)| - 3 ≤ log10 C ≤ 3, -3 ≤ log10 σ ≤ 3} for all methods. For TSGS3VM, the step size γ equals 1 η , where 0 ≤ log10 η ≤ 3 is searched after C and σ. Besides, the number of random features is set to be ⌈√n⌉ and the batch size is set to 256. The test error was obtained by using these optimal model parameters for all the methods. To achieve a comparable accuracy to our TSGS3VM, we set the minimum budget sizes Bl and Bu as 100 and 0.2 ∗ nu respectively for BGS3VM. We stop TSGS3VM and BGS3VM after one pass over the entire dataset. We stop FRS3VM after 10 pass over the entire dataset to achieve a comparable accuracy. All results are the average of 10 trials.
2 BLS3VM and S3VMlight can be found in
Datasets. Table 3 summarizes the 8 datasets used in our experiments. They are from LIBSVM 3 and UCI 4 repositories. Since all these datasets are originally labeled, we intentionally randomly sample 200 labeled instances and treat the rest of data as unlabeled to make a semi-supervised learning setting.
6.2 Experimental Results
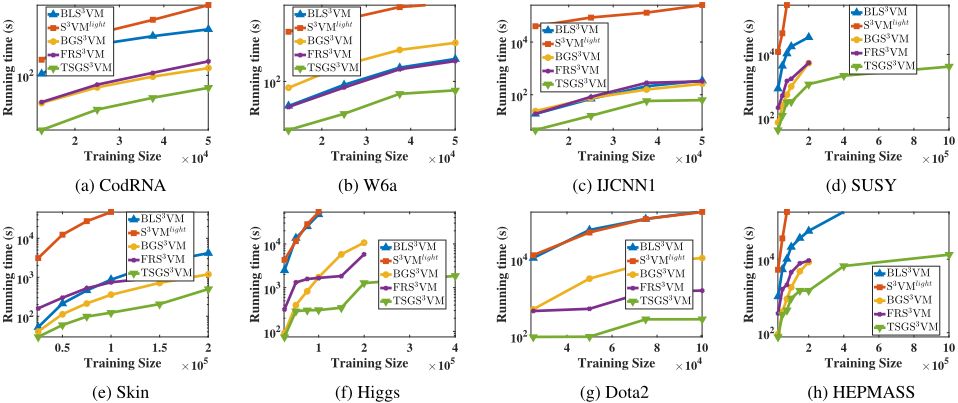
Fig. 2 shows the test error v.s. the training size for different algorithms. The results clearly show that TSGS3VM runs much faster than other methods. Specifically, Figs. 2d and 2h confirm the high efficiency of TSGS3VM even on the datasets with one million samples. Besides, TSGS3VM requires low memory benefiting from pseudo-randomness for generating random features, while BLS3VM and S3VMlight would be often out of memory on large scale datasets.
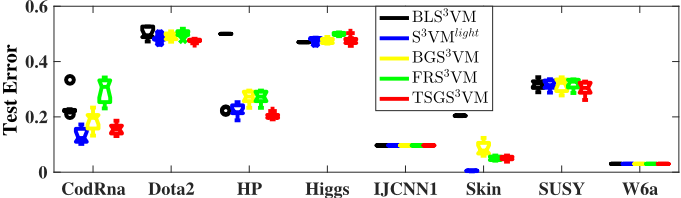
Fig. 3 shows the test error of different methods. The results were obtained at the optimal hyper-parameters for different algorithms. From the figure, it is clear that TSGS3VM achieves similar generalization performance as that of BLS3VM, S3VMlight , and BGS3VM methods which confirm that TSGS3VM converge well in practice. Besides, TSGS3VM achieves better generalization performance than FRS3VM, because TSGS3VM has the advantage that it would automatically use more and more random features (for each data x) as the number of iterations increases.
Based on these results, we conclude that TSGS3VM is much more efficient and scalable than these algorithms while retaining the similar generalization performance.
7 Conclusion
In this paper, we provide a novel triply stochastic gradients algorithm for kernel S3VM to make it scalable. We establish new theoretic analysis for TSGS3VM which guarantees that TSGS3VM can efficiently converge to a stationary point for a general non-convex learning problem under weak assumptions. As far as we know, TSGS3VM is the first work that offers non-convex analysis for DSG-like algorithm without a strong initialization assumption. Extensive experimental results on a variety of benchmark datasets demonstrate the superiority of our proposed TSGS3VM.
Acknowledgments
H.H. was partially supported by U.S. NSF IIS 1836945, IIS 1836938, DBI 1836866, IIS 1845666, IIS 1852606, IIS 1838627, IIS 1837956. B.G. was partially supported by the National Natural Science Foundation of China (No: 61573191), and the Natural Science Foundation (No. BK20161534), Six talent peaks project (No. XYDXX-042) in Jiangsu Province.
3 https://www.csie.ntu.edu.tw/ cjlin/libsvmtools/datasets/
4 http://archive.ics.uci.edu/ml/datasets.html
@inproceedings{ijcai2019p328,
  title     = {Scalable Semi-Supervised SVM via Triply Stochastic Gradients},
  author    = {Geng, Xiang and Gu, Bin and Li, Xiang and Shi, Wanli and Zheng, Guansheng and Huang, Heng},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2364--2370},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/328},
  url       = {https://doi.org/10.24963/ijcai.2019/328},
}
TY - CPAPER TI - Scalable Semi-Supervised SVM via Triply Stochastic Gradients AU - Geng, Xiang AU - Gu, Bin AU - Li, Xiang AU - Shi, Wanli AU - Zheng, Guansheng AU - Huang, Heng T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2364 EP - 2370 DO - 10.24963/ijcai.2019/328 UR - https://doi.org/10.24963/ijcai.2019/328 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





