
Interactive Teaching Algorithms for Inverse Reinforcement Learning
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2692-2700.
https://doi.org/10.24963/ijcai.2019/374
Keywords
- Humans and AI: Computer-Aided Education
- Machine Learning: Reinforcement Learning
Abstract
We study the problem of inverse reinforcement learning (IRL) with the added twist that the learner is assisted by a helpful teacher. More formally, we tackle the following algorithmic question: How could a teacher provide an informative sequence of demonstrations to an IRL learner to speed up the learning process? We present an interactive teaching framework where a teacher adaptively chooses the next demonstration based on learner's current policy. In particular, we design teaching algorithms for two concrete settings: an omniscient setting where a teacher has full knowledge about the learner's dynamics and a blackbox setting where the teacher has minimal knowledge. Then, we study a sequential variant of the popular MCE-IRL learner and prove convergence guarantees of our teaching algorithm in the omniscient setting. Extensive experiments with a car driving simulator environment show that the learning progress can be speeded up drastically as compared to an uninformative teacher.
- [Abbeel and Ng, 2004] Pieter Abbeel and Andrew Y Ng. Ap- prenticeship learning via inverse reinforcement learning. In ICML, 2004.
- [Amin et al., 2017] Kareem Amin, Nan Jiang, and Satinder P. Singh. Repeated inverse reinforcement learning. In NIPS, pages 1813-1822, 2017.
- [Amir et al., 2016] Ofra Amir, Ece Kamar, Andrey Kolobov, and Barbara J. Grosz. Interactive teaching strategies for agent training. In IJCAI, pages 804-811, 2016.
- [Argall et al., 2009] Brenna D Argall, Sonia Chernova, Manuela Veloso, and Brett Browning. A survey of robot learning from demonstration. Robotics and autonomous systems, 2009.
- [Bain and Sommut, 1999] Michael Bain and Claude Sommut. A framework for hehavioural claning. Machine Intelligence 15, 15:103, 1999.
- [Billard et al., 2008] Aude Billard, Sylvain Calinon, Ruedi- ger Dillmann, and Stefan Schaal. Robot programming by demonstration. In Springer handbook of robotics. 2008.
- [Boularias et al., 2011] Abdeslam Boularias, Jens Kober, and Jan Peters. Relative entropy inverse reinforcement learning. In AISTATS, pages 182-189, 2011.
- [Brown and Niekum, 2019] Daniel S. Brown and Scott Niekum. Machine teaching for inverse reinforcement learn- ing: Algorithms and applications. In AAAI, 2019.
- [Buchsbaum et al., 2011] Daphna Buchsbaum, Alison Gop- nik, Thomas L Griffiths, and Patrick Shafto. Children's imitation of causal action sequences is influenced by statis- tical and pedagogical evidence. Cognition, 2011.
- [Cakmak and Lopes, 2012] Maya Cakmak and Manuel Lopes. Algorithmic and human teaching of sequential decision tasks. In AAAI, 2012.
- [Cakmak and Thomaz, 2014] Maya Cakmak and Andrea L Thomaz. Eliciting good teaching from humans for machine learners. Artificial Intelligence, 217:198-215, 2014.
- [Chen et al., 2018] Yuxin Chen, Adish Singla, Oisin Mac Aodha, Pietro Perona, and Yisong Yue. Understand- ing the role of adaptivity in machine teaching: The case of version space learners. In NeurIPS, 2018.
- [Chernova and Thomaz, 2014] Sonia Chernova and Andrea L Thomaz. Robot learning from human teachers. Synthesis Lectures on Artificial Intelligence and Machine Learning, 2014.
- [Dorsa Sadigh et al., 2017] Anca D Dragan Dorsa Sadigh, Shankar Sastry, and Sanjit A Seshia. Active preference- based learning of reward functions. In RSS, 2017.
- [Finn et al., 2016] Chelsea Finn, Sergey Levine, and Pieter Abbeel. Guided cost learning: Deep inverse optimal control via policy optimization. In ICML, pages 49-58, 2016.
- [Goldman and Kearns, 1995] Sally A Goldman and Michael J Kearns. On the complexity of teaching. Journal of Computer and System Sciences, 50(1):20-31, 1995.
- [Hadfield-Menell et al., 2016] Dylan Hadfield-Menell, Stu- art J Russell, Pieter Abbeel, and Anca Dragan. Cooperative inverse reinforcement learning. In NIPS, 2016.
- [Haug et al., 2018] Luis Haug, Sebastian Tschiatschek, and Adish Singla. Teaching Inverse Reinforcement Learners via Features and Demonstrations. In NeurIPS, 2018.
- [Ho and Ermon, 2016] Jonathan Ho and Stefano Ermon. Gen- erative adversarial imitation learning. In NIPS, 2016.
- [Ho et al., 2016] Mark K Ho, Michael Littman, James Mac- Glashan, Fiery Cushman, and Joseph L Austerweil. Show- ing versus doing: Teaching by demonstration. In NIPS, 2016.
- [Hunziker et al., 2018] Anette Hunziker, Yuxin Chen, Oisin Mac Aodha, Manuel Gomez-Rodriguez, Andreas Krause, Pietro Perona, Yisong Yue, and Adish Singla. Teaching mul- tiple concepts to a forgetful learner. CoRR, abs/1805.08322, 2018.
- [Kamalaruban et al., 2019] Parameswaran Kamalaruban, Rati Devidze, Volkan Cevher, and Adish Singla. Interactive teaching algorithms for inverse reinforcement learning. CoRR, abs/1905.11867, 2019.
- [Levine et al., 2010] Sergey Levine, Zoran Popovic, and Vladlen Koltun. Feature construction for inverse reinforce- ment learning. In NIPS, pages 1342-1350, 2010.
- [Liu et al., 2017] Weiyang Liu, Bo Dai, Ahmad Humayun, Charlene Tay, Chen Yu, Linda B. Smith, James M. Rehg, and Le Song. Iterative machine teaching. In ICML, 2017.
- [Liu et al., 2018] Weiyang Liu, Bo Dai, Xingguo Li, Zhen Liu, James Rehg, and Le Song. Towards black-box iterative machine teaching. In ICML, 2018.
- [Melo et al., 2018] Francisco S Melo, Carla Guerra, and Manuel Lopes. Interactive optimal teaching with unknown learners. In IJCAI, pages 2567-2573, 2018. IJCAI
- [Ng and Russell, 2000] Andrew Y Ng and Stuart J Russell. Algorithms for inverse reinforcement learning. In ICML, 2000.
- [Ng et al., 1999] Andrew Y Ng, Daishi Harada, and Stuart Russell. Policy invariance under reward transformations: Theory and application to reward shaping. In ICML, 1999.
- [Osa et al., 2018] Takayuki Osa, Joni Pajarinen, Gerhard Neumann, J Andrew Bagnell, Pieter Abbeel, Jan Peters, et al. An algorithmic perspective on imitation learning. Foundations and Trends® in Robotics, 7(1-2):1-179, 2018.
- [Patil et al., 2014] Kaustubh R Patil, Xiaojin Zhu, Łukasz Kopeć, and Bradley C Love. Optimal teaching for limited- capacity human learners. In NIPS, pages 2465-2473, 2014.
- [Rafferty et al., 2016] Anna N Rafferty, Emma Brunskill, Thomas L Griffiths, and Patrick Shafto. Faster teaching via pomdp planning. Cognitive science, 2016.
- [Ratliff et al., 2006] Nathan D Ratliff, J Andrew Bagnell, and Martin A Zinkevich. Maximum margin planning. In ICML, pages 729-736, 2006.
- [Rhinehart and Kitani, 2017] Nicholas Rhinehart and Kris M Kitani. First-person activity forecasting with online inverse reinforcement learning. In ICCV, pages 3696-3705, 2017.
- [Russell, 1998] Stuart Russell. Learning agents for uncertain environments. In COLT, pages 101-103, 1998.
- [Schaal, 1997] Stefan Schaal. Learning from demonstration. In NIPS, pages 1040-1046, 1997.
- [Shafto et al., 2014] Patrick Shafto, Noah D Goodman, and Thomas L Griffiths. A rational account of pedagogical reasoning: Teaching by, and learning from, examples. Cog- nitive psychology, 71:55-89, 2014.
- [Singla et al., 2013] Adish Singla, Ilija Bogunovic, G Bartók, A Karbasi, and A Krause. On actively teaching the crowd to classify. In NIPS Workshop on Data Driven Education, 2013.
- [Singla et al., 2014] Adish Singla, Ilija Bogunovic, Gábor Bartók, Amin Karbasi, and Andreas Krause. Near- optimally teaching the crowd to classify. In ICML, 2014.
- [Sorg et al., 2010] Jonathan Sorg, Satinder P. Singh, and Richard L. Lewis. Reward design via online gradient ascent. In NIPS, pages 2190-2198, 2010.
- [Tadepalli, 2008] Prasad Tadepalli. Learning to solve prob- lems from exercises. Computational Intelligence, 2008.
- [Torrey and Taylor, 2013] Lisa Torrey and Matthew Taylor. Teaching on a budget: Agents advising agents in reinforce- ment learning. In AAMAS, pages 1053-1060, 2013.
- [Walsh and Goschin, 2012] Thomas J. Walsh and Sergiu Goschin. Dynamic teaching in sequential decision making environments. In UAI, 2012.
- [Wulfmeier et al., 2015] Markus Wulfmeier, Peter Ondruska, and Ingmar Posner. Maximum entropy deep inverse rein- forcement learning. CoRR, abs/1507.04888, 2015.
- [Yeo et al., 2019] Teresa Yeo, Parameswaran Kamalaruban, Adish Singla, Arpit Merchant, Thibault Asselborn, Louis Faucon, Pierre Dillenbourg, and Volkan Cevher. Iterative classroom teaching. In AAAI, 2019.
- [Zhang et al., 2009] Haoqi Zhang, David C Parkes, and Yil- ing Chen. Policy teaching through reward function learning. In EC, pages 295-304, 2009.
- [Zhou et al., 2018] Zhengyuan Zhou, Michael Bloem, and Nicholas Bambos. Infinite time horizon maximum causal entropy inverse reinforcement learning. IEEE Trans. Au- tomat. Contr., 63(9):2787-2802, 2018.
- [Zhu et al., 2018] Xiaojin Zhu, Adish Singla, Sandra Zilles, and Anna N. Rafferty. An overview of machine teaching. CoRR, abs/1801.05927, 2018.
- [Ziebart et al., 2008] Brian D Ziebart, Andrew L Maas, J An- drew Bagnell, and Anind K Dey. Maximum entropy inverse reinforcement learning. In AAAI, 2008.
- [Ziebart, 2010] Brian D Ziebart. Modeling purposeful adap- tive behavior with the principle of maximum causal entropy. Carnegie Mellon University, 2010.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Imitation Learning, also known as Learning from Demonstrations, enables a learner to acquire new skills by observing a teacher's behavior. It plays an important role in many real-life learning settings, including human-to-human interaction [Buchsbaum et al., 2011; Shafto et al., 2014], and human-to-robot interaction [Schaal, 1997; Billard et al., 2008; Argall et al., 2009; Chernova and Thomaz, 2014].
Inverse reinforcement learning (IRL) is one of the popular approaches to imitation learning: IRL algorithms operate by first inferring an intermediate reward function explaining the demonstrated behavior, and then obtaining a policy corresponding to the inferred reward [Russell, 1998; Abbeel and Ng, 2004]. IRL has been extensively studied in the context of designing efficient learning algorithms for a given set of demonstrations [Abbeel and Ng, 2004; Ratliff et al., 2006; Ziebart et al., 2008; Boularias et al., 2011; Wulfmeier et al., 2015; Finn et al., 2016]. There has also been some recent work on designing active/interactive IRL algorithms that focus on reducing the number of demonstrations that needs to be requested from a teacher [Amin et al., 2017; Dorsa Sadigh et al., 2017]. Despite these advances, the problem of generating an optimal sequence of demonstrations to teach an IRL agent is still not well understood.
∗Authors contributed equally to this work.
Motivated by applications of intelligent tutoring systems to teach sequential decision-making tasks, such as surgical training 1 or car driving 2 , we study the IRL framework from the viewpoint of a "teacher" in order to best assist an IRL "learner". Cakmak and Lopes; Brown and Niekum (2012; 2019) have studied the problem of teaching an IRL learner in a batch setting, i.e., the teacher has to provide a near-optimal set of demonstrations at once. Their teaching algorithms are non-interactive, i.e., they construct their teaching sequences without incorporating any feedback from the learner and hence unable to adapt the teaching to the learner's progress.
In real-life pedagogical settings, it is evident that a teacher can leverage the learner's feedback in adaptively choosing next demonstrations/tasks to accelerate the learning progress. For instance, consider a scenario where a driving instructor wants to teach a student certain driving skills. The instructor can easily identify the mistakes/weaknesses of the student (e.g., unable to do rear parking), and then carefully choose tasks that this student should perform, along with specific demonstrations to rectify any mistakes. In this paper, we study the problem of designing an interactive teaching algorithm for an IRL learner.
1.1 Overview of Our Approach
We consider an interactive teaching framework where at any given time: (i) the teacher observes the learner's current policy, (ii) then, the teacher provides the next teaching task/demonstration, and (iii) the learner performs an update. We design interactive teaching algorithms for two settings:
- an "omniscient" teaching setting where the teacher has full knowledge of the learner's dynamics and can fully observe the learner's current policy.
- a "blackbox" teaching setting where the teacher doesn't know learner's dynamics and has only a noisy estimate of the learner's current policy.
1 Simulators for surgical training: https://www.virtamed.com/en/
2 Simulators for car driving: https://www.driverinteractive.com/
In the omniscient teaching setting, we study a sequential variant of the popular IRL algorithm, namely Maximum Causal Entropy (MCE) IRL algorithm [Ziebart et al., 2008; Rhinehart and Kitani, 2017]). Our main idea in designing our omniscient teaching algorithm, OMNITEACHER, is to first reduce the problem of teaching a target policy to that of teaching a corresponding hyperparameter (see Section 3.2); then, the teacher greedily steers the learner towards this hyperparameter. We then prove convergence guarantees of the OMNITEACHER algorithm and show that it can significantly reduce the number of demonstrations required to achieve a desired performance of the learner (see Theorem 1, Section 4).
While omniscient teacher yields strong theoretical guarantees, it's applicability is limited given that the learner's dynamics are unknown and difficult to infer in practical applications. Based on insights from the omniscient teacher, we develop a simple greedy teaching algorithm, BBOXTEACHER, for a more practical blackbox setting (see Section 5).
We perform extensive experiments in a synthetic learning environment (with both linear and non-linear reward settings) inspired by a car driving simulator [Ng and Russell, 2000; Levine et al., 2010]. We demonstrate that our teaching algorithms can bring significant improvements in speeding up the learning progress compared to an uninformative teaching strategy that picks demonstrations at random. Furthermore, the performance of the BBOXTEACHER algorithm is close to the OMNITEACHER algorithm even though it operates with limited information about the learner.
2 Problem Setup
We now formalize the problem addressed in this paper.
2.1 Environment
The environment is formally represented by an MDPM := (S, A, T, γ, P0, RE ). The sets of possible states and actions are denoted by S and A respectively. T : S × S × A → [0, 1] captures the state transition dynamics, i.e., T (s′ | s, a) denotes the probability of landing in state s′ by taking action a from state s. Here γ is the discounting factor, and P0 : S → [0, 1] is an initial distribution over states S. We denote a policy π : S × A → [0, 1] as a mapping from a state to a probability distribution over actions. The underlying reward function is given by RE : S ×A→R.
2.2 Interaction between Learner and Teacher
In our setting, we have two entities: a teacher and a sequential IRL learner. The teacher has access to the full MDPMand has a target policy πE computed as an optimal policy w.r.t. RE . The learner knows the MDPMbut not the reward function RE , i.e., has only access toM\RE . The teacher's goal is to provide an informative sequence of demonstrations to teach the policy πE to the learner. Here, a teacher's demonstration ξ = {(sτ , aτ )}τ=0,1,... is obtained by first choosing an initial state s0 ∈ S (where P0(s0) > 0) and then choosing a trajectory of state-action pairs obtained by executing the policy πE in the MDP M.
We consider an interactive teaching framework with three key steps formally described in Algorithm 1. At any time t,
Algorithm 1 Interactive Teaching Framework
- 1: for t = 1, 2, . . . , T do
- 2: teacher observes an estimate of learner's policy πL t
- 3: teacher provides a demonstration ξt to the learner
- 4: learner updates the policy to πL t+1 using ξt
the teacher observes an estimate of learner's current policy πL t and accordingly provides an informative demonstration ξt to assist the learner. Then, the learner updates it's policy to πL t+1 based on demonstration ξt and it's internal learning dynamics.
2.3 OccupancyMeasure and Expected Reward
We introduce the following two notions to formally define the teaching objective. For any policy π, the occupancy measure ρ and the total expected reward ν of π in the MDP M are defined as follows respectively:
Here, P{Sτ = s | π,M} denotes the probability of visiting the state s after τ steps by following the policy π. Similarly, for any demonstration ξ = {(sτ , aτ )}τ=0,1,... , we define
Then for a collection of demonstrations Ξ = {ξt}t=1,2,... , we have ρΞ (s, a) := 1 |Ξ| ∑t ρξt (s, a).
2.4 Teaching Objective
Let πL denote the learner's final policy at the end of teaching. The performance of the policy πL (w.r.t. πE ) in M can be evaluated via the following measures (for some fixed ϵ > 0):
- ∣∣∣ν πE - ν πL ∣∣∣ ≤ ϵ, ensuring high reward [Abbeel and Ng, 2004; Ziebart, 2010].
- DTV (ρπE , ρπL ) ≤ ϵ, ensuring that learner's behavior induced by the policy πL matches that of the teacher [Ho and Ermon, 2016]. Here DTV (p, q) is the total variation distance between two probability measures p and q.
IRL learner's goal is to ϵ-approximate the teacher's policy w.r.t. one of these performance measures [Ziebart, 2010; Ho and Ermon, 2016]. In this paper, we study this problem from the viewpoint of a teacher in order to provide a nearoptimal sequence of demonstrations {ξt}t=1,2,... to the learner to achieve the desired goal. The teacher's performance is then measured by the number of demonstrations required to achieve the above objective.
3 Omniscient Teaching Setting
In this section, we consider the omniscient teaching setting where the teacher knows the learner's dynamics including the learner's current parameters at any given time. We begin by introducing a specific learner model that we study for this setting.
Algorithm 2 Sequential MCE-IRL
- 1: Initialization: parameter λ1, policy πL 1 := πL λ1
- 2: for t = 1, 2, . . . , T do
- 3: receives a demonstration ξt with starting state st,0
- 4: update λt+1 ←ΠΩ [λt - ηt(µπL t ,st,0 -µξt )]
- 5: compute πL t+1 ← Soft-Value-Iter(M\RE , RL λt+1 )
- 6: Output: policy πL ← πL T +1
3.1 Learner Model
We consider a learner implementing an IRL algorithm based on Maximum Causal Entropy approach (MCE-IRL) [Ziebart et al., 2008; Ziebart, 2010; Wulfmeier et al., 2015; Rhinehart and Kitani, 2017; Zhou et al., 2018]. First, we discuss the parametric reward function of the learner and then introduce a sequential variant of the MCE-IRL algorithm used in our interactive teaching framework.
Parametric reward function. We consider the learner model with parametric reward function RL λ : S × A → R where λ ∈ Rd is a parameter. The reward function also depends on the learner's feature representation φL : S ×A → Rd′ . For linear reward function RL λ (s, a) := 〈λ, φL (s, a)〉, λ represents the weights. As an example of non-linear rewards, the function RL λ could be high-order polynomial in λ (see Section 6.2). As a more powerful non-linear reward model, λ could be the weights of a neural network with φL (s, a) as input layer and RL λ (s, a) as output [Wulfmeier et al., 2015].
Soft Bellman policies. Given a fixed parameter λ, wemodel the learner's behavior via the following soft Bellman policy 3 :
For any given λ, the corresponding policy πL λ can be efficiently computed via Soft-Value-Iteration procedure (see [Ziebart, 2010, Algorithm. 9.1], [Zhou et al., 2018]).
Gradient update for sequential MCE-IRL. We consider a sequential MCE-IRL learner for our interactive setting where, at time step t, the learner receives next demonstration ξt = {(st,τ , at,τ )}τ=0,1,... with starting state st,0. Given the learner's current parameter λt and policy πL t := πL λt , the learner updates its parameter via an online gradient descent update rule given by λt+1 = λt-ηtgt with ηt as the learning rate. The gradient gt at time t is computed as
3 For the case of linear reward functions, soft Bellman policies are obtained as the solution to the MCE-IRL optimization problem [Ziebart, 2010; Zhou et al., 2018]. Here, we extend this idea to model the learner's policy with the general parametric reward function. However, we note that for our learner model, it is not always possible to formulate a corresponding optimization problem that leads to the policy form mentioned above.
Algorithm 3 OMNITEACHER for sequential MCE-IRL
- 1: for t = 1, 2, . . . , T do
- 2: teacher picks ξt by solving Eq. (6)
- 3: learner receives ξt and updates using Algorithm 2
where ρπL t ,st,0 (s, a) is given by Eq. (1) and computed with st,0 as the only initial state, i.e., P0(st,0) = 1. As shown in the longer version of the paper [Kamalaruban et al., 2019], gt is the gradient of the loss function
capturing the discounted negative log-likelihood of teacher's demonstration ξt.
Sequential MCE-IRL algorithm. For brevity, we define the following quantities:
and we write the gradient compactly as gt = µπL t ,st,0 -µξt . Algorithm 2 presents the proposed sequential MCE-IRL learner. In particular, we use the online projected gradient descent update given by λt+1 ← ΠΩ [λt - ηtgt], where Ω = {λ : ‖λ‖2 ≤ z} for large enough z (cf. Section 4.3).
3.2 Omniscient Teacher
Next, we present our omniscient teaching algorithm, OMNITEACHER, for sequential MCE-IRL learner.
Policy to hyperparameter teaching. The main idea in designing our algorithm, OMNITEACHER, is to first reduce the problem of teaching a target policy πE to that of teaching a corresponding hyperparameter, denoted below as λ∗ . Then, under certain technical conditions, teaching this λ∗ to the learner ensures that the learner's policy ϵ-approximate the target policy πE . We defer the technical details to Section 4.
Omniscient teaching algorithm. Now, we design a teaching strategy to greedily steer the learner's parameter λt towards the target hyperparameter λ∗ . The main idea is to pick a demonstration which minimizes the distance between the learner's current parameter λt and λ∗ , i.e., minimize ‖λt+1 -λ∗ ‖ = ‖λt - ηtgt -λ∗ ‖. We note that, Liu et al.; Liu et al. (2017; 2018) have used this idea in their iterative machine teaching framework for regression and classification tasks. In particular, we consider the following optimization problem for selecting an informative demonstration at time t:
where s ∈ S is an initial state (where P0(s0) > 0) and ξ is a trajectory obtained by executing the policy πE starting from s. 4 The resulting teaching strategy is given in Algorithm 3.
4 Note that ξ is not constructed synthetically by the teacher, but is obtained by executing policy πE starting from s. However, ξ is not just a random rollout of the policy πE : When there are multiple possible trajectories from s using πE , the teacher can choose the most desirable one as per the joint optimization problem in Eq. (6).
4 Omniscient Teaching Setting: Analysis
In this section, we analyze the teaching complexity of our algorithm OMNITEACHER; the proofs are provided in the longer version of the paper [Kamalaruban et al., 2019].
4.1 Convergence to Hyperparameter λ∗
In this section, we analyze the teaching complexity, i.e., the total number of time steps T required, to steer the learner towards the target hyperparameter. For this analysis, we quantify the "richness" of demonstrations (i.e., (st,0, ξt) as solution to Eq. (6)) in terms of providing desired gradients to the learner.
For the state st,0 picked by the teacher at time step t, let us first define the following objective function given by
Ideally, the teacher would like to provide a demonstration ξt (starting from st,0) for which µξt = µsyn t . In this case, the learner's hyperparameter converges to λ∗ after this time step. However, in our setting, the teacher is restricted to only provide demonstrations obtained by executing the teacher's policy πE in the MDPM. We say that a teacher is ∆max-rich, if for every t, the teacher can provide a demonstration ξt that satisfies the following:
for some δt s.t. ‖δt‖2 ≤ ∆max, and βt ∈ [0, 1 ηt ]. The main intuition behind these two quantities is the following: (i) βt bounds the magnitude of the gradient in the desired direction of (λt -λ∗ ) and (ii) δt accounts for the deviation of the gradient from the desired direction of (λt - λ∗ ).
The following lemma provides a bound on the teaching complexity of OMNITEACHER to steer the learner's parameter to the target λ∗ .
Lemma 1. Given ϵ′ > 0, let the OMNITEACHER be ∆maxrich with ∆max = ϵ′2 β2 4ηmax[4(1-β)z+1] , where β = mint ηtβt, and ηmax = maxt ηt. Then for the OMNITEACHER algorithm with T = O (log 1 ϵ′ ), we have ‖λT - λ∗ ‖ ≤ ϵ′ .
Note that the above lemma only guarantees the convergence to the target hyperparameter λ∗ . To provide guarantees on our teaching objective, we need additional technical conditions which we discuss below.
4.2 Convergence to Policy πL λ∗
We require a smoothness condition on the learner's reward function to ensure that the learner's output policy πL is close to the policy πL λ∗ in terms of the total expected reward ν π (see Eq. (2)). Formally RL λ : S ×A→R is m-smooth if the following holds:
Note that in the linear reward case, the smoothness parameter is m = √d. Given that the reward function RL λ is smooth, the following lemma illustrates the inherent smoothness of the soft Bellman policies given in Eq. (3).
Lemma 2. Consider an MDPM, and a learner model with parametric reward function RL λ which is m-smooth. Then for any λ, λ′ ∈ Rd , the associated soft Bellman policies πL λ and πL λ′ satisfy the following:
The above lemma suggests that convergence to the target hyperparameter λ∗ also guarantees convergence to the policy πL λ∗ associated with the target hyperparameter in terms of total expected reward.
4.3 Convergence to Policy πE
Finally, we need to ensure that the learner's model (RL λ , φL) is powerful enough to capture the teacher's reward RE and policy πE . Intuitively, this would imply that there exists a target hyperparameter λ∗ for which the soft Bellmann policy πL λ∗ has a total expected reward close to that of the teacher's policy πE w.r.t. the reward function RE . Formally, we say that a learner is ℓ-learnable (where ℓ > 0) if there exists a λ ∈ Ω, such that the following holds:
In particular, for achieving the desired teaching objective (see Theorem 1), we require that the learner is ϵ2 -learnable. This in turn implies that there exists a λ∗ ∈ Ω such that ∣∣∣ν πL λ∗ - ν πE ∣∣∣ ≤ ϵ2 . 5 Then, combining Lemma 1 and Lemma 2, we obtain our main result:
Theorem 1. Given ϵ > 0. Define REmax := maxs,a ∣∣RE (s, a)∣∣. Let RL λ be m-smooth. Set ϵ′ = (1-γ)5 ϵ2 32m(REmax )2 . In addition, we have the following:
- Teacher is ∆max-rich with ∆max = ϵ′2 β2 4ηmax[4(1-β)z+1] , where β = mint ηtβt, and ηmax = maxt ηt.
- Learner is ϵ2 -learnerable.
- Teacher has access to λ∗ such that ∣∣∣ν πL λ∗ - ν πE ∣∣∣ ≤ ϵ2 .
Then, for the OMNITEACHER algorithm with T = O (log 1ϵ ),
The above result states that the number of demonstrations required to achieve the desired objective is only O (log 1ϵ ). In practice, this can lead to a drastic speed up in teaching compared to an "agnostic" teacher (referred to as AGNOSTIC) that provides demonstrations at random, i.e., by randomly choosing the initial state s0 ∼ P0 and then picking a random rollout of the policy πE in the MDPM. In fact, for teaching regression and classification tasks, Liu et al. (2017) showed that an omniscient teacher achieves an exponential improvement in teaching complexity as compared to AGNOSTIC teacher who picks the examples at random.
5 For the case of linear rewards, such a λ∗ is guaranteed to exist and it can be computed efficiently; further details are provided in the longer version of the paper [Kamalaruban et al., 2019].
5 Blackbox Teaching Setting
In this section, we study a more practical setting where the teacher (i) cannot directly observe the learner's policy πL t at any time t and (ii) does not know the learner's dynamics. The resulting teaching strategy, namely BBOXTEACHER, is given in Algorithm 4; details are provided below.
Limited observability. We first address the challenge of limited observability. The main idea is that in real-world applications, the teacher could approximately infer the learner's policy πL t by probing the learner, for instance, by asking the learner to perform certain tasks or "tests". Here, the notion of a test is to pick an initial state s ∈ S (where P0(s) > 0) and then asking the learner to execute the current policy πL t from s. Formally, we characterize this probing via two parameters (B, k): After an interval of B time steps of teaching, the teacher asks learner to perform k "tests" for every initial state. Then, based on observed demonstrations of the learner's policy, the teacher can approximately estimate the occupancy
Unknown learner's dynamics. To additionally deal with the second challenge of unknown learner's dynamics, we propose a simple greedy strategy of picking an informative demonstration. In particular, we pick the demonstration at time t by solving the following optimization problem (see the corresponding equation Eq. (6) for the omniscient teacher):
where s ∈ S is an initial state (where P0(s0) > 0) and ξ is a trajectory obtained by executing the policy πE starting from s. Note that we have used the estimate ̂ ρπL t ,s instead of ρπL t ,s . This strategy is inspired from insights of the omniscient teaching setting and can be seen as picking a demonstration (s, ξ) with maximal discrepancy between the learner's current policy and the teacher's policy in terms of expected reward.
6 Experimental Evaluation
In this section, we demonstrate the performance of our algorithms in a synthetic learning environment (with both linear and non-linear reward settings) inspired by a car driving simulator [Ng and Russell, 2000; Levine et al., 2010].
Environment Setup
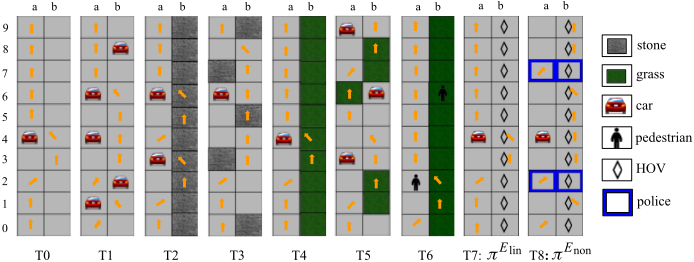
Fig. 1 illustrates a car driving simulator environment consisting of 9 different lane types (henceforth referred to as tasks), denoted as T0, T1, . . ., T8. Each of these tasks is associated with different driving skills. For instance, task T0 corresponds to a basic setup representing a traffic-free highway-it has a very small probability of the presence of another car. However, task T1 represents a crowded highway with 0.25 probability of encountering a car. Task T2 has stones on the right lane, whereas task T3 has a mix of both cars and stones. Similarly, tasks T4 has grass on the right lane, and T5 has a mix of both grass and cars. Tasks T6, T7, and T8 introduce more complex features such as pedestrians, HOV, and police.
Algorithm 4 BBOXTEACHER for a sequential IRL learner
- 1: Initialization: probing parameters (B frequency, k tests)
- 2: for t = 1, 2, . . . , T do
- 3: if t % B = 1: teacher estimates πL t using k tests
- 4: teacher picks ξt by solving Eq. (8)
- 5: learner receives ξt and updates using it's algorithm
The agent's goal is to navigate starting from an initial state at the bottom left to the top of the lane. The agent can take three different actions given by A = {left, straight, right}. Action left steers the agent to the left of the current lane. If agent is already in the leftmost lane when taking action left, then the lane is randomly chosen with probability 0.5. We define similar dynamics for taking action right; action straight means no change in the lane. Irrespective of the action taken, the agent always moves forward. W.l.o.g., we consider that only the agent moves in the environment.
6.1 Linear Reward Setting
First, we study a linear reward setting, and use the notation of lin in subscript to denote the MDPMlin, the teacher's reward RElin , and the teacher's policy πElin .
MDP and Teacher's Policy
We consider lanes corresponding to the first 8 tasks in the environment, namely T0, T1, . . ., T7. We have n number of lanes of a given task, each generated randomly according to the tasks' characteristics described above. Hence, the total number of states |S| in our MDP Mlin is n × 8 × 20 where each cell represents a state, and each lane is associated with 20 states (see Fig. 1). There is one initial state for each lane corresponding to the bottom left cell of that lane.
Next, we define the reward function RElin (i.e., the teacher's reward function). We consider a state-dependent reward that depends on the underlying features of a state s given by the vector φ (s) as follows:
- features indicating the type of the current grid cell as stone, grass, car, ped, HOV, and police.
- features providing some look-ahead information such as whether there is a car or pedestrian in the immediate front cell (denoted as car-in-f and ped-in-f).
Given this, we define the teacher's reward function of linear form as RElin (s) = 〈w, φ (s)〉, where the w values are given in Fig. 2. Teacher's policy πElin is then computed as the optimal policy w.r.t. this reward function and is illustrated via arrows in Fig. 1 (T0 to T7) representing the path taken by the teacher when driving in this environment.
Learner Model
We consider the learner model with linear reward function that depends only on state, i.e., RL λ (s) = 〈λ, φL (s)〉, where φL (s) = φ (s) as given in Fig. 2. The learner is implementing the sequential MCE-IRL in Algorithm 2, where the learner's prior knowledge is captured by the initial policy πL 1 (corresponding to hyperparameter λ1).
In the experiments, we consider the following prior knowledge of the learner: πL 1 is initially trained based on demonstrations of πElin sampled only from the lanes associated with the tasks T0, T1, T2, and T3. Intuitively, the learner initially possesses skills to avoid collisions with cars and to avoid hitting stones while driving. We expect to teach three major skills to the learner, i.e., avoiding grass while driving (task T4, T5, and T6), maintaining distance to pedestrians (task T6), and not to drive on HOV (task T7).
| φ(s) | w |
| stone | -1 |
| grass | -0.5 |
| car | -5 |
| ped | -10 |
| HOV | -1 |
| police | 0 |
| car-in-f | -2 |
| ped-in-f | -5 |
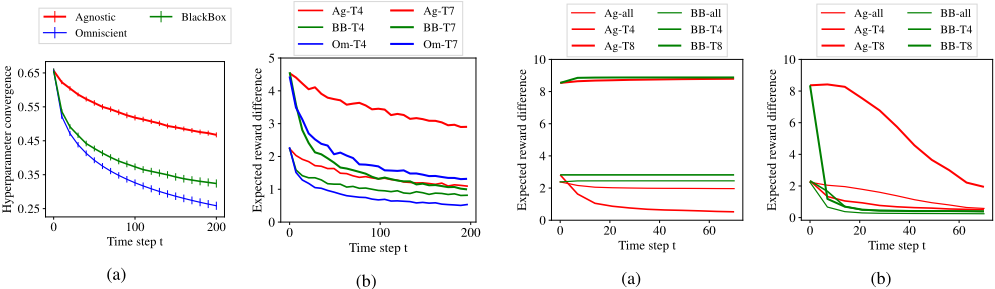
Figure 4: Non-linear setting of Section 6.2. (a) Results for a learner model with linear function RL λ unable to represent the teacher's reward. (b) Results for a learner model with non-linear function RL λ .
Experimental Results
We evaluate the performance of different teaching algorithms, and report the results by averaging over 10 runs. We use n = 5 lanes of each task (i.e., 40 lanes in total). OMNITEACHER in Algorithm 3 computes the target hyperparameter λ∗ as per Footnote 5. For BBOXTEACHER in Algorithm 4, we use B = 5 and k = 5.
Fig. 3a shows the convergence of ‖λt - λ∗ ‖2 , where λ∗ is computed by OMNITEACHER. As expected, OMNITEACHER outperforms other teaching algorithms (BBOXTEACHER and AGNOSTIC teacher) that do not have knowledge of the learner's dynamics and are not directly focusing on teaching this hyperparameter λ∗ . Interestingly, the convergence of BBOXTEACHER is still significantly faster than AGNOSTIC teacher. In Fig. 3b, we consider the teaching objective of total expected reward difference |ν πElin -ν πL t |. We separately plot this objective with starting states limited to task T4 and task T7. The results suggest that convergence to target λ∗ leads to reduction in expected reward difference (one of the teaching objective). The performance of BBOXTEACHER (BB-T7) is even better than OMNITEACHER (Om-T7) for task T7. This is because BBOXTEACHER (Eq. (8)) picks tasks on which the learner's total expected reward difference is highest.
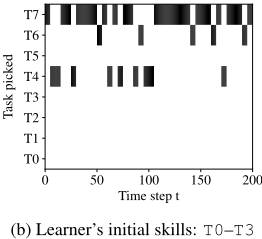
In Fig. 5, we compare the teaching curriculum of BBOXTEACHER for three different settings, where the learner's initial policy πL 1 is trained based on demonstrations of πElin sampled only from the lanes associated with the tasks (a) T0, (b) T0-T3, and (c) T0-T5. The curriculum here refers to the task associated with the state st,0 picked by the teacher at time t to provide the demonstration. In these plots, we can see specific structures and temporal patterns emerging in the curriculum. In particular, we can see that the teaching curriculum focuses on tasks that help the learner acquire new skills. For instance, in Fig. 5b, the teacher primarily picks tasks that provide new skills corresponding to the features grass, HOV, and ped. Recall that, for BBOXTEACHER (Algorithm 4), we use B = 5 and k = 5 for our experiments. As a result, the curriculum plots show blocks of length B = 5 as the algorithm ends up picking the same task until new tests are performed to get a fresh estimate of the learner's policy.
Task picked T7
T6
T5
T4
T3
T2
T1
T0
0
50
100
Time step t
150
200
- (a) Learner's initial skills: T0
0
50
100
Time step t
150
200
(c) Learner's inital skills: T0-T5
Figure 5: Teaching curriculum (i.e., the task associated with the picked state st,0 by BBOXTEACHER in Algorithm 4) for three different settings depending on the learner's initial skills trained on (a) T0, (b) T0-T3, and (c) T0-T5.
6.2 Non-linear Reward Setting
Here, we study a non-linear reward setting, and use the notation of non in subscript for Mnon, REnon , and πEnon .
MDP and Teacher's Policy
We consider the MDPMnon which consists of lanes corresponding to 5 tasks: T0, T1, T2, T4, and T8 with the total number of states being n × 5 × 20 as described above.
Here, we define the teacher's reward function REnon . The key difference between REnon and RElin is that the teacher in this setting prefers to drive on HOV (gets a +1 reward instead of -1 reward). However, if police is present while driving on HOV, there is a penalty of -5. Teacher's optimal policy πEnon for T8 is given in Fig. 1. For other tasks (apart from T7 and T8), the teacher's optimal policy πEnon is the same as πElin .
Learner Model
We consider two different learner models: (i) with linear reward function RL λ (s) = 〈λ, φL (s)〉, and (ii) with non-linear reward function RL λ (s) = 〈λ1:d′ , φL (s)〉 + 〈λd′+1:2d′ , φL (s)〉2 . Here, φL (s) = φ (s) as in Section 6.1 and d′ = 8 is the dimension of φ (s). As a prior knowledge to get πL 1 at time t = 1, we train the learner initially based on demonstrations of πEnon sampled only from the lanes associated with the tasks T0, T1, and T2.
Experimental Results
We use similar experimental settings as in Section 6.1 (i.e., n = 5, averaging 10 runs, etc.). We separately report results for teaching a learner with linear RL λ (see Fig. 4a) and nonlinear RL λ (see Fig. 4b).
Fig. 4a shows that both BBOXTEACHER and AGNOSTIC teacher are unable to make progress in teaching task T8 to the learner. Interestingly, the overall performance measuring the total expected reward difference on the whole MDP for BBOXTEACHER (BB-all) is worse compared to AGNOSTIC (Ag-all): This is an artifact of BBOXTEACHER's strategy in Eq. (8) being stuck in always picking task T8 (even though the learner is not making any progress). Fig. 4b illustrates that the above mentioned limitations are gone when teaching a learner using a non-linear reward function. Here, the rate of reduction in total expected reward difference is significantly faster for BBOXTEACHER as compared to AGNOSTIC, as was also observed in Fig. 3b.
These results demonstrate that the learning progress can be sped up significantly by an adaptive teacher even with limited knowledge about the learner, as compared to an uninformative teacher. These results also signify the importance that the learner's representation of feature space and reward function should be powerful enough to learn the desired behavior.
7 RelatedWork
Imitation learning. The two popular approaches for imitation learning include (i) behavioral cloning, which directly replicates the desired behavior [Bain and Sommut, 1999], and (ii) inverse reinforcement learning (IRL) which infers the reward function explaining the desired behavior [Russell, 1998]. We refer the reader to a recent survey by Osa et al. (2018) on imitation learning. Our approach is inspired by real-life pedagogical settings where carefully choosing the teaching demonstrations and tasks can accelerate the learning progress [Ho et al., 2016]. Hadfield-Menell et al. (2016) have studied the value alignment problem in a game-theoretic setup, and provided an approximate scheme to generate instructive demonstrations for an IRL agent. In our work, we devise a systematic procedure (with convergence guarantees for the omniscient setting) to choose an optimal sequence of demonstrations, by taking into account the learner's dynamics.
Steering and teaching in reinforcement learning. A somewhat different but related problem setting is that of reward shaping and environment design where the goal is to design the reward function to steer the behavior of a learning agent [Ng et al., 1999; Zhang et al., 2009; Sorg et al., 2010]. Another related problem setting is considered in the advicebased interaction framework (e.g., [Torrey and Taylor, 2013; Amir et al., 2016]), where the goal is to communicate advice to a suboptimal agent on how to act in the world.
Algorithmic teaching. Another line of research relevant to our work is that of algorithmic teaching. Here, one studies the interaction between a teacher and a learner where the teacher's objective is to find an optimal training sequence to steer the learner towards a desired goal [Goldman and Kearns, 1995; Liu et al., 2017; Zhu et al., 2018]. Algorithmic teaching provides a rigorous formalism for a number of real-world applications such as personalized education and intelligent tutoring systems [Patil et al., 2014; Rafferty et al., 2016;
Task picked T7
T6
T5
T4
T3
T2
T1
T0
Hunziker et al., 2018], social robotics [Cakmak and Thomaz, 2014], and human-in-the-loop systems [Singla et al., 2014; Singla et al., 2013]. Most of the work in machine teaching is in a batch setting where the teacher provides a batch of teaching examples at once without any adaptation. The question of how a teacher should adaptively select teaching examples for a learner has been addressed recently but only in the supervised learning setting [Melo et al., 2018; Liu et al., 2018; Chen et al., 2018; Yeo et al., 2019].
Teaching sequential tasks. Walsh and Goschin; Cakmak and Lopes (2012; 2012) have studied algorithmic teaching for sequential decision-making tasks. Cakmak and Lopes (2012) studied the problem of teaching an IRL agent in the batch setting. They considered the IRL algorithm by Ng and Russell (2000), which could only result in inferring an equivalent class of reward weight parameters for which the observed behavior is optimal. Brown and Niekum (2019) have extended the work of Cakmak and Lopes (2012) by showing that the teaching problem can be formulated as a set cover problem. However, their teaching strategy does not take into account how the learner progresses (i.e., it is noninteractive). In contrast, we study interactive teaching setting to teach a sequential MCE-IRL algorithm [Ziebart et al., 2008; Rhinehart and Kitani, 2017]. This interactive setting, in turn, allows the teacher to design a personalized and adaptive curriculum important for efficient learning [Tadepalli, 2008]. Haug et al. (2018) have studied the problem of teaching an IRL agent adaptively; however, they consider a very different setting where the teacher and the learner have a mismatch in their worldviews.
8 Conclusions
We studied the problem of designing interactive teaching algorithms to provide an informative sequence of demonstrations to a sequential IRL learner. In an omniscient teaching setting, we presented OMNITEACHER which achieves the teaching objective with O (log 1ϵ ) demonstrations. Then, utilizing the insights from OMNITEACHER, we proposed BBOXTEACHER for a more practical blackbox setting. We showed the effectiveness of our algorithms via extensive experiments in a learning environment inspired by a car driving simulator.
As future work, we will investigate extensions of our ideas to more complex environments; we hope that, ultimately, such extensions will provide a basis for designing teaching strategies for intelligent tutoring systems (see Footnote 1 and Footnote 2). It would also be interesting to benchmark active imitation methods for MCE-IRL learner using our omniscient teacher (see, e.g., [Brown and Niekum, 2019]). Our results are also important in getting a better understanding of the robustness of MCE-IRL learner against adversarial training-set poisoning attacks. Our fast convergence results in Theorem 1 suggests that the MCE-IRL learner is actually brittle to adversarial attacks, and designing a robust MCE-IRL is an important direction of future work.
Acknowledgments
This work was supported in part by the Swiss National Science Foundation (SNSF) under grant number 407540_167319.
@inproceedings{ijcai2019p374,
  title     = {Interactive Teaching Algorithms for Inverse Reinforcement Learning},
  author    = {Kamalaruban, Parameswaran and Devidze, Rati and Cevher, Volkan and Singla, Adish},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2692--2700},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/374},
  url       = {https://doi.org/10.24963/ijcai.2019/374},
}
TY - CPAPER TI - Interactive Teaching Algorithms for Inverse Reinforcement Learning AU - Kamalaruban, Parameswaran AU - Devidze, Rati AU - Cevher, Volkan AU - Singla, Adish T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2692 EP - 2700 DO - 10.24963/ijcai.2019/374 UR - https://doi.org/10.24963/ijcai.2019/374 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





