
Planning with Expectation Models
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 3649-3655.
https://doi.org/10.24963/ijcai.2019/506
Keywords
- Machine Learning: Reinforcement Learning
- Planning and Scheduling: Planning Algorithms
Abstract
Distribution and sample models are two popular model choices in model-based reinforcement learning (MBRL). However, learning these models can be intractable, particularly when the state and action spaces are large. Expectation models, on the other hand, are relatively easier to learn due to their compactness and have also been widely used for deterministic environments. For stochastic environments, it is not obvious how expectation models can be used for planning as they only partially characterize a distribution. In this paper, we propose a sound way of using approximate expectation models for MBRL. In particular, we 1) show that planning with an expectation model is equivalent to planning with a distribution model if the state value function is linear in state features, 2) analyze two common parametrization choices for approximating the expectation: linear and non-linear expectation models, 3) propose a sound model-based policy evaluation algorithm and present its convergence results, and 4) empirically demonstrate the effectiveness of the proposed planning algorithm.
- [Baird, 1995] Leemon Baird. Residual algorithms: Rein- forcement learning with function approximation. In Ma- chine Learning Proceedings 1995, pages 30-37. Elsevier, 1995.
- [Chua et al., 2018] Kurtland Chua, Roberto Calandra, Rowan McAllister, and Sergey Levine. Deep reinforce- ment learning in a handful of trials using probabilistic dynamics models. In Advances in Neural Information Processing Systems, pages 4759-4770, 2018.
- [Chung et al., 2018] Wesley Chung, Somjit Nath, Ajin Joseph, and Martha White. Two-timescale networks for nonlinear value function approximation. 2018.
- [Coulom, 2006] Rémi Coulom. Efficient selectivity and backup operators in monte-carlo tree search. In Interna- tional conference on computers and games, pages 72-83. Springer, 2006.
- [Deisenroth and Rasmussen, 2011] Marc Deisenroth and Carl E Rasmussen. Pilco: A model-based and data- efficient approach to policy search. In Proceedings of the 28th International Conference on machine learning (ICML-11), pages 465-472, 2011.
- [Ghiassian et al., 2018] Sina Ghiassian, Andrew Patterson, Martha White, Richard S. Sutton, and Adam White. On- line off-policy prediction. CoRR, abs/1811.02597, 2018.
- [Glorot and Bengio, 2010] Xavier Glorot and Yoshua Ben- gio. Understanding the difficulty of training deep feedfor- ward neural networks. In Proceedings of the thirteenth in- ternational conference on artificial intelligence and statis- tics, pages 249-256, 2010.
- [Jaderberg et al., 2016] Max Jaderberg, Volodymyr Mnih, Wojciech Marian Czarnecki, Tom Schaul, Joel Z Leibo, David Silver, and Koray Kavukcuoglu. Reinforcement learning with unsupervised auxiliary tasks. arXiv preprint arXiv:1611.05397, 2016.
- [Konidaris et al., 2011] George Konidaris, Sarah Osentoski, and Philip Thomas. Value function approximation in rein- forcement learning using the fourier basis. In Twenty-fifth AAAI conference on artificial intelligence, 2011.
- [Le et al., 2017] Lei Le, Raksha Kumaraswamy, and Martha White. Learning sparse representations in reinforce- ment learning with sparse coding. arXiv preprint arXiv:1707.08316, 2017. IJCAI
- [Leibfried et al., 2016] Felix Leibfried, Nate Kushman, and Katja Hofmann. A deep learning approach for joint video frame and reward prediction in atari games. arXiv preprint arXiv:1611.07078, 2016.
- [Modayil et al., 2014] Joseph Modayil, Adam White, and Richard S Sutton. Multi-timescale nexting in a reinforce- ment learning robot. Adaptive Behavior, 22(2):146-160, 2014.
- [Moore and Atkeson, 1993] Andrew W Moore and Christo- pher G Atkeson. Prioritized sweeping: Reinforcement learning with less data and less time. Machine learning, 13(1):103-130, 1993.
- [Oh et al., 2015] Junhyuk Oh, Xiaoxiao Guo, Honglak Lee, Richard L Lewis, and Satinder Singh. Action-conditional video prediction using deep networks in atari games. In Advances in Neural Information Processing Systems, pages 2863-2871, 2015.
- [Pan et al., 2018] Yangchen Pan, Muhammad Zaheer, Adam White, Andrew Patterson, and Martha White. Organiz- ing experience: a deeper look at replay mechanisms for sample-based planning in continuous state domains. arXiv preprint arXiv:1806.04624, 2018. IJCAI
- [Parr et al., 2008] Ronald Parr, Lihong Li, Gavin Taylor, Christopher Painter-Wakefield, and Michael L Littman. An analysis of linear models, linear value-function ap- proximation, and feature selection for reinforcement learn- ing. In Proceedings of the 25th international conference on Machine learning, pages 752-759. ACM, 2008.
- [Sutton and Barto, 2018] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction. 2018.
- [Sutton et al., 1999] Richard S Sutton, Doina Precup, and Satinder Singh. Between mdps and semi-mdps: A frame- work for temporal abstraction in reinforcement learning. Artificial intelligence, 112(1-2):181-211, 1999.
- [Sutton et al., 2009] Richard S Sutton, Hamid Reza Maei, Doina Precup, Shalabh Bhatnagar, David Silver, Csaba Szepesvári, and Eric Wiewiora. Fast gradient-descent methods for temporal-difference learning with linear func- tion approximation. In Proceedings of the 26th Annual In- ternational Conference on Machine Learning, pages 993- 1000. ACM, 2009.
- [Sutton et al., 2011] Richard S Sutton, Joseph Modayil, Michael Delp, Thomas Degris, Patrick M Pilarski, Adam White, and Doina Precup. Horde: A scalable real-time ar- chitecture for learning knowledge from unsupervised sen- sorimotor interaction. In The 10th International Con- ference on Autonomous Agents and Multiagent Systems- Volume 2, pages 761-768. International Foundation for Autonomous Agents and Multiagent Systems, 2011.
- [Sutton et al., 2012] Richard S Sutton, Csaba Szepesvári, Alborz Geramifard, and Michael P Bowling. Dyna-style planning with linear function approximation and priori- tized sweeping. arXiv preprint arXiv:1206.3285, 2012.
- [Sutton, 1991] R.S. Sutton. Integrated modeling and control based on reinforcement learning and dynamic program- ming. In Advances in Neural Information Processing Sys- tems, 1991.
- [Sutton, 1996] Richard S Sutton. Generalization in rein- forcement learning: Successful examples using sparse coarse coding. In Advances in neural information process- ing systems, pages 1038-1044, 1996.
- [White and others, 2015] Adam White et al. Developing a predictive approach to knowledge. 2015.
- [Yu, 2010] Huizhen Yu. Convergence of least squares tem- poral difference methods under general conditions. In ICML, pages 1207-1214, 2010.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Learning models of the world and effectively planning with them remains a long-standing challenge in artificial intelligence. Model-based reinforcement learning formalizes this problem in the context of reinforcement learning where the model approximates the environment's dynamics. The output of the model is one of the key choices in the design of a planning agent, as it determines the way the model is used for planning. Should the model produce 1) a distribution over the next-state feature vectors and rewards, 2) a sample of the next-state feature vector and reward , or 3) the expected next-state feature vector and reward? For stochastic environments, distribution and sample models can be used effectively, particularly if the distribution can be assumed to be of a special form [Deisenroth and Rasmussen, 2011; Chua et al., 2018]. For arbitrarily stochastic environments, learning a sample or distribution model could be intractable or even impossible. For deterministic environments, expectation models appear to be the default choice as they are easier to learn and have been used [Oh et al., 2015; Leibfried et al., 2016]. However, for general stochastic environments, it is not obvious how expectation models can be used for planning as they only partially characterize a distribution. In this paper, we develop an approach to use expectation models for arbitrarily stochastic environments by restricting the value function to be linear in the state-feature vector.
∗ denotes joint first authorship
1 Supplementary materials: https://arxiv.org/abs/1904.01191
Once the choice of expectation models with linear value function has been made, the next question is to develop an algorithm which uses the model for planning. In previous work, planning methods have been proposed which use expectation models for policy evaluation [Sutton et al., 2012]. However, as we demonstrate empirically, the proposed methods require strong conditions on the model which might not hold in practice, causing the value function to diverge to infinity. Thus, a key challenge is to devise a sound planning algorithm which uses expectation models for policy evaluation and has convergence guarantees. In this work, we propose a new objective function called Model Based-Mean Square Projected Bellman Error (MB-MSPBE) for policy evaluation and show how it relates to Mean Square Projected Bellman Error (MSPBE) [Sutton et al., 2009]. We derive a planning algorithm which minimizes the proposed objective and show its convergence under conditions which are milder than the ones assumed in the previous work [Sutton et al., 2012].
It is important to note that in this work, we focus on the value prediction task for model-based reinforcement learning. Predicting the value of a policy is an integral component of Generalized Policy Iteration (GPI) on which much of modern reinforcement learning control algorithms are built [Sutton and Barto, 2018]. Policy evaluation is also key for building predictive world knowledge where the questions about the world are formulated using value functions [Sutton et al., 2011; Modayil et al., 2014; White and others, 2015]. More recently, policy evaluation has also been shown to be useful for representation learning where value functions are used as auxiliary tasks [Jaderberg et al., 2016]. While model-based reinforcement learning for policy evaluation is interesting in its own right, the ideas developed in this paper can also be extended to the control setting.
2 Problem Setting
We formalize an agent's interaction with its environment by a finite Markov Decision Process (MDP) defined by the tuple (S,A,R, p, γ), where S is a set of states, A is a set of actions, R is a set of rewards, γ ∈ [0, 1) is a discount factor, and p : S ×A× S ×R ↦→ [0, 1] is the dynamics of the environment such that p(s′ , r|s, a) .= Pr(St+1 = s′ ,Rt+1 = r|St = s,At = a) for all s, s′ ∈ S, a ∈ A, and r ∈ R. A stationary policy π determines the behavior of the agent. The value function vπ : S ↦→ R describes the expected discounted sum of rewards obtained by following policy π from each state.
In function approximation setting, value, policy and model are all functions of state, but only through a m-dimensional real-valued feature vector xt = x(St) where x : S ↦→ Rm is the feature mapping, which can be an arbitarily complex function. Tile-coding [Sutton, 1996] and Fourier basis [Konidaris et al., 2011] are examples of state-feature mapping functions which are expert designed. An alternative is to learn the mapping x using auxiliary tasks [Chung et al., 2018; Jaderberg et al., 2016]. The policy π : Rm × A → [0, 1] is usually a parameterized function mapping from a mdimensional feature vector and an action to the probability of choosing the action when observing the feature vector. The value function is usually approximated using a parametrized function with a n-dimensional weight vector w ∈ Rn , where typically n ≪ |S|. We write ˆ v(φ, w) ≈ vπ(s) for the approximate value of state s, if φ is the feature vector of s. The approximate value function can either be a linear function of the state-feature vector ˆ v(φ, w) = φ⊤w where n = m, or a nonlinear function ˆ v(φ,w) = f(φ,w) where f : Rm ×Rn ↦→R is an arbitrary function. In addition, the state feature vector is also used as both input and output of the model, which we will discuss in the next section.
The Dyna architecture [Sutton, 1991] is an MBRL algorithm which unifies learning, planning, and acting via updates to the value and policy functions. The agent interacts with the world, using observed state, action, next state, and reward tuples to learn a model ˆ p to capture the environment dynamics p, and update value and policy functions. The planning step in Dyna repeatedly produces predicted next states and rewards from the model, given input state-action pairs. These hypothetical experiences can be used to update the value and policy functions, just as if they had been generated by interacting with the environment. The search control process decides what states and actions are used to query the model during planning. The efficiency of planning can be significantly improved with clever search control strategy such as prioritized sweeping [Moore and Atkeson, 1993; Sutton et al., 2012; Pan et al., 2018]. In the function approximation setting, there are three factors that can affect the solution of a planning algorithm: 1) the distribution of data used to train the model, 2) the search control process's distribution for selecting the starting feature vectors and actions for simulating the next feature vectors, and 3) the policy being evaluated.
Consider an agent wanting to evaluate a policy π, i.e., approximate vπ, using a Dyna-style planning algorithm. Assume that the data used to learn the model come from the agent's interaction with the environment using policy b. It is common to have an ergodicity assumption on the markov chain induced by b:
Assumption 2.1 The markov chain induced by policy b is ergodic.
Under this assumption we can define the expectation Eb[·] in terms of the unique stationary distribution of b, for example, Eb[xtx⊤t ] = ∑s∈S η(s)x(s)x(s)⊤ where η denote b's stationary state distribution.
Let Hφ .= {s ∈ S : x(s) = φ} as the set of all states sharing feature vector φ. Consequently, the stationary feature vector distribution corresponding to η would be µ(φ) .= ∑s∈Hφ η(s). Let's suppose the search control process generates a sequence of i.i.d random vectors {φk} where each φk is a m-dimensional random vector following distribution ζ, and chooses actions {Ak} according to policy π i.e. Ak ∼ π(·|φk), which is the policy to be evaluated. The sequence {φk} is usually assumed to be bounded.
Assumption 2.2 {φk} is bounded.
For the uniqueness of the solution, it is also assumed that the features generated by the search-control process are linearly independent:
Assumption 2.3 Eζ[φkφ⊤k ] is non-singular.
3 Models
A model can be learned if the environment dynamics is not known. There are at least three types of models: distribution models, sample models and expectation models. While all of them take a state-feature vector φ and an action a as input, their outputs are different.
A distribution model ˆ p produces the distribution over the next state-feature vectors and rewards: ˆ p(φ′ , r|φ, a) ≈ Pr[xt+1 = φ′ ,Rt+1 = r|xt = φ,At = a]. Distribution models have typically been used with special forms such a Gaussians [Chua et al., 2018] or Gaussian processes [Deisenroth and Rasmussen, 2011]. In general, however, learning a distribution can be impractical as distributions are potentially large objects. For example, if the state is represented by a feature vector of dimension m, then the first moment of its distribution is a m-vector, but the second moment is a m×m matrix, and the third moment is m×m×m, and so on.
Sample models are a more practical alternative, as they only need to generate a sample of the next-state feature vector and reward, given a state-feature vector and action. Sample models can use arbitrary distributions to generate the samples-even though they do not explicitly represent those distributions-but can still produce objects of a limited size (e.g. feature vectors of dimension m). They are particularly well suited for sample-based planning methods such as Monte Carlo Tree Search [Coulom, 2006]. Unlike distribution models, however, sample models are stochastic which creates an additional branching factor in planning, as multiple samples are needed to be drawn to gain a representative sense of what might happen.
Expectation models are an even simpler approach, where the model produces the expectation of the next reward and the next-state feature vector. An expectation model {ˆx, ˆ r} consists of two functions: feature-vector function ˆx such that ˆx(φ, a) ≈ Eb[xt+1|xt = φ,At = a] and reward function ˆ r such that ˆ r(φ, a) ≈ Eb[Rt+1|xt = φ,At = a]. The advantages of expectation models are that the feature vector output is compact (like a sample model) and deterministic (like a distribution model). The potential disadvantage of an expectation model is that it is only a partial characterization of the distribution. For example, if the result of an action (or option) is that two binary state features both occur with probability 0.5, but are never present (=1) together, then an expectation model can capture the first part (each present with probability 0.5), but not the second (never both present). This may not be a substantive limitation, however, as we can always add a third binary state feature, for example, for the AND of the original two features, and then capture the full distribution with the expectation of all three state features.
4 ExpectationModels and Linearity
Expectation models can be less complex than distribution and sample models and, therefore, can be easier to learn. This is especially critical for model-based reinforcement learning where the agent is to learn a model of the world and use it for planning. In this work, we focus on answering the question: how can expectation models be used for planning in Dyna, despite the fact that they are only a partial characterization of the distribution?
There is a surprisingly simple answer to this question: if the value function is linear in the feature vector, then there is no loss of generality when using an expectation model instead of a distribution model for planning. Let ˆ p be an arbitrary distribution model and ˆx, ˆ r be the feature-vector and reward functions of the corresponding expectation model, that is, with ˆx(φ, a) = ∑φ′ ,r φ′ ˆ p(φ′ , r|φ, a) and ˆ r(φ, a) = ∑φ′ ,r rˆ p(φ′ , r|φ, a). Then approximate dynamic programming (policy evaluation) with the distribution model and linear function approximation performs an update of w for each feature vector φ such that ˆ v(φ,w) is moved toward:
The last expression, using just an expectation model, is equal to the first, thus showing that no generality has been lost compared to an arbitrary distribution model, if the value function is linear. Further, the same equations also advocate the other direction: if we are using an expectationmodel, then the approximate value function should be linear. This is because (2) is unlikely to equal (1) for general distributions if ˆ v is not linear in state-feature vector.
It is important to point out that linearity does not particularly restrict the expressiveness of the value function since the mapping x could still be non-linear and, potentially, learned end-to-end using auxiliary tasks [Jaderberg et al., 2016; Chung et al., 2018].
5 Linear &Non-Linear ExpectationModels
We now consider the parameterization of the expectation model: should the model be a linear projection from a state feature vector and an action to the expected next state feature vector and reward or should it be an arbitrary non-linear function? In this section, we discuss the two common choices and their implications in detail.
The general case for an expectation model is that ˆx and ˆ r are arbitrary non-linear functions. A special case is of the linear expectation model, in which both of these functions are linear, i.e., ˆx(φ, a) = Faφ and ˆ r(φ, a) = b⊤a φ where matrices {Fa, ∀a ∈ A} (shortened as {Fa}) and vectors {ba, ∀a ∈ A} (shortened as {ba}) are parameters of the model.
We now define the best linear expectation model and the best non-linear expectation model trained using data generated by policy b. In particular, let {F∗a }, {b∗a } be the parameters of best linear expectation model. Then we have ∀a ∈ A
For the uniqueness of the best linear model, we assume
Assumption 5.1 Eb[I(At = a)xtx⊤t ] is non-singular ∀a ∈
AUnder this assumption we have closed-from expression of F∗a , b∗a
Let ˆx∗ , ˆ r∗ be the feature-vector and reward functions of the best non-linear expectation model. Then we have
Both linear and non-linear models can be learned using samples via stochastic gradient descent.
5.1 Why Linear Models are Not Enough?
In previous work, linear expectation models have been used to simulate a transition and execute TD(0) update [Sutton et al., 2012]. Convergence to the TD-fixed point using TD(0) updates with a non-action linear expectation model is shown in theorem 3.1 and 3.3 of [Sutton et al., 2012]. An additional benefit of this method is that the point of convergence does not rely on the distribution ζ of the search-control process. Critically, a non-action model cannot be used for evaluating an arbitrary policy, as it is tied to a single policy - the one that generates the data for learning the model. To evaluate multiple policies, an action model is required. In this case, the point of convergence of the TD(0) algorithm is dependent on ζ. From corollary 5.1 of [Sutton et al., 2012], the convergent point of TD(0) update with linear action model with parameters {Fa}, {ba} is:
Eζ[φkφ⊤k ]-1Eζ[φkφ⊤k bAk ]. It is obvious that the convergence point changes as the feature vector generating distribution ζ changes. We now ask even if ζ equals µ, is the solution of planning using the model same as the solution of learning using the real data. In the next proposition we show that this is not true in general for the best linear model, however, it is true for the best non-linear model.
Let the fixed point of the expected off-policy TD(0) update using the real data be wenv, the fixed point of the expected TD(0) update using the data generated by the best linear model be wlinear , and the fixed point of the expected TD(0) update using the data generated by the best non-linear model be wnon-linear (assuming three fixed points all exist). These fixed points are all unique and can be written as follow:
where ρt = π(At|xt) b(At|xt) is the importance sampling ratio.
Proposition 5.1 suppose
1. assumptions 2.1, 5.1 hold
- ζ = µ.
then in general wenv = wnon-linear ̸= wlinear
5.2 An Illustrative Example on the Limitation of Linear Models
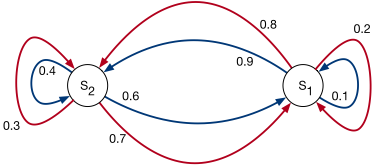
In order to clearly elucidate the limitation of linear models for planning, we use a simple two-state MDP, as outlined in Figure 1. The policy b used to generate the data for learning the model, and the the policy π to be evaluated are also described in Figure 1. We learn a linear model with the data collected by interacting with the environment using policy b and verify that it is the best linear model that could be obtained. We can then obtain wlinear using equation(3). wenv is calculated by off-policy LSTD[Yu, 2010] using the same data that is used to learn the linear model. In agreement to proposition 5.1, the two resulting fixed points are different: wlinear = [0.953]⊤ and wenv = [8.89]⊤.
Previous works [Parr et al., 2008; Sutton et al., 2012] showed that a non-action linear expectation model could just be enough if the value function is linear in state-feature vector. Proposition 5.1 coupled with the above example suggests that this is not true for the more general case of linear expectation models, and expressive non-linear models could potentially be a better choice for planning with expectation models. From now on, we focus on non-linear models as the parametrization of choice.
6 Gradient-based Dyna-style Planning Methods
In the previous section, we established that more expressive non-linear models are needed to recover the solution obtained by real data. An equally crucial choice is that of the planning algorithm: do TD(0) updates converge to the fixed-point? For this to be true for linear models, the numerical radius of F needs to be less than 1 [Sutton et al., 2012]. We conjecture that this condition might not hold in practice causing the planning to diverge and illustrate this point using Baird's Counter Example [Baird, 1995] in the next section.
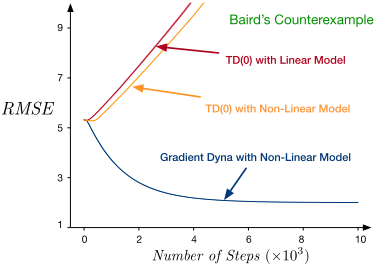
The proof of proposition 5.1 further implies that the expected TD(0) update with the best non-linear model Eζ[∆kφk] is the same as the expected model-free offpolicy TD(0) update Eb[ρtδtxt], where ∆k = ˆ r(φk, Ak) + γw⊤ ˆx(φk, Ak)-w⊤φk and δt = Rt+1+γw⊤xt+1-w⊤xt. However, for off-policy learning, TD(0) is not guaranteed to be stable, which suggests that even with the best non-linear model, the TD(0) algorithm is also prone to divergence. This is also empirically verified in Baird's Counter Example.
Inspired by the Gradient-TD off-policy policy evaluation algorithms [Sutton et al., 2009] which are guaranteed to be stable under function approximation, we propose a family of convergent planning algorithms. The proposed methods are guaranteed to converge for both linear and non-linear expectation models. This is true even if the models are imperfect, which is usually the case in model-based reinforcement learning where the models are learned online.
To achieve this goal, we define a new objective function which our planning algorithm would optimize: Model-Based Mean Square Projected Bellman Error, MB-MSPBE(w) = Eζ[∆kφk]⊤Eζ[φkφ⊤k ]-1Eζ[∆kφk]. This new objective is similar to what GTD learning algorithm optimizes, the Mean Square Projected Bellman Error, MSPBE(w) = Eb[ρtδtxt]⊤Eb[xtx⊤t ]-1Eb[ρtδtxt]. This new objective can be optimized using a variety of gradient-based methods - as we will elaborate later. We call the family of methods using gradient to optimize this objective Gradient-based Dyna-style Planning (Gradient Dyna) methods.
Number of Steps (⇥103 )
Figure 2: Gradient Dyna vs TD(0) in Baird's counterexample: Gradient Dyna remains stable, whereas TD(0) algorithm diverges. The reported curve is the average of 30 runs and the standard deviation is too small to be visible clearly
Similar to MSPBE, MB-MSPBE is also quadratic, and if it is not strictly convex then minimizing it give us infinite solutions for w. Since features are assumed to be independent, this would mean that we have infinite different solutions for the approximate value function. Therefore it's reasonable to assume that the solutions of minimizing MB-MSPBE is unique. This would be true iff the Hessian ∇2MB-MSPBE(w) = A⊤C-1A, where A = Eζ [φk(φk - γˆx(φk,Ak))⊤] and C = Eζ[φkφ⊤k ]-1 , is invertible. This is equivalent to A being non-singular.
Assumption 6.1 A is non-singular.
It can be shown that the unique solution for minimizing this new objective is w∗ .= A-1c, where c = Eζ[ˆ r(φk , Ak)φk ], if the above assumption holds.
Furthermore, we note that there is an equivalence between MB-MSPBE and MSPBE. That is, if a best non-linear model is learned from the data generated from some policy b and ζ in the search control process equals b's stationary feature vector distribution µ, then MB-MSPBE is the MSPBE.
Proposition 6.1 If
- Assumption 2.1 and 2.3 hold.
- ζ = µ
- ˆx = ˆx∗ and ˆ r = ˆ r∗
Then MB-MSPBE(w) = MSPBE(w).
The above proposition does not hold for the best linear model for the same reason elaborated in proposition 5.1.
Let's now consider algorithms that can be used to minimize this objective. Consider the gradient of MB-MSPBE: ∇MB-MSPBE(w) = Eζ[(γˆx(φk,Ak) - φk)φ⊤k ]Eζ[φkφ⊤k ]-1Eζ[∆kφk]. We have a product of three expectations and, therefore, we cannot simply use one sample to obtain an unbiased estimate of the gradient. In order to obtain an unbiased estimate of the gradient, we could either draw three independent samples or learn the product of the the last two factors using a linear least-square method. GTD methods take the second route leading to an algorithm with O(m) complexity in which two sets of parameters are mutually related in their updates. However, if one uses a linear
Algorithm 1 Gradient Dyna Algorithm
Input: w0, V0, policy π, feature vector distribution ζ, expectation model {ˆx, ˆ r}, stepsizes αk, βk for k = 1, 2, · · ·
Output: wk
- 1: for k = 1, 2, · · · do
- 3: Sample Ak ∼ π(·|φk)
- 2: Sample φk ∼ ζ(·)
- 4: wk+1 ←wk -αkVk∆kφk
- 6: end for
- 5: Vk+1 ←Vk+βk((γˆx(φk,Ak)-φk)φ⊤k -Vkφkφ⊤k )
model, the computational complexity for storing and using the model is already O(m2 ). For a non-linear model, depending on the parameterization choices, the complexity can be either smaller or greater than O(m2 ). Thus, a planning algorithms with O(m2 ) complexity can be an acceptable choice. This leads to two choices: we can sample the three expectations and and then multiply them to produce an unbiased estimate of the gradient. Note that this would still lead to an O(m2 ) algorithm as the matrix inversion can be done in O(m2 ) using Sherman-Morrison formula. Alternatively, we can use the linear least-square method to estimate the first two expectations and sample the third one. Compared with GTD methods, there are still two sets of parameters but their updates are not mutually dependent, which potentially leads to faster convergence. Although both of these approaches have O(m2 ) complexity, we adopt the second approach, which is summarized in algorithm 1. We now present the convergence theorem for the proposed algorithm, which is followed by its empirical evaluation. The reader can refer to the supplementary materials for the proof of the theorem.
Theorem 6.1 (Convergence of Gradient Dyna Algorithm)
Consider algorithm 1. If
- Assumptions 2.2, 2.3 and 6.1 hold
Then for any initial weight vector w0, limk→∞wk = w∗ w.p. 1.
7 Experiments
The goal of the experiment section is to validate the theoretical results and investigate how Gradient Dyna algorithm performs in practice. Concretely, we seek to answer the following questions: 1) is the proposed planning algorithm stable for the non-linear model choice, especially when the model is learned online and 2) what solution does the proposed planning algorithm converge to.
7.1 Divergence in TD(0)
Our first experiment is designed to illustrate the divergence issue with TD(0) update. We use Baird's counterexample [Baird, 1995; Sutton and Barto, 2018] - a classic example to highlight the off-policy divergence problem with the modelfree TD(0) algorithm. The policy b used to learn the model is arranged to be the same as the behavior policy in the counterexample, whereas the policy π to be evaluated is arranged Number of Steps (⇥103 )
Number of Steps (⇥103 )
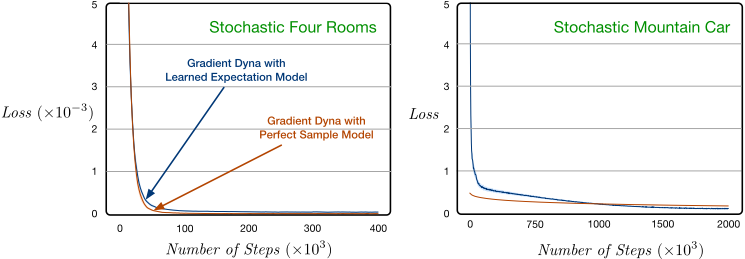
Figure 3: Gradient Dyna with a learned expectation model remains stable and converges to the off-policy LSTD solution. The reported curve is the average of 30 runs and the standard deviation is too small to be visible clearly
to be the same as the counterexample's target policy. For TD(0) with linear model, we initialize the matrix Fa and vector ba for all a to be zero. For TD(0) with non-linear model and Gradient Dyna, we use a neural network with one hidden layer of 200 units as the non-linear model. We initialize the non-linear model using Xavier initialization [Glorot and Bengio, 2010]. The parameter w for the estimated value function is initialized as proposed in the counterexample. The model is learned in an online fashion, that is, we use only the most recent sample to perform a gradient-descent update on the mean-square error. The search-control process is also restricted to generate the last-seen feature vector, which is then used with an a ∼ π to simulate the next feature vector. The resulting simulated transition is used to apply the planning update. The evaluation metric is the Root Mean Square Error (RMSE): √∑s (ˆ v(x(s),w) - vπ(s))2 /|S|. The results are reported for hyperparameters chosen based on RMSE over the latter half of a run. In Figure 2, we see that TD(0) updates with both linear and non-linear expectation model cause the value function to diverge. In contrast, Gradient Dyna remains sound and converges to the RMSE of 2.0.
7.2 Convergence in Practice
In this set of experiments, we want to investigate how Gradient Dyna algorithm performs in practice. We evaluate the proposed method for the non-linear model choice in two simple yet illustrative domains: stochastic variants of Four Rooms [Sutton et al., 1999; Ghiassian et al., 2018] and Mountain Car [Sutton, 1996]. Similar to the previous experiment, the model is learned online. Search control, however, samples uniformly from the recently visited 1000 feature vectors to approximate the i.i.d. assumption in Theorem 6.1.
We modified the Four Rooms domain by changing the states on the four corners to terminal states. The reward is zero everywhere except when the agent transitions into a terminal state, where the reward is one. The episode starts in one of the non-terminal states uniform randomly. The policy b to generate the data for learning the model takes all actions with equal probability, whereas the policy π to be evaluated constitutes the shortest path to the top-left terminal state and is deterministic. We used tile coding [Sutton, 1996] to obtain feature vector(4 2 × 2 tilings). In mountain car, the policy b used to generate the data is the standard energy-pumping policy with 50% randomness [Le et al., 2017], where the policy π to be evaluated is also the standard energy-pumping policy but with no randomness. We again used tile coding to obtain feature vector (8 8 × 8 tilings). We inject stochasticity in the environments by only executing the chosen action 70% of the times, whereas a random action is executed 30% of the time. In both experiments, we do one planning step for each sample collected by the policy b. As noted in proposition 6.1, if we have ζ = µ, the minimizer of MBMSPBE for the best non-linear model is the off-policy LSTD solution A-1 LSTDcLSTD, ALSTD = Eb[ρtxt(xt - γxt+1)⊤], cLSTD = Eb[ρtRt+1xt] [Yu, 2010]. Therefore, for both domains, we run the off-policy LSTD algorithm for 2 million time-steps and use the resulting solution as the evaluation metric: Loss = ‖ALSTDw - cLSTD‖22 .
The results are reported for hyper-parameters chosen according to the LSTD-solution based loss over the latter half of a run. In Figure 3, we see that Gradient Dyna remains stable and converges to off-policy LSTD solution in both domains.
8 Conclusion
In this paper, we proposed a sound way of using the expectation models for planning and showed that it is equivalent to planning with distribution models if the state value function is linear in feature vector. We made a theoretical argument for non-linear expectation models to be the parametrization of choice even if the value-function is linear. Lastly, we proposed Gradient Dyna, a model-based policy evaluation algorithm with convergence guarantees, and empirically demonstrated its effectiveness.
Acknowledgements
We would like to thank Huizhen Yu, Sina Ghiassian, Banafsheh Rafiee and Khurram Javed for useful discussions and feedbacks.
@inproceedings{ijcai2019p506,
  title     = {Planning with Expectation Models},
  author    = {Wan, Yi and Zaheer, Muhammad and White, Adam and White, Martha and Sutton, Richard S.},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {3649--3655},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/506},
  url       = {https://doi.org/10.24963/ijcai.2019/506},
}
TY - CPAPER TI - Planning with Expectation Models AU - Wan, Yi AU - Zaheer, Muhammad AU - White, Adam AU - White, Martha AU - Sutton, Richard S. T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 3649 EP - 3655 DO - 10.24963/ijcai.2019/506 UR - https://doi.org/10.24963/ijcai.2019/506 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





