
Generalized Majorization-Minimization for Non-Convex Optimization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 4257-4263.
https://doi.org/10.24963/ijcai.2019/591
Keywords
- Computer Vision: Big Data and Large Scale Methods
- Machine Learning: Data Mining
Abstract
Majorization-Minimization (MM) algorithms optimize an objective function by iteratively minimizing its majorizing surrogate and offer attractively fast convergence rate for convex problems. However, their convergence behaviors for non-convex problems remain unclear. In this paper, we propose a novel MM surrogate function from strictly upper bounding the objective to bounding the objective in expectation. With this generalized surrogate conception, we develop a new optimization algorithm, termed SPI-MM, that leverages the recent proposed SPIDER for more efficient non-convex optimization. We prove that for finite-sum problems, the SPI-MM algorithm converges to an stationary point within deterministic and lower stochastic gradient complexity. To our best knowledge, this work gives the first non-asymptotic convergence analysis for MM-alike algorithms in general non-convex optimization. Extensive empirical studies on non-convex logistic regression and sparse PCA demonstrate the advantageous efficiency of the proposed algorithm and validate our theoretical results.
- [Agarwal and Bottou, 2014] Alekh Agarwal and Leon Bot- tou. A lower bound for the optimization of finite sums. arXiv preprint arXiv:1410.0723, 2014.
- [Bietti and Mairal, 2017] Alberto Bietti and Julien Mairal. Stochastic optimization with variance reduction for infinite datasets with finite sum structure. In Advances in Neural Information Processing Systems, pages 1623-1633, 2017.
- [Borwein and Lewis, 2010] Jonathan Borwein and Adrian S Lewis. Convex analysis and nonlinear optimization: the- ory and examples. Springer Science & Business Media, 2010.
- [Cappé and Moulines, 2009] Olivier Cappé and Eric Moulines. On-line expectation-maximization algorithm for latent data models. Journal of the Royal Statistical So- ciety: Series B (Statistical Methodology), 71(3):593-613, 2009.
- [Chang and Lin, 2011] Chih-Chung Chang and Chih-Jen Lin. LIBSVM: A library for support vector machines. ACM Transactions on Intelligent Systems and Technology, 2:27:1-27:27, 2011. Software available at http://www. csie.ntu.edu.tw/ ∼ cjlin/libsvm. Link
- [Defazio et al., 2014] Aaron Defazio, Francis Bach, and Si- mon Lacoste-Julien. Saga: A fast incremental gradient method with support for non-strongly convex composite objectives. In Advances in neural information processing systems, pages 1646-1654, 2014.
- [Draper and Smith, 2014] Norman R Draper and Harry Smith. Applied regression analysis, volume 326. John Wiley & Sons, 2014.
- [Fang et al., 2018] Cong Fang, Chris Junchi Li, Zhouchen Lin, and Tong Zhang. Spider: Near-optimal non-convex optimization via stochastic path-integrated differential es- timator. In Advances in Neural Information Processing Systems, pages 687-697, 2018.
- [Feng et al., 2013] Jiashi Feng, Huan Xu, and Shuicheng Yan. Online robust pca via stochastic optimization. In Ad- vances in Neural Information Processing Systems, pages 404-412, 2013.
- [Gasso et al., 2009] Gilles Gasso, Alain Rakotomamonjy, and Stéphane Canu. Recovering sparse signals with a cer- tain family of nonconvex penalties and dc programming. IEEE Transactions on Signal Processing, 57(12):4686- 4698, 2009.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In Advances in neural information pro- cessing systems, pages 315-323, 2013.
- [Kang et al., 2015] Yangyang Kang, Zhihua Zhang, and Wu- Jun Li. On the global convergence of majorization min- imization algorithms for nonconvex optimization prob- lems. arXiv preprint arXiv:1504.07791, 2015.
- [Kingma and Ba, 2014] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Lange et al., 2000] Kenneth Lange, David R Hunter, and Il- soon Yang. Optimization transfer using surrogate objec- tive functions. Journal of computational and graphical statistics, 9(1):1-20, 2000.
- [LeCun et al., 2015] Yann LeCun, Yoshua Bengio, and Ge- offrey Hinton. Deep learning. nature, 521(7553):436, 2015.
- [Mairal, 2013a] Julien Mairal. Optimization with first-order surrogate functions. In International Conference on Ma- chine Learning, pages 783-791, 2013.
- [Mairal, 2013b] Julien Mairal. Stochastic majorization- minimization algorithms for large-scale optimization. In Advances in Neural Information Processing Systems, pages 2283-2291, 2013.
- [Mairal, 2015] Julien Mairal. Incremental majorization- minimization optimization with application to large-scale machine learning. SIAM Journal on Optimization, 25(2):829-855, 2015.
- [Nesterov, 1998] Yurii Nesterov. Introductory lectures on convex programming volume i: Basic course. Lecture notes, 1998.
- [Nguyen et al., 2017] Lam M Nguyen, Jie Liu, Katya Scheinberg, and Martin Takáč. Sarah: A novel method for machine learning problems using stochastic recursive gradient. In Proceedings of the 34th International Confer- ence on Machine Learning-Volume 70, pages 2613-2621. JMLR. org, 2017.
- [Parizi et al., 2015] Sobhan Naderi Parizi, Kun He, Stan Sclaroff, and Pedro Felzenszwalb. Gener- alized majorization-minimization. arXiv preprint arXiv:1506.07613, 2015.
- [Razaviyayn et al., 2016] Meisam Razaviyayn, Maziar San- jabi, and Zhi-Quan Luo. A stochastic successive min- imization method for nonsmooth nonconvex optimiza- tion with applications to transceiver design in wireless communication networks. Mathematical Programming, 157(2):515-545, 2016.
- [Shalev-Shwartz and Zhang, 2013] Shai Shalev-Shwartz and Tong Zhang. Stochastic dual coordinate ascent methods for regularized loss minimization. Journal of Machine Learning Research, 14(Feb):567-599, 2013.
- [Vaida, 2005] Florin Vaida. Parameter convergence for em and mm algorithms. Statistica Sinica, 15(3):831, 2005.
- [Wang et al., 2018] Zhe Wang, Kaiyi Ji, Yi Zhou, Yingbin Liang, and Vahid Tarokh. Spiderboost: A class of faster variance-reduced algorithms for nonconvex optimization. arXiv preprint arXiv:1810.10690, 2018.
- [Xu et al., 2016] Chen Xu, Zhouchen Lin, Zhenyu Zhao, and Hongbin Zha. Relaxed majorization-minimization for non-smooth and non-convex optimization. In Thirtieth AAAI Conference on Artificial Intelligence, 2016.
- [Zou et al., 2006] Hui Zou, Trevor Hastie, and Robert Tib- shirani. Sparse principal component analysis. Journal of computational and graphical statistics, 15(2):265-286, 2006.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In this paper, let us consider the following finite-sum optimization problem:
where each component fi : Rp → R is a continuous, nonconvex but smooth function, associated with one sample. The second term h(θ) could be non-smooth and non-convex. n is the number of samples. Such a formulation encapsulates many statistical learning tasks, e.g. principle component analysis [Feng et al., 2013], regression [Draper and Smith, 2014] and training neural networks [LeCun et al., 2015].
Majorization-Minimization (MM) [Lange et al., 2000] is an optimization framework for designing well-behaved optimization algorithms for non-convex functions. MM algorithms solve problem (1) via two steps. The first step is to construct a proper surrogate g that upper bounds the objective function Φ(θ) tightly, i.e., g(θ) ≥ Φ(θ). The second step is to optimize the surrogate whose optimum is much easier to obtain. Since the surrogate constructed at the current estimator is majorant to the objective function, each minimization step over the surrogate will decrease the objective function monotonically. MM is attractive in practice as one can decompose the original complex problem to a series of much simpler sub-problems that are easier and faster to optimize.
∗ Part of this work was done when Yi Yang was visiting Baidu Research during his Professional Experience Program.
Previous works show that the convergence rate of MM algorithms is nearly optimal when the objective is convex [Mairal, 2013b]. Specifically, they are shown to converge at a rate of O(1/√t) in a finite-sum setting and O(1/t) in a stochastic setting for strongly convex objective functions. However, when the component fi in (1) is non-convex, an exact global optimum is unreachable and the theoretical convergence guarantee is hard to obtain by nature. Though previous studies have provided analysis of the convergence for asymptotic stationary points [Borwein and Lewis, 2010], their results are rather limited, and little work has revealed the specific convergence rate.
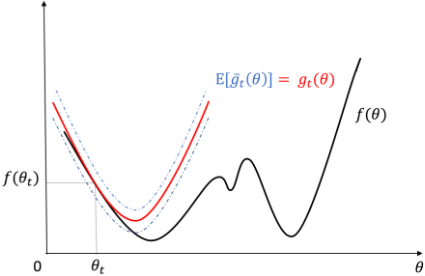
In this work, we aim to conquer this challenge and give concrete convergence rate analysis of MM-alike algorithms for solving non-convex problems. Inspired by the recently proposed SPIDER (Stochastic Path Integrated Differential EstimatoR) [Fang et al., 2018] method, we propose a generalized surrogate which fully exploits the historical gradient information and develop a new MM algorithm, called SPI-MM. The proposed SPI-MM algorithm significantly relaxes the requirement on the surrogate from classic MM algorithms. Instead of tightly bounding the objective for all the samples, it only requires the surrogate to bound the objective in expectation. The SPI-MM is general and can instantiate existing MM methods. Figure 1 illustrates such generalization over the surrogate construction by SPI-MM. The red line is the classic surrogate which strictly upper bounds the objective function at the solution θt. Our proposed surrogate can lie in the space between two dotted lines and the requirement is much milder.
In particular, when we adopt a first-order generalized surrogate, we prove that the proposed SPI-MM algorithm decreases the objective value in expectation. In addition, we prove that the SPI-MM algorithm terminates after O( √n ϵ2 + n) gradient computations when searching for an ϵ-approximation first-order stationary point θ with E‖∇Φ(θ)‖ ⩽ ϵ. These results are obtained by our developed novel proof techniques that we will detail in the method section, on top of the techniques from SPIDER.
The main contributions of our paper are as follows:
- We propose a generalized surrogate for non-convex optimization problems. Instead of requiring the surrogate to exactly upper bound the objective, we only require that the surrogate upper bound the objective in expectation. With such generalization, we put forward a new MM algorithm, named SPI-MM.
- We give the first non-asymptotic convergence rate and IFO complexity result for MM-alike algorithms, by nontrivially extending the techniques introduced in SPIDER. For the first time, we prove that MM algorithms can achieve O( √n ϵ2 + n) in gradient computation complexity, for non-convex optimization.
- We conduct extensive experiments on logistic regression with a non-convex regularizer and sparse PCA to show the superior effectiveness of our proposed SPI-MM algorithm over well-established baseline algorithms including MM, MISO, MISO1 and SMM.
2 RelatedWork
The Majorization-Minimization (MM) framework was first proposed in [Lange et al., 2000]. It generalizes methods like EM by "transferring" the optimization to a sequence of surrogate functions which upper bound the original objective function. [Mairal, 2013a] proposed a stochastic majorizationminimization scheme, extending the MM principle to largescale or possibly infinite datasets. [Mairal, 2015] proposed an incremental MM algorithm where a single function is obtained in each iteration, based on which the approximate surrogate function is updated. [Parizi et al., 2015] provided a general MM scheme that is less sensitive to initialization in Concave-Convex Procedure (CCCP) problems. [Xu et al., 2016] presented a relaxed version of the MM algorithm to solve the robust matrix factorization (RMF) problems, which only requires a locally majorant surrogate. More recently, [Bietti and Mairal, 2017] proposed variance reduced MISO for data augmentation problems.
Regarding convergence analysis of MM algorithms, [Vaida, 2005] revealed the global convergence of EM algorithms, extended the result of EM to that of MM algorithms under some conditions. However, they could only solve cases where the objective function is differentiable and convex, whereas we consider a non-convex problem here. [Mairal, 2013b] only studied the asymptotic stationary point conditions with first-order surrogate functions for non-convex problems, although this work gave concrete convergence results for convex and strongly-convex problems. [Kang et al., 2015] established sublinear convergence results for noncovex problems by applying the theory of the KurdykaLojasiewicz inequality. They only considered the regularizer h(θ) to be non-convex rather than a general non-convex problem. [Xu et al., 2016] gave a statement on asymptotic stationary point conditions with the relaxed MM algorithm.
SGD as well as its variants [Nesterov, 1998; Capp´e and Moulines, 2009; Kingma and Ba, 2014] is another line of approaches for solving problem (1). Based on SGD, various variance reduction methods have been proposed, like SAGA [Defazio et al., 2014], SDCA[Shalev-Shwartz and Zhang, 2013], SVRG [Johnson and Zhang, 2013] and SARAH [Nguyen et al., 2017]. SPIDER was proposed in [Fang et al., 2018], which has been proved to be the most efficient algorithm for non-convex problems so far w.r.t. gradient complexity. It achieved O( √n ϵ2 + n) IFO complexity, which outperforms the results in previous methods, e.g. O( n 23 ϵ2 +n)
in SVRG.
Despite the considerable previous research, the convergence analysis of existing MM algorithms for non-convex problems is still not limited. When one considers a first-order surrogate, either a specific convergence result is absent or the gradient complexity has never been considered in MM algorithms. We apply the idea of SPIDER in extended MM definition and propose a generalized SPI-MM algorithm. We also give a concrete convergence rate and a clear IFO complexity analysis.
3 Proposed Algorithm
In this section, we first introduce useful assumptions and definitions in Section 3.1. Then we revisit the classic MM algorithms by examining some surrogate examples in details in Section 3.2. After that, we introduce our proposed SPI-MM algorithm in Section 3.3 and provide convergence analysis results in Section 3.4 and 3.5.
3.1 Preliminaries
We consider problem (1) with the objective function Φ(θ) satisfying the following usual assumptions.
Assumption 1. The objective function in problem (1) satisfies 1. Φ(θ) is bounded below, i.e., Φ∗ = infθ∈Rp Φ(θ) > -∞;
Algorithm 1 Classic MM Algorithm
Input: initial estimator θ0, iteration number K;
- 1: for t = 0, ..., T -1 do
- 2: Compute a surrogate function gt of Φ(θ) near θt,
- 3: Update the solution: θt ∈ argmin gt(θ; θt);
θ
- 4: end for
Output: θT .
- For every i = 1,. . . ,n, the gradient ∇fi is L-Lipschitz continuous, i.e.,
and fi is also said to be L-smooth.
MM algorithms heavily rely on constructing a proper surrogate function for the objective Φ(θ). Typically, the surrogate function should have the following properties.
Definition 1 (Classic surrogate). A function g : Rp → R is a first-order surrogate function of Φ in problem (1) near θt when
- g(θ; θt) is a global majorant surrogate if the general condition g(θ; θt) ⩾ Φ(θ) holds for all θ;
- g(θt; θt) = Φ(θt); ∇g(θt; θt) =∇Φ(θt) when Φ(θ) is smooth.
The incremental first-order oracle (IFO) is usually used to measure the computation complexity of evaluating stochastic optimization algorithms[Agarwal and Bottou, 2014; Wang et al., 2018].
Definition 2 (IFO complexity). For Φ(θ) in problem (1), an IFO means selecting an index i and a datum xi and returning the pair (Φ(θ; xi), ∇Φ(θ; xi)).
3.2 The MMAlgorithms
We here briefly review the classic MM algorithm [Lange et al., 2000; Razaviyayn et al., 2016]. In each iteration, it requires the surrogate function g to tightly upper bound the objective at estimator obtained in last iteration, i.e., θt, as explained in Definition 1.
One popular choice for the surrogate g is the proximal gradient surrogates. Given the gradient ∇f(θt) and another sufficiently large parameter L, the surrogate of Φ(θ) is constructed as follows:
Surrogates like the above one are strongly convex thus are much easier to optimize. MM sets the new θt from
as the starting point for the next iteration.
A surrogate constructed as above satisfies the strict majorization condition in Definition 1 and will result in non-increasing loss function on the sequential estimate {θ0, ..., θt}. Namely, Φ(θt+1) ≤ g(θt+1) ≤ g(θt) = Φ(θt). With such a property, previous works derive convergence rate
Algorithm 2 SPI-MM Algorithm
Input: Initial θ0 ∈ Θ, iteration number T, iteration interval p, mini-batch size S2. Choose a surrogate gi0 of fi near θ0 for all i;
- 1: for t = 0, ..., T -1 do
- 2: if mod(t, p)==0 then
- 3: Draw all samples and choose some surrogates gi for all i ∈ [n], ¯ gt(θ; θt) = 1 |S1| ∑i∈S1 gi,
- 4: else
- 5: Randomly drawmini-batch S2 and choose base surrogate gi for all i ∈ S2,
- 6: ¯ gt(θ; θt) = gS t2 (θ; θt) + (-∇gS t2 (θt-1; θt-1) + Vt-1)⊤(θ - θt) + µ2 ‖θ - θt‖2 ;
- 7: end if
- 8: Update the solution: θt+1 ∈ argmin θ ¯ gt(θ; θt);
Output: θξ that is uniformly chosen at random from
- 9: end for {θt}T-1 t=0 .
for convex and strongly convex problems. Several previous algorithms like SMM [Mairal, 2013b] and MISO [Mairal, 2015] adopt different combinations of surrogates constructed in different iterations, but it is always required that the final surrogates at the current iteration upper bound the original objective function. A classic procedure of MM algorithms is summarized in Algorithm 1.
The globally majorant requirement can conveniently facilitate the convergence proof for convex problems. As above mentioned, one can directly establish the relation between the values of an objective function in two adjacent iterations. However, under this strict requirement, it is hard to fully utilize the historical gradient information though the construction of the surrogate relies on gradients in the past iterations. Moreover, the strictly selected surrogates may lead to a very small step size under a non-convex setting, resulting in a slower convergence rate in practice. In this work, we substantially relax such a requirement and surprisingly obtain convergence guarantees by leveraging recent non-convex optimization techniques.
3.3 The SPI-MMAlgorithm
We first describe our generalized MM idea and then elaborate on the surrogate construction process. In our generalized MM definition, we measure progress per iteration over the objective function using expectation. It allows us to relax the surrogate constraint in classic MM.
Generalized Surrogate
Under our generalized MM framework, we only require the surrogate to satisfy below conditions.
Definition 3 (Generalized surrogate). A function ggen is said to be a surrogate function in generalized MM if
3. Eggen(θ; θt) ≥ Φ(θ) for all θ.
The conditions above are closely related to those in classic MM. For the 2nd condition in Definition 3, we expect the value of a new surrogate to equal the objective function at θt-1. The expectation of the new surrogate's gradient at θt-1 is also required to equal that of the objective function. However, instead of ensuring the surrogate to be globally majorant, we only require its expectation to be globally majorant. When we construct the surrogate on a single datum xi, we also just require Egigen (θ; θt) ≥ Φi (θ) for all θ. This relaxed condition ensures that our surrogate be valid but of sufficient flexibility in exploring the solution space. Such milder constraints in generalized MM do not directly imply Φ(θt) ≤ Φ(θt-1), but they ensure ∀t, EΦ(θt) ≤ Φ(θ0). This implies guarantees for the objective function value to be non-increased in expectation.
Note that the above surrogate is valid in the classic sense. The first condition requires that the surrogate concentrate around a classic surrogate. However, with slight uncertainty, the choice over the surrogates becomes more flexible. For example, we can make slight compromise in accuracy to obtain a larger step size, giving faster convergence in practice. Also, by generalizing the surrogate, we are able to use the techniques for proving the objective decrease in expectation. This is key for obtaining our following convergence guarantees.
With the generalized surrogate definition, we propose a method to construct the surrogate and develop the SPI-MM algorithm for solving problem (1). Overall, this method considers the combination of past and current gradient information, and an arbitrary valid surrogate obtained in the classic MM setting. Some surrogates proposed in [Mairal, 2013a] and [Xu et al., 2016] also apply here. We show that the constructed surrogate is not necessarily restricted to the traditional MM setting.
SPI-MM Algorithm
Here, we propose a concrete algorithm, named SPI-MM that employs a specific generalized surrogate construction.
Our proposed SPI-MM algorithm fully leverages the gradient of past surrogates as follows. Suppose each epoch includes p iterations and totally we need T iterations. At the first step t0 in each epoch, we use all the samples n to construct a strict surrogate as in classic MM. For each datum, we choose a surrogate gi of Φi near θ0. When h(θ) in Φ(θ) is non-smooth, we choose a surrogate gi of fi near θ0. We define |S1| = n. Then we have
We minimize Eqn.(3) to get θ1. For the next step, we only sample S2 samples. Relying on θ0, θ1 respectively, we construct a base surrogate gS2 (θ; θ1) of Φi ∈ S2 near θ1 and an auxiliary surrogate gS2 (θ; θ0) near θ0. These two surrogates here at least satisfy the 2nd condition in Definition 1.
We use the base surrogate gS2 (θ; θ1) as the first term of the new surrogate in this step. We compute the gradient of the auxiliary surrogate gS2 (θ; θ0) and ¯ g0(θ; θ0) at θ0, i.e. ∇gS2 (θ0; θ0),∇¯ g0(θ0; θ0) to construct a linear term (-∇gS2 (θ0; θ0) + ∇¯ g0(θ0; θ0))⊤(θ-θ1), and take it as the second term in the new surrogate. We add a second-order term µ2 ‖θ - θ1‖2 to complement for the relaxing in the base surrogate. We minimize the sum of these three terms to get θ2. The following optimization iterations repeat the above surrogate construction, summarized as
We rewrite the gradient part in the linear term as -∇gS t2 (θt-1; θt-1) +Vt-1 for simplicity:
Samples {S t-1 2 , S t-2 2 , ..., S 1 2 } in different iterations are equal in number. The idea for constructing this surrogate is borrowed from SPIDER [Fang et al., 2018], where current gradient is estimated by utilizing the gradient in the past to reduce the variance, leading to smaller sampling numbers.
We demonstrate below that the surrogate in SPI-MM satisfies conditions in our Definition 3. For the first condition, we have
from Eqn. 4. On the other side,
as we require the base surrogate gS t2 (θ; θt) to satisfy the 2nd condition in Definition 1, leading to ¯ gt(θt; θt) = Φ(θt) verifying the first condition.
For ∇¯ gt(θ; θt) at θt, the gradient is computed as
It is easy to obtain the expectation of -∇gS t2 (θt-1; θt-1) + Vt-1 is zero by iteratively unfolding this term and i.i.d. sampling condition. Thus, we have E∇¯ gt(θt; θt) = E∇gS t2 (θt; θt) = ∇Φ(θt), which satisfies the 2nd condition.
Finally, for the 3rd condition in Definition 3, we have E¯ gt(θ, θt) = EgS t2 (θ-θt)+ µ2 ‖θ-θt‖2 . Suppose the objective function Φ(θ) is L-smooth, ∇2EgS t2 (θ-θt) ⪰ µf . Then we just need to tune µ large enough to make ¯µ = µ+µf larger than L to satisfy the 3rd condition in Definition 3. We argue that µf here is reasonable, since the base surrogate gS t2 (θ; θt) is selected by ourselves. For simplicity, we can even directly select a strongly convex function here.
Our way of constructing the new surrogate accords with the basic idea in SPIDER. Based on the base surrogate, we use the gradient of past surrogates to construct a linear term, which is able to reduce the variance of the base surrogate. Such a composition also facilitates the convergence analysis, which is explained in next subsection. The overall algorithm is summarized in Algorithm 2.
3.4 Convergence Guarantees
We here analyze the convergence properties of the proposed scheme under the generalized MM setting. We focus on the non-convex problem and searching for a stationary point E‖∇Φ(θ)‖ ≤ ϵ. We first show our loss function is decreasing every epoch in expectation and then give the concrete convergence results and corresponding IFO complexity.
Lemma 1. Suppose Assumption 3.1 holds, and a sequence {θntp} is produced by Algorithm 2 after every p iterations. The base surrogate gt(θ; θt) is Lf -smooth, α = 1 2µ - Lf 2µ¯µ2 - L 2¯µ2 - L2 p 2¯µ2 µ|S2| , Vi = ∇¯ gi(θi; θi). Then the objective function Φ(θ) after every p iterations is guaranteed to decrease in expectation:
By Lemma 1, if each epoch contains p iterations, we guarantee that the objective function be almost certain to be decreasing in expectation. It is also very easy to derive EΦ(θT ) - Φ(θ0) ≤ - ∑T-1 i=0 αE‖Vi‖2 , meaning the objective function value is driven to be shrinking. Theorem 1 gives the final convergence rate and IFO complexity by applying Lemma 1. It shows that the objective function converges to a stationary point at a rate of O(1/√t) and the total gradient computation is O(√nϵ-2 + n).
Theorem 1. Suppose Assumptions 3.1 holds and apply SPIMM in Algorithm 2. Let p = √n, S2 = √n and µ be large enough. Then we have final output satisfying E‖∇Φ(θξ)‖ ≤ ϵ as long as the total number of iterations T satisfies
And the total resulting IFO complexity is O(√nϵ-2 + n).
3.5 Proof Roadmap
Due to space limit, we omit details of the proof and provide a proof roadmap here to illustrate the basic idea.
We aim to bound the iteration steps and gradient computations for attaining the first-order stationary point E‖∇Φ(θξ)‖ ≤ ε in non-convex problems. To this end, we leverage the structure in SPI-MM and rewrite E‖∇Φ(θξ)‖ ≤ ε as follows:
Then we bound the above two last terms by establishing following two lemmas respectively.
Lemma 2. Under Assumption 1, let nt = [t/p] such that (nt -1)p ≤ t ≤ ntp-1, (nt -1)p is the beginning of epoch nt. Then the estimator Vk satisfies
The above lemma bounds the first term. Now we proceed to bound the second term E‖Vt‖ as follows. We have
By substituting θt+1 - θt into the following formulation
we get Lemma 3.
Lemma 3. Under Assumption 1, our new surrogate is ¯µstrongly convex and the base surrogate is Lf -smooth. If the parameters µ, ¯µ, Lf , p and S2 are chosen satisfying
we have
By applying Lemma 2 and Lemma 3, we can prove E‖∇Φ(θξ)‖2 ≤ 2 Tα (1+ L2 p ¯µ2 |S2| ) (Φ(θ0) - Φ∗ ), and with proper parameters selected we get the convergence rate and IFO complexity results in Theorem 2.
4 Experiments
We conduct two groups of experiments on non-convex problems to evaluate our proposed results. The first group is to optimize a logistic regression loss with a non-convex regularizer[Gasso et al., 2009]. Specifically, we optimize the following problem:
where θ[j] is the j-th element in θ. The function h(θ) here is not differentiable. We write it as a composition of h(u) = log(u + ε) and u = |θ[j]|. We construct the following surrogate for h(θ) through linear approximation:
By choosing a second-order approximation of the first logistic term fS t-1 2 (θt-1) + ∇fS t-1 2 (θt-1)⊤(θ - θt-1) + Lf 2 ‖θ -θt-1‖2 , we can establish the linear term (-∇fS t-1 2 (θt-2) + ∑t-2 i=1 [∇fS i2 (θi) - ∇fS i2 (θi-1)] + ∇f(θ0))(θ-θt-1) and the second-order term µ2 ‖θ-θt-1‖2
according to SPI-MM. We then have the final surrogate function with omitted constants:
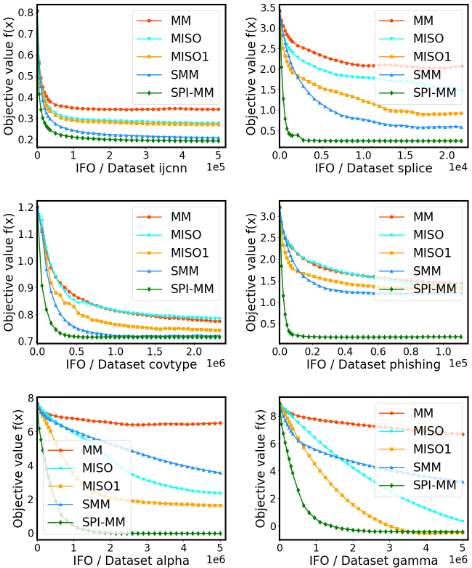
We choose four algorithms as baselines, i.e. classic MM in Algorithm 1, MISO [Mairal, 2015], MISO1 [Mairal, 2015] and SMM [Mairal, 2013b], for performance comparison with ours on four datasets including ijcnn, splice, covtype, phishing 1 [Chang and Lin, 2011] and two larger datasets including alpha and gamma 2 . MISO1 is a modification of vanilla MISO by tuning the Lipschitz parameter of the surrogate on 5% of the samples.
Figure 2 shows the curves of different algorithms on IFO vs. objective function value. One can observe that our proposed SPI-MM algorithm outperforms all compared algorithms on all the six datasets. It is obvious that SPI-MM has sharper convergence behavior w.r.t. the IFO complexity. SPI-MM also gives a lower objective function value. In contrast, the compared algorithms are more likely to get stuck in a poorer local minimum.
1 https://www.csie.ntu.edu.tw/ cjlin/libsvmtools/datasets/
2 ftp://largescale.ml.tu-berlin.de/largescale/
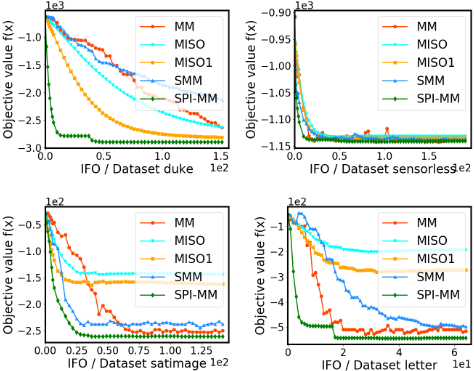
In the second group of experiments, we compare our SPIMM algorithm with the same four baselines as above on four datasets including duke, satimage, sensorless and letter 1 , on the sparse-PCA problem that is formulated as below [Zou et al., 2006]:
where Σ ≜ X⊤X,X ∈ Rn×p , n is the number of samples and p is the dimension. Our algorithm SPI-MM exhibits faster convergence rate w.r.t. IFO as shown in Figure 3. SPIMM decreases the objective function value much faster than others. We observe that the loss curves of SMM and MM are less stable here. Our assumed explanation is that they lack past gradient information as supervision.
Both groups of experiments clearly demonstrate the advantage of the proposed SPI-MM over well-developed baseline algorithms.
5 Conclusions
In this work, we propose a generalized concept of surrogate that is core to MM algorithms, which requires milder conditions for bounding the objective functions. This generalized conception facilitates the convergence analysis for nonconvex problems. We then develop a specific algorithm SPIMM based on the generalized surrogate and prove its nonasymptotic convergence rate and IFO complexity. Numerical results confirm the computational superiority of SPI-MM over other popular algorithms.
Acknowledgments
Hu Zhang (No. 201706340188) is partially supported by the Chinese Scholarship Council. The work of Jiashi Feng was partially supported by NUS IDS R-263-000-C67-646, ECRA R-263-000-C87-133 and MOE Tier-II R-263-000-D17-112.
@inproceedings{ijcai2019p591,
  title     = {Generalized Majorization-Minimization for Non-Convex Optimization},
  author    = {Zhang, Hu and Zhou, Pan and Yang, Yi and Feng, Jiashi},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {4257--4263},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/591},
  url       = {https://doi.org/10.24963/ijcai.2019/591},
}
TY - CPAPER TI - Generalized Majorization-Minimization for Non-Convex Optimization AU - Zhang, Hu AU - Zhou, Pan AU - Yang, Yi AU - Feng, Jiashi T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 4257 EP - 4263 DO - 10.24963/ijcai.2019/591 UR - https://doi.org/10.24963/ijcai.2019/591 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





