
Exploring and Distilling Cross-Modal Information for Image Captioning
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 5095-5101.
https://doi.org/10.24963/ijcai.2019/708
Keywords
- Computer Vision: Language and Vision
- Natural Language Processing: Natural Language Processing
Abstract
Recently, attention-based encoder-decoder models have been used extensively in image captioning. Yet there is still great difficulty for the current methods to achieve deep image understanding. In this work, we argue that such understanding requires visual attention to correlated image regions and semantic attention to coherent attributes of interest. To perform effective attention, we explore image captioning from a cross-modal perspective and propose the Global-and-Local Information Exploring-and-Distilling approach that explores and distills the source information in vision and language. It globally provides the aspect vector, a spatial and relational representation of images based on caption contexts, through the extraction of salient region groupings and attribute collocations, and locally extracts the fine-grained regions and attributes in reference to the aspect vector for word selection. Our fully-attentive model achieves a CIDEr score of 129.3 in offline COCO evaluation with remarkable efficiency in terms of accuracy, speed, and parameter budget.
- [Anderson et al., 2016] Peter Anderson, Basura Fernando, Mark Johnson, and Stephen Gould. SPICE: Semantic propositional image caption evaluation. In ECCV, 2016.
- [Anderson et al., 2018] Peter Anderson, Xiaodong He, Chris Buehler, Damien Teney, Mark Johnson, Stephen Gould, and Lei Zhang. Bottom-up and top-down attention for im- age captioning and VQA. In CVPR, 2018.
- [Banerjee and Lavie, 2005] Satanjeev Banerjee and Alon Lavie. METEOR: An automatic metric for MT evalua- tion with improved correlation with human judgments. In ACL, 2005.
- [Brendel and Bethge, 2019] Wieland Brendel and Matthias Bethge. Approximating CNNs with bag-of-local-features models works surprisingly well on imageNet. In ICLR, 2019.
- [Chen et al., 2015] Xinlei Chen, Hao Fang, Tsung-Yi Lin, Ramakrishna Vedantam, Saurabh Gupta, Piotr Dollár, and C. Lawrence Zitnick. Microsoft COCO captions: Data collection and evaluation server. arXiv preprint arXiv:1504.00325, 2015.
- [Fang et al., 2015] Hao Fang, Saurabh Gupta, Forrest N. Ian- dola, Rupesh Kumar Srivastava, Li Deng, Piotr Dollár, Jianfeng Gao, Xiaodong He, Margaret Mitchell, John C. Platt, C. Lawrence Zitnick, and Geoffrey Zweig. From captions to visual concepts and back. In CVPR, 2015.
- [Geirhos et al., 2019] Robert Geirhos, Patricia Rubisch, Claudio Michaelis, Matthias Bethge, Felix A. Wichmann, and Wieland Brendel. ImageNet-trained CNNs are biased towards texture; increasing shape bias improves accuracy and robustness. In ICLR, 2019.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, 2016.
- [Hochreiter and Schmidhuber, 1997] Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. Neural Computation, 1997.
- [Jiang et al., 2018a] Wenhao Jiang, Lin Ma, Xinpeng Chen, Hanwang Zhang, and Wei Liu. Learning to guide decoding for image captioning. In AAAI, 2018.
- [Jiang et al., 2018b] Wenhao Jiang, Lin Ma, Yu-Gang Jiang, Wei Liu, and Tong Zhang. Recurrent fusion network for image captioning. In ECCV, 2018.
- [Karpathy and Li, 2015] Andrej Karpathy and Fei-Fei Li. Deep visual-semantic alignments for generating image de- scriptions. In CVPR, 2015.
- [Kingma and Ba, 2014] Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In ICLR, 2014.
- [Lin, 2004] Chin-Yew Lin. ROUGE: A package for auto- matic evaluation of summaries. In ACL, 2004.
- [Liu et al., 2018a] Daqing Liu, Zheng-Jun Zha, Hanwang Zhang, Yongdong Zhang, and Feng Wu. Context-aware visual policy network for sequence-level image caption- ing. In ACM Multimedia Conference, 2018.
- [Liu et al., 2018b] Fenglin Liu, Xuancheng Ren, Yuanxin Liu, Houfeng Wang, and Xu Sun. simNet: Stepwise image-topic merging network for generating detailed and comprehensive image captions. In EMNLP, 2018.
- [Lu et al., 2017] Jiasen Lu, Caiming Xiong, Devi Parikh, and Richard Socher. Knowing when to look: Adaptive attention via a visual sentinel for image captioning. In CVPR, 2017.
- [Papineni et al., 2002] Kishore Papineni, Salim Roukos, Todd Ward, and Wei-Jing Zhu. BLEU: a Method for auto- matic evaluation of machine translation. In ACL, 2002.
- [Rennie et al., 2017] Steven J. Rennie, Etienne Marcheret, Youssef Mroueh, Jarret Ross, and Vaibhava Goel. Self- critical sequence training for image captioning. In CVPR, 2017.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NIPS, 2017.
- [Vedantam et al., 2015] Ramakrishna Vedantam, C. Lawrence Zitnick, and Devi Parikh. Cider: Consensus- based image description evaluation. In CVPR, 2015.
- [Vinyals et al., 2015] Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. Show and tell: A neu- ral image caption generator. In CVPR, 2015.
- [Wu et al., 2016] Qi Wu, Chunhua Shen, Lingqiao Liu, An- thony R. Dick, and Anton van den Hengel. What value do explicit high level concepts have in vision to language problems? In CVPR, 2016.
- [Xu et al., 2015] Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron Courville, Ruslan Salakhudinov, Rich Zemel, and Yoshua Bengio. Show, attend and tell: Neural image caption generation with visual attention. In ICML, 2015.
- [Yao et al., 2017] Ting Yao, Yingwei Pan, Yehao Li, Zhao- fan Qiu, and Tao Mei. Boosting image captioning with attributes. In ICCV, 2017.
- [Yao et al., 2018] Ting Yao, Yingwei Pan, Yehao Li, and Tao Mei. Exploring visual relationship for image captioning. In ECCV, 2018.
- [You et al., 2016] Quanzeng You, Hailin Jin, Zhaowen Wang, Chen Fang, and Jiebo Luo. Image captioning with semantic attention. In CVPR, 2016.
- [Zhang et al., 2006] Cha Zhang, John C. Platt, and Paul A. Viola. Multiple instance boosting for object detection. In NIPS, 2006.
- [Zhu et al., 2018] Xinxin Zhu, Lixiang Li, Jing Liu, Haipeng Peng, and Xinxin Niu. Captioning transformer with stacked attention modules. Applied Sciences, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Image captioning is a very challenging yet pragmatic multidiscipline task that combines image understanding and language generation. The deep neural networks, especially the models based on the encoder-decoder framework, have shown great success in pushing the state-of-the-art image captioning [Yao et al., 2018]. A modern solution is to exploit a convolutional neural network (CNN), e.g., ResNet [He et al., 2016], to encode the image and a recurrent neural network (RNN), e.g., LSTM [Hochreiter and Schmidhuber, 1997], to generate the sentence with attention mechanisms [Xu et al., 2015] extracting relevant information. Considerable efforts are put to improve the framework, such as incorporating object-oriented image representations [Anderson et al., 2018] and augmenting the information source with predicted textual attributes [Fang et al., 2015]. Recently, several studies try to
∗Equal contributions.
†Corresponding authors.
umbrella
woman, umbrella, holding, yellow, clock, sign, building, standing, street, man, brick, walking, tower, train, her, wall, posing, stop, old, front, girl, bathroom, tennis, person, carrying, young, down, people, wearing, bananas, sitting, tree, toilet, hanging, giraffe, red, cat, white, wooden, field, tall, tracks, surfboard, bench, pole, tie, city, kite, it
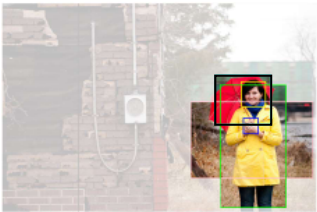
Figure 1: Individual components of image representations often embody intrinsic combinations, which is beneficial for deep and semantic understanding of images. For visual regions, the focus on the umbrella is naturally extended to the related areas. For attribute words, the input word umbrella is associated with common collocations. Those are learned by the proposed approach.
consider the problem from a cross-modal way, making use of both image regions and textual attributes [Yao et al., 2017; Jiang et al., 2018a; Liu et al., 2018b].
However, there is still great difficulty in deep image understanding, as the systems tend to view the image as unrelated individual parts [Brendel and Bethge, 2019; Geirhos et al., 2019] and are not guided to comprehend the general correlations of such parts. For example, given the word umbrella, a person would likely associate it with the notion of rain or the act of holding, which is generally not learned by the existing systems regardless of the image representations they use. In this work, we argue that such understanding requires effective attention to correlated image regions and coherent attributes of interest, so that the systems could learn generalized combinations through observations from images and written captions.
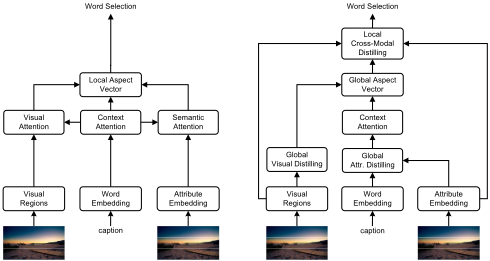
In order to achieve that, we propose the Global-and-Local Information Exploring-and-Distilling approach that explores and distills the cross-modal source information. It first distills individual parts of image representations into inherently grouped image regions and attribute words, to form a spatial and relational representation. Those representations are not coupled with specific captions but contain general, informative, associative knowledge related to the image. Then, considering the current partially-generated captions, it provides globally the aspect vector, which semantically expresses and explores all the related representation groups that should be considered for the next output word. As the global aspect vector may not be rich in details, GLIED revisits individual parts of images and distills the regions and attributes again to form the local aspect vector, which could be more precise and finergrained. We implement the approach upon a fully-attentive decoder using cross-modal representations. Sketches of both the base model and the proposed approach are shown in Figure 2. The experiments on COCO image captioning dataset validate our argument and prove the effectiveness of the proposed approach.
Overall, the main contributions of this work are:
- We propose the Global-and-Local Information Exploring-and-Distilling approach, which globally captures the inherent spatial and relational groupings of the individual image regions and attribute words for an aspectbased image representation, and locally it extracts finegrained source information for precise and accurate word selection.
- The experiments based on a fully-attentive decoder on the COCO image captioning dataset prove the effectiveness of our approach, which achieves 129.3 in terms of CIDEr with fewer parameters and faster computation, compared with existing state-of-the-art systems.
- Further analysis shows that the proposed approach excels at generating complete descriptions and the learned region groupings and attribute collocations are in accordance with human intuition, which forms a powerful basis for describing images.
2 RelatedWork
Attention-based encoder-decoder models are used extensively in modern image captioning systems. Our work closely relates to the efforts on refining source image representations, using cross-modal information, and exploring semantic relationships for better image understanding.
Refining source representations. To represent images, visual features extracted by CNNs are most-widely used [Xu et al., 2015], while textual features consisting of attribute word vectors are also proposed [Wu et al., 2016]. Those kinds of features are often used by the decoder with the help of attention mechanisms to focus on the most relevant image regions or attribute words instead of the whole image, namely, visual attention [Xu et al., 2015] or semantic attention [You et al., 2016]. Visual features based on Region-CNNs and predicted bounding boxes [Anderson et al., 2018] further extract object-oriented regions instead of generic regions considered by normal CNNs. Regardless of the type of source representations, relationships among the individual parts of representations (regions or attributes) are not defined, which should be essential to a semantic understanding of images.
Using cross-modal information. To our knowledge, there are some efforts [Jiang et al., 2018a; Yao et al., 2017] trying to use both kinds of features in a non-trivial way. Jiang et al. [2018a] proposed to use a linear layer with max pooling to select guiding attributes as additional input for a recurrent decoder using visual attention. Yao et al. [2017] presented a series of models (LSTM-A2,3,4,5) to combine visual features and textual attributes. Notably, those systems are based on recurrent decoders, while our approach is implemented on a fully-attentive decoder. Zhu et al. [2018] also used a fullyattentive decoder but they did not consider cross-modal information and only incorporated visual attention.
Exploring semantic relationships. A new advance [Yao et al., 2018] tried to explore visual relationships explicitly by using graph networks to encode scene graphs modeling the spatial and semantic relationships of image regions. However, the relationships between visual objects are predicted by a separate model with extra annotated data. In contrast, our model associates the features based on attention and the relationships are implicitly modeled as weighted combinations and trained together with the captioning model.
3 Approach
We first introduce the cross-modal information we used and our fully-attentive base decoder. Then, we present the global distilling method for extracting salient region groupings and attribute collocations, and the local distilling method for extracting fine-grained source information.
3.1 Information Sources
Since we consider the problem from a cross-modal point of view, we use both kinds of source representations, namely visual features and textual attributes. Visual features are good at illustrating the shapes and the colors, while it is not informative in what the item is in words. Textual attributes, in contrast, represent an image with high-level semantic concepts. Typically, the concepts are words that describe objects (e.g. person, car), attributes (e.g. off, electric), or relationships (e.g. using, sitting). For visual regions, we utilize the RCNN-based features, following the implementation of Anderson et al. [2018]. We denote the extracted image regions as I. For textual attributes, we adopt Multiple Instance Learning [Zhang et al., 2006], a weakly-supervised method, to build an attribute extractor, following Fang et al. [2015]. Since textual attributes are discrete word tokens, we use an attribute embedding to project them into vectors, which are then stacked as visual attributes A.
3.2 Cross-Modal Base Model
Our cross-modal base model is adapted from [Vaswani et al., 2017], which is a neural model entirely driven by attention mechanisms without recurrent connections, and further incorporates the visual attention and the semantic attention specific to the image captioning task, making up a fully-attentive captioning decoder, which is shown in the left of Figure 2.
The basic building block is the multi-head attention, and each head is defined as a scaled dot-product:
where Q ∈ Rdl×dh and K, V ∈ Rk×dh represent the packed queries, keys, and values, respectively. Wis are the parameters of the linear transformations, 1 dl is the number of query vectors, and dk = dh/n is the size for each head, where n is the number of heads and dh is the hidden size. The outputs of the n heads are then concatenated and projected to form the final attentive representation:
The multihead attention is followed by a series of operations of shortcut connection, dropout, and layer normalization, which we denote as function G(·, ∗), where ∗ is the input.
At each generation timestep, the input caption word x from last timestep first attends to the previously generated words X to obtain the contextual information ˜x:
and then attends to the image regions I and attribute words A to gain the related cross-modal information c:
The parameters of Hv and Ha are shared so that their outputs are in the same space and we only use one head so that they resemble the conventional visual attention and semantic attention. The results are then transformed into ˜c using a two-layer rectified linear unit F surrounded by G as well and another G with original input x as residual is applied to enhance the importance of the current input:
The vector ˜c could be regarded as the local aspect vector, since it also depicts a specific aspect of the image but is not aware of the inherent relations among the individual regions or attributes. Finally, the output word is sampled from:
where each value of p ∈ R|D| is a probability indicating how likely each word in vocabulary D should be the current output word. In training, the whole model is trained with cross entropy loss with respect to the reference captions. The model can also be training further with reinforcement learning using a CIDEr-based reward as Rennie et al. [2017].
1 For conciseness, all the bias terms of linear transformations in this paper are omitted.
3.3 Global-and-Local Information Exploring-and-Distilling
The proposed approach also takes advantage of the multihead attention to realize the idea of learning salient region groupings and attribute collocations, which could be seen as weighted combination of the individual features.
Global Visual Distilling
When we look at an image and try to describe it, we often extend the focus on one specific object to its surrounding areas and seek for other objects that often appears together with the object. Those spatially or semantically related objects form an inherent group we attend to. Thus, visual distilling is supposed to learn region groupings that characterize the spatial or semantic relationships of each seemingly independent image regions. We use a visual self attention to achieve the effect:
Please note that we also apply the non-linear transformation and post processing as in Eq. (5), which is not included in the above equation for ease of introduction. The representation is global in that it is not coupled with specific caption contexts but learns general combinations of image regions that helps the learning of the systems. It distills naturally related image regions for a higher-level representation of the image in the vision domain and remains the same for every decoding timestep.
Global Attribute Distilling
In the language domain, we also have the ability of thinking in association and using collocations when phrasing sentences. Self-attention could also be applied to emulate the process. However, unlike image regions which are based on shapes or textures, simply combining the attributes may result in common collocations that do not actually appear in the image. The captioning system may be misled if such kind of collocations are used, which we empirically verify in the preliminary experiments. To learn meaningful collocations, we propose to use a pivot word and gather the collocations of this word, so that for each decoding timestep, a different attribute combination can be used by the decoder:
As the input information is also bypassed, the collocations serve as a reference of possibly related, commonly cooccurring attributes, further lessening the risk of misinterpretation of the actual image.
Global Aspect Generation
To make use of the distilled visual and attribute knowledge and obtain a global aspect vector, the caption context is first constructed via self attention based on the input word embeddings enriched by attribute collocations:
where ˜ T is the pack of ˜ t. Then, the caption context is used to further incorporate the visual region groups:
Eq. (5) is used to obtain ˜cg. We do not include the semantic attention such that each kind of source information is incorporated into the vector only once. The vector ˜cg could be seen as the global aspect vector, since it includes not only the regions or the attributes related to the current caption context, but also the regions and attributes that commonly show up with them. It provides a context that also explores the associative aspect of the source representations.
Local Cross-Modal Distilling
The global aspect vector gathers and distills the related crossmodal source information that is more general to the current context, which is a powerful basis for description. On the other hand, it could be too general for word selection that is precise and detailed, since the basic unit of its sources is the learned groupings of regions and attributes. We further propose the local cross-modal distilling method to make the decoding revisit the fine-grained source information so that the exact aspect could be retrieved:
Similar to the base modal, the parameters of Hvl and Hal are also shared. Because G bypasses the global aspect vector, cl serves as a comprehensive guide that explores and distills all of the available and presumably essential information. It is then fed to the output layer for word selection the same with the base model. It should be noted it is essentially the same procedure as the cross-modal attention in the base model; however, since the input is different in terms of information, it is for different purpose and functions differently. From another perspective, the base model and most of the existing models all conduct local information distilling that does not take intrinsic associations of source information into account.
The proposed approach processes the source information in such a way that from input to output, the granularity of the information goes from fine-grained to coarse-grained to finegrained through exploring and distilling. The receptive field of the decoder is broadened at the middle of the process to accommodate the spatial and relational representation of the images and to realize an efficient flow of information.
4 Experiment
In this section, we describe a benchmark dataset for image captioning and some widely-used metrics, followed by our training details and evaluation of the proposed approach.
4.1 Datasets andMetrics
We evaluate the proposed approach on the widely-used COCO dataset [Chen et al., 2015], which contains 123,287 images. Each image in the dataset is paired with 5 sentences. We use the publicly-available splits in [Karpathy and Li, 2015] for offline evaluation. There are 5,000 images each in validation set and test set for COCO. We report results from the official COCO captioning evaluation toolkit [Chen et al., 2015] that uses automatic evaluation metrics SPICE [Anderson et al., 2016], CIDEr [Vedantam et al., 2015], BLEU [Papineni et al., 2002], METEOR [Banerjee and Lavie, 2005] and ROUGE [Lin, 2004], of which SPICE and CIDEr are specifically designed to evaluate image captioning systems.
| Cross-Entropy | B-1 | B-4 | M | R | C | S |
|---|---|---|---|---|---|---|
| SCST∑ | - | 32.8 | 26.7 | 55.1 | 106.5 | - |
| Up-Down | 77.2 | 36.2 | 27.0 | 56.4 | 113.5 | 20.3 |
| RFNet∑ | 77.4 | 37.0 | 27.9 | 57.3 | 116.3 | 20.8 |
| GCN-LSTM | 77.4 | 37.1 | 28.1 | 57.2 | 117.1 | 21.1 |
| Base | 77.0 | 36.3 | 27.6 | 56.6 | 113.5 | 20.6 |
| GLIED | 77.8 | 37.9 | 28.3 | 57.6 | 118.2 | 21.2 |
| RL on CIDEr | B-1 | B-4 | M | R | C | S |
| SCST∑ | - | 35.4 | 27.1 | 56.6 | 117.5 | - |
| Up-Down | 79.8 | 36.3 | 27.7 | 56.9 | 120.1 | 21.4 |
| RFNet∑ | 80.4 | 37.9 | 28.3 | 58.3 | 125.7 | 21.7 |
| GCN-LSTM | 80.9 | 38.3 | 28.6 | 58.5 | 128.7 | 22.1 |
| GLIED | 80.4 | 39.6 | 28.9 | 58.8 | 129.3 | 22.6 |
4.2 Settings
For image regions, we use the RCNN-based visual features provided by Anderson et al. [2018], which are extracted by Faster R-CNN. For attributes, we use the attribute prediction model pre-trained by Fang et al. [2015] for 1,000 attribute words on COCO. For an image, the number of attribute words is reduced to the number of image regions.
We replace caption words that occur less than 5 times in the training set with the generic unknown word token, resulting in a vocabulary with 9,487 words. The word embedding size and model size are 256 and 512, respectively, and in implementation, we share the attribute embedding and the input word embedding. The number of heads n in multi-head attention is set to 8 unless otherwise stated. We train the model with both cross-entropy loss and reinforcement learning optimizing CIDEr. The model is trained with batch size of 80 for 25 epochs with early stopping based on CIDEr with crossentropy loss, followed by reinforcement learning. We use Adam [Kingma and Ba, 2014] with a learning rate of 10-4 for parameter optimization. We also apply beam search with beam size = 3 during inference.
4.3 Experimental Results and Analysis
In this section, we compare the proposed approach with the state-of-the-art models in terms of captioning performance and model complexity. Examples are given to show the effect of our approach. Ablation studies are conducted to verify the effectiveness of each component in the proposed approach.
Quantitative Comparisons
Four state-of-the-art models, namely SCST [Rennie et al., 2017], Up-Down [Anderson et al., 2018], RFNet [Jiang et al., 2018b], and GCN-LSTM [Yao et al., 2018] are selected. The results on Karpathy test split are shown in Table 1. For the baselines, we directly report the results from original papers. Our cross-modal base model is competitive and outperforms Up-Down, which is a strong baseline, especially in SPICE, which correlates the best with human judgment [Anderson et al., 2016], suggesting the cross-modal point of view helps to
Reference: small dog sitting on covered table with orange toy.
LSTM: a dog sitting on a bed.
SoftAtt: a dog laying on a bed with a ball.
Up-Down: a dog sitting on a bed with a ball in front of it.
Base: a white and brown dog sitting on top of a bed. GLIED: a small [dog] sitting on top of a bed next to a toy.
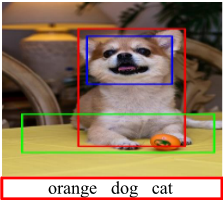
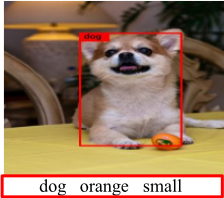
Figure 3: Examples of the generated captions and cross-modal sources. Please view in color. The first column shows the global distilling results and the second columns shows the local distilling results with image regions on the top and attribute words at the bottom. Those results are from the timestep that outputs dog and inputs small. For global visual distilling, we show the top-3 visual regions of the group that is most attended in local distilling. For global attribute distilling, we also show the top-3 collocations. Based on the intrinsic combinations of the source information, GLIED is able to generate more complete captions that is detailed both in the attributes and objects it describes.
generate coherent captions. The proposed approach (denoted as GLIED) overpasses all baselines under cross-entropy loss and reinforcement learning settings, respectively. In reference to Table 4, which shows sub-category scores of SPICE, GLIED does especially well in Relations and Count, which requires semantic and deep understanding of images, showing that the intrinsic associations of source information provides a solid basis for describing images.
Qualitative Analysis
Figure 3 shows an example in comparison with the reference and the captions generated by different models. As we can see, all the models generate fluent and descriptive sentences of the image. However, they differ in how much the input information is expressed. Compared with those systems, GLIED produces a more complete and coherent caption.
We illustrate the most attended vision region group and the top-3 most attended textual attributes in local cross-modal distilling. We also show the top-3 most attended image regions in the vision region group from global visual distilling and the top-3 most attended textual attributes in global attribute distilling. Global visual distilling learns to extend focus in space and seek for related regions to form a salient region group with semantics. Global attribute distilling learns word collocations within the set of visual attributes and enriched semantic information. When the input words are descriptive (e.g., small), it gives more attention to relevant entities (e.g., orange, dog, and cat). The global aspect generator further gains related information in vision domain based on the enriched semantic information. Based on the collected source information (the global aspect vector), the local distilling attention retrieves original visual and textual information and decides on what is the most probable next word. For example, when inputting small, the final attention retrieves the textual dog and the visual dog from the sources, which are much more concentrated than the global aspect vector and ensure the focus on current caption generation.
Model Complexity and Computation Speed
To analyze model complexity, we compare our model with (1) LSTM, which only uses a one-layer LSTM decoder [Vinyals et al., 2015] but inputs visual features at each timestep as Lu et al. [2017], (2) SoftAtt [Xu et al., 2015], which extends LSTM with visual attention, (3) Up-Down, which includes a two-layer LSTM decoder with top-down attention, (4) CT [Zhu et al., 2018], which is based on a transformer with six decoder blocks, and our cross-modal base model. For fair comparison, we reimplement those models using RCNNbased visual feature under the maximum log-likelihood setting. We also report obtained CIDEr scores. As Table 2 shows, our model achieves arguably the best balance between speed and accuracy. Our cross-modal base model is very efficient and is comparable with Up-Down in accuracy, yet 4x smaller and 2x faster. GLIED brings about a 5-point CIDEr improvement by moderate increase in parameters with even faster training and slight inference speed regression. It suggests that the cross-modal point of view and our approach benefits deep image understanding in several aspects.
| Methods | #Parameters | Train Time (h) | Inference Speed (ips) | CIDEr |
|---|---|---|---|---|
| LSTM | 11.5M | 16.8 | 28.6 | 105.7 |
| SoftAtt | 12.1M | 20.4 | 23.3 | 111.5 |
| Up-Down | 50.1M | 24.9 | 14.8 | 113.2 |
| CT† | 27.5M | 22.7 | 12.9 | 115.1 |
| Base | 12.3M | 13.2 | 37.9 | 113.5 |
| Ours | 18.3M | 11.9 | 34.5 | 118.2 |
Performance on the Online COCO Evaluation Server
Following Jiang et al. [2018b], we also submit our GLIED optimized using reinforcement learning to online COCO evaluation server. We compare with the top-performing entries on the leaderboard whose methods are published, which are RFNet [Jiang et al., 2018b], CAVP [Liu et al., 2018a], UpDown [Anderson et al., 2016], LSTM-A [Yao et al., 2017], SCST [Rennie et al., 2017], AdaAtt [Lu et al., 2017] and HardAtt [Xu et al., 2015]. As we can see, the GLIED performs better than the existing systems.
| COCO | BLEU-1 | BLEU-2 | BLEU-3 | BLEU-4 | METEOR | ROUGE-L | CIDEr | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | c5 | c40 | |
| HardAtt | 70.5 | 88.1 | 52.8 | 77.9 | 38.3 | 65.8 | 27.7 | 53.7 | 24.1 | 32.2 | 51.6 | 65.4 | 86.5 | 89.3 |
| AdaAtt | 74.8 | 92.0 | 58.4 | 84.5 | 44.4 | 74.4 | 33.6 | 63.7 | 26.4 | 35.9 | 55.0 | 70.5 | 104.2 | 105.9 |
| SCST | 78.1 | 93.7 | 61.9 | 86.0 | 47.0 | 75.9 | 35.2 | 64.5 | 27.0 | 35.5 | 56.3 | 70.7 | 114.7 | 116.7 |
| LSTM-A | 78.7 | 93.7 | 62.7 | 86.7 | 47.6 | 76.5 | 35.6 | 65.2 | 27.0 | 35.4 | 56.4 | 70.5 | 116.0 | 118.0 |
| Up-Down | 80.2 | 95.2 | 64.1 | 88.8 | 49.1 | 79.4 | 36.9 | 68.5 | 27.6 | 36.7 | 57.1 | 72.4 | 117.9 | 120.5 |
| CAVP | 80.1 | 94.9 | 64.7 | 88.8 | 50.0 | 79.7 | 37.9 | 69.0 | 28.1 | 37.0 | 58.2 | 73.1 | 121.6 | 123.8 |
| RFNet | 80.4 | 95.0 | 64.9 | 89.3 | 50.1 | 80.1 | 38.0 | 69.2 | 28.2 | 37.2 | 58.2 | 73.1 | 122.9 | 125.1 |
| GLIED | 80.1 | 94.6 | 64.7 | 88.9 | 50.2 | 80.4 | 38.5 | 70.3 | 28.6 | 37.9 | 58.3 | 73.8 | 123.3 | 125.6 |
| Methods | B-1 | B-4 | M | R | C | S | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| All | Objects | Attributes | Relations | Color | Count | Size | ||||||
| Base | 77.0 | 36.3 | 27.6 | 56.6 | 113.5 | 20.5 | 37.3 | 10.0 | 5.2 | 11.6 | 5.8 | 4.0 |
| Base w/ Global Vis. Dist. | 77.3 | 36.5 | 27.8 | 56.9 | 115.3 | 20.6 | 36.9 | 9.8 | 5.7 | 9.3 | 9.2 | 3.9 |
| Base w/ Global Attr. Dist. | 77.1 | 36.9 | 27.9 | 56.8 | 114.7 | 20.8 | 36.6 | 10.4 | 5.5 | 12.5 | 8.5 | 4.2 |
| Base w/ Global Dist. | 77.4 | 36.8 | 27.9 | 57.2 | 116.4 | 20.9 | 37.3 | 10.2 | 5.9 | 13.1 | 8.7 | 3.9 |
| Base w/ Local Dist. | 76.2 | 36.0 | 27.7 | 56.6 | 113.7 | 20.4 | 37.2 | 9.6 | 5.7 | 11.6 | 5.2 | 3.2 |
| GLIED | 77.8 | 37.9 | 28.3 | 57.6 | 118.2 | 21.2 | 38.1 | 10.6 | 6.2 | 11.6 | 9.4 | 4.4 |
Incremental Study
We conduct a series of studies to investigate the contribution of each component in the proposed approach and the results are shown in Table 4. These experiments use cross-entropy loss. We also list the results of SPICE sub-categories to help analyze the quality and the difference of the captions.
Effect of global visual distilling. An overall improvement is achieved when representing the visual features as region groupings. As we expected, the refined visual features are good at associating related parts in the image, which is demonstrated by the increased scores in Relations and Count. However, as much more information is provided, the decoder may get confused about the exact object or the attribute that is to be described, leading to impaired accuracy.
Effect of global attribute distilling. Global attribute distilling promotes the base model in almost all sub-categories except for Object. Compared with the self-clustered visual regions, the attribute collocations have the input word as pivot to extract constrained collocations, which are learned across examples and provide comprehensive context for details.
Effect of global distilling. Combining the global visual distilling and the global attribute distilling gives rise to a series of multimodal representations, with correlated features being aggregated in each modality. As a result, the advantages of the region groupings and attribute collocations are united to produce a balanced improvement.
Effect of local distilling. As we can see, incorporating local distilling directly on the base model, which is essentially a two-layer version of the base model, leads to almost the same performance, if not worse. Despite that, GLIED, which implements both global distilling and local distilling, demonstrates overall improvements. It suggests that the introduction of global combined source information induces new learning dynamics and local distilling functions differently in the new scenario. With the abundant and enriched information extracted by the global distilling method, the local distilling method helps the extraction of original and precise information, turning the cross-modal source information into further advantages in deep and semantic image understanding.
5 Conclusions
In this work, we present a simple yet effective approach exploring and distilling the cross-modal source information. The global distilling methods learn to capture salient region groupings and attribute collocations and explore a spatial and relational coarse-grained representation of the image, which serves as powerful basis for image descriptions. The local distilling method in contrast makes the decoder revisit the fine-grained source representation so that related and specific details can be retrieved. Experiments on the COCO dataset validate our proposal, which achieves 129.3 CIDEr score with fewer parameters and faster computation.
Acknowledgments
This work was supported in part by National Natural Science Foundation of China (No. 61673028) and the Shenzhen Fundamental Research Project (No. ZDSYS201802051831427). We thank all the anonymous reviewers for their constructive comments and suggestions.
@inproceedings{ijcai2019p708,
  title     = {Exploring and Distilling Cross-Modal Information for Image Captioning},
  author    = {Liu, Fenglin and Ren, Xuancheng and Liu, Yuanxin and Lei, Kai and Sun, Xu},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {5095--5101},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/708},
  url       = {https://doi.org/10.24963/ijcai.2019/708},
}
TY - CPAPER TI - Exploring and Distilling Cross-Modal Information for Image Captioning AU - Liu, Fenglin AU - Ren, Xuancheng AU - Liu, Yuanxin AU - Lei, Kai AU - Sun, Xu T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 5095 EP - 5101 DO - 10.24963/ijcai.2019/708 UR - https://doi.org/10.24963/ijcai.2019/708 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





