
Causal Embeddings for Recommendation: An Extended Abstract
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Best Sister Conferences. Pages 6236-6240.
https://doi.org/10.24963/ijcai.2019/870
Keywords
- Machine Learning: Transfer, Adaptation, Multi-task Learning
- Machine Learning: Learning Preferences or Rankings
Abstract
Recommendations are commonly used to modify
user’s natural behavior, for example, increasing
product sales or the time spent on a website. This
results in a gap between the ultimate business ob-
jective and the classical setup where recommenda-
tions are optimized to be coherent with past user be-
havior. To bridge this gap, we propose a new learn-
ing setup for recommendation that optimizes for the
Incremental Treatment Effect (ITE) of the policy.
We show this is equivalent to learning to predict
recommendation outcomes under a fully random
recommendation policy and propose a new domain
adaptation algorithm that learns from logged data
containing outcomes from a biased recommenda-
tion policy and predicts recommendation outcomes
according to random exposure. We compare our
method against state-of-the-art factorization meth-
ods, in addition to new approaches of causal rec-
ommendation and show significant improvements.
- [Bonner and Vasile, 2018] Stephen Bonner and Flavian Vasile. Causal embeddings for recommendation. In Pro- ceedings of the 12th ACM Conference on Recommender Systems, pages 104-112. ACM, 2018.
- [Grbovic et al., 2015] Mihajlo Grbovic, Vladan Radosavlje- vic, Nemanja Djuric, Narayan Bhamidipati, Jaikit Savla, Varun Bhagwan, and Doug Sharp. E-commerce in your inbox: Product recommendations at scale. In Proceedings of the 21th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, KDD '15, pages 1809-1818, New York, NY, USA, 2015. ACM.
- [Hidasi et al., 2015] Balázs Hidasi, Alexandros Karat- zoglou, Linas Baltrunas, and Domonkos Tikk. Session- based recommendations with recurrent neural networks. arXiv preprint arXiv:1511.06939, 2015.
- [Hidasi et al., 2016] Balázs Hidasi, Massimo Quadrana, Alexandros Karatzoglou, and Domonkos Tikk. Paral- lel recurrent neural network architectures for feature-rich session-based recommendations. In Proceedings of the 10th ACM Conference on Recommender Systems, pages 241-248. ACM, 2016.
- [Joachims et al., 2018] Thorsten Joachims, Artem Grotov, Adith Swaminathan, and Maarten de Rijke. Deep learn- ing with logged bandit feedback. Proceedings of the Inter- national Conference on Learning Representations (ICLR), 2018.
- [Johansson et al., 2016] Fredrik D Johansson, Uri Shalit, and David Sontag. Learning representations for counterfactual inference. arXiv preprint arXiv:1605.03661, 2016.
- [Liang et al., 2016] Dawen Liang, Laurent Charlin, and David M Blei. Causal inference for recommendation. 2016. [
- [Pennington et al., 2014] Jeffrey Pennington, Richard Socher, and Christopher Manning. Glove: Global Vectors for Word Representation. In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 1532-1543, Doha, Qatar, 2014. Association for Computational Linguistics.
- [Rendle et al., 2009] Steffen Rendle, Christoph Freuden- thaler, Zeno Gantner, and Lars Schmidt-Thieme. Bpr: Bayesian personalized ranking from implicit feedback. In Proceedings of the twenty-fifth conference on uncertainty in artificial intelligence, pages 452-461. AUAI Press, 2009.
- [Rendle, 2010] Steffen Rendle. Factorization machines. In Data Mining (ICDM), 2010 IEEE 10th International Con- ference on, pages 995-1000. IEEE, 2010.
- [Rosenfeld et al., 2016] Nir Rosenfeld, Yishay Mansour, and Elad Yom-Tov. Predicting counterfactuals from large his- torical data and small randomized trials. arXiv preprint arXiv:1610.07667, 2016.
- [Rubin, 1974] Donald B Rubin. Estimating causal effects of treatments in randomized and nonrandomized studies. Journal of educational Psychology, 66(5):688, 1974.
- [Schnabel et al., 2016] Tobias Schnabel, Adith Swami- nathan, Ashudeep Singh, Navin Chandak, and Thorsten Joachims. Recommendations as treatments: Debiasing learning and evaluation. In Proceedings of the 33rd International Conference on International Conference on Machine Learning -Volume 48, ICML'16, pages 1670-1679, 2016.
- [Shalit et al., 2017] Uri Shalit, Fredrik D Johansson, and David Sontag. Estimating individual treatment effect: generalization bounds and algorithms. In Proceedings of the 34th International Conference on Machine Learning- Volume 70, pages 3076-3085. JMLR. org, 2017.
- [Swaminathan and Joachims, 2015] Adith Swaminathan and Thorsten Joachims. Batch learning from logged bandit feedback through counterfactual risk minimization. Jour- nal of Machine Learning Research, 16:1731-1755, 2015.
- [Vasile et al., 2016] Flavian Vasile, Elena Smirnova, and Alexis Conneau. Meta-prod2vec: Product embeddings us- ing side-information for recommendation. In Proceedings of the 10th ACM Conference on Recommender Systems, pages 225-232. ACM, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In recent years, online commerce has outpaced the growth of traditional commerce. As such, research work on recommender systems has also grown significantly, with recent Deep Learning (DL) approaches achieving state-of-the-art results. Broadly, these DL approaches frame the recommendation task as either:
- A distance learning problem between pairs of products or pairs of users and products, measured with Mean Squared Error (MSE) and Area Under the Curve (AUC), like in the work by [Grbovic et al., 2015; Vasile et al., 2016; Pennington et al., 2014].
- A next item prediction problem that models user behavior and predicts the next action, measured with ranking metrics such as Precision@K and Normalized Discounted Cumulative Gain (NDCG), as presented in [Hidasi et al., 2015; Hidasi et al., 2016].
∗Work first published as: Bonner, S., Vasile, F. (2018). Causal embeddings for recommendation. In Proceedings of the 12th ACM Conference on Recommender Systems (pp. 104-112). ACM.
However, we argue that both approaches fail to model the inherent interventionist nature of recommendation, which should not only attempt to model the organic user behavior, but to actually attempt to optimally influence it according to a preset objective.
Using a causal vocabulary, we are interested in finding the treatment recommendation policy that maximizes the reward obtained from each user with respect to the control recommendation policy. This objective is traditionally denoted as the Individual Treatment Effect (ITE) [Rubin, 1974].
In our work, we introduce a modification to the classical matrix factorization approach which leverages both a large biased sample of biased recommendation outcomes and a small sample of randomized recommendation outcomes in order to create user and products representations. We show that using our method, we improve the ITE prediction performance over traditional matrix factorization and causal inference approaches.
1.1 Causal Vocabulary
Below we briefly introduce the causal vocabulary and notation that we will be using throughout the paper.
The Causal Inference Objective
In the classical setup, we want to determine the causal effect of one single action which constitutes the treatment versus the control case where no action or a placebo action is undertaken (do vs. not do). In the stochastic setup, we want to determine the causal effect of a stochastic treatment policy versus the baseline control policy. In this case, both treatment and control are distributions over all possible actions. We retrieve the classical setup as a special case.
Recommendation Policy
We assume a stochastic policy πx that associates to each user ui and product pj a probability for the user ui to be exposed to the recommendation of product pj:
For simplicity we assume showing no products is also a valid intervention in P.
Policy Rewards
Reward rij is distributed according to an unknown conditional distribution r depending on ui and pj :
The reward Rπx associated with a policy πx is equal to the sum of the rewards collected across all incoming users by using the associated personalized product exposure probability:
Individual Treatment Effect
The Individual Treatment Effect (ITE) value of a policy πx for a given user i and a product j is defined as the difference between its reward and the control policy reward:
We are interested in finding the policy π∗ with the highest sum of ITEs:
Optimal ITE Policy
It is easy to show that, starting from any control policy πc, the best incremental policy π∗ is the policy that shows deterministically to each user ui the product p∗i with the highest personalized reward r∗ i :
IPS Solution For π∗
In order to find the optimal policy π∗ we need to find for each user ui the product with the highest personalized reward r∗ i .
In practice we do not observe directly rij, but yij ∼ rij πc(pj |ui).
The current approach to estimate rij constitutes in using Inverse Propensity Scoring (IPS)-based methods to predict the unobserved reward rij :
This assumes we have incorporated randomization in the current policy πc. Even with the existence of randomization, the main shortcoming of IPS-based estimators is that they do not handle well big shifts in exposure probability between treatment and control policies (products with low probability under the logging policy πc will tend to have higher predicted rewards).
Addressing the Variance Issues of IPS
Ideally, in order to maintain minimum variance, we should collect data using fully randomized recommendations, e.g. when: πc = πrand. However, this means zero recommendation performance and therefore cannot be a solution in practice.
Our question: Could we learn from πc a predictor for performance under πrand and use it to compute the optimal product recommendations p∗i ?
2 Our Approach: Causal Embeddings (CausE)
We are interested in building a good predictor for recommendation outcomes under random exposure for all the userproduct pairs, which we denote as ˆ yrand ij . We make the assumption that we have access to a large sample Sc from the logging policy πc and a small sample St from the randomized treatment policy πt=rand (e.g. the logging policy πc uses egreedy randomization).
To this end, we propose a multi-task objective that jointly factorizes the matrix of observations yc ij ∈ Sc and the matrix of observations yt ij ∈ St. Our approach is inspired by the work in [Rosenfeld et al., 2016] and shares similarities with other domain-adaptation based models for counterfactual inference such as the work in [Johansson et al., 2016; Shalit et al., 2017].
2.1 Predicting Rewards ViaMatrix Factorization
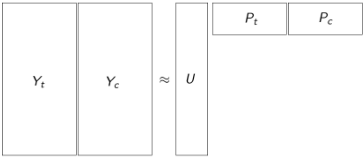
By using a matrix factorization model, we assume that both the expected factual control and treatment rewards can be approximated as linear predictors over the shared user representations ui, as shown in Fig. 1.
As a result, we can approximate the ITE of a user-product pair i, j as the difference between the two, see eq.1 below:
Proposed Joint Optimization Solution
The joint optimization objective contains two terms, one measuring the performance of the solution on the treatment sample and one on the control sample. The novel part of the objective comes from the additional constraint on the distance between the treatment and control vectors for the same action/item, that can be directly linked to the ITE effect of the item.
Sub-objective #1: treatment loss term Lt. We define the first part of our joint prediction objective as the supervised predictor for yt ij , trained on the limited sample St, as shown in the eq. 2 below:
where:
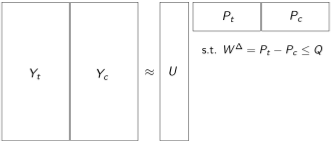
- Pt is the parameter matrix of treatment product representations.
- U is the fixed matrix of the user representations.
- Yt is the observed rewards matrix.
- L is an arbitrary loss function.
- Ω(.) is a regularization term over the model parameters.
Linking the control and treatment effects. Additionally, we can use the translation factor in order to be able to use the model built from the treatment data St to predict outcomes from the control distribution Sc:
Sub-objective #2: control loss term Lc. Now we want to leverage our ample control data Sc and we can use our treatment product representations through a translation:
which can be written equivalently as:
where we regularize the control Pc against the treatment embeddings Pt (W ∆ = Pt - Pc). As shown in the eq. 4 below, we can see that IPS is a function of W ∆. Therefore, by regularizing W ∆ we are effectively putting a constraint on the magnitude of the IPS term.
Overall Joint Objective
By putting the two tasks together (Lt and Lc) and regrouping the loss functions and the regularizer terms, we have that:
where L(.) is the reconstruction loss function for the concatenation matrix of Pt and Pc, Ωdisc(.) is a regularization function that weights the discrepancy between the treatment and control product representations and Ωembed(.) is a regularization function that weights the representation vectors.
Generalization to User Shift
Our objective function can be altered to allow for the user representations to change, we obtain the equation below:
Putting the loss functions associated with the user and product dimension together (Lprod CausE , Luser CausE ), we reach the final loss function for our method:
3 Experimental Results
3.1 Experimental Setup
The task is predicting the outcomes yrand ij under treatment policy πrand, where all of the methods have available at training time a large sample of observed recommendations outcomes from πc and a small sample from πrand. Essentially this is a classical conversion-rate prediction problem so we measure Mean-Squared Error (MSE) and Negative LogLikelihood (NLL). We report lift over average conversation rate from the test dataset:
3.2 Baselines
We compare our method with the following Matrix Factorization baselines:
Algorithm 1: CausE - Causal embeddings for recommendations.
Input : Mini-batches of Sc = {(ui, pcj , δc ij )}Mc i=1 and St = {(ui, ptj , δt ij )}Mt i=1 , regularization parameters λembed and λdist, learning rate η Output: Pt, Pc, Ut, Uc - Product and User Control and Treatment Matrices 1 Random initialization of Pt, Pc,Ut,Uc ; 2 while not converged do 3 read batch of training samples; 4 for each product pj in Pc, Pt do 5 Update product vector: pj ← pj - η∇Lprod CausE (p, λembed, λdist)) 6 end 7 for each user ui in Uc, Ut do 8 Update user vector: ui ← ui - η∇Luser CausE (u, λembed, λdist)) 9 end 10 end 11 return Pt, Pc,Ut,Uc| Method | MovieLens10M (SKEW) | Netflix (SKEW) | ||||
|---|---|---|---|---|---|---|
| MSE lift | NLL lift | AUC | MSE lift | NLL lift | AUC | |
| BPR-no | - | - | 0.693(±0.001) | - | - | 0.665(±0.001) |
| BPR-blend | - | - | 0.711(±0.001) | - | - | 0.671(±0.001) |
| SP2V-no | +3.94%(±0.04) | +4.50%(±0.04) | 0.757(±0.001) | +10.82%(±0.02) | +10.19%(±0.01) | 0.752(±0.002) |
| SP2V-blend | +4.37%(±0.04) | +5.01%(±0.05) | 0.768(±0.001) | +12.82%(±0.02) | +11.54%(±0.02) | 0.764(±0.003) |
| SP2V-test | +2.45%(±0.02) | +3.56%(±0.02) | 0.741(±0.001) | +05.67%(±0.02) | +06.23%(±0.02) | 0.739(±0.004) |
| WSP2V-no | +5.66%(±0.03) | +7.44%(±0.03) | 0.786(±0.001) | +13.52%(±0.01) | +13.11%(±0.01) | 0.779(±0.001) |
| WSP2V-blend | +6.14%(±0.03) | +8.05%(±0.03) | 0.792(±0.001) | +14.72%(±0.02) | +14.23%(±0.02) | 0.782(±0.002) |
| BN-blend | - | - | 0.794(±0.001) | - | - | 0.785(±0.001) |
| CausE-avg | +12.67%(±0.09) | +15.15%(±0.08) | 0.804(±0.001) | +15.62%(±0.02) | +15.21%(±0.02) | 0.799(±0.002) |
| CausE-prod-T | +07.46%(±0.08) | +10.44%(±0.09) | 0.779(±0.001) | +13.97%(±0.02) | +13.52%(±0.02) | 0.789(±0.003) |
| CausE-prod-C | +15.48%(±0.09) | +19.12%(±0.08) | 0.814(±0.001) | +17.82%(±0.02) | +17.19%(±0.02) | 0.821(±0.003) |
- Bayesian Personalized Ranking (BPR) To compare our approach against a ranking based method, we use Bayesian Personalized Ranking (BPR) for matrix factorization on implicit feedback data [Rendle et al., 2009].
- Supervised-Prod2Vec (SP2V): As a second factorization baseline we will use a Factorization Machine-like method [Rendle, 2010] that approximates yij as a sigmoid over a linear transform of the inner-product between the user and product representations.
And these Causal Inference baselines:
- Weighted-SupervisedP2V (WSP2V): We employ the SP2V algorithm on propensity-weighted data, this method is similar to the Propensity-Scored Matrix Factorization (PMF) from [Schnabel et al., 2016] but with cross-entropy reconstruction loss instead of MSE/MAE.
- BanditNet (BN): To utilize BanditNet [Joachims et al., 2018] as a baseline, we use SP2V as our target policy πw. For the existing policy πc, we model the behavior of the recommendation system as a popularity-based solution, described by the marginal probability of each product in the training data.
3.3 Experimental Datasets
We use the Netflix and MovieLens10M explicit rating datasets (1-5). In order to validate our method, we preprocess them as follows: We binarize the ratings yij by setting 5-star ratings to 1 (click) and everything else to zero (view only) and generate a skewed dataset (SKEW) with 70/10/20 train/validation/test event split that simulates rewards collected from uniform exposure πrand t , following a similar protocol with the one presented in previous counterfactual estimation work such as in [Liang et al., 2016; Swaminathan and Joachims, 2015] and described in detail in the long version of our paper [Bonner and Vasile, 2018].
3.4 Experimental Setup: Exploration Sample St
We define 5 setups for incorporating the exploration data:
- No adaptation (no) - trained only on Sc.
- Blended adaptation (blend) - trained on the blend of the Sc and St samples.
- Test adaptation (test) - trained only on the St samples.
- Product adaptation (prod) - separate treatment embedding for each product based on the St sample.
- Average adaptation (avg) - average treatment product by pooling all the St sample into a single vector.
3.5 Results
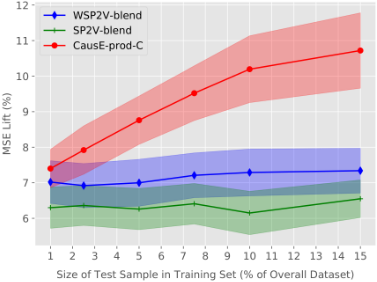
Table 1 displays the results for running all the approaches on the datasets. Our proposed CausE method significantly outperforms all baselines across both datasets, demonstrating that it has a better capacity to leverage the small test distribution sample St. We observe that, out of the three CausE variants, CausE-prod-C, the variant that is using the regularized control matrix, clearly out-performs the others. Further, figure 3 highlights how CausE is able to make better use of increasing quantities of test distribution present in the training data compared with the baselines.
@inproceedings{ijcai2019p870,
  title     = {Causal Embeddings for Recommendation: An Extended Abstract},
  author    = {Vasile, Flavian and Bonner, Stephen},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {6236--6240},
  year      = {2019},
  month     = {8},
  note      = {Best Sister Conferences},
  doi       = {10.24963/ijcai.2019/870},
  url       = {https://doi.org/10.24963/ijcai.2019/870},
}
TY - CPAPER TI - Causal Embeddings for Recommendation: An Extended Abstract AU - Vasile, Flavian AU - Bonner, Stephen T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 6236 EP - 6240 DO - 10.24963/ijcai.2019/870 UR - https://doi.org/10.24963/ijcai.2019/870 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





