
Zero-shot High-fidelity and Pose-controllable Character Animation
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence. Main Track. Pages 1788-1797.
https://doi.org/10.24963/ijcai.2024/198
Keywords
- Machine Learning: ML: Multi-modal learning
- Computer Vision: CV: Image and video synthesis and generation
Abstract
Image-to-video (I2V) generation aims to create a video sequence from a single image, which requires high temporal coherence and visual fidelity. However, existing approaches suffer from inconsistency of character appearances and poor preservation of fine details. Moreover, they require a large amount of video data for training, which can be computationally demanding. To address these limitations, we propose PoseAnimate, a novel zero-shot I2V framework for character animation. PoseAnimate contains three key components: 1) a Pose-Aware Control Module (PACM) that incorporates diverse pose signals into text embeddings, to preserve character-independent content and maintain precise alignment of actions. 2) a Dual Consistency Attention Module (DCAM) that enhances temporal consistency and retains character identity and intricate background details. 3) a Mask-Guided Decoupling Module (MGDM) that refines distinct feature perception abilities, improving animation fidelity by decoupling the character and background. We also propose a Pose Alignment Transition Algorithm (PATA) to ensure smooth action transition. Extensive experiment results demonstrate that our approach outperforms the state-of-the-art training-based methods in terms of character consistency and detail fidelity. Moreover, it maintains a high level of temporal coherence throughout the generated animations.
- [Balaji et al., 2019] Yogesh Balaji, Martin Renqiang Min, Bing Bai, Rama Chellappa, and Hans Peter Graf. Con- ditional gan with discriminative filter generation for text- to-video synthesis. In IJCAI, volume 1, page 2, 2019.
- [Blattmann et al., 2023a] Andreas Blattmann, Tim Dock- horn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, et al. Stable video diffusion: Scaling latent video diffusion models to large datasets. arXiv preprint arXiv:2311.15127, 2023.
- [Blattmann et al., 2023b] Andreas Blattmann, Robin Rom- bach, Huan Ling, Tim Dockhorn, Seung Wook Kim, Sanja Fidler, and Karsten Kreis. Align your latents: High-resolution video synthesis with latent diffusion mod- els. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 22563- 22575, 2023.
- [Chan et al., 2019] Caroline Chan, Shiry Ginosar, Tinghui Zhou, and Alexei A Efros. Everybody dance now. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 5933-5942, 2019.
- [Chen et al., 2023] Haoxin Chen, Menghan Xia, Yingqing He, Yong Zhang, Xiaodong Cun, Shaoshu Yang, Jinbo Xing, Yaofang Liu, Qifeng Chen, Xintao Wang, et al. Videocrafter1: Open diffusion models for high-quality video generation. arXiv preprint arXiv:2310.19512, 2023.
- [Dhariwal and Nichol, 2021] Prafulla Dhariwal and Alexan- der Nichol. Diffusion models beat gans on image synthe- sis. Advances in neural information processing systems, 34:8780-8794, 2021.
- [Esser et al., 2023] Patrick Esser, Johnathan Chiu, Parmida Atighehchian, Jonathan Granskog, and Anastasis Ger- manidis. Structure and content-guided video synthesis with diffusion models. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 7346-7356, 2023.
- [Ge et al., 2023] Songwei Ge, Seungjun Nah, Guilin Liu, Tyler Poon, Andrew Tao, Bryan Catanzaro, David Jacobs, Jia-Bin Huang, Ming-Yu Liu, and Yogesh Balaji. Pre- serve your own correlation: A noise prior for video dif- fusion models. In Proceedings of the IEEE/CVF Inter- national Conference on Computer Vision, pages 22930- 22941, 2023.
- [Goodfellow et al., 2014] Ian Goodfellow, Jean Pouget- Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Gen- erative adversarial nets. Advances in neural information processing systems, 27, 2014.
- [Gu et al., 2023] Jiaxi Gu, Shicong Wang, Haoyu Zhao, Tianyi Lu, Xing Zhang, Zuxuan Wu, Songcen Xu, Wei Zhang, Yu-Gang Jiang, and Hang Xu. Reuse and diffuse: Iterative denoising for text-to-video generation. arXiv preprint arXiv:2309.03549, 2023.
- [Güler et al., 2018] Rıza Alp Güler, Natalia Neverova, and Iasonas Kokkinos. Densepose: Dense human pose estima- tion in the wild. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 7297- 7306, 2018.
- [He et al., 2022] Yingqing He, Tianyu Yang, Yong Zhang, Ying Shan, and Qifeng Chen. Latent video diffusion models for high-fidelity video generation with arbitrary lengths. arXiv preprint arXiv:2211.13221, 2022.
- [Hertz et al., 2022] Amir Hertz, Ron Mokady, Jay Tenen- baum, Kfir Aberman, Yael Pritch, and Daniel Cohen-or. Prompt-to-prompt image editing with cross-attention con- trol. In The Eleventh International Conference on Learn- ing Representations, 2022.
- [Heusel et al., 2017] Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, and Sepp Hochre- iter. Gans trained by a two time-scale update rule converge to a local nash equilibrium. Advances in neural information processing systems, 30, 2017.
- [Ho and Salimans, 2022] Jonathan Ho and Tim Salimans. Classifier-free diffusion guidance. arXiv preprint arXiv:2207.12598, 2022.
- [Ho et al., 2020] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. Advances in neural information processing systems, 33:6840-6851, 2020.
- [Ho et al., 2022] Jonathan Ho, William Chan, Chitwan Saharia, Jay Whang, Ruiqi Gao, Alexey Gritsenko, Diederik P Kingma, Ben Poole, Mohammad Norouzi, David J Fleet, et al. Imagen video: High definition video generation with diffusion models. arXiv preprint arXiv:2210.02303, 2022.
- [Hu et al., 2023] Li Hu, Xin Gao, Peng Zhang, Ke Sun, Bang Zhang, and Liefeng Bo. Animate anyone: Consistent and controllable image-to-video synthesis for character anima- tion. arXiv preprint arXiv:2311.17117, 2023.
- [Jafarian and Park, 2021] Yasamin Jafarian and Hyun Soo Park. Learning high fidelity depths of dressed humans by watching social media dance videos. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pat- tern Recognition, pages 12753-12762, 2021.
- [Karras et al., 2019] Tero Karras, Samuli Laine, and Timo Aila. A style-based generator architecture for generative adversarial networks. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 4401-4410, 2019.
- [Karras et al., 2023] Johanna Karras, Aleksander Holyn- ski, Ting-Chun Wang, and Ira Kemelmacher-Shlizerman. Dreampose: Fashion image-to-video synthesis via stable diffusion. arXiv preprint arXiv:2304.06025, 2023.
- [Liu et al., 2023a] Peng Liu, Fanyi Wang, Jingwen Su, Yan- hao Zhang, and Guojun Qi. Lightweight high-resolution subject matting in the real world. arXiv preprint arXiv:2312.07100, 2023.
- [Liu et al., 2023b] Yaofang Liu, Xiaodong Cun, Xuebo Liu, Xintao Wang, Yong Zhang, Haoxin Chen, Yang Liu, Tiey- ong Zeng, Raymond Chan, and Ying Shan. Evalcrafter: Benchmarking and evaluating large video generation mod- els. arXiv preprint arXiv:2310.11440, 2023.
- [Ma et al., 2023] Yue Ma, Yingqing He, Xiaodong Cun, Xintao Wang, Ying Shan, Xiu Li, and Qifeng Chen. Fol- low your pose: Pose-guided text-to-video generation using pose-free videos. arXiv preprint arXiv:2304.01186, 2023.
- [Mokady et al., 2023] Ron Mokady, Amir Hertz, Kfir Aber- man, Yael Pritch, and Daniel Cohen-Or. Null-text inver- sion for editing real images using guided diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 6038-6047, 2023.
- [Ni et al., 2022] Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, and Haibin Ling. Expanding language-image pre- trained models for general video recognition. In European Conference on Computer Vision, pages 1-18. Springer, 2022.
- [Nikankin et al., 2022] Yaniv Nikankin, Niv Haim, and Michal Irani. Sinfusion: Training diffusion models on a single image or video. arXiv preprint arXiv:2211.11743, 2022.
- [Radford et al., 2021] Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agar- wal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, et al. Learning transferable visual models from nat- ural language supervision. In International Conference on Machine Learning, pages 8748-8763. PMLR, 2021.
- [Ren et al., 2020] Yurui Ren, Ge Li, Shan Liu, and Thomas H Li. Deep spatial transformation for pose-guided person image generation and animation. IEEE Transac- tions on Image Processing, 29:8622-8635, 2020.
- [Rombach et al., 2022] Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, and Björn Ommer. High-resolution image synthesis with latent diffusion models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 10684-10695, 2022.
- [Ronneberger et al., 2015] Olaf Ronneberger, Philipp Fis- cher, and Thomas Brox. U-net: Convolutional networks for biomedical image segmentation. In Medical Image Computing and Computer-Assisted Intervention-MICCAI 2015: 18th International Conference, Munich, Germany, October 5-9, 2015, Proceedings, Part III 18, pages 234- 241. Springer, 2015.
- [Siarohin et al., 2019a] Aliaksandr Siarohin, Stéphane Lath- uilière, Sergey Tulyakov, Elisa Ricci, and Nicu Sebe. An- imating arbitrary objects via deep motion transfer. In Pro- ceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 2377-2386, 2019.
- [Siarohin et al., 2019b] Aliaksandr Siarohin, Stéphane Lath- uilière, Sergey Tulyakov, Elisa Ricci, and Nicu Sebe. First order motion model for image animation. Advances in neural information processing systems, 32, 2019.
- [Siarohin et al., 2021] Aliaksandr Siarohin, Oliver J Wood- ford, Jian Ren, Menglei Chai, and Sergey Tulyakov. Mo- tion representations for articulated animation. In Proceed- ings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 13653-13662, 2021.
- [Song et al., 2020] Jiaming Song, Chenlin Meng, and Ste- fano Ermon. Denoising diffusion implicit models. arXiv preprint arXiv:2010.02502, 2020.
- [Teed and Deng, 2020] Zachary Teed and Jia Deng. Raft: Recurrent all-pairs field transforms for optical flow. In Computer Vision-ECCV 2020: 16th European Confer- ence, Glasgow, UK, August 23-28, 2020, Proceedings, Part II 16, pages 402-419. Springer, 2020.
- [Unterthiner et al., 2018] Thomas Unterthiner, Sjoerd Van Steenkiste, Karol Kurach, Raphael Marinier, Marcin Michalski, and Sylvain Gelly. Towards accurate genera- tive models of video: A new metric & challenges. arXiv preprint arXiv:1812.01717, 2018.
- [Wang et al., 2022] Yaohui Wang, Di Yang, Francois Bre- mond, and Antitza Dantcheva. Latent image animator: Learning to animate images via latent space navigation. arXiv preprint arXiv:2203.09043, 2022.
- [Wang et al., 2023a] Tan Wang, Linjie Li, Kevin Lin, Yuan- hao Zhai, Chung-Ching Lin, Zhengyuan Yang, Hanwang Zhang, Zicheng Liu, and Lijuan Wang. Disco: Disentan- gled control for realistic human dance generation. arXiv preprint arXiv:2307.00040, 2023.
- [Wang et al., 2023b] Xiang Wang, Hangjie Yuan, Shiwei Zhang, Dayou Chen, Jiuniu Wang, Yingya Zhang, Yu- jun Shen, Deli Zhao, and Jingren Zhou. Videocomposer: Compositional video synthesis with motion controllability. arXiv preprint arXiv:2306.02018, 2023.
- [Wu et al., 2023] Jay Zhangjie Wu, Yixiao Ge, Xintao Wang, Stan Weixian Lei, Yuchao Gu, Yufei Shi, Wynne Hsu, Ying Shan, Xiaohu Qie, and Mike Zheng Shou. Tune-a- video: One-shot tuning of image diffusion models for text- to-video generation. In Proceedings of the IEEE/CVF In- ternational Conference on Computer Vision, pages 7623- 7633, 2023.
- [Xing et al., 2023a] Zhen Xing, Qi Dai, Han Hu, Zuxuan Wu, and Yu-Gang Jiang. Simda: Simple diffusion adapter for efficient video generation. arXiv preprint arXiv:2308.09710, 2023.
- [Xing et al., 2023b] Zhen Xing, Qi Dai, Zihao Zhang, Hui Zhang, Han Hu, Zuxuan Wu, and Yu-Gang Jiang. Vid- iff: Translating videos via multi-modal instructions with diffusion models. arXiv preprint arXiv:2311.18837, 2023.
- [Xing et al., 2023c] Zhen Xing, Qijun Feng, Haoran Chen, Qi Dai, Han Hu, Hang Xu, Zuxuan Wu, and Yu-Gang Jiang. A survey on video diffusion models. arXiv preprint arXiv:2310.10647, 2023.
- [Xu et al., 2023] Zhongcong Xu, Jianfeng Zhang, Jun Hao Liew, Hanshu Yan, Jia-Wei Liu, Chenxu Zhang, Jiashi Feng, and Mike Zheng Shou. Magicanimate: Temporally consistent human image animation using diffusion model. arXiv preprint arXiv:2311.16498, 2023.
- [Yang et al., 2023] Ruihan Yang, Prakhar Srivastava, and Stephan Mandt. Diffusion probabilistic modeling for video generation. Entropy, 25(10):1469, 2023.
- [Ye et al., 2023] Hu Ye, Jun Zhang, Sibo Liu, Xiao Han, and Wei Yang. Ip-adapter: Text compatible image prompt adapter for text-to-image diffusion models. arXiv preprint arXiv:2308.06721, 2023.
- [Zhang et al., 2018] Richard Zhang, Phillip Isola, Alexei A Efros, Eli Shechtman, and Oliver Wang. The unreasonable effectiveness of deep features as a perceptual metric. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 586-595, 2018.
- [Zhang et al., 2022] Pengze Zhang, Lingxiao Yang, Jian- Huang Lai, and Xiaohua Xie. Exploring dual-task correla- tion for pose guided person image generation. In Proceed- ings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 7713-7722, 2022.
- [Zhang et al., 2023] Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. Adding conditional control to text-to-image dif- fusion models. In Proceedings of the IEEE/CVF Interna- tional Conference on Computer Vision, pages 3836-3847, 2023.
- [Zhao and Zhang, 2022] Jian Zhao and Hui Zhang. Thin- plate spline motion model for image animation. In Pro- ceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 3657-3666, 2022.
- [Zhu et al., 2017] Jun-Yan Zhu, Taesung Park, Phillip Isola, and Alexei A Efros. Unpaired image-to-image translation using cycle-consistent adversarial networks. In Proceed- ings of the IEEE International Conference on Computer Vision, pages 2223-2232, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Image animation [Siarohin et al., 2019b; Siarohin et al., 2019a; Siarohin et al., 2021; Wang et al., 2022; Zhao and Zhang, 2022] is a task that brings static images to life by seamlessly transforming them into dynamic and realistic videos. It involves the transformation of still images into a sequence of frames that exhibit smooth and coherent motions. In this task, character animation has gained significant attention due to its valuable applications in various scenarios, such as television production, game development, online retail and artistic creation, etc. However, minor motion variations hardly meet with the requirements. The goal of character animation is to make the character in the image perform target pose sequences, while maintaining identity consistency and visual coherence. In early works, most of character animation was driven by traditional animation techniques, which involves meticulous frame-by-frame drawing or manipulation. In the subsequent era of deep learning, the advent of generative models [Goodfellow et al., 2014; Zhu et al., 2017; Karras et al., 2019] drove the shift towards data-driven and automated approaches [Ren et al., 2020; Chan et al., 2019; Zhang et al., 2022]. However, there are still ongoing challenges in achieving highly realistic and visually consistent animations, especially when dealing with complex motions, fine-grained details, and long-term temporal coherence.
∗Corresponding Authors.
Recently, diffusion models [Ho et al., 2020] have demonstrated groundbreaking generative capabilities. Driven by the open source text-to-image diffusion model Stable Diffusion [Rombach et al., 2022], the realm of video generation [Xing et al., 2023c] has achieved unprecedented progress in terms of visual quality and content richness. Hence, several endeavors [Wang et al., 2023a; Xu et al., 2023; Hu et al., 2023] have sought to extrapolate the text-to-video (T2V) methods to image-to-video (I2V) by training additional image feature preserving networks and adapt them to the character animation task. Nevertheless, these trainingbased methods face challenges in accurately preserving features for arbitrary images and exhibit notable deficiencies in appearance control and loss of details. Additionally, they typically rely on extensive training data and significant computational overhead.
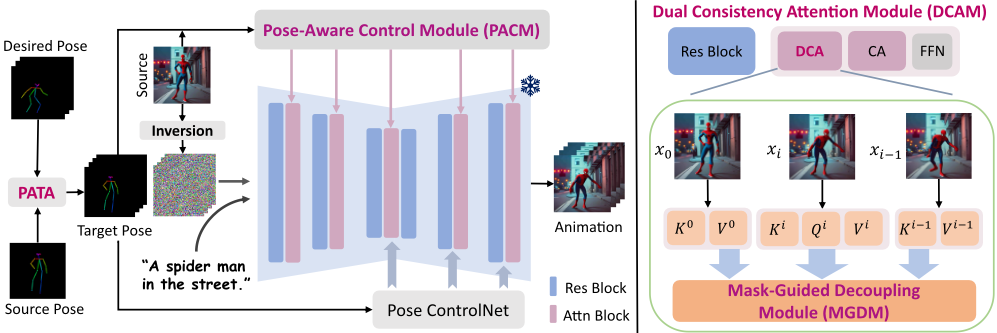
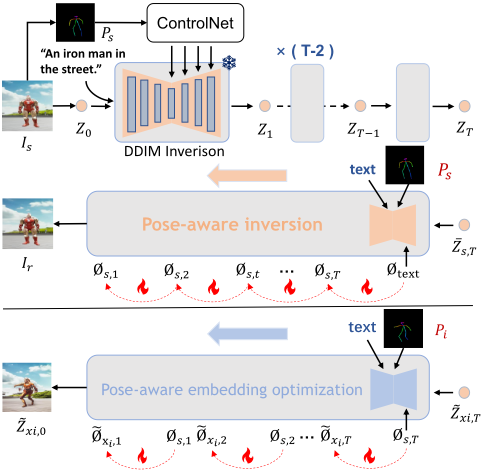
To this end, we contemplate employing a more refined and efficient approach, image reconstruction for feature preservation, to tackle this problem. We propose PoseAnimate, depicted in Fig. 2, a zero-shot reconstruction-based I2V framework for pose controllable character animation. PoseAnimate introduces a pose-aware control module (PACM), shown in Fig. 3 which optimizes the text embedding twice based on the original and target pose conditions respectively, finally resulting a unique pose-aware embedding for each generated frame. This optimization strategy allows for the gener-
Source
Generated Character Animation
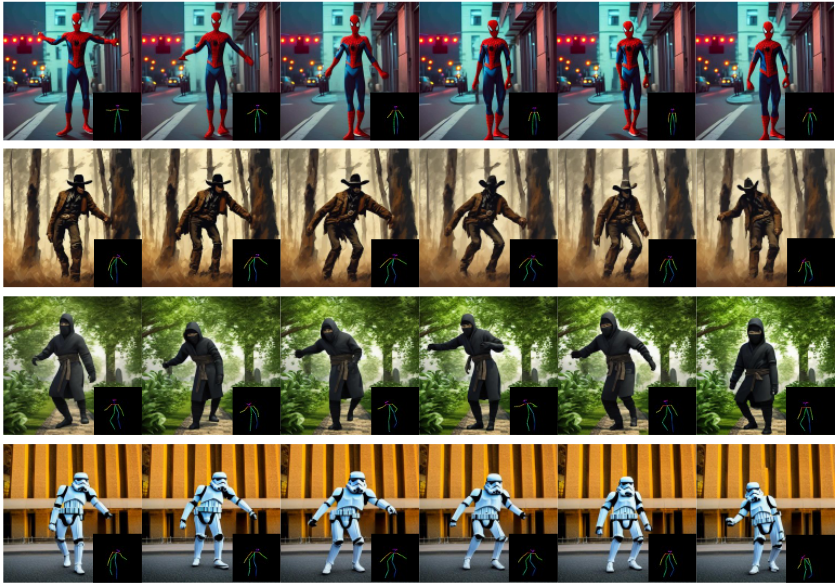
ated actions to be aligned with the target pose while keeping the character-independent scene consistent. However, the introduction of a new target pose in the second optimization, which differs from the original pose, inevitably undermines the reconstruction of the character identity and background. Thus, we further devise a dual consistency attention module (DCAM), as dedicated in the right part of Fig. 2, to address the disruption, in addition to maintain a smooth temporal progression. Since directly employing the entire attention map or key for attention fusion may result in loss of fine-grained detail perception. We propose a mask-guided decoupling module (MGDM) to enable independent and focused spatial attention fusion for both the character and background. As such, our framework is able to capture the intricate character and background details, thereby effectively enhancing the fidelity of the animation. In addition, for the sake of adaptation to various scales and positions of target pose sequences, a pose alignment transition algorithm (PATA) is designed to ensure pose alignment and smooth transitions. Through combination of these novel modules, PoseAnimate achieves promising character animation results, as shown in Fig. 1, in a more efficient manner with lower computational overhead.
In summary, our contributions are as follows: (1) We introduce a reconstruction-based approach to handle the task of character animation and propose PoseAnimate, a novel zero-shot framework, which generates coherent high-quality videos for arbitrary character images under various pose sequences, without any training of the network. To the best of our knowledge, we are the first to explore a training-free approach to character animation. (2) We propose a pose-aware control module that enables precise alignment of actions while maintaining consistency across character-independent scenes. (3) We decouple the character and the background regions, performing independent inter-frame attention fusion for them, which significantly enhances visual fidelity. (4) Experiment results demonstrate the superiority of PoseAnimate compared with the state-of-the-art training-based methods in terms of character consistency and image fidelity.
2 RelatedWork
2.1 DiffusionModels for Video Generation
Image generation has made significant progress due to the advancement of Diffusion Models (DMs) [Ho et al., 2020]. Motivated by DM-based image generation [Rombach et al., 2022], some works [Yang et al., 2023; Ho et al., 2022; Nikankin et al., 2022; Esser et al., 2023; Xing et al., 2023a; Blattmann et al., 2023b; Xing et al., 2023b] explore DMs for video generation. Most video generation methods incorporate temporal modules to pre-trained image diffusion models, extending 2D U-Net to 3D U-Net. Recent works control the generation of videos with multiple conditions. For text-guided video generation, these works [He et al., 2022; Ge et al., 2023; Gu et al., 2023] usually tokenize text prompts with a pre-trained image-language model, such as CLIP [Radford et al., 2021], to control video generation through crossattention. Due to the imperfect alignment between language and visual modalities in existing image-language models, text-guided video generation cannot achieve high textual alignment. Alternative methods [Wang et al., 2023b; Chen et al., 2023; Blattmann et al., 2023a] employ images as additional guidance for video generation. These works encode reference images to token space, helping capturing visual semantic information. VideoComposer [Wang et al., 2023b] combines textual conditions, spatial conditions (e.g., depth, sketch, reference image) and temporal conditions (e.g., motion vector) through Spatio-Temporal Condition encoders. VideoCrafter1 [Chen et al., 2023] introduces a text-aligned rich image embedding to capture details both from text prompts and reference images. Stable Video Diffusion [Blattmann et al., 2023a] is a latent diffusion model for high-resolution T2V and I2V generation, which sets three different stages for training: text-to-image pretraining, video pretraining, and high-quality video finetuning.
2.2 Video Generation with Human Pose
Generating videos with human pose is currently a popular task. Compared to other conditions, human pose can better guide the synthesis of motions in videos, which ensures good temporal consistency. Follow your pose [Ma et al., 2023] introduces a two-stage method to generate posecontrollable character videos. Many studies [Wang et al., 2023a; Karras et al., 2023; Xu et al., 2023; Hu et al., 2023] try to generate character videos from still images via pose sequence, which needs to preserve consistency of appearance from source images as well. Inspired by ControlNet [Zhang et al., 2023], DisCo [Wang et al., 2023a] realizes disentangled control of human foreground, background and pose, which enables faithful human video generation. To increase fidelity to reference human images, DreamPose [Karras et al., 2023] proposes an adapter to models CLIP and VAE image embeddings. MagicAnimate [Xu et al., 2023] adopts ControlNet [Zhang et al., 2023] to extract motion conditions. It also introduces a appearance encoder to model reference images embedding. Animate Anyone [Hu et al., 2023] designs a ReferenceNet to extract detail features from reference images, combined with a pose guider to guarantee motion generation.
3 Method
Given a source character image Is, and a desired pose sequence P = {pi}Mi=1 , where M is the length of the sequence. In the generated animation, we adopt a progressive approach to seamlessly transition the character from the source pose ps to the desired pose sequence P = {pi}Mi=1 . We first facilitate the Pose Alignment Transition Algorithm (PATA) to smoothly interpolate t intermediate frames between the source pose ps and the desired pose P = {pi}Mi=1 . Simultaneously, it aligns each pose pi with the source pose ps to compensate for their discrepancies in terms of position and scale. As a result, the final target pose sequence is P = {pi}Ni=0 , where N = M + t. It is worth noting that the first frame x0 in our generated animation X = {xi}Ni=0 is identical to the source image Is. Secondly, we propose a pose-aware control module (PACM) that optimizes a unique pose-aware embedding for each generated frame. This module can eliminate perturbation of the original character posture, thereby ensuring the generated actions aligned with the target pose P . Furthermore, it also maintains consistency of content irrelevant to characters. Thirdly, a dual consistency attention module (DCAM) is developed to ensure consistency of the character identity and improve temporal consistency. In addition, we design a mask-guided decoupling module (MGDM) to further enhance perception of character and background details. The overview of our PoseAnimate is depicted in Fig. 2.
In this section, we begin with a brief introduction to Stable Diffusion in Sec. 3.1. Subsequently, Sec. 3.2 introduces the incorporation of motion awareness into pose-aware embedding. The proposed dual consistency control module is elaborated in Sec. 3.3, followed by the mask-guided decoupling module in Sec. 3.4.
3.1 Preliminaries on Stable Diffusion
Stable Diffusion [Rombach et al., 2022] has demonstrated strong text-to-image generation ability through a diffusion model in a latent space constructed by a pair of image encoder E and decoder D. For an input image I, the encoder E first maps it to a lower dimensional latent code z0 = E(I), then Gaussian noise is gradually added to z0 through the diffusion forward process:
where t = 1, ..., T, denotes the timesteps, βt ∈ (0, 1) is a predefined noise schedule, and I is identity matrix. Through a parameterization trick, we can directly sample zt from z0:
where ¯ αt = ∏ti=1 αi, and αt = 1-βt. Diffusion models use a neural network ϵθ to learn to predict the added noise ϵ by minimizing the mean square error of the predicted noise:
where c is embedding of textual prompt. During inference, we can adopt a deterministic DDIM sampling [Song et al., 2020], to iteratively recover a denoised representation x0 from standard Gaussian noise zT , zT ∼ N (0, I):
where ˆ zt→0 is the predicted z0 at timestep t,
Then x0 is decoded into an output image I ′ = D(x0) using the pre-trained decoder D.
3.2 Pose-Aware Control Module
For generating a high fidelity character animation from a static image, two tasks need to be accomplished. Firstly, it is critical to preserve the consistency of original character and background in generated animation. In contrast to other approaches [Karras et al., 2023; Xu et al., 2023; Hu et al., 2023] that rely on training additional spatial preservation networks for consistency identity, we achieve it through a computationally efficient reconstruction-based method. Secondly, the actions in the generated frames need to align with the target poses. Although the pre-trained OpenPose ControlNet [Zhang et al., 2023] has great spatial control capabilities in controllable condition synthesis, our purpose is to discard the original pose and generate new continuous motion. Therefore, directly introducing pose signals through ControlNet may result in conflicts with the original pose, resulting in severe ghosting and blurring in motion areas.
In light of this, we propose the pose-aware control module, as illustrated in Fig. 3. Inspired by the idea of inversion in image editing [Mokady et al., 2023], we achieve the perception of pose signals by optimizing the text embedding ∅text twice based on the source pose ps and the target pose pi, respectively. In the first optimization, i.e. pose-aware inversion, we involve a progressive optimization process for ∅text to accurately reconstruct the source image Is under the source pose ps. We initialize ¯ Zs,T = ZT , ∅s,T = ∅text, and perform the following optimization for the timesteps t = T, . . . , 1, each step for n inner iterations:
zt-1(·) denotes applying DDIM sampling using latent code ¯ Zs,t, source embedding ∅s,t, source pose ps, and text prompt C. Building upon the optimized source embeddings {∅s,t}Tt=1 obtained from this process, we then proceed with the second optimization, i.e. pose-aware embedding optimization, where we inject the target pose signals P = {pi}Ni=1 into the optimized pose-aware embeddings {{˜∅xi,t}Tt=1 }Ni=1 , as detailed in Alg. 1. Perceiving the target pose signals, these optimized pose-aware embeddings {{˜∅xi,t}Tt=1 }Ni=1 ensure a flawless alignment between the generated character actions and the target poses, while upholding the consistency of character-independent content.
Specifically, to incorporate the pose signals, we integrate ControlNet into all processes of the module. Diverging from null-text inversion [Mokady et al., 2023] that achieves image reconstruction by optimizing unconditional embeddings [Ho and Salimans, 2022], our pose-aware inversion optimizes the conditional embedding ∅text of the text prompt C during the reconstruction process. The motivation stems from the observation that conditional embedding contains more abundant and robust semantic information, which endows it with a heightened potential for encoding pose signals.
3.3 Dual Consistency AttentionModule
Although the pose-aware control module accurately captures and injects body poses, it may unintentionally alter the identity of the character and the background details due to the introduction of different pose signals, as demonstrated by the example ˜ Zxi,0 in Fig. 3, which is undesirable. Since selfattention layers in the U-Net [Ronneberger et al., 2015] play a crucial role in controlling appearance, shape, and fine-grained details, existing attention fusion paradigms commonly employ cross-frame attention mechanism [Ni et al., 2022], to facilitate spatial information interaction across frames:
where Qi is the query feature of frame xi, and Kj , V j correspond to the key feature and value feature of frame xj.
As pose p1 is identical to the source pose ps, the reconstruction of frame x0 remains undisturbed, allowing for a perfect restoration of the source image Is. Hence, we can compute the cross-frame attention between each subsequent frame {xi}Ni=1 with the frame x0 to ensure the preservation of identity and intricate details. However, solely involving frame x0 in the attention fusion would bias the generated actions towards the original action, resulting in ghosting artifacts and flickering. Consequently, we develop the Dual Consistency Attention Module (DCAM) by replacing self-attention layers with our dual consistency attention (DC Attention) to address the issue of appearance inconsistency and improve temporal consistency. The DC Attention mechanism operates for each subsequent frame xi as follows:
where CFAi,j refers to cross-frame attention between frames xi and xj. λ1, λ2, λ3 ∈ (0, 1) are hyper-parameters, and λ1 + λ2 + λ3 = 1. They jointly control the participation of the initial frame x0, the current frame xi and the preceding frame xi-1 in the DC Attention calculation. In the experiment, we set λ1 = 0.7 and λ2 = λ3 = 0.15 to enable the frame x0 to be more involved in the spatial correlation control of the current frame for the sake of better appearance preservation. Apart from this, retaining a relatively small portion of feature interaction for the current frame and the preceding frame simultaneously is promised to enhance motion stability and improve temporal coherence of the generated animation.
Algorithm 1 Pose-aware embedding optimization.
Input: Source character image Is, source character pose ps, text prompt C, and target pose sequence P = {pi}Ni=1 , number of frames N, timestep T.
Output: Optimized source embeddings {∅s,t}Tt=1 , Optimized pose-aware embeddings {{˜∅xi,t}Tt=1 }Ni=1 , and latent code ZT .
- 1: Set guidance scale = 1.0. Calculate DDIM inversion [Dhariwal and Nichol, 2021] latent code Z0, ...,ZT corresponding to input image Is.
- 2: Set guidance scale = 7.5. Obtain optimized source embeddings {∅s,t}Tt=1 through pose-aware inversion.
- 3: for i = 1, 2, ...,N do
- 4: Initialize ˜ Zxi,T = ZT , {˜∅xi,t}Tt=1 = {∅s,t}Tt=1 ;
- 5: for t = T, T - 1, ..., 1 do
- 6: ˜ Zxi,t-1 ← Sample( ˜ Zxi,t, ϵθ( ˜ Zxi,t, ˜∅xi,t, pi, C, t));
- 7: ˜∅xi,t ← ˜∅xi,t - η∇˜∅MSE(Zt-1, ˜ Zxi,t-1);
- 8: end for
- 9: end for
- 10: Return ZT , {∅s,t}Tt=1 , {{˜∅xi,t}Tt=1 }Ni=1
Furthermore, it is vital to note that we do not replace all the U-Net [Ronneberger et al., 2015] transformer blocks with DCAM. We find that incorporating the DC Attention only in the upsampling blocks of the U-Net architecture while leaving the remaining unchanged allows us to maintain consistency with the identity and background details of the source, without compromising the current frame's pose and layout.
3.4 Mask-Guided DecouplingModule
Directly utilizing the entire image features for attention fusion can result in a substantial loss of fine-grained details. To address this problem, we propose the mask-guided decoupling module, which decouples the character and background and enables individual inter-frame interaction to further refine spatial feature perception.
For the source image Is, we obtain a precise body mask Ms (i.e. Mx0 ) that separates the character from the background by an off-the-shelf segmentation model [Liu et al., 2023a]. The target pose prior is insufficient to derive body mask for each generated frame of the character. Considering the strong semantic alignment capability of cross attention layers mentioned in Prompt-to-prompt [Hertz et al., 2022], we extract the corresponding body mask Mxi for each frame from the cross attention maps. With Ms and Mxi , only attentions of character and background within corresponding region are calculated, according to the mask-guided decoupling module as follows:
where CFAci,j is the attention output in character between frame xi and xj, and CFAbi,j is for the background. Then we can get the final DC Attention output:
for i = 1, ...,N. The proposed decoupling module introduces explicit learning boundary between the character and background, allowing the network to focus on their respective content independently rather than blending features. Consequently, the intricate details of both the character and background are preserved, leading to a substantial improvement in the fidelity of the animation.
4 Experiment
4.1 Experiment Settings
We implement PoseAnimate based on the public pre-trained weights of ControlNet [Zhang et al., 2023] and Stable Diffusion [Rombach et al., 2022] v1.5. For each generated character animation, we generate N = 16 frames with a unified 512 × 512 resolution. In the experiment, we use DDIM sampler [Song et al., 2020] with the default hyperparameters: number of diffusion steps T = 50 and guidance scale w = 7.5. For the pose-aware control module, loss function of optimizing text embedding ∅text is MSE. The optimization iterations are 250 in total with n = 5 inner iterations per step, and the optimizer is Adam. All experiments are performed on a single NVIDIA A100 GPU.
4.2 Comparison Result
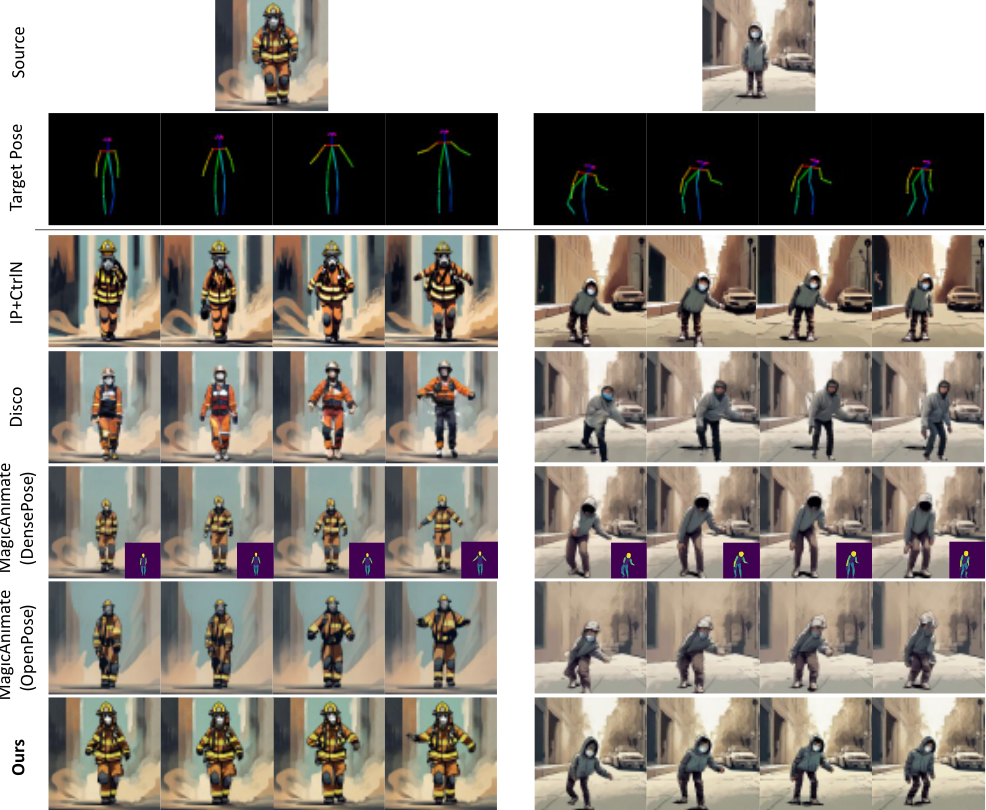
We compare our PoseAnimate with several state-of-the-art methods for character animation: MagicAnimate [Xu et al., 2023] and Disco [Wang et al., 2023a]. For MagicAnimate (MA), both DensePose [G¨uler et al., 2018] and OpenPose signals of the same motion are applied to evaluate the performances. We leverage the official open source code of Disco to test its effectiveness. Additionally, we construct a competitive character animation baseline by IP-Adapter [Ye et al., 2023] with ControlNet [Zhang et al., 2023] and spatio-temporal attention [Wu et al., 2023], which is termed as IP+CtrlN. It is worth noting that these methods are all training-based, while ours does not require training.
Qualitative Results. We set up two different levels of pose for the experiments to fully demonstrate the superiority of our method. The visual comparison results are shown in Fig. 4, with the left side displaying simple actions and the right side complex actions. Although IP+CtrlN has good performance on identity preservation, it fails to maintain details and interframe consistency. Disco completely loses character appearance, and severe frame jitter leads to ghosting shadows and visual collapse for complex actions. MagicAnimate performs better than the other two methods, but it still encounters inconsistencies in character appearance at a more fine-grinded level guided by DensePose. It is also unable to preserve background and character details accurately, e.g., vehicle textures and masks of the firefighter and the boy in Fig. 4. MagicAnimate under OpenPose signal conditions has worse performances than that under DensePose. Our method exhibits the best performance on image fidelity to the source image and effectively preserves complex fine-grained appearance details and temporal consistency.
| Method | LPIPS ↓ | CLIP-I ↑ | FC ↑ | WE ↓ |
|---|---|---|---|---|
| IP+CtrlN | 0.466 | 0.937 | 94.88 | 0.1323 |
| Disco | 0.278 | 0.811 | 92.23 | 0.0434 |
| MA (DensePose) | 0.273 | 0.870 | 97.87 | 0.0193 |
| MA (OpenPose) | 0.411 | 0.867 | 97.63 | 0.0261 |
| Ours | 0.247 | 0.948 | 97.33 | 0.0384 |
Quantitative Results. For quantitative analysis, we first randomly sample 50 in-the-wild image-text pairs and 10 different disered pose sequences to conduct evaluations. In this section, we adopt four evaluation metrics: (1) LPIPS [Zhang et al., 2018] measures the fidelity between generated frames and the source image. (2) CLIP-I [Ye et al., 2023] represents the similarity of CLIP [Radford et al., 2021] image embedding between generated frames and the source image. (3) Frame Consistency (FC) [Esser et al., 2023] evaluates video continuity by computing the average CLIP cosine similarity of two consecutive frames. (4) Warping Error (WE) [Liu et al., 2023b] evaluates the temporal consistency of the generated animation through the Optical Flow algorithm [Teed and Deng, 2020]. Quantitative results are provided in Tab. 1. Our method achieves the best scores on LPIPS and CLIP-I, and significantly surpasses other comparison methods in terms of fidelity to the source image, demonstrating outstanding detail preservation capability. In addition, PoseAnimate outperforms two training-based methods in terms of interframe consistency and obtains a good Warping Error score, illustrating that it is able to ensure good temporal coherence without additional training.
To further make a comprehensive quantitative performance comparison, we also follow the experimental settings in MagicAnimate, and evaluate both image fidelity and video quality on two benchmark datasets, namely TikTok [Jafarian and Park, 2021] and TED-talks [Siarohin et al., 2021]. we compare FID-VID [Balaji et al., 2019] and FVD [Unterthiner et al., 2018] metrics for video quality, as well as two essential image fidelity metrics, L1 and FID [Heusel et al., 2017]. The experimental results are presented in Tab. 2, where PoseAnimate achieves state-of-the-art image fidelity while maintaining competitive video quality.
4.3 Ablation Study
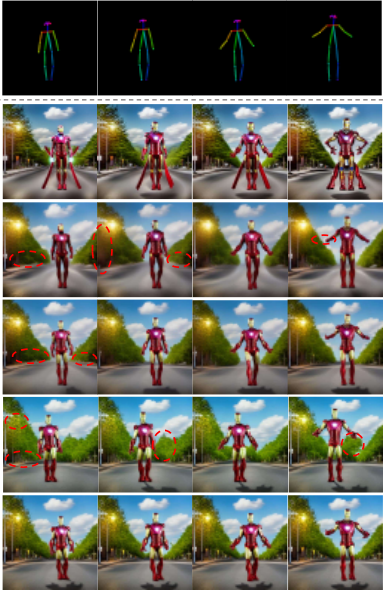
We conduct an ablation study to verify the effectiveness of each component of our framework and present the visualization results in Fig. 5. The leftmost one in the first row is the source image and the others are the target pose sequences. The following rows are generation results without certain MagicAnimate components: (a) Pose-Aware Control Module that effectively removes the interference of the source pose and maintains consistency of the content unrelated to the character; (b) Dual Consistency Attention Module that restores and preserves character identity while also improves temporal consistency; (c) Masked-Guided Decoupling Module that preserves finegrained details and enhances animation fidelity; and (d) Pose Alignment Transition Algorithm that tackles the issue of pose misalignments while enabling smooth motion transitions.
PACM. Fig. 5(a) illustrates the significant interference of the original pose on the generated actions. Due to the substantial difference between the posture of Iron Man's legs in the source and in the target, there is a severe breakdown in the leg area of the generated frame, undermining the generation of a reasonable target action. Moreover, character-independent scenes also have noticeable distortion.
DCAM. From Fig. 5(b) we can find that it fails to maintain character identity consistency without DCAM. And the missing pole and Iron Man's hand in the red circles reveal interframe inconsistency, indicating that both spatial and temporal consistency cannot be effectively maintained.
MGDM. Compared with our results in Fig. 5(e), it can be observed that small signs are missing without MGDM. It shows that MGDM can effectively enhance the perception of fine-grained features and image fidelity.
PATA. Fig. 5(d) verifies the proposed Pose Alignment Transition Algorithm. The red circles in the second frame indicate the spatial content misalignment. When Iron Man in the original image does not match with the input pose position, an extra tree appears in the original position of Iron Man. And such misalignment can also lead to disappearance of background details, e.g., streetlights and distant signage.
| Method | Image | Video | ||
|---|---|---|---|---|
| L1↓ | FID↓ | FID-VID↓ | FVD↓ | |
| IP+CtrlN | 7.13E-04 | 68.23 | 93.56 | 724.37 |
| DisCo | 3.78E-04 | 30.75 | 59.90 | 292.80 |
| MA | 3.13E-04 | 32.09 | 21.75 | 179.07 |
| Ours | 3.06E-04 | 31.47 | 63.26 | 286.33 |
| Method | Image | Video | ||
|---|---|---|---|---|
| L1↓ | FID↓ | FID-VID↓ | FVD↓ | |
| IP+CtrlN | 4.06E-04 | 45.75 | 38.48 | 281.42 |
| DisCo | 2.07E-04 | 27.51 | 19.02 | 195.00 |
| MA | 2.92E-04 | 22.78 | 19.00 | 131.51 |
| Ours | 1.98E-04 | 21.24 | 20.15 | 168.02 |
- (b) Quantitative comparisons on TED-talks dataset.

w/o PACM ;aͿ
w/o DCAM ;ďͿ
w/o MGDM ;ĐͿ
w/o PATA ;dͿ
Ours ;eͿ
5 Conclusion
This paper proposes a novel zero-shot approach PoseAnimate to tackle the task of character animation for the first time. Through the integration of three key modules and an alignment transition algorithm, PoseAnimate can efficiently generate high-fidelity, pose-controllable and temproally coherent animations for a single image across diverse pose sequences. Extensive experiments demonstrate that PoseAnimate outperforms the state-of-the-art training based methods in terms of character consistency and detail fidelity.
Acknowledgments
This project was supported by NSFC under Grant No. 62032006.
@inproceedings{ijcai2024p198,
  title     = {Zero-shot High-fidelity and Pose-controllable Character Animation},
  author    = {Zhu, Bingwen and Wang, Fanyi and Lu, Tianyi and Liu, Peng and Su, Jingwen and Liu, Jinxiu and Zhang, Yanhao and Wu, Zuxuan and Qi, Guo-Jun and Jiang, Yu-Gang},
  booktitle = {Proceedings of the Thirty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-24}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Kate Larson},
  pages     = {1788--1797},
  year      = {2024},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2024/198},
  url       = {https://doi.org/10.24963/ijcai.2024/198},
}
TY - CPAPER TI - Zero-shot High-fidelity and Pose-controllable Character Animation AU - Zhu, Bingwen AU - Wang, Fanyi AU - Lu, Tianyi AU - Liu, Peng AU - Su, Jingwen AU - Liu, Jinxiu AU - Zhang, Yanhao AU - Wu, Zuxuan AU - Qi, Guo-Jun AU - Jiang, Yu-Gang T2 - Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, IJCAI-24 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2024 SP - 1788 EP - 1797 DO - 10.24963/ijcai.2024/198 UR - https://doi.org/10.24963/ijcai.2024/198 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





