
Arrange, Inpaint, and Refine: Steerable Long-term Music Audio Generation and Editing via Content-based Controls
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence. AI, Arts & Creativity. Pages 7690-7698.
https://doi.org/10.24963/ijcai.2024/851
Keywords
- Methods and resources: Machine learning, deep learning, neural models, reinforcement learning
- Application domains: Music and sound
Abstract
Controllable music generation plays a vital role in human-AI music co-creation. While Large Language Models (LLMs) have shown promise in generating high-quality music, their focus on autoregressive generation limits their utility in music editing tasks. To bridge this gap, To address this gap, we propose a novel approach leveraging a parameter-efficient heterogeneous adapter combined with a masking training scheme. This approach enables autoregressive language models to seamlessly address music inpainting tasks. Additionally, our method integrates frame-level content-based controls, facilitating track-conditioned music refinement and score-conditioned music arrangement. We apply this method to fine-tune MusicGen, a leading autoregressive music generation model. Our experiments demonstrate promising results across multiple music editing tasks, offering more flexible controls for future AI-driven music editing tools. The source codes and a demo page showcasing our work are available at https://kikyo-16.github.io/AIR.
- [Agostinelli et al., 2023] Andrea Agostinelli, Timo I Denk, Zalán Borsos, Jesse Engel, Mauro Verzetti, Antoine Cail- lon, Qingqing Huang, Aren Jansen, Adam Roberts, Marco Tagliasacchi, et al. MusicLM: Generating music from text. arXiv preprint arXiv:2301.11325, 2023.
- [Böck et al., 2016] Sebastian Böck, Filip Korzeniowski, Jan Schlüter, Florian Krebs, and Gerhard Widmer. Madmom: A new python audio and music signal processing library. In Proceedings of the 24th ACM international conference on Multimedia, pages 1174-1178, 2016.
- [Chang et al., 2021] Chin-Jui Chang, Chun-Yi Lee, and Yi- Hsuan Yang. Variable-length music score infilling via xl- net and musically specialized positional encoding. In Pro- ceedings of the 22nd Conference of the International Soci- ety for Music Information Retrieval, pages 97-104, 2021.
- [Chen et al., 2020] Ke Chen, Cheng-i Wang, Taylor Berg- Kirkpatrick, and Shlomo Dubnov. Music sketchnet: Con- trollable music generation via factorized representations of pitch and rhythm. In Proceedings of the 21st Conference of the International Society for Music Information Retrieval, pages 77-84, 2020.
- [Copet et al., 2023] Jade Copet, Felix Kreuk, Itai Gat, Tal Remez, David Kant, Gabriel Synnaeve, Yossi Adi, and Alexandre Défossez. Simple and controllable music gen- eration. arXiv preprint arXiv:2306.05284, 2023.
- [Défossez et al., 2022] Alexandre Défossez, Jade Copet, Gabriel Synnaeve, and Yossi Adi. High fidelity neural au- dio compression. arXiv preprint arXiv:2210.13438, 2022.
- [Défossez et al., 2023] Alexandre Défossez, Jade Copet, Gabriel Synnaeve, and Yossi Adi. High fidelity neural audio compression. Transactions on Machine Learning Research, 2023. Featured Certification, Reproducibility Certification.
- [Dhariwal et al., 2020] Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, and Ilya Sutskever. Jukebox: A generative model for music. arXiv preprint arXiv:2005.00341, 2020.
- [Gao et al., 2023] Peng Gao, Jiaming Han, Renrui Zhang, Ziyi Lin, Shijie Geng, Aojun Zhou, Wei Zhang, Pan Lu, Conghui He, Xiangyu Yue, et al. Llama-adapter v2: Parameter-efficient visual instruction model. arXiv preprint arXiv:2304.15010, 2023.
- [Garcia et al., 2023] Hugo F Flores Garcia, Prem Seethara- man, Rithesh Kumar, and Bryan Pardo. Vampnet: Music generation via masked acoustic token modeling. In Ismir 2023 Hybrid Conference, 2023.
- [Goto et al., 2002] Masataka Goto, Hiroki Hashiguchi, Takuichi Nishimura, and Ryuichi Oka. Rwc music database: Popular, classical and jazz music databases. In Proceedings of the 3rd Conference of the International Society for Music Information Retrieval, volume 2, pages 287-288, 2002.
- [Hu et al., 2021] Edward J Hu, Yelong Shen, Phillip Wallis, Zeyuan Allen-Zhu, Yuanzhi Li, Shean Wang, Lu Wang, and Weizhu Chen. Lora: Low-rank adaptation of large language models. arXiv preprint arXiv:2106.09685, 2021.
- [Huang and Yang, 2020] Yu-Siang Huang and Yi-Hsuan Yang. Pop music transformer: Beat-based modeling and generation of expressive pop piano compositions. In Pro- ceedings of the 28th ACM international conference on multimedia, pages 1180-1188, 2020.
- [Huang et al., 2018] Cheng-Zhi Anna Huang, Ashish Vaswani, Jakob Uszkoreit, Noam Shazeer, Ian Simon, Curtis Hawthorne, Andrew M Dai, Matthew D Hoffman, Monica Dinculescu, and Douglas Eck. Music transformer. arXiv preprint arXiv:1809.04281, 2018.
- [Ippolito et al., 2018] Daphne Ippolito, Anna Huang, Cur- tis Hawthorne, and Douglas Eck. Infilling piano perfor- mances. In NIPS Workshop on Machine Learning for Cre- ativity and Design, volume 2, page 5, 2018.
- [Jiang et al., 2019] Junyan Jiang, Ke Chen, Wei Li, and Gus Xia. Large-vocabulary chord transcription via chord struc- ture decomposition. In Proceedings of the 20th Confer- ence of the International Society for Music Information Retrieval, pages 644-651, 2019.
- [Li and Liang, 2021] Xiang Lisa Li and Percy Liang. Prefix- tuning: Optimizing continuous prompts for generation. arXiv preprint arXiv:2101.00190, 2021.
- [Lin et al., 2024] Liwei Lin, Gus Xia, Junyan Jiang, and Yix- iao Zhang. Content-based controls for music large lan- guage modeling, 2024.
- [Liu et al., 2022] Xiao Liu, Kaixuan Ji, Yicheng Fu, Weng Tam, Zhengxiao Du, Zhilin Yang, and Jie Tang. P-tuning: Prompt tuning can be comparable to fine-tuning across scales and tasks. In Proceedings of the 60th Annual Meet- ing of the Association for Computational Linguistics (Vol- ume 2: Short Papers), pages 61-68, 2022.
- [Manilow et al., 2019] Ethan Manilow, Gordon Wichern, Prem Seetharaman, and Jonathan Le Roux. Cutting mu- sic source separation some slakh: A dataset to study the impact of training data quality and quantity. In 2019 IEEE Workshop on Applications of Signal Processing to Audio and Acoustics (WASPAA), pages 45-49. IEEE, 2019.
- [Marafioti et al., 2019] Andrés Marafioti, Nathanaël Per- raudin, Nicki Holighaus, and Piotr Majdak. A context en- coder for audio inpainting. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 27(12):2362- 2372, 2019.
- [Marafioti et al., 2020] Andres Marafioti, Piotr Majdak, Nicki Holighaus, and Nathanaël Perraudin. Gacela: A generative adversarial context encoder for long audio in- painting of music. IEEE Journal of Selected Topics in Sig- nal Processing, 15(1):120-131, 2020.
- [Min et al., 2023] Lejun Min, Junyan Jiang, Gus Xia, and Jingwei Zhao. Polyffusion: A diffusion model for poly- phonic score generation with internal and external con- trols. In Proceedings of the 24th Conference of the In- ternational Society for Music Information Retrieval, pages 231-238, 2023.
- [Mitsufuji et al., 2022] Yuki Mitsufuji, Giorgio Fabbro, Ste- fan Uhlich, Fabian-Robert Stöter, Alexandre Défossez, Minseok Kim, Woosung Choi, Chin-Yun Yu, and Kin-Wai Cheuk. Music demixing challenge 2021. Frontiers in Sig- nal Processing, 1:808395, 2022.
- [Perraudin et al., 2018] Nathanael Perraudin, Nicki Ho- lighaus, Piotr Majdak, and Peter Balazs. Inpainting of long audio segments with similarity graphs. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 26(6):1083-1094, 2018.
- [Raffel et al., 2020] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. The Journal of Machine Learning Research, 21(1):5485- 5551, 2020.
- [Schneider et al., 2023] Flavio Schneider, Ojasv Kamal, Zhijing Jin, and Bernhard Schölkopf. Mo\ˆusai: Text-to- music generation with long-context latent diffusion. arXiv preprint arXiv:2301.11757, 2023.
- [Van Den Oord et al., 2017] Aaron Van Den Oord, Oriol Vinyals, et al. Neural discrete representation learning. Advances in neural information processing systems, 30, 2017.
- [Wang and Xia, 2021] Ziyu Wang and Gus Xia. Musebert: Pre-training music representation for music understanding and controllable generation. In ISMIR, pages 722-729, 2021.
- [Wei et al., 2023] Shiqi Wei, Ziyu Wang, Weiguo Gao, and Gus Xia. Controllable music inpainting with mixed-level and disentangled representation. In ICASSP 2023 -2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), pages 1-5, 2023.
- [Wu et al., 2023a] Shih-Lun Wu, Chris Donahue, Shinji Watanabe, and Nicholas J. Bryan. Music controlnet: Mul- tiple time-varying controls for music generation, 2023.
- [Wu et al., 2023b] Yusong Wu, Ke Chen, Tianyu Zhang, Yuchen Hui, Taylor Berg-Kirkpatrick, and Shlomo Dub- nov. Large-scale contrastive language-audio pretraining with feature fusion and keyword-to-caption augmentation. In ICASSP 2023-2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), pages 1-5. IEEE, 2023.
- [Zhang et al., 2023] Renrui Zhang, Jiaming Han, Aojun Zhou, Xiangfei Hu, Shilin Yan, Pan Lu, Hongsheng Li, Peng Gao, and Yu Qiao. Llama-adapter: Efficient fine- tuning of language models with zero-init attention. arXiv preprint arXiv:2303.16199, 2023.
- [Zhao and Xia, 2021] Jingwei Zhao and Gus Xia. Accomon- tage: Accompaniment arrangement via phrase selection and style transfer. arXiv preprint arXiv:2108.11213, 2021.
- [Zhou et al., 2019] Hang Zhou, Ziwei Liu, Xudong Xu, Ping Luo, and Xiaogang Wang. Vision-infused deep audio in- painting. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 283-292, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In recent years, there has been a surge in the development of deep music generative models, encompassing both audio and symbolic domains [Huang et al., 2018; Huang and Yang, 2020; Dhariwal et al., 2020; Wang and Xia, 2021; Zhao and Xia, 2021; Copet et al., 2023; Agostinelli et al., 2023]. Particularly, the emergence of Large Language Models (LLMs) has enabled various systems to achieve highquality generations. Such progress offers a glimpse into the potential of constructing effective tools for facilitating human-AI co-creation.
Current LLM-based music audio generation models exhibit remarkable performance [Dhariwal et al., 2020; Agostinelli et al., 2023; Copet et al., 2023]. Some initiatives [Lin et al., 2024] aim to equip these models with content-based controls, such as drum patterns and chord progressions, showcasing their potential for flexible music editing tasks. However, as these models focus on autoregressive generation, they lack the capability of inpainting, a common practice in music creation involving iterative refinements of arbitrary audio segments. Existing music inpainting models [Zhou et al., 2019; Marafioti et al., 2020; Garcia et al., 2023], while attempting to address this need, struggle with controllable inpainting and capturing long-term music context dependencies. Consequently, they are primarily effective for short-range gap filling, typically limited to one or two seconds, and lack controllability.
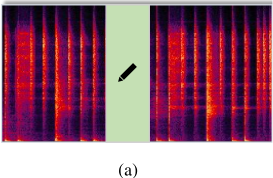
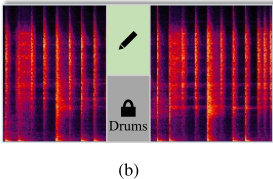
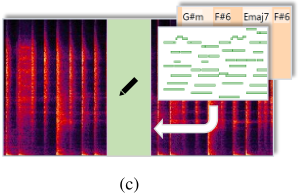
To this end, we introduce AIRGen, a model capable of doing arrangement, inpainting, and refinement by applying a novel parameter-efficient heterogeneous adapter to fine-tune MusicGen [Copet et al., 2023], an advanced autoregressive music audio language model. Our heterogeneous adapter repurposes the autoregressive language model to seamlessly solve mask-filling tasks, thereby equipping MusicGen with music in-painting ability (Fig. 1(a)). Moreover, the heterogeneous adapter integrates frame-level audio controls into the model architecture, enabling precise content-based manipulation, including drum tracks, chord progression, and piano covers. This enables track-conditioned music refinement (Fig. 1(b)) and score-conditioned music arrangement (Fig. 1(c)).
In summary, the contributions of this work are as follows:
Parameter-efficient heterogeneous adapter. We introduce a novel heterogeneous adapter, combined with a welldesigned masking training scheme. This approach successfully transforms a pretrained autoregressive LM into a masked LM, while incorporating sequential controls through Parameter-Efficient Fine-Tuning.
Flexible long-termmusic editing. As shown in Figure 1, our model enables flexible editing of arbitrary segments of the audio mixture. This includes re-generating (inpainting) the segment based on its past and future contexts, refining the segment based on prescribed audio content (e.g., the drum track), and re-arranging the segment given semantic controls such as chord progressions and piano arrangements. Additionally, our model is adept at filling segments lasting more than 8 seconds.
High-quality steerable Generation. Experimental results demonstrate that our model outperforms existing baselines at the inpainting task. Additionally, for the refinement and arrangement tasks, our model achieves comparable quality to unconditioned autoregressive generation, a capability not observed in other models.
2 RelatedWork
2.1 General Audio andMusic GenerationModels
Music audio generation necessitates extensive contextual modeling to account for the intricate structure of musical language. Recent large-scale music audio generative models, encompassing autoregressive and diffusion-based approaches, have made remarkable strides in capturing such a longterm structure while introducing cross-modal conditions. For example, Jukebox [Dhariwal et al., 2020] leverages VQVAE [Van Den Oord et al., 2017] and transformer decoders to achieve lyric and genre-based generation; Diffusion-based Moˆusai [Schneider et al., 2023] adopts the pretrained frozen T5 encoder [Raffel et al., 2020] to summarize text conditions; autoregressive MusicGen [Copet et al., 2023] realizes monophonic melody and text controls by assembling EnCodec [D´efossez et al., 2022], T5 encoder, and an acoustic transformer decoder. Additionally, Coco-Mulla [Lin et al., 2024] and Music ControlNet [Wu et al., 2023a] facilitate more flexible music generation by incorporating contentbased controls.
2.2 Music Inpainting
Music inpainting models support music generation in more diverse and interactive scenarios. In the symbolic music domain, the inpainting duration is usually long [Ippolito et al., 2018; Chen et al., 2020; Chang et al., 2021; Min et al., 2023; Wei et al., 2023]. In the music audio domain, Perraudin et al. [2018] use a similarity graph to retrieve suitable segments in the source audio to patch up the masked section; Marafioti et al. [2019] use a conv-deconv neural net to predict the masked spectrogram given the past and future contexts; Zhou et al. [2019] condition the inpainting on the music performance video via a visual-audio joint feature space; GACELA [Marafioti et al., 2020] uses a generator with a latent condition code as input to address the multi-modality of music content; Vampnet [Garcia et al., 2023] adopts that methodology and uses masked acoustic token modeling to implement music inpainting. However, in all the abovementioned works, the inpainting duration is limited to under 2 seconds, and the models fail to meet flexible content-based controls.
2.3 Parameter-Efficient Fine-tuning
Parameter-efficient fine-tuning (PEFT) methods adapt pretrained language models (PLMs) by selectively updating model parameters, leading to notable reductions in computational and storage costs. Methods such as appending taskspecific prefixes to input sequences [Li and Liang, 2021; Liu et al., 2022] and employing low-rank adaption (LoRA) for fine-tuning pretrained linear matrices [Hu et al., 2021] have shown promise. Additionally, approaches like LLaMAAdapter adjust attention outputs using prompt adapters and zero gate scalars, with a multi-modal conditional variant incorporating global image representations [Zhang et al., 2023; Gao et al., 2023]. Inspired by LLaMA-Adapter, we introduce a novel PEFT method in this study, designed to fine-tune large-scale models while accommodating external sequential conditions, transforming a pretrained autoregressive language model into a masked LM.
3 Methodology
In this section, we describe in detail the base LLM to finetune, the well-designed content-based controls, the tokenization scheme for input into the LLM, and the proposed heterogeneous adapter.
3.1 MusicGen
We take the text-only version of MusicGen as the base LLM. MusicGen is an autoregressive transformer-based model, conditioned on text or melody, using quantized tokens from an EnCodec [D´efossez et al., 2023] audio tokenizer for highfidelity music generation. It incorporates Residual Vector Quantization to handle multiple streams of discrete tokens from learned codebooks.
This version of MusicGen comprises three key components: a pretrained EnCodec, a pretrained T5 encoder, and an acoustic transformer decoder. The acoustic transformer decoder is composed of N layers, each featuring a causal selfattention block and a cross-attention block tailored to handle conditioning text prompts. Our PEFT training process solely
Algorithm 1 Piano reduction algorithm
Input: M = Original MIDI tracks
Output: P = Reduced piano track
- 1: Let Γ = Piano-like MIDI tracks inM.
- 2: Γ′ = Sort all note events in Γ by duration in a descending order.
- 3: Initiate an empty piano track P.
- 4: for all Note event e in Γ′ do
- 5: e′ ←Set program of e to 0.
- 6: if e′ does not overlap with any event in P then
- 7: Add e′ to P.
- 8: end if
- 9: end for
- 10: return P
modifies the self-attention blocks within the acoustic transformer decoder.
3.2 Content-Based Controls
We categorize content-based controls into two types: external and internal controls. Internal controls involve surface-level manipulation of acoustic tracks, requiring the generated audio to include the condition tracks. External controls, on the other hand, entail conceptual adjustments such as chord progression or piano cover. The apparent challenge is how MusicGen, an audio model, can process the symbolic conditions (e.g., notes, chords) prescribed by the external controls. Our solution is to algorithmically render all symbolic controls into the audio format before inputting them to MusicGen.
In our experiments that demonstrate internal controls, we use drum tracks as the condition. The external controls in our experiments include chord progression and piano cover. During audio synthesis, we render the current chord annotation into a block chord at each beat onset. For piano cover controls, we introduce a rule-based piano reduction algorithm outlined in Algorithm 1 to extract piano covers from provided MIDI annotations. Subsequently, we render the piano reduction to audio.
3.3 Tokenization Design
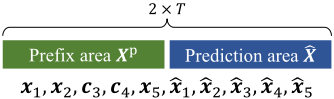
We extract discrete tokens from both the target and the condition audio sequences using Encodec, operating at a resolution of 50 frames per second. Let X = {x1, x2, ..., xT} (X ∈ RT×n ) and C = {c1, c2, ..., cT} (C ∈ RT×n ) represent the extracted tokens of the target and condition sequences, respectively, where T denotes the total number of frames and n denotes the dimension of a discrete token. Our goal is to reconstruct the original X from a corrupted X using the condition C.
We prepend the combination of C and corrupted X as the prefix of the input sequence to the decoder (Figure 2). Denote the prefix as Xp = {xp1 , xp2 , ..., xpT } (Xp ∈ RT×n ),
Given ˆx1, ˆx2, ..., ˆxt, which are the predicted tokens up to t,
𝒙𝒙ଵ, 𝒙𝒙ଶ, 𝒄𝒄ଷ, 𝒄𝒄ସ, 𝒙𝒙ହ, �𝒙𝒙ଵ, �𝒙𝒙ଶ, �𝒙𝒙ଷ, �𝒙𝒙ସ, �𝒙𝒙ହ
Figure 2: Design of the input sequence, with T = 5 as an example. The prefix area is followed by the prediction area. The prefix area spans from 1 to T . Here the unmasked locations contain the infilling contexts. At the masked locations, the ground-truth audio is masked away and replaced by the frame-level condition audio track. The prediction area spans from T + 1 to 2 × T. In this example, the masks happen to be contiguous, while in general an arbitrary set of frames can be masked.
then the next predicted audio token ˆxt+1 ∈ Rn is,
During training, we apply cross-entropy loss to the prediction area for both masked and unmasked tokens,
This design enables the autoregressive decoder to capture full-context information and incorporate frame-wise condition information when inpainting corrupted audio.
3.4 Heterogeneous Adapter
To enhance decoder fine-tuning efficiency, we introduce a heterogeneous adapter, where multiple different lightweight adapters are trained to work together in the same decoder.
In vanilla PEFT with adapters, the same type of adapters is applied to all frames since the signal Xp is homogeneous in a typical LM task. In our method, each layer incorporates four different types of trainable adapters, with each type directed at frames of a specific type, as depicted in Figure 3. Let al1 , al2 , al3 , al4 ∈ Rm×d represent the adapters of the l-th self-attention layer, where m is the number of adapter vectors per type and d is the dimension of both the decoder's hidden state and each adapter vector. We deploy al1 and al3 to incorporate the infilling context at the unmasked locations and deploy al2 and al4 to take in condition information and perform inpainting at the masked locations.
Let Hl = {hl1 , hl2 , ..., hl2T } denote the input representation of the l-th self-attention layer. The heterogeneous adapter modifies the attention output of hlt by computing cross-attention between hlt and alr(t) . The type r(t) is selected based on whether the t-th frame is in the prefix area or the prediction area and whether it is masked:
Before being modified by heterogeneous adapters, each layer of the transformer decoder computes self-attention Sl = {sl1 , sl2 , ...sl2T } among the hidden states with a causal mask:
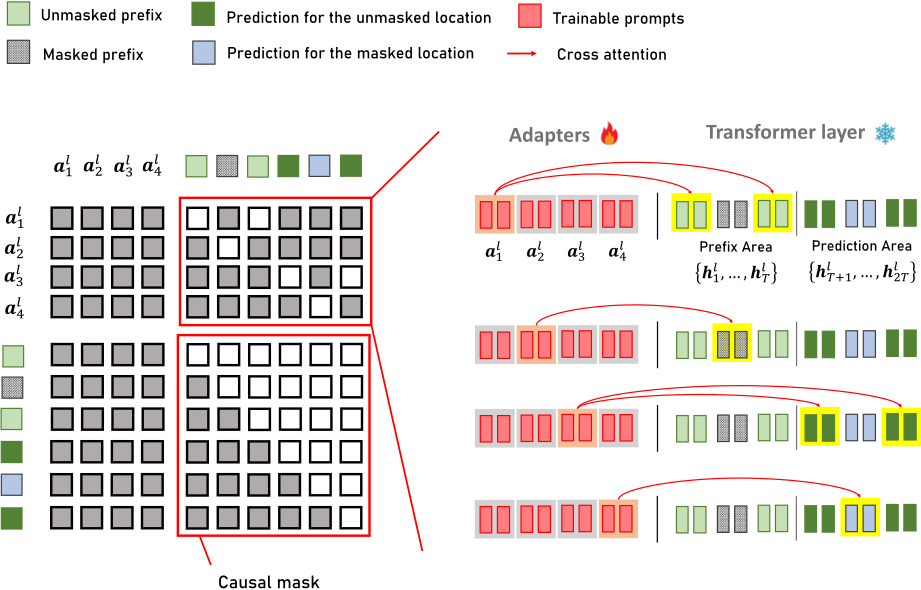
The heterogeneous adapters introduce a cross-attention mechanism, between learnable adapters and the hidden states of the transformer layers, as shown in Figure 3. This crossattention reuses all the projection matrices of the original transformer decoder, which are used to perform self-attention as described in Equation 5. The cross-attention ult for hlt is computed as follows:
After being modified by the adapters, the adjusted attention output sl,∗ t is given by:
where glr(t) is a learnable gating factor initialized to zero.
Throughout the training, all parameters in the decoder remain frozen except for the adapters {al1 , al2 , al3 , al4 } and the gates {gl1 , gl2 , gl3 , gl4 } at each layer.
4 Experiments
4.1 Dataset
Our model is trained on the training split of Slakh2100, a dataset of synthesized MIDI files using a high-quality soundfont [Manilow et al., 2019]. We derive pseudo chord and beat annotations using Madmom [B¨ock et al., 2016] and a chord recognition model [Jiang et al., 2019]. The total training set comprises 1289 instrumental songs with silence trimmed away at both ends. Evaluation is conducted on both the test split (151 songs) of Slakh2100 and RWC-POP100, a dataset featuring 100 real-recording pop songs with MIDI, chord, and beat annotations [Goto et al., 2002].
4.2 Training
We train three models: Drum-AIR, Chord-AIR, and PianoAIR, tailored for drum-track conditioning, chord-progression conditioning, and piano-cover conditioning, respectively.
Each model is trained using two A800's with an initial learning rate of 2e-3, a batch size of 24, and a sample duration of 15 seconds, for 10 epochs, totaling 8 hours of training time. The warm-up epoch is set to 1, and the model is updated using a cross-entropy loss.
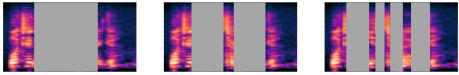
(a) Mask Pattern 1. (b) Mask Pattern 2. (c) Mask Pattern 3.
Figure 4: The three types of masks used in evaluation. The number of masks is by design and the location is random.
(a) Slakh2100 Test Set
| CLAPsrc ↑ | FADvgg ↓ | |||
|---|---|---|---|---|
| Full | Prefix | Full | Prefix | |
| Drum-AIR | 0.749 | 0.756 | 1.423 | 1.422 |
| Chord-AIR | 0.753 | 0.757 | 1.220 | 1.222 |
| Piano-AIR | 0.755 | 0.761 | 1.290 | 1.282 |
| MusicGen | 0.656 | 0.687 | 1.251 | 1.218 |
| VampNet | 0.631 | 0.643 | 2.910 | 3.424 |
(b) RWC-POP-100
| CLAPsrc ↑ | FADvgg ↓ | |||
|---|---|---|---|---|
| Full | Prefix | Full | Prefix | |
| Drum-AIR | 0.619 | 0.627 | 1.606 | 1.691 |
| Chord-AIR | 0.614 | 0.625 | 1.593 | 1.681 |
| Piano-AIR | 0.611 | 0.621 | 1.531 | 1.623 |
| MusicGen | 0.373 | 0.441 | 2.474 | 2.276 |
| VampNet | 0.613 | 0.618 | 3.689 | 3.910 |
4.3 Evaluation
Throughout the training process, we uniformly sample a mask ratio from the interval [0.4, 0.8] and generate a binary mask with this ratio. To maintain the continuity of audio segments, we utilize a median filter with a window size of 11 to smooth the mask before applying it to the input Encodec tokens.
We assess the performance of our models using two distinct datasets: the synthetic instrumental dataset (Slakh2100 Test Set) and a real-recording vocal dataset (RWC-POP-100). From each test song, we extract a 15-second audio segment for evaluation. We present three types of masks to corrupt the test audio, resulting in discontinuous masking areas: one, two, and four masking areas, respectively, referred to as Mask Pattern 1 through 3, as shown in Figure 4. The total duration of masking areas sums up to 7.5s for each setting.
The metrics we employ are as follows:
- Source-to-Distortion Ratio (SDR). To evaluate how closely Drum-AIR adheres to the drum-track condition, we measure the SDR between the inpainted drum tracks (separated by Demucs) and the condition drum tracks. This measurement uses the latest SDR definition as specified in the Music Demixing Challenge (MDX
(a) Slakh2100 Test Set
| DrumSDR ↓ | Chordrec ↑ | Chromacos ↑ | |
|---|---|---|---|
| Drum-AIR | 6.676 | - | - |
| Chord-AIR | - | 0.745 | 0.830 |
| Piano-AIR | - | 0.720 | 0.849 |
(b) RWC-POP-100
| DrumSDR ↓ | Chordrec ↑ | Chromacos ↑ | |
|---|---|---|---|
| Drum-AIR | 6.531 | - | - |
| Chord-AIR | - | 0.650 | 0.837 |
| Piano-AIR | - | 0.615 | 0.845 |
2021) competition [Mitsufuji et al., 2022].
- Chord Accuracy. For both Chord-AIR and Piano-AIR, we evaluate adherence to the condition chord progression by comparing the inpainted chords (predicted by a chord recognition model [Jiang et al., 2019]) with the condition chords. We report the weighted recall scores with a time resolution of 20ms to measure chord accuracy.
- Chroma Cosine Similarity. To assess how well ChordAIR and Piano-AIR adhere to the chord and piano conditions, we calculate the chroma cosine similarity between the inpainted audios and the condition tracks, with a window size of 2048 and a hop size of 640 for the chromagram.
- CLAP Score. For each model, we report the CLAP score [Wu et al., 2023b], which assesses the semantic distance between the inpainted audio and the original audio.
- Fr´echet Audio Distance (FAD). For each model, we calculate the Frechet Audio Distance (FAD) of Visual Geometry Group (VGG) features between the inpainted audio and the original audio.
4.4 Baselines
We designate MusicGen [Copet et al., 2023] and VampNet [Garcia et al., 2023] as our baselines, as there are currently no other comparable content-based controllable inpainting models available for comparison. As MusicGen can only perform continuation rather than inpainting, we only evaluate MusicGen using the past context of Mask Pattern 1.
- MusicGen. We reproduce the MusicGen model with the MusicGen-large official checkpoint. 1
- VampNet. VampNet employs a non-autoregressive, bidirectional transformer with a variable masking schedule, enabling high-fidelity music synthesis across various tasks, such as inpainting and outpainting, through
1 https://huggingface.co/facebook/musicgen-large.
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence (IJCAI-24)
Special Track on AI, the Arts and Creativity
FAD assess both the predicted prefix, the inpainted segment, and the predicted suffix.
The comparison between prefix-CLAP and full-CLAP values in Table 1(a) indicates that as MusicGen generates longer continuations, it "strays further" from the given context. When employing our heterogeneous adapter to enable inpainting settings for MusicGen, the resulting audio exhibits promising fidelity in preserving the original semantic context during generation. Furthermore, the low FAD further indicates that audio samples inpainted by our model exhibit competitive naturalness compared to those generated by the vallina MusicGen without suffix constraints. Compared to VampNet, our model achieves superior long-gap inpainting, as evidenced by the FAD value.
Table 1(b) presents the results on the real-recording dataset with vocals, which is Out-Of-Distribution (OOD) w.r.t. the training dataset of MusicGen and our models but not w.r.t. VampNet. Comparing these results with those in Table 1(a), it is evident that our models exhibit superior generalization ability, outperforming the vanilla MusicGen.
Controllable Inpainting. As demonstrated in Table 1, our model excels in controllable inpainting across various music editing tasks. The high SDR values in Table 2 indicate our
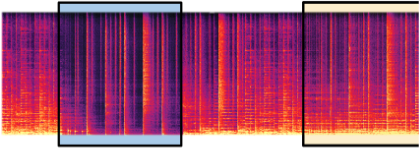
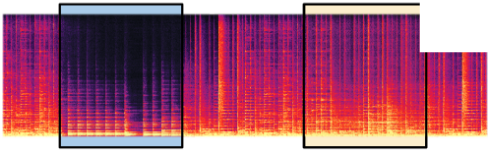
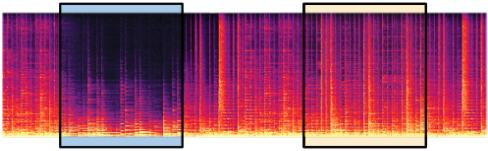
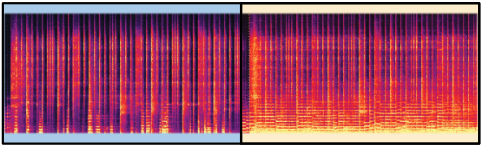
Figure 5: Inpainting with various controls. The spectrogram conceptually repeats the same music segment twice, with the left half (1, ..., T) providing the model with the infilling context and the controls, and the right half (T + 1, ..., 2T) for the model to predict. Specifically, in the left half, outside the blue rectangle is the unmasked infilling context, and inside the blue rectangle is the separated/synthesized/user-specified audio representation of the condition (e.g., (a) drum, (b) block chords, (c) piano cover). In the right half, the orange rectangle highlights the inpainted results.
flexible inference masks. We reproduce the VampNet model with the the official code 2 and checkpoint 3 .
4.5 Results
As illustrated in Table 1 and Table 2, our model demonstrates competitive performance compared to unconditional generation and inpainting models. Furthermore, it showcases promising steerabilty.
Long-Gap Inpainting. Table 1 presents the semantic similarity between inpainted audios and the original recordings, along with the audio qualities. In this scenario, MusicGen receives the prefix of Mask Pattern 1 (3.75s) and is tasked with generating an 11.25-second continuation. Conversely, VampNet and AIR models are conditioned with both the prefix and suffix of Mask Pattern 1. We present metrics for prefix-CLAP and prefix-FAD, evaluating the predicted (repeated) prefix and inpainted segments (11.25s), while full-CLAP and fullmodel's proficiency in internal control, effectively inpainting the masked areas while preserving the condition track. Additionally, chord, chroma, and beat metrics underscore the capability of our models to integrate controls. Furthermore, CLAP values in Table 1 highlight that applying content-based controls extracted from the original audio serve as an auxiliary mechanism for maintaining the semantics of the original audio.
2 https://github.com/hugofloresgarcia/vampnet.
3 https://zenodo.org/record/8136629/.
| m | Trainable | Storage | Slakh2100 Test Set | RWC-POP-100 | ||||
|---|---|---|---|---|---|---|---|---|
| parameters | Space | DrumSDR ↑ | CLAPsrc ↑ | FADvgg ↓ | DrumSDR ↑ | CLAPsrc ↑ | FADvgg ↓ | |
| 10 | 3.75M | 15M | 6.475 | 0.758 | 1.416 | 6.109 | 0.652 | 1.634 |
| 30 | 11.25M | 45M | 6.257 | 0.761 | 1.434 | 6.479 | 0.646 | 1.705 |
| 50 | 18.75M | 75M | 6.628 | 0.759 | 1.442 | 6.628 | 0.643 | 1.673 |
Arrangement and Refinement. Figure 5 illustrates examples of the results for the score-conditioned arrangement and the track-conditioned refinement tasks, highlighting our model's capability to reconstruct missing segments of the spectrogram. This demonstrates our approach's adaptability in performing spectrogram inpainting under various conditions.
Figure 6 presents a case of inpainting where 70% of the spectrogram was intentionally masked prior to the inpainting process. Despite the significant loss of information, our model is able to restore the music composition, showing its robustness in handling substantial data gaps.
Low-Resource Fine-Tuning. As shown in Table 3, our heterogeneous adapters demonstrate a notable advantage in lowresource settings, with trainable parameters totaling less than 20M and a storage space requirement of less than 75M for the largest model. In comparison with the 3.3B parameters of vanilla MusicGen, our method effectively facilitates finetuning, converting an autoregressive music audio LLM into a steerable inpainting model.
4.6 Ablation
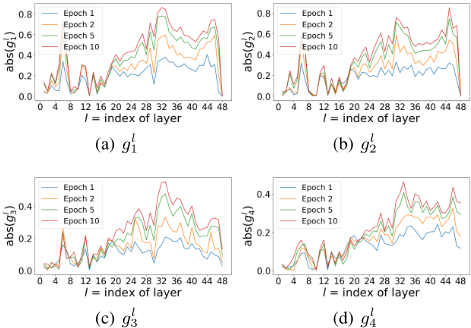
Impact of Different Adapter Size. A smaller m implies a reduced size of adapters, resulting in fewer trainable parameters. However, Table 3 illustrates that a small m does not significantly impair performance, highlighting the effectiveness of the proposed heterogeneous adapters. Additionally, Figure 7 displays the variation of absolute values of learnable gates glr(t) in different layers during training. It reveals that the adapter influences deep layers more than shallow layers and that the adapters al≤2 for the prefix area encode more information than the prediction area al>2 .
Impact of Different Mask Patterns. During the ablation study, we utilize three different mask patterns, as illustrated in Figure 4, and report the FAD values of inpainted audios in Table 4. The context becomes more continuous, and the gap to be filled becomes shorter as we progress from Mask Pattern 1 to Mask Pattern 3. The results indicate that our model is highly robust to different mask structures and demonstrates Table 4: The FAD values of generated audio with different mask patterns. A lower value indicates higher audio quality.
| Mask 1 | Mask 2 | Mask 3 | |
|---|---|---|---|
| Drum-AIR | 1.423 | 1.442 | 1.467 |
| VampNet | 2.910 | 2.390 | 2.091 |
| Mask 1 | Mask 2 | Mask 3 | |
|---|---|---|---|
| Drum-AIR | 1.606 | 1.673 | 1.759 |
| VampNet | 3.689 | 3.496 | 3.336 |
a promising long-gap inpainting capability. Conversely, the baseline model's performance deteriorates as the masked gap lengthens.
5 Conclusions
In this paper, we propose a novel Parameter-Efficient FineTuning (PEFT) method and apply it to MusicGen. It enables the model to inpaint arbitrary segments of music, while retaining the generation quality of MusicGen. Furthermore, we introduce frame-level content-based controls during finetuning, and demonstrate it with conditional generation tasks given the drum track, chord sequence, or piano cover. The model shows improved performance over baseline methods on several metrics. The result shows strong usability and flexibility for future music editing tools.
There are several potential improvements for the method. First, the unmasked infilling context weakens the effectiveness of the text prompt for MusicGen. A different fine-tuning setting might be required to resolve the problem. Other future works include introducing more content-based controls, as well as conditional generation based on multiple contentbased controls simultaneously.
Acknowledgments
This work was supported in part through the NYU and NYUSH IT High Performance Computing resources, services, and staff expertise.
@inproceedings{ijcai2024p851,
  title     = {Arrange, Inpaint, and Refine: Steerable Long-term Music Audio Generation and Editing via Content-based Controls},
  author    = {Lin, Liwei and Xia, Gus and Zhang, Yixiao and Jiang, Junyan},
  booktitle = {Proceedings of the Thirty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-24}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Kate Larson},
  pages     = {7690--7698},
  year      = {2024},
  month     = {8},
  note      = {AI, Arts & Creativity},
  doi       = {10.24963/ijcai.2024/851},
  url       = {https://doi.org/10.24963/ijcai.2024/851},
}
TY - CPAPER TI - Arrange, Inpaint, and Refine: Steerable Long-term Music Audio Generation and Editing via Content-based Controls AU - Lin, Liwei AU - Xia, Gus AU - Zhang, Yixiao AU - Jiang, Junyan T2 - Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, IJCAI-24 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2024 SP - 7690 EP - 7698 DO - 10.24963/ijcai.2024/851 UR - https://doi.org/10.24963/ijcai.2024/851 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





