
CrossVTON: Mimicking the Logic Reasoning on Cross-Category Virtual Try-On Guided by Tri-Zone Priors
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 1711-1719.
https://doi.org/10.24963/ijcai.2025/191
Keywords
- Computer Vision: CV: Image and video synthesis and generation
Abstract
Despite remarkable progress in image-based virtual try-on systems, generating realistic and robust fitting images for cross-category virtual try-on remains a challenging task. The primary difficulty arises from the absence of human-like reasoning, which involves addressing size mismatches between garments and models while recognizing and leveraging the distinct functionalities of various regions within the model images. To address this issue, we draw inspiration from human cognitive processes and disentangle the complex reasoning required for cross-category try-on into a structured framework. This framework systematically decomposes the model image into three distinct regions: try-on, reconstruction, and imagination zones. Each zone plays a specific role in accommodating the garment and facilitating realistic synthesis. To endow the model with robust reasoning capabilities for cross-category scenarios, we propose an iterative data constructor. This constructor encompasses diverse scenarios, including intra-category try-on, any-to-dress transformations (replacing any garment category with a dress), and dress-to-any transformations (replacing a dress with another garment category). Utilizing the generated dataset, we introduce a tri-zone priors generator that intelligently predicts the try-on, reconstruction, and imagination zones by analyzing how the input garment is expected to align with the model image. Guided by these tri-zone priors, our proposed method, CrossVTON, achieves state-of-the-art performance, surpassing existing baselines in both qualitative and quantitative evaluations. Notably, it demonstrates superior capability in handling cross-category virtual try-on, meeting the complex demands of real-world applications.
- [Chen et al., 2024] Mengting Chen, Xi Chen, Zhonghua Zhai, Chen Ju, Xuewen Hong, Jinsong Lan, and Shuai Xiao. Wear-any-way: Manipulable virtual try- on via sparse correspondence alignment. arXiv preprint arXiv:2403.12965, 2024.
- [Choi et al., 2021] Seunghwan Choi, Sunghyun Park, Min- soo Lee, and Jaegul Choo. Viton-hd: High-resolution vir- tual try-on via misalignment-aware normalization. In Pro- ceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 14131-14140, 2021.
- [Choi et al., 2024] Yisol Choi, Sangkyung Kwak, Kyungmin Lee, Hyungwon Choi, and Jinwoo Shin. Improving diffu- sion models for virtual try-on. ECCV, 2024.
- [Dong et al., 2019] Haoye Dong, Xiaodan Liang, Xiaohui Shen, Bochao Wang, Hanjiang Lai, Jia Zhu, Zhiting Hu, and Jian Yin. Towards multi-pose guided virtual try-on network. In Proceedings of the IEEE/CVF international conference on computer vision, pages 9026-9035, 2019.
- [Ge et al., 2021a] Chongjian Ge, Yibing Song, Yuying Ge, Han Yang, Wei Liu, and Ping Luo. Disentangled cycle consistency for highly-realistic virtual try-on. In Proceed- ings of the IEEE/CVF conference on computer vision and pattern recognition, pages 16928-16937, 2021.
- [Ge et al., 2021b] Yuying Ge, Yibing Song, Ruimao Zhang, Chongjian Ge, Wei Liu, and Ping Luo. Parser-free virtual try-on via distilling appearance flows. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 8485-8493, 2021.
- [Goodfellow et al., 2020] Ian Goodfellow, Jean Pouget- Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Gen- erative adversarial networks. Communications of the ACM, 63(11):139-144, 2020.
- [Gou et al., 2023] Junhong Gou, Siyu Sun, Jianfu Zhang, Jianlou Si, Chen Qian, and Liqing Zhang. Taming the power of diffusion models for high-quality virtual try-on with appearance flow. In Proceedings of the 31st ACM In- ternational Conference on Multimedia, pages 7599-7607, 2023.
- [Han et al., 2018] Xintong Han, Zuxuan Wu, Zhe Wu, Ruichi Yu, and Larry S Davis. Viton: An image-based virtual try-on network. In Proceedings of the IEEE con- ference on computer vision and pattern recognition, pages 7543-7552, 2018.
- [Han et al., 2019] Xintong Han, Xiaojun Hu, Weilin Huang, and Matthew R Scott. Clothflow: A flow-based model for clothed person generation. In Proceedings of the IEEE/CVF international conference on computer vision, pages 10471-10480, 2019.
- [He et al., 2022] Sen He, Yi-Zhe Song, and Tao Xiang. Style-based global appearance flow for virtual try-on. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 3470-3479, 2022.
- [Hu et al., 2024] Xiaobin Hu, Xu Peng, Donghao Luo, Xi- aozhong Ji, Jinlong Peng, Zhengkai Jiang, Jiangning Zhang, Taisong Jin, Chengjie Wang, and Rongrong Ji. Diffumatting: Synthesizing arbitrary objects with matting- level annotation. arXiv preprint arXiv:2403.06168, 2024.
- [Issenhuth et al., 2020] Thibaut Issenhuth, Jérémie Mary, and Clément Calauzenes. Do not mask what you do not need to mask: a parser-free virtual try-on. In Computer Vision-ECCV 2020: 16th European Conference, Glasgow, UK, August 23-28, 2020, Proceedings, Part XX 16, pages 619-635. Springer, 2020.
- [Jiang et al., 2024] Boyuan Jiang, Xiaobin Hu, Donghao Luo, Qingdong He, Chengming Xu, Jinlong Peng, Jiangn- ing Zhang, Chengjie Wang, Yunsheng Wu, and Yanwei Fu. Fitdit: Advancing the authentic garment details for high- fidelity virtual try-on. arXiv preprint arXiv:2411.10499, 2024.
- [Kim et al., 2024] Jeongho Kim, Guojung Gu, Minho Park, Sunghyun Park, and Jaegul Choo. Stableviton: Learning semantic correspondence with latent diffusion model for virtual try-on. In Proceedings of the IEEE/CVF Confer- ence on Computer Vision and Pattern Recognition, pages 8176-8185, 2024.
- [Lee et al., 2022] Sangyun Lee, Gyojung Gu, Sunghyun Park, Seunghwan Choi, and Jaegul Choo. High-resolution virtual try-on with misalignment and occlusion-handled conditions. In European Conference on Computer Vision, pages 204-219. Springer, 2022.
- [Li et al., 2024] Yuhan Li, Hao Zhou, Wenxiang Shang, Ran Lin, Xuanhong Chen, and Bingbing Ni. Anyfit: Control- lable virtual try-on for any combination of attire across any scenario. arXiv preprint arXiv:2405.18172, 2024.
- [Liang et al., 2024] Yujie Liang, Xiaobin Hu, Boyuan Jiang, Donghao Luo, Kai Wu, Wenhui Han, Taisong Jin, and Chengjie Wang. Vton-handfit: Virtual try-on for arbi- trary hand pose guided by hand priors embedding. arXiv preprint arXiv:2408.12340, 2024.
- [Liu et al., 2024] Yu Liu, Mingbo Zhao, Zhao Zhang, Yup- ing Liu, and Shuicheng Yan. Arbitrary virtual try-on net- work: Characteristics preservation and tradeoff between body and clothing. ACM Transactions on Multimedia Computing, Communications and Applications, 20(5):1- 23, 2024.
- [Men et al., 2020] Yifang Men, Yiming Mao, Yuning Jiang, Wei-Ying Ma, and Zhouhui Lian. Controllable person im- age synthesis with attribute-decomposed gan. In Proceed- ings of the IEEE/CVF conference on computer vision and pattern recognition, pages 5084-5093, 2020.
- [Minar et al., 2020] Matiur Rahman Minar, Thai Thanh Tuan, Heejune Ahn, Paul Rosin, and Yu-Kun Lai. Cp- vton+: Clothing shape and texture preserving image-based virtual try-on. In CVPR workshops, volume 3, pages 10- 14, 2020.
- [Morelli et al., 2022] Davide Morelli, Matteo Fincato, Mar- cella Cornia, Federico Landi, Fabio Cesari, and Rita Cuc- chiara. Dress code: High-resolution multi-category vir- tual try-on. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 2231- 2235, 2022.
- [Morelli et al., 2023] Davide Morelli, Alberto Baldrati, Giuseppe Cartella, Marcella Cornia, Marco Bertini, and Rita Cucchiara. Ladi-vton: Latent diffusion textual- inversion enhanced virtual try-on. In Proceedings of the 31st ACM International Conference on Multimedia, pages 8580-8589, 2023.
- [Rombach et al., 2022] Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, and Björn Ommer. High-resolution image synthesis with latent diffusion models. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 10684-10695, 2022.
- [Ruiz et al., 2023] Nataniel Ruiz, Yuanzhen Li, Varun Jam- pani, Yael Pritch, Michael Rubinstein, and Kfir Aber- man. Dreambooth: Fine tuning text-to-image diffusion models for subject-driven generation. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 22500-22510, 2023.
- [Saharia et al., 2022] Chitwan
- Saharia, William Chan, Saurabh Saxena, Lala Li, Jay Whang, Emily L Denton, Kamyar Ghasemipour, Raphael Gontijo Lopes, Burcu Karagol Ayan, Tim Salimans, et al. Photorealistic text-to-image diffusion models with deep language un- derstanding. Advances in neural information processing systems, 35:36479-36494, 2022.
- [Sun et al., 2024] Ke Sun, Jian Cao, Qi Wang, Linrui Tian, Xindi Zhang, Lian Zhuo, Bang Zhang, Liefeng Bo, Wenbo Zhou, Weiming Zhang, et al. Outfitanyone: Ultra-high quality virtual try-on for any clothing and any person. arXiv preprint arXiv:2407.16224, 2024.
- Kolors Team. Kolors: Effective training of diffusion model for photorealistic text-to-image synthesis. arXiv preprint, 2024.
- [Wang et al., 2018] Bochao Wang, Huabin Zheng, Xiaodan Liang, Yimin Chen, Liang Lin, and Meng Yang. Toward characteristic-preserving image-based virtual try-on net- work. In Proceedings of the European conference on com- puter vision (ECCV), pages 589-604, 2018.
- [Xie et al., 2023] Zhenyu Xie, Zaiyu Huang, Xin Dong, Fuwei Zhao, Haoye Dong, Xijin Zhang, Feida Zhu, and Xiaodan Liang. Gp-vton: Towards general purpose virtual try-on via collaborative local-flow global-parsing learn- ing. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 23550- 23559, 2023.
- [Xu et al., 2024] Yuhao Xu, Tao Gu, Weifeng Chen, and Chengcai Chen. Ootdiffusion: Outfitting fusion based la- tent diffusion for controllable virtual try-on. arXiv preprint arXiv:2403.01779, 2024.
- [Yang et al., 2020] Han Yang, Ruimao Zhang, Xiaobao Guo, Wei Liu, Wangmeng Zuo, and Ping Luo. Towards photo- realistic virtual try-on by adaptively generating-preserving image content. In Proceedings of the IEEE/CVF confer- ence on computer vision and pattern recognition, pages 7850-7859, 2020.
- [Yang et al., 2023] Zhijing Yang, Junyang Chen, Yukai Shi, Hao Li, Tianshui Chen, and Liang Lin. Occlumix: To- wards de-occlusion virtual try-on by semantically-guided mixup. IEEE Transactions on Multimedia, 25:1477-1488, 2023.
- [Zeng et al., 2024] Jianhao Zeng, Dan Song, Weizhi Nie, Hongshuo Tian, Tongtong Wang, and An-An Liu. Cat- dm: Controllable accelerated virtual try-on with diffusion model. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 8372- 8382, 2024.
- [Zhang et al., 2024] Xuanpu Zhang, Dan Song, Pengxin Zhan, Qingguo Chen, Zhao Xu, Weihua Luo, Kaifu Zhang, and Anan Liu. Boow-vton: Boosting in-the-wild virtual try-on via mask-free pseudo data training. arXiv preprint arXiv:2408.06047, 2024.
- [Zhu et al., 2023] Luyang Zhu, Dawei Yang, Tyler Zhu, Fit- sum Reda, William Chan, Chitwan Saharia, Mohammad Norouzi, and Ira Kemelmacher-Shlizerman. Tryondiffu- sion: A tale of two unets. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 4606-4615, 2023.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The significant expansion of e-commerce has led to a continuous demand for a more convenient and customized shopping experience. Image-based virtual try-on (VTON) has become a popular method for producing realistic images of human models dressed in particular clothing items, thus improving the consumer shopping experience. Recently, numerous researchers [Dong et al., 2019; Ge et al., 2021a; Issenhuth et al., 2020; Han et al., 2019; Han et al., 2018; He et al., 2022; Minar et al., 2020; Wang et al., 2018; Yang et al., 2020] have devoted considerable effort to attaining more lifelike and photorealistic virtual try-on outcomes.
As a predominant generative method, Diffusion [Rombach et al., 2022] shows high authenticity generation and rich texture-wise maintenance compared with generative adversarial networks (GANs) [Goodfellow et al., 2020]. Despite these advancements, Diffusion-based approaches often struggle with the cross-category virtual try-on [Kim et al., 2024; Sun et al., 2024; Morelli et al., 2023; Gou et al., 2023] (e.g., long skirt ↔ upper jacket, short sleeves ↔ long skirt) widely existing in the real-world scenarios. Although Anyfit [Li et al., 2024] and AVTON [Liu et al., 2024] have attempted to mitigate the cross-category virtual try-on, they mainly adopt the adjustment on the mask strategy to fit the length of target garments. To handle the challenging cross-category cases (e.g., long skirt ↔ upper jacket), these methods usually require users to specify one of three major categories (i.e., upper garments, lower garments, and dresses) to distinguish the area to be processed, rather than adaptively determine the area based on the model image and garment image. Such manual intervention still suffers from the performance deterioration and the lack of reasoning ability to reasonably paint the imagination zone, as shown in Fig. 1.
The hidden reason for this obstacle lies in the lack of logical reasoning about how the target garment is dressed on the model and split the picture into the different zones, i.e., the reconstruction zone that is learning from the model image, the try-on zone that is referring to the garment image, and imagination zone that developing the imaginative potential of Diffusion to paint on. Thus, to enhance cross-category try-on performance in more practical and diverse real-world scenarios, it is both meaningful and essential for the try-on model to develop logical reasoning and adaptively learn the variable tri-regions based on the input garment and model images.
Following this research line, we propose a novel pipeline Model Garment Binary Prior Binary Prior Result Our Tri-zone Prior Our Result to prompt the tri-zone priors via mimicking logic reasoning for cross-category try-on. Such a pipeline includes the iterative cross-category data construction and progressively training manner guided by tri-zone priors. Basically, we classify the cross-category cases into the intra-category, Any-to-Dress and Dress-to-Any cross-category depending on the length and category of the target garments. Given a model and a garment, we customize a tri-zone priors generator to reason the different function zones as a constraint for better reasonable cross-category try-on. Typically, the imagination region is required when the clothing in the original model image does not fully cover the target garment area. By leveraging the masks of these three regions, it is possible to eliminate the need for manual specification of the clothing category in the virtual try-on task, thereby facilitating cross-category try-on.
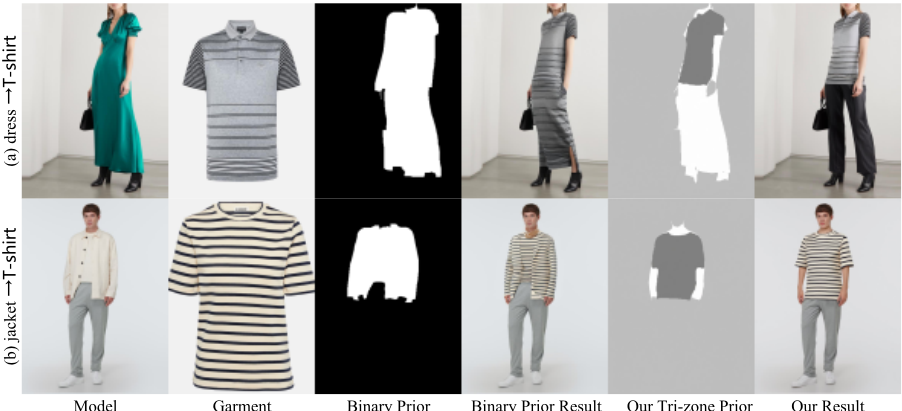
Figure 1: Tri-zone prior decomposes the content of the model image to determine whether it belongs to the try-on, reconstruction, or imagination zone. Different from commonly used binary mask priors, such priors can endow our CrossVTON with the capability of crosscategory virtual try-on.
Considering that the existing models fail to directly construct challenging dress-to-any cross-category cases (e.g., long skirt → upper or lower), we tailor an iterative crosscategory data construction to progressively compose the quadruplets data from simple to more complex cases. The iterative cross-category data construction is first based on the off-the-shelf try-on model and then adopts the maskadjust operator (i.e., stretch or shorten mask) to collect intracategory data (e.g., upper → upper) and Any-to-Dress crosscategory data (i.e., change the any category with dress) to compose quadruplets data (e.g., synthetic model with longskirt, short garment, real-model with short garment, tri-zone prior ground-truth). After train the CrossVTON with the ability with the intra-category and Dress-to-Any cross-category try-on, we then use this pre-trained CrossVTON to obtain the Dress-to-Any cross-category quadruplets data (i.e., real model with long-skirt, long garment, synthetic-model with short garment, tri-zone prior ground-truth). With the aid of such an iterative cross-category data construction, we finally progressively train two-stage CrossVTON to both satisfy the intra-category and cross-category virtual try-on. To mitigate the performance deterioration caused by the synthesis image, we always obey the principle that the real image is regarded as the ground-truth and the synthesis image is only as the input. Such a principle encourages the virtual try-on results close to the real data distribution. Overall, the main contributions of this paper can be summarized as follows:
- A novel tri-zone priors are proposed to mimic the logic reasoning to distinguish different functionalities of various zones (i.e., try-on, reconstruction, or imagination area) after considering the cross-category inputs.
- An iterative cross-category data scheme is designed to successively generate quadruplets data for cross-category virtual try-on.
- A progressively training manner guided by tri-zone priors to enable the CrossVTON with the capability of crosscategory virtual try-on.
- Extensive qualitative and quantitative evaluations have clearly demonstrated CrossVTON's superiority over stateof-the-art virtual try-on models, particularly in managing cross-category virtual try-on scenarios.
2 RelatedWork
Image-based Virtual Try-on. GAN-based methods [Lee et al., 2022; Men et al., 2020; Xie et al., 2023; Yang et al., 2023] have been extensively explored for natural image generation but often struggle to produce high-fidelity outfitted images. With the rapid progress of Text-to-Image diffusion models [Saharia et al., 2022; Ruiz et al., 2023; Hu et al., 2024], recent studies [Chen et al., 2024; Liang et al., 2024; Team, 2024; Zhu et al., 2023] have adopted pre-trained diffusion models as generative priors for virtual try-on. Approaches like IDMVTON [Choi et al., 2024] and FitDiT [Jiang et al., 2024] refine inpainting diffusion models to preserve details and enhance image realism. However, despite their success in generating high-quality results, these methods face significant challenges in cross-category virtual try-on due to the lack of priors necessary for reasoning about size mismatches, a key challenge in real-world applications. Motivated by this, we present a novel CrossVTON method here.
Cross-category Virtual Try-on. Cross-category virtual tryon remains a challenging yet under-explored problem, limiting the development of generalized solutions. AVTON [Liu et al., 2024] introduces a limbs prediction module for basic cross-category cases, while AnyFit [Li et al., 2024] uses an adaptive mask boost to refine masks during inference. However, these methods only handle simple scenarios (e.g., long sleeves ↔ short sleeves) and struggle with complex cases such as long skirts ↔ upper jackets. To address this, we propose a tri-zone prior framework to emulate logical reasoning, enabling differentiation of functional zones in cross-category try-on.
Image Synthesis of Try-on. Try-on training typically requires paired data where the same individual appears in different outfits with identical ID, pose, and background, varying only the garment. However, such data is challenging to collect, prompting research into curated data constructors for specific try-on tasks. WUTON [Issenhuth et al., 2020] and PF-AFN [Ge et al., 2021b] adopt a student-teacher paradigm, using parsing-based reconstruction to train models without relying on parsing during inference. While these methods leverage realistic try-on images, they are limited by data scale and scenario diversity. Recently, BooW-VTON [Zhang et al., 2024] generates pseudo triplet pairs using off-the-shelf IDM models and employs wild data augmentation for mask-free virtual try-on. However, these methods still struggle with cross-category and size-mismatching scenarios in virtual tryon data construction, which are tackled in this paper.
3 Method
3.1 Tri-zone Priors for Virtual Try-on
Existing diffusion-based methods typically regard virtual tryon as a conditional inpainting task. The mask is only derived from the model image rather than comprehensively taking into account how the garment is dressed on the model. Moreover, the mask only focus on two types of zone: reconstruction region and generation region without the capability to reason the imagination zone.
To tackle the aforementioned problems, we propose that virtual try-on task actually needs to distinguish three types of regions: The try-on region Z tryon , which indicates the area covered by the target clothing worn on the model. This area should comprehensively take into account the information of both the model and the garment. It should maintain consistency with the model in aspects of posture and body shape, and with the clothing in terms of pattern. The reconstruction region Z recon which represents the area that ought to be exactly the same as the original image, typically including the face, hands, feet, and background. The imagination region Z imagi which reveals the area that needs to be complemented by the model through its imaginative faculty, and the outcome of this supplementation should be as harmonious as feasible with the other two regions. It is worth noting that among the three types of regions, the try-on region and the reconstruction region are essential. Typically, the imagination region is necessary when the clothing in the original model image does not fully cover the new clothing area. By utilizing the masks of these three regions, it becomes possible to avoid manually specifying the clothing category in the virtual try-on task, thereby enabling cross-category try-on. Furthermore, these three types of regions should adaptively determined based on the model image and the target clothing.
3.2 Model Structure of CrossVTON
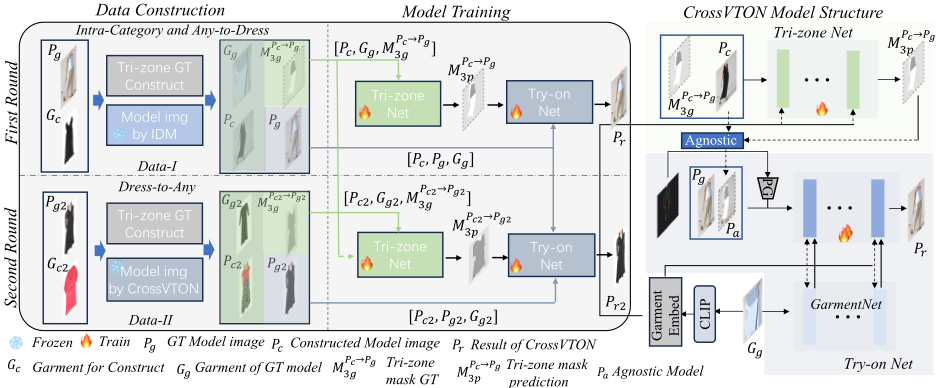
As shown in Fig. 2, we design a two-stage pipeline, termed as CrossVTON for cross-category virtual try-on. For the first stage, a tri-zone mask is generated via Tri-zone Net to distinguish three types of regions. Subsequently, in the second stage, leveraging the tri-zone mask as a prior, the process of try-on is executed in a manner of inpainting via Try-on Net.
The objective of the Tri-zone Net is to generate a reasonable tri-zone mask given a model and target clothing. As shown in Fig. 2, we adopt SD3 as the backbone. To more effectively extract high-level semantic information such as the pattern and length of the clothing, we utilize the image encoder of CLIP to extract clothing features and then substitute the text embedding in the original SD3 with these features. The goal of the Try-on Net is to obtain a natural and harmonious try-on result given a model, target clothing, and the tri-zone prior. As depicted in Fig. 2, we also adopt SD3 as backbone. Since the focus of the second stage is on maintaining the details of the clothing, which corresponds to low-level features, we employ GarmentNet to extract clothing features. The structure of GarmentNet is identical to that of SD3, and it is initialized with the weights of SD3. Subsequently, the clothing feature is fused to latent feature by concatenating K and V of the clothing features and then calculating selfattention. The training loss for first and second stage are both consistent with that of SD3,
where zt = (1 - t)z0 + tϵ is the noisy latent, and w(t) is a weighting function at each timestep t.
Training CrossVTON for tri-zone try-on relies on a large amount of quadruple data. The quadruple consists of: 1) a model picture Pa, where the model wears clothing of pattern a; 2) a model picture Pb, with the model wearing clothing of pattern b; 3) the clothing of pattern b; and 4) the tri-zone mask M Pa→Pb that corresponds to substituting the clothing in Pa with that in Pb. Pa and Pb share the same model, posture, and background, with the only variance being the clothing. Clothing a and clothing b can be either from the same category or different categories. A model trained in this fashion exhibits excellent generalization capabilities for both in-category and cross-category try-on.
However, existing virtual try-on datasets generally consist of pairs of model image and their corresponding clothing. This is merely a subset of the quadruple data, specifically the model picture Pb and the clothing b. Even with the cooperation of the clothing model, it remains challenging to acquire Pa and M (Pa→Pb) . Therefore, the quadruple data can only be obtained through data construction methods. To align with the model training process, we denote the ground-truth model image during model training as Pg, the corresponding garment image as Gg, the model image constructed using Pg and Gc as Pc, and the ground-truth tri-zone mask for try-on the model image Pc with Gg as M Pc→Pg 3g . Consequently, the quadruple data is represented as [Pc, Pg,Gg,M Pc→Pg 3g ].
| Pc | ||||||||
|---|---|---|---|---|---|---|---|---|
| Upper | Dress | Lower | ||||||
| Short | Long | Short | Long | Short | Long | |||
| Upper | Short Long | IDM IDM S | IDM S IDM | IDM | N/A | |||
| Pg | Dress | Short Long | CrossVTON | IDM IDM S | IDM S IDM | CrossVTON | ||
| Lower | Short Long | N/A | IDM S | IDM | IDM | |||
When training the first-stage model, Pc is utilized as the input model image, and the garment image Gg is employed as the input clothing. The model predicts the tri-zone mask M Pc→Pg 3p , with M Pc→Pg 3g acting as the ground-truth for supervision during training. When training the second-stage model, the model takes the model image Pc, the ground-truth clothing image Gg, and the tri-zone mask M Pc→Pg 3p predicted in first stage as inputs. Subsequently, the model predicts the try-on result Pr, with Pg serving as the ground-truth for supervision in the training process.
3.3 Progressive Learning Paradigm
For the quadruple data used in training, the pattern differences between Pc and Pg should encompass as many scenarios as possible. As shown in Table 1, we categorize clothing based on types and lengths. This classification can generate diverse combinations of quadruples. Some of these quadruples can be constructed using existing mask-based methods or combined with some mask strategies. While for the remaining quadruples, it do not work. Nevertheless, these quadruples can be constructed by leveraging the try-on model trained with the previously constructed quadruples. Therefore, we propose a progressive learning paradigm (Fig.2) that includes two rounds of data construction and two rounds of model training. First, we construct data using existing mask-based methods and their improved strategies. Then, we conduct the first-round model training using these data. Subsequently, we use the well-trained model for the second-round data construction. Finally, we perform the second-round training using all the constructed data.
First Round Data Construction
Intra-Category with match size and any-to-dress, by IDM. As shown by orange in Tab.1, when Gc and Gg fall into the same category and they have matched size (e.g. both Gc and Gg are short T-shirt), or when Gc can largely cover Gg (e.g. Gc is dress and Gg is short T-shirt), existing mask-based methods can already yield satisfactory results with specified mask. Therefore, we can directly utilize these methods to construct Pc by inputting Pg and Gc. In this paper, we employ IDM for data construction. The mask M (Pg→Pc) 2 employed by IDM discriminates two types of regions. The reconstruction region Z recon 2 denotes the area where Pc remains consistent with Pg, while the generation region Z gen 2 represents the area that is regenerated during the construction process. Obtain tri-zone GT. As shown in Fig. 3, to construct the mask M (Pc→Pg) 3g required for training CrossVTON, we actually need to distinguish three types of regions. The try-on region Z tryon 3g represents the area of the clothing Gg in Pg, which can be obtained by extracting the Gg part Z Gg Pg from the parsing map PMg of Pg, i.e. Z tryon 3g = Z Gg Pg . The imagination region Z imagi 3g represents the area that the model needs to imagine and supplement reasonably. It can be obtained by taking the intersection of the generation region Z gen 2 during construction and the foreground area Z fPc of Pc segment mask SMc, and then subtracting the intersection with the try-on region Z tryon 3g , i.e. Z imagi 3g = (Z gen 2 ∩ Z fPc ) - Z tryon 3g . The reconstruction region Z recon 3g represents the area that should be consistent with the input Pc, it is the area excluding Z tryon 3g and Z imagi 3g .
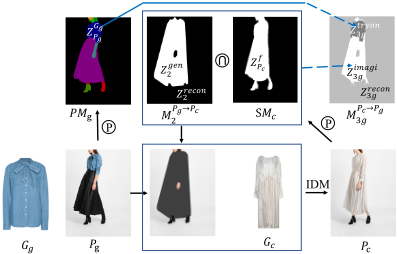
Intra-category with mismatch size, by IDM S. As indicated by yellow in Tab.1, these size-mismatch cases can't be handle by IDM. Therefore, we design dedicated data construction method for such scenarios. The following uses tops as an example for illustration. For the scenario where Gg is a short top and Gc is a long top, we leverage the densepose of model Pg to shift the lower boundary of Z gen 2 downward, thereby obtaining Z gen↓ 2 . Based on the new mask M (Pg→Pc)↓ 2 , we employ IDM to conduct the virtual try-on process, resulting in the model image P ↓ c depicting the model wearing a longer top. For the case where Gg is a long top and Gc is a short top, we randomly shift the lower boundary of Z gen 2 upward to get Z gen↑ 2 . Subsequently, based on the new mask M (Pg→Pc)↑ 2 , we utilize IDM to conduct the tryon process, thus obtaining the model P ↑′ c wearing a shorter top. Nevertheless, the content within the corresponding area of Z gen 2 -Z gen↑ 2 in P ↑′ c remains the same as that in Pg. Ultimately, we employ an inpainting model to complete this area, resulting in a reasonable P ↑ c . The construction of M (Pc→Pg) 3g follows the same approach as the IDM-based construction method.
First Round Model Training
As shown by red in Tab.1, for these categories, existing methods are unable to construct an upper/lower-garment model from a dress-wearing model. Specifically, the constructed model image is not reasoning or it is exactly the original model image. However, we have constructed the reverse data in the first round data construction. Therefore, we can utilize these quadruple data to train our CrossVTON which can generate reasonable try-on results when provided with a dress model and an upper/lower-garment.
Second Round Data Construction
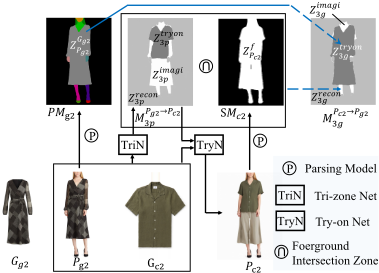
Dress-to-any, By CrossVTON. To distinguish from the first round, elements used in the second round in the following text are marked with subscript 2. As shown in Fig.4, based on the CrossVTON obtained from the first round training, using the dress-wearing model Pg2 and the upper/lowergarment Gc2 as inputs, we can batch-construct Pc2 with the upper/lower-garment on. The mask M (Pg2→Pc2) 3p predicted by the first stage of CrossVTON consists of three types of regions: the try-on region Z tryon 3p , the reconstruction region Z recon 3p , and the imagination region Z imagi 3p . When constructing M (Pc2→Pg2) 3g , we take the parsed Gg2 region Z Gg2 Pg2 which from the parsing map PMg2 as Z tryon 3g , i.e. Z tryon 3g = Z Gg2 Pg2 . The imagination area Z imagi 3p can be obtained using Z tryon 3p , Z imagi 3p , Z fPc2 and Z tryon 3p , i.e. Z imagi 3g = (Z tryon 3p ∪Z imagi 3p ∩ Z fPc2 ) - Z tryon 3g . While the reconstruction region Z recon 3p is the remaining area.
Second Round Model Training
By training the model using all the data generated in the previous two stages, we can acquire the final model. This final model is able to support cross-category and intra-category (wether size match or not) try-on task.
4 Experiments
Dataset. We trained our model on two widely adopted virtual try-on datasets: VITON-HD [Choi et al., 2021] and DressCode [Morelli et al., 2022]. By combining model image and garment image from different category of DressCode, we construct a Cross-Category DressCode test set, namely CCDC which include 7200 test pairs. To more effectively assess the performance of cross-category clothing transfer, a dedicated test set for this purpose, named the Cross-Category Garment Dataset (CCGD), has been meticulously assembled. The CCGD encompasses eight distinct categories: long-tops, short-tops, long dresses, short dresses, long pants, short pants, long skirts, and short skirts. In total, it comprises 400 modelgarment pairs, 50 pairs for each category. The model and garment items from different categories are combined to compose 2000 test set pairs.
| Methods | DressCode | VITON-HD | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Paired | Paired | Unpaired | ||||||||||
| SSIM ↑ | LPIPS ↓ | FID ↓ | KID ↓ | Unpaired FID ↓ | KID ↓ | SSIM ↑ | LPIPS ↓ | FID ↓ | KID ↓ | FID ↓ | KID ↓ | |
| LaDI-VTON (2023) | 0.9025 | 0.0719 | 4.8636 | 1.5580 | 6.8421 | 2.3345 | 0.8763 | 0.0911 | 6.6044 | 1.0672 | 9.4095 | 1.6866 |
| StableVTON (2024) | - | - | - | - | - | - | 0.8665 | 0.0835 | 6.8581 | 1.2553 | 9.5868 | 1.4508 |
| OOTDiffusion (2024) | 0.8975 | 0.0725 | 3.9497 | 0.7198 | 6.7019 | 1.8630 | 0.8513 | 0.0964 | 6.5186 | 0.8961 | 9.6733 | 1.2061 |
| IDM-VTON (2024) | 0.9228 | 0.0478 | 3.8001 | 1.2012 | 5.6159 | 1.5536 | 0.8806 | 0.0789 | 6.3381 | 1.3224 | 9.6114 | 1.6387 |
| CatVTON (2024) | 0.9011 | 0.0705 | 3.2755 | 0.6696 | 5.4220 | 1.5490 | 0.8694 | 0.0970 | 6.1394 | 0.9639 | 9.1434 | 1.2666 |
| CrossVTON (Ours) | 0.9130 | 0.0470 | 2.7515 | 0.5229 | 5.0465 | 1.2368 | 0.8550 | 0.0786 | 5.7171 | 0.8804 | 8.6596 | 0.8120 |
Person Garment Ours IDM
CatVTON LaDI-VTON OOTDiffusion
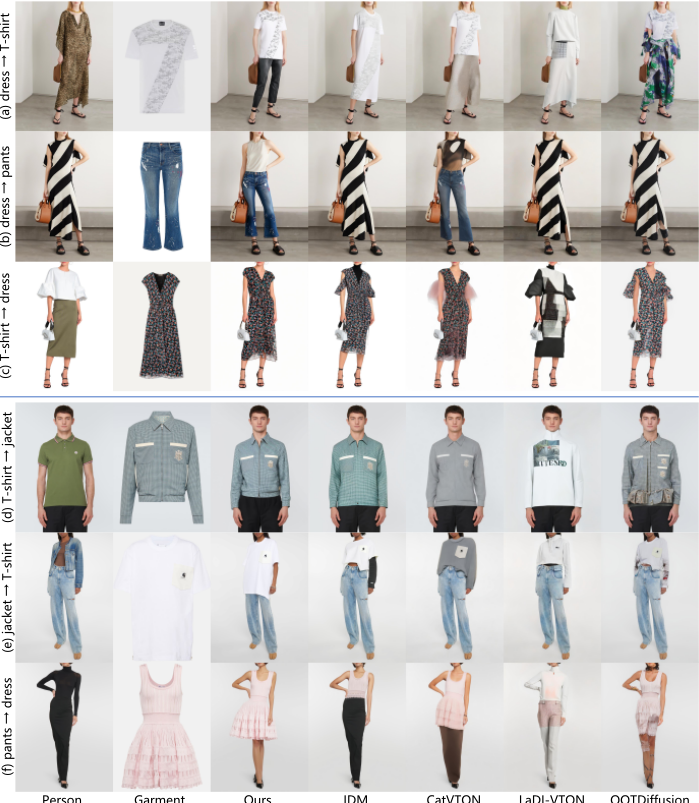
Figure 5: Visual results on CCDC (top) and CCGD (bottom). Best viewed when zoomed in.
Baselines. We compare CrossVTON with five SOTA diffusion-based virtual try-on methods: LaDI-VTON [Morelli et al., 2023], StableVTON [Kim et al., 2024], OOTDiffusion [Xu et al., 2024], IDM-VTON [Choi et al., 2024], and CatVTON [Zeng et al., 2024].
Evaluation. Through extensive experimentation, we discovered that given a model, clothing, and the outcome of a try-on model, Qwen-VL-Max can precisely determine whether the clothing transfer result is correct. Consequently, we utilize the accuracy rate provided by this model (i.e., the ratio of the number of correct results to the total number of samples in the entire test set) to evaluate the model's proficiency in cross-category try-on.
Implementation details. We utilize the official training set of VITON-HD and DressCode to construct training quadruple VITONHD-CT and DressCode-CT respectively. The former only has intra-category quadruple while the later has intraand cross-category quadruple. To validate the performance of cross-category clothing transfer, we combine VTONHD-CT and DressCode-CT for training. Then, we conduct evaluations on the cross-category test sets CCDC and CCGD. The qualitative results are also based on this model. All models are trained uniformly with a batch size of 32, employing the AdamW optimizer at a learning rate of 3 × 10⁻⁵ .
| Methods | Cross-Category DressCode | CCGD | ||||
|---|---|---|---|---|---|---|
| FID ↓ | KID ↓ | Acc ↑ | FID ↓ | KID ↓ | Acc ↑ | |
| LaDI-VTON | 34.53 | 23.11 | 12.54 | 52.2 | 20.16 | 12.65 |
| IDM-VTON | 18.51 | 9.31 | 45.04 | 39.99 | 8.22 | 45.85 |
| OOTDiffusion | 28.69 | 16.52 | 40.72 | 52.72 | 16.7 | 33.05 |
| CatVTON | 23.01 | 14.22 | 55.23 | 46.86 | 14.02 | 41.75 |
| Ours | 9.35 | 3.11 | 69.11 | 33.07 | 3.46 | 61.75 |
| Methods | FID ↓ | KID ↓ | Acc ↑ |
|---|---|---|---|
| Oursw/o Tri-zone | 36.29 | 4.99 | 57.05 |
| Oursmerge | 33.37 | 4.06 | 58.40 |
| Ours | 33.07 | 3.46 | 61.75 |
4.1 Quantitative results
As depicted in Tab. 2, for try-on task within the same category, in comparison with several recent methods, our approach significantly outperforms all baselines. This verifies that our model, which is primarily engineered for crosscategory try-on, also attains the SOTA level in conventional try-on tasks. For cross-category try-on, as illustrated in Tab. 3 CrossVTON has an advantage of 14% and 16% respectively over the second-best method on CCDC and CCGD, demonstrating its absolute leadership in this task.
4.2 Qualitative results
Fig.5 showcases a comparison of the visual effects of CrossVTON and other methods on CCDC and CCGD. Evidently, our method exhibits remarkable advantages across diverse crosscategory scenarios. (a) and (b) illustrate that CrossVTON is capable of managing try-on tasks like transforming a skirt into an upper-garment or lower-garment, which needs sound imagination capabilities. In contrast, other methods are incapable of handling these tasks. (c), and (f) reveal that CrossVTON can effectively preserve the pattern of the dress, regardless of the clothing initially worn by the model. In contrast, the results of other methods are influenced by the original clothing on the model, with the patterns differing substantially from the provided clothing. (d) and (e) demonstrate that when the category and length of the model's upper-garment vary from those of the given upper-garment, CrossVTON can consistently match the provided clothing adeptly, while other methods fall short in appropriately dealing with such cases.
4.3 Ablation Study
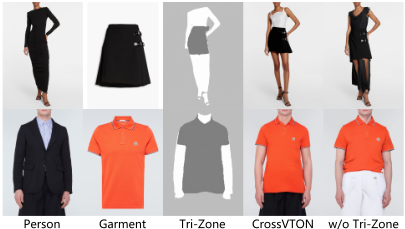
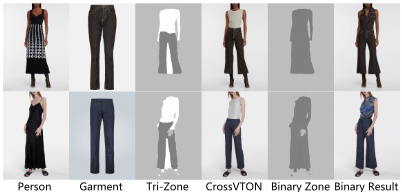
To validate the role of the three-region prior, we remove the first stage of CrossVTON and directly utlizing [Pct, Pgt, Cgt] to train a mask-free Try-on Net. As presented in the tab.4, compared with CrossVTON, the accuracy Acc drops significantly by 4.7%, and both FID and KID also declines substantially. Nevertheless, our mask-free model still holds a remarkable 11.2% edge over IDM. This clearly demonstrates the effectiveness of our progressive learning paradigm. As depicted in the fig. 6, the tri-zone prior can enhance the stability of the model. To validate the difference between the trizone and binary prior, we merge the try-on region and imagination region to form a binary prior and directly used for Try-on Net. As shown in the tab. 4, the binary prior leads to decrease on accuracy compared to the tri-zone prior, but still has a significant advantage over other methods. This indicates the tri-zone prior can provide more information to help try-on. It also demonstrates robustness of Try-on Net for different mask. Fig. 7 shows the visual comparison.
5 Conclusion
We propose novel tri-zone priors to emulate logical reasoning in distinguishing the distinct functionalities of various zones (i.e., try-on, reconstruction, or imagination zones) when considering cross-category inputs. Specifically, to endow the model with reasoning capabilities for cross-category scenarios, we also develop an iterative data constructor that encompasses key cases, including intra-category, any-to-dress, and dress-to-any virtual try-on. Through this iterative data construction process, our CrossVTON is progressively trained under the guidance of tri-zone priors, thereby acquiring the capability for cross-category virtual try-on.
Contribution Statement
All authors conceive the paper's methodology and experiments. Donghao Luo and Yujie Liang contribute equally to this work and should be considered co-first authors. Yanwei Fu is the corresponding author of this paper.
@inproceedings{ijcai2025p191,
  title     = {CrossVTON: Mimicking the Logic Reasoning on Cross-Category Virtual Try-On Guided by Tri-Zone Priors},
  author    = {Luo, Donghao and Liang, Yujie and Peng, Xu and Hu, Xiaobin and Jiang, Boyuan and Xu, Chengming and Jin, Taisong and Wang, Chengjie and Fu, Yanwei},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {1711--1719},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/191},
  url       = {https://doi.org/10.24963/ijcai.2025/191},
}
TY - CPAPER TI - CrossVTON: Mimicking the Logic Reasoning on Cross-Category Virtual Try-On Guided by Tri-Zone Priors AU - Luo, Donghao AU - Liang, Yujie AU - Peng, Xu AU - Hu, Xiaobin AU - Jiang, Boyuan AU - Xu, Chengming AU - Jin, Taisong AU - Wang, Chengjie AU - Fu, Yanwei T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 1711 EP - 1719 DO - 10.24963/ijcai.2025/191 UR - https://doi.org/10.24963/ijcai.2025/191 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





