
I-EDI: Robust Self-Evolution Agents via Verifiable Counterfactual Simulation
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 90-98.
https://doi.org/10.24963/ijcai.2026/11
Keywords
- Agent-based and Multi-agent Systems: Agent communication
- Natural Language Processing: Applications
- Agent-based and Multi-agent Systems: Agent theories and models
- Agent-based and Multi-agent Systems: Multi-agent learning
Abstract
Current self-evolution methods mostly chase recall, they learn from any trajectory that ends with the right answer, even when the path relies on a "lucky guess". Such reasoning appears valid in-distribution but often fails the moment the task shifts slightly. We argue that robust evolution implies Structural Invariance: a reasoning path is valid only if its core dependency graph remains isomorphic under counterfactual perturbations. I-EDI enforces this with Verifiable Counterfactual Simulation (VCS). Instead of treating data generation as mere "sample and filter," we treat it as an intervention. Unlike standard rejection sampling, VCS acts as a structural stress test: it accepts a reasoning trace only if it remains valid across generated counterfactuals (e.g., numerical perturbations, context shifts). While this strict filtering reduces the volume of training data (trading recall for precision), our experiments on MATH and GSM8K show it effectively prevents hallucination accumulation, achieving superior out-of-distribution generalization compared to baselines.
- [An et al., 2024] Shengnan An, Zexiong Ma, Siqi Cai, Zeqi Lin, Nanning Zheng, Jian-Guang Lou, and Weizhu Chen. Can llms learn from mistakes? an empirical study on rea- soning tasks. In Findings of the Association for Computa- tional Linguistics: EMNLP 2024, pages 833-854, 2024.
- [Chen, 2021] Mark Chen. Evaluating large language models trained on code. arXiv preprint arXiv:2107.03374, 2021.
- [Cobbe et al., 2021] Karl Cobbe, Vineet Kosaraju, Moham- mad Bavarian, Mark Chen, Heewoo Jun, Lukasz Kaiser, Matthias Plappert, Jerry Tworek, Jacob Hilton, Reiichiro Nakano, et al. Training verifiers to solve math word prob- lems. arXiv preprint arXiv:2110.14168, 2021.
- [Do et al., 2025] Cong Thanh Do, Rama Sanand Doddipatla, and Kate Knill. Effectiveness of chain-of-thought in dis- tilling reasoning capability from large language models. In Proceedings of the 18th International Natural Language Generation Conference, pages 833-845, 2025.
- [Du et al., 2025] Xinrun Du, Yifan Yao, Kaijing Ma, Bingli Wang, Tianyu Zheng, King Zhu, Minghao Liu, Yiming Liang, Xiaolong Jin, Zhenlin Wei, et al. Supergpqa: Scal- ing llm evaluation across 285 graduate disciplines. arXiv preprint arXiv:2502.14739, 2025.
- [Gao et al., 2025] Huan-ang Gao, Jiayi Geng, Wenyue Hua, Mengkang Hu, Xinzhe Juan, Hongzhang Liu, Shilong Liu, Jiahao Qiu, Xuan Qi, Yiran Wu, et al. A survey of self- evolving agents: On path to artificial super intelligence. arXiv preprint arXiv:2507.21046, 1, 2025.
- [He et al., 2024] Chaoqun He, Renjie Luo, Yuzhuo Bai, Shengding Hu, Zhen Thai, Junhao Shen, Jinyi Hu, Xu Han, Yujie Huang, Yuxiang Zhang, et al. Olympiad- bench: A challenging benchmark for promoting agi with olympiad-level bilingual multimodal scientific problems. In Proceedings of the 62nd Annual Meeting of the Associ- ation for Computational Linguistics (Volume 1: Long Pa- pers), pages 3828-3850, 2024.
- [Hendrycks et al., 2021] Dan Hendrycks, Collin Burns, Saurav Kadavath, Akul Arora, Steven Basart, Eric Tang, Dawn Song, and Jacob Steinhardt. Measuring mathemati- cal problem solving with the math dataset. arXiv preprint arXiv:2103.03874, 2021.
- [Huang et al., 2025] Chengsong Huang, Wenhao Yu, Xi- aoyang Wang, Hongming Zhang, Zongxia Li, Ruosen Li, Jiaxin Huang, Haitao Mi, and Dong Yu. R-zero: Self- evolving reasoning llm from zero data. arXiv preprint arXiv:2508.05004, 2025.
- [Kazemi et al., 2025] Mehran Kazemi, Bahare Fatemi, Hri- tik Bansal, John Palowitch, Chrysovalantis Anastasiou, Sanket Vaibhav Mehta, Lalit K Jain, Virginia Aglietti, Disha Jindal, Yuanzhu Peter Chen, et al. Big-bench ex- tra hard. In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 26473-26501, 2025.
- [Lee et al., 2024] Hojae Lee, Junho Kim, and SangKeun Lee. Mentor-kd: Making small language models better multi-step reasoners. arXiv preprint arXiv:2410.09037, 2024.
- [Lewkowycz et al., 2022] Aitor Lewkowycz, Anders An- dreassen, David Dohan, Ethan Dyer, Henryk Michalewski, Vinay Ramasesh, Ambrose Slone, Cem Anil, Imanol Schlag, Theo Gutman-Solo, et al. Solving quantitative rea- soning problems with language models. Advances in neu- ral information processing systems, 35:3843-3857, 2022.
- [Liang et al., 2025] Xuechen Liang, Meiling Tao, Yinghui Xia, Jianhui Wang, Kun Li, Yijin Wang, Yangfan He, Jing- song Yang, Tianyu Shi, Yuantao Wang, et al. Sage: Self- evolving agents with reflective and memory-augmented abilities. Neurocomputing, page 130470, 2025.
- [Lin et al., 2025] Xixun Lin, Yucheng Ning, Jingwen Zhang, Yan Dong, Yilong Liu, Yongxuan Wu, Xiaohua Qi, Nan Sun, Yanmin Shang, Kun Wang, et al. Llm-based agents suffer from hallucinations: A survey of taxonomy, meth- ods, and directions. arXiv preprint arXiv:2509.18970, 2025.
- [Liu et al., 2025] Bo Liu, Leon Guertler, Simon Yu, Zichen Liu, Penghui Qi, Daniel Balcells, Mickel Liu, Che- ston Tan, Weiyan Shi, Min Lin, et al. Spiral: Self- play on zero-sum games incentivizes reasoning via multi- agent multi-turn reinforcement learning. arXiv preprint arXiv:2506.24119, 2025.
- [Lu et al., 2023] Pan Lu, Hritik Bansal, Tony Xia, Jiacheng Liu, Chunyuan Li, Hannaneh Hajishirzi, Hao Cheng, Kai- Wei Chang, Michel Galley, and Jianfeng Gao. Mathvista: Evaluating mathematical reasoning of foundation models in visual contexts. arXiv preprint arXiv:2310.02255, 2023.
- [Luo et al., 2025] Junyu Luo, Weizhi Zhang, Ye Yuan, Yusheng Zhao, Junwei Yang, Yiyang Gu, Bohan Wu, Binqi Chen, Ziyue Qiao, Qingqing Long, et al. Large language model agent: A survey on methodology, appli- cations and challenges. arXiv preprint arXiv:2503.21460, 2025.
- [Pryzant et al., 2023] Reid Pryzant, Dan Iter, Jerry Li, Yin Tat Lee, Chenguang Zhu, and Michael Zeng. Au- tomatic prompt optimization with" gradient descent" and beam search. arXiv preprint arXiv:2305.03495, 2023.
- [Qian et al., 2024] Chen Qian, Jiahao Li, Yufan Dang, Wei Liu, YiFei Wang, Zihao Xie, Weize Chen, Cheng Yang, Yingli Zhang, Zhiyuan Liu, et al. Iterative experience re- finement of software-developing agents. arXiv preprint arXiv:2405.04219, 2024.
- [Qiu et al., 2025] Jiahao Qiu, Xuan Qi, Tongcheng Zhang, Xinzhe Juan, Jiacheng Guo, Yifu Lu, Yimin Wang, Zixin Yao, Qihan Ren, Xun Jiang, et al. Alita: Generalist agent enabling scalable agentic reasoning with minimal predefinition and maximal self-evolution. arXiv preprint arXiv:2505.20286, 2025.
- [Rein et al., 2024] David Rein, Betty Li Hou, Asa Cooper Stickland, Jackson Petty, Richard Yuanzhe Pang, Julien Dirani, Julian Michael, and Samuel R Bowman. Gpqa: A graduate-level google-proof q&a benchmark. In First Conference on Language Modeling, 2024.
- [Shinn et al., 2023] Noah Shinn, Federico Cassano, Ashwin Gopinath, Karthik Narasimhan, and Shunyu Yao. Reflex- ion: Language agents with verbal reinforcement learn- ing. Advances in Neural Information Processing Systems, 36:8634-8652, 2023.
- [Sumers et al., 2024] Theodore R. Sumers, Shunyu Yao, Karthik Narasimhan, and Thomas L. Griffiths. Cognitive architectures for language agents, 2024.
- [Team et al., 2023] Gemini Team, Rohan Anil, Sebastian Borgeaud, Jean-Baptiste Alayrac, Jiahui Yu, Radu Soricut, Johan Schalkwyk, Andrew M Dai, Anja Hauth, Katie Mil- lican, et al. Gemini: a family of highly capable multimodal models. arXiv preprint arXiv:2312.11805, 2023.
- [Wang et al., 2023a] Guanzhi Wang, Yuqi Xie, Yunfan Jiang, Ajay Mandlekar, Chaowei Xiao, Yuke Zhu, Linxi Fan, and Anima Anandkumar. Voyager: An open- ended embodied agent with large language models. arXiv preprint arXiv:2305.16291, 2023.
- [Wang et al., 2023b] Xinyuan Wang, Chenxi Li, Zhen Wang, Fan Bai, Haotian Luo, Jiayou Zhang, Nebojsa Jojic, Eric P Xing, and Zhiting Hu. Promptagent: Strategic planning with language models enables expert-level prompt opti- mization. arXiv preprint arXiv:2310.16427, 2023.
- [Wang et al., 2024] Yubo Wang, Xueguang Ma, Ge Zhang, Yuansheng Ni, Abhranil Chandra, Shiguang Guo, Weim- ing Ren, Aaran Arulraj, Xuan He, Ziyan Jiang, et al. Mmlu-pro: A more robust and challenging multi-task lan- guage understanding benchmark. Advances in Neural In- formation Processing Systems, 37:95266-95290, 2024.
- [Wang et al., 2025a] Shaobo Wang, Zhengbo Jiao, Zifan Zhang, Yilang Peng, Xu Ze, Boyu Yang, Wei Wang, Hu Wei, and Linfeng Zhang. Socratic-zero: Bootstrapping reasoning via data-free agent co-evolution. arXiv preprint arXiv:2509.24726, 2025.
- [Wang et al., 2025b] Wei Wang, Zhaowei Li, Qi Xu, Yiqing Cai, Hang Song, Qi Qi, Ran Zhou, Zhida Huang, Tao Wang, and Li Xiao. Qcrd: Quality-guided contrastive ra- tionale distillation for large language models. In Proceed- ings of the 2025 Conference on Empirical Methods in Nat- ural Language Processing, pages 14345-14356, 2025.
- [Wei et al., 2022] Jason Wei, Xuezhi Wang, Dale Schuur- mans, Maarten Bosma, Fei Xia, Ed Chi, Quoc V Le, Denny Zhou, et al. Chain-of-thought prompting elicits reasoning in large language models. Advances in neural information processing systems, 35:24824-24837, 2022.
- [Wu et al., 2024] Zhiyong Wu, Chengcheng Han, Zichen Ding, Zhenmin Weng, Zhoumianze Liu, Shunyu Yao, Tao Yu, and Lingpeng Kong. Os-copilot: Towards generalist computer agents with self-improvement. arXiv preprint arXiv:2402.07456, 2024.
- [Wu et al., 2025a] Junde Wu, Jiayuan Zhu, Yuyuan Liu, Min Xu, and Yueming Jin. Agentic reasoning: A streamlined framework for enhancing llm reasoning with agentic tools. arXiv preprint arXiv:2502.04644, 2025.
- [Wu et al., 2025b] Rong Wu, Xiaoman Wang, Jianbiao Mei, Pinlong Cai, Daocheng Fu, Cheng Yang, Licheng Wen, Xuemeng Yang, Yufan Shen, Yuxin Wang, et al. Evolver: Self-evolving llm agents through an experience-driven lifecycle. arXiv preprint arXiv:2510.16079, 2025.
- [Xia et al., 2025] Peng Xia, Kaide Zeng, Jiaqi Liu, Can Qin, Fang Wu, Yiyang Zhou, Caiming Xiong, and Huaxiu Yao. Agent0: Unleashing self-evolving agents from zero data via tool-integrated reasoning. arXiv preprint arXiv:2511.16043, 2025.
- [Yang et al., 2018] Zhilin Yang, Peng Qi, Saizheng Zhang, Yoshua Bengio, William Cohen, Ruslan Salakhutdinov, and Christopher D Manning. Hotpotqa: A dataset for di- verse, explainable multi-hop question answering. In Pro- ceedings of the 2018 conference on empirical methods in natural language processing, pages 2369-2380, 2018.
- [Yang et al., 2025a] An Yang, Anfeng Li, Baosong Yang, Beichen Zhang, Binyuan Hui, Bo Zheng, Bowen Yu, Chang Gao, Chengen Huang, Chenxu Lv, et al. Qwen3 technical report. arXiv preprint arXiv:2505.09388, 2025.
- [Yang et al., 2025b] Cheng Yang, Xuemeng Yang, Licheng Wen, Daocheng Fu, Jianbiao Mei, Rong Wu, Pinlong Cai, Yufan Shen, Nianchen Deng, Botian Shi, et al. Learn- ing on the job: An experience-driven self-evolving agent for long-horizon tasks. arXiv preprint arXiv:2510.08002, 2025.
- [Zhao et al., 2025] Andrew Zhao, Yiran Wu, Yang Yue, Tong Wu, Quentin Xu, Matthieu Lin, Shenzhi Wang, Qingyun Wu, Zilong Zheng, and Gao Huang. Absolute zero: Reinforced self-play reasoning with zero data. arXiv preprint arXiv:2505.03335, 2025.
- [Zhou et al., 2022] Yongchao Zhou, Andrei Ioan Muresanu, Ziwen Han, Keiran Paster, Silviu Pitis, Harris Chan, and Jimmy Ba. Large language models are human-level prompt engineers. In The eleventh international confer- ence on learning representations, 2022.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
LLM agents[Team et al., 2023; Yang et al., 2025a] have gotten better at logic[Wu et al., 2025a] and tool use[Luo et al., 2025], largely because of Chain-of-Thought (CoT)[Wei et al., 2022] and self-correction. But the current approach to self-evolution has a blind spot: Most self-evolution methods still put too much faith in the final answer. Existing frameworks lean almost entirely on outcome supervision.[Rein et al., 2024; Lu et al., 2023; Chen, 2021]. If an agent lands on the correct answer, the system treats the reasoning path as valid-even if the logic was flawed or simply a "lucky guess"[Sumers et al., 2024]. Since standard rejection sampling only checks the last output, these structurally unsound trajectories slip into the training set. This isn't harmless noise, it's poison for the model. Instead of learning robust decision-making, the agent effectively memorizes bad heuristics, creating a brittle policy that falls apart the moment the data distribution shifts[An et al., 2024]. Recent work has pushed toward modular agent designs, trying to impose structure on reasoning[Wu et al., 2025b; Yang et al., 2025b], but structure isn't enough-verifying the internal logic of the generated data remains the bottleneck. However, defining "correct reasoning" in open-ended domains is messy and subjective. That is why we explicitly focus on Verifiable Domains (like Math and Code) where ground truth is unambiguous and failure is easy to detect. before agents take on fuzzy, ambiguous problems, they should prove they can maintain causal consistency in deterministic ones. They need to show they can isolate which steps are genuinely necessary and which are incidental. In other words, the logic should survive small perturbations to the input, not collapse because the agent memorized a single path that happened to work once.
∗Corresponding author.
We present Iterative Event-Driven Internalization (I-EDI), a closed-loop framework designed for enforcing structural consistency in self-evolution. Our main idea is that true understanding requires Structural Invariance. Verifiable Counterfactual Simulation (VCS) is our core mechanism. Instead of broadly accepting all correct trajectories, VCS subjects the agent's reasoning to a "stress test": we generate counterfactual variants of a problem (e.g., numerical perturbations, isomorphic context shifts) and require the agent to solve them with the same core action dependency graph. This acts as a strict filter: if an action sequence is truly causal, it must remain valid across such structural variations.
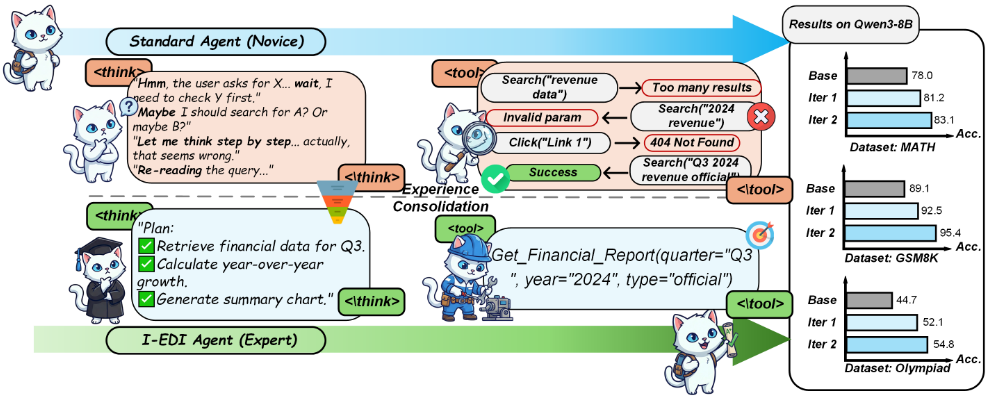
Figure 1 gives a general picture of the cognitive changes brought by I-EDI, which shows how a novice agent that depends on wordy deliberation transforms into an expert agent with a skillful and precise tool-use mode after it accumulates experience. Unlike static distillation pipelines, I-EDI runs as a spiral loop rather than a one-shot process. Each cycle revisits and refines the agent's behavior through three recurring phases: (1) Active Boundary Probing: the agent creates adversarial tasks specifically designed to challenge its current intuitive policy, aiming at the "zone of proximal development." (2) Verifiable Counterfactual Simulation (VCS): to reduce hallucination, we use a deterministic verifier V over auditable outcomes and admit only trajectories that are strictly verified and structure-consistent. (3) Parsimonious Internalization: rather than replicating long thinking processes, agents distill verified trajectories into optimized actions, learning to bypass redundant computations and solve problems with the lowest cognitive load. Experiments show that I-EDI consistently outperforms strong selfevolution baselines, with the largest gains on frontier/hard subsets and improved out-of-distribution generalization. Importantly, I-EDI is intentionally built from three auditable primitives:(i) frontier targeting (find dissonance where πfast fails but πslow verifies), (ii) structural stress-test verification (VCS: Execution + TSC + NbD), and (iii) parsimonious projection from τslow to τopt. All other components (e.g., edit operators, dedup rules) are implementation-level choices that only instantiate these primitives; they are not additional conceptual modules. This reframing makes the method easy to audit: each primitive has a single, executable acceptance criterion.
2 RelatedWork
2.1 Self-evolving Agent
Research has shifted from static models to agents that can adapt over time[Gao et al., 2025]. One stream formulates prompt engineering as black-box optimization[Zhou et al., 2022; Wang et al., 2023b; Pryzant et al., 2023], iteratively updating instructions to improve performance, while leaving the agent's parameters unchanged. Other approaches focus on accumulating experience, building structured skill libraries or curated toolsets for reuse[Wang et al., 2023a; Wu et al., 2024; Qian et al., 2024; Qiu et al., 2025]. Selfreflexive frameworks instead rely on feedback signals to iteratively correct errors.[Shinn et al., 2023; Liang et al., 2025]. While Agent0[Xia et al., 2025]/R-Zero[Huang et al., 2025]/Socratic-Zero[Wang et al., 2025a] primarily filter by final-answer correctness, I-EDI changes the object of verification: we verify auditable structure via (i) invariance across counterfactual stress tests (TSC) and (ii) operational necessity (NbD under deterministic replay). This targets a concrete failure mode-answer-correct but structurally spurious "lucky guesses"-that accumulates in outcome-only self-training. IEDI also rethinks what distillation should copy. Instead of imitating verbose rationales, accepted traces are projected to τopt, which makes training noticeably more stable across rounds.
2.2 Reasoning-Oriented, Distillation, and Efficiency-Driven Works
Much of the prior work improves LLM reasoning by adding CoT or structured planning at inference time, often by generating long multi-step traces. Knowledge distillation can transfer performance, and recent rationale-distillation methods attempt to inherit reasoning behaviors [Do et al., 2025; Wang et al., 2025b; Lee et al., 2024], but they largely perform inference-time scaffolding or imitate surface traces rather than the underlying decision logic. By comparison, hallucination mitigation is usually handled through post-hoc filtering or verification [Lin et al., 2025], not by folding verified experience back into the model.
3 Preliminaries
We consider an agent that solves reasoning tasks by interacting with an environment. Let X be the input space and Y the answer space. A policy πθ(at | st) produces a trajectory τ = (x, a1:T , o1:T , y), where at denotes an action (reasoning step or tool call) and ot is the resulting observation. We use the same model parameters θ but distinguish two inference modes by decoding: an intuitive policy πfast (greedy decoding) and a deliberate policy πslow that applies a deliberative decoding strategy Dslow (e.g., exploration and selfcorrection). Let V (y) ∈ {0, 1} be a deterministic verifier. Our goal is to internalize verified deliberation into fast inference by maximizing the likelihood of parsimonious verified trajectories τopt: θ∗ = argmaxθ Ex∼D [ logπfast(τopt | x)]
4 Methodology
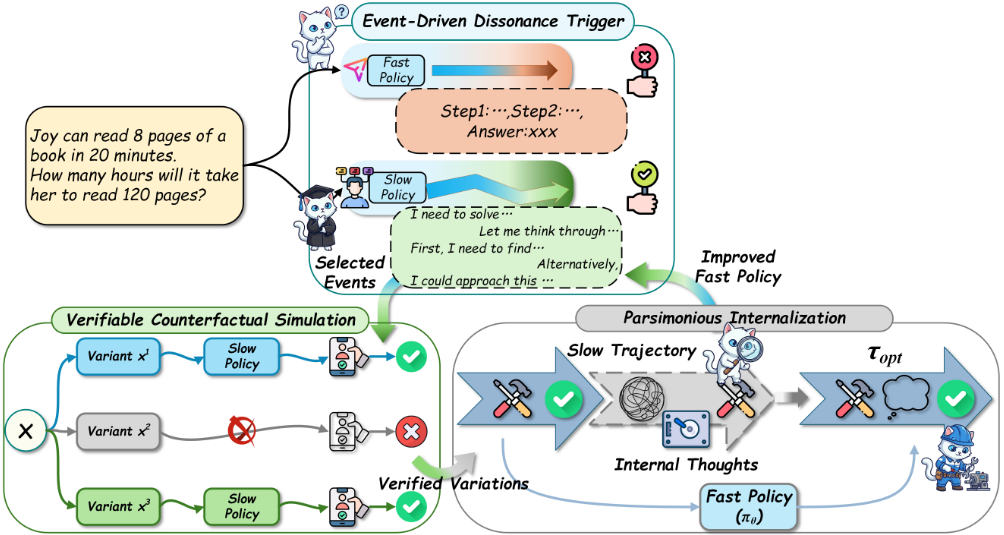
We propose Iterative Event-Driven Internalization (I-EDI), a closed-loop framework for iterative improvement of the the reasoning capacity. It transfers πslow into the intuitive parameters of πfast. As shown in Figure 2, I-EDI is a Spiral Curriculum. The framework runs in three phases: (1) Active Boundary Probing, (2) Verifiable Counterfactual Simulation, and (3) Parsimonious Internalization. Importantly, NbD is meant to test necessity of auditable actions under a fixed interface, not to penalize free-form reasoning. If the agent were allowed to introduce new tool calls after a deletion, the notion of necessity would quickly break down. Any removed node could be reconstructed through an alternative tool path, turning NbD into a test of search ability rather than causal dependence. Our runner therefore freezes the auditable interface and asks a sharper question: given the same observable tool outputs and the same allowed calls, is node u dispensable? The result is a conservative, precision-first core. That conservatism is deliberate-it prevents shortcut structures from slipping through and accumulating over successive self-evolution rounds.
4.1 Generative Frontier Probing
We implement Gϕ as the same backbone LLM with an editoperator prompt that applies one of: numeric substitution, isomorphic context rewrite, constraint perturbation while preserving the task type. We reject trivial edits (near-paraphrases or no-operator-change) and enforce hard constraints (e.g., keep the same answer format and required tool type). We sample n variants with temperature T , deduplicate them using normalized string hashes and an embedding similarity threshold (< ϵ), and monitor diversity via the distribution of applied edit operators.
4.2 Verifiable Counterfactual Simulation (VCS)
For each frontier instance x (fast fails, slow succeeds), we first obtain a verified seed trace τseed and extract its Core Action Structure S: a minimal auditable action-dependency graph (not free-form text). We then generate M structurepreserving counterfactuals ˜x and run πslow(˜x). A trace is admitted only if it passes: Execution V (τ) = 1, TSC (its auditable graph is isomorphic to S under the same canonicalization), and NbD (deleting any core node flips verification under no-recompute replay). Finally, the admitted trace is projected to a parsimonious supervision target τopt to update πfast .
ExtractCoreStructure(τ). We define the core S as the smallest auditable subgraph that is (i) sufficient to pass the verifier and (ii) necessary under our replay protocol (NbD). Concretely, starting from the full auditable graph G(τ), we iteratively remove candidate nodes and keep a deletion only if the replayed trace still verifies. The pruning order is fixed only to guarantee reproducibility, not to claim a unique mathematical optimum; when multiple deletion orders yield different minimal cores, we retain all verified minimal cores as an equivalence class S(x) (below). Thus, verification never depends on one arbitrary template.
Algorithm 1 VCS: Core Structure Extraction & Verification
Require: Instance x′ , Policy π, Verifier V , Gen Gϕ, Count M Ensure: Dataset D 1: τ0 ← π(x′ ); if V (τ0) = 0 then return ∅ 2: S ← GETCORE(τ0); D ← ∅; N ← {Gϕ(x′ , PRESERVE(S))}Mm=1 3: for ˜x ∈ N do 4: τ ← π(˜x) 5: if V (τ ) ̸= 0andCONSISTENT(τ, S)andNBD(τ, S, V ) then 6: D←D∪ {(˜x, PARSIMONIOUS(τ))} 7: end if 8: end for 9: return DTSC(τ, S). Extract G(τ) under the same canonicalization; accept iff there exists an isomorphism that matches all node signatures (t, name, args∗ , outs∗ ) and dependency edges. (QA uses set-equivalence for evidence chains.)
NbD(τ, S, V ). For each u ∈ S, replay τ \ {u} under a deterministic no-recompute runner: (i) permit only the original auditable calls from τ excluding deleted nodes, in the same order; (ii) block any new auditable action not present in τ; (iii) additionally block any action a′ whose canonical signature collides with u, where σ(a) = (name,C(args),H(C(outs))) and collision is σ(a′ ) = σ(u). Declare u necessary iff V (τ ) = 1 but V (τ \ {u}) = 0. No-Recompute is an Attribution Test, not a Solvability Test. Allowing re-computation would merely verify if the problem can be solved (solvability), whereas NbD rigorously tests if the specific deleted node was statistically necessary for the current trajectory's success (causal attribution). This strict isolation is required to distill the exact winning logic.
Core Action Structure. Figure2 ("Joy reading book") illustrates S. A standard agent may reach the correct answer ("0.5 hours") via spurious cancellations (e.g., unnecessary unit conversions). Definition: we define S as the minimal auditable dependency graph, not the full reasoning text. For "Joy", S contains only: Read Rate = 8/20 → Total Time = 120/Read Rate → Convert To Hours. Mechanism: VCS (i) extracts an inclusion-minimal S by NbD pruning under the no-recompute replay, and (ii) stresstests invariance with counterfactuals (e.g., "120 pages" → "200 pages"): a trace is admitted only if its auditable graph is isomorphic to S (TSC) and core deletions flip verification (NbD). Thus, answer-correct "lucky guesses" are rejected when their structure breaks under counterfactuals (TSC) or when deletion exposes hidden dependence (NbD); accepted traces are projected to the parsimonious target τopt to supervise πfast.
Structure-Preserving Counterfactuals. A single frontier event is insufficient for robust internalization: themodel must learn that surface form can change while the auditable dependency structure remains invariant. So we create a Counterfactual Contrast Set (N(x′ ) = ˜x1, . . . , ˜xM) by changing the non-essential features (e.g., variable names, wording, distractors, or isomorphic context shifts),and we force the intended (S) to remain unchanged. Counterfactuals are intuitively as design (normalize within each node's args/outs only, without modifying cross-node dependencies). We instantiate S across domains (Table 1): symbolic ops (Math) and retrieval/evidence APIs (QA).
| Domain | Auditable Node Signa- ture (u) | Canonicalization Rule C(·) |
|---|---|---|
| Math | Tool: symbolic ops (e.g., simplify); Commit: commit(ˆ y) | Term rewriting: Parse w/ SymPy, serialize via srepr; sort operands; norm precision. Ambigu- ous → distinct. |
| QA† | Retrieve: ⟨q, ids⟩; Select: ⟨d id, s id⟩; Commit: compose(ˆ y, evs) | Grounded QA: Sort doc IDs; evidence as ⟨d id, s id⟩; norm query whitespace. Set- equivalence for evidence. |
Dependency Edge. For two nodes (u, v) add a directed edge (u → v) if (v)'s canonical arguments reference (u)'s canonical outputs:
where (Ref) is a domain-specific reference detector (defined per domain below), implemented via ID linking, variablebinding tables, or hash references (preferred), and falls back to exact token match if necessary. The Core Action Structure
"near-boundary drills" around the same basic decision structure.
Double Verification. A counterfactual candidate ˜x ∈ N(x′ ) is admitted only if its slow-policy trajectory τslow(˜x) passes: (i) Execution verification: a deterministic verifier returns V (τslow(˜x)) = 1; (ii) Structural verification: the trace must be consistent with the extracted core structure S (TSC), and deleting any core node aligned with S must flip verification to failure (NbD). See Algorithm 1 (gates) and Table 1 (canonical signatures); the Appendix only lists additional edge cases and examples. We employ the strict 'norecompute' constraint as a conservative precision-first. This intentionally trades recall for precision, ensuring that it can learn explicit dependencies rather than latent correlations or shortcuts. The resulting dataset (D(k) ∗ train) contains pairs ((˜x, τ ∗ opt)), where (τopt) is the optimized tight trajectory derived from verified (τslow).
Given a slow-policy trace τ from πslow, an auditable node is a typed record
where i is the step index; t ∈ {tool, retrieve, select, check, commit}; name is the tool/API identifier; args∗ = C(args) and outs∗ = C(outs) are canonicalized arguments/outputs; and meta stores optional hashes/timestamps/status. S is defined only over auditable actions (not free-form CoT), making deletion/necessity tests well-posed. Canonicalization C(·) is deterministic and aims for stable equivalence when it is unambiguous; we use a conservative, locality-preserving is a directed attributed graph:
where U is a subset of auditable action nodes extracted from τ , E ⊆ U × U are dependency edges, and ψ stores node attributes (t, name, args∗, outs∗). We compute S by pruning non-essential nodes from the full auditable graph G(τ) using a verifier V . Informally, S contains the smallest set of nodes that are (i) sufficient to pass verification and (ii) necessary under deletion tests. We define S strictly over auditable actions rather than free-form natural-language steps. Table1 defines the auditable node signatures and canonicalization rules (per domain), and Algorithm 1 defines Ref/TSC/NbD operationally; the Appendix only adds extended rules and worked examples.
Deterministic (dataset-grounded) verification for multihop QA. Our deterministic/semi-deterministic QA claims are restricted to evidence-supervised multi-hop datasets (e.g., HotpotQA) with gold supporting facts; we do not claim deterministic verification for open-domain QA without such annotations. For QA, we instantiate S as an auditable evidence-chain graph retrieve(query) → select evidence(doc id, sent id)→compose/commit (not free-form CoT), so TSC and NbD are executable. We define VQA(τ) = 1 iff the final answer matches and the selected evidence covers at least one gold supporting-fact set with threshold α, which is deterministic given dataset annotations and evidence IDs (Appendix for edge cases).
To enforce structural invariance across counterfactuals, we require the extracted dependency graph to match the seed structure S under canonicalization C(·). Edges are defined by auditable data flow (Table 1): u→v iff Ref(outs∗u , args∗v ) = 1. We accept a candidate trace only if it matches S exactly; for QA we relax strict isomorphism to set-equivalence over valid evidence chains to accommodate order invariance, filtering answer-correct but structurally spurious traces.
For a verified trajectory τ , NbD tests whether an auditable node u is operationally necessary under a fixed replay protocol: we replay τ \ u and declare u necessary iff the verifier flips, i.e.,V (τ) = 1 but V (τ \ u) = 0. For QA evidenceselection nodes, deleting u removes its (doc id, sent id) tuple from the composed evidence; VQA fails if either the answer is incorrect or the remaining evidence violates the supporting-fact check. Replay is enforced by a deterministic no-recompute runner to prevent recovery via alternative tool calls (details in Appendix). NbD deletes a node u and replays τ \{u} under a conservative runner that prevents 're-deriving' deleted evidence via alternate tool paths. Concretely, during replay we (i) permit only the original auditable calls from τ excluding deleted nodes, in the same order, plus freeform text; (ii) block any newly proposed auditable action not present in τ; and (iii) additionally block any action a′ whose canonical signature σ(a′ ) collides with the deleted node u, where σ(a) := (name(a),C(args(a)),H(C(outs(a)))) and collision is σ(a′ ) = σ(u) (exact match on name + normalized args; and, when outs exist, matching output-hash). This makes NbD a precision-first necessity test: if a solution still verifies under these constraints, the deleted node is not necessary; otherwise we conservatively keep it.
Multiple valid cores (budgeted). We maintain an equivalence class S(x) = {Sr}Rr=1 of distinct minimal cores from trajectories that pass V/TSC/NbD. Cores are clustered by a canonical graph hash (node signatures + edges under the same canonicalization) and we keep top-R (default R=8) by frequency/parsimony. A trajectory is accepted if it matches any Sr (OR-over-cores); matching costs O(R· |E|) and Sec. 5 shows robustness to R.
Canonicalization robustness. When equivalence is ambiguous we keep structures distinct (precision-first); a strictness sweep in Appendix shows Iter3 is stable, with expected admit/match trade-offs and reported per-gate rejection rates.
4.3 Parsimonious Internalization
Naively cloning τslow makes πfast imitate deliberation traces (trial-and-error) rather than internalize the underlying decision structure. We therefore train on a parsimonious trajectory that retains only auditable structure and the minimal bindings needed to execute it.
Parsimonious trajectory τopt. We deterministically construct τopt = PROJ(τslow, S) by: (i) keeping all auditable actions in S (tool/retrieve/select/check/commit) in topological order; (ii) retaining only the minimal text spans that bind each action's canonical arguments (dropping alternatives and self-corrections); and (iii) keeping the final commit. In practice, we select the shortest contiguous spans that contain all symbols/IDs in the canonical argument set args∗ of actions in S (examples in Appendix).
Training. πfast is updated by maximizing the likelihood of optimized trajectories:
Training on τopt teaches πfast to execute verified cores without reproducing the slow scaffolding. We iterate until validation performance plateaus; as πfast absorbs the current frontier, Active Probing naturally shifts to harder instances, yielding a spiral curriculum from novice to expert.
4.4 Experimental Setup
Implementation Details. We use Qwen3-4B-Base and Qwen3-8B-Base as the backbone. The intuitive policy πfast uses greedy decoding (T=0), while the slow teacher πslow follows a Plan-Execute-Critique-Repair protocol with T=0.7. We run K=3 evolution rounds; in each round, candidates must pass VCS (execution correctness and TSC) and only verified traces are used for NLL fine-tuning. Key hyperparameters are n=16, Tprobe=0.7, ε=0.92, M=8, R=8, and WL-iters= 2. Unless stated otherwise, each seed reruns the full pipeline (probing → VCS filtering → finetuning). The Appendix reports a light sensitivity sweep over (M, R, ε, Tprobe), showing stable Iter3 performance with predictable gate-rate trade-offs.
Benchmarks and Baselines. We use datasets that have deterministic verifiers (GSM8K[Cobbe et al., 2021], Minerva[Lewkowycz et al., 2022], MATH[Hendrycks et al., 2021] and the math subset of Olympiad-Bench[He et al., 2024] and HotpotQA[Yang et al., 2018]) for seed generation. For evaluation, we also run out-of-domain benchmarks with no training exposure, including SuperGPQA[Du et al., 2025], MMLU-Pro[Wang et al., 2024], and BBEH[Kazemi et al., 2025]. We compare against standard base models and strong self-evolving agents: R-Zero[Huang et al., 2025], Absolute Zero[Zhao et al., 2025], SPIRAL[Liu et al., 2025], SocraticZero[Wang et al., 2025a], and Agent0[Xia et al., 2025] to keep controlled inference budgets for all methods.
Decontamination. To prevent data leakage, we do a strict double-stage cleaning filter (exact hashing and semantic similarity checks) to remove the generated instances that align with test sets.
4.5 Main Result
We present results for mathematical reasoning and generaldomain reasoning in Table 2 and Table 3.
Comparison with Baselines. I-EDI consistently outperforms strong baselines across model sizes. Notably, I-EDI (Iter 3) significantly surpasses the tool-integrated Agent0 on Qwen3-8B-Base. Its clear lead on Olympiad-Bench demonstrates robust complex problem-solving capability without test-time sampling. Furthermore, the performance gain from Iter 1 to 3 validates our evolutionary loop: active frontier internalization steadily enhances reasoning robustness.
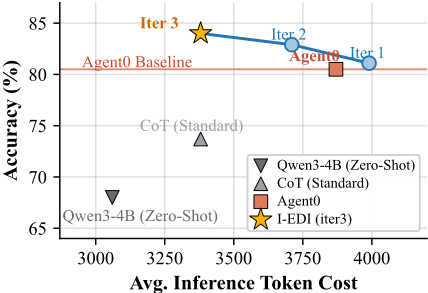
Generalization. Table 3 highlights impressive out-ofdomain results, where I-EDI achieves superior average scores on symbolic reasoning benchmarks. This confirms that IEDI learns transferable, structure-grounded behaviors rather than task-specific memorization, enabling robust generalization. Figure 3 plots accuracy-token trajectories across iterations for both Agent0 and I-EDI under matched evaluation (greedy decoding). Early iterations may increase average tokens due to exploration, while later iterations achieve the intended upward-left shift as πfast internalizes verified structure and relies less on verbose deliberation.
| Model Name | Minerva | MATH | GSM8K | Olympiad |
|---|---|---|---|---|
| Qwen3-4B-Base Base | 39.6 | 71.0 | 88.6 | 43.7 |
| + Absolute Zero | 41.9 | 76.2 | 89.3 | 41.5 |
| + SPIRAL | 42.4 | 76.4 | 91.0 | 38.4 |
| + R-Zero | 52.9 | 79.6 | 92.1 | 44.6 |
| + Agent0 | 55.6 | 80.5 | 92.6 | 46.7 |
| + I-EDI(iter1) | 56.2 | 81.1 | 92.4 | 47.8 |
| + I-EDI(iter2) | 57.8 | 82.9 | 93.6 | 48.6 |
| + I-EDI(iter3) | 58.6 | 84.0 | 95.1 | 50.5 |
| Qwen3-8B-Base Base | 54.9 | 79.2 | 90.7 | 47.9 |
| + Absolute Zero | 52.9 | 76.6 | 92.0 | 47.8 |
| + R-Zero | 60.7 | 82.0 | 94.1 | 48.9 |
| + Socratic-Zero | 52.4 | 81.2 | 87.3 | 55.1 |
| + Agent0 | 61.3 | 82.4 | 94.5 | 54.0 |
| + I-EDI(iter1) | 61.0 | 81.2 | 92.5 | 52.1 |
| + I-EDI(iter2) | 62.8 | 83.1 | 95.4 | 54.8 |
| + I-EDI(iter3) | 64.6 | 84.2 | 97.0 | 55.5 |
4.6 Capability Frontier Expansion on HotpotQA
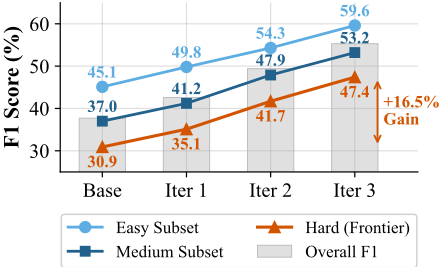
We investigate whether I-EDI gives rise to genuine capability expansion instead of simply distorting existing reasoning patterns with Qwen3-4B. As shown in Figure 4, I-EDI has achieved a significant improvement in all difficulty buckets of HotpotQA across multiple evolution rounds. The improvement performance on Hard instances is close to the overall improvement, which indicates that iterative internalization process helps to gradually expand the agent's ability to tackle more complex multi-hop reasoning problems, rather than causing it to overfit on simpler instances.
4.7 Ablation Study: Stability of Iterative Self-Evolution
Table 4 shows that only the complete I-EDI pipeline achieves consistent gains across three evolution rounds on MATH (Qwen3-4B), while the ablation studies show either saturation or degradation in the later rounds. Specifically: (i) w/o Active Boundary Probing quickly saturates, highlighting the necessity of frontier mining for targeted capability growth; (ii) w/o Structural Verification reveals the common failure mode in self-training-initial gains that are followed by a decline-indicating that simply verifying the final answers isn't enough, as shortcut trajectories tend to accumulate over rounds; (iii) w/o Parsimonious Internalization (training on τslow instead of τopt) reduces consolidation to imitation of deliberation artifacts, yielding weaker and less stable improvements. These findings bolster our argument that stable self-evolution requires a combination of frontier targeting, structure-preserving verification, and parsimonious internalization; the low variance is consistent with deterministic gating and fixed evaluation. Figure 5 confirms the same trend on HotpotQA-Hard: only I-EDI sustains steady growth; ablations either stagnate (no probing), regress late (no structural verification), or progress slowly (raw traces).
| Model Name | SuperGPQA | MMLU-Pro | BBEH |
|---|---|---|---|
| Qwen3-4B-Base Base | 25.8 | 42.9 | 8.32 |
| + Absolute Zero | 27.1 | 52.6 | 8.3 |
| + SPIRAL | 27.1 | 53.2 | 9.57 |
| + R-Zero | 27.6 | 51.5 | 10.4 |
| + Agent0 | 29.9 | 55.9 | 12.0 |
| + I-EDI(iter1) | 30.4 | 56.4 | 12.5 |
| + I-EDI(iter2) | 30.9 | 56.9 | 13.1 |
| + I-EDI(iter3) | 31.5 | 57.3 | 13.4 |
| Qwen3-8B-Base Base | 29.5 | 54.8 | 9.37 |
| + Absolute Zero | 33.5 | 62.5 | 10.8 |
| + R-Zero | 31.4 | 58.2 | 10.6 |
| + Socratic-Zero | 30.1 | 60.9 | 9.5 |
| + Agent0 | 33.0 | 63.4 | 13.7 |
| + I-EDI(iter1) | 33.7 | 63.9 | 14.2 |
| + I-EDI(iter2) | 34.6 | 64.3 | 14.8 |
| + I-EDI(iter3) | 35.1 | 65.0 | 15.1 |
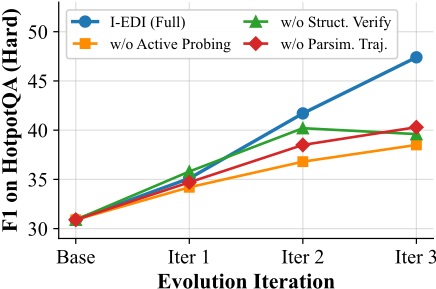
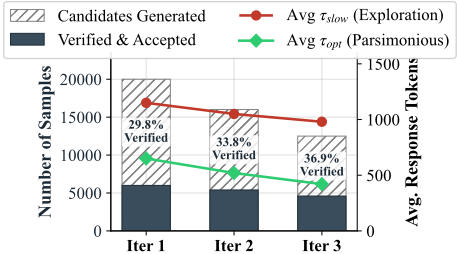
Figure 6 reports per-iteration generation-verification accounting: candidates shrink as πfast improves (fewer frontier cases survive), while the verified-acceptance ratio risesindicating cleaner data rather than filter overfitting, since the frontier rate and edit-operator entropy stay high across rounds.
| Variant | Iter1 | Iter2 | Iter3 |
|---|---|---|---|
| I-EDI (Full) | 81.1±0.21 | 82.9±0.18 | 84.0±0.17 |
| w/o Active Boundary Probing | 81.0±0.29 | 81.4±0.31 | 81.6±0.34 |
| w/o Structural Verification | 81.2±0.26 | 82.0±0.28 | 81.7±0.33 |
| w/o Counterfactual Genera- tion | 80.8±0.30 | 81.0±0.32 | 81.3±0.35 |
| w/o Parsimonious Trajectory (τopt ) | 81.3±0.24 | 81.7±0.27 | 82.0±0.29 |
| Static Distillation | 81.1±0.33 | 81.0±0.35 | 80.9±0.37 |
| Tp | Transformation | Purpose |
|---|---|---|
| A | Param shift (5 tosses/2 heads → 4/3) | Prevent memorization; en- force re-instantiation. |
| B | Context switch (coins → 6 kids/2 girls) | Test isomorphic transfer across domains. |
| C | Edge case (exactly 0 heads) | Probe boundary robustness & consistency. |
5 Conclusion
We presented I-EDI, a self-evolution framework that turns verified deliberation into compact parametric intuition by evolving on cognitive-dissonance events and enforcing antishortcut learning via verifiable counterfactual simulation. This yields stable capability growth across iterations, with pronounced gains on frontier instances and reduced redundant reasoning. Our current instantiations require auditable actions with deterministic or dataset-grounded verification, covering symbolic math and evidence-supervised multi-hop QA; extending structural verification beyond verifiable domains is future work.
Acknowledgments
This work is partly supported by the Project of Beijing Welinkirt DaoAI Tech-nologies Co., Ltd.
@inproceedings{ijcai2026p11,
  title     = {I-EDI: Robust Self-Evolution Agents via Verifiable Counterfactual Simulation},
  author    = {Fan, Runze and Li, Yong},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {90--98},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/11},
  url       = {https://doi.org/10.24963/ijcai.2026/11},
}
TY - CPAPER TI - I-EDI: Robust Self-Evolution Agents via Verifiable Counterfactual Simulation AU - Fan, Runze AU - Li, Yong T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 90 EP - 98 DO - 10.24963/ijcai.2026/11 UR - https://doi.org/10.24963/ijcai.2026/11 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





