
A₃B₂: Adaptive Asymmetric Adapter for Alleviating Branch Bias in Vision-Language Image Classification with Few-Shot Learning
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 2136-2144.
https://doi.org/10.24963/ijcai.2026/238
Keywords
- Computer Vision: Transfer, low-shot, semi- and un- supervised learning
- Computer Vision: Multimodal learning
Abstract
Efficient transfer learning methods for large-scale vision–language models (e.g., CLIP) enable strong few-shot transfer, yet existing adaptation methods follow a fixed fine-tuning paradigm that implicitly assumes a uniform importance of the image and text branches, which has not been systematically studied in image classification. Through extensive analysis, we reveal a Branch Bias issue in vision–language image classification: adapting the image encoder does not always improve performance under out-of-distribution settings. Motivated by this observation, we propose A₃B₂, an Adaptive Asymmetric Adapter that alleviates Branch Bias in few-shot learning. A₃B₂ introduces Uncertainty-Aware Adapter Dampening (UAAD), which automatically suppresses image-branch adaptation when prediction uncertainty is high, enabling soft and data-driven control without manual intervention. Architecturally, A₃B₂ adopts a lightweight asymmetric design inspired by mixture-of-experts with Load Balancing Regularization. Extensive experiments demonstrate that A₃B₂ consistently outperforms 11 competitive prompt- and adapter-based baselines.
- [Bossard et al., 2014] Lukas Bossard, Matthieu Guillaumin, and Luc Van Gool. Food-101-mining discriminative com- ponents with random forests. In Computer vision-ECCV 2014: 13th European conference, zurich, Switzerland, September 6-12, 2014, proceedings, part VI 13, pages 446-461. Springer, 2014.
- [Brown et al., 2020] Tom Brown, Benjamin Mann, Nick Ry- der, Melanie Subbiah, Jared D Kaplan, Prafulla Dhari- wal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, et al. Language models are few-shot learners. Advances in neural information processing sys- tems, 33:1877-1901, 2020.
- [Cimpoi et al., 2014] Mircea Cimpoi, Subhransu Maji, Ia- sonas Kokkinos, Sammy Mohamed, and Andrea Vedaldi. Describing textures in the wild. In Proceedings of the IEEE conference on computer vision and pattern recog- nition, pages 3606-3613, 2014.
- [Deng et al., 2009] Jia Deng, Wei Dong, Richard Socher, Li- Jia Li, Kai Li, and Li Fei-Fei. Imagenet: A large-scale hierarchical image database. In 2009 IEEE conference on computer vision and pattern recognition, pages 248-255.
- [Fedus et al., 2022] William Fedus, Barret Zoph, and Noam Shazeer. Switch transformers: Scaling to trillion param- eter models with simple and efficient sparsity. Journal of Machine Learning Research, 23(120):1-39, 2022.
- [Fei-Fei et al., 2004] Li Fei-Fei, Rob Fergus, and Pietro Per- ona. Learning generative visual models from few train- ing examples: An incremental bayesian approach tested on 101 object categories. In 2004 conference on computer vision and pattern recognition workshop, pages 178-178. IEEE, 2004.
- [Fu et al., 2025] Stephanie Fu, Tyler Bonnen, Devin Guil- lory, and Trevor Darrell. Hidden in plain sight: Vlms overlook their visual representations. arXiv preprint arXiv:2506.08008, 2025.
- [Gao et al., 2024a] Chongyang Gao, Kezhen Chen, Jinmeng Rao, Baochen Sun, Ruibo Liu, Daiyi Peng, Yawen Zhang, Xiaoyuan Guo, Jie Yang, and VS Subrahmanian. Higher layers need more lora experts. arXiv preprint arXiv:2402.08562, 2024.
- [Gao et al., 2024b] Peng Gao, Shijie Geng, Renrui Zhang, Teli Ma, Rongyao Fang, Yongfeng Zhang, Hongsheng Li, and Yu Qiao. Clip-adapter: Better vision-language models with feature adapters. International Journal of Computer Vision, 132(2):581-595, 2024.
- [Gong et al., 2025] Shizhan Gong, Yankai Jiang, Qi Dou, and Farzan Farnia. Kernel-based unsupervised embedding alignment for enhanced visual representation in vision- language models. arXiv preprint arXiv:2506.02557, 2025.
- [Guo and Gu, 2025a] Yuncheng Guo and Xiaodong Gu. Mmrl: Multi-modal representation learning for vision- language models. arXiv preprint arXiv:2503.08497, 2025.
- [Guo and Gu, 2025b] Yuncheng Guo and Xiaodong Gu. Mmrl++: Parameter-efficient and interaction-aware rep- resentation learning for vision-language models. arXiv preprint arXiv:2505.10088, 2025.
- [Helber et al., 2019] Patrick Helber, Benjamin Bischke, An- dreas Dengel, and Damian Borth. Eurosat: A novel dataset and deep learning benchmark for land use and land cover classification. IEEE Journal of Selected Top- ics in Applied Earth Observations and Remote Sensing, 12(7):2217-2226, 2019.
- [Hendrycks and Gimpel, 2016] Dan Hendrycks and Kevin Gimpel. A baseline for detecting misclassified and out-of- distribution examples in neural networks. arXiv preprint arXiv:1610.02136, 2016.
- [Hendrycks et al., 2021a] Dan Hendrycks, Steven Basart, Norman Mu, Saurav Kadavath, Frank Wang, Evan Dorundo, Rahul Desai, Tyler Zhu, Samyak Parajuli, Mike Guo, et al. The many faces of robustness: A critical anal- ysis of out-of-distribution generalization. In Proceedings of the IEEE/CVF international conference on computer vi- sion, pages 8340-8349, 2021.
- [Hendrycks et al., 2021b] Dan Hendrycks, Kevin Zhao, Steven Basart, Jacob Steinhardt, and Dawn Song. Natu- ral adversarial examples. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 15262-15271, 2021.
- [Khattak et al., 2023] Muhammad Uzair Khattak, Hanoona Rasheed, Muhammad Maaz, Salman Khan, and Fa- had Shahbaz Khan. Maple: Multi-modal prompt learning. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 19113-19122, 2023.
- [Krause et al., 2013] Jonathan Krause, Michael Stark, Jia Deng, and Li Fei-Fei. 3d object representations for fine- grained categorization. In Proceedings of the IEEE inter- national conference on computer vision workshops, pages 554-561, 2013.
- [Lee et al., 2023] Dongjun Lee, Seokwon Song, Jihee Suh, Joonmyeong Choi, Sanghyeok Lee, and Hyunwoo J Kim. Read-only prompt optimization for vision-language few- shot learning. In Proceedings of the IEEE/CVF interna- tional conference on computer vision, pages 1401-1411, 2023.
- [Li et al., 2022] Boyi Li, Kilian Q Weinberger, Serge Be- longie, Vladlen Koltun, and René Ranftl. Language-driven semantic segmentation. arXiv preprint arXiv:2201.03546, 2022.
- [Li et al., 2024] Ming Li, Jike Zhong, Chenxin Li, Li- uzhuozheng Li, Nie Lin, and Masashi Sugiyama. Vision- language model fine-tuning via simple parameter-efficient modification. arXiv preprint arXiv:2409.16718, 2024.
- [Liang et al., 2023] Feng Liang, Bichen Wu, Xiaoliang Dai, Kunpeng Li, Yinan Zhao, Hang Zhang, Peizhao Zhang, Peter Vajda, and Diana Marculescu. Open-vocabulary se- mantic segmentation with mask-adapted clip. In Proceed- ings of the IEEE/CVF conference on computer vision and pattern recognition, pages 7061-7070, 2023.
- [Maji et al., 2013] Subhransu Maji, Esa Rahtu, Juho Kan- nala, Matthew Blaschko, and Andrea Vedaldi. Fine- grained visual classification of aircraft. arXiv preprint arXiv:1306.5151, 2013.
- [Mu and Lin, 2025] Siyuan Mu and Sen Lin. A comprehen- sive survey of mixture-of-experts: Algorithms, theory, and applications. arXiv preprint arXiv:2503.07137, 2025.
- [Nilsback and Zisserman, 2008] Maria-Elena Nilsback and Andrew Zisserman. Automated flower classification over a large number of classes. In 2008 Sixth Indian conference on computer vision, graphics & image processing, pages 722-729. IEEE, 2008.
- [Parkhi et al., 2012] Omkar M Parkhi, Andrea Vedaldi, An- drew Zisserman, and CV Jawahar. Cats and dogs. In 2012 IEEE conference on computer vision and pattern recogni- tion, pages 3498-3505. IEEE, 2012.
- [Peng et al., 2025] Zelin Peng, Zhengqin Xu, Zhilin Zeng, Changsong Wen, Yu Huang, Menglin Yang, Feilong Tang, and Wei Shen. Understanding fine-tuning clip for open- vocabulary semantic segmentation in hyperbolic space. In Proceedings of the Computer Vision and Pattern Recogni- tion Conference, pages 4562-4572, 2025.
- [Radford et al., 2021] Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agar- wal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, et al. Learning transferable visual models from nat- ural language supervision. In International conference on machine learning, pages 8748-8763. PmLR, 2021.
- [Recht et al., 2019] Benjamin Recht, Rebecca Roelofs, Lud- wig Schmidt, and Vaishaal Shankar. Do imagenet classi- fiers generalize to imagenet? In International conference on machine learning, pages 5389-5400. PMLR, 2019.
- [Shazeer et al., 2017] Noam Shazeer, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hin- ton, and Jeff Dean. Outrageously large neural net- works: The sparsely-gated mixture-of-experts layer. arXiv preprint arXiv:1701.06538, 2017.
- [Soomro et al., 2012] Khurram Soomro, Amir Roshan Za- mir, and Mubarak Shah. Ucf101: A dataset of 101 human actions classes from videos in the wild. arXiv preprint arXiv:1212.0402, 2012.
- [Tian et al., 2024] Chunlin Tian, Zhan Shi, Zhijiang Guo, Li Li, and Cheng-Zhong Xu. Hydralora: An asymmet- ric lora architecture for efficient fine-tuning. Advances in Neural Information Processing Systems, 37:9565-9584, 2024.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. Advances in neural information processing systems, 30, 2017.
- [Wang et al., 2019] Haohan Wang, Songwei Ge, Zachary Lipton, and Eric P Xing. Learning robust global repre- sentations by penalizing local predictive power. Advances in neural information processing systems, 32, 2019.
- [Xiao et al., 2010] Jianxiong Xiao, James Hays, Krista A Ehinger, Aude Oliva, and Antonio Torralba. Sun database: Large-scale scene recognition from abbey to zoo. In 2010 IEEE computer society conference on computer vision and pattern recognition, pages 3485-3492. IEEE, 2010.
- [Xu et al., 2023] Mengde Xu, Zheng Zhang, Fangyun Wei, Han Hu, and Xiang Bai. Side adapter network for open- vocabulary semantic segmentation. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 2945-2954, 2023.
- [Xue et al., 2022] Fuzhao Xue, Ziji Shi, Futao Wei, Yuxuan Lou, Yong Liu, and Yang You. Go wider instead of deeper. In Proceedings of the AAAI Conference on Artificial Intel- ligence, volume 36, pages 8779-8787, 2022.
- [Yang et al., 2024] Lingxiao Yang, Ru-Yuan Zhang, Yanchen Wang, and Xiaohua Xie. Mma: Multi-modal adapter for vision-language models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 23826-23837, 2024.
- [Yang et al., 2025] Jingfeng Yang, Ziyang Wu, Yue Zhao, and Yi Ma. Language-image alignment with fixed text en- coders. arXiv preprint arXiv:2506.04209, 2025.
- [Yao et al., 2023] Hantao Yao, Rui Zhang, and Changsheng Xu. Visual-language prompt tuning with knowledge- guided context optimization. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 6757-6767, 2023.
- [Yao et al., 2024] Hantao Yao, Rui Zhang, and Changsheng Xu. Tcp: Textual-based class-aware prompt tuning for visual-language model. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 23438-23448, 2024.
- [Zhang et al., 2024] Jingyi Zhang, Jiaxing Huang, Sheng Jin, and Shijian Lu. Vision-language models for vision tasks: A survey. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2024.
- [Zhou et al., 2022a] Kaiyang Zhou, Jingkang Yang, Chen Change Loy, and Ziwei Liu. Conditional prompt learning for vision-language models. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 16816-16825, 2022.
- [Zhou et al., 2022b] Kaiyang Zhou, Jingkang Yang, Chen Change Loy, and Ziwei Liu. Learning to prompt for vision-language models. International Journal of Computer Vision, 130(9):2337-2348, 2022.
- [Zhou et al., 2025] Yiyun Zhou, Chang Yao, and Jingyuan Chen. Cola: Collaborative low-rank adaptation. In Find- ings of the Association for Computational Linguistics: ACL 2025, pages 14115-14130, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Large-scale Vision-Language Models (VLMs) with dual branches are foundational for downstream transfer learning tasks due to their strong generalization. CLIP [Radford et al., 2021], trained on 400 million image-text pairs, aligns visual and textual modalities in a shared feature space via separate encoders and contrastive learning. However, full finetuning VLMs for specific tasks is computationally expensive and prone to overfitting in few-shot settings.
To address the aforementioned issues, efficient transfer learning methods have been proposed [Zhou et al., 2022b; Yang et al., 2024; Guo and Gu, 2025a; Guo and Gu, 2025b], enabling VLMs to adapt to different downstream tasks with minimal additional parameters. Previous approaches have mainly focused on prompt tuning and adapter-based methods. Prompt tuning aims to address the limitation of VLMs that require manually designed text prompts, which requires expert knowledge and is time-consuming. For instance, in the OxfordPets [Parkhi et al., 2012] dataset, CLIP's text encoder computes class embeddings using the prompt "A photo of a [CLASS], a type of pet.". These embeddings are then matched with the outputs by the image encoder, and the most similar one is selected to predict the image category. Most prior prompt tuning methods [Zhou et al., 2022b; Guo and Gu, 2025a] introduce learnable continuous vectors into the text encoder to dynamically model prompts, optimizing them during training while freezing other parameters, thereby enabling adaptation to specific datasets. In contrast, adapter-based methods [Yang et al., 2024] add lightweight, architecture-agnostic modules, making them easily integrable into different VLMs and allowing the models to adapt to potential downstream task spaces.
∗Corresponding author.
Although prior methods have achieved impressive few-shot performance in data and model adaptation, most CLIP-based methods follow a fixed fine-tuning paradigm: prompt tuning methods optimize the text encoder, while adapter-based methods are attached to the image encoder [Li et al., 2024; Zhang et al., 2024]. This raises a compelling research question: which matters more in different few-shot tasks, CLIP's text or image encoder? (We refer to this as the CLIP's Branch Bias issue) Recent studies have sparked interest in this issue. Yang et al. train only the image encoder while keeping the text encoder fixed, achieving surprising results on compositional understanding and long-text description tasks. Gong et al. propose a kernel-based method, significantly improving the image encoder's performance on zero-shot target recognition, fine-grained spatial reasoning, and localization tasks. Fu et al. find that in vision-centered benchmarks (e.g., depth estimation, correspondence), VLMs perform worse than their image encoders, with performance nearing random levels. In open-vocabulary semantic segmentation tasks, most past methods [Li et al., 2022; Liang et al., 2023; Xu et al., 2023] freeze the text encoder to preserve generalization, while recent studies [Peng et al., 2025] show that jointly fine-tuning both encoders leads to better segmentation results. However, there is no consensus on the Branch Bias issue in the general tasks of image classification.
To address gaps in prior work, we conduct extensive exploratory experiments on three visual tasks: base-to-novel generalization, cross-dataset evaluation, and domain generalization. Crucially, our insights reveal a significant phenomenon: fine-tuning the image encoder does not always yield performance gains and may even degrade robustness on out-of-distribution (OOD) tasks. While a straightforward response to this discovery would be to rigidly lock the image encoder for OOD scenarios, such a hard-coded approach is cumbersome and impractical, as it requires prior knowledge of the target data distribution to manually toggle the adapters. To resolve this dilemma, we propose a novel Adaptive Asymmetric Adapter for alleviating Branch Bias (A3B2) in vision-language image classification. Unlike rigid switching mechanisms, A3B2 achieves adaptability through a uncertainty-aware optimization mechanism. Specifically, we introduce Uncertainty-Aware Adapter Dampening (UAAD). This mechanism dynamically monitors prediction confidence; when the model encounters high-uncertainty samples (indicative of potential OOD data), it automatically suppresses the magnitude of the image adapter's contribution via a regularization penalty. This soft-constraint approach effectively operationalizes our insights without requiringmanual intervention. Structurally, inspired by theMixture of Experts (MoE) design [Fedus et al., 2022; Xue et al., 2022; Tian et al., 2024; Gao et al., 2024a; Zhou et al., 2025], A3B2 consists of a single dimensionality-reduction matrix and multiple dimensionality-expansion matrices, further enhanced by a Load Balancing Regularization to ensure diverse expert utilization [Shazeer et al., 2017].
Our contributions are summarized as follows:
- We systematically explore the Branch Bias issue in image classification for transformer-based CLIP models. Three insights discovered help build the optimal adapter structure for vision-language image classification tasks.
- We propose a task-adaptive, structure-asymmetric adapter to alleviate Branch Bias in vision-language image classification. Empirical evidence, theoretical support for the asymmetric structure, and theoretical guarantees of the method are provided in the extended version, respectively.
- Evaluations on three few-shot tasks show that, across 11 image classification datasets, A3B2 consistently achieves leading performance compared to 11 competitive baselines. The experiments also confirm the generality of our insights.
2 RelatedWork
2.1 CLIP's Branch Bias in Various Tasks
Recent studies have sparked significant interest in the CLIP's Branch Bias issue, particularly in tasks requiring fine-grained visual discrimination. For compositional and spatial tasks, the image branch often requires more adaptation. Yang et al. demonstrate that training only the image encoder while keeping the text encoder fixed yields superior performance in compositional understanding and long-text description. Similarly, Gong et al. propose a kernel-based alignment method that focuses on the image encoder, significantly improving zero-shot target recognition and localization. Fu et al. further reveal that in strictly vision-centered benchmarks (e.g., depth estimation), full VLMs can paradoxically perform worse than their frozen image encoders, suggesting textual interference. In contrast, for open-vocabulary semantic segmentation, the consensus has shifted. While earlier methods [Li et al., 2022; Liang et al., 2023; Xu et al., 2023] froze the text encoder to preserve generalization, recent work by Peng et al. argues that jointly fine-tuning both encoders is essential for aligning pixel-level features with semantic concepts. Despite these diverse findings in structured prediction and reasoning tasks, the manifestation of this Branch Bias in general image classification remains largely underexplored.
2.2 Efficient Transfer Learning in Vision-Language Image Classification
Prompt learning methods enhance the adaptability of VisionLanguage Models (VLMs) by dynamically adjusting pretrained representations. CoOp [Radford et al., 2021] introduces the learnable prompt vector, replacing fixed templates with optimized contexts to improve flexibility, though this sacrifices CLIP's zero-shot generalization. CoCoOp [Zhou et al., 2022a] addresses this limitation by incorporating dynamic instance-conditioned prompts, improving generalization to unseen categories. KgCoOp [Yao et al., 2023] further constrains the semantic gap between learned and handcrafted prompts, preserving general textual knowledge and enhancing model generalization. RPO [Lee et al., 2023] employs a masked attention mechanism to freeze the pretrained representations, reducing internal representation changes and improving model stability, particularly in data-scarce scenarios. MaPLe [Khattak et al., 2023] achieves cross-modal alignment by coupling visual-text prompts, enhancing adaptability to new categories and unseen domains. TCP [Yao et al., 2024] innovatively embeds category semantics into prompt tokens, strengthening generalization for new categories and few-shot settings. MMRL [Guo and Gu, 2025a] proposes a shared learnable representation space to facilitate efficient visual-text interaction, with regularization to prevent overfitting, especially suited for few-shot learning and task adaptation. MMRL++ [Guo and Gu, 2025b] further optimizes this framework by employing a parameterefficient low-rank alignment and progressive feature composition, which jointly facilitate robust generalization and training stability with minimal overhead.
Recent adapter-style methods provide another effective approach for model adaptation, typically integrating lightweight modules into VLMs for downstream task. CLIPAdapter [Gao et al., 2024b] introduces a residual MLP layer at the image encoder's end, significantly improving performance in visual tasks. MMA [Yang et al., 2024] proposes a multimodal adapter method, aggregating image and text features into a shared space, enhancing consistency between modalities and allowing cross-modal gradient flow, thereby improving the model's overall adaptability and task transfer capability. However, none of these methods have systematically investigated the Branch Bias in vision-language image classification, typically adhering to static adaptation paradigms that fail to dynamically balance the dual encoders. Consistent with previous research [Zhou et al., 2022b; Zhou et al., 2022a; Guo and Gu, 2025b], we use CLIP (transformerbased ViT-B/16 backbone) as the base model for our method.
3 Methodology
3.1 Preliminary
The CLIP model consists of an image encoder V and a text encoder T , encoding images and corresponding texts.
Image Encoder The image encoder V consists of L Transformer blocks [Vaswani et al., 2017], denoted as {Vi}Li=1 . The input image I ∈ RH×W×3 is divided into M patches, which are then embedded to obtain the initial features x0:
where x0 ∈ RM×dv (dv is the image embedding dimension). The patch embeddings xi-1, along with a learnable class (CLS) token ci-1, serve as inputs to the next Transformer block Vi and are processed sequentially:
Finally, a patch projection layer maps the CLS token cL from the last Transformer block VL into a shared VisionLanguage (V-L) latent space to obtain the final image rep-
where x ∈ Rd , and d is the feature dimension of the shared V-L space.
Text Encoder For a given text T (e.g., "A photo of a [CLASS]."), it is first tokenized and converted into word embeddings w0 using a Text Embedding layer:
where w0 ∈ RN×dt , with N as the token length and dt as the text embedding dimension.
At each layer, wi-1 is sequentially processed by the next Transformer block Ti to extract text features wi:
The final text representation w is obtained by projecting the last token output from the final Transformer block TL into the shared V-L space via a Text Projection layer:
where w ∈ Rd .
Zero-shot Classification Given the image representation x and text representations {wc}Nc c=1 , where Nc is the number of classes, CLIP computes the cosine similarity between them:
where | · | denotes the L2 norm. The classification probability for each class c is then predicted as:
where τ is a learnable temperature parameter in CLIP. The class with the highest probability is selected as the final prediction.
3.2 A3B2: Adaptive Asymmetric Adapter
Experimental Observations on Branch Bias
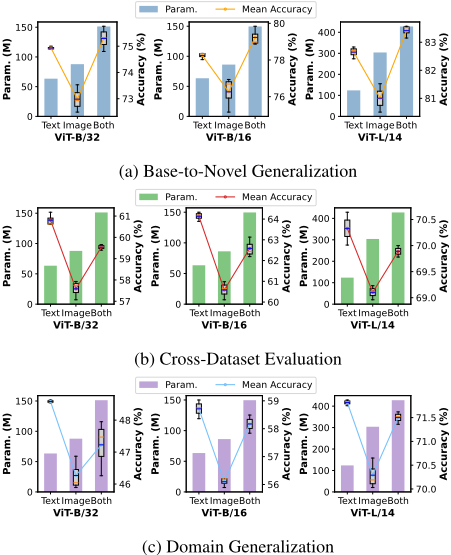
We conduct extensive exploratory experiments to investigate CLIP's Branch Bias in image classification tasks. Specifically, we apply 11 diverse image datasets across three widely used image classification tasks (base-to-novel generalization, cross-dataset evaluation, and domain generalization). By fine-tuning a basic adapter (a pair of dimensionality reduction and expansion matrices) on each layer of the image or text encoders in three different CLIP variants (ViT-B/32, ViTB/16, ViT-L/14), we evaluate performance across different tasks. Fig. 1 shows the average performance across these tasks, along with the parameter sizes of the image and text encoders in various CLIP variants. Further details (experimental setup and additional results) are available in the extended version. We summarize the following three insights:
Insight I In various tasks, fine-tuning additional parameters on the image encoder results in lower performance gains compared to the text encoder.
Insight II In in-distribution tasks (e.g., base-to-novel generalization), fine-tuning adapters on both encoders achieves the best performance.
Insight III In out-of-distribution tasks (e.g., crossdataset evaluation and domain generalization), fine-tuning additional parameters on the image encoder may harm the transferability of VLMs on non-distribution data.
Task-adaptive and Structure-asymmetric Adapter
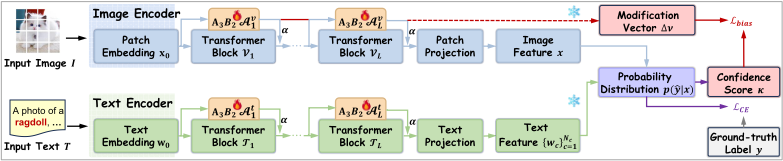
Based on the insights above, we propose an asymmetric architecture where adapters are always active on the text encoder (Insight I), while the image encoder's adaptation is dynamically regulated (Insight II & III).
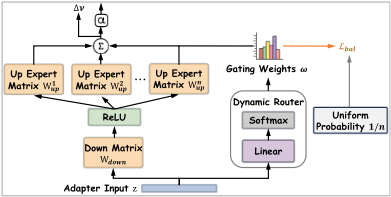
As shown in Fig. 2, we integrate the A3B2 adapter (details in Fig. 3) into the CLIP backbone. For the text encoder, we modify Eq. 5 by adding the adapter At to each layer:
where underline indicates trainable modules, and α controls the adaptation strength. ReLU(·) is the activation function. W t downi ∈ Rdht×r and W tup ki ∈ Rr×dht , where dht represents the hidden layer dimension of the text encoder and rank r ≪ dht, represent the "Down" matrix and k-th "Up" expert matrix in text encoder layer Ti, respectively. Additionally, a dynamic router computes the expert weights:
where tW g i ∈ Rdht×n , n is the number of experts.
Similarly, for the image encoder, we introduce an adapter Av at each layer to modify Eq. 2:
where W v downi ∈ Rdhv×r and W v up ki ∈ Rr×dhv are the "Down" expert matrix and k-th "Up" matrix of image encoder layer Vi, respectively, with dhv as the hidden dimension of the image encoder. vwi ∈ Rn represents the gating weights from the router:
Rather than rigidly locking the image encoder, we fine-tune the image adapters while constraining their optimization via a novel uncertainty-aware mechanism, described below.
Optimization Objectives
To effectively alleviate Branch Bias and ensure structural diversity within the adapters [Mu and Lin, 2025], we introduce two auxiliary objectives: Uncertainty-Aware Adapter Dampening (UAAD) and Load Balancing Regularization.
Uncertainty-Aware Adapter Dampening Insight III suggests that aggressive modification of image features on out-of-distribution (OOD) data degrades performance. To address this without manual locking, we propose UAAD. This mechanism leverages the model's prediction confidence to gauge whether a sample lies within the distribution. Low confidence implies potential OOD data, triggering a penalty on the image adapter's activation magnitude [Hendrycks and Gimpel, 2016].
Let p(ˆ y|x) be the softmax probability distribution for the image feature x. We define the confidence score as κ = max p(ˆ y|x). The bias alleviation loss Lbias is formulated as:
where B is the batch size, and ∆vi,j = Avi (zj) represents the feature modification vector produced by the image adapter at layer i. When the model is uncertain (low κ), Lbias forces the adapter output ∆v towards zero, effectively reverting the model to the robust pre-trained CLIP features.
Load Balancing Regularization Standard MoE routing often suffer from expert collapse. To prevent this, we enforce a uniform distribution of expert usage across the batch. Unlike methods relying on selection frequency [Fedus et al., 2022], we minimize the variance of the routing probabilities directly. Let ¯wl,j,k (derived from Eq. 10 and Eq. 12) denote the gating probability of the k-th expert for the j-th sample in the l-th layer, averaged over the batch. We adopt a coefficient of variation [Shazeer et al., 2017] based loss:
| Dataset | Setting | CLIP | CoOp | CoCoOp | KgCoOp | RPO | MaPLe | CLIP-Adapter | TCP | MMA | MMRL | MMRL++ | A3B2 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ImageNet | Base 72.40 Novel 68.09 70.18 | 76.18 70.47 73.21 | 75.63 70.45 72.95 | 76.08 70.59 73.23 | 74.53 70.26 72.33 | 76.73 70.49 73.48 | 74.10 68.89 71.40 | 75.39 70.21 72.08 | 77.19 69.63 73.22 | 77.00 70.70 73.72 | 76.87 70.72 73.67 | 77.37 70.83 73.96 | |
| Caltech101 | HM Base Novel HM | 97.16 98.36 94.21 94.18 95.66 96.22 | 97.59 94.69 | 96.12 | 98.15 94.65 96.37 | 97.14 94.32 95.71 | 98.26 97.29 94.14 94.10 82.54 95.67 | 97.61 94.54 96.05 | 98.54 93.63 96.02 | 96.09 | 98.19 94.07 | 98.26 94.36 96.27 | 98.73 95.17 96.92 |
| Base OxfordPets Novel HM | 91.26 97.15 94.11 | 95.27 97.78 96.51 | 95.39 97.32 96.35 | 94.84 97.43 96.12 | 88.76 96.66 92.54 | 95.21 97.93 96.55 | 94.22 97.05 95.61 | 94.79 97.59 96.17 | 95.20 97.59 96.38 | 95.41 97.26 96.33 | 95.16 97.60 96.36 | 95.52 97.83 96.66 | |
| Base StanfordCars Novel HM | 63.77 74.96 68.91 | 74.89 71.70 73.26 | 69.28 73.83 71.48 | 71.93 73.35 72.63 | 66.18 75.65 70.60 | 76.17 73.33 74.72 | 65.93 75.44 70.37 | 70.47 75.40 72.85 | 78.95 72.53 75.60 | 75.55 74.99 75.27 | 75.60 74.83 75.21 | 81.96 75.58 78.64 | |
| Flowers102 | Base Novel HM | 71.73 77.45 74.48 | 97.12 71.94 82.65 | 86.29 74.21 79.80 | 96.20 72.88 82.93 | 73.82 78.44 76.06 | 97.09 72.03 82.70 | 75.18 75.58 75.38 | 93.41 75.25 83.35 | 97.79 75.96 85.50 | 97.79 75.13 84.98 | 97.68 76.59 85.86 | 98.14 77.39 86.54 |
| Food101 | Base Novel HM | 90.07 91.15 90.61 | 90.26 91.25 90.75 | 90.66 91.58 91.12 | 90.24 91.50 90.87 | 88.92 89.73 89.32 | 90.29 91.54 90.91 | 90.29 91.12 90.70 | 90.57 91.53 91.05 | 88.88 90.51 89.69 | 90.52 91.82 91.17 | 90.73 92.35 91.53 | 89.21 91.75 90.46 |
| FGVCAircraft | Base Novel HM | 27.63 35.95 31.25 | 37.82 33.31 35.42 | 33.53 32.27 32.89 | 36.85 33.29 34.98 | 28.15 34.25 30.90 | 39.22 34.35 36.62 | 30.69 36.35 33.28 | 35.79 35.19 35.49 | 43.18 35.39 38.90 | 38.70 37.51 38.10 | 39.53 37.16 38.31 | 47.59 37.48 41.93 |
| SUN397 | Base Novel HM | 69.35 75.56 72.32 | 81.23 75.43 78.22 | 78.39 77.37 77.88 | 80.82 74.97 77.79 | 74.40 77.67 76.00 | 81.85 76.93 79.31 | 74.57 77.40 75.96 | 79.96 78.11 79.02 | 81.50 77.75 79.58 | 81.87 79.16 80.49 | 81.55 79.05 80.28 | 82.36 78.72 80.50 |
| DTD | Base Novel HM | 53.24 60.87 56.80 | 78.63 50.48 61.49 | 67.75 55.64 61.10 | 78.32 56.88 65.90 | 56.02 61.31 58.55 | 80.71 55.63 65.86 | 57.72 60.79 59.22 | 78.20 53.90 63.81 | 84.03 65.05 73.33 | 83.22 62.04 71.09 | 83.18 62.57 71.42 | 84.18 64.71 73.17 |
| EuroSAT | Base Novel HM | 57.02 64.03 60.32 | 88.81 59.38 71.17 | 78.41 66.90 | 85.82 58.89 | 53.52 65.53 | 92.63 70.13 79.82 | 62.80 62.76 62.78 | 84.25 70.17 76.57 | 94.22 62.94 | 90.39 68.44 | 90.64 68.73 | 95.86 69.75 80.75 |
| UCF101 | Base Novel | 70.89 78.42 | 83.71 74.17 | 72.20 78.71 | 69.85 | 58.92 71.53 | 84.89 78.06 | 75.52 77.54 | 81.76 77.93 | 75.47 86.20 | 77.90 | 78.18 | 86.49 79.58 |
| HM | 74.47 | 78.65 | 74.56 76.58 | 83.54 74.36 78.68 | 73.12 72.32 | 81.33 | 76.52 | 79.80 | 77.73 81.75 | 85.52 78.35 81.78 | 85.47 79.57 82.42 | 82.89 | |
| Average | Base Novel HM | 69.50 74.35 71.84 | 82.03 71.83 76.59 | 77.42 73.53 75.42 | 81.16 72.62 76.65 | 70.27 74.27 72.21 | 83.00 74.05 78.27 | 72.57 74.27 73.41 | 80.20 74.53 77.26 | 84.15 74.43 78.99 | 83.11 75.41 79.07 | 83.15 75.78 79.29 | 85.22 76.25 80.49 |
where 1/n represents the target uniform probability. Minimizing this objective penalizes deviations from a balanced distribution, ensuring diverse expert utilization.
Total Objective The model is primarily optimized using the cross-entropy loss, derived from the classification probabilities defined in Sec. 3.1. For a batch of size B, given the ground-truth label yj for the image future xj , this loss is defined as:
The final training objective is a weighted sum of the crossentropy loss and the auxiliary regularizations:
where λbias governs the suppression strength for uncertain samples, and λbal enforces the diversity of expert utilization. This formulation allows A3B2 to adaptively balance between general linguistic knowledge and task-specific visual adaptation, dynamically alleviating branch bias during training.
4 Experiments
We comprehensively evaluate A3B2's performance around three core image classification tasks in few-shot setting and validate the effectiveness of the discovered insights.
4.1 Experimental Setup
Base-to-Novel Generalization Consistent with previous studies [Brown et al., 2020; Guo and Gu, 2025a], this evaluation divides the dataset into base and novel categories. The model is trained on base categories under a few-shot setting and tested separately on both base and novel categories. This evaluation includes 11 visual classification benchmark datasets: ImageNet [Deng et al., 2009], Caltech101 [FeiFei et al., 2004], OxfordPets [Parkhi et al., 2012], StanfordCars [Krause et al., 2013], Flowers102 [Nilsback and Zisserman, 2008], Food101 [Bossard et al., 2014], FGVCAircraft [Maji et al., 2013], SUN397 [Xiao et al., 2010], DTD [Cimpoi et al., 2014], EuroSAT [Helber et al., 2019], and UCF101 [Soomro et al., 2012].
| Method | ImageNet | Caltech101 | OxfordPets | StanfordCars | Flowers102 | Food101 | FGVCAircraft | SUN397 | DTD | EuroSAT | UCF101 | Average |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| CoOp | 71.30 | 94.20 | 89.91 | 64.20 | 70.66 | 85.82 | 22.34 | 66.36 | 43.36 | 48.50 | 68.90 | 65.43 |
| KgCoOp | 71.12 | 94.24 | 90.29 | 65.39 | 71.23 | 86.24 | 21.99 | 67.03 | 44.39 | 43.89 | 68.67 | 65.34 |
| MaPLe | 71.91 | 93.39 | 90.41 | 64.37 | 70.28 | 85.63 | 22.88 | 66.04 | 44.60 | 39.87 | 67.91 | 64.54 |
| TCP | 70.36 | 94.21 | 90.16 | 65.23 | 71.46 | 86.73 | 23.74 | 67.13 | 45.06 | 43.00 | 68.91 | 65.56 |
| MMA | 72.45 | 92.39 | 89.59 | 61.69 | 68.52 | 81.94 | 24.19 | 66.32 | 44.29 | 39.70 | 67.86 | 63.65 |
| MMRL | 72.10 | 93.90 | 91.31 | 65.07 | 72.22 | 85.68 | 25.44 | 67.24 | 44.78 | 48.66 | 68.07 | 66.24 |
| MMRL++ | 71.96 | 93.97 | 91.43 | 65.38 | 72.57 | 85.72 | 25.28 | 67.65 | 44.83 | 48.49 | 68.52 | 66.38 |
| A3B2 | 72.57 | 94.52 | 91.36 | 65.32 | 72.15 | 86.75 | 24.53 | 67.15 | 45.30 | 47.42 | 69.43 | 66.39 |
| Method | ImageNet | -V2 | -S | -A | -R | Average |
|---|---|---|---|---|---|---|
| CoOp | 71.30 | 64.52 | 49.02 | 51.29 | 76.69 | 60.38 |
| KgCoOp | 71.12 | 64.33 | 48.97 | 51.41 | 76.60 | 60.33 |
| MaPLe | 71.91 | 64.69 | 48.91 | 49.26 | 76.47 | 59.83 |
| TCP | 70.36 | 63.60 | 48.74 | 50.50 | 76.70 | 59.89 |
| MMA | 72.45 | 65.23 | 48.09 | 48.07 | 75.43 | 59.21 |
| MMRL | 72.10 | 64.35 | 48.70 | 48.82 | 76.40 | 59.57 |
| MMRL++ | 71.97 | 64.61 | 48.95 | 48.69 | 76.52 | 59.69 |
| A3B2 | 72.52 | 65.47 | 49.13 | 51.75 | 76.91 | 60.81 |
Cross-Dataset Evaluation This evaluation measures a model's discriminative ability on unseen datasets and its grasp of general knowledge. Following CoCoOp [Zhou et al., 2022a], the model is trained on ImageNet with 1k classes and 16 shots per class, then directly evaluated on 10 other datasets mentioned in the base-to-novel generalization task.
Domain Generalization This task evaluates the model's robustness to domain shifts and its discriminative ability to out-of-distribution data. Following the setup of CoCoOp [Zhou et al., 2022a], we fine-tune the model on ImageNet and test it on four of its variants: ImageNetV2 [Recht et al., 2019], ImageNet-Sketch [Wang et al., 2019], ImageNetA [Hendrycks et al., 2021b], and ImageNet-R [Hendrycks et al., 2021a].
Baselines We compare the proposed A3B2 with 11 competitive methods, including: CLIP (zero-shot) [Radford et al., 2021], CoOp [Radford et al., 2021], CoCoOp [Zhou et al., 2022a], KgCoOp [Yao et al., 2023], RPO [Lee et al., 2023], MaPLe [Khattak et al., 2023], CLIP-Adapter [Gao et al., 2024b], TCP [Yao et al., 2024], MMA [Yang et al., 2024], MMRL [Guo and Gu, 2025a], and MMRL++ [Guo and Gu, 2025b].
Implementation Details Consistent with previous studies [Yang et al., 2024; Guo and Gu, 2025b], all experiments are conducted using a pre-trained transformer-based ViT-B/16 backbone of the CLIP model under a 16-shot setting (i.e., 16 training samples per class). To ensure consistency with prior work [Radford et al., 2021; Zhou et al., 2022a; Yang et al., 2024] as much as possible, we set the batch size to 8, with 5 epochs for ImageNet and 10 epochs for other datasets. The same image augmentation methods are used, and the SGD optimizer is employed with an initial learning rate of 0.0015, a momentum of 0.9, and a weight decay of 0.0005, combined with a cosine annealing scheduler with 1 epoch of warm-up. The text templates for the proposed A3B2 follow [Gao et al., 2024b], with the default number of experts n = 3, low-rank r = 32, coefficient α = 0.001, suppression strength λbias = 0.3 and balance parameter λbal = 0.1. The optimization strategies for other baselines follow the settings of the original papers. For fairness, all baselines are re-implemented under the same experimental setup and trained with mixed-precision acceleration on a single NVIDIA A800 GPU. Final performance is reported as the average over three random seeds (seed=1,2,3).
4.2 Base-to-Novel Generalization
In this task, we report the model's accuracy on both base and novel classes, along with their harmonic mean (HM), as shown in Table 1. Overall, our method consistently outperforms all baselines across all metrics and datasets. The key findings are as follows:
- Among all baselines, the recently proposed MMA and MMRL++ achieve the best average performance. MMRL++ leverages its decoupled inference strategy and progressive inter-layer composition to achieve leading novel-class accuracy with high parameter efficiency. MMA, on the other hand, integrates features from different branches into a shared space, enhancing gradient flow across branches, thus improving consistency between modalities and achieving optimal base-class recognition.
- The proposed A3B2 consistently leads all metrics across 11 datasets. Compared to MMA, which performs best on baseclass recognition, and MMRL++, which excels on the novel and HM metrics, A3B2 shows a significant advantage in average performance. These impressive results validate the effectiveness of our insights.
- In this in-distribution task, methods with dual-branch optimization (e.g., MaPLe, MMA, and MMRL++) generally outperform single-branch optimization methods (e.g., CoOp, CoCoOp, KgCoOp, and TCP), further confirming the universality and broad applicability of our Insight II.
4.3 Cross-Dataset Evaluation
We have compared the top 7 methods in the base-to-novel generalization task with the proposed A3B2 in the crossdataset evaluation task, as shown in Table 2. We observe that MMA performs poorly in our experimental setup, which we attribute to MMA simultaneously adapting the image encoder in out-of-distribution tasks, contrary to our Insight III. And this experiment validates the broad applicability of the Insight III: Text-only encoder optimization methods (e.g., CoOp, CoCoOp, KgCoOp) generally outperform methods with image encoder optimization (e.g., RPO, MaPLe, MMA). Notably, the MMRL and MMRL++ with image encoder optimization even outperform the proposed A3B2 in some cases. We believe these unexpected results stem from their use of a loss-function-driven model exploration strategy during optimization, differing from other methods, whereas we adopt a more general and adaptive structural design based on exploratory observations.
| n | Base | Novel | HM | r | Base | Novel | HM | α | Base | Novel | HM | λbias | Base | Novel | HM | λbal | Base | Novel HM |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | 82.75 | 73.95 | 78.10 | 8 | 82.93 | 74.69 | 78.59 | 0.0001 | 85.13 | 75.62 | 80.09 | 0.1 | 84.82 | 75.69 80.00 | 0.01 | 85.15 | 75.93 | 80.28 |
| 2 | 84.89 | 75.83 | 80.10 | 16 | 84.24 | 75.26 | 79.50 | 0.0005 | 85.07 | 75.98 | 80.27 | 0.2 | 84.93 | 75.91 80.17 | 0.05 | 85.26 | 76.13 | 80.44 |
| 3 | 85.22 | 76.25 | 80.49 | 32 | 85.22 | 76.25 | 80.49 | 0.001 | 85.22 | 76.25 | 80.49 | 0.3 | 85.22 | 76.25 80.49 | 0.1 | 85.22 | 76.25 | 80.49 |
| 4 | 84.92 | 75.52 | 79.94 | 64 | 85.37 | 75.63 | 80.21 | 0.005 | 85.25 | 76.15 | 80.44 | 0.4 | 85.08 | 75.62 80.07 | 0.15 | 85.23 | 76.17 | 80.45 |
| 5 | 83.41 | 74.73 | 78.83 | 128 | 84.57 | 73.82 | 78.83 | 0.01 | 85.38 | 76.09 | 80.47 | 0.5 | 84.67 | 75.59 79.87 | 0.2 | 85.03 | 75.82 | 80.16 |
4.4 Domain Generalization
As shown in Table 3, the text-only encoder optimization methods significantly outperform the methods with image encoder optimization, further validating the effectiveness of the Insight III. Meanwhile, we also observe that the MMRL and MMRL++ methods perform poorly on this task, while our A3B2 method consistently achieves leading performance. This suggests that the A3B2, which focuses more on model structure optimization, is more stable, providing strong support for its future application and the insights derived for related research.
4.5 In-depth Analysis
We conduct analytical experiments on 11 datasets for the base-to-novel task; detailed results are in the extended version.
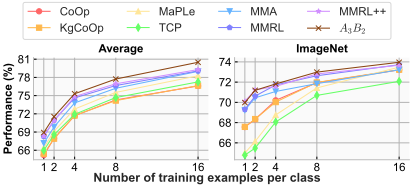
Few-Shot Learning As shown in Fig. 4, A3B2 consistently achieves the best performance across 11 datasets under all shot settings, with its advantage increasing as the number of shots grows. This demonstrates its strong transfer capability and robustness, even in data-scarce few-shot scenarios.
Sensitivity Analysis We analyze the sensitivity of the A3B2 hyperparameters, as shown in Table 4.
Number of Experts n. Too few experts limit model expressiveness, while too many may lead to overfitting. The optimal balance is achieved when n = 3.
Low-rank r. The low-rank r faces a similar trade-off to the number of experts. Performance is best when r = 32.
Balance Coefficient α. The coefficient α controls the relationship between pre-trained and learnable weights, which are more effective for base and novel settings, respectively. A good balance is achieved when α = 0.001.
Suppression Strength λbias. This term controls the strength of uncertainty-aware dampening on image adapters. Moderate suppression (λbias = 0.3) best balances robustness and adaptability, while overly large values over-constrain visual adaptation.
Balance Parameter λbal. This parameter regulates expert utilization diversity. A moderate value (λbal = 0.1) effectively prevents expert collapse and yields the most stable performance across base and novel classes.
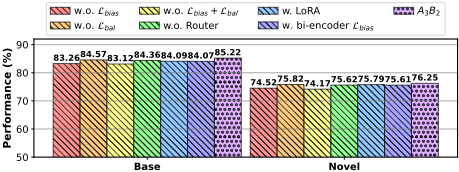
Ablation Study As shown in Fig. 5, removing any component degrades performance, confirming their effectiveness. Notably, removing Lbias + Lbal leads to the largest drop, highlighting their synergy. Applying Lbias to the text encoder ("w. bi-encoder Lbias") also causes a significant decline, validating the applicability of Insight II & III.
We provide a cost analysis of A3B2 and additional experiments on ResNet-based CLIP in the extended version.
5 Conclusion
This paper identifies the Branch Bias issue in few-shot visionlanguage classification, showing that fine-tuning the image encoder can be detrimental to out-of-distribution robustness. We propose A3B2, an adaptive asymmetric adapter that modulates the image branch based on prediction uncertainty. Extensive experiments demonstrate that A3B2 consistently improves performance across various few-shot settings, providing an effective solution for branch-aware adaptation.
Acknowledgments
This research was supported by grants from the "Pioneer" and "Leading Goose" R&D Program of Zhejiang under Grant No. 2025C02022 and the National Natural Science Foundation of China (No.62307032).
@inproceedings{ijcai2026p238,
  title     = {A₃B₂: Adaptive Asymmetric Adapter for Alleviating Branch Bias in Vision-Language Image Classification with Few-Shot Learning},
  author    = {Zhou, Yiyun and Jiang, Zhonghua and Han, Wenkang and Li, Kunxi and Xu, Mingjing and Yao, Chang and Chen, Jingyuan},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {2136--2144},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/238},
  url       = {https://doi.org/10.24963/ijcai.2026/238},
}
TY - CPAPER TI - A₃B₂: Adaptive Asymmetric Adapter for Alleviating Branch Bias in Vision-Language Image Classification with Few-Shot Learning AU - Zhou, Yiyun AU - Jiang, Zhonghua AU - Han, Wenkang AU - Li, Kunxi AU - Xu, Mingjing AU - Yao, Chang AU - Chen, Jingyuan T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 2136 EP - 2144 DO - 10.24963/ijcai.2026/238 UR - https://doi.org/10.24963/ijcai.2026/238 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





