
Cost of Structural Learning Under Censored Feedback: A Threshold-Bandit Approach
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 4448-4455.
https://doi.org/10.24963/ijcai.2026/495
Keywords
- Agent-based and Multi-agent Systems: Agent communication
- Machine Learning: Online learning
- Agent-based and Multi-agent Systems: Multi-agent learning
- Agent-based and Multi-agent Systems: Coordination and cooperation
- Machine Learning: Multi-armed bandits
Abstract
In many multi-agent applications, tasks yield rewards only when executed by a coalition meeting an unknown size threshold; otherwise, feedback is fully censored. This censorship creates an identifiability problem: agents cannot distinguish stochastic failure from insufficient coordination. We formalize this setting as the Threshold-Activated Cooperative Multi-Armed Bandit (TAC-MAB) and analyze it under both centralized and decentralized coordination. We show that a centralized algorithm (C-TAC) achieves cumulative regret O(log T), decomposed into a structural-search term that captures the cost of resolving feasibility under censored feedback and a statistical-monitoring term for value estimation. We then introduce D-TAC, a decentralized event-triggered protocol in which agents synchronize only when their structural beliefs change. Empirically, D-TAC achieves a 23x reduction in communication relative to the centralized baseline while preserving feasibility alignment under conservative belief fusion. These results characterize the coordination cost of learning under censored feedback and show that near-centralized communication efficiency is achievable without continuous synchronization.
- [Abernethy et al., 2016] Jacob D Abernethy, Kareem Amin, and Ruihao Zhu. Threshold bandits, with and without cen- sored feedback. Advances In Neural Information Process- ing Systems, 29, 2016.
- [Agarwal et al., 2022] Mridul Agarwal, Vaneet Aggarwal, and Kamyar Azizzadenesheli. Multi-agent multi-armed bandits with limited communication. Journal of Machine Learning Research, 23(212):1-24, 2022.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine learning, 47:235-256, 2002.
- [Barrett et al., 2014] Samuel Barrett, Noa Agmon, Noam Hazon, Sarit Kraus, and Peter Stone. Communicating with unknown teammates. In ECAI 2014, pages 45-50. IOS Press, 2014.
- [Cao et al., 2024] Xiao Cao, Mingyang Li, Yuting Tao, and Peng Lu. Hma-sar: Multi-agent search and rescue for un- known located dynamic targets in completely unknown environments. IEEE Robotics and Automation Letters, 9(6):5567-5574, 2024.
- [Chakraborty et al., 2017] Mithun Chakraborty, Kai Yee Phoebe Chua, Sanmay Das, and Brendan Juba. Coordinated versus decentralized exploration in multi- agent multi-armed bandits. In IJCAI, pages 164-170, 2017.
- [Chang and Lu, 2023] William Chang and Yuanhao Lu. Optimal cooperative multiplayer learning bandits with noisy rewards and no communication. arXiv preprint arXiv:2311.06210, 2023.
- [Chang et al., 2022] William Chang, Mehdi Jafarnia- Jahromi, and Rahul Jain. Online learning for cooperative multi-player multi-armed bandits. In 2022 IEEE 61st Conference on Decision and Control (CDC), pages 7248-7253. IEEE, 2022.
- [Chawla et al., 2020] Ronshee Chawla, Abishek Sankarara- man, Ayalvadi Ganesh, and Sanjay Shakkottai. The gos- siping insert-eliminate algorithm for multi-agent bandits. In International conference on artificial intelligence and statistics, pages 3471-3481. PMLR, 2020.
- [Chen et al., 2013] Wei Chen, Yajun Wang, and Yang Yuan. Combinatorial multi-armed bandit: General framework and applications. In International Conference on Machine Learning, pages 151-159. PMLR, 2013.
- [Chen et al., 2023] Yu-Zhen Janice Chen, Lin Yang, Xuchuang Wang, Xutong Liu, Mohammad Hajiesmaili, John C.S. Lui, and Don Towsley. On-demand com- munication for asynchronous multi-agent bandits. In International Conference on Artificial Intelligence and Statistics, pages 3903-3930. PMLR, 2023.
- [Combes et al., 2015] Richard Combes, Mohammad Sadegh Talebi Mazraeh Shahi, Alexandre Proutiere, et al. Combi- natorial bandits revisited. Advances in neural information processing systems, 28, 2015.
- [Das et al., 2022] Debojit Das, Shweta Jain, and Sujit Gu- jar. Budgeted combinatorial multi-armed bandits. arXiv preprint arXiv:2202.03704, 2022.
- [Kalathil et al., 2014] Dileep Kalathil, Naumaan Nayyar, and Rahul Jain. Decentralized learning for multiplayer multiarmed bandits. IEEE Transactions on Information Theory, 60(4):2331-2345, 2014.
- [Landgren et al., 2021] Peter Landgren, Vaibhav Srivastava, and Naomi Ehrich Leonard. Distributed cooperative deci- sion making in multi-agent multi-armed bandits. Automat- ica, 125:109445, 2021.
- [Magesh and Veeravalli, 2021] Akshayaa Magesh and Venu- gopal V. Veeravalli. Decentralized heterogeneous multi- player multi-armed bandits with non-zero rewards on collisions. IEEE Transactions on Information Theory, 68(4):2622-2634, 2021.
- [Mahajan et al., 2019] Anuj Mahajan, Tabish Rashid, Mikayel Samvelyan, and Shimon Whiteson. Maven: Multi-agent variational exploration. Advances in neural information processing systems, 32, 2019.
- [Martínez-Rubio et al., 2018] David Martínez-Rubio, Varun Kanade, and Patrick Rebeschini. Decentralized coopera- tive stochastic bandits. arXiv preprint arXiv:1810.04468, 2018.
- [Oliehoek et al., 2016] Frans A Oliehoek, Christopher Am- ato, et al. A concise introduction to decentralized POMDPs, volume 1. Springer, 2016.
- [Tobin et al., 2017] Josh Tobin, Rachel Fong, Alex Ray, Jonas Schneider, Wojciech Zaremba, and Pieter Abbeel. Domain randomization for transferring deep neural net- works from simulation to the real world. In 2017 IEEE/RSJ international conference on intelligent robots and systems (IROS), pages 23-30. IEEE, 2017.
- [Tran-Thanh et al., 2012] Long Tran-Thanh, Archie Chap- man, Alex Rogers, and Nicholas Jennings. Knapsack based optimal policies for budget-limited multi-armed bandits. In Proceedings of the AAAI Conference on Ar- tificial Intelligence, volume 26, pages 1134-1140, 2012.
- [Verma et al., 2019] Arun Verma, Manjesh Hanawal, Arun Rajkumar, and Raman Sankaran. Censored semi-bandits: A framework for resource allocation with censored feed- back. Advances in Neural Information Processing Sys- tems, 32, 2019.
- [Zhang et al., 2024] Jiahao Zhang, Tao Lin, Weiqiang Zheng, Zhe Feng, Yifeng Teng, and Xiaotie Deng. Learn- ing thresholds with latent values and censored feedback. In The Twelfth International Conference on Learning Rep- resentations (ICLR), 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Cooperative multi-agent systems often operate in environments where task success depends on coordinated action by multiple agents, and execution feedback becomes informative only when a sufficient coalition acts jointly. Consider domains such as search-and-rescue [Cao et al., 2024], where multiple agents explore an environment and success depends on deploying a coalition of the right size acting in unison. Similar coordination dependencies arise in distributed sensing, signal jamming, and logistics coordination, where agents must combine capabilities to achieve an outcome.
In these settings, the coalition size required to produce informative feedback can be viewed as a latent feasibility threshold, a quantitative constraint that is hidden from agents but determines whether a joint action yields any reward. When too few agents are deployed, execution fails silently without producing informative feedback, making stochastic failure indistinguishable from insufficient coordination.
Existing models for cooperative decision making typically assume execution feedback is informative whenever agents act, enabling learning through independent or weakly coordinated exploration [Landgren et al., 2021]. This challenge persists across modeling frameworks: MARL methods under sparse rewards [Mahajan et al., 2019] treat feasibility as a learning problem but do not exploit its structural nature, while Dec-POMDP formulations [Oliehoek et al., 2016] assume observation models that censored feedback violates. A multiarmed bandit framing, by contrast, isolates the allocation decision from state and policy dynamics, making the coordination cost itself analytically tractable. When task outcomes are gated by unknown coalition-size requirements, execution attempts below the feasibility threshold yield fully censored feedback, and the probability of independently forming a feasible coalition vanishes as coalition-size requirements grow. Independent exploration thus cannot reliably resolve feasibility on its own.
Coordination requirements could in principle be specified offline, but feasibility often depends on transient or adversarial conditions that resist pre-programming, and offline training suffers from the sim-to-real gap [Tobin et al., 2017]. Teams must therefore infer feasibility online. Yet committing more agents is not free: practical deployments incur communication and execution costs [Chakraborty et al., 2017] (energy, bandwidth, time) when allocating larger coalitions. This creates an exploration dilemma: independent learning fails under censored feedback, while naive full coordination is prohibitively costly. We measure the resulting inefficiency using regret, which captures the cost of operating under incorrect feasibility beliefs.
To address this challenge, we introduce the ThresholdActivated Cooperative Multi-Armed Bandit (TAC-MAB), a model that isolates the structural difficulty of feasibilitygated feedback. We first analyze an idealized centralized baseline (C-TAC) and prove O(logT) cumulative regret, decomposed into a structural-search term that captures the cost of resolving feasibility under censored feedback and a statistical-monitoring term for value estimation (Theorem 1).
We then propose D-TAC, a decentralized event-triggered protocol in which agents synchronize only when structural beliefs change. Once structural beliefs align, D-TAC executes the same plan as C-TAC and empirically approaches its asymptotic performance, modulo a transient during the structural-learning phase (Section 4). Empirically, D-TAC achieves a 23× reduction in communication relative to the centralized baseline while preserving feasibility alignment through conservative belief fusion.
2 ProblemFormulation
We study a cooperative multi-agent learning problem in which M agents must allocate themselves across K tasks, where each task requires an unknown integer number of agents to activate. Below this threshold, execution attempts yield no informative feedback. We refer to this setting as the Threshold-Activated Cooperative Multi-Armed Bandit (TAC-MAB).
TAC-MAB is a multi-agent specialization of the censored semi-bandit framework of Verma et al. [2019], which studies single-learner allocation with continuous-valued thresholds and a divisible resource budget. Our setting differs in three structural ways: the resource is a coalition of M distinct agents (rather than a divisible budget), thresholds are integer-valued (rather than continuous), and observations are partitioned by agent assignment under decentralized execution. These differences enable the study of decentralized coordination protocols, which we develop in Section 4.
2.1 Agents and Task Types
The team consists of M homogeneous agents indexed by i ∈ {1, . . . ,M} operating over a finite horizon T. The environment contains K stationary tasks indexed by k ∈ {1, . . . , K}, each characterized by a feasibility threshold τk ∈ Z≥1 (the minimum coalition size required to activate task k, possibly with τk > M for structurally infeasible tasks), a success probability pk ∈ [0, 1] (the probability that task k succeeds when executed by a feasible coalition), and a task value vk ∈ R+ (the reward obtained on a successful execution). These parameters are stationary over the horizon. Together with the fixed feasibility set C defined in Section 2.4, this makes the oracle's optimal allocation c⋆ time-invariant.
An instance of TAC-MAB is identified by (τ , p, v, M, T ). The vectors τ and p are unknown and must be learned through interaction. The remaining quantities are known to the team: K, M, T, the per-task values v = {vk}Kk=1 , and a known lower bound pmin ∈ (0, 1] such that pk ≥ pmin for all feasible tasks (i.e., tasks with τk ≤ M). We treat v as known; this is standard in resource-allocation problems with pre-specified task values [Verma et al., 2019] and lets us isolate the cost of learning (τ, p). Extending to unknown v is left to future work.
We assume K > M throughout, the regime in which the team cannot evaluate all tasks in parallel and must select a subset to attempt each round. This is what makes the allocation problem non-trivial: even with full knowledge of (τ, p, v), the optimal allocation solves a 0/1 knapsack with weights τk and values pkvk.
2.2 Joint Actions and Censored Feedback
In round t, the team selects ct = (c1,t, . . . , cK,t) with ck,t ∈ {0, . . . ,M} and ∑k ck,t ≤ M. For each task k and round t, Xk,t ∼ Bernoulli(pk) is drawn independently across tasks and rounds. The observed outcome is
Censoring at observation, not generation. Xk,t is realized regardless of coalition size, but the team observes Yk,t = 0 deterministically when ck,t < τk. Crucially, when Yk,t = 0, the team cannot distinguish censoring (ck,t < τk) from stochastic failure (Xk,t = 0 with ck,t ≥ τk). This is the identifiability challenge that motivates our analysis.
Observation convention. We treat Yk,t as the per-task aggregate outcome; this is what enters the regret definition. In our implementation, the reward vk is distributed evenly across the coalition assigned to task k; each agent on task k thus observes the success indicator 1{Yk,t > 0} via its own share. The team-level cumulative reward and our regret analysis are invariant to this distribution choice.
2.3 Observations and Communication
Each agent i observes only the outcome Yk,t for its assigned task at round t, via the share convention above. Agents do not observe outcomes of other tasks, nor the thresholds τk, but each agent knows the coalition size assigned to its own task (via the coordinator in the centralized setting and via the protocol in the decentralized setting). A successful outcome (Yk,t > 0) reveals that the executed coalition was feasible and that Xk,t = 1; a failed outcome (Yk,t = 0) is uninformative about which of the two failure modes occurred.
Agents may communicate at the end of each round; communication, when it occurs, is reliable and synchronous within the round. We abstract communication cost as the number of messages exchanged per round (independent of payload size), corresponding to a shared-medium broadcast model for one-to-many transmissions and point-to-point unicast for direct messages. A single broadcast counts as one message, while all-to-all exchange among M agents incurs O(M 2 ) messages.
We analyze TAC-MAB under two coordination architectures. In the centralized architecture, all observations in a round are available to a coordinator that maintains global estimates and selects joint actions; this serves as a theoretical baseline (Section 3). In the decentralized architecture, each agent has access only to its own observations and may exchange messages with peers subject to the cost model above; coordination protocols are developed in Section 4. In our centralized analysis (Section 3), we treat coordinator-to-agent communication as a zero-cost idealization to isolate the statistical cost of learning; decentralized communication costs are accounted for in Section 4.
2.4 Objective and Regret
The objective of the team is to maximize cumulative reward over the horizon T. This requires solving two coupled subproblems online:
- Threshold learning under censored feedback. Estimate τ from observed outcomes, where failures below τk provide no information distinguishing insufficient coordination from stochastic failure.
- Optimal allocation under resource constraints. Given threshold estimates ˆ τ and value estimates ˆµ, select an allocation c ∈ C that maximizes expected reward, where C = {c ∈ ZK≥0 : ∑k ck ≤ M}. Since K > M, this is a 0/1 knapsack.
These sub-problems are coupled through the per-round resource constraint: probing a task's threshold requires committing agents to it, which forecloses other allocations that round. Threshold learning therefore competes with reward collection for the same scarce resource.
Let µk = pkvk. The oracle benchmark knows (τ,µ) and selects
which does not depend on t by stationarity. We assume a unique maximizer for clarity. Let
denote the expected reward of this optimal joint allocation. Cumulative regret is
where the expectation is over {Xk,t} and any randomness in the learning policy. The oracle is assumed to solve the allocation optimization exactly; regret is measured relative to this ideal benchmark.
Regret in TAC-MAB decomposes into two sources: the cost of resolving threshold uncertainty under censored feedback, and the cost of estimating the success probabilities p under the integer knapsack constraint. Theorem 1 (Section 3) characterizes both.
3 Centralized Coordination Baseline
We first analyze TAC-MAB under an idealized centralized coordination architecture in which a coordinator observes all task outcomes immediately and broadcasts joint allocations at zero cost. This baseline isolates the statistical difficulty of learning under censored feedback from the logistical cost of coordination, and provides a regret reference for the decentralized strategies in Section 4.
3.1 Structural and Statistical Uncertainty
Even with perfect information sharing, learning under TACMAB couples two sources of uncertainty. Structural uncertainty arises from unknown feasibility thresholds τ that gate informative feedback: when a coalition is below threshold, outcomes are fully censored and failures do not distinguish insufficient coordination from stochastic effects. Statistical uncertainty arises from unknown success probabilities p once a task is executed by a feasible coalition. Theorem 1 decomposes regret along this split.
To ensure regret is measured only with respect to information limitations, we assume the coordinator has access to an exact planning oracle that solves the integer 0/1 knapsack at each round given current estimates. Under this assumption, regret is attributable to censored feedback and statistical estimation, not computational approximation. For our integerthreshold setting, the knapsack is solved exactly in O(KM) time via dynamic programming.
3.2 AConstructive Centralized Strategy
We instantiate this baseline as C-TAC (Centralized Threshold-Activated Coordination), shown in Algorithm 1. We assume the identifiability condition: every feasible task k (i.e., τk ≤ M) satisfies pk ≥ pmin > 0 for some known constant pmin. Without this condition, feasibility cannot be distinguished from stochastic failure under censored feedback, making sublinear regret impossible.
C-TAC maintains a per-task phase ϕk ∈ {SEARCH, MONITOR, INFEASIBLE}, with the first two labeled active. A task begins in SEARCH with ˆ τk = 1 and advances ˆ τk on repeated failures; the first non-zero observation at ˆ τk transitions the task to MONITOR, freezing ˆ τk and confining further updates to the mean-reward estimate ˆµk. This avoids spurious pruning once feasibility is confirmed. If ˆ τk exceeds M during SEARCH, the task is marked INFEASIBLE and excluded from planning. Each round, the coordinator solves an exact 0/1 knapsack over active tasks using UCB1-based indices [Auer et al., 2002] (Algorithm 1, line 3). We use linear search for threshold updates, appropriate for the team sizes we consider; larger teams could employ doubling or binary search for a logM reduction at the cost of harder analysis.
Before stating the theoretical guarantees, we formally define the suboptimality gaps for our combinatorial setting, adapting standard definitions from the combinatorial semibandit literature [Chen et al., 2013; Combes et al., 2015]. Let µ(c) = ∑Kj=1 1{cj ≥ τj}µj denote the expected reward of any feasible allocation c ∈ C, and let ∆c = µ⋆ - µ(c) be its corresponding suboptimality gap. For each task k, the taskspecific gap ∆k is defined as the minimum positive suboptimality gap among all allocations that feasibly activate task k:
Furthermore, let ∆max = maxc∈C ∆c denote the maximum possible suboptimality gap across all valid allocations.
Theorem 1 (Centralized TAC-MAB Regret). Consider the TAC-MAB problem with K tasks and M agents over a time horizon T , under centralized coordination. Setting the failure budget to Nmax = ⌈ 2 log T log(1/(1-pmin)) ⌉, the expected cumulative team regret R(T ) of C-TAC satisfies:
statistical monitoring
Algorithm 1 C-TAC (Centralized Threshold-Activated Coordination)
Require: Tasks K, Agents M, Horizon T , Values v, Identi-
fiability bound pmin, Failure budget Nmax, UCB constant c 1: Initialize: For each task k, set ˆ τk ← 1, ϕk ← SEARCH, Nfail,k ← 0, ˆµk ← 0, Nk ← 0 2: for t = 1, . . . , T do 3: Planning: c∗t ← exact 0/1 knapsack over active tasks {k : ϕk ̸= INFEASIBLE} with weights ˆ τk and per-task indices ˆµk +vk√c log t/Nk (Nk = 0 treated as +∞) 4: Execution: Execute c∗t , observe outcomes {Yk,t} 5: for each task k with coalition size c∗k,t ≥ ˆ τk do 6: if ϕk = SEARCH then 7: if Yk,t > 0 then 8: ϕk ← MONITOR; Nfail,k ← 0 {feasibility confirmed} 9: Nk ← Nk + 1; update ˆµk via empirical mean 10: else 11: Nfail,k ← Nfail,k + 1 {censored failure} 12: if Nfail,k ≥ Nmax then 13: ˆ τk ← ˆ τk + 1; Nfail,k ← 0 {linear prune} 14: if ˆ τk > M then 15: ϕk ← INFEASIBLE 16: end if 17: end if 18: end if 19: else if ϕk = MONITOR then 20: Nk ← Nk + 1; update ˆµk via empirical mean 21: end if 22: end for 23: end forProof sketch. We decompose the expected cumulative regret into three components: structural search under censored feedback, statistical monitoring of feasible allocations, and a constant bounding the tail failures.
(i) Structural search. For any feasible coalition allocation ck,t ≥ τk, the probability of Nmax consecutive Bernoulli(pk) failures is at most (1 - pk)Nmax , which by the identifiability condition (pk ≥ pmin) is at most (1 - pmin)Nmax ≤ 1/T 2 . By a union bound over T rounds and K tasks, with probability at least 1 -K/T no feasible task is incorrectly marked INFEASIBLE. The SEARCH-only pruning rule advances ˆ τk incrementally, taking at most min(τk,M) phases. Each phase costs Nmax = O(log T/pmin) rounds, during which the team forgoes a worst-case expected reward of up to µ⋆ (the optimal joint allocation) per round. The MONITOR transition freezes ˆ τk on the first feasible success, and tasks never reenter SEARCH, so no further structural regret accrues. Summing over tasks yields the first term.
(ii) Statistical monitoring and tail failures. Conditioned on feasible execution, the per-pull reward sequence {Xk,tvk} is i.i.d. with support {0, vk}. Crucially, the empirical mean ˆµk ← (1/Nk) ∑s≤t:feasible exec on k Yk,s and pull counter Nk are only updated during these feasible executions, ensuring the estimates remain unbiased by censored feedback. At any round t, the Hoeffding bound yields a confidence radius of vk√c log t/Nk for a constant c > 0, cleanly recovered by our planning index. Applying the gap-dependent regret bound for combinatorial semi-bandits with multi-play feedback [Combes et al., 2015] bounds the statistical regret by O(v2 k logT/∆k) per feasible task. The tail failure term O(K∆max) arises from the exponentially decaying failure tails of the confidence intervals [Auer et al., 2002; Chen et al., 2013].
Implementation details. While Theorem 1 dictates a conservative failure budget that scales with logT, in our experiments we use a fixed budget of Nmax = 5, which provides sufficient feasibility-resolution power for the environments we consider. For the exploration radius, we use c = 2, the standard UCB1 constant. The mean-reward estimate ˆµk is updated only on feasible executions; failures below ˆ τk contribute only to the SEARCH-phase pruning counter. The perround computational cost is O(KM) to exactly solve the integer knapsack via dynamic programming, plus O(K) for the UCB index updates.
4 Decentralized Coordination
Unlike the centralized baseline, decentralized agents lack access to a global view of outcomes. They observe only their own rewards and must rely on communication to synchronize their beliefs. The primary challenge is not just statistical estimation, but alignment on feasibility: if agents disagree on the current hypothesis ˆ τk, they may compute conflicting optimal plans, leading to mis-coordinated coalitions that fail to trigger tasks.
To address this, we introduce D-TAC (Decentralized Threshold-Activated Coordination). D-TAC instantiates a Virtual Coordinator at each agent: a local copy of the C-TAC planner (Section 3) that operates on the agent's belief state. Because every agent runs the same deterministic planner under shared rules, identical belief states produce identical joint plans without explicit negotiation. Following the "Public Agent" paradigm [Chakraborty et al., 2017], agents share four pieces of structure prior to deployment: the C-TAC planner, a rank-based assignment rule, belief-state fusion rules, and common synchronization triggers. Under these shared rules, communication is required only to maintain belief-state consistency, not to coordinate actions. The contribution of D-TAC lies in the event-triggered protocol that schedules belief synchronization based on structural changes; the actioncoordination mechanism is inherited from prior work. Because feasibility threshold estimates are non-decreasing under conservative max-fusion and bounded by M, structural disagreement is self-limiting and the team stabilizes on a shared hypothesis within a finite number of events (Proposition 2).
4.1 The Virtual Coordinator Architecture
Each agent i maintains a local belief state Bt i comprising, for each task k: a threshold lower bound ˆ τ lo k , a threshold upper bound ˆ τ hi k , a phase indicator ϕk ∈ {SEARCH, MONITOR, INFEASIBLE}, and reward statistics
(ˆµk,Nk). The agent also stores the most recent joint plan c∗ . The lower bound ˆ τ lo k is initialized to 1 and advances on Type II events; the upper bound ˆ τ hi k is initialized to M (the maximum coalition size) and tightens to min(ˆ τ hi k , ck,t) on observing Yk,t > 0. The planner uses ˆ τ hi k as the coalition-size weight, since it represents the smallest empirically-confirmed feasible size. Each agent also stores ˆ τ lo,synced k and ϕsynced k , the values of ˆ τ lo k and ϕk at the most recent sync, used to detect Type I breakthroughs against the last globally-known hypothesis.
Deterministic Consensus. We use consensus in the engineering sense of a shared assignment rule, not in the distributed-systems sense of a negotiated protocol: there is no message exchange in this step. Agents are indexed by unique IDs i ∈ {1, . . . ,M}. If the joint plan c∗ allocates c∗k agents to task k, agents are assigned in ID order: the first c∗1 to task 1, the next c∗2 to task 2, and so on. Agents with index beyond ∑k c∗k idle that round. Since this rule is deterministic and depends only on c∗ , any two agents holding identical plans produce identical assignments. Transient disagreement may occur between syncs; agents persist with the last agreed-upon plan ("sticky execution") to avoid mis-coordination.
4.2 Structure-Aware Communication Protocol
D-TAC uses an event-triggered protocol with a low-frequency heartbeat backstop, optimizing for the number of synchronization rounds rather than payload size (consistent with Section 2.3). Agents operate silently by default. A sync is triggered when one of three events occurs:
- Type I (Feasibility Breakthrough): agent i observes Yk,t > 0 at ck,t < ˆ τ lo,synced k or at a task with ϕsynced k = INFEASIBLE.
- Type II (Structural Pruning): agent i accumulates Nmax consecutive informative failures (coalition ≥ ˆ τ lo k in phase SEARCH), advancing ˆ τ lo k and changing the planner's coalition-size weight.
- Periodic Heartbeat: every Th rounds, to bound divergence in reward estimates. Performance is robust to Th over a wide range.
D-TAC begins with a warmup phase (t = 1, . . . ,K) in which all M agents probe each task once; a single sync at t = K+1 pools the warmup observations.
When a sync fires, agents broadcast belief states and fuse peer states under three rules. Threshold bounds are fused conservatively: ˆ τ lo k ← maxj ˆ τ lo k,j (monotone nondecreasing) and ˆ τ hi k ← minj ˆ τ hi k,j (tightening on any peer's success). Phases combine under the precedence MONITOR ≻ INFEASIBLE ≻ SEARCH, so a single peer with empirically confirmed feasibility overrides others' SEARCH or pessimistic INFEASIBLE claims. Reward estimates are fused as the count-weighted mean ˆµk ← (∑j Nk,j ˆµk,j)/(∑j Nk,j) over local observations accumulated since the last sync, yielding the same posterior as pooling raw samples. Fusion is idempotent: a repeated sync with no new observations leaves belief components unchanged.
Algorithm 2 D-TAC (Agent i View)
Require: Tasks K, Agents M, Heartbeat Th, Failure budget
- Nmax 1: Init: Bi ←priors; c∗ ← Planner(Bi) 2: Warmup: for t = 1, . . . ,K, all M agents probe task t; sync at t = K+1 3: for t =K+1, . . . , T do 4: Sync ← (t mod Th = 0) ▷ heartbeat 5: if Type I or Type II event since last sync then Sync ← True 6: if Sync then 7: Broadcast Bi; receive {Bj} 8: Fuse: ˆ τ lo k ←maxj, ˆ τ hi k ←minj, ϕk by precedence, ˆµk count-weighted 9: ˆ τ lo,synced k ← ˆ τ lo k ; ϕsynced k ←ϕk; c∗ ← Planner(Bi) 10: end if 11: Execute k ← c∗ [i]; observe Yk,t 12: if Yk,t > 0 then ▷ success 13: ˆ τ hi k ←min(ˆ τ hi k , ck,t) 14: if ck,t < ˆ τ lo k then ˆ τ lo k ← 1 ▷ refutation 15: Update ˆµk,Nk 16: if ϕk ∈ {SEARCH, INFEASIBLE} then ϕk ← MONITOR 17: Flag Type I if ck,t < ˆ τ lo,synced k or ϕsynced k = INFEASIBLE 18: else if ϕk = SEARCH and ck,t ≥ ˆ τ lo k then ▷ informative failure 19: Nfail,k ←Nfail,k +1 20: if Nfail,k ≥ Nmax then advance ˆ τ lo k ; flag Type II 21: end if 22: end for
Convergence and Communication Bound. D-TAC is not designed to provide worst-case regret guarantees under decentralization in this work; a formal characterization requires bounding the transient phase of mismatched plans, the expected time to belief alignment, and the impact of stale estimates, which we defer to ongoing work. Instead, we establish a finite bound on the structural communication overhead.
Proposition 2 (D-TAC Communication Complexity). Under the D-TAC protocol, the total number of structural synchronization events (Type I and Type II triggers) over any horizon T is at most O(KM) network-wide before structural consensus is established at sync events.
Proof sketch. We bound the number of sync events triggered by structural changes team-wide. Type II events advance ˆ τ lo k , whose team-synced value is monotone non-decreasing through {1, . . . ,M+1} under max-fusion; at most M such advances per task. Type I events fire when successes refute the team's synced hypothesis; each such event tightens the team-synced upper bound, which is monotone non-increasing through the same range under min-fusion; at most M such tightenings per task. Summing over K tasks gives O(KM) structural sync events team-wide; beyond this, only the heartbeat fires.
Once structural beliefs align (within O(KM) events) and all feasible tasks transition to MONITOR, D-TAC's planner produces the same plan that C-TAC would given the shared belief state. From this point, regret accrues only from statistical estimation and the bounded lag between heartbeat syncs, so D-TAC empirically approaches C-TAC's asymptotic performance, modulo a transient during the structural-learning phase. The total communication budget under D-TAC is therefore O(KM + T/Th), with heartbeats dominating once structural consensus is reached.
5 Experimental Evaluation
We evaluate TAC-MAB to quantify the cost of learning under censored feedback and to assess whether explicit coordination is necessary to escape feasibility-gated failure modes. Our experiments isolate structural difficulty (identifying unknown coalition-size requirements) from standard statistical estimation error, and compare centralized and decentralized coordination under a shared observation model.
Experimental setup and baselines. All results are averaged over N = 40 independent runs with different random seeds; shaded regions and error bars indicate ±1 standard error. Unless otherwise stated, methods are evaluated with horizon T = 10,000, M = 5 agents, and K = 10 task types. The environment includes two infeasibility decoys (τ >M), one full-team task (τ = M), several mid-coordination tasks, and low-threshold distractors. D-TAC uses heartbeat period Th = 50 and failure budget Nmax = 5. C-TAC uses an exact knapsack planner (Section 3), isolating learning and coordination effects from computational approximation.
We compare the following strategies:
- Oracle Allocation: a full-information benchmark that knows all feasibility thresholds and success probabilities and selects the optimal allocation in every round.
- Independent UCB: a decentralized baseline in which agents independently estimate task values using UCB without communication or coordination.
- C-TAC: the centralized feasibility-aware strategy described in Section 3 (Algorithm 1), which explicitly probes coalition sizes to resolve feasibility.
- D-TAC: the decentralized coordination protocol introduced in Section 4 (Algorithm 2), which synchronizes agents only upon structural belief updates.
All methods receive the same local observations as defined in Section 2.3; only coordination and communication differ. We omit direct comparison against decentralized cooperativeMAB baselines such as Landgren-CoopUCB [Landgren et al., 2021] and DDUCB [Mart´ınez-Rubio et al., 2018]: faithful reproduction requires implementation choices (e.g., UCB exploration constants, fusion conventions) that could not be calibrated against authors' reference implementations. We defer this comparison to follow-up work.
Censored feedback breaks independent exploration. We first consider an environment containing one high-value cooperative task that requires full-team coordination and several low-threshold distractor tasks that provide immediate but smaller rewards. This setting isolates the censored-feedback failure mode: without explicit coordination, independent agents are unlikely to activate the cooperative task and instead converge to suboptimal alternatives.
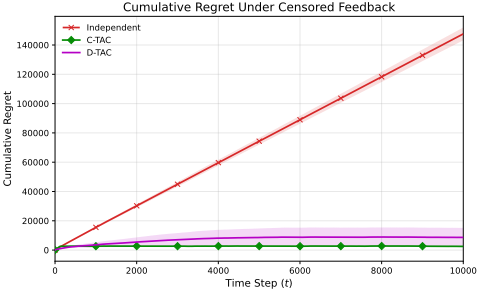
Figure 1 reports cumulative regret over time. Independent UCB exhibits sustained linear regret, reflecting its inability to reliably form sufficiently large coalitions under censored feedback. Failures below the feasibility threshold provide no informative signal, so independent exploration does not guide agents toward larger coalitions. C-TAC (centralized) and DTAC (decentralized) incur an initial coordination cost during early structure learning; once feasibility is resolved, regret growth slows substantially. The cost of learning feasibility is incurred early and does not scale with the horizon.
Communication efficiency. At T=10,000, D-TAC achieves cumulative regret of 13,700 using 4,303 messages, versus C-TAC's 4,500 regret at 100,000 messages-a 23× reduction in communication while remaining within the same order of magnitude in regret. D-TAC's message budget is amortized over structural events: the periodic heartbeat accounts for most messages once feasibility is resolved, while Type I and Type II structural triggers fire only during the learning phase.
Structural hardness induced by feasibility thresholds. We next examine how learning difficulty scales with the magnitude of coordination requirements. We vary the maximum feasibility threshold τmax across environments while keeping the number of agents, tasks, rewards, and success probabilities fixed. As τmax increases, informative feedback becomes increasingly unlikely under uncoordinated exploration.
Figure 2 reports the final cumulative regret R(T) as a function of τmax. Independent UCB suffers rapidly increasing regret as coordination requirements grow, reflecting the vanishing probability of independently activating thresholdgated tasks. C-TAC maintains consistently low regret across all threshold levels by explicitly probing feasibility. DTAC degrades gracefully and approaches centralized perfor- Maximum Threshold max mance, demonstrating that event-triggered coordination preserves feasibility learning while substantially reducing communication.
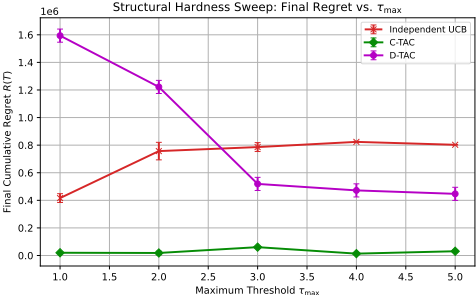
Figure 2: Structural hardness versus regret. Final cumulative regret R(T) as a function of the maximum feasibility threshold τmax. Independent UCB exhibits increasing regret as coordination requirements grow. C-TAC maintains low regret across all threshold levels. D-TAC approaches centralized performance while substantially reducing communication. Results are averaged over N = 40 runs with horizon T = 10,000; error bars denote ±1 standard error.
Limitations. Our experiments focus on stationary feasibility thresholds and synchronous rounds. In settings with nonstationary coordination requirements, delayed communication, or adversarial failures, additional mechanisms may be required to maintain feasibility alignment. While D-TAC substantially reduces communication in practice, we do not provide worst-case decentralization regret guarantees; characterizing the minimal communication required for feasibility learning under adversarial or dynamic conditions remains an open direction.
6 RelatedWork
Our work intersects with several primary domains in sequential decision-making, each with distinct limitations when applied to decentralized, threshold-gated coordination.
Multi-Agent Multi-Armed Bandits (MAMAB). Recent advances in MAMAB explore communication-constrained coordination [Landgren et al., 2021; Mart´ınez-Rubio et al., 2018; Chang et al., 2022; Chakraborty et al., 2017; Agarwal et al., 2022], including event-triggered and on-demand protocols [Chen et al., 2023], gossip-based information sharing [Chawla et al., 2020], heterogeneous and collision-aware decentralized learning [Kalathil et al., 2014; Magesh and Veeravalli, 2021], and fully-decentralized cooperation without communication [Chang and Lu, 2023]. These formulations assume rewards are triggered by individual agent actions or independent arm pulls. They fail in environments where task feasibility is gated by coalition size, as independent exploration yields fully censored feedback, preventing agents from learning task values. Related work in ad hoc teamwork [Barrett et al., 2014] addresses coordination among agents with unknown communication protocols but focuses on uncertainty over teammate behavior rather than environmental coordination requirements.
Combinatorial and Knapsack Bandits. Centralized combinatorial multi-armed bandits (CMAB) and knapsack-based bandits study how to allocate limited resources to maximize reward over time [Chen et al., 2013; Combes et al., 2015; Tran-Thanh et al., 2012; Das et al., 2022]. These models typically assume that resource costs or activation conditions are known in advance. In our setting, the feasibility threshold is a latent parameter that must be learned online, imposing an additional structural learning cost that standard CMAB frameworks do not address.
Censored Feedback and Resource Allocation. Bandit models with threshold-based or censored feedback have recently gained traction. Abernethy et al. [2016] study settings where rewards are observed only if expected values exceed a known threshold; Zhang et al. [2024] extend this to actively learning thresholds with latent values under single-agent censored feedback. Most closely related, Verma et al. [2019] introduce censored semi-bandits. This literature is restricted to centralized settings allocating a continuous, divisible resource budget; it does not address the discrete, integer-based coordination of distinct agents, nor does it provide mechanisms for decentralized agents to align on unknown thresholds under communication constraints.
Our Contributions. TAC-MAB and D-TAC address these gaps. We model task requirements as integer coalition thresholds and prove that the proposed centralized algorithm (CTAC) achieves O(log T) cumulative regret, decomposed into a structural-search term capturing the cost of resolving feasibility under censored feedback and a statistical-monitoring term for value estimation (Theorem 1). We then introduce a decentralized event-triggered protocol (D-TAC) that maintains feasibility alignment under conservative max-fusion and empirically achieves a 23× reduction in communication relative to the centralized baseline (Section 5).
7 Conclusion
We introduced the Threshold-Activated Cooperative MultiArmed Bandit (TAC-MAB), a framework for cooperative tasks whose rewards are gated by unknown coalition-size requirements and are fully censored below feasibility. Independent exploration fails structurally in this setting: agents receive no informative feedback below threshold and cannot distinguish infeasibility from stochastic failure.
Decomposing regret into feasibility learning and value estimation, we proved that the centralized algorithm achieves O(log T ) cumulative regret under the identifiability condition pk ≥ pmin > 0 for feasible tasks (Theorem 1), with feasibility resolving in O(logT/pmin) probes per task. Empirically, C-TAC resolves feasibility via targeted coalition-size probing, while D-TAC approximates this behavior through eventtriggered synchronization-achieving a 23× reduction in communication relative to the centralized baseline while preserving feasibility alignment under conservative max-fusion.
Extending D-TAC to lossy or adversarial communication remains open; we are pursuing a formal regret characterization under intermittent communication in ongoing work.
Acknowledgements
The conclusions and opinions expressed in this research paper are those of the authors and do not necessarily reflect the official policy or position of the U.S. Government or Department of Defense.
@inproceedings{ijcai2026p495,
  title     = {Cost of Structural Learning Under Censored Feedback: A Threshold-Bandit Approach},
  author    = {Ledford, Michael and Regli, William},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {4448--4455},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/495},
  url       = {https://doi.org/10.24963/ijcai.2026/495},
}
TY - CPAPER TI - Cost of Structural Learning Under Censored Feedback: A Threshold-Bandit Approach AU - Ledford, Michael AU - Regli, William T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 4448 EP - 4455 DO - 10.24963/ijcai.2026/495 UR - https://doi.org/10.24963/ijcai.2026/495 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





