
Towards Fair Graph Learning Without Demographic Supervision
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 789-797.
https://doi.org/10.24963/ijcai.2026/89
Keywords
- AI Ethics, Trust, Fairnes: Fairness and diversity
- AI Ethics, Trust, Fairnes: AI and law, governance, regulation
- AI Ethics, Trust, Fairnes: Ethical, legal and societal issues
Abstract
Graph Neural Networks (GNNs) have demonstrated strong predictive performance across a wide range of applications. However, their increasing deployment has raised critical fairness concerns, as these models can inherit and amplify existing biases. Most existing fairness approaches rely on explicit demographic information, either directly available or inferred, to measure and mitigate bias. In real-world settings, however, such information is often unavailable or legally prohibited to infer due to privacy concerns, legal restrictions, or regulatory constraints, which substantially limits the applicability of these methods. To address this challenge, we propose Demographic-Independent Fair Graph Learning (DIFGL), a novel framework for fair graph learning without demographic supervision. DIFGL mitigates group unfairness by minimizing disparities in individual treatment across implicitly identified subgroups, thereby enforcing fairness without requiring explicit demographic information. Extensive experiments on benchmark datasets demonstrate that DIFGL achieves significant improvements in fairness while maintaining competitive predictive performance.
- [Andrus et al., 2021] McKane Andrus, Elena Spitzer, Jeffrey Brown, and Alice Xiang. What we can't measure, we can't understand: Challenges to demographic data procurement in the pursuit of fairness. In Proceedings of the 2021 ACM conference on fairness, accountability, and transparency, pages 249-260, 2021.
- [Arvey, 1979] Richard D Arvey. Unfair discrimination in the employment interview: Legal and psychological aspects. Psychological bulletin, 86(4):736, 1979.
- [Ashurst and Weller, 2023] Carolyn Ashurst and Adrian Weller. Fairness without demographic data: A survey of approaches. In Proceedings of the 3rd ACM Conference on Equity and Access in Algorithms, Mechanisms, and Opti- mization, pages 1-12, 2023.
- [Asuncion and Newman, 2007] Arthur Asuncion and David Newman. Uci machine learning repository, 2007.
- [Chen et al., 2024] April Chen, Ryan A Rossi, Namyong Park, Puja Trivedi, Yu Wang, Tong Yu, Sungchul Kim, Franck Dernoncourt, and Nesreen K Ahmed. Fairness- aware graph neural networks: A survey. ACM Trans- actions on Knowledge Discovery from Data, 18(6):1-23, 2024.
- [Dai and Wang, 2021] Enyan Dai and Suhang Wang. Say no to the discrimination: Learning fair graph neural networks with limited sensitive attribute information. In Proceed- ings of the 14th ACM International Conference on Web Search and Data Mining, pages 680-688, 2021.
- [Dwork et al., 2012] Cynthia Dwork, Moritz Hardt, Toniann Pitassi, Omer Reingold, and Richard Zemel. Fairness through awareness. In Proceedings of the 3rd innovations in theoretical computer science conference, pages 214- 226, 2012.
- [Hardt et al., 2016] Moritz Hardt, Eric Price, and Nati Sre- bro. Equality of opportunity in supervised learning. Ad- vances in neural information processing systems, 2016.
- [Jiang et al., 2024] Zhimeng Jiang, Xiaotian Han, Chao Fan, Zirui Liu, Na Zou, Ali Mostafavi, and Xia Hu. Chasing fairness in graphs: A gnn architecture perspective. In Pro- ceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 21214-21222, 2024.
- [Kenfack et al., 2024] Patrik Joslin Kenfack, Samira Ebrahimi Kahou, and Ulrich Aïvodji. A sur- vey on fairness without demographics. Transactions on Machine Learning Research, 2024.
- [Kipf and Welling, 2016] Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. arXiv preprint arXiv:1609.02907, 2016.
- [Ni et al., 2024] Hongliang Ni, Lei Han, Tong Chen, Shazia Sadiq, and Gianluca Demartini. Fairness without sensitive attributes via knowledge sharing. In The 2024 ACM Con- ference on Fairness, Accountability, and Transparency, pages 1897-1906, 2024.
- [Rawls, 1971] A Rawls. Theories of social justice, 1971.
- [Voigt and Von dem Bussche, 2017] Paul Voigt and Axel Von dem Bussche. The eu general data protection regu- lation (gdpr). A Practical Guide, 1st Ed., Cham: Springer International Publishing, 10(3152676):10-5555, 2017.
- [Wang and Zhang, 2024] Zichong Wang and Wenbin Zhang. Group fairness with individual and censorship constraints. In Proceedings of the 27th European Conference on Arti- ficial Intelligence, pages 906-913. IOS Press, 2024.
- [Wang and Zhang, 2025] Zichong Wang and Wenbin Zhang. Fdgen: A fairness-aware graph generation model. In Forty-second International Conference on Machine Learning, 2025.
- [Wang et al., 2023a] Zichong Wang, Giri Narasimhan, Xin Yao, and Wenbin Zhang. Mitigating multisource biases in graph neural networks via real counterfactual samples. In ICDM 2023, 2023.
- [Wang et al., 2023b] Zichong Wang, Nripsuta Saxena, Tongjia Yu, Sneha Karki, Tyler Zetty, Israat Haque, Shan Zhou, Dukka Kc, Ian Stockwell, Xuyu Wang, et al. Preventing discriminatory decision-making in evolving data streams. In Proceedings of the 2023 ACM Conference on Fairness, Accountability, and Transparency, pages 149-159, 2023.
- [Wang et al., 2023c] Zichong Wang, Charles Wallace, Al- bert Bifet, Xin Yao, and Wenbin Zhang. : Fairness-aware graph generative adversarial networks. In Joint European Conference on Machine Learning and Knowledge Discov- ery in Databases, pages 259-275. Springer, 2023.
- [Wang et al., 2024a] Zichong Wang, Zhibo Chu, Ronald Blanco, Zhong Chen, Shu-Ching Chen, and Wenbin Zhang. Advancing graph counterfactual fairness through fair representation learning. In Joint European Confer- ence on Machine Learning and Knowledge Discovery in Databases, pages 40-58. Springer, 2024.
- [Wang et al., 2024b] Zichong Wang, David Ulloa, Tongjia Yu, Raju Rangaswami, Roland Yap, and Wenbin Zhang. Individual fairness with group constraints in graph neural networks. In Proceedings of the 27th European Confer- ence on Artificial Intelligence. IOS Press, 2024.
- [Wang et al., 2025a] Xuemin Wang, Tianlong Gu, Xuguang Bao, and Liang Chang. Towards fair graph neural networks via graph counterfactual without sensitive at- tributes. In 2025 IEEE 41st International Conference on Data Engineering (ICDE), pages 265-277. IEEE, 2025.
- [Wang et al., 2025b] Zichong Wang, Zhibo Chu, Thang Viet Doan, Shiwen Ni, Min Yang, and Wenbin Zhang. History, development, and principles of large language models: an introductory survey. AI and Ethics, 5(3):1955-1971, 2025.
- [Wang et al., 2025c] Zichong Wang, Zhibo Chu, Thang Viet Doan, Shaowei Wang, Yongkai Wu, Vasile Palade, and Wenbin Zhang. Fair graph u-net: A fair graph learning framework integrating group and individual awareness. In proceedings of the AAAI conference on artificial intelli- gence, volume 39, pages 28485-28493, 2025.
- [Wang et al., 2025d] Zichong Wang, Nhat Hoang, Xingyu Zhang, Kevin Bello, Xiangliang Zhang, Sun- dararaja Sitharama Iyengar, and Wenbin Zhang. Towards fair graph learning without demographic information. In The 28th International Conference on Artificial Intel- ligence and Statistics, volume 258, pages 2107-2115, 2025.
- [Wang et al., 2025e] Zichong Wang, Fang Liu, Shimei Pan, Jun Liu, Fahad Saeed, Meikang Qiu, and Wenbin Zhang. fairgnn-wod: Fair graph learning without complete demo- graphics. pages 556-564, 8 2025. Main Track. IJCAI
- [Wang et al., 2025f] Zichong Wang, Anqi Wu, Nuno Moniz, Shu Hu, Bart Knijnenburg, Qingquan Zhu, and Wenbin Zhang. Towards fairness with limited demographics via disentangled learning. In Proceedings of the 34th Interna- tional Joint Conference on Artificial Intelligence (IJCAI), 2025. IJCAI
- [Wang et al., 2025g] Zichong Wang, Zhipeng Yin, Zhen Liu, Roland HC Yap, Xiaocai Zhang, Shu Hu, and Wenbin Zhang. Redefining fairness: A multi-dimensional perspec- tive and integrated evaluation framework. In Joint Eu- ropean Conference on Machine Learning and Knowledge Discovery in Databases, pages 336-353. Springer, 2025.
- [Wang et al., 2025h] Zichong Wang, Zhipeng Yin, Liping Yang, Jun Zhuang, Rui Yu, Qingzhao Kong, and Wenbin Zhang. Fairness-aware graph representation learning with limited demographic information. In Joint European Con- ference on Machine Learning and Knowledge Discovery in Databases, pages 354-371. Springer, 2025.
- [Wang et al., 2025i] Zichong Wang, Zhipeng Yin, Roland HC Yap, and Wenbin Zhang. Ai fairness be- yond complete demographics: Current achievements and future directions. ECAI 2025, 2025.
- [Wang et al., 2026a] Zichong Wang, Tongliang Liu, and Wenbin Zhang. Guic: Certified graph unlearning with in- dividual fairness guarantees. In proceedings of the AAAI conference on artificial intelligence, volume 40, pages 35820-35828, 2026.
- [Wang et al., 2026b] Zichong Wang, Jie Yang, Jun Zhuang, Puqing Jiang, Mingzhe Chen, Ye Hu, and Wenbin Zhang. Fair graph learning with limited sensitive attribute infor- mation. In proceedings of the AAAI conference on artifi- cial intelligence, volume 40, pages 39423-39431, 2026.
- [Wang et al., 2026c] Zichong Wang, Zhipeng Yin, Zhong Chen, Jack Yang, Jun Liu, and Wenbin Zhang. Learn- ing counterfactual fairness from authentic generation. In Proceedings of the 35th International Joint Conference on Artificial Intelligence, 2026. IJCAI
- [Wang et al., 2026d] Zichong Wang, Zhipeng Yin, and Wen- bin Zhang. A unified framework for fair graph generation: Theoretical guarantees and empirical advances. Advances in Neural Information Processing Systems, 38:64883- 64909, 2026.
- [Xu et al., 2018] Keyulu Xu, Weihua Hu, Jure Leskovec, and Stefanie Jegelka. How powerful are graph neural net- works? arXiv preprint arXiv:1810.00826, 2018.
- [Yan et al., 2020] Shen Yan, Hsien-te Kao, and Emilio Fer- rara. Fair class balancing: Enhancing model fairness without observing sensitive attributes. In Proceedings of the 29th ACM International Conference on Information & Knowledge Management, pages 1715-1724, 2020.
- [Yeh and Lien, 2009] I-Cheng Yeh and Che-hui Lien. The comparisons of data mining techniques for the predictive accuracy of probability of default of credit card clients. Expert systems with applications, 36(2):2473-2480, 2009.
- [Yin et al., 2025] Zhipeng Yin, Zichong Wang, Avash Pa- likhe, Zhen Liu, Jun Liu, and Wenbin Zhang. Amcr: A framework for assessing and mitigating copyright risks in generative models. 28th European Conference on Artifi- cial Intelligence, 2025.
- [Yin et al., 2026] Zhipeng Yin, Zichong Wang, Zhong Chen, Jack Yang, Xin Ning, and Wenbin Zhang. Disentangled graph-enhanced large language models for fair learning. In Proceedings of the 35th International Joint Conference on Artificial Intelligence, 2026. IJCAI
- [Zhang and Ntoutsi, 2019] Wenbin Zhang and Eirini Ntoutsi. Faht: An adaptive fairness-aware decision tree classifier. In Proceedings of the Twenty-Eighth Interna- tional Joint Conference on Artificial Intelligence, pages 1480-1486. International Joint Conferences on Artificial Intelligence Organization, 2019. IJCAI
- [Zhang and Weiss, 2021] Wenbin Zhang and Jeremy C Weiss. Fair decision-making under uncertainty. In 2021 IEEE international conference on data mining (ICDM), pages 886-895. IEEE, 2021.
- [Zhang and Weiss, 2022] Wenbin Zhang and Jeremy C Weiss. Longitudinal fairness with censorship. In proceed- ings of the AAAI conference on artificial intelligence, vol- ume 36, pages 12235-12243, 2022.
- [Zhang et al., 2021] Wenbin Zhang, Liming Zhang, Dieter Pfoser, and Liang Zhao. Disentangled dynamic graph deep generation. In Proceedings of the 2021 SIAM Interna- tional Conference on Data Mining (SDM), pages 738-746.
- [Zhang et al., 2023] Wenbin Zhang, Tina Hernandez- Boussard, and Jeremy Weiss. Censored fairness through awareness. In Proceedings of the AAAI conference on artificial intelligence, volume 37, pages 14611-14619, 2023.
- [Zhang et al., 2025] Wenbin Zhang, Shuigeng Zhou, Toby Walsh, and Jeremy C Weiss. Fairness amidst non-iid graph data: A literature review. AI Magazine, 46(1):e12212, 2025.
- [Zhang, 2024a] Wenbin Zhang. Ai fairness in practice: Paradigm, challenges, and prospects. Ai Magazine, 45(3):386-395, 2024.
- [Zhang, 2024b] Wenbin Zhang. Fairness with censorship: Bridging the gap between fairness research and real-world deployment. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 22685-22685, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
With the increasing popularity of graph learning models for high-stakes decision-making, fairness has become an important topic in graph learning in recent years [Wang et al., 2026a; Chen et al., 2024; Zhang et al., 2025]. Many efforts have been made to achieve fair graph learning, highlighting algorithmic decisions that neither discriminate against nor unfairly favor specific demographic groups [Wang et al., 2025h]. However, most of these methods assume the complete availability of demographic information (e.g., gender or race), which often does not hold in practice. In many realworld applications, explicit demographic information is unavailable due to privacy concerns, legal limitations, or ethical constraints that restrict the collection or use of demographic information [Ashurst andWeller, 2023]. For example, in employment decision-making scenarios, job applicants may hesitate or refuse to disclose demographic information because of fears of potential discrimination [Arvey, 1979]. Hence, existing fairness methods relying on explicit demographic information become infeasible.
∗Corresponding author: wenbin.zhang@fiu.edu
To this end, several methods have started exploring fairness-aware graph models without explicit demographic information. Among these, a popular and well-studied approach involves inferring proxies for the missing demographic information, then treating these inferred proxies as if they were known demographic information for enforcing fairness constraints [Wang et al., 2025i]. For example, fairGNNWOD [Wang et al., 2025e] addresses this issue through a two-stage framework, explicitly designed to first infer demographic proxies and then use these inferred attributes in downstream fairness-aware graph learning. However, such models overlook critical limitations of proxy inference. For example, inference of sensitive attributes might itself be restricted or prohibited under regulatory frameworks such as the EU General Data Protection Regulation (GDPR) [Voigt and Von dem Bussche, 2017], which explicitly limits or forbids processing of sensitive personal data like race, political opinions, religion, health status, biometrics, and sexual orientation. Moreover, inaccuracies or errors in the proxy estimation process may significantly compromise the reliability and effectiveness of fairness measurements, ultimately leading to unintended biases in downstream decisions.
To this end, it is essential to develop fairness-aware models that neither rely on explicit nor infer demographic information, thus avoiding regulatory conflicts and inaccuracies inherent to proxy-based approaches. Despite the importance of achieve fairness without direct demographic supervision, this remains a highly open research area with several unaddress and unique challenges: i) QuantifyingBias without Explicit Demographic Information. The critical challenge in scenarios where demographic inference is explicitly prohibited is to develop novel fairness measures and methodologies capable of comprehensively detecting and quantifying implicit biases across the entire spectrum of nodes with varying prediction costs, without relying on explicit demographic information or subgroup identification. ii) Mitigating Bias without Demographic Supervision. Existing fairness constraints depend on explicit demographic information to enforce fairness. When demographic inference is explicitly prohibited, bias mitigation becomes even more challenging, as fairness constraints must be enforced solely based on observed prediction outcomes without referencing demographics at all. The core challenge in this setting is designing novel and efficient optimization strategies capable of reliably reducing implicit biases identified from predictive disparities alone, without incurring substantial losses in predictive performance. iii) Meeting User-Specified Fairness Thresholds. Ensuring that user-defined fairness constraints are reliably satisfied becomes particularly challenging without demographic supervision, since the absence of explicit group information makes fairness measurement and constraint-aware optimization nontrivial. Hence, designing mechanisms that can both verify fairness compliance and enforce fairness guarantees remains difficult in practical deployments.
To address these challenges, this paper studies a novel problem of fair graph learning without explicit or inferred demographics. We propose a novel framework, termed Demographic-Independent Fair Graph Learning (DIFGL), specifically designed to enable fairness evaluation and mitigation by addressing treatment disparities without demographic supervision. To best of our knowledge, this is the first work that achieve fair graph learning without relying on demographic supervision. Specifically, we propose a novel fairness notion based on principled variance analysis, which identifies implicit biases by quantifying disparities in individual-level treatment. Building upon our proposed fairness notion, we develop a structured optimization framework grounded in the Rawlsian difference principle to systematically mitigate these disparities. Our proposed framework iteratively improves outcomes for implicitly identified least-advantaged nodes while ensuring no adverse impacts on other nodes. Additionally, we introduce a randomized optimization strategy explicitly designed to reduce node-level treatment variance, thus consistently maintaining compliance with predefined fairness threshold. Our contributions are outlined below:
- We propose a novel fairness notion that accurately identifies implicit biases without relying on explicit demographic information or inferred proxies.
- We design a novel optimization framework that builds on the fairness notion we proposed, explicitly targeting and reducing disparities among the least advantaged nodes through iterative variance-aware updates, thereby achieving graph fairness without demographic information or inferred proxies.
- We validate the effectiveness of our proposed methods through extensive experiments on three graph datasets, demonstrating significant improvements in fairness results without compromising model utility.
2 RelatedWork
2.1 Fairness in Graph Learning
Fairness has been widely studied in graph learning, and numerous fairness notions have been proposed in recent years [Wang et al., 2026d; Wang and Zhang, 2025; Wang et al., 2025c]. Among these, one of the most extensively studied concepts is group fairness, which emphasizes ensuring algorithmic decisions do not discriminate against or favor specific demographic subgroups based on demographic information like race or gender [Jiang et al., 2024]. In other words, group fairness seeks to make the predictions of GNNs independent of demographic information [Wang et al., 2023c; Wang et al., 2025g; Wang and Zhang, 2024]. For example, FAHT [Zhang and Ntoutsi, 2019], an extension of the Hoeffding Tree algorithm, introduces fairness into online stream-based decision-making by accounting for the evolution of the underlying data population, mitigating discrimination as new instances arrive. Similarly, RFCGNN [Wang et al., 2023a] addresses label bias in GNNs through counterfactual fairness, identifying authentic counterfactual samples within graph structures and applying causal analysis to mitigate bias in downstream predictions. However, these methods rely on the assumption that accurate demographic information is readily available to use, a condition that often does not hold in practical scenarios due to data collection constraints, privacy considerations, and regulatory requirements [Andrus et al., 2021]. Given these requirements, there is an emerging trend in the research community to explore fairness methods without demographic information.
2.2 Fairness without Demographics in Graph Learning
There has been growing interest in achieving fair graph learning in settings where explicit demographic information is unavailable [Ashurst and Weller, 2023; Wang et al., 2025h; Wang et al., 2026b]. A common line of work addresses this problem by inferring proxies for missing demographic information and then treating these inferred proxies as substitutes to satisfy fairness constraints [Kenfack et al., 2024]. For example, the approach proposed in [Wang et al., 2025f] leverages partially available demographic information to infer the missing demographics, while simultaneously evaluating and optimizing model fairness during training. However, such methods still rely on the availability of partial demographic labels to guide the inference process, which limits their applicability. More recent studies have taken initial steps toward fair graph learning without assuming fully observed demographics. For instance, fairGNN-WOD [Wang et al., 2025e] adopts a two-stage framework that first infers demographic information from node features and graph structure, and then applies these inferred proxies in downstream fairness-aware GNN training. Similarly, FairWOS [Wang et al., 2025a] introduces pseudo-demographic information combined with graph counterfactual reasoning to improve fairness without demographics. Despite removing the need for ground-truth demographic information, these approaches still assume that inferring demographic information is permissible and reliable. In practice, however, such assumptions may not hold due to privacy concerns, legal restrictions, or regulatory prohibitions on demographics inference [Wang et al., 2025i]. These limitations highlight a fundamental gap in existing work and underscore the need for fairness-aware graph learning methods that neither require explicit demographic information nor attempt to infer the proxy of missing demographics indirectly.
Unlike existing demographic-dependent and proxyinference-based approaches, the proposed method adopts an individual-level treatment perspective to identify and mitigate bias without relying on explicit or inferred demographic information. In addition, a structured optimization framework grounded in the Rawlsian difference principle is developed to systematically improve outcomes for implicitly identified disadvantaged individuals while explicitly enforcing a predefined fairness threshold, yielding a principled and practically applicable solution for fair learning without demographic supervision.
3 Notation
In this paper, we consider an attributed graph G, represented as (G = (V, E,X)), consisting of a set of nodes (V = {v1, v2, . . . , vn}) and a set of undirected edges (E ⊆ vi, vj | vi, vj ∈ V). Each node vi is characterized by a (d)- dimensional feature vector (xi ∈ Rd ), and collectively, these vectors form the node feature matrix (X ∈ Rn×d ). The connectivity between nodes is encoded by an adjacency matrix (A ∈ {0, 1}n×n ), with (Ai,j = 1) if an edge connects nodes vi and vj, and (Ai,j = 0) otherwise. Additionally, each node (vi) has an associated binary sensitive attribute (si ∈ {0, 1}), collectively represented by the vector (S ∈ {0, 1}n×1 ). This sensitive attribute partitions the node set into two groups: the deprived group (Sd = {vi | si = 0}) (e.g., female) and the favored group (Sf = {vi | si = 1}) (e.g., male). Each node vi also carries a binary outcome label (yi ∈ {0, 1}) representing a granted decision outcome such as approval (yi = 1) or rejected decision such as rejection (yi = 0). The outcomes predicted by a model for each node are denoted as ˆ yi .
4 Methodology
4.1 Quantifying Group Unfairness without Demographics
Existing fairness approaches typically depend on explicit demographic information, either directly available or inferred, to identify and measure bias, thus limiting their applicability when demographic information is unavailable [Ashurst and Weller, 2023]. To this end, we propose a novel fairness notion that evaluates unfairness through the training perspective by examining disparities in model performance as reflected by training losses, without relying on demographics supervision. Specifically, the training loss reflects how accurately a model learns each individual, and systematic differences in these losses indicate consistent advantages afforded to certain individuals over others during the learning process. These persistent disparities can signal underlying structural or societal biases, even when the affected subsets are not explicitly labeled. By shifting evaluation away from final outcomes (e.g., approval or rejection) toward analyzing consistency in training performance, this method enables fairness assessments independent of demographic groupings, offering detailed insights into model behavior. By shifting evaluation from final outcomes (such as approval or rejection) to consistency in training performance, this approach enables fairness assessment without relying on demographic groupings, while providing more fine-grained insights into model behavior. For instance, in a graph-based classifier predicting financial reliability without access to demographic information such as race, if a subset of nodes {v1, . . . , vk}, possibly representing Black individuals, routinely experiences higher losses, this persistent disparity signals latent unfairness. To quantify this implicit subgroup unfairness without demographic information, the most direct approach is to measure how significantly the average loss among individuals with the highest losses deviates from the other population average. By capturing these disparities, it becomes possible to approximate implicit maximum subgroup-level unfairness, thereby providing a clear and systematic way to evaluate fairness even in the absence of explicit demographic information.
However, while conceptually intuitive, directly using the average loss of individuals with the highest training losses introduces practical limitations. In particular, this measurement uses the experience of these particular individuals as a proxy for group-level disparity, which may overlook the experiences of other individuals across the population. To address this limitation, we propose quantifying fairness using the empirical variance of training losses instead. The core idea is that variance, by accounting for the loss of every individual in the population, reflects how consistently the model performs across implicitly defined regions of the data and offers a more stable measure of latent unfairness. Moreover, variance is smooth and differentiable, enabling gradient-based optimization. Motivated by these properties, we define the Latent Disparity Index (LDI), a variance-based fairness measure that quantifies the extent to which the individuals with the highest training losses diverge from the rest of the population mean, providing a principled and practical framework for evaluating fairness without explicit demographic information. Formally, LDI is defined as follows:
Definition 4.3 (Latent Disparity Index). Given a graph learning model parameterized by θ, the latent disparity index quantifies implicit bias by measuring the extent to which the subset of individuals with the highest training losses deviates from the average loss of the remaining population:
where Qk denotes the subset containing the k nodes with the highest training losses, and Qrest denotes the complementary subset with N denotes the total number of the nodes. In addition, ℓ(i; θ) represents the training loss of one individual node i, while ¯ ℓ(θ) denotes the mean training loss over all nodes, defined as:
where Qtrain denotes the empirical training set across all N nodes.
In summary, LDI provides a without demographic supervision mechanism to quantify latent disparity by contrasting the loss dispersion of the worst-off (top-k) nodes against the remaining population. Due to the top-k operator defining Qk and the absolute-value operation, LDI inherently becomes non-smooth when node membership in Qk changes or when the disparity gap reaches zero. To this end, in our framework, LDI primarily serves as a fairness criterion to be monitored or enforced at the objective or constraint level. To achieve stable optimization, we instead utilize node-level residual signals, defined as the standardized deviation of each node's loss from the global mean loss, for reweighting. These node-level residuals continuously vary with individual losses, enabling stable gradient-based updates. This method progressively reduces the underlying loss imbalance and, as a result, robustly decreases the LDI value throughout training iterations. This strategy effectively addresses the non-smoothness inherent in LDI, ensuring a practical and stable approach to fairness evaluation and enforcement.
4.2 Mitigating Unfairness without Explicit Demographics
Building on the proposed LDI, a novel framework is introduced to systematically mitigate bias without requiring explicit demographic information. The core idea is inspired by the Rawlsian difference principle [Rawls, 1971], which aims to improve the outcomes of the least advantaged group without reducing the welfare of others. In this framework, welfare is represented by individual training losses, with disparity measured through variations in these losses. Under the absence of explicit demographic information, the "least advantaged group" is naturally defined as the top-k highest-loss nodes identified by LDI.
Guided by this principle, we develop the DemographicIndependent Fair Graph Learning (DIFGL) framework, which implements Rawlsian fairness through two iterative steps. First, at each training iteration, nodes experiencing the greatest disadvantage are identified based on their individual training losses. This criterion directly leverages training loss as a proxy signal for implicit disadvantage in settings where explicit demographic information is unavailable. Second, after this subset of high-loss nodes is identified, the training process explicitly prioritizes these nodes, guiding model updates to reduce their losses toward the overall population average and thereby shrinking the LDI-based disparity. Since the composition of the least advantaged group may change dynamically during training, this identification-andcorrection procedure is repeated at each iteration. Specifically, at iteration t, the identification step is implemented by ranking training nodes according to their current loss values and selecting the top-k nodes with the highest losses. Formally, an ordering πθ over the training nodes is defined as follows:
where Vtrain ⊆ V denotes the set of training nodes with cardinality N = |Vtrain|, while ℓ(vi; θ) represents the training loss of node vi under parameters θ.
Using this sorted order, we dynamically define the least advantaged subset and advantaged subset as:
This subset, Vdis(θ), is re-identified after every model update, ensuring that the framework consistently targets the nodes currently most disadvantaged under the latest model parameters.
Armed with the identification of the least advantaged group, the next step is to translate this fairness criterion into a stable, node-level update rule. Specifically, while LDI effectively signals the existence of disparities, it remains a global scalar measure, offering no explicit indication of which individual nodes require correction or the extent to which each node should influence subsequent updates. To this end, we propose a two-stage mechanism that explicitly bridges the gap between global fairness signals and actionable node-level guidance. First, a diagnostic component (the separating oracle) translates the overall loss disparity into individual residual scores, clearly indicating how much loss is caused if each node deviates from the population mean. Second, a corrective component (the weighted optimization oracle) transforms these residual scores into training weights, systematically assigning greater emphasis to nodes with above-average losses, thus directly reducing their disadvantage. Guided by this mechanism, DIFGL maintains and iteratively updates a distribution over candidate models, systematically reducing loss variability across all nodes. By repeatedly applying this diagnostic and corrective process, DIFGL ensures that no subgroup consistently experiences disproportionately higher losses and progressively reduces the disparities captured by LDI, resulting in stable and sustained fairness improvements throughout training. Specifically, we first introduce the separate oracle and formally define how it computes the residual scores. Formally, the separating oracle outputs the residual vector, which captures node-level deviations from the global average loss as follows:
where ϵ > 0 ensures numerical stability. To clarify why the residual is an appropriate node-level signal for reducing dispersion, we view the empirical variance as a function of the loss vector. Let ℓi = ℓ(vi; θ) and µ = ¯ ℓ(θ) = 1N ∑Ni=1 ℓi, so that:
Differentiating σ2 ℓ (θ) with respect to the ith loss component yields:
which shows that the centered loss ℓ(vi; θ) - ¯ ℓ(θ) is exactly the direction that increases the variance most. The residual ri(θ) is a normalized version of this gradient component (up to a global scaling factor), since:
Therefore, if we view σ2 ℓ (θ) as a function of the loss vector (ℓ(v1; θ), . . . , ℓ(vN; θ)), then decreasing the losses of nodes with positive residuals (that is, nodes whose losses lie above the mean) reduces σ2 ℓ at the first-order level, making the loss profile more uniform across nodes. Up to this point, we have described the deterministic variant that maintains a single parameter vector θ. By doing so, DIFGL can be implemented in a deterministic form by updating a single parameter vector θ ← θ+. To avoid abruptly replacing the current model after each oracle call, we maintain a mixture state over candidate parameters. Concretely, we represent the current state by a distribution D and evaluate each node by its expected loss:
Given the residual vector produced by the separating oracle, the weighted optimization oracle performs the second step of the framework by translating these residuals into a concrete model update. Specifically, we update the state by a convex mixture Dnew = (1-γ)Dold+γ δθ+ , where the mixing rate γ controls how much probability mass is assigned to θ+ (smaller γ yields a more gradual update). This distributional form includes the single-model case as a special instance: if D = δθ, then ℓ(vi; D) = ℓ(vi; θ). After receiving the residual vector from the separating oracle, the weighted oracle reduces the loss disparity by solving a weighted training problem that assigns larger influence to nodes whose losses are above the population level. With step size η > 0 and an optional regularization R(θ), we compute:
where ri can be ri(θ) for a single model or ri(D) for randomized distributions. Notably, we use wi = clip(1 + ηri,wmin,wmax) to ensure nonnegative, bounded weights. Minimizing 1N ∑i wi, ℓ(vi; θ) + λregR(θ) aligns the update direction with -∇σ2 ℓ at the loss level, systematically reducing node loss variance.
Intuitively, because ri > 0 indicates that node vi lies above the global mean loss, upweighting such nodes increases the training pressure to reduce their losses, which in turn makes the loss distribution more uniform across nodes. In DIFGL, this idea is applied to the current model state in a gradual manner by maintaining a distribution Dt over candidate parameters, so that node-level quantities are evaluated in expectation rather than relying on a single point estimate. Accordingly, at iteration t the separating oracle first computes each node's expected training loss under Dt, and then derives the population mean and dispersion from these expected losses:
where ¯ ℓ(Dt) = 1N ∑Ni=1 ℓ(vi;Dt), and N = |Vtrain|. The separating oracle then recalculates node-level residuals from {ℓ(vi;Dt)}Ni=1 , providing a quantitative assessment of how each node deviates from the global mean. Subsequently, the weighted oracle uses these residual scores to perform a reweighted training step and returns a new candidate parameter vector θ+.
To update the model state in a controlled and gradual manner, DIFGL does not fully replace the current state with the new candidate. Instead, it mixes θ+ into the current distribution using a tunable mixing rate:
where γt ∈ (0, 1] controls how aggressively the state moves toward θ+ at iteration t. In practice, we choose γt by a short line search along the mixture path D(γ) = (1-γ)Dt +γδθ+ , selecting γt so that the variance of the expected losses does not increase:
After updating Dt+1, we recompute ℓ(vi;Dt+1) and the residual vector and repeat the loop.
Finally, we stop once the dispersion is small enough to imply the target LDI threshold. Let α = k/N for the top-k split used in LDI. The mean-loss gap between the top-k set and the remaining set admits the bound:
Therefore, a sufficient stopping condition for ensuring LDI(·) ≤ ε is:
Under Equation (14), the resulting model state satisfies the LDI-based fairness requirement in Definition 4.3.
4.3 Overall Optimization Objectives
In this subsection, we introduce our overall training objective that jointly considers predictive accuracy and fairness criteria. Specifically, our optimization framework involves two key components: i) predictive performance evaluated through the binary cross-entropy loss on labeled nodes, and ii) fairness constraints measured by disparities between the top-k highest-loss nodes and the rest of the training population. We define the predictive accuracy component using the standard binary cross-entropy loss across labeled training nodes VL:
In addition, we then formalize a fairness constraint based on the proposed LDI measure. Mathematically, this is represented as:
Finally, the overall training objective combines predictive loss and fairness loss as:
| Dataset | Metrics Methods | GCN | GIN | KSMOTE | Reckoner | Themis | fairGNN-WOD | DIFGL |
|---|---|---|---|---|---|---|---|---|
| Credit AUC F1-Score ∆DP ∆EO(↓) | (↑) 0.681 ± 0.056 (↑) 0.794 ± 0.023 (↓) 0.118 ± 0.013 0.098 ± 0.027 | 0.707 ± 0.048 0.807 ± 0.028 0.147 ± 0.030 0.089 ± 0.023 | 0.656 ± 0.059 0.755 ± 0.052 0.073 ± 0.043 0.065 ± 0.023 | 0.668 ± 0.021 0.763 ± 0.045 0.068 ± 0.027 0.055 ± 0.014 | 0.675 ± 0.032 0.760 ± 0.048 0.049 ± 0.021 0.042 ± 0.023 | 0.680 ± 0.052 0.785 ± 0.027 0.041 ± 0.021 0.038 ± 0.023 | 0.701 ± 0.790± 0.038 ± 0.033 ± | 0.052 0.038 0.020 0.013 |
| German AUC F1-Score ∆DP ∆EO(↓) | (↑) 0.746 ± 0.045 (↑) 0.807 ± 0.032 (↓) 0.365 ± 0.032 0.315 ± 0.041 | 0.728 ± 0.823 ± 0.159 ± 0.097 ± | 0.030 0.027 0.046 0.037 | 0.679±0.034 0.775 ± 0.048 0.086± 0.027 0.062 ± 0.020 | 0.662 ± 0.051 0.738 ± 0.046 0.077 ± 0.018 0.055 ± 0.018 | 0.713 ± 0.041 0.747 ± 0.032 0.071 ± 0.037 0.040 ± 0.013 | 0.728 ± 0.043 0.752 ± 0.042 0.063 ± 0.017 0.044 ± 0.013 | 0.733 ± 0.021 0.783 ± 0.032 0.057 ± 0.013 0.038 ± 0.015 |
| NBA AUC (↑) F1-Score (↑) ∆DP (↓) ∆EO(↓) | 0.691 ± 0.035 0.631 ± 0.022 0.081 ± 0.033 0.156 ± 0.049 | 0.683 ± 0.048 0.629 ± 0.042 0.075 ± 0.017 0.132 ± 0.057 | 0.680 ± 0.624 ± 0.032 ± ± | 0.053 0.681 0.019 0.621 0.025 0.027 0.039 0.020 0.033 | ± 0.028 0.679 ± 0.032 0.616 ± 0.018 0.031 ± 0.011 0.038 | ± 0.054 ± 0.029 ± 0.019 ± 0.025 | 0.678 ± 0.024 0.626 ± 0.029 0.023 ± 0.008 0.034 ± 0.017 | 0.681 ± 0.024 0.626 ± 0.029 0.021 ± 0.023 0.031 ± 0.016 |
where a controls the balance between predictive performance and the strength of fairness enforcement.
5 Experiment
5.1 Datasets
Our experiments are conducted on two widely used datasets:, namely Credit, German, and NBA. The Credit dataset [Yeh and Lien, 2009] consists of credit card holders represented as nodes, with edges capturing similarities in their purchasing and repayment behaviors. Age is considered the sensitive attribute, and the task aims to determine whether a cardholder is likely to default on future payments. The German dataset [Asuncion and Newman, 2007] models clients of a German financial institution as nodes, where edges are constructed between individuals exhibiting similar credit account characteristics. In this dataset, gender is treated as the sensitive attribute, and the learning objective is to predict whether a client presents a high or low credit risk. The NBA dataset [Dai and Wang, 2021] is professional basketball players from the 2016-2017 season as nodes, while edges denote social interactions among players on Twitter. Nationality, categorized as American or overseas, serves as the sensitive attribute, and the classification task focuses on predicting whether a player's salary is above the median level.
5.2 Baselines
We evaluate the proposed DIFGL method against a set of representative baseline approaches, which are grouped into two categories. i) Vanilla graph models: GCN [Kipf and Welling, 2016] and GIN [Xu et al., 2018]. ii) Fairnessenhanced methods: KSMOTE [Yan et al., 2020], which constructs pseudo-groups through clustering and enforces fairness using prediction regularization; Reckoner [Ni et al., 2024], which promotes group fairness through learnable noise injection and knowledge sharing in a dual-model framework; Themis [Wang et al., 2025d], which addresses fair graph learning without demographic information by inferring demographic proxies via a Bayesian variational autoencoder and enforcing fairness through disentangled latent; and fairGNN-WOD [Wang et al., 2025e], which mitigate bias without demographics by leveraging disentanglement learning to separate sensitive and task-related information. For approaches not originally developed for graph-structured data, we adapt their implementations to operate with our GNN backbone following the authors' original designs.
5.3 EvaluationMetrics
We adopt two predictive performance metrics, namely AUC and F1-score, with higher scores indicating better predictive accuracy. For fairness evaluation, we utilize two commonly used metrics: Demographic Parity (∆DP ) [Dwork et al., 2012] and Equalized Odds (∆EO) [Hardt et al., 2016], where values approaching zero represent greater fairness.
5.4 Experiment Results
Comparison Study. Table 1 presents a detailed comparison of DIFGL against six baseline methods on three benchmark datasets, evaluating both predictive performance metrics and fairness metrics. We first observed that DIFGL consistently achieves the best fairness outcomes across all datasets, reflecting lower values of fairness metrics compared to baseline methods. This improvement in fairness arises from DIFGL's explicit strategy of targeting the highest-loss nodes, identified via the LDI perspective, and incrementally adjusting their weights during training. In contrast, standard GNNmethods, such as GCN and GIN, optimize only average predictive performance, often leaving persistent disparities among certain node subpopulations. Data-level approaches (e.g., KSMOTE) attempt to mitigate disparity by altering the training data distribution, but this can cannot guarantee a balanced representation across different subgroups, nor can they ensure independence between demographic attributes and model decisions. Similarly, approaches based on demographic inference may suffer from inaccuracies in inferred demographic labels, preventing them from accurately enforcing fairness constraints at the group level. In addition, we also observed that DIFGL reliably maintains competitive predictive performance, closely matching or slightly trailing behind the top predictive backbones, while substantially improving fairness. This is due to DIFGL's incremental correction mechanism guided by stable node-level residual signals, which avoids drastic parameter updates and thus preserves predictive accuracy. Overall, DIFGL consistently achieves a balanced trade-off between fairness and predictive performance, demonstrating its effectiveness in practical scenarios where explicit demographic information is unavailable or restricted.
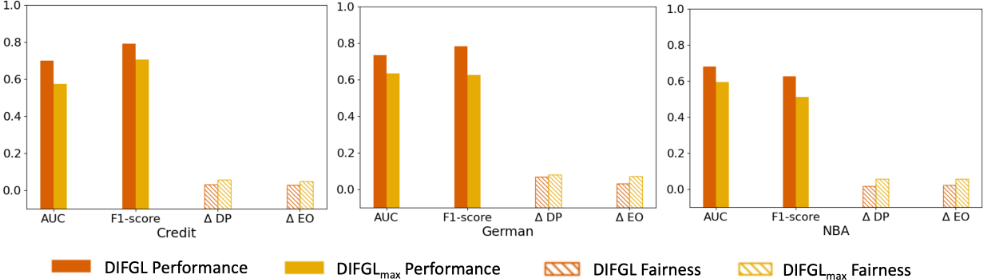
Ablation Study. We conduct an ablation study to gain deeper insights into the design and effectiveness of the LDI in DIFGL. Specifically, we compare DIFGL against a variant (denoted as DIFGLmax) that directly defines model bias as the maximum individual loss gap, representing a stricter, worst-case definition of latent disparity. Figure 1 shows the results, indicating that the DIFGLmax variant yields both worse predictive performance and weaker fairness outcomes compared to the original DIFGL. This occurs because the max-min loss range used by LDImax is dominated by only a few extreme nodes, and as training progresses, the identities of these nodes (maximizer and minimizer) often change abruptly. Such instability generates unreliable update signals, causing the model to chase after outlier nodes rather than systematically enhancing outcomes for the genuinely leastadvantaged subset. Moreover, reducing LDImax may involve overly suppressing the loss of the highest-loss node or artificially inflating the lowest-loss node, neither of which necessarily decreases the average disparity experienced by a meaningful fraction of the population. Hence, DIFGL with the original LDI effectively maintains a better balance between predictive utility and fairness compared to the DIFGLmax. Parameters Sensitivity. We investigate DIFGL's sensitivity
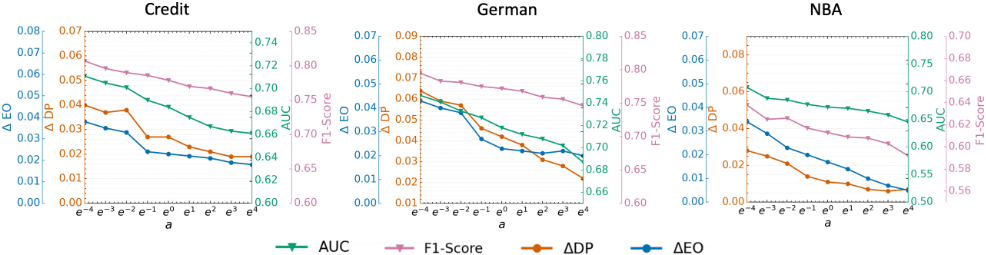
to the fairness-utility trade-off parameter a, varying it across the set {e-4 , e-3 , · · · , e4 }. The results are presented in Figure 2. We observe that increasing a places greater emphasis on minimizing the LDI-based disparity, typically resulting in improved fairness metrics. However, this improvement often comes with a trade-off in utility, as the model focuses more heavily on mitigate bias, potentially diverting capacity from overall prediction accuracy. Conversely, smaller values of a push the training closer to standard, accuracy-driven learning, which generally produces higher predictive performance but offers weaker fairness.
6 Conclusion
Given the observed gap between the assumptions made by existing AI fairness methods regarding the availability of demographic information and the reality of practical constraints in real-world applications, we introduced a novel framework for fair graph learning without explicit or inferred demographic information. Furthermore, we developed a randomized optimization strategy explicitly targeting variance reduction in node-level losses, ensuring consistent compliance with fairness threshold. Extensive experiments confirmed our framework's effectiveness, showing significant fairness gains without major drops in predictive accuracy. Our work thus provides a practical solution for achieving fairness in graph learning scenarios constrained by privacy or regulatory limitations, paving the way for future research in fairness without demographic supervision.
@inproceedings{ijcai2026p89,
  title     = {Towards Fair Graph Learning Without Demographic Supervision},
  author    = {Wang, Zichong and Yin, Zhipeng and Sha, Mo and Gao, Xiaofeng and Li, Xiaoli and Zhang, Wenbin},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {789--797},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/89},
  url       = {https://doi.org/10.24963/ijcai.2026/89},
}
TY - CPAPER TI - Towards Fair Graph Learning Without Demographic Supervision AU - Wang, Zichong AU - Yin, Zhipeng AU - Sha, Mo AU - Gao, Xiaofeng AU - Li, Xiaoli AU - Zhang, Wenbin T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 789 EP - 797 DO - 10.24963/ijcai.2026/89 UR - https://doi.org/10.24963/ijcai.2026/89 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





