
Entangled Kernels
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2578-2584.
https://doi.org/10.24963/ijcai.2019/358
Keywords
- Machine Learning: Kernel Methods
- Machine Learning: Multi-instance;Multi-label;Multi-view learning
Abstract
We consider the problem of operator-valued kernel learning and
investigate the possibility of going beyond the well-known separable
kernels. Borrowing tools and concepts from the field of quantum computing, such
as partial trace and entanglement, we propose a new view on
operator-valued kernels and define a general family of kernels that
encompasses previously known operator-valued kernels, including
separable and transformable kernels. Within this framework, we introduce another novel class of
operator-valued kernels called entangled kernels that are not
separable. We propose an efficient two-step algorithm for this framework, where the
entangled kernel is learned based on a novel extension of kernel
alignment to operator-valued kernels. The utility of the algorithm is illustrated on both artificial and real data.
- [Alvarez et al., 2012] Mauricio A. Alvarez, Lorenzo Rosasco, Neil D. Lawrence, et al. Kernels for vector- valued functions: A review. Foundations and Trends R in Machine Learning, 4(3):195-266, 2012.
- [Attal, 2015] Stephane Attal. Lectures in quantum noise the- ory. Lecture 6: Quantum channels, 2015.
- [Bengtsson and Życzkowski, 2017] Ingemar Bengtsson and Karol Życzkowski. Geometry of quantum states: an intro- duction to quantum entanglement. Cambridge university press, 2017.
- [Brault et al., 2016] Romain Brault, Markus Heinonen, and Florence Buc. Random Fourier features for operator- valued kernels. In ACML, pages 110-125, 2016.
- [Brouard et al., 2016] Céline Brouard, Marie Szafranski, and Florence d'Alché Buc. Input output kernel regression: Supervised and semi-supervised structured output predic- tion with operator-valued kernels. JMLR, 17(176):1-48, 2016.
- [Caponnetto et al., 2008] Andrea Caponnetto, Charles A. Micchelli, Massimiliano Pontil, and Yiming Ying. Uni- versal multi-task kernels. JMLR, 9(Jul):1615-1646, 2008.
- [Carmeli et al., 2010] Claudio Carmeli, Ernesto De Vito, Alessandro Toigo, and Veronica Umanita. Vector valued reproducing kernel hilbert spaces and universality. Analy- sis and Applications, 08(01):19-61, 2010.
- [Choi, 1975] Man-Duen Choi. Completely positive linear maps on complex matrices. Linear algebra and its ap- plications, 10(3):285-290, 1975.
- [Ciliberto et al., 2015] Carlo Ciliberto, Youssef Mroueh, Tomaso Poggio, and Lorenzo Rosasco. Convex learning of multiple tasks and their structure. In ICML, 2015.
- [Cortes et al., 2010] Corinna Cortes, Mehryar Mohri, and Afshin Rostamizadeh. Two-stage learning kernel algo- rithms. In ICML, pages 239-246, 2010.
- [Cristianini et al., 2002] Nello Cristianini, John Shawe- Taylor, Andre Elisseeff, and Jaz S Kandola. On kernel- target alignment. In NIPS, pages 367-373, 2002.
- [Dinuzzo and Fukumizu, 2011] Francesco Dinuzzo and Kenji Fukumizu. Learning low-rank output kernels. In ACML, 2011.
- [Dinuzzo et al., 2011] Francesco Dinuzzo, Cheng S. Ong, Gianluigi Pillonetto, and Peter V Gehler. Learning output kernels with block coordinate descent. In ICML, 2011.
- [Evgeniou et al., 2005] Theodoros Evgeniou, Charles A. Micchelli, and Massimiliano Pontil. Learning multiple tasks with kernel methods. JMLR, 6:615-637, 2005.
- [Filipiak et al., 2018] Katarzyna Filipiak, Daniel Klein, and Erika Vojtková. The properties of partial trace and block trace operators of partitioned matrices. 33, 2018.
- [Gregorová et al., 2017] Magda Gregorová, Alexandros Kalousis, and Stéphane Marchand-Maillet. Forecast- ing and granger modelling with non-linear dynamical dependencies. In ECML-PKDD, 2017. [
- [Horodecki et al., 2009] Ryszard Horodecki, Paweł Horodecki, Michał Horodecki, and Karol Horodecki. Quantum entanglement. Reviews of modern physics, 81(2):865, 2009.
- [Jawanpuria et al., 2015] Pratik Jawanpuria, Maksim Lapin, Matthias Hein, and Bernt Schiele. Efficient output kernel learning for multiple tasks. In NIPS, 2015.
- [Kadri et al., 2012] Hachem Kadri, Alain Rakotomamonjy, Philippe Preux, and Francis R Bach. Multiple operator- valued kernel learning. In NIPS, 2012.
- [Kadri et al., 2016] Hachem Kadri, Emmanuel Duflos, Philippe Preux, Stéphane Canu, Alain Rakotomamonjy, and Julien Audiffren. Operator-valued kernels for learning from functional response data. JMLR, 16:1-54, 2016.
- [Kraus, 1983] Karl Kraus. States, effects and operations: fundamental notions of quantum theory. Springer, 1983.
- [Lim et al., 2015] Néhémy Lim, Florence d'Alché Buc, Cédric Auliac, and George Michailidis. Operator-valued kernel-based vector autoregressive models for network in- ference. Machine learning, 99(3):489-513, 2015.
- [Micchelli and Pontil, 2005] Charles A. Micchelli and Mas- similiano Pontil. On learning vector-valued functions. Neural Computation, 17:177-204, 2005.
- [Minh et al., 2016] Ha Quang Minh, Loris Bazzani, and Vit- torio Murino. A unifying framework in vector-valued re- producing kernel hilbert spaces for manifold regularization and co-regularized multi-view learning. JMLR, 17(25):1- 72, 2016.
- [Minh, 2016] Ha Quang Minh. Operator-valued Bochner theorem, Fourier feature maps for operator-valued ker- nels, and vector-valued learning. arXiv preprint arXiv:1608.05639, 2016.
- [Mintert et al., 2009] F Mintert, C Viviescas, and A Buch- leitner. Basic concepts of entangled states. In Entangle- ment and Decoherence, pages 61-86. Springer, 2009.
- [Petersen and Pedersen, 2008] Kaare Brandt Petersen and Michael Syskind Pedersen. The matrix cookbook. Techni- cal University of Denmark, 7(15):510, 2008.
- [Rahimi and Recht, 2008] Ali Rahimi and Benjamin Recht. Random features for large-scale kernel machines. In NIPS, pages 1177-1184, 2008.
- [Rieffel and Polak, 2011] Eleanor G. Rieffel and Wolf- gang H. Polak. Quantum computing: A gentle introduc- tion. MIT Press, 2011.
- [Sangnier et al., 2016] Maxime Sangnier, Olivier Fercoq, and Florence d'Alché Buc. Joint quantile regression in vector-valued rkhss. In NIPS, pages 3693-3701, 2016.
- [Sindhwani et al., 2013] Vikas Sindhwani, Minh Ha Quang, and Aurélie C. Lozano. Scalable matrix-valued kernel learning for high-dimensional nonlinear multivariate re- gression and granger causality. In UAI, 2013.
- [Williams and Seeger, 2001] Christopher KI Williams and Matthias Seeger. Using the nyström method to speed up kernel machines. In NIPS, pages 682-688, 2001.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
There is a growing body of learning problems for which each instance in the training set is naturally associated with a set of labels (discrete and/or continuous). Output kernel learning algorithms approach these problems by learning simultaneously a vector-valued function in a reproducing kernel Hilbert space (RKHS) and a positive semidefinite matrix that describes the relationships between the labels [Dinuzzo et al., 2011; Dinuzzo and Fukumizu, 2011; Ciliberto et al., 2015; Jawanpuria et al., 2015]. The main idea of these methods is to learn a separable operator-valued kernel.
Operator-valued kernels appropriately generalize the wellknown notion of reproducing kernels and provide a means for extending the theory of reproducing kernel Hilbert spaces from scalar- to vector-valued functions. They were introduced as a machine learning tool in [Micchelli and Pontil, 2005] and have since been investigated for use in various machine learning tasks, including multi-task learning [Evgeniou et al., 2005], functional regression [Kadri et al., 2016], structured output prediction [Brouard et al., 2016], quantile learning [Sangnier et al., 2016] and multi-view learning [Minh et al., 2016]. The kernel function outputs then a linear operator (a matrix in the case of finite-dimensional output spaces) which encodes information about multiple output variables.
A challenging question in vector-valued learning is what sort of interactions should the operator-valued kernel learn and quantify, and how should one build and design these kernels. This is the main question investigated in the paper in the context of non-separability between input and output variables.
Some classes of operator-valued kernels have been proposed in the literature [Caponnetto et al., 2008; Alvarez et al., 2012], with separable kernels being one of the most widely used for learning vector-valued functions due to their simplicity and computational efficiency. These kernels are formulated as a product between a kernel function for the input space alone, and a matrix that encodes the interactions among the outputs. In order to overcome the need for choosing a kernel before the learning process, output kernel learning methods learn the output matrix from data [Ciliberto et al., 2015; Dinuzzo et al., 2011; Jawanpuria et al., 2015]. However there are limitations in using separable kernels. These kernels use only one output matrix and one input kernel function, and then cannot capture different kinds of dependencies and correlations. Moreover the kernel matrix associated to separable kernels is a rank-one kronecker product matrix (i.e, computed by only one kronecker product), which is restrictive as it assumes a strong repetitive structure in the operator-valued kernel matrix that models input and output interactions.
To go beyond separable kernels, some attempts have been made to learn a weighted sum of them in the multiple kernel learning framework [Kadri et al., 2012; Sindhwani et al., 2013; Gregorov´a et al., 2017]. Another approach, proposed by [Lim et al., 2015], is to learn a combination of a separable and a transformable kernel. The form of the transformable kernel is fixed in advance but allows to encode non-separable dependencies between inputs and outputs. Despite these previous investigations, the lack of knowledge about the full potential of operator-valued kernels and how to go beyond the restrictive separable kernel clearly hampers their widespread use in machine learning and other fields.
Contributions. In the present paper, we provide a novel framework for characterizing and designing inseparable kernels. By leveraging tools from the field of quantum computing (Section 2), we introduce a novel class of kernels based on the notion of partial trace which generalizes the trace operation to block matrices. This class of partial trace kernels we propose is very broad and encompasses previously known operator-valued kernels, including separable and transformable kernels (Section 3). From the new class of partial trace kernels we derive another new class of operatorvalued kernels, called entangled kernels, that are not separable. To our knowledge, this is the first time such operatorvalued kernel categorization has been performed. For this class of kernels we develop a new algorithm called EKL (Entangled Kernel Learning) that in two steps learns a partial trace kernel function (Section 4), and a vector-valued funcion. For the first step of kernel learning, we propose a novel definition of alignment between an operator-valued kernel and labels of a multi-output learning problem. To our knowledge, this is the first proposition on how to extend alignment to context of operator-valued kernels. Our algorithm offers improvements to high computational cost usually associated with learning with general operator-valued kernels. We provide an empirical evaluation of EKL performance which demonstrates its effectiveness on artificial data as well as real benchmarks (Section 5).
Notation. We denote scalars, vectors and matrices as a, a and A respectively. The notation A ≥ 0 will be used to denote a positive semidefinite (psd) matrix. Throughout the paper we use n as the number of labeled data samples and p as the number of outputs corresponding to one data sample. We denote our set of data samples by {xi, yi}ni=1 on X × Y, where X is a Polish space and Y is a separable Hilbert space. Usually, X and Y are respectively Rd and Rp equipped with the standard Euclidean metric. We use k(·, ·) as a scalar-valued, and K(·, ·) as an operator-valued kernel function; the corresponding kernel matrices are K ∈ Rn×n and G ∈ Rnp×np , the latter containing blocks of size p × p. We denote by K and H the reproducing kernel Hilbert spaces associated to the kernels k and K, respectively.
2 Background
In this section we give some background about quantum entanglement and review the basics of learning with operatorvalued kernels.
2.1 Background on QuantumEntanglement
Quantum entanglement is a fundamental feature of quantum mechanics and quantum information. This section is not intended to provide a broad overview or exhaustive survey of the literature on quantum etanglement, but gives some notions on entanglement as quantum property of mixed composite quantum systems that inspired our entangled kernel design. We refer the reader to [Horodecki et al., 2009], [Bengtsson and ˙Zyczkowski, 2017], and [Rieffel and Polak, 2011, chap. 10] for more background information.
Composite quantum systems are systems that naturally decompose into two or more subsystems, where each subsystem itself is a proper quantum system. We focus here only on bipartite quantum systems, i.e., systems composed of two distinct subsystems. The Hilbert space F associated with a bipartite quantum system is given by the tensor product F1⊗F2 of the spaces corresponding to each of the subsystems. In quantum mechanics, the state of a quantum system is represented by a state vector ψ ∈ F. However, it is also possible for a system to be in a statistical ensemble of different state vectors. The sate of the quantum system in this case is called a mixed state. It is characterized by a density matrix ρ which in general takes the following form
where the coefficients pj are non-negative and sum to one. For a composite quantum system of two subsytems with a density matrix ρ, the state of, say, the first subsystem is described by a reduced density matrix, given by taking the partial trace of ρ over F2. In the following we review the notions of partial trace, separability and entanglement of bipartite quantum systems.
We denote the set of linear operators from a Hilbert space B to B as L(B). Let F1 and F2 be separable Hilbert spaces.
Definition 1. (partial trace)
Partial trace operator on L(F1 ⊗ F2) is the unique linear operator trF2 : L(F1 ⊗F2) → L(F1) such that trF2 (A⊗ B) =A tr(B), ∀ A ∈ L(F1), B ∈ L(F2).
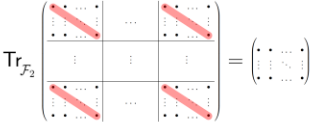
In finite dimensions, elements in L(A) and L(A⊗B) are simply matrices and block matrices of some sizes p × p and pN × pN, and the partial trace is obtained by computing the trace of each block in the input matrix (see Figure 1). The notion of partial trace is a generalization of the trace operation to block structured matrices [Rieffel and Polak, 2011, chap. 10]. Note that there are two ways of generalizing trace to block matrices. Another possiblity would be so-called block trace [Filipiak et al., 2018] where the result is sum of diagonal blocks, but in this work we only consider the "blockwise trace" definition.
In the case where the density matrix ρ of a mixed bipartite state can be written as ρ = ρ1 ⊗ ρ2, where ρ1 and ρ2 are subsystems' density matrices on F1 and F2, the partial trace of ρ with respect to F2 is ρ1. This form of mixed product states is restrictive and does not exhibit correlations between the two subsystems. A convex sum of different product states,
with pi ≥ 0 and ∑i pi = 1, however, will in general represent certain types of correlations between the subsystems of the composite quantum system. These correlations can be described in terms of the classical probabilities pi, and are therefore considered classical. States of the form (1) thus are called separable mixed states. In contrast, a mixed state is entangled if it cannot be written as a convex combination of product states, i.e.,
Entangled states are one of the most commonly encountered class of bipartite states possessing quantum correlations [Mintert et al., 2009]. A challenging problem in quantum computing is to identify necessary and suffcient conditions for quantum separability. There is no practically efficient necessary and suffcient criteria for identifying whether a given ρ is entangled or separable [Horodecki et al., 2009].
2.2 Learning with Operator-Valued Kernels
We now review the basics of operator-valued kernels (OvKs) and their associated vector-valued reproducing kernel Hilbert spaces (RKHSs) in the setting of supervised learning. Vectorvalued RKHSs were introduced to the machine learning community by [Micchelli and Pontil, 2005] as a way to extend kernel machines from scalar to vector outputs. Given a set of training samples {xi, yi}ni=1 on X ×Y, optimization problem
where f is a vector-valued function and V is a loss function, can be solved in a vector-valued RKHS H by the means of a vector-valued extension of the representer theorem.
Definition 2. (vector-valued RKHS)
A Hilbert space H of functions from X to Y is called a reproducing kernel Hilbert space if there is a positive definite L(Y)-valued kernel K on X × X such that:
- the function z ↦→ K(x, z)y belongs to H, ∀ z, x ∈ X, y ∈ Y,
- ∀f ∈ H, x ∈ X, y ∈ Y, 〈f,K(x, ·)y〉H = 〈f(x), y〉Y (reproducing property).
Definition 3. (operator-valued kernel)
A L(Y)-valued kernel K on X ×X is a function K(·, ·) : X ×X →L(Y); it is positive semidefinite if:
- K(x, z) = K(z, x)∗ , where superscript ∗ denotes the adjoint operator,
- and, for every r ∈ N and all {(xi, yi)i=1,...,r} ∈ X ×Y, ∑i,j 〈yi, K(xi, xj )yj 〉Y ≥ 0.
Theorem 1. (bijection between vector-valued RKHS and operator-valued kernel) An L(Y)-valued kernel K on X ×X is the reproducing kernel of some Hilbert space H, if and only if it is positive semidefinite.
Theorem 2. (representer theorem)
Let K be a positive semidefinite operator-valued kernel and H its corresponding vector-valued RKHS. The solution ˆ f ∈ H of the regularized optimization problem (3) has the form
With regard to the classical representer theorem, here the kernel K outputs a matrix and the "weights" ci are vectors. The proofs of Theorem 1 and 2 can be found in [Micchelli and Pontil, 2005; Kadri et al., 2016]. For further reading on operator-valued kernels and their associated RKHSs, see, e.g., [Caponnetto et al., 2008; Carmeli et al., 2010].
3 Partial Trace and Entangled Kernels
Some well-known classes of operator-valued kernels include separable and transformable kernels. Separable kernels are defined by
where T is a psd matrix in Rp×p (an operator in L(Y) in the general case of any separable Hilbert space Y) and k is a scalar-valued kernel. This class of kernels is very attractive in terms of computational time, as it is easily decomposable. However the matrix T acts only on the outputs independently of the input data, which makes it difficult for these kernels to capture input-output relations. In the same spirit a more general class, sum of separable kernels, is given by
where kl are a scalar-valued kernels and Tl ∈ Rp×p are psd. It can capture different kinds of similarities but still assumes that the unknown input-output dependencies can be decomposed into a product of two separate kernel functions that encode interactions among inputs and outputs independently.
Transformable kernels are defined by
Here m and l are indices of the output matrix and {St}pt=1 are mappings which transform the data from X to another space ˜ X in which a scalar-valued kernel ˜k : ˜ X × ˜ X → R is defined. In contrast to separable kernels, here the mappings St operate on input data while dependening on outputs; however they are not intuitive nor easy to interpret and determine.
While it is straightforward to see that separable kernels belong to the larger class of sum of separable, the picture is less clear for transformable kernels. The following examples clarify this situation.
Example 1. On the space X = R, consider the kernel
K is a transformable kernel, but not a (sum of) separable kernel. We obtain that K is transformable simply by choosing ˜k(x, z) = xz, S1(x) = x, and S2(x) = x2 in Eq. 7. From the property of positive definiteness of the operator-valued kernel, it is easy to see that the matrix T of a separable kernel is symmetric (see Eq. 5), and since the matrix K(x, z) is not, K is not a separable kernel.
Example 2. Let K be the kernel function defined as
where T ∈ Rp×p is a rank one positive semidefinite matrix. K is both separable and transformable kernel. Since T is of rank one, it follows that (K(x, z))lm = ulum〈x, z〉, with T = uu⊤. We can see that K is transformable by replacing in Eq. 7 ˜k(x, z) by 〈x, z〉 and St(x) by utx, t = 1, . . . , p. K is separable by construction.
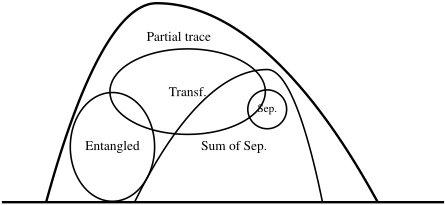
It is worth noting that separable kernels are not limited to finite-dimensional output spaces, while transformable kernels are. Figure 2 depicts inclusions among kernel classes discussed here and the two new families of operator-valued kernels we propose: partial trace kernels and entangled kernels.
We now define two novel classes of operator-valued kernels. The first one, class of partial trace kernels, encompasses both (sum of) separable and transformable kernels, while the second, entangled kernels, is a class of non-separable kernels. We start by introducing the more general class of partial trace kernels. The intuition behind this class of kernels is that in the scalar-valued case any kernel function k can be written as the trace of an operator in L(K). It is easy to show that k(x, z) = tr(φ(x) ⊗ φ(z)⊤).
Definition 4. (Partial trace kernel)
A partial trace kernel is an operator-valued kernel function K having the following form
where Pφ(x),φ(z) is an operator on L(Y ⊗ K), and trK is the partial trace on K (i.e., over the inputs).
The class of partial trace kernels is very broad and encompasses the classes of separable and transformable kernels (see Figure 2). From the definition of the partial trace operation, we can see that if we choose Pφ(x),φ(z) = ∑l Tl ⊗ (φl(x) ⊗ φl(z)⊤), we recover the case of sum of separable kernels. In the same way, if we fix [P˜ φ(x), ˜ φ(z) ]pl,m=1 = ( ˜ φ ◦ Sl(x)) ⊗ ( ˜ φ◦Sm(z))⊤ in Eq. 8, computing the trace of each block using the partial trace will give the transformable kernel. With this in mind, we can use the partial trace kernel formulation to induce a novel class for operator-valued kernels which are not separable, with the goal to characterize inseparable correlations between inputs and outputs.
Definition 5. (Entangled kernel)
An entangled operator-valued kernel K is defined as
where T is of size p × p, and U ∈ RpN×pN is not separable.
Here we have abused the notation by introducing N as the dimensionality of feature representation φ(x). However we do not restrict ourselves to finite dimensions and N in this notation can also be infinite. In this definition, U not being separable means that it cannot be written as U = A⊗B, with A ∈ Rp×p and B ∈ RN×N . The term T ⊗ (φ(x) ⊗ φ(z)⊤) represents a separable kernel function over inputs and outputs, while U characterizes the entanglement shared between them. Some intuition to U can be seen from its role of an "entangled" similarity in the joint feature space. It is entangled in the sense that cannot be decomposed into two "sub"-matrices of similarity between inputs and between outputs independently. The partial trace is the operation used to recover the sub-similarity matrix between the outputs from the entangled joint similarity matrix. In the particular case of separability, the partial trace will give the output metric. Choice of U is crucial to this class of kernels. In the next section we develop an algorithm that learns an entangled kernel from data.
4 Entangled Kernel Learning
In general, there is no knowing whether input and output data are or are not entangled. In this sense, learning the entangled K in Eq. 9 by imposing that U is inseparable can sometimes be restrictive. In our entangled kernel learning approach we do not impose any separability restriction, with the hope that our learning algorithm can automatically detect the lack or presence of entanglement. Key to our method is a reformulation of the entangled kernel K (Eq. 9) via Choi-Kraus representation. The infinite case is less treated in literature, and for it we refer reader to [Attal, 2015].
Theorem3. (Choi-Kraus representation [Choi, 1975; Kraus, 1983; Rieffel and Polak, 2011])
The map K(x, z) = trK (U(T ⊗ (φ(x) ⊗ φ(z)⊤))U⊤) can be generated by an operator sum representation containing at most pN elements,
where Mi ∈ Rp×N and 1 ≤ r ≤ pN.
It is easy to see that our kernel is positive. Using this formulation, entangled kernel learning consists of finding a low-rank decomposition of the kernel by learning the matrices Mi, i = 1, . . . , r (r ≪ pN), which "merge" the matrices T and U. While every entangled kernel can be represented like this, the representation is not restricted only to entangled kernels. Thus by learning theMi we expect to learn the meaningful relationships in the data, be they entangled or not.
Because the feature space can easily be of very large dimensionality (or infinite-dimensional), we consider an approximation to speed up the computation. For example random Fourier features or Nystr¨om approximation [Rahimi and Recht, 2008; Williams and Seeger, 2001] give us ˆ φ such that k(x, z) = 〈φ(x), φ(z)〉 ≈ 〈 ˆ φ(x), ˆ φ(z)〉. We note that our approximation is on scalar-valued kernel, not operator-valued, although there are methods for approximating them, too, directly [Brault et al., 2016; Minh, 2016]. Our approximated kernel is thus
where ˆ φ(x) ∈ Rm and ˆMi ∈ Rp×m, from where our goal is to learn the ˆMi. We can write our np × np kernel matrix as
where ˆΦ = [ˆ φ(x1), · · · , ˆ φ(xn)] is of size m×n. Further, if we denote D = ∑ri=1 vec( ˆMi) vec( ˆMi)⊤, we can write
To learn an entangled kernel, we need to learn the psd matrix D. We adopt kernel alignment -based kernel learning strategy introduced in [Cristianini et al., 2002; Cortes et al., 2010] for scalar-valued kernels in the setting when every input was associated with only one output, or label. Alignment between two matrices M and N is defined as
where subscript c refers to centered matrices. We extend the concept of alignment into case of multiple outputs and consider a convex combination of two such alignments. Namely our optimization problem is
where γ ∈ [0, 1], y = vec(Y), and Y is of size p×n, containing the labels associated to data sample i on its ith column. We note that by applying Lemma 2.11 from [Filipiak et al., 2018], we can write trp( ˆG) = ˆΦ⊤trp(D) ˆΦ.
Intuitively the first alignment learns a scalar-valued kernel matrix that can be obtained via partial trace applied to the more complex operator-valued kernel, while the second term focuses on the possibly entangled relationships in the data. Indeed, one possibility for using the entangled kernel framework is to learn a scalar-valued kernel for multi-output problem and to use this kernel in machine learning algorithms.
The optimization problem is solved with gradient-based approach. To make sure that the resulting kernel is valid (psd), we write D = QQ⊤ with Q of size mp × r with r at most mp, and perform the optimization over Q. The gradients for alignment terms are straightforward to calculate. The optimization is performed on sphere manifold as a way to regularize D. 2 After we have learned the entangled kernel, we solve the learning problem by choosing the squared loss
For this c update we can find the classical closed-form solution, c = ( ˆG+ λI)-1 vec(Y). Note that this computation is, by considering the entangled structure of ˆG, more computationally efficient than a general (say, some transfomable)
1 [Petersen and Pedersen, 2008, Eq. 520]
2 www.manopt.org/ ; pymanopt.github.io/
Algorithm 1 Entangled Kernel Learning (EKL)
Input: matrix of features Φ, labels Y
// 1) Kernel learning: (D=QQ⊤)
Solve for Q in eq.14 within a sphere manifold
// 2) Learning the predictive function:
if Predict with scalar-valued kernel then
operator-valued kernel. Generally we can say that the complexity of predicting with nonseparable operator-valued kernels is O(n3 p3 ). In our proposed network, however, we can apply Woodbury formula for the matrix inversion and only invert a r×r matrix, giving total complexity of O(r3 +mnp2 ). Moreover it is possible in our kernel learning framework to extract a scalar-valued kernel, K = trp( ˆG), and use that in predicting with traditional cost of O(n3 ), or O(m3 +mnp) if taken advantage of the form of the entangled kernel. The parameters γ and λ can be set with cross-validation, first caclulating the kernel learning step with various γ parameters and then considering the various λ for each of them.
5 Experiments
In this section the performance of our algorithm is illustrated with artificial and real datasets. The algorithms compared in these settings are: EKL 3 ; our proposed Entangled Kernel Learning algorithm, OKL [Dinuzzo et al., 2011]; a kernel learning method for separable kernels (we use the code provided by the authors 4 ), and KRR; kernel ridge regression. Furhtermore, we investigate performance of predicting with scalar-valued kernel extracted from the operator-valued kernel matrix EKL learns, and call this ptrEKL. In all the experiments we cross-validate over various regularization parameters λ, and for EKL also γs controlling the combination of alignments. In the experiments we consider (normalized) mean squared error (nMSE) and normalized improvement to KRR (nI) [Ciliberto et al., 2015] as error measures.
5.1 Artificial Data
EKL is expected to learn complex relationships within the data. To illustrate this, we created data with bi-linear model TCA+ ICK = Y, where T, C and A are randomly created p×p, p×n, and n×n matrices respectively. K is linear kernel calculated from randomly generated data X ∈ Rn×d ; this kernel is given to the learning algorithms along with noisy labels Y. We can see that when p is larger than n (or comparable) the predictive capabilities of EKL are much better than for other methods. Here predicting with the scalarvalued kernel extracted form learned entangled kernel gives the best results (Figure 3(a)).
3 The code will be made available at RH's personal webpage
4 http://people.tuebingen.mpg.de/fdinuzzo/okl.html
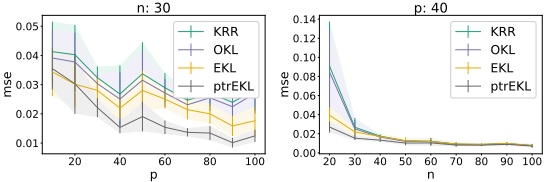
- (a) Results of the simulated experiments with fixed amount of inputs and varying number of outputs (left), and fixed amount of outputs and varying inputs (right).
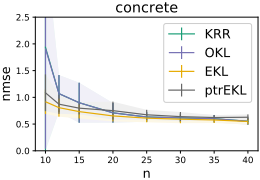
- (b) Results on Concrete data set with varying amount of training data (n) used.
| n = 50 | n = 100 | n = 200 | n = 1000 | |||||
|---|---|---|---|---|---|---|---|---|
| method | nMSE | nI | nMSE | nI | nMSE | nI | nMSE | nI |
| KRR | 0.2418 ± 0.0281 | 0.0000 | 0.1668 ± 0.0097 | 0.0000 | 0.1441 ± 0.0037 | 0.0000 | 0.1273 ± 0.0006 | 0.0000 |
| OKL | 0.2445 ± 0.0296 | -0.0109 | 0.1672 ± 0.0099 | -0.0026 | 0.1442 ± 0.0037 | -0.0009 | 0.1273 ± 0.0006 | -0.0000 |
| EKL/ptrEKL | 0.2381 ± 0.0250 | 0.0139 | 0.1661 ± 0.0097 | 0.0040 | 0.1440 ± 0.0037 | 0.0003 | 0.1273 ± 0.0006 | 0.0001 |
| n = 5 | n = 10 | |||
|---|---|---|---|---|
| method | nMSE | nI | nMSE | nI |
| KRR | 0.951 ± 0.101 | 0.000 | 0.813 ± 0.141 | 0.000 |
| OKL | 1.062 ± 0.250 | -0.092 | 0.900 ± 0.196 | -0.094 |
| EKL/ptrEKL | 0.840 ± 0.084 | 0.124 | 0.722 ± 0.036 | 0.107 |
Table 2: Results on Weather data set averaged over 5 data partitions.
5.2 Real Data
We have considered the following regression data sets: Concrete slump test (UCI dataset repository) with 103 data samples and three output variables; Sarcos 5 is a dataset characterizing robot arm movements with 7 tasks; Weather 6 has daily weather data (p = 365) from 35 stations.
The main advantage of learning complex dependencies in the data lies in the setting where number of samples is relatively low; a phenomenon observed already in output kernel learning setting [Ciliberto et al., 2015; Jawanpuria et al., 2015]. With small amounts of data learning the complex relationships in EKL is even more beneficial than learning the output dependencies of OKL. Figure 3(b) shows this advantage on Concrete data set when number of instances used in training is small. Here, in contrast to our simulated data, EKL performs better than ptrEKL. For Sarcos data set we consider the setting in [Ciliberto et al., 2015] and show the results in Table 1 (predicting is done to all 5000 test samples). Similarly, we observe that the advantages of using EKL diminish with more data samples added to the problem. This is also clearly seen in the Weather data set, where number of outputs is much larger than the number of data samples (Table 2).
5 www.gaussianprocess.org/gpml/data/
6 https://www.psych.mcgill.ca/misc/fda/
6 Conclusion
In this work we shed new light on meaning of inseparable kernels by defining a general framework for constructing operator-valued kernels based on the notion of partial trace and using ideas borrowed from the field of quantum computing. Instances of our framework include entangled kernels, a new conceptually interesting class of kernels that is designed to capture more complex dependencies between input and output variables as the more restricted class of separable kernels. We have proposed a new algorithm, entangled kernel learning (EKL), that learns this entangled kernel and a vector- or scalar-valued function in two steps. The first step that learns the entangled kernel uses a definition of kernel alignment, extended here for use with operator-valued kernels with help of partial trace operator. In contrast to output kernel learning, EKL is able to learn inseparable kernels and can model a larger variety of interactions between input and output data. Moreover, the structure of the entangled kernels enables more efficient computation than that with general operator-valued kernels. Our illustration on artificial data and experiments on real data give validation to our approach.
In the future work the potential of EKL should be investigated further, especially the effect of very small number of columns in matrix Q, in low rank kernel setting. The twostep kernel learning is proven to produce good predictors with alignment to ideal kernel [Cortes et al., 2010]. It is reasonable to expect that some similar guarantees could be formulated also for our setting, as it is provably effective in practice.
Acknowledgements
We would like to thank F. Denis, P. Arrighi and G. Di Molfetta for helpful discussions. This work is granted by Lives project (ANR-15-CE23-0026).
@inproceedings{ijcai2019p358,
  title     = {Entangled Kernels},
  author    = {Huusari, Riikka and Kadri, Hachem},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2578--2584},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/358},
  url       = {https://doi.org/10.24963/ijcai.2019/358},
}
TY - CPAPER TI - Entangled Kernels AU - Huusari, Riikka AU - Kadri, Hachem T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2578 EP - 2584 DO - 10.24963/ijcai.2019/358 UR - https://doi.org/10.24963/ijcai.2019/358 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





