
Who Should Pay the Cost: A Game-theoretic Model for Government Subsidized Investments to Improve National Cybersecurity
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. AI for Improving Human Well-being. Pages 6020-6027.
https://doi.org/10.24963/ijcai.2019/834
Keywords
- Special Track on AI for Improving Human-Well Being: Human wellbeing (Special Track on AI and Human Wellbeing)
- Special Track on AI for Improving Human-Well Being: AI benefits to society AI applications (Special Track on AI and Human Wellbeing)
Abstract
Due to the recent cyber attacks, cybersecurity is becoming more critical in modern society. A single attack (e.g., WannaCry ransomware attack) can cause as much as $4 billion in damage. However, the cybersecurity investment by companies is far from satisfactory. Therefore, governments (e.g., in the UK) launch grants and subsidies to help companies to boost their cybersecurity to create a safer national cyber environment. The allocation problem is hard due to limited subsidies and the interdependence between self-interested companies and the presence of a strategic cyber attacker. To tackle the government's allocation problem, we introduce a Stackelberg game-theoretic model where the government first commits to an allocation and the companies/users and attacker simultaneously determine their protection and attack (pure or mixed) strategies, respectively. For the pure-strategy case, while there may not be a feasible allocation in general, we prove that computing an optimal allocation is NP-hard and propose a linear reverse convex program when the attacker can attack all users. For the mixed-strategy case, we show that there is a polynomial time algorithm to find an optimal allocation when the attacker has a single-attack capability. We then provide a heuristic algorithm, based on best-response-gradient dynamics, to find an effective allocation in the general setting. Experimentally, we show that our heuristic is effective and outperforms other baselines on synthetic and real data.
- [Basilico et al., 2016] Nicola Basilico, Stefano Coniglio, and Nicola Gatti. Methods for finding leader-follower equilibria with multiple followers. In AAMAS, pages 1363-1364, 2016.
- [Böhme et al., 2010] Rainer Böhme, Galina Schwartz, et al. Modeling cyber-insurance: towards a unifying framework. In WEIS, 2010.
- [CBS, 2017] CBS. Wannacry ransomware attack losses could reach $4 billion. https://www.cbsnews.com/news /wannacry-ransomware-attacks-wannacry-virus-losses/, 2017. Last accessed on 25 Feb 2019. Link
- [Chan et al., 2012] Hau Chan, Michael Ceyko, and Luis E. Ortiz. Interdependent defense games: Modeling interde- pendent security under deliberate attacks. In UAI, pages 152-162, 2012.
- [Chan et al., 2017] Hau Chan, Michael Ceyko, and Luis Or- tiz. Interdependent defense games with applications to in- ternet security at the level of autonomous systems. Games, 8(1):13, 2017.
- [Coniglio et al., 2017] Stefano Coniglio, Nicola Gatti, and Alberto Marchesi. Pessimistic leader-follower equilibria with multiple followers. In IJCAI, pages 171-177, 2017. IJCAI
- [Czyzyk et al., 1998] Joseph Czyzyk, Michael P Mesnier, and Jorge J Moré. The NEOS server. IEEE Computational Science and Engineering, 5(3):68-75, 1998.
- [Fang et al., 2016] Fei Fang, Thanh H Nguyen, Rob Pickles, Wai Y Lam, Gopalasamy R Clements, Bo An, Amandeep Singh, Milind Tambe, and Andrew Lemieux. Deploying PAWS: Field optimization of the protection assistant for wildlife security. In IAAI, pages 3966-3973, 2016.
- [Fudenberg and Levine, 1998] Drew Fudenberg and David K Levine. The Theory of Learning in Games, volume 2. MIT press, 1998.
- [Gan et al., 2015] Jiarui Gan, Bo An, and Yevgeniy Vorob- eychik. Security games with protection externalities. In AAAI, pages 914-920, 2015.
- [Gan et al., 2018] Jiarui Gan, Edith Elkind, and Michael Wooldridge. Stackelberg security games with multiple un- coordinated defenders. In AAMAS, pages 703-711, 2018.
- [Gordon and Loeb, 2002] Lawrence A Gordon and Martin P Loeb. The economics of information security investment. ACM Transactions on Information and System Security (TISSEC), 5(4):438-457, 2002.
- [Gordon et al., 2003] Lawrence A Gordon, Martin P Loeb, and William Lucyshyn. Sharing information on computer systems security: An economic analysis. Journal of Ac- counting and Public Policy, 22(6):461-485, 2003.
- [Grossklags et al., 2010] Jens Grossklags, Svetlana Ra- dosavac, Alvaro A Cárdenas, and John Chuang. Nudge: Intermediaries' role in interdependent network security. In TRUST, pages 323-336, 2010.
- [Guo et al., 2016] Qingyu Guo, Bo An, Yair Zick, and Chun- yan Miao. Optimal interdiction of illegal network flow. In IJCAI, pages 2507-2513, 2016.
- [Horst and Tuy, 2013] Reiner Horst and Hoang Tuy. Global Optimization: Deterministic Approaches. Springer Sci- ence & Business Media, 2013.
- [Jiang et al., 2011] Libin Jiang, Venkat Anantharam, and Jean Walrand. How bad are selfish investments in network security? IEEE/ACM Transactions on Networking (TON), 19(2):549-560, 2011.
- [Kearns and Ortiz, 2004] Michael Kearns and Luis E Ortiz. Algorithms for interdependent security games. In NIPS, pages 561-568, 2004.
- [Kunreuther and Heal, 2003] Howard Kunreuther and Geof- frey Heal. Interdependent security. Journal of Risk and Uncertainty, 26(2-3):231-249, 2003.
- [Laszka et al., 2015] Aron Laszka, Mark Felegyhazi, and Levente Buttyan. A survey of interdependent information security games. ACM Computing Surveys, 47(2):23, 2015.
- [Omic et al., 2009] Jasmina Omic, Ariel Orda, and Piet Van Mieghem. Protecting against network infections: A game theoretic perspective. In INFOCOM, pages 1485- 1493, 2009.
- [Paruchuri et al., 2008] Praveen Paruchuri, Jonathan P Pearce, Janusz Marecki, Milind Tambe, Fernando Or- donez, and Sarit Kraus. Playing games for security: An efficient exact algorithm for solving bayesian Stackelberg games. In AAMAS, pages 895-902, 2008.
- [Schlenker et al., 2017] Aaron Schlenker, Haifeng Xu, Mina Guirguis, Chris Kiekintveld, Arunesh Sinha, Milind Tambe, Solomon Sonya, Darryl Balderas, and Noah Dun- statter. Don't bury your head in warnings: A game- theoretic approach for intelligent allocation of cyber- security alerts. In IJCAI, pages 381-387, 2017.
- [Schlenker et al., 2018] Aaron Schlenker, Omkar Thakoor, Haifeng Xu, Fei Fang, Milind Tambe, Long Tran-Thanh, Phebe Vayanos, and Yevgeniy Vorobeychik. Deceiving cy- ber adversaries: A game theoretic approach. In AAMAS, pages 892-900, 2018.
- [Tambe, 2011] Milind Tambe. Security and Game Theory: Algorithms, Deployed Systems, Lessons Learned. Cam- bridge University Press, 2011.
- [Thycotic, 2017] Thycotic. 2017 state of cyber security metrics annual report. https://thycotic.com/wp-content/u ploads/2013/03/2017-Cyber-Security-Strategy-Executive -Summary.pdf, 2017. Last accessed on 25 Feb 2019. Link
- [UK, 2015] UK. National Security Strategy and Strategic Defence and Security Review 2015. Government of the United Kingdom, 2015.
- [UK, 2016] UK. National Cyber Security Strategy 2016- 2021. Government of the United Kingdom, 2016.
- [Vorobeychik and Letchford, 2015] Yevgeniy Vorobey- chik and Joshua Letchford. Securing interdependent assets. Autonomous Agents and Multi-Agent Systems, 29(2):305-333, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Cybersecurity has become one of the most important issues of the modern society, and cyber attacks can cause extremely high loss to many companies, organizations and governments. For instance, the 2017 WannaCry ransomware attack affected more than 300,000 computers across 150 countries with a total damage $4 billion [CBS, 2017]. It is obviously clear that, from these recent cyber attacks, businesses are not doing enough to protect themselves and/or do not have sufficient awareness of cyber threats. In fact, 80% of over 400 global companies do not know where their sensitive data is located and how to secure it, and 60% of them do not protect their privileged accounts adequately [Thycotic, 2017]. Because companies and organizations are interdependent in cyber space, cyber attacks could propagate from one company to other organizations. Thus, the lack of protections against cyber threats not only causes damages to companies and organizations but also decreases the national cybersecurity level 1 .
To combat these issues, governments around the world have launched various initiatives to improve the national cybersecurity level. For example, the UK government, one of the pioneering countries on national cybersecurity practice, provided millions of subsidies, i.e., grants and vouchers, for businesses to boost their cybersecurity in 2015 and 2016 [UK, 2015]. The UK government's goal is [UK, 2016]
to intervene more actively and use increased investment, while continuing to support market forces to raise cyber security standards across the UK.
The government's goal is optimally assigning limited subsidies to companies to protect against the attacker. However, this assignment task is highly challenging because cyber companies are self-interested and interdependent (induced by the spreadability of cyber attacks) when making cyber protection decisions. In this work, we adopt game-theoretic methodologies to analyze cyber interactions and help the government to improve the national cybersecurity through subsidies.
Our contributions. First, we formulate our cybersecurity setting as a Stackelberg game played between the government, interdependent companies/users and an attacker where the government moves first to allocate subsidies and the users and attacker move simultaneously to determine their protection and attack (pure or mixed) strategies, respectively. We comprehensively investigate three settings where the attacker has different capabilities (i.e., attack all users, a single user and multiple users). For the pure-strategy case, we show that computing an optimal allocation is NP-hard when the attacker is able to attack all users. We propose a linear reverse convex program to compute an optimal allocation in this setting. However, we show that there may not be a feasible allocation in the two other settings. For the mixed-strategy case, we show that there is a polynomial time algorithm to find an optimal allocation in the single-attack setting. We then provide a heuristic algorithm, based on best-response-gradient dynamics, to find an effective allocation in the general setting. We extensively evaluate our model and the heuristic algorithm on synthetic and real data. The results show that our model captures the interdependent behaviors of users and our heuristic algorithm is effective and outperforms other baselines.
1 The national cybersecurity level in this paper is defined as the social welfare for companies across a country against cyber crimes.
2 RelatedWorks
There are several lines of the research related to this work. The first line is interdependent security game [Kunreuther and Heal, 2003; Kearns and Ortiz, 2004] where users are interdependent and can experience direct risk from internal contamination and indirect risk transferred from their neighbors and is widely applied to security settings such as airline baggage security, fire safety and computer virus. An extension of these works is interdependent defense game [Chan et al., 2012; Chan et al., 2017] where a strategic attacker is added into the game. However, they focus on the computation of Nash equilibria between users and the attacker and there is no defender who tries to optimize the global security level.
The second line of the related research is interdependent information security game [Laszka et al., 2015]. The famous Gordon-Loeb model [Gordon and Loeb, 2002] is a singleagent decision model, whose parameters are similar to our model, and its extension [Gordon et al., 2003] studies the information sharing between two agents, which differs from our model. Various schemes are proposed to improve the security level, which are based on either game-theoretic equilibrium improvements [Jiang et al., 2011] or mechanisms such as mandatory or optional insurances [B¨ohme et al., 2010], subsidies and fines [Grossklags et al., 2010] and regulations [Omic et al., 2009]. However, the mechanisms in these works are modeled as a part of agent's utility explicitly, which is not determined by a strategic agent as in our setting. Besides, there is no strategic attacker in all these works.
The third line of the related research is Stackelberg security game [Tambe, 2011; Fang et al., 2016] for security problems where the defender allocates limited resources to protect valuable targets against the attacker. Some recent works extended the method to cybersecurity problems, such as allocating cyber alerts [Schlenker et al., 2017] and deceiving cyber adversaries [Schlenker et al., 2018]. Some works consider the games where multiple types of independent followers following a known distribution [Paruchuri et al., 2008], the interdependence between targets [Vorobeychik and Letchford, 2015], the externalities of the protection [Gan et al., 2015] and network security games [Guo et al., 2016]. However, the interdependence between self-interested followers is not tackled in all previous works. Some works consider the multiple defenders against an attacker [Gan et al., 2018], which also cannot be applied to our problem due to the lack of the global optimizer. Recent works [Basilico et al., 2016; Coniglio et al., 2017] proposed the game between a leader and multiple followers. Their algorithms for the optimistic case (corresponding to our model) needs to enumerate all pure strategies of followers which is impossible in our case because we adopt a more compact representation of the game.
3 Motivation
We use the UK as a motivating example to illustrate the applicability of our model. From 2015 to 2020, the UK government will invest £1.9 billion to improve its cybersecurity through various schemes, such as grants, vouchers and subsidies [UK, 2015]. The UK government also builds the national cyber security centre (NCSC) 2 to manage cyber incidents, analyze cyber threats and provide tailored expertise support to businesses [UK, 2016]. With the help of NCSC, companies can obtain accurate information of cyber space and learn optimal cyber investment strategies. The information includes the vulnerabilities of businesses and the connections between businesses. The information is provided with the existence of the strategic cyber attacker (e.g., hacktivist) [UK, 2016].
We assume that companies are self-interested and there is no cooperation or coordination among them. It is worth noting that it is difficult for the attacker to observe companies' strategies before the attacks due to the lack of transparency of the cyber space. For example, the attacker cannot observe anti-spam filtering systems of companies before sending spam emails in phishing attacks. Therefore, we assume that companies and the attacker move simultaneously. We note that Nash equilibrium is a canonical solution concept for non-cooperative simultaneous-move settings.
4 Cybersecurity Investment Game
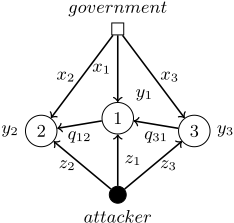
A Stackelberg Cybersecurity Investment Game (SCIG) is played between a government (e.g., cybersecurity agency), a set of interdependent users (e.g., companies and organizations) and an attacker. The whole procedure of the game can be divided into two stages: i) the government allocates budgeted subsidies to users, ii) each user, after obtaining the government's subsidy amount, and the attacker decide their own strategies simultaneously. Both users and the attacker are termed as followers. The interactions between followers exactly follow the assumptions and models in interdependent security (defense) game, which is widely investigated in [Kunreuther and Heal, 2003; Kearns and Ortiz, 2004; Chan et al., 2012; Chan et al., 2017].
Formally, we consider N interdependent users, of which each user i ∈ [N] = {1, 2, ...,N} is characterized by a tuple with parameters 〈pi, ci, li〉 where pi is the probability that user i will be compromised if being attacked by the attacker, i.e., direct attack, ci is the cost of user i to get a cybersecurity system such as installing firewalls, building intrusion detection systems and investigation programs, to prevent himself from the contamination, and li is the loss user i may suffer if he is compromised. To avoid the trivial case, we assume that ci < pili, ∀i ∈ [N]. We use q = 〈qji〉 to model the spread of the attack between users. For each pair j, i ∈ [N], j ̸= i, let qji denote the probability that user i is compromised as a result of a transfer of the attack from j, i.e., indirect attack.
Strategies. The government's strategy is denoted by the vector x = 〈xi〉 where xi is the subsidy assigned to the user i, constrained by the budget B (i.e., ∑Ni=1 xi ≤ B). The subsidies can only be used to invest in cybersecurity. The users' pure strategies are denoted by a = 〈ai〉 where ai = 1 if user i invests, otherwise ai = 0. The users' mixed strategies are denoted by y where yi ∈ [0, 1] is the probability that user i will invest in cybersecurity. The attacker's pure strategy is denoted by the vector b = 〈bi〉 where bi = 1 implies the attacker attacks user i, otherwise bi = 0. Note that ∑Ni=1 bi ≤ K where K is the number of users the attacker can attack. We use BK to denote the set of pure strategies of the attacker. The mixed strategy of the attacker is denoted by z which is a distribution over all pure strategies in BK .
2 https://www.ncsc.gov.uk/
attacker
Figure 1: An illustrative example of SCIG where the square node is the government who assigns the subsidy to users (circle nodes) first, and users and the attacker (filled circle node) make their decisions simultaneously. Solid arrows between users indicate indirect risks.
Utilities. Given a strategy profile 〈x, a, b〉 where the followers take pure strategies, the users' utilities are defined as
The first term of Eq.(1) is the investment cost of user i with the subsidy xi assigned by the government where the user will obtain the subsidy if he invests, i.e., ai = 1. The second term is the expected loss to i due to the direct attack, i.e., bipili if ai = 0 and 0 if ai = 1. The third term is the expected loss due to the indirect attack transferred from others, i.e., (1 - bipi) [1- ∏j̸=i (1 - biqji)(1-aj) ] li if ai = 0 and [1- ∏j̸=i (1 - biqji)(1-aj) ] li if ai = 1 where 1 - ∏j̸=i (1 - biqji)(1-aj) is the probability that there is at least one of user i's neighbors will transfer the contamination to him. The utilities (omitting the xi's) and terms are defined the same way as in [Kearns and Ortiz, 2004; Chan et al., 2017]. The government's utility is defined to be the negative of the summation of the expected loss of users
We use the user's utilities to define the government's utility for simplicity and note that the government's utility is independent of the terms ai(xi-ci), which are canceled out when substituting Eq.(1) into Eq.(2). The attacker's utility is defined as U a (x, a, b) = -U d (x, a, b). Analogously, given a strategy profile 〈x, y, z〉 where the followers take mixed strategies, the users' utility is
The first term yi[(xi - ci) - Ψ1i li] is the user's utility when he chooses to invest and Ψ1i = ∑b∈BK z(b) [1- ∏j̸=i (1 - (1 - yj)bjqji)] is the indirect risk of the user where 1 - ∏j̸=i (1 - (1 - yj)bjqji) is the probability that the user will be compromised when other users take y and the attacker takes b, i.e., the probability that there is at least one of the neighbors of user i will transfer the contamination to him. The second term -(1 - yi)[Ψ2i pi +Ψ1i ]li is the user's utility when he chooses not to invest where Ψ1l is the same as introduced before and Ψ2i = ∑b∈BK z(b)bi [∏j̸=i (1 - (1 - yj)bjqji)] denotes the probability that user i is attacked and there is no neighbor of user i will transfer the contamination to him because for b ∈ BK , if bi = 1, which means that user i is attacked and we add ∏j̸=i (1 - (1 - yj)bjqji) into Ψ2i , which is the probability that no user transfers the contamination to user i. We can check all the three cases of the user i will suffer when he does not invest to verify the correctness that Ψ2i pi +Ψ1i , which are i) user i is successfully attacked, ∑b∈BK z(b)bipi, no matter whether the neighbors transfer the contamination to user i or not because the user can only be compromised once, ii) user i is attacked but not compromised and there is at least one of user i's neighbors transfers the contamination to him, ∑b∈BK z(b)bi(1 - pi) [1 - ∏j̸=i (1 - (1 - yj)bjqji)] and iii) user i is not attacked and there is at least one of user i's neighbors transfers the contamination to him, ∑b∈BK z(b)(1 - bi) [1- ∏j̸=i (1 - (1 - yj)bjqji)]. Readers can obtain the term Ψ2i pi +Ψ1i by summing all three cases. The government's utility for mixed strategies U d (x, y, z) is defined analogously, also the attacker's utility U a (x, y, z).
Equilibrium. Our objective is to find the optimal strategy for the government to assign the subsidy to the users, as well as the users' and the attacker's strategies. In particular, we are interested in the Stackelberg equilibrium between the government and followers (the users and the attacker), and Nash equilibrium between followers. We denote this notion as Stackelberg-Pure-Nash Equilibrium (SPNE) when the followers take pure strategies and Stackelberg-Mixed-Nash Equilibrium (SMNE) when the followers take mixed strategies, respectively. We assume that users break ties in favor of the government, i.e., if there are multiple equilibria, followers would select the one maximizing the government's utility. This is the standard assumption in Stackelberg security game [Tambe, 2011]. As the attacker's utility is the negation of the government's utility, the attacker does not need to break ties.
5 Solution Approach
In this section, we consider computing SPNE and SMNE in three settings where the attacker has different capabilities. We first show that SPNE always exists in all-user attacks and does not exist in the other two settings. We show that computing an SPNE is NP-hard and propose a linear reverse convex formulation to compute an SPNE. In the single-user attack setting, we provide an exact polynomial algorithm to compute an SMNE. Then, we provide an effective heuristic algorithm to compute an SMNE in all-user and multiple-user attacks.
5.1 All-user Attack: K ≥ N
In this section, we consider the case where the attacker is able to attack all users. We note that the attacker will always attack all users due to the non-negative utilities an attack can obtain. We focus on the computation of SPNE in this section. SMNE will be discussed in the multiple-user attack case.
Given the strategy x, there is at least one PNE, which can be computed in time O(N 2 ), while computing all PNE of users is NP-complete [Kearns and Ortiz, 2004]. Therefore, there always exists at least a PNE for all-user attacks. However, Theorem 1 proves that computing an SPNE is NP-hard.
Theorem 1. Computing an SPNE is NP-hard.
Proof. We reduce from the knapsack problem which is known to be NP-hard. In a knapsack problem, we are given a set of items [N] and a budget W > 0. Each item i ∈ [N] has a value fi > 0 and weight wi > 0. The goal is to find S ⊆ [N] such that ∑i∈S wi ≤ W and ∑i∈S fi is maximum.
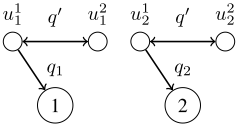
We reduce the knapsack problem to our problem. For each item i ∈ [N], we introduce a user i with 〈ci, pi, li〉 and two additional connected users, i.e., u1i and u2i and connects u1i to user i, as displayed in Figure 2. For pairs of users u1i and u2i , we set c1i = c2i = c′ and p1i = p2i = p′ , l1 i = l2 i = l′ and q12 i = q21 i = q′ . We set that p′ (1 - q′ )l′ < c′ < q′ l′ and c′ - p′ (1 - q′ )l′ > B, i.e., any of the additional users will not invest even with the government's subsidy. For each user i ∈ [N], the connection between u1i and i is denoted as qi and we set pi(1-qi)li < ci < pili, ci -pi(1-qi)li = wi and pi(1 - qi)li = fi, i.e., by assigning wi to user i, the user would invest and the government gains a positive utility pi(1 - qi)li. The government's budget B is set to be equal to W. Given a solution of the knapsack problem S ⊆ [N], the solution is also ensured to be optimal to our problem, and vice versa. Note that the government will never assign the subsidy to the additional users.
We can formulate the problem to compute an SPNE as Program 3, which is a bilevel optimization problem:
To make the problem computable, we reduce the bilevel formulation to single level optimization by rewriting each user i's utility as
Eq.(4) can be easily obtained from Eq.(1). The reduction from Eq.(4) to Eq.(5) is due to the fact that (1 - pi)(1-ai) = 1-(1-ai)pi when ai ∈ {0, 1} and Ωi = (1-pi) ∏j̸=i (1qji)(1-aj) -li, which is independent of ai and can be ignored when users maximize their own utilities. Therefore, we introduce Program 6 which is a single level optimization problem.
Eq.(6b) ensures that if xi-ci+pili ∏j̸=i (1-qji)(1-aj) < 0, the user will not invest, i.e., ai = 0, otherwise ai = 1, which is straightforward from Eq.(5). Theorem 2 proves that Program 6 can be reformulated as a linear reverse convex program with a linear objective and constraints as g(x) ≥ 0 where g(x) is a convex function [Horst and Tuy, 2013].
Theorem 2. Program 6 can be reformulated as a linear reverse convex program.
Proof. The utility function of user i can be reformulated as
For simplicity, we denote pi as qii. Thus, the government's utility, i.e., the objective of Program 6, is reformulated as
It can be easily verified by computing the Hessian matrix of U d (x, a, 1) that U d (x, a, 1) is convex and ∑i∈[N] li is constant. Then, Eq.(6b) can be equivalently rewritten as
Eqs.(8b)-(8c) ensure that if ai = 0, vi = xi and vi = 0 otherwise. Eq.(8d)-(8e) ensure that if ai = 0, zi = pili · wi and vi = 0 otherwise, where M is a big constant. To maximize the government utility, wi will always be equal to ∏j̸=i (1-qji)1-aj in Eq.(8f), which is a reverse convex constraint. Besides, as the variables ai are binary, we can also add a reverse convex constraint into the program for each ai
Furthermore, we introduce an auxiliary variable U as the linear objective with an additional reverse convex constraint
Thus, we obtain the linear reverse convex program.
The reformulation in Theorem 2 ensures that all terms in the objective and constraints are convex, which makes it easier to solve. In this work, we use global optimization solvers, e.g., BARON, to solve the problem.
5.2 Single-user Attack: K = 1
We consider the game where the attacker can only attack one user. The setting without the government is extensively investigated in [Chan et al., 2012; Chan et al., 2017], which provides some useful results for us to develop our algorithm. The following proposition proves that, except the case where all users invest, there is no other pure NE between followers.
Proposition 3. Given the strategy x, if 〈a, b〉 = 〈1, ∗〉 is not an NE, then there is no pure NE between followers.
Proof. As there is at most a user being attacked, we can write the attacker's utility as
If U a (x, a∗ , b∗ ) = 0, it is the trivial case which means that all users invest under the given strategy x, i.e., 〈a, b〉 = 〈1, ∗〉 is an NE where ∗ means the attacker's strategy can be any valid pure strategy because all pure strategies bring the same utility to the attacker, i.e., 0. We can easily check whether the strategy x can make 〈a, b〉 = 〈1, ∗〉 as an NE or not. For the case where U a (x, a∗ , b∗ ) > 0, suppose that b∗k = 1 for some k ∈ [N], which implies that a∗k = 0, i.e., user k does not invest. As a∗k = 0 is user k's best-response to the attacker, we have ck ≥ xk + pklk. As we have xk ≥ 0, we obtain ck ≥ pklk, which contradicts our assumption ci < pili.
The case that all users invest occurs when the budget is high, which is not the case in general. Therefore, we then focus on the mixed NE between followers. With a slight abuse of notation, we denote zi as the probability of attacking i. Therefore, we can rewrite the user's utility as
where Ψ1i and Ψ2i are defined previously. The reduction from Eq.(11) to Eq.(12) is based on the key observation that Ψ2i = zi, so we can ignore the last two terms of Eq.(12) which are independent of the user's strategy. Then, we define that ∆i = ci-xi pili and Li = pili + ∑j̸=i qijlj. We denote that V (x) = {i|∆i > 0, i ∈ [N]} for a given x because if ∆i ≤ 0, the user will definitely invest, so we can remove it from our game. Proposition 4 characterizes the set of mixed Nash equilibria between followers in the three cases where ∑i∈V (x) ∆i is less, equal and larger than 1, which plays a central role to compute the optimal strategy of the government.
Proposition 4. Given x, the strategy profile 〈y, z〉 is a mixed Nash equilibrium (MNE) in the game where
- ∑i∈V (x) ∆i < 1, if and only if ∀i ∈ V (x), yi = 1, zi ≥ ∆i and ∑i∈[N] zi = 1;
- ∑i∈V (x) ∆i = 1, if and only if ∀i ∈ V (x), yi = 1 - L/Li, 0 ≤ L ≤ mini∈V (x) Li, zi = ∆i;
- ∑i∈V (x) ∆i > 1, if and only if there is a non-singleton, nonempty subset I ⊂ V (x) such that mini∈I Li ≥ maxj∈V (x)\I Lj and the followings hold: i) ∀i ∈ V (x) \ I, yi = zi = 0; ii) let J = argmini∈I Li, ∀i ∈ J, yi = 0, 0 ≤ zi ≤ ∆i; iii) ∀i ∈ I \ J, yi = 1 -minj∈I Lj/Li, zi = ∆i.
Proof. We can rewrite the attacker's utility as
The key observation is Ψ1i = ∑j̸=i zj(1 - yj)qji. Then the proof can be adapted from the proof of Proposition 5 in [Chan et al., 2017] by setting the attack cost to zero. Generally speaking, the proof of the proposition is based on three facts: i) when zi = ∆i, the users will be indifferent to the investment which is observed from Eq.(12), ii) under any of the equilibria, the values (1-yi) (pili + ∑j̸=i qijlj ) are equal for all users with zi > 0 and iii) for users with zi = 0, i ∈ V (x), yi = 0.
Proposition 5. As the followers break ties in favor of the government, for the game where ∑i∈V (x) ∆i ≤ 1, the users will fully invest, i.e., y = 1, and the attacker will choose zi ≥ ∆i, ∀i ∈ V (x) and zi, i ∈ [N] \ V (x) are irrelevant.
Proof. According to Proposition 4, when ∑i∈V (x) ∆i < 1, the only NE strategy for users is y = 1 and the attacker's utility is 0 for all NE strategies of the attacker. For the case where ∑i∈V (x) ∆i = 1, the only NE strategy for the attacker is zi, i ∈ [N] \ V (x). As we suppose the users will break ties in favor of the government, i.e., minimize the attacker's utility. Therefore, the users will choose y = 1 as their NE strategy, which leads to the case where the attacker's utility is 0. Thus, for the game where ∑i∈V (x) ∆i ≤ 1, the users will fully invest, i.e., y = 1, and the attacker will choose zi ≥ ∆i, ∀i ∈ V (x) and zi, i ∈ [N]\V (x) are irrelevant.
Given Proposition 5, we find that if ∑i∈V (x) ∆i ≤ 1, the users will always invest. And for the case where ∑i∈V (x) ∆i > 1, Proposition 6 proves that all MNE can be computed in polynomial time in this case.
Proposition 6. For the game where ∑i∈V (x) ∆i > 1, given x, all MNE can be computed in polynomial time.
Proof. The algorithm can be adapted from Theorem 1 in [Chan et al., 2017] by setting the attack cost to zero. Roughly speaking, the algorithm sorts users in descending order according to Li and then finds t such that 1 - ∆idx1(t) ≤ ∑t-1 j=1 ∆idx1(j) < 1, where idx1(·) and val1(·) are the index and the value in the sorted list. We denote I = {idx1(k)|k ≤ t} and specify followers' strategies by Proposition 4.
Given Proposition 6, we now prove that the government's optimal strategy can be computed in polynomial time. Denote ∆ = ∑Ni=1 ∆i. We first check whether the government can make ∆ ≤ 1 by greedily assigning ci to users in the ascent order of pili. For the case where the government cannot make ∆ ≤ 1, we can see from Proposition 6 that the government's utility is equal to val1(t) in the sorted list such that 1 - ∆idx1(t) ≤ ∑t-1 j=1 ∆idx1(j) < 1. Therefore, maximizing the government's utility is equivalent to minimizing val1(t), which is depicted in Algorithm 1.
Proposition 7. Algorithm 1 computes an SMNE in polynomial time when the attacker has a single-attack capability.
Algorithm 1: Compute government's optimal strategy
- 1 x = 0, t = 0, t′ = N; 2 Sort Li in descending order and let val1(i) and idx1(i) be the ith value and index in the sorted list, respectively; 3 Sort pili in descending order and let val2(i) and idx2(i) be the ith value and index in the sorted list, respectively; 4 Find t′ such that 1-∆idx1(t′ ) ≤ ∑t-1 j=1 ∆idx1(j) < 1; 5 while t′ > t do 6 b = B, x = 0, t = t′ ; 7 while true do 8 j ∈ argminidx1(i)≤t,i∈V (x) val2(i); 9 if j == null then break; 10 else if b ≥ cj then xj = cj;b = b - cj; 11 else cj = b; break; 12 Find t′ where 1-∆idx1(t′ ) ≤ ∑t′-1 j=1 ∆idx1(j) < 1; 13 return x
Proof. We first prove that the loop in lines 7-11 can return the optimal solution if we only consider the users with idx1(i) ≤ t. As the attacker will attack the users with probability ∆i, when the government assigns the subsidy with the minimal pili, which is denoted by j, i.e., j ∈ argminidx1(i)≤t {pili}. Then, user j will definitely invest and the attacker will assign the amount ∆j to users with idx1(i) > t. Thus, the greedy assignment of the subsidy is optimal due to the fact that assigning the subsidy to user j will reduce the largest amount of the probability that the attacker allocates to users with idx1(i) ≤ t. Then, we prove that when t′ = t, the assignment is globally optimal. Observing that t′ ≥ t at line 12, if t′ = t, there is no user with idx1(i) > t being attacked by the attacker, given the optimal result of the loop in lines 7-11, the returned solution is globally optimal and we terminate the algorithm. The two sorting processes take O(N logN). The two while loops in line 5 and 7 run at most N times. The finding minimum operation in line 8 needs at most N comparisons. Thus, the runtime is O(N 3 +N logN) = O(N 3 ).
5.3 Multiple-user Attack: 1 <K < N
For multiple-user attacks, an argument similar to Proposition 3 can prove that there is no PNE between followers, so we focus on the mixed NE case. As claimed in [Chan et al., 2017], the computation of MNE in general case is intractable. Therefore, we adopt best-responsegradient dynamics (BRGD) [Fudenberg and Levine, 1998] to compute an ϵ-MNE and greedily assign the subsidy to users. The algorithm is presented in Algorithm 2. BRGD initializes the users' strategies with 0.5 and the attacker's strategy uniformly with ∑b∈BK zb = 1. At each round, BRGD updates yi = yi + α(U u i (x, y-i, 1, z) - U u i (x, y-i, 0, z)) and zb = zb + α(U a (x, y, b) - U a (x, y, z)) where y-i is the strategies of other users except i, α is the step size of BRGD and U u i (x, y-i, σ, z), σ ∈ {0, 1} is user i's utility when i takes the pure strategy σ, given that the other users take y-i and the attacker takes z. We define that for each user, ri = | U u i -U u i (x,y,z) U u i (x,y,z) | where U u i = max{U u i (x, y-i, 1, z),U u i (x, y-i, 0, z)} and ra = | U a-U a (x,y,z) Ua | where U a = maxb∈BK{U a (x, y, b)} for the attacker. BRGD will terminate when r < ϵ where r = max{r1, ..., rN, ra} and the solution is ensured to be an ϵMNE. To obtain ϵ-MNE using BRGD, for each iteration (Lines 3-11), we assign the δ = B/D to the user who can increase the government's utility the most, where D is the maximum number of iterations. We note that this algorithm can also be applied to approximate SMNE of all-user attacks.
Algorithm 2: Allocation for multiple attacks
1 x = 0, δ = B/D; 2 〈y, z〉 ← BRGD(x, ϵ); 3 for d = 1 : D do 4 icr = 0; 5 for i = 1 : N do 6 x′ = x, x′i = xi + δ; 7 〈y′ , z′ 〉 ← BRGD(x′ ); 8 icri = U d (x′ , y′ , z′ ) - U d (x, y, z); 9 j = argmaxi∈[N],icri>0 icri; 10 if j = null then break; 11 else xj = xj + δ; 12 return x6 Experimental Results
We evaluate our algorithms through extensive experiments. All computations are performed on a 64-bit PC with 4.0 GB RAM and a 2.40 GHz CPU unless otherwise specified. All games are randomly generated with ci = 107 + [0, 108 ], li = 108 + [0, 109 ] and pi, qji ∈ [0, 1] (Similar to [Chan et al., 2012]). As there is an exact polynomial algorithm for singleuser attacks, we focus on the other two cases in this section.
6.1 Results of All-user Attack for SPNE
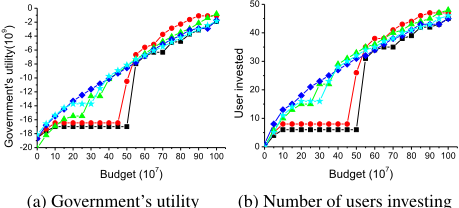
We use global nonlinear online solver BARON, provided by NEOS server [Czyzyk et al., 1998], to find a global or local optimal solution of the problem. Figure 3 displays five generated instances of 50 users with different government budget. BARON can compute the government's optimal strategy in 5 minutes on average. Figure 3a and 3b show the government's utility and the number of users who invest against budget, respectively. There are two observations from the results: i)
smooth transition where the number of users who invest and the government's utility increase smoothly (see blue, green and cyan lines) and ii) phase transition where increasing the budget leads to a significant increment in the number of invested users and government's utility (16 in red line and 25 in black line). The conclusion is supported by more instances.
6.2 Results of Multiple-user Attack for SMNE
We now present experimental results for multiple-user attacks. The convergence criteria is ϵ = 0.05, the step size is α = 0.05/(K · maxi∈[N] li), the government's budget is B = 5 · 108 and the number of iterations D is 10. To generate the synthetic data, we vary K ∈ {4, 6} and N ∈ {12, 14, 16, 18, 20}. Each case is averaged over 30 instances.
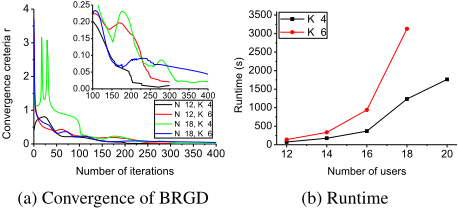
Convergence and runtime. We first investigate the convergence of BRGD. Figure 4a shows the convergence results and, to make the figure readable, only four among all cases are depicted. All cases reach the termination in less than 350 iterations. We note that the number of iterations before the termination does not significantly depend on N or K. Furthermore, we display the runtime results of the algorithm with a cap of 3600 seconds in Figure 4b, where when K is large, the algorithm takes more time to terminate. Note that when N = 20 and K = 6, the runtime is beyond the cap.
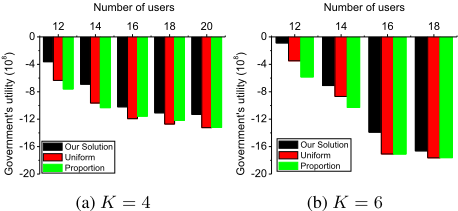
Solution quality. We compare our solution with two other baselines: uniform where the government divides the subsidy to users uniformly and proportion where the government assigns the subsidy proportionally to the user's loss li. Figure 5 shows the solution quality with different values of K where our solution is better than the two baselines. The advantage of our solution is reduced when K is smaller, i.e., users are more reluctant to invest in safer environments.
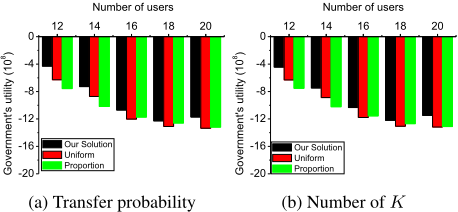
Robustness. We consider two kinds of uncertainties: i) transfer probability where ˜ qji = (1+δ)qji, δ ∈ [-10%, 10%] where ˜ qji is the real transfer probability and qji is the transfer probability that the government uses to compute his strategy; and ii) the number of K where the real number of users the attacker can attack ˜K is either K+1 or K-1 with a probability of 10%, respectively, where K is the number used by the government to decide his strategy. Figure 6 shows that our solution outperforms the two baselines against the uncertainties for K = 4. Results for K = 6 are similar and omitted.
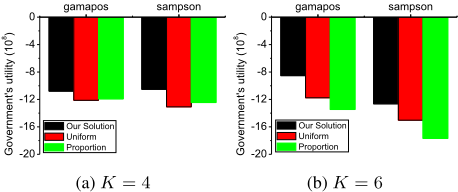
Experiments on real networks. As business networks are often generated socially, we consider two real social networks. The networks are gamapos, a highland tribe network with 16 nodes and 58 edges, and sampson, a monastery monk network with 18 nodes and 55 edges 3 . Figure 7 shows that our solution outperforms the baselines. The results also demonstrate that our heuristic algorithm are better than baselines.
7 Conclusion
We propose a novel Stackelberg cybersecurity investment game between the government, interdependent users and an attacker. We investigate three cases where the attacker can attack all, single and multiple users and propose a reverse convex formulation, an exact polynomial algorithm and a heuristic algorithm for the three cases, respectively. Experimentally, we show that our heuristic algorithm is effective and outperforms baselines on synthetic and real data.
Acknowledgements
This research is supported by NCR2016NCR-NCR001-0002, MOE, and NTU.
3 Both networks are from http://konect.uni-koblenz.de/networks/
@inproceedings{ijcai2019p834,
  title     = {Who Should Pay the Cost: A Game-theoretic Model for Government Subsidized Investments to Improve National Cybersecurity},
  author    = {Wang, Xinrun and An, Bo and Chan, Hau},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {6020--6027},
  year      = {2019},
  month     = {8},
  note      = {AI for Improving Human Well-being},
  doi       = {10.24963/ijcai.2019/834},
  url       = {https://doi.org/10.24963/ijcai.2019/834},
}
TY - CPAPER TI - Who Should Pay the Cost: A Game-theoretic Model for Government Subsidized Investments to Improve National Cybersecurity AU - Wang, Xinrun AU - An, Bo AU - Chan, Hau T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 6020 EP - 6027 DO - 10.24963/ijcai.2019/834 UR - https://doi.org/10.24963/ijcai.2019/834 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





