
Exploring the Benefits of Teams in Multiagent Learning
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 454-460.
https://doi.org/10.24963/ijcai.2022/65
Keywords
- Agent-based and Multi-agent Systems: Agent-Based Simulation and Emergence
- Agent-based and Multi-agent Systems: Coordination and Cooperation
- Agent-based and Multi-agent Systems: Multi-agent Learning
Abstract
For problems requiring cooperation, many multiagent systems implement solutions among either individual agents or across an entire population towards a common goal. Multiagent teams are primarily studied when in conflict; however, organizational psychology (OP) highlights the benefits of teams among human populations for learning how to coordinate and cooperate. In this paper, we propose a new model of multiagent teams for reinforcement learning (RL) agents inspired by OP and early work on teams in artificial intelligence. We validate our model using complex social dilemmas that are popular in recent multiagent RL and find that agents divided into teams develop cooperative pro-social policies despite incentives to not cooperate. Furthermore, agents are better able to coordinate and learn emergent roles within their teams and achieve higher rewards compared to when the interests of all agents are aligned.
- [Anastassacos et al., 2020] N. Anastassacos, S. Hailes, and M. Musolesi. Partner selection for the emergence of coop- eration in multi-agent systems using reinforcement learn- ing. In AAAI, 2020.
- [Anastassacos et al., 2021] N. Anastassacos, J. Garcia, S. Hailes, and M. Musolesi. Cooperation and reputation dynamics with reinforcement learning. In AAMAS, 2021.
- [Andrejczuk et al., 2016] E. Andrejczuk, J. A. Rodriguez- Aguilar, and C. Sierra. A concise review on multiagent teams: contributions and research opportunities. Multi- Agent Systems and Agreement Technologies, 2016.
- [Baker et al., 2019] B. Baker, I. Kanitscheider, T. Markov, Y. Wu, G. Powell, B. McGrew, and I. Mordatch. Emergent tool use from multi-agent autocurricula. In ICLR, 2019.
- [Baker, 2020] B. Baker. Emergent reciprocity and team formation from randomized uncertain social preferences. NeurIPS, 2020.
- [Dafoe et al., 2021] A. Dafoe, Y. Bachrach, G. Hadfield, E. Horvitz, K. Larson, and T. Graepel. Cooperative AI: machines must learn to find common ground. Nature, 2021.
- [Deka and Sycara, 2021] A. Deka and K. Sycara. Natural emergence of heterogeneous strategies in artificially intel- ligent competitive teams. In Int. Conf. on Swarm Intelli- gence, 2021.
- [Grosz and Kraus, 1996] B. Grosz and S. Kraus. Collabora- tive plans for complex group action. Artif. Intell., 1996.
- [Grosz and Sidner, 1988] B. J. Grosz and C. L. Sidner. Plans for discourse. Technical report, BBN Labs, 1988.
- [Hughes et al., 2018] E. Hughes, J. Z. Leibo, M. Phillips, K. Tuyls, E. A. Duéñez-Guzmán, A. Castañeda, I. Dun- ning, T. Zhu, K. R. McKee, R. Koster, H. Roff, and T. Graepel. Inequity aversion improves cooperation in in- tertemporal social dilemmas. In NeurIPS, 2018.
- [Jaderberg et al., 2019] M. Jaderberg, W. Czarnecki, I. Dun- ning, L. Marris, G. Lever, A. Castañeda, C. Beattie, N. C. Rabinowitz, A. S. Morcos, A. Ruderman, N. Sonnerat, T. Green, L. Deason, J. Z. Leibo, D. Silver, D. Hassabis, K. Kavukcuoglu, and T. Graepel. Human-level perfor- mance in 3d multiplayer games with population-based re- inforcement learning. Science, 364:859 -865, 2019.
- [Jaques et al., 2019] N. Jaques, A. Lazaridou, E. Hughes, C ¸. Gülc ¸ehre, P. A. Ortega, D. Strouse, J. Z. Leibo, and N. D. Freitas. Social influence as intrinsic motivation for multi- agent deep reinforcement learning. In ICML, 2019.
- [Kitano et al., 1997] H. Kitano, M. Asada, Y. Kuniyoshi, I. Noda, and E. Osawa. Robocup: The robot world cup initiative. In AGENTS '97, 1997.
- [Kraemer and Banerjee, 2016] L. Kraemer and B. Banerjee. Multi-agent reinforcement learning as a rehearsal for de- centralized planning. Neurocomputing, 190:82-94, 2016.
- [Leibo et al., 2017] J. Leibo, V. Zambaldi, M. Lanctot, J. Marecki, and T. Graepel. Multiagent reinforcement learning in sequential social dilemmas. AAMAS, 2017.
- [Macke et al., 2021] W. Macke, R. Mirsky, and P. Stone. Ex- pected value of communication for planning in ad hoc teamwork. In AAAI-21, 2021.
- [McKee et al., 2020] K.R. McKee, I. Gemp, B. McWilliams, E.A. Duéñez-Guzmán, E. Hughes, and J. Z. Leibo. So- cial diversity and social preferences in mixed-motive rein- forcement learning. AAMAS, 2020.
- [Mnih et al., 2015] V. Mnih, K. Kavukcuoglu, D. Silver, A. A. Rusu, J. Veness, M. G. Bellemare, A. Graves, M. A. Riedmiller, A. Fidjeland, G. Ostrovski, S. Petersen, C. Beattie, A. Sadik, I. Antonoglou, H. King, D. Ku- maran, D. Wierstra, S. Legg, and D. Hassabis. Human- level control through deep reinforcement learning. Nature, 518:529-533, 2015.
- [Muthukrishna, 2017] M. Muthukrishna. Corruption, coop- eration, and the evolution of prosocial institutions. Evo- nomics, 2017.
- [Nisioti and Moulin-Frier, 2020] E. Nisioti and C. Moulin- Frier. Grounding artificial intelligence in the origins of human behavior. ArXiv, abs/2012.08564, 2020.
- [Pollack, 1990] M. E. Pollack. Plans as complex mental atti- tudes. In Intentions in Communication, 1990.
- [Radke et al., 2022] D. Radke, K. Larson, and T. Brecht. The importance of credo in multiagent learning. Adaptive and Learning Agents Workshop at AAMAS, 2022.
- [Rapoport, 1974] A. Rapoport. Prisoner's dilemma -recol- lections and observations. In Game Theory as a Theory of a Conflict Resolution, pages 17-34. Springer, 1974.
- [Ryu et al., 2021] H. Ryu, H. Shin, and J. Park. Coopera- tive and competitive biases for multi-agent reinforcement learning. In AAMAS, 2021.
- [Schnell et al., 2021] E. Schnell, R. Schimmelpfennig, and M. Muthukrishna. The size of the stag determines the level of cooperation. bioRxiv, 2021.
- [Schulman et al., 2017] J. Schulman, F. Wolski, P. Dhariwal, A. Radford, and O. Klimov. Proximal policy optimization algorithms. CoRR, abs/1707.06347, 2017.
- [Tambe, 1997] M. Tambe. Towards flexible teamwork. J. Artif. Intell. Res., 7:83-124, 1997.
- [Vinitsky et al., 2019] E. Vinitsky, N. Jaques, J. Leibo, A. Castenada, and E. Hughes. An open source implementation of sequential social dilemma games. https://github.com/eugenevinitsky/ sequential social dilemma games/issues/182, 2019. Link
- [Wang et al., 2019] J. X. Wang, E. Hughes, C. Fernando, W. M. Czarnecki, E. A. Duéñez-Guzmán, and J. Z. Leibo. Evolving intrinsic motivations for altruistic behavior. In AAMAS-19, pages 683-692, 2019.
- [Zaccaro et al., 2020] S. J. Zaccaro, S. Dubrow, E. M. Tor- res, and L. Campbell. Multiteam systems: An integrated review and comparison of different forms. Annual Review of Organizational Psychology and Organizational Behav- ior, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Observed in both animal and human behavior, the ability to work in teams can magnify a group's abilities beyond the capability of individuals. Organizational psychology (OP) and biology have done extensive research on how "teamsof-teams" with a shared overall goal increase the collective efforts of all component teams and individuals [Zaccaro et al., 2020]. Recently, there is increasing interest in making the study of cooperation central to the development of artificial intelligence (AI) and multiagent systems (MAS) [Dafoe et al., 2021]. We propose that adapting a similar team structure as in OP to a population of AI agents serves as a middle ground between centralized and decentralized systems of coordination and cooperation that can benefit agents' learning processes.
In the context of teams, multiagent reinforcement learning (MARL) has achieved impressive results in competitive twoteam zero-sum settings such as capture the flag [Jaderberg et al., 2019], hide-and-seek [Baker et al., 2019], and Robot Soccer (RoboCup) [Kitano et al., 1997]. However, when agents are deployed into the real world, they will be faced with problems that are not zero-sum [Baker, 2020]. Therefore, it is essential to explore cooperation in mixed-motive domains, such as Sequential Social Dilemmas (SSDs) [Leibo et al., 2017]. With the growing interest in exploring mixed-motive domains and investigating the impact of group size and structure on system stability [Nisioti and Moulin-Frier, 2020], we aim to model teams and understand their benefits on MARL agents' ability to learn.
∗Contact Author
Inspired by group structures in OP and early models of teams from the AI literature for task completion, we propose a general model of multiagent teams and validate it in the context of social dilemmas. It is well documented that individual RL agents fail to learn cooperation in social dilemmas while agents with common interest have more success [Anastassacos et al., 2020; Baker et al., 2019]. Our teams model is situated between these two extremes, where teammates are bound by common interest but mixed-motives exist between non-teammates. We show, across several games, that teams improve how agents learn and develop pro-social policies. This work makes the following contributions:
- We define a model of teams inspired by early work in multiagent systems and organizational psychology.
- We discuss the theoretical ramifications of our model in the context of social dilemmas regarding game theoretical incentives under different environmental conditions.
- Through an extensive empirical evaluation, we show how our model of teams helps agents develop globally beneficial pro-social behavior despite short-term incentives to defect. As a result, agents in these teams achieve higher rewards in complex domains than when the interests of all agents are aligned, and autonomously learn more efficient combinations of roles when compared with common interest scenarios.
2 RelatedWork
There is a long history of exploring how agents can coordinate their behavior via teamwork, typically for task completion domains. Early work by Pollack formally defines an agent's mental model for making collaborative plans between two agents [Pollack, 1990]. Extending Pollack's work, [Grosz and Sidner, 1988] construct SharedPlans, a model that includes more actions and agent beliefs, similar to shared mental models in human teamwork and modeled joint actions as non-additive [Grosz and Kraus, 1996]. Tambe uses a task allocation structure similar to SharedPlans in developing STEAM, a general model of teams where tasks can be completed by sub-teams of agents within a larger system [Tambe, 1997]. The idea of sub-teams within a population was novel to AI; however, SharedPlans and STEAM remained unable to broadly generalize due to limited agent capabilities.
Recent work with teams in MAS has focused on ad hoc teamwork [Macke et al., 2021], teams in competition [Ryu et al., 2021], or coordination problems [Jaques et al., 2019]. When not in competition, teams in AI are typically designed to achieve a common objective and has been criticized for its disregard for adapting significant findings in OP [Andrejczuk et al., 2016]. We evaluate our model of teams in other settings where teams are not directly competitive, complex mixedmotive social dilemmas, to explore how structures inspired by OP can be adapted to MAS.
Studying social dilemmas and how agents or people can overcome them has been a topic of research in game theory, economics, psychology, and more recently, AI. Fostering cooperation in social dilemmas with MARL agents often relies on reward sharing among the population [McKee et al., 2020] or only a subset of agents with uncertainty [Baker, 2020]. We broadly classify the literature into centralized and decentralized approaches of fostering cooperation.
Centralized systems have taken various forms in the literature, ranging from centralized training for better coordination at test time [Kraemer and Banerjee, 2016] to explicitly providing access to another agent's internal state [Deka and Sycara, 2021]. While centralized systems are efficient and convergence is reliable, it is often unsafe to assume access to all agents and they are brittle to exogenous changes.
Inspired by the hypothesized emergence of cooperation in humans and evolutionary game theory, decentralized systems that promote cooperation are primarily implemented at the individual agent level. Giving agents the ability to punish and sanction others in response to a specific behavior has been shown to foster cooperation in MARL [Anastassacos et al., 2021; Leibo et al., 2017].
In this work, we adapt findings from OP to AI by constructing a general model of multiagent teams inspired by human teams, SharedPlans, and STEAM to analyze the benefits of teams on how MARL agents learn. We divide a population of MARL agents into teams not in direct competition and show how teams, as they have been found to do with humans, improve how RL agents co-evolve and learn in challenging domains. We position our work between centralized and decentralized systems. While our teams model does not assume any form of centralized control, the team structure itself provides a way for agents to better coordinate.
3 AModel for Multiagent Teams
We model our base environment as a stochastic game G = ⟨N, S, {A}i∈N, {R}i∈N, P, γ, Σ⟩. N is our set of all agents that learn online from experience and S is the state space, observable by all agents, where si is a single state observed by agent i. A = A1 × . . . ×AN is the joint action space for all agents where Ai is the action space of agent i. R = R1 × . . . ×RN is the joint reward space for all agents where Ri is the reward function of agent i defined as Ri : S×A×S ↦→ R, a real-numbered reward for taking an action in an initial state and resulting in the next state. P : S×A ↦→∆(S) represents the transition function which maps a state and joint action into a next state with some probability and γ represents the discount factor so that 0 ≤ γ < 1. Σ represents the policy space of all agents, and the policy of agent i is represented as πi : S ↦→ Ai which specifies an action that the agent should take in an observed state. 1
Our teams model consists of a stochastic game with teams ⟨G, T ⟩, where T is a partition of the population of agents into disjoint teams, T = {Ti|Ti ⊆ N, ∪T = N, Ti∩Tj = ∅∀i, j}. A team structure defines the composition of T , such as the number of teams and agents on each team. Consistent with the original groundwork on multiagent teams [Tambe, 1997; Grosz and Sidner, 1988], we define a team of agents as being bounded together through common interest. Consistent with recent MARL work, we model common interest through reward sharing making the assumption agents value rewards equivalently [McKee et al., 2020; Hughes et al., 2018]. We define a new reward function for agents on a team as TRi : S ×A× S ↦→ R so that the reward for i ∈ Ti is dependant on their own behavior and that of their teammates. Any function can be implemented to define TRi. In our analysis and experiments, we use:
where teammates share their rewards equally to be consistent with past work [Wang et al., 2019; Baker et al., 2019].
Agents learn from their individual experience using RL. As is standard in many MARL problems, agents are trained to independently maximize their own rewards. In particular, at time t each agent i selects some action ai which together form a joint action at . This action results in a transition from state st to state st+1 , according to the transition function P, and provides each agent i with reward Ri,t(st , at , st+1 ). Agents seek to maximize their sum of discounted future rewards, Vi = ∑∞t=0 γ tRi,t. Our model replaces Ri with TRi, reconfiguring the learning problem so that agents must simultaneously learn what individual behavior maximizes their team's expected discounted future reward.
4 Social Dilemmas
Social dilemmas are situations which present tension between short-term individual incentives and the long-term collective interest where agents must cooperate for higher rewards. All agents prefer the benefits of a cooperative equilibria; however, the short-term benefits of self-interested behavior outweigh those of cooperative behavior. For our analysis, we consider intertemporal social dilemmas with active provision defined as when cooperation carries an explicit cost [Hughes et al., 2018]. We implement our model of teams in the Iterated Prisoner's Dilemma (IPD) [Rapoport, 1974] and the Cleanup domain game [Vinitsky et al., 2019].
1 We can also allow for randomized policies.
4.1 Environment 1: Iterated Prisoner's Dilemma
In the one-shot Prisoner's Dilemma, two agents interact and each must decide to either cooperate (C) with or defect (D) on each other. We assume there is a cost (c) and a benefit (b) to cooperating where b > c > 0. If an agent cooperates, it incurs the cost c. If both agents cooperate, they both also benefit, each receiving a reward of b-c. If one agent cooperates but the other defects, then we assume that the cooperating agent incurs the cost c, but the defecting agent reaps the benefit b (e.g., by stealing the contribution of the cooperator). If neither cooperate, neither benefit nor incur a cost, leading to a reward of zero for both. The unique Nash Equilibrium is obtained when both agents defect, represented by (D, D). Joint cooperation does not form an equilibrium, since if one agent cooperates, the other agent is strictly better off defecting and receiving b, instead of b - c.
In the IPD, this game is repeatedly played which adds a temporal component and allows agents to learn a policy over time. Instead of just two agents, we work with a population of agents that are divided into teams a priori. At each timestep, agents are randomly paired with another agent, a counterpart, that may or may not be a teammate. Agents are informed as to what team their counterpart belongs to through a numerical signal si, though additional identity information is not shared. Agents must decide to cooperate with or defect on their counterpart. Their payoff for the interaction is the team reward, TRi, based on their own and other teammates' interactions. Agents update their strategies (i.e., learn) using their direct observation si, what action they chose ai, and their team reward TRi. Since only the team information of the counterpart is shared, the strategies of all agents on team Ti ultimately affects how agents learn to play any member of Ti.
Equilibrium Analysis
We are interested in understanding how the introduction of teams may help or hinder cooperation. As a first step towards addressing this question, we investigate the impact of teams on the stage game of the IPD. To provide a clear comparison with the standard IPD, we take an ex-ante approach, where agents are aware of their imminent interaction and the existence of other teams but not the actual team membership of their counterpart. For further details, refer to Appendix A 2 .
Assume a pair of agents, i, j, have been selected to interact at some iteration of the IPD and agent i knows j will be a teammate with probability ν and a non-teammate with probability (1-ν). Let σTi = (σji, 1-σji) represent j's strategy profile when j ∈ Ti, where σji is the probability for cooperation (C). Likewise, let σTj = (σjj, 1 - σjj) be j's strategy profile when j ∈ Tj , any other team.
If agent i decides to cooperate, its expected utility, subject to agent j's strategy, is:
If agent i decides to defect, its expected utility, subject to agent j's strategy, is:
2 https://cs.uwaterloo.ca/∼dtradke/pdfs/IJCAI22 Appendix.pdf
We determine the conditions under which agent i has incentive to cooperate as when E(C, σT ) ≥ E(D, σT ). Substituting Equations 2 and 3, this simplifies to:
regardless of σTi or σTj . Since b > c > 0, this constraint is meaningful. Satisfying Equation 4 shifts the Nash Equilibrium of the stage game from (D, D) to (C, C) in expectation. This means that there exist circumstances where teams can support cooperative incentives, but these circumstances are not universal. Our experiments explore this in more detail.
4.2 Environment 2: CleanupMarkov Game
Cleanup [Vinitsky et al., 2019] is a temporally and spatially extended Markov game representing a social dilemma. This domain allows us to examine if the benefits of teams generalize to more complex environments since agents must learn a cooperative policy through movement and decision actions instead of choosing an explicit cooperation action like in the IPD. Active provision is represented in Cleanup by agents choosing actions with no associated environmental reward that are necessary agents to achieve any rewards.
Figure 6 in Appendix B.2 shows the Cleanup environment and provides more details about the environment parameters. At each timestep, agents choose among nine actions: 5 movement (up, down, left, right, or stay), 2 turning (left or right), and a cleaning or punishing beam. One half of the map contains an aquifer, or river, and the other an apple orchard. Waste accumulates in the river with some probability at each timestep which must be cleaned by the agents. Once a cleanliness threshold is reached, apples spawn in the orchard proportional to the overall cleanliness of the river. Agents receive a reward of +1 for consuming an apple by moving on top of them. The dilemma exists in agents needing to spend time cleaning the river to spawn new apples and receive no exogenous reward versus just staying in the orchard and enjoying the fruits of another's labor. Agents have the incentive to stay in the orchard, however if all agents attempt this freeriding policy, no apples grow and no-one gets any reward. A successful group in Cleanup will balance the temptation to free-ride with the public obligation to clean the river.
5 Empirical Evaluation
In this section, we present the setup and results of experiments in both environments using MARL agents. While our teams model does not require it, we assume that for all Ti, Tj ∈ T , |Ti| = |Tj| (i.e., given a team model, the teams are the same size). This avoids complications that might arise with agent interactions if teams were significantly different sizes and to be consistent across our domains. Alternative interaction mechanisms and teams of different sizes are left for future work. We use the notation |T |/|Ti| to indicate the total number of teams and the size of each team. For example, 1/N
indicates one team of N agents (fully common-interest) and N/1 represents N teams of one agent (fully mixed-motive). Of course, many scenarios may fall between these two extremes. Since fully mixed-motive has agents working as individuals (i.e., no teams), it serves as a benchmark against which we can compare the performance of team structures.
5.1 IPD Evaluation
In the IPD, each experiment lasts 1.0 × 10⁶ episodes where N = 30 agents learn using Deep Q-Learning [Mnih et al., 2015]. An episode is defined by a set of agent interactions where each agent is paired with another agent and plays an instance of the Prisoner's Dilemma. Agent pairings are assigned using a uniform random distribution over each team so agents are unable to explicitly modify who they interact with, shown as a challenging scenario for cooperation to arise without additional infrastructure [Anastassacos et al., 2020]. Each experiment is repeated five times. In Appendix B.1, we prove how this configuration ensures that each agent has the same number of expected interactions to learn from. Further implementation details are provided in Appendix B.1 3 .
Reward
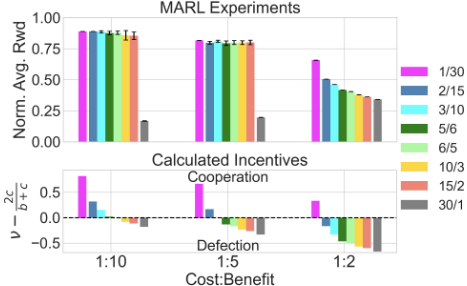
In our first set of experiments, we explore the degree to which team structures support cooperation. We fix the cost (c) at 1, and let the benefit (b) be 2, 5, or 10. To capture the behavior of agents after they have converged to a policy, the top graph of Figure 1 shows the normalized average global reward of the last 25% of the episodes using MARL agents. We normalize the average global reward of each experiment in the interval [0-c, 0+b] and calculate 95% confidence intervals to compare different cost and benefit ratios. To show the corresponding incentives of each experiment, we include the bottom graph which displays the calculated action incentive by a modified Equation 4, ν - 2c b+c . Each bar in this graph corresponds with the experiment above so that positive (or zero) bars represent cooperation being incentivized and negative bars represent defection. Cost and benefit ratios are arranged from highest benefit (left) to lowest benefit (right).
3 Code: https://github.com/Dtradke/Teams IPD
By Equation 4, team structures present agents with the incentive to defect in 13 of 18 scenarios (72%) in Figure 1 (not including 1/30 and 30/1). Our results show teams always achieve more reward than individual agents (30/1); however, this reward depends on the cost and benefit ratio. When b = 2, the experiment results for average population reward a follow trend to the incentives of each scenario in the bottom graph. Our main finding in Figure 1 is how, when the benefit increases, MARL agents achieve high average population reward despite the incentive to defect as shown in the bottom graph. When b ∈ {5, 10}, every team structure, other than the individualistic 30/1 scenario, achieves basically the same reward as 1/30 even though there exists mixed-motive environments. Defection is the incentivized action in seven of 12 (58%) of these experiments which would produce low global reward if agents actually learned defection. Instead, we observe agents develop reciprocally pro-social policies that achieve high rewards in every scenario with teams of multiple agents when b ∈ {5, 10}. To analyze how high rewards are achieved in environmental conditions which promote defection, we study agents' behavior over time.
Policy
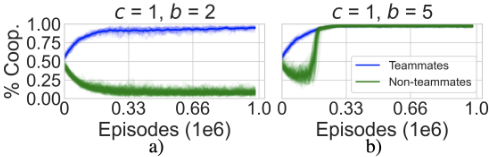
In evolutionary biology, fostering cooperation at various levels has been found to depend on the size of the cooperative return [Schnell et al., 2021]. Different types of cooperation, or levels of cooperation, have yet to be explicitly explored in MARL. We identify two levels of cooperation in our IPD environment: with teammates and with non-teammates. Figure 2 shows the percent of cooperative actions over time with the 5/6 team structure when b ∈ {2, 5}. By Equation 4, agents have the incentive to defect in both scenarios. The x-axis shows time and the y-axis shows the percent of an agent's actions that are cooperation (2,000 episode averages).
Both graphs in Figure 2 show that agents immediately learn to cooperate with teammates regardless of b. When b = 2, agents defect on non-teammates; however, when b = 5, agents learn to cooperate with both teammates and nonteammates. We observe similar behavior with every other team structure (not including 30/1) when b ∈ {5, 10}. That is, cooperation emerges with teammates and non-teammates despite incentives to defect. While other work requires strong assumptions of agent behavior to foster cooperation, our results indicate teams allow agents to learn an emergent cooperative convention at multiple levels of a system.
5.2 Cleanup Evaluation
In Cleanup, similar to previous work [Hughes et al., 2018; McKee et al., 2020; Jaques et al., 2019], we experiment with N = 6 agents. Our agents use the Proximal Policy Optimization (PPO) [Schulman et al., 2017] RL algorithm for 1.6×10⁸ environmental timesteps (each episode is 1,000 timesteps). Agent observability is limited to a 15 × 15 RGB window. Teammates share the same color and optimize for TRi calculated at each environmental timestep. Each experiment is repeated for eight trials. Further details are in Appendix B.2.
Reward
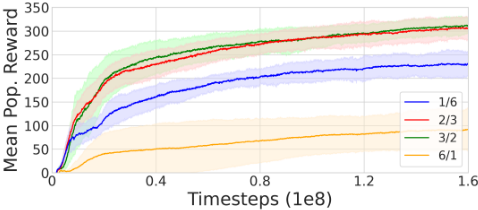
Figure 3 shows the mean population reward for each scenario in Cleanup with 95% confidence intervals. It has been previously shown that the setting that achieves the most population reward is when agents are altruistic and optimize for the collective rewards of the entire group [Wang et al., 2019; McKee et al., 2020], similar to our 1/6 configuration. However, teams introduce a new dynamic to the environment and we find the 2/3 and 3/2 team structures both achieve higher reward than 1/6 despite the interests of all agents not being aligned. As expected, the 6/1 scenario fails to achieve significant reward since agents succumb to the incentive to free ride and few apples grow. [McKee et al., 2020] has shown that only evaluating a system for mean reward masks other dynamics such as high levels of reward inequality among agents.
Equality
It is important to consider the process of how teams achieve higher reward and the potential side effects on population equality, such as the reward distributed among agents. We model population reward equality as the inverse Gini index, similar to past work [McKee et al., 2020], calculated as:
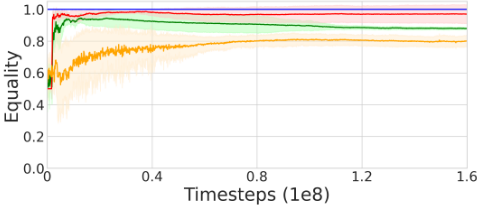
Figure 4: Cleanup: Inverse Gini index (equality) for each team structure with 95% confidence intervals. Higher values represent more equality. Both 2/3 and 3/2 team structures have high equality despite the interests of all agents not being aligned.
where RN is the mean population reward. Figure 4 shows our results for equality where higher values represent more equality. The 1/6 scenario is, by definition, always 1 since there is only one team. Despite earning high reward, both 2/3 and 3/2 team structures also achieve high equality and always have greater equality than 6/1. Success in Cleanup relies on agents coordinating to form an effective joint policy instead of simply choosing an explicit cooperation action (as in the IPD). To further understand how team structures achieve the highest rewards while also maintaining high equality, we analyze agents' policies and division of labor among teammates.
Division of Labor
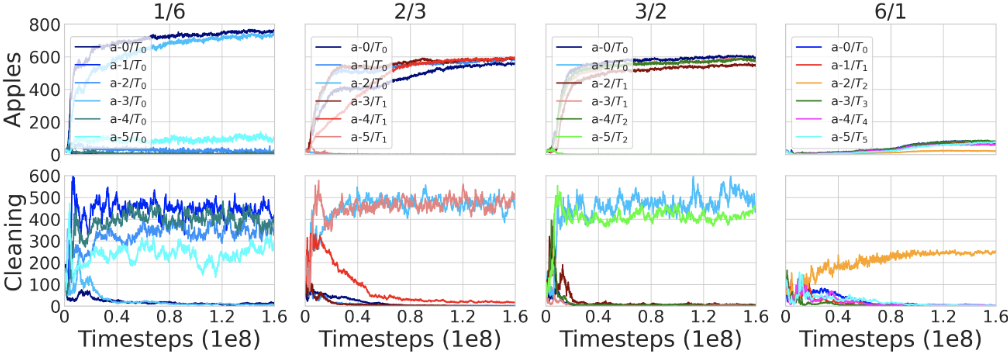
While agents consistently learn to divide labor among them, the same numbered agent does not always learn the same behavior across different trials of our experiments which makes aggregating multiple trials difficult. Therefore, Figure 5 shows the mean apples picked (top) and cleaning beams (bottom) for each agent in one trial of our evaluation. The behavior in this trial represents the most common division of labor for each team structure. Agents on the same team in each plot are presented as different shades of the same color. The y-axis shows the number of apples collected or cleaning actions taken and the x-axis represents time. Agents rarely punish, thus we omit it from our analysis.
In the 1/6 configuration (Figure 5, left), two agents learn to mostly pick apples while four agents clean the river. While this represents the most common division of labor with 1/6, we do observe two trials where three agents learn to pick apples and three agents learn to clean the river. These strategies achieve high mean reward but is not the best division of labor and consistently achieves less reward than the 2/3 and 3/2 team structures. When analyzing both team structures of 2/3 and 3/2 (Figure 5, middle columns), agents tend to divide themselves into four apple pickers and two river cleaners. This division of labor consistently achieves the highest reward in our evaluation. The 3/2 team structure tends to learn this division slightly quicker, although on average both configurations eventually achieve basically the same reward as shown in Figure 3. Independent agents in 6/1 fail to significantly clean the river, therefore few apples grow which leads to low rewards. In the example shown in Figure 5, five agents free-ride on the labor of only one river cleaning agent.
In summary, our results show how agents in team structures learn better task specialization among the population by autonomously learning roles within their team. This allows populations in the 2/3 and 3/2 team structures to keep the river clean while most agents collect the spawning apples. This causes 2/3 and 3/2 to achieve high population reward and equality across teams even though agents on different teams optimize for their own team's reward.
6 Discussion and FutureWork
Across multiple domains, we have shown that our model of teams has a significant impact on how agents learn to develop pro-social policies and coordinate their behavior. In the IPD, we show how teams allow agents to immediately identify and cooperate with their teammates, which may be similar to kin selection in human behavior [Muthukrishna, 2017]. Interestingly, we find that RL agents develop a prosocial convention and adapt this cooperative behavior towards non-teammates, even if defection has greater expected value. This behavior may be comparable with different levels of cooperation in humans, similar to increasing cooperation from only kin selection to notions of direct reciprocity with other groups [Muthukrishna, 2017].
While it was previously thought that optimizing for signals from all agents achieves the highest reward in Cleanup [Wang et al., 2019; McKee et al., 2020], our results show that agents optimizing for only a subset of the population (i.e., a team) achieves higher reward. Agent specialization in Cleanup is identified in [McKee et al., 2020]. In that work, specialization is viewed as a negative result which causes high labor inequality. However, the context of teams should change how task specialization is viewed in MARL. In the literature on Team Forming and Coalition Structure Generation, teams are often explicitly constructed to fill necessary roles [Andrejczuk et al., 2016]. We view task specialization as the agents autonomously learning these roles with only the feedback of their team's reward. This reinforces our hypothesis that teams can help improve how MARL agents learn to coordinate, and may be of specific interest to the emergent behavior community.
However, certain side effects may occur among teams. While our 3/2 team structure achieves high reward in Cleanup, there is higher inequality than 2/3. To achieve the four picker/two cleaner division of labor, one team (T1 (red) in Figure 5) must free-ride on the labor of the other two teams. In practice, systems should consider potential side effects if slight inequality is detrimental to its welfare in the long-run, despite short-term stability. Furthermore, while we explore teams of AI agents, teams may also consist of humans or hybrid populations of both AI and humans. Exploring alternative team reward functions may lead to interesting results and future research, particularly in the context of hybrid teams.
We see many interesting open questions with multiagent teams. For example, constructing richer reward structures by individuals optimizing for various types of goals [Radke et al., 2022]. Regarding levels of cooperation, exploring teams of unequal size and conditions under which low-level cooperation (i.e., nepotism or bribery) undermines global progress may be of interest. Our model is constructed to easily allow the adaptation of additional infrastructure among the agents. Thus, longer term questions include analyzing how features such as communication, negotiation, trust, and sanctions impact our model and introduce new challenges. We hope that this work will reinvigorate the study of multiagent teams with RL agents to further understand how findings in organizational psychology and AI can complement each other.
Acknowledgements
This research is funded by the Natural Sciences and Engineering Research Council of Canada (NSERC), an Ontario Graduate Scholarship, a Cheriton Scholarship, and the University of Waterloo President's Graduate Scholarship. We also thank Jesse Hoey, Robin Cohen, Alexi Orchard, Sriram Subramanian, Valerie Platsko, and Kanav Mehra for their feedback and useful discussion on earlier drafts of this work.
@inproceedings{ijcai2022p65,
  title     = {Exploring the Benefits of Teams in Multiagent Learning},
  author    = {Radke, David and Larson, Kate and Brecht, Tim},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {454--460},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/65},
  url       = {https://doi.org/10.24963/ijcai.2022/65},
}
TY - CPAPER TI - Exploring the Benefits of Teams in Multiagent Learning AU - Radke, David AU - Larson, Kate AU - Brecht, Tim T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 454 EP - 460 DO - 10.24963/ijcai.2022/65 UR - https://doi.org/10.24963/ijcai.2022/65 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





