
OTOcc: Optimal Transport for Occupancy Prediction
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence. Main Track. Pages 1010-1019.
https://doi.org/10.24963/ijcai.2024/112
Keywords
- Computer Vision: CV: Machine learning for vision
- Computer Vision: CV: 3D computer vision
- Computer Vision: CV: Applications
Abstract
The autonomous driving community is highly interested in 3D occupancy prediction due to its outstanding geometric perception and object recognition capabilities. However, previous methods are limited to existing semantic conversion mechanisms for solving sparse ground truths problem, causing excessive computational demands and sub-optimal voxels representation. To tackle the above limitations, we propose OTOcc, a novel 3D occupancy prediction framework that models semantic conversion from 2D pixels to 3D voxels as Optimal Transport (OT) problem, offering accurate semantic mapping to adapt to sparse scenarios without attention or depth estimation. Specifically, the unit transportation cost between each demander (voxel) and supplier (pixel) pair is defined as the weighted occupancy prediction loss. Then, we utilize the Sinkhorn-Knopp Iteration to find the best mapping matrices with minimal transportation costs. To reduce the computational cost, we propose a block reading technique with multi-perspective feature representation, which also brings fine-grained scene understanding. Extensive experiments show that OTOcc not only has the competitive prediction performance but also has about more than 4.58% reduction in computational overhead compared to state-of-the-art methods.
- [Berman et al., 2018] Maxim Berman, Amal Rannen Triki, and Matthew B Blaschko. The lovász-softmax loss: A tractable surrogate for the optimization of the intersection- over-union measure in neural networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 4413-4421, 2018.
- [Caesar et al., 2020] Holger Caesar, Varun Bankiti, Alex H Lang, Sourabh Vora, Venice Erin Liong, Qiang Xu, Anush Krishnan, Yu Pan, Giancarlo Baldan, and Oscar Beijbom. nuscenes: A multimodal dataset for autonomous driv- ing. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 11621- 11631, 2020.
- [Cao and others, 2022] Cao et al. Monoscene: Monocular 3d semantic scene completion. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 3991-4001, 2022.
- [Cortinhal and others, 2020] Cortinhal et al. Salsanext: Fast, uncertainty-aware semantic segmentation of lidar point clouds. In Advances in Visual Computing: 15th Interna- tional Symposium, ISVC 2020, San Diego, CA, USA, Oc- tober 5-7, 2020, Proceedings, Part II 15, pages 207-222. Springer, 2020.
- [Cuturi, 2013] Marco Cuturi. Sinkhorn distances: Light- speed computation of optimal transport. Advances in Neu- ral Information Processing Systems, 26, 2013.
- [Dai et al., 2017] Jifeng Dai, Haozhi Qi, Yuwen Xiong, Yi Li, Guodong Zhang, Han Hu, and Yichen Wei. De- formable convolutional networks. In Proceedings of the IEEE International Conference on Computer Vision, pages 764-773, 2017.
- [Ge et al., 2021] Zheng Ge, Songtao Liu, Zeming Li, Osamu Yoshie, and Jian Sun. Ota: Optimal transport assignment for object detection. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 303-312, 2021.
- [Huang et al., 2021] Junjie Huang, Guan Huang, Zheng Zhu, Yun Ye, and Dalong Du. Bevdet: High-performance multi-camera 3d object detection in bird-eye-view. arXiv preprint arXiv:2112.11790, 2021.
- [Huang et al., 2023] Yuanhui Huang, Wenzhao Zheng, Yun- peng Zhang, Jie Zhou, and Jiwen Lu. Tri-perspective view for vision-based 3d semantic occupancy prediction. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9223-9232, 2023.
- [Jia et al., 2023] Yupeng Jia, Jie He, Runze Chen, Fang Zhao, and Haiyong Luo. Occupancydetr: Making seman- tic scene completion as straightforward as object detec- tion. arXiv preprint arXiv:2309.08504, 2023.
- [Li et al., 2022a] Wuyang Li, Xinyu Liu, and Yixuan Yuan. Scan++: Enhanced semantic conditioned adaptation for domain adaptive object detection. IEEE Transactions on Multimedia, 2022.
- [Li et al., 2022b] Zhiqi Li, Wenhai Wang, Hongyang Li, Enze Xie, Chonghao Sima, Tong Lu, Yu Qiao, and Jifeng Dai. Bevformer: Learning bird's-eye-view representation from multi-camera images via spatiotemporal transform- ers. In European Conference on Computer Vision, pages 1-18. Springer, 2022.
- [Li et al., 2023a] Yiming Li, Zhiding Yu, Christopher Choy, Chaowei Xiao, Jose M Alvarez, Sanja Fidler, Chen Feng, and Anima Anandkumar. Voxformer: Sparse voxel trans- former for camera-based 3d semantic scene completion. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9087-9098, 2023.
- [Li et al., 2023b] Yinhao Li, Han Bao, Zheng Ge, Jinrong Yang, Jianjian Sun, and Zeming Li. Bevstereo: Enhanc- ing depth estimation in multi-view 3d object detection with temporal stereo. In Proceedings of the AAAI Conference on Artificial Intelligence, pages 1486-1494, 2023.
- [Li et al., 2023c] Yinhao Li, Zheng Ge, Guanyi Yu, Jinrong Yang, Zengran Wang, Yukang Shi, Jianjian Sun, and Zem- ing Li. Bevdepth: Acquisition of reliable depth for multi- view 3d object detection. In Proceedings of the AAAI Con- ference on Artificial Intelligence, pages 1477-1485, 2023.
- [Li et al., 2023d] Zhiqi Li, Zhiding Yu, David Austin, Ming- sheng Fang, Shiyi Lan, Jan Kautz, and Jose M Al- varez. Fb-occ: 3d occupancy prediction based on forward-backward view transformation. arXiv preprint arXiv:2307.01492, 2023.
- [Lu et al., 2023] Yuhang Lu, Xinge Zhu, Tai Wang, and Yuexin Ma. Octreeocc: Efficient and multi-granularity oc- cupancy prediction using octree queries. arXiv preprint arXiv:2312.03774, 2023.
- [Miao et al., 2023a] Ruihang Miao, Weizhou Liu, Mingrui Chen, Zheng Gong, Weixin Xu, Chen Hu, and Shuchang Zhou. Occdepth: A depth-aware method for 3d seman- tic scene completion. arXiv preprint arXiv:2302.13540, 2023.
- [Miao et al., 2023b] Ruihang Miao, Weizhou Liu, Mingrui Chen, Zheng Gong, Weixin Xu, Chen Hu, and Shuchang Zhou. Occdepth: A depth-aware method for 3d seman- tic scene completion. arXiv preprint arXiv:2302.13540, 2023.
- [Milioto et al., 2019] Andres Milioto, Ignacio Vizzo, Jens Behley, and Cyrill Stachniss. Rangenet++: Fast and ac- curate lidar semantic segmentation. In 2019 IEEE/RSJ In- ternational Conference on Intelligent Robots and Systems (IROS), pages 4213-4220. IEEE, 2019.
- [Ouyang et al., 2024] Wenzhe Ouyang, Xiaolin Song, Bailan Feng, and Zenglin Xu. Octocc: High-resolution 3d occupancy prediction with octree. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 4369-4377, 2024.
- [Pan et al., 2023] Mingjie Pan, Jiaming Liu, Renrui Zhang, Peixiang Huang, Xiaoqi Li, Li Liu, and Shanghang Zhang. Renderocc: Vision-centric 3d occupancy pre- diction with 2d rendering supervision. arXiv preprint arXiv:2309.09502, 2023.
- [Qi et al., 2023] Zhangyang Qi, Jiaqi Wang, Xiaoyang Wu, and Hengshuang Zhao. Ocbev: Object-centric bev trans- former for multi-view 3d object detection. arXiv preprint arXiv:2306.01738, 2023.
- [Tan et al., 2023] Zhiyu Tan, Zichao Dong, Cheng Zhang, Weikun Zhang, Hang Ji, and Hao Li. Ovo: Open- vocabulary occupancy. arXiv preprint arXiv:2305.16133, 2023.
- [Tian et al., 2023] Xiaoyu Tian, Tao Jiang, Longfei Yun, Yue Wang, Yilun Wang, and Hang Zhao. Occ3d: A large-scale 3d occupancy prediction benchmark for autonomous driv- ing. arXiv preprint arXiv:2304.14365, 2023.
- [Wang et al., 2023] Yuqi Wang, Yuntao Chen, Xingyu Liao, Lue Fan, and Zhaoxiang Zhang. Panoocc: Unified oc- cupancy representation for camera-based 3d panoptic seg- mentation. arXiv preprint arXiv:2306.10013, 2023.
- [Xu et al., 2021] Jianyun Xu, Ruixiang Zhang, Jian Dou, Yushi Zhu, Jie Sun, and Shiliang Pu. Rpvnet: A deep and efficient range-point-voxel fusion network for lidar point cloud segmentation. In Proceedings of the IEEE/CVF In- ternational Conference on Computer Vision, pages 16024- 16033, 2021.
- [Yang et al., 2023] Chenyu Yang, Yuntao Chen, Hao Tian, Chenxin Tao, Xizhou Zhu, Zhaoxiang Zhang, Gao Huang, Hongyang Li, Yu Qiao, Lewei Lu, et al. Bevformer v2: Adapting modern image backbones to bird's-eye-view recognition via perspective supervision. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pat- tern Recognition, pages 17830-17839, 2023.
- [Zhang and others, 2023] Zhang et al. Occformer: Dual-path transformer for vision-based 3d semantic occupancy pre- diction. arXiv preprint arXiv:2304.05316, 2023.
- [Zhang et al., 2020] Yang Zhang, Zixiang Zhou, Philip David, Xiangyu Yue, Zerong Xi, Boqing Gong, and Has- san Foroosh. Polarnet: An improved grid representation for online lidar point clouds semantic segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9601-9610, 2020.
- [Zhou et al., 2022] Hongyu Zhou, Zheng Ge, Zeming Li, and Xiangyu Zhang. Matrixvt: Efficient multi-camera to bev transformation for 3d perception. arXiv preprint arXiv:2211.10593, 2022.
- [Zhu et al., 2020] Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, and Jifeng Dai. Deformable detr: Deformable transformers for end-to-end object detection. arXiv preprint arXiv:2010.04159, 2020.
- [Zhu et al., 2021] Xinge Zhu, Hui Zhou, Tai Wang, Fangzhou Hong, Yuexin Ma, Wei Li, Hongsheng Li, and Dahua Lin. Cylindrical and asymmetrical 3d convolution networks for lidar segmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9939-9948, 2021.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Vision-based 3D Occupancy Prediction aims to estimate the occupancy state of 3D voxels surrounding the ego-vehicle which provides a comprehensive 3D scene understanding. It is particularly an essential solution for recognizing irregularly shaped objects and also enables the open-set understanding [Tan et al., 2023], further benefiting downstream tasks, like prediction and planning.
Though success, most works still struggle to overcome the semantic sparsity of ground truths, which is the fundamental latent depth distribution for building 3D representations. (b) Querybased methods pre-define the query (BEV or 3D voxels) to encode semantics from multi-images. (c) Our OT-based method models the mapping strategy from 2D to 3D as the Optimal Transport problem.
∗Corresponding Author.
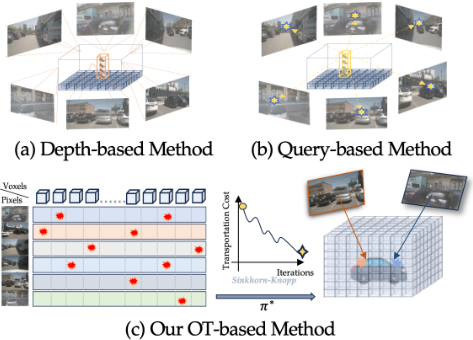
problem. The information density of such uncompressed representation is low, with numerous regions corresponding to free space in the physical world, resulting in biased 3D presentation construction. Most works are limited to two kinds of semantic conversion mechanisms for alleviating the abovementioned problem, which can be divided into the following two categories [Qi et al., 2023] : depth-based and querybased methods as shown in Figure 1(a, b). Depth-based methods [Li et al., 2023c; Miao et al., 2023a] leverage the depth estimation to build the multi-view frustums to form the BEV or 3D voxels. Query-based methods [Huang et al., 2023] utilize deformable attention for collecting semantics from images. However, they still suffer from the high computational cost of utilizing heavy decoders or relying on the depth estimation quality due to the sparse scene semantics, which rarely made any fundamental changes to the semantic conversion method. It motivates us to solve its efficiency problems by building the new semantic conversion mechanism without any attention or depth estimation.
In contrast to previous attempts, we address this issue with the Optimal Transport (OT), a well-studied topic in Optimization Theory that directly collects semantics from images by constructing and optimizing the mapping matrix from 2D to 3D via Sinkhorn-Knopp Iteration as shown in Figure 1(c). This method of semantic collection using matrix transformation reduces computational consumption by avoiding repeated learning of partial semantics like attention mechanism and can produce accurate and effective semantic mapping to avoid heavy decoder design. Completely different from current methods, our methods do not use any attention mechanism [Jia et al., 2023], temporal fusion [Yang et al., 2023] or depth estimation [Li et al., 2023a] at all. Specifically, we define each pixel as a supplier that supplies a certain number of semantic marks and define each grid as a demander who needs one unit semantic mark. if a grid receives a sufficient amount of semantic marks from a certain pixel, this grid becomes one important position for that pixel in which the complete semantics will be captured. In this context, the number of semantic marks each pixel supplies can be interpreted as "how many grids that pixels need for better convergence during the training process". The unit transportation cost between each pixel-grid pair is defined as the weighted classification loss of the corresponding grid, where the weight depends on the proportion of semantic marks contribution of each pixel to that grid. After formulation, finding the best semantic conversion strategy is converted to solve the optimal transport plan, which can be quickly and efficiently solved by the off-the-shelf Sinkhorn-Knopp Iteration [Cuturi, 2013].
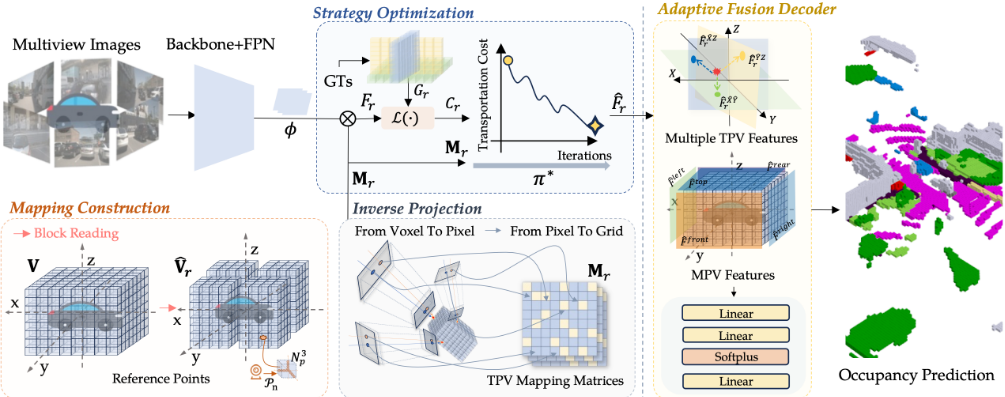
Our complete framework is as shown in Figure 2, which is named OTOcc (Optimal Transport for Occupancy Prediction). First, we pre-define a group of 3D voxels representation V containing dense reference point mapping from 3D voxels to 2D images. Motivated by low memory cost design [Huang et al., 2023], we also pre-define tri-perspective view (TPV) mapping matrices for converting multi-view images into TPV features. After applying the camera principle, we utilize the existing reference point mapping relationship to complete various coarse mapping matrices from pixels to grids by inverse projection [Zhou et al., 2022]. Then, coarse mapping matrices are refined via Sinkhorn-Knopp Iteration to seek the best semantic conversion strategy π∗ . Multiplying π∗ with the image features, we obtain diverse refined TPV features, which can accurately represent current scene information. For further reducing computational cost, we propose a practical block reading technique, which divides the V equally into four small sets of voxels for optimization in turn. It not only brings Multi-Perspective View (MPV) characteristics to obtain more accurate estimation of 3D scenes but also mitigates the semantic loss caused by tri-plane compression of complex scene information. Finally, we use the lightweight Adaptive Fusion Decoder to process MPV features for obtaining the 3D voxel representation and accurate occupancy prediction. Extensive experiments against state-of-the-art occupancy prediction methods demonstrate that OTOcc outperforms others on two benchmarks, reducing about 4.58% computational cost. Ablation studies further validate the effectiveness of each module within our method. To summarise, our main contributions are as follows:
- We introduce an innovative vision-based 3D occupancy prediction framework named OTOcc. This work represents the first attempt at formulating the semantic conversion from pixels to voxels as the Optimal Transport problem to the best of our knowledge.
- OTOcc designs the dense reference points from voxels to pixels and projects them into multiple mapping matrices inversely. Then, OTOcc utilizes the Sinkhorn-Knopp Iteration to find the optimal mapping matrices. Note that OTOcc doesn't use any attention mechanisms, temporal fusion or depth estimation to show its effectiveness.
- Comprehensive experiments verify that the proposed OTOcc achieves the competitive performance on the Occ3D-nuScene benchmark and also show its effectiveness for vision-based semantic segmentation task.
2 RelatedWork
2.1 3DOccupancy Prediction
The 3D occupancy prediction task has garnered significant attention due to its enhanced geometry information and superior capabilities in generalized object recognition compared to 3D object detection. Previous works [Yang et al., 2023; Li et al., 2023d] directly utilize the BEV feature for occupancy prediction tasks. Current research in occupancy prediction focuses on dense voxel modelling. OccFormer [Zhang and others, 2023] decomposes the 3D processing into the local and global transformer pathways along the horizontal plane. Due to the high resolution of standard voxel representation and sparse context distribution in 3D scenes, these methods [Zhang and others, 2023; Miao et al., 2023b] face significant computational overhead and efficiency challenges. Some approaches [Huang et al., 2023; Li et al., 2023a] propose to reduce the number of modelled voxels to address this problem. TPVFormer [Huang et al., 2023] proposes a tri-perspective view method for predicting 3D occupancy, leading to performance loss caused by coarse scene semantic compression. VoxFormer [Li et al., 2023a] mitigates computational complexity through depth estimation and modelling only those specific areas. However, the success of this procedure critically depends on the precision of depth estimation. PanoOcc [Wang et al., 2023] presents a coarse-to-fine manner for constructing 3D voxel representation. However, the lack of information from coarse-grained modelling cannot be adequately addressed by the up-sampling process. Some works [Lu et al., 2023; Ouyang et al., 2024] utilize the octree representation for finetuning the 3D voxels. Different from above methods, our approach models the semantics conversion from 2D images to 3D representation as the Optimal Transport problem, which finds the best mapping strategy via Sinkhorn-Knopp Iteration. It leverages direct mathematical mapping to avoid redundant and complex semantic collection mechanisms like attention or depth estimation, thereby better adapting to sparse semantic scenes and reducing computational consumption.
2.2 Optimal Transport
Optimal Transport (OT), a well-studied topic in Optimization Theory, efficiently quantifies the minimum "cost" of transporting mass from one distribution to another. It enables measuring the similarity between two distributions, widely applied in various fields, such as object detection [Ge et al., 2021] or domain adaptive [Li et al., 2022a]. Motivated by this well-known theory, we propose a novel framework for 3D occupancy prediction by utilizing OT, which tackles the sub-optimal transformation problem.
3 Method
In this section, we first revisit the definition of the Optimal Transport problem and then demonstrate how we formulate the semantic conversion from 2D images to 3D representation in occupancy prediction into an OT problem as shown in Figure 2. Then, motivated by TPVFormer and MatrixVT [Zhou et al., 2022], we convert the image semantics into TPV features by inverse projection, which utilizes the SinkhornKnopp Iteration to find the best semantic mapping strategy. For reducing the memory cost, we propose the block reading technique. It brings the more accurate estimation of 3D scenes and mitigates the semantic loss caused by tri-plane compression of complex scene information. Finally, we introduce the Adaptive Fusion Decoder for obtaining an accurate 3D voxel representation, which is lightweight and simple, showing the superiority of our OT-based design.
3.1 Optimal Transport
Optimal Transport (OT) describes the following problem: supposing there are ns suppliers and nd demanders in a certain area. The α-th supplier holds sα units of goods while the β-th demander needs dβ units of goods. Transporting cost for each unit of good from supplier α to demander β is denoted by cαβ. The goal of OT problem is to find a transportation plan π∗ = {παβ | α = 1, 2, . . . ns, β = 1, 2, . . . nd}, according to which all goods from suppliers can be transported to demanders at a minimal transportation cost:
This is a linear program which can be solved in polynomial time. However, the resulting linear program is large, involving the square of feature dimensions with the semantic conversion from 2D images to 3D representation. Hence, we address this issue by a fast iterative solution named SinkhornKnopp [Cuturi, 2013].
3.2 OT for Semantic Conversion
As shown in Figure 2, we present a coarse-to-fine manner for finding the semantic conversion strategy. We define the semantic conversion from 2D images to 3D voxels as the OT problem. Specifically, We instantiate the semantic conversion strategy as a mapping matrix, which defines each pixel as a supplier who supplies a certain number of semantic marks, and defines each voxel as a demander who needs one unit semantic mark. The pair-wise transportation cost is defined as the weighted occupancy prediction loss. With SinkhornKnopp optimization, we can find the optimal mapping matrix. In this section, we will introduce how to generate the mapping matrix, calculate the transportation cost and optimize the semantic conversion strategy via Sinkhorn-Knopp Iteration.
Mapping Construction. We first define a group of 3D voxels representation V ∈ RX×Y×Z , where X, Y,Z are the spatial resolution of the voxel space. For reducing the computional cost, we divide the Vr equally into four small ˆV ∈ R ˆX׈ Y×Z , where ˆX = X2 , ˆ Y = Y2 , r ∈ {1, 2, 3, 4}. Each grid cell in the voxel corresponds to a box in the realworld size of (ex, ey, ez) meters. We uniformly sample Np points within a certain range along a dimension of the real world. The real position of a reference point located at voxel grid (i, j, k) in the ego-vehicle frame is (xmi , ym j , zm k ), where i, j, k ∈ {1, 2, · · · ,Np}, m ∈ {1, 2, · · · ,N 3 p }. The projection between m-th projected reference point Ref mi,j,k = (xmi , ym j , zm k ) and its corresponding 2D reference point n-th view can be formulate as:
where Pn ∈ R3×4 is the projection matrix of the n-th camera. n ∈ {0, 1, ...,Nc - 1} and Nc denotes the number of cameras. (un,m ijk , vn,m ijk ) denotes the m-th 2D reference point on n-th image view. dn,m ijk is the depth in the camera frame. For the sake of simplicity, we denote the process of projecting from three-dimensional coordinates to pixels coordinates as { ˜ Ref mi,j,k } = Pn({Ref mi,j,k }). Since not all cameras can capture the reference points of v, we can further reduce computation by removing invalid sets from { ˜ Ref mi,j,k } if none of the reference points falls onto the image captured by the corresponding camera.
Inverse Projection. For further reducing memory cost, we decide to utilize the Tri-Perspective View (TPV) shape matrices as our mapping matrices from 2D images to 3D voxels for storing the current mapping strategy and represent the 3D voxel semantics as TPV features. In detailed, for r-th ˆV, we first define its mapping matrices as follows:
where H,W denotes the weight and width of image feature maps and r ∈ {1, 2, 3, 4}. All elements of Mr are filled with 0. Since the mappings contained inMr and { ˜ Ref mi,j,k } are exactly opposite, we obtain Mr through { ˜ Ref mi,j,k } by inverse projection PI :
Specifically, for ˜ Ref mi,j,k = (un,m ijk , vn,m ijk ), we first encode it as { ˜ Ref mi,j,k } = {(pn,m ijk )} for obtaining its position of the feature map after flattening:
where pn,m ijk ∈ [1,NcHW]. Each pixel coordinates (un,m ijk , vn,m ijk ) in each voxel can be expressed as a value pn,m ijk in one dimension. Then, we set the element in Mr to 1 if its corresponding point exists in { ˜ Ref mi,j,k } and obtain the coarse mapping matrix Mr that converts 2D image semantics into TPV features. Next, we map the one fused feature map ϕ ∈ RC×NcHW with 1/16 of the input resolution to coarse TPV features Fr = [F ˆX ˆ Y r , F ˆXZ r , F ˆ Y Z r ] withMr as follows:
Algorithm 1 Optimal Transport for Strategy Optimization
Input:
ϕ ∈ RC×Nc×Hf×Wf is the feature map
F ∈ RC×Ht×Wt is the coarse TPV feature
M∈ RNcHfWf×HtWt is the coarse mapping matrix
A ∈ RHtWt is the sum of each column of M
G is the ground truth for F
Parameters:
C is the number of the channel Nc is the number of the camera view (Hf ,Wf ) is resolution of the feature map (Ht,Wt) is resolution of the TPV feature γ is the regularization intensity in Sinkhorn-Knopp Iter. T is the number of iterations in Sinkhorn-Knopp Iter.
Output:
π∗ is the optimal strategy
- 1: P ← Forward(F)
- 2: sα(α = 1, 2....,NcHfWf) ← ∑HtWt j=1 (M[α, j])
- 3: dβ(β = 1, 2, ...,HtWt) ←OnesInit
- 4: classification cost: C ∈ RHt×Wt ←CE(P,G)
- 5: C is flattened and broadcast into ˆ C ∈ RNcHfWf×HtWt
- 6: transportation cost: ˜ C =M· ˆ C/A
- 7: v0 , u0 ←OnesInit
- 8: for t=0 to T do:
- 9: vt+1 , ut+1 ←SinkhornIter(c, vt , ut , s, d)
- 10: obtain π∗ from SinkhornIter(c, vT , uT , s, d)
- 11: return π∗
where C is the channel number and fmlp(·) denotes the multilayer perception layer (MLP). This MLP layer learns the characteristics of Sinkhorn Iteration for better optimization and fine-tune. The coarse mapping matrices Mr and TPV features Fr will be used to calculate initial transportation cost and finding the best semantic conversion strategy by refining Mr in the following module.
Strategy Optimization. Supposing there are ns image pixels and nd grids (across all mapping matrices Mr) for multi-view features ϕ, we view each pixel as a supplier who holds sα units of semantics marks (i.e., α = 1, 2, .., NcHW), and each grid as a demander who needs dβ units of semantic mark (i.e., β = 1, 2, .., η), where η ∈ { ˆX ˆ Y , ˆXZ, ˆ Y Z}. The cost crpα,gβ for transporting one unit of semantic marks from pixel pα to grid gβ is defined as the weighted occupancy prediction loss corresponding to gβ:
where P(gβ) denotes the predicted classification score and Ggβ denotes ground truth class for gβ. L(·) generally stands for cross entropy loss. Specifically, we use top plane mapping matrix M ˆX ˆ Y r to instantiate the above how to transportation cost for instance. We first use its corresponding top plane feature F ˆX ˆ Y j to calculating the classification loss:
Then, we flatten the C ˆXˆ Y r into a vector and broadcast the vector into the matrix ˆ C ˆX ˆ Y r ∈ RNcHW× ˆXˆ Y , so that we can calculate the initial transportation cost ofM ˆXˆ Y r as follows:
| Method | mIoU | ■ others | ■ barrier | ■ bicycle | ■ bus | ■ car | ■ const. veh. | ■ motorcycle | ■ pedestrian | ■ traffic cone | ■ trailer | ■ truck | ■ drive. suf. | ■ other flat | ■ sidewalk | ■ terrain | ■ manmade | ■ vegetation |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| MonoScene [Cao and others, 2022] | 6.06 | 1.75 | 7.23 | 4.26 | 4.93 | 9.38 | 5.67 | 3.98 | 3.01 | 5.90 | 4.45 | 7.17 | 14.91 | 6.32 | 7.92 | 7.43 | 1.01 | 7.65 |
| BEVDet [Huang et al., 2021] | 11.73 | 2.09 | 15.29 | 0.0 | 4.18 | 12.97 | 1.35 | 0.0 | 0.43 | 0.13 | 6.59 | 6.66 | 52.72 | 19.04 | 26.45 | 21.78 | 14.51 | 15.26 |
| BEVStereo [Li et al., 2023b] | 24.51 | 5.73 | 38.41 | 7.88 | 38.70 | 41.20 | 17.56 | 17.33 | 14.69 | 10.31 | 16.84 | 29.62 | 54.08 | 28.92 | 32.68 | 26.54 | 18.74 | 17.49 |
| OccFormer [Zhang and others, 2023] | 21.93 | 5.94 | 30.29 | 12.32 | 34.40 | 39.17 | 14.44 | 16.45 | 17.22 | 9.27 | 13.90 | 26.36 | 50.99 | 30.96 | 34.66 | 22.73 | 6.76 | 6.97 |
| RenderOcc [Pan et al., 2023] | 26.11 | 4.84 | 31.72 | 10.72 | 27.67 | 26.45 | 13.87 | 18.20 | 17.67 | 17.84 | 21.19 | 23.25 | 63.20 | 36.42 | 46.21 | 44.26 | 19.58 | 20.70 |
| BEVFormer [Cortinhal and others, 2020] | 26.88 | 5.85 | 37.83 | 17.87 | 40.44 | 42.43 | 7.36 | 23.88 | 21.81 | 20.98 | 22.38 | 30.70 | 55.35 | 28.36 | 36.00 | 28.06 | 20.04 | 17.69 |
| TPVFormer [Huang et al., 2023] | 27.83 | 7.22 | 38.90 | 13.67 | 40.78 | 45.90 | 17.23 | 19.99 | 18.85 | 14.30 | 26.69 | 34.17 | 55.65 | 35.47 | 37.55 | 30.70 | 19.40 | 16.78 |
| CTF-Occ [Zhu et al., 2021] | 28.53 | 8.09 | 39.33 | 20.56 | 38.29 | 42.24 | 16.93 | 24.52 | 22.72 | 21.05 | 22.98 | 31.11 | 53.33 | 33.84 | 37.98 | 33.23 | 20.79 | 18.00 |
| OTOcc | 29.10 | 7.81 | 39.23 | 19.45 | 39.54 | 42.45 | 18.15 | 25.72 | 23.81 | 20.13 | 24.56 | 34.73 | 54.45 | 37.12 | 37.23 | 34.56 | 18.53 | 17.10 |
| Method | Input Modality | mIoU | ■ barrier | ■ bicycle | ■ bus | ■ car | ■ const. veh. | ■ motorcycle | ■ pedestrian | ■ traffic cone | ■ trailer | ■ truck | ■ drive. suf. | ■ other flat | ■ sidewalk | ■ terrain | ■ manmade ■ | vegetation |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| RangeNet++ [Milioto et al., 2019] | LiDAR | 65.5 | 66.0 | 21.3 | 77.2 | 80.9 | 30.2 | 66.8 | 69.6 | 52.1 | 54.2 | 72.3 | 94.1 | 66.6 | 63.5 | 70.1 | 83.1 | 79.8 |
| PolarNet [Zhang et al., 2020] | LiDAR | 71.0 | 74.7 | 28.2 | 85.3 | 90.9 | 35.1 | 77.5 | 71.3 | 58.8 | 57.4 | 76.1 | 96.5 | 71.1 | 74.7 | 74.0 | 87.3 | 85.7 |
| Salsanext [Cortinhal and others, 2020] | LiDAR | 72.2 | 74.8 | 34.1 | 85.9 | 88.4 | 42.2 | 72.4 | 72.2 | 63.1 | 61.3 | 76.5 | 96.0 | 70.8 | 71.2 | 71.5 | 86.7 | 84.4 |
| Cylinder3D++ [Zhu et al., 2021] | LiDAR | 76.1 | 76.4 | 40.3 | 91.2 | 93.8 | 51.3 | 78.0 | 78.9 | 64.9 | 62.1 | 84.4 | 96.8 | 71.6 | 76.4 | 75.4 | 90.5 | 87.4 |
| RPVNet [Xu et al., 2021] | LiDAR | 77.6 | 78.2 | 43.4 | 92.7 | 93.2 | 49.0 | 85.7 | 80.5 | 66.0 | 66.9 | 84.0 | 96.9 | 73.5 | 75.9 | 76.0 | 90.6 | 88.9 |
| BEVFormer-Base [Li et al., 2022b] | Camera | 56.2 | 54.0 | 22.8 | 76.7 | 74.0 | 45.8 | 53.1 | 44.5 | 24.7 | 54.7 | 65.5 | 88.5 | 58.1 | 50.5 | 52.8 | 71.0 | 63.0 |
| TPVFormer-Base [Huang et al., 2023] | Camera | 68.9 | 70.0 | 40.9 | 93.7 | 85.6 | 49.8 | 68.4 | 59.7 | 38.2 | 65.3 | 83.0 | 93.3 | 64.4 | 64.3 | 64.5 | 81.6 | 79.3 |
| Occformer [Zhang and others, 2023] | Camera | 70.4 | 70.3 | 43.8 | 93.2 | 85.2 | 52.0 | 59.1 | 67.6 | 45.4 | 64.4 | 84.5 | 93.8 | 68.2 | 67.8 | 68.3 | 82.1 | 80.4 |
| PanoOcc-Base [Wang et al., 2023] | Camera | 70.7 | 73.7 | 42.6 | 94.1 | 87.1 | 56.4 | 62.4 | 64.7 | 36.7 | 69.3 | 86.4 | 94.9 | 69.8 | 67.1 | 67.9 | 80.3 | 77.0 |
| OTOcc | Camera | 70.9 | 73.0 | 43.2 | 93.9 | 88.5 | 53.5 | 66.5 | 62.5 | 41.0 | 68.5 | 87.2 | 90.5 | 69.4 | 66.0 | 66.0 | 80.5 | 81.7 |
where A ˆX ˆ Y r ∈ R ˆXˆ Y denotes the sum of each column of M ˆX ˆ Y r , which is the vector. In a standard OT problem, the total supply must be equal to the total demand. Hence, for each supplier gβ, we sum up all elements in its corresponding row of M ˆXˆ Y r as its holding semantic marks. As we already have cost matrix ˜ C ˆX ˆ Y , supplying vector sα ∈ RNcHW and demanding vector dβ ∈ R ˆXˆ Y , the optimal transportation plan π∗, ˆX ˆ Y r ∈ RNcHW× ˆXˆ Y can be obtained by solving this OT problem via the off-the-shelf Sinkhorn-Knopp Iteration [Cuturi, 2013]. After T iteration, we get π∗, ˆXˆ Y r . One can decode the corresponding semantic conversion strategy by directly multiplying it with feature map by Eq. (6), which obtains the better top plane ˆ F ˆXˆ Y r = fmlp(ϕ · π∗, ˆXˆ Y r ). The similar procedure is repeated for all mapping matrices Mr as shown in Algorithm 1. Here, we get the refined TPV features ˆ Fr from each segmented voxel ˆV, which contains the pure semantics from 2D images, facilitating accurate scene representation. Note that the optimization process of OT problem only contains some matrix multiplications which can be accelerated by GPU devices. Hence, the optimization module only increases the total training time.
3.3 Adaptive Fusion Decoder
After sending four small ˆV through the above modules, we obtain the refining TPV features ˆ Fr for each ˆVr, which collects pure semantics from 2D images. We first need to combine these features to form five diverse planes to represent the front, left, right, rear and top features as follows:
where C(·) stands for the concat operation. Compared to ordinary TPV features setting [Huang et al., 2023], our methods perform a more comprehensive representation of the 3D scene representation by introducing the Multi-Perspective View (MPV) features. Due to the top plane ˆ F top containing comprehensive and significant labeling of scene category position relationships, we propose to decouple ˆ F top on other planes ˆ F ′ (front, rear, left and right) for condensing voxel semantics. Specifically, we use several convolutional layers to highly aggregate plane feature semantics and perform dual fusion:
where Pa(·) is composed of three convolutional layers, a linear layer and an upsampled layer. Pb(·) consists of two convolutional layers, a linear layer, an upsampled layer and a relu layer. For dense voxel features, we actively broadcast each plane ˆ F ′ along the corresponding orthogonal direction to produce three feature tensors of the same upsampled size C×X′ ×Y ′ ×Z ′ and aggregate them by summation to obtain the full-scale voxel features. To conduct fine-grained prediction or segmentation tasks, we apply a lightweight MLP on voxel features to predict their semantic labels, which is instantiated by only three linear layers, and an intermediate activation layer.
| Method | Memory | Latency | FPS | mIoU |
|---|---|---|---|---|
| TPVFormer-Base | 33.5G / 7.1G | 268ms | 3.7 | 68.9 |
| PanoOcc-Base | 24.0G / 6.0G | 203ms | 4.8 | 70.7 |
| OTOcc (Ours) | 22.9G / 5.3G | 227ms | 4.4 | 70.9 |
3.4 Model Optimization
In the training stage of the OTOcc, the whole loss function L consists of three main components:
where LCE denotes the cross entropy loss (all voxels), LLovasz denotes the Lovasz loss [Berman et al., 2018] (voxels containing LiDAR points) for voxel prediction and LOT denotes the mean of the initial transportation cost of TPV mapping matrices Mr. We utilize the hyperparameter λ for controlling the sensitivity of LOT .
3.5 Model Inference
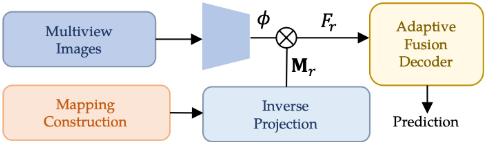
The whole test pipeline of our proposed OTOcc is as shown in Figure 3. Caused by the time cost of the Sinkhorn-Knopp Iteration, we abandon the Strategy Optimization module from the training framework, which promotes the inference speed significantly. Moreover, the fmlp also plays a similar role as Strategy Optimization for fine-tuning the coarse TPV features, which contains sufficient inherent semantic knowledge from TPV features and voxels presentation.
4 Experiments
4.1 Datasets
Occ3D-nuScenes 1 [Tian et al., 2023] contains 700 training scenes and 150 validation scenes. The occupancy scope is defined as -40m to 40m for x-axis or y-axis, and -1m to 5.4m for the z-axis in the ego coordinate. The voxel size is 0.4m× 0.4m× 0.4m for the occupancy label. The semantic labels contain 17 categories.
1 https://github.com/Tsinghua-MARS-Lab/Occ3D/
nuScenes [Caesar et al., 2020] is a large-scale autonomous driving dataset, collected in Boston and Singapore. It includes 1000 driving sequences from various scenes, split into 700 in the training set, 150 in the validation set, and 150 in the test set. Each sequence is captured at 20Hz frequency with 20 seconds duration. Each sample contains RGB images from 6 cameras with 360◦ horizontal FOV and point cloud data from 32 beam LiDAR sensor.
4.2 Experimental Settings
We adopt TPVFormer as our baseline and use its framework for developing our method. Following the setting in previous works, we adopted ResNet101-DCN [Dai et al., 2017] as the image backbone and trained the model on 8 NVIDIA A100 GPUs with a batch size of 1 per GPU. We also employ both cross entropy loss and Lovasz-softmax loss [Berman et al., 2018]. In the implementation, both two loss use voxel predictions as input. During training, we utilize the AdamW optimizer with an initial learning rate of 2×10⁻⁴ and the cosine schedule. Additionally, we employ photo-metric distortion as the data augmentation technique. The initial resolution of the (X, Y,Z) is (100, 100, 8) and the upsampled voxel features have dimensions of (X′ , Y ′ ,Z ′ ) is (200, 200, 16). We also set Np = 4, T = 40, λ = 0.2 and C = 256. Note that our proposed OTOcc is trained with only 15 epochs for efficiency.
4.3 Main Results
3D Occupancy Prediction. Evaluation results for 3D occupancy prediction are recorded in Table 1. OTOcc can achieve SOTA prediction performance with a 29.10% mIoU, outperforming existing counterparts significantly. Moreover, OTOcc surpasses CTF-Occ (28.53% mIoU), TPVFormer (28.34% mIoU) and BEVFormer (26.88% mIoU) with 0.57%, 0.76%, 2.22% mIoU gains, showing the advantage in terms of accurate semantic conversion. After that, our method can better detect easily confused objects such as the motorcycle (25.72%) or pedestrian (23.81%) than SOTAs.
3D Semantic Segmentation. We utilize the voxel predictions on sparse LiDAR points for the semantic segmentation evaluation. As shown in Table 2, we evaluate the semantic segmentation performance on the nuScenes validation set. OTOcc surpasses TPVFormer-Base, and Occformer with 2.0%, 0.5% mIoU, verifying its better ability to effectively sample semantics than these non-linear strategies. Moreover, OTOcc can achieve comparable performance to methods with LiDAR as input modality. For the model efficiency as shown in Table 3, we compare the performance and efficiency of our method with TPVformer and PanoOcc, under the same experimental setup. Our model still exhibits lower memory consumption with 22.9G training memory consumption (inference with 5.3G), showing the effectiveness of our methods. Moreover, our methods also have similar and competitive inference latency or FPS performance compared to PanoOcc.
| N x p | N y p | N z p | Occ. mIoU | LiDAR Seg. mIoU |
|---|---|---|---|---|
| 3 | 3 | 3 | 27.45 | 65.79 |
| 3 | 3 | 4 | 28.76 | 66.98 |
| 3 | 4 | 4 | 28.36 | 68.34 |
| 4 | 4 | 4 | 29.10 | 70.87 |
| 4 | 4 | 5 | 29.02 | 70.92 |
| 4 | 5 | 5 | 29.21 | 69.78 |
| 5 | 5 | 5 | 28.57 | 68.36 |
| 6 | 6 | 6 | 26.31 | 66.43 |
4.4 Ablation Studies
We present detailed ablation studies of Occupancy Prediction on Occ3D-nuScenes and LiDAR segmentation on the validation sets of nuScenes respectively.
Ablation for Sampling Points
Our framework relies on the quality of mapping matrices. The sampling point setting is essential for constructing our initial reference points. As shown in Table 4, we perform analysis on different numbers of points settings on each voxel. N ip , i ∈ {x, y, z} denotes the number of points sampled along i-axis in a voxel. We can conclude that the sparse point setting like N ip = 3 causes a worse result because sparse points are struggling to capture scene semantics. Meanwhile, too dense point setting like N ip = 6 leads to significant performance degradation because the diversity of the mapping relationship has approached its limit, which brings more noise confusing our model. N ip = 4 can strike the right balance between projecting appropriate image semantics and sampling noise, which prevents our model from overfitting catastrophe.
| M ˆX ˆ Y r | M ˆ Y Z r | M ˆXZ r | Occ. mIoU | LiDAR Seg. mIoU |
|---|---|---|---|---|
| - | - | - | 26.04 | 65.21 |
| � | - | - | 27.98 | 67.87 |
| - | � | - | 27.34 | 66.89 |
| - | - | � | 27.82 | 66.21 |
| � | � | - | 29.25 | 70.13 |
| � | - | � | 28.44 | 70.68 |
| - | � | � | 27.23 | 69.14 |
| � | � | � | 29.10 | 70.87 |
Ablation for Strategy Optimization
OTOcc presents a coarse-to-fine semantic conversion strategy. We compare different settings of the iteration number T, optimization object Mr choice of each ˆv and sensitive parameter λ in Sinkhorn-Knopp Iteration for exploring their impact on semantic conversion.
Mapping Matrices Optimization. As shown in Table 5, we can conclude that if we don't optimize any mapping matrices and directly utilize the coarse Mr for semantic conversion, it leads to serious performance degradation (like 3.06% decrease in occupancy prediction). Even though, it still demonstrates strong prediction accuracy compared to BEVFormer, thanks to the superiority of MPV features representation. Then, we find that compared with optimizing other plane features, optimizing the top plane M ˆXˆ Y r can significantly enhance the semantic representation of 3D scenes, benefiting from its comprehensive spatial information representation. Sinkhorn-Knopp Iteration Setting. As shown in Table 6, we observe that a higher λ (λ = 1) setting compromises the model performance, which focuses on the loss of a single plane is inconsistent with the loss optimization direction of the overall calculation of 3D voxels. Then, higher T will bring better performance, but also increase the computational cost. Like T = 30, the Sinkhorn-Knopp Iteration can bring more than 1.00% mIoU gains on occupancy prediction or 3.20% mIoU gains on LiDAR segmentation compared to T = 0, while the training time increases by more than 16% due to the large scale optimization. When T = 50, performance on two benchmarks generally decreases caused of the optimization limits from the Sinkhorn-Knopp Iteration. To balance the computational cost and prediction performance, we set the T to 40 and λ to 0.2.
| T | Time | λ | Occ. mIoU | LiDAR Seg. mIoU |
|---|---|---|---|---|
| 0 | 1.207s | 0 | 26.04 | 65.21 |
| 30 | 1.427s | 1.0 0.5 0.2 | 27.04 27.67 28.13 | 68.41 68.29 69.43 |
| 40 | 1.545s | 1.0 0.5 0.2 | 28.43 28.97 29.10 | 69.54 70.05 70.87 |
| 50 | 1.682s | 1.0 0.5 0.2 | 27.62 29.21 28.65 | 69.31 69.64 70.12 |
4.5 Qualitative Results
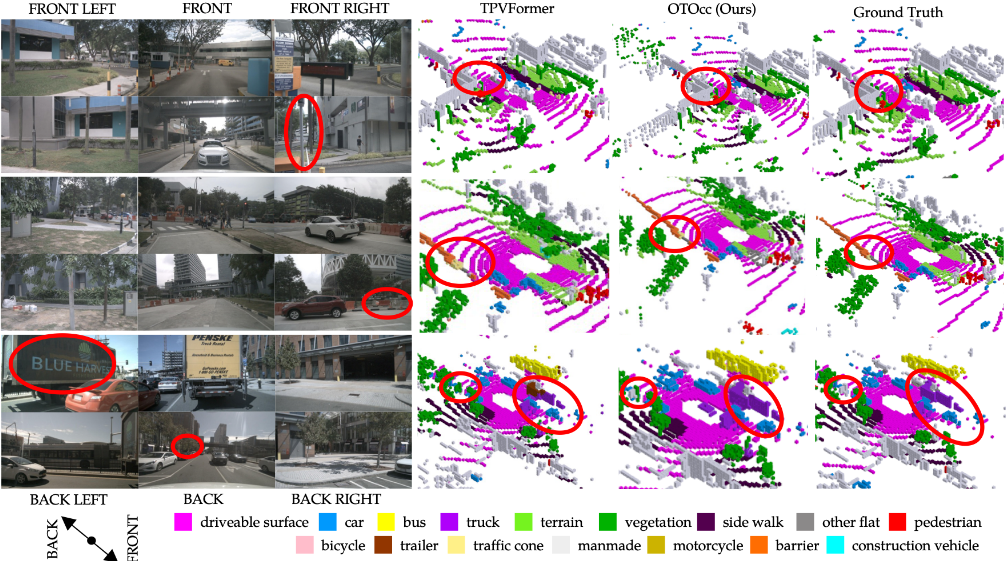
We present the comparisons of LiDAR segmentation results among TPVFormer, OTOcc and ground truth, which are shown in Figure 4. OTOcc can reduce class errors in LiDAR segmentation, such as the truck in the third row while TPVFormer classifies it as a trailer. We also observe that OTOcc has a better perception of small and blurry objects like the less occupied traffic cone in the second row or the manmade in the third row, demonstrating the advantages of finding the optimal semantic transport strategy for significant prediction.
5 Discussion
Motivation. From another perspective, calculating the optimal semantic conversion strategy is equivalent to performing auxiliary task learning, not limited to occupancy prediction. OTOcc utilizes transportation loss to calibrate the MPV feature semantics, thereby providing a guarantee for building accurate voxel representation.
Limitation. We admit that the deformable attention [Zhu et al., 2020] mechanism has a better computation speed than OT-based methods no matter from theoretical derivation or experiments as shown in the speed comparison results with PanoOcc from Table 3. However, it only samples several points on key, which easily aggregates semantics within a certain range leading to the slower convergence. In future works, we will investigate more efficient methods in OTbased deeply. After that, the Sinkhorn Iteration still brings the high training time cost and the instability prediction performance, easily leading to the cherry picking. Then, OTOcc only uses a lightweight decoder to explore the effectiveness of applying OT methods, which motivates us to design a more powerful decoder for accurate occupancy prediction.
6 Conclusion
In this paper, we propose a novel framework named OTOcc --Optimal Transport for Occupancy Prediction. It represents the semantic conversion from 2D images to 3D voxels as the Optimal Transport problem, which breaks the barrier of existing approaches relying on attention or depth estimation to collect information in sparse semantic scenes. It generates initial mapping matrices from the designed dense reference points, which are refined via Sinkhorn-Knopp Iteration to seek the best semantic conversion strategy. Then, it adopts an Adaptive Fusion Decoder for obtaining accurate voxel representation. Extensive experiments on two benchmarks show the effectiveness of our proposed method.
Acknowledgments
This work is supported in part by the National Natural Science Foundation of China (NSFC) under Grants 62271324, 62231020, 62371309 and 61976142, Shenzhen Science and Technology Program under Grant ZDSYS20220527171400002 and the Hetao ShenzhenHongKong Science and Technology Innovation Cooperation Zone (HZQB-KCZYZ-2021055). This work is also funded by Shenzhen Deeproute.ai Co., Ltd.
@inproceedings{ijcai2024p112,
  title     = {OTOcc: Optimal Transport for Occupancy Prediction},
  author    = {Li, Pengteng and He, Ying and Yu, F. Richard and Song, Pinhao and Zhou, Xingchen and Zhou, Guang},
  booktitle = {Proceedings of the Thirty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-24}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Kate Larson},
  pages     = {1010--1019},
  year      = {2024},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2024/112},
  url       = {https://doi.org/10.24963/ijcai.2024/112},
}
TY - CPAPER TI - OTOcc: Optimal Transport for Occupancy Prediction AU - Li, Pengteng AU - He, Ying AU - Yu, F. Richard AU - Song, Pinhao AU - Zhou, Xingchen AU - Zhou, Guang T2 - Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, IJCAI-24 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2024 SP - 1010 EP - 1019 DO - 10.24963/ijcai.2024/112 UR - https://doi.org/10.24963/ijcai.2024/112 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





