
Learning from Long-Tailed Noisy Data with Sample Selection and Balanced Loss
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence. Main Track. Pages 5471-5480.
https://doi.org/10.24963/ijcai.2024/605
Keywords
- Machine Learning: ML: Classification
Abstract
The success of deep learning depends on large-scale and well-curated training data, while data in real-world applications are commonly long-tailed and noisy. Existing methods are usually dependent on label frequency to tackle class imbalance, while the model bias on different classes is not directly related to label frequency and the true label frequency is inaccessible under label noise. To solve this, we propose a robust method for learning from long-tailed noisy data with sample selection and balanced loss. Specifically, we separate the noisy training data into clean labeled set and unlabeled set with sample selection, and train the deep neural network in a semi-supervised manner with a balanced loss based on model bias. Extensive experiments on benchmarks demonstrate that our method outperforms existing state-of-the-art methods.
- [Arazo et al., 2019] Eric Arazo, Diego Ortego, Paul Albert, Noel O'Connor, and Kevin Mcguinness. Unsupervised la- bel noise modeling and loss correction. In Proceedings of the 36th International Conference on Machine Learning, pages 312-321, 2019.
- [Arpit et al., 2017] Devansh Arpit, Stanisław Jastrzębski, Nicolas Ballas, David Krueger, Emmanuel Bengio, Maxinder S Kanwal, Tegan Maharaj, Asja Fischer, Aaron Courville, Yoshua Bengio, et al. A closer look at memo- rization in deep networks. In Proceedings of the 34th In- ternational Conference on Machine Learning, pages 233- 242, 2017.
- [Berthelot et al., 2019] David Berthelot, Nicholas Carlini, Ian Goodfellow, Nicolas Papernot, Avital Oliver, and Colin Raffel. Mixmatch: A holistic approach to semi- supervised learning. In Advances in Neural Information Processing Systems 32, pages 5050-5060, 2019.
- [Cao et al., 2019] Kaidi Cao, Colin Wei, Adrien Gaidon, Nikos Arechiga, and Tengyu Ma. Learning imbalanced datasets with label-distribution-aware margin loss. In Advances in Neural Information Processing Systems 32, pages 1567-1578, 2019.
- [Cao et al., 2021] Kaidi Cao, Yining Chen, Junwei Lu, Nikos Aréchiga, Adrien Gaidon, and Tengyu Ma. Het- eroskedastic and imbalanced deep learning with adaptive regularization. In Proceedings of the 9th International Conference on Learning Representations, 2021.
- [Cubuk et al., 2020] Ekin D Cubuk, Barret Zoph, Jonathon Shlens, and Quoc V Le. Randaugment: Practical auto- mated data augmentation with a reduced search space. In Proceedings of the 2020 IEEE Conference on Computer Vision and Pattern Recognition Workshops, pages 702- 703, 2020.
- [Cui et al., 2019] Yin Cui, Menglin Jia, Tsung-Yi Lin, Yang Song, and Serge Belongie. Class-balanced loss based on effective number of samples. In Proceedings of the 2019 IEEE Conference on Computer Vision and Pattern Recog- nition, pages 9268-9277, 2019.
- [Fang et al., 2023] Chaowei Fang, Lechao Cheng, Yining Mao, Dingwen Zhang, Yixiang Fang, Guanbin Li, Huiyan Qi, and Licheng Jiao. Separating noisy samples from tail classes for long-tailed image classification with label noise. IEEE Transactions on Neural Networks and Learn- ing Systems, 2023.
- [Ghosh et al., 2017] Aritra Ghosh, Himanshu Kumar, and P. S. Sastry. Robust loss functions under label noise for deep neural networks. In Proceedings of the 31st AAAI Conference on Artificial Intelligence, pages 1919-1925, 2017.
- [Gui et al., 2021] Xian-Jin Gui, Wei Wang, and Zhang-Hao Tian. Towards understanding deep learning from noisy la- bels with small-loss criterion. In Proceedings of the 30th International Joint Conference on Artificial Intelligence, pages 2469-2475, 2021. IJCAI
- [Han et al., 2018] Bo Han, Quanming Yao, Xingrui Yu, Gang Niu, Miao Xu, Weihua Hu, Ivor W. Tsang, and Masashi Sugiyama. Co-teaching: Robust training of deep neural networks with extremely noisy labels. In Advances in Neural Information Processing Systems 31, pages 8536-8546, 2018.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition, pages 770-778, 2016.
- [Jeatrakul et al., 2010] Piyasak Jeatrakul, Kok Wai Wong, and Chun Che Fung. Classification of imbalanced data by combining the complementary neural network and smote algorithm. In Proceedings of the 17th International Con- ference on Neural Information Processing, pages 152- 159, 2010.
- [Jiang et al., 2020] Lu Jiang, Di Huang, Mason Liu, and Weilong Yang. Beyond synthetic noise: Deep learning on controlled noisy labels. In Proceedings of the 37th Inter- national Conference on Machine Learning, pages 4804- 4815, 2020.
- [Jiang et al., 2021] Shenwang Jiang, Jianan Li, Ying Wang, Bo Huang, Zhang Zhang, and Tingfa Xu. Delving into sample loss curve to embrace noisy and imbalanced data. arXiv, 2021.
- [Kang et al., 2019] Bingyi Kang, Saining Xie, Marcus Rohrbach, Zhicheng Yan, Albert Gordo, Jiashi Feng, and Yannis Kalantidis. Decoupling representation and classi- fier for long-tailed recognition. arXiv, 2019.
- [Kang et al., 2021] Bingyi Kang, Yu Li, Zehuan Yuan, and Jiashi Feng. Exploring balanced feature spaces for repre- sentation learning. In Proceedings of the 9th International Conference on Learning Representations, 2021.
- [Karthik et al., 2021] Shyamgopal Karthik, Jérome Revaud, and Boris Chidlovskii. Learning from long-tailed data with noisy labels. arXiv, 2021.
- [Kim et al., 2020] Jaehyung Kim, Youngbum Hur, Sejun Park, Eunho Yang, Sung Ju Hwang, and Jinwoo Shin. Dis- tribution aligning refinery of pseudo-label for imbalanced semi-supervised learning. In Advances in Neural Informa- tion Processing Systems 33, pages 14567-14579, 2020.
- [Krizhevsky et al., 2009] Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny im- ages. Master's thesis, University of Toronto, 2009.
- [Laine and Aila, 2017] Samuli Laine and Timo Aila. Tem- poral ensembling for semi-supervised learning. In Pro- ceedings of the 5th International Conference on Learning Representations, 2017.
- [Lee et al., 2018] Kuang-Huei Lee, Xiaodong He, Lei Zhang, and Linjun Yang. Cleannet: Transfer learning for scalable image classifier training with label noise. In Pro- ceedings of the 2018 IEEE Conference on Computer Vi- sion and Pattern Recognition, pages 5447-5456, 2018.
- [Lee et al., 2021] Hyuck Lee, Seungjae Shin, and Heey- oung Kim. Abc: Auxiliary balanced classifier for class- imbalanced semi-supervised learning. In Advances in Neu- ral Information Processing Systems 34, pages 7082-7094, 2021.
- [Li et al., 2017] Wen Li, Limin Wang, Wei Li, Eirikur Agustsson, and Luc V. Gool. Webvision database: Visual learning and understanding from web data. arXiv, 2017.
- [Li et al., 2020] Junnan Li, Richard Socher, and Steven C. H. Hoi. Dividemix: Learning with noisy labels as semi- supervised learning. In Proceedings of the 8th Interna- tional Conference on Learning Representations, 2020.
- [Lin et al., 2014] Tsung-Yi Lin, Michael Maire, Serge Be- longie, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C Lawrence Zitnick. Microsoft coco: Com- mon objects in context. In Proceedings of the 13th Eu- ropean Conference on Computer Vision, pages 740-755, 2014.
- [Liu et al., 2019] Ziwei Liu, Zhongqi Miao, Xiaohang Zhan, Jiayun Wang, Boqing Gong, and Stella X Yu. Large-scale long-tailed recognition in an open world. In Proceedings of the 2019 IEEE Conference on Computer Vision and Pat- tern Recognition, 2019.
- [Liu et al., 2020] Sheng Liu, Jonathan Niles-Weed, Narges Razavian, and Carlos Fernandez-Granda. Early-learning regularization prevents memorization of noisy labels. In Advances in Neural Information Processing Systems 33, pages 20331-20342, 2020.
- [Lu et al., 2023] Yang Lu, Yiliang Zhang, Bo Han, Yiu-ming Cheung, and Hanzi Wang. Label-noise learning with in- trinsically long-tailed data. In Proceedings of the 19th In- ternational Conference on Computer Vision, pages 1369- 1378, 2023.
- [Menon et al., 2021] Aditya Krishna Menon, Sadeep Jaya- sumana, Ankit Singh Rawat, Himanshu Jain, Andreas Veit, and Sanjiv Kumar. Long-tail learning via logit adjust- ment. In Proceedings of the 9th International Conference on Learning Representations, 2021.
- [Patrini et al., 2017] Giorgio Patrini, Alessandro Rozza, Aditya K. Menon, Richard Nock, and Lizhen Qu. Making deep neural networks robust to label noise: A loss correc- tion approach. In Proceedings of the 2017 IEEE Confer- ence on Computer Vision and Pattern Recognition, pages 2233-2241, 2017.
- [Qi and Chelmis, 2023] Wenting Qi and Charalampos Chelmis. Noisy label detection and counterfactual correction. IEEE Transactions on Artificial Intelligence, 2023.
- [Russakovsky et al., 2015] Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, Michael Bernstein, et al. Imagenet large scale visual recogni- tion challenge. International Journal of Computer Vision, pages 211-252, 2015.
- [Shu et al., 2019] Jun Shu, Qi Xie, Lixuan Yi, Qian Zhao, Sanping Zhou, Zongben Xu, and Deyu Meng. Meta- weight-net: Learning an explicit mapping for sample weighting. In Advances in Neural Information Processing Systems 32, pages 1919-1930, 2019.
- [Song et al., 2019] Hwanjun Song, Minseok Kim, and Jae- Gil Lee. Selfie: Refurbishing unclean samples for ro- bust deep learning. In Proceedings of the 36th Inter- national Conference on Machine Learning, pages 5907- 5915, 2019.
- [Song et al., 2022] Hwanjun Song, Minseok Kim, Dongmin Park, Yooju Shin, and Jae-Gil Lee. Learning from noisy labels with deep neural networks: A survey. IEEE Trans- actions on Neural Networks and Learning Systems, 2022.
- [Tanaka et al., 2018] Daiki Tanaka, Daiki Ikami, Toshihiko Yamasaki, and Kiyoharu Aizawa. Joint optimization framework for learning with noisy labels. In Proceedings of the 2018 IEEE Conference on Computer Vision and Pat- tern Recognition, pages 5552-5560, 2018.
- [Xiao et al., 2015] Tong Xiao, Tian Xia, Yi Yang, Chang Huang, and Xiaogang Wang. Learning from massive noisy labeled data for image classification. In Proceedings of the 2015 IEEE Conference on Computer Vision and Pattern Recognition, pages 2691-2699, 2015.
- [Yi and Wu, 2019] Kun Yi and Jianxin Wu. Probabilistic end-to-end noise correction for learning with noisy labels. In Proceedings of the 2019 IEEE Conference on Computer Vision and Pattern Recognition, pages 7017-7025, 2019.
- [Yi et al., 2022] Xuanyu Yi, Kaihua Tang, Xian-Sheng Hua, Joo-Hwee Lim, and Hanwang Zhang. Identifying hard noise in long-tailed sample distribution. In Proceedings of the 17th European Conference on Computer Vision, pages 739-756, 2022.
- [Zhang and Pfister, 2021] Zizhao Zhang and Tomas Pfister. Learning fast sample re-weighting without reward data. In Proceedings of the 18th International Conference on Com- puter Vision, pages 725-734, 2021.
- [Zhang et al., 2021] Chiyuan Zhang, Samy Bengio, Moritz Hardt, Benjamin Recht, and Oriol Vinyals. Understand- ing deep learning (still) requires rethinking generalization. Communications of the ACM, 64(3):107-115, 2021.
- [Zhao et al., 2023] Qihao Zhao, Fan Zhang, Wei Hu, Songhe Feng, and Jun Liu. Ohd: An online category-aware frame- work for learning with noisy labels under long-tailed dis- tribution. IEEE Transactions on Circuits and Systems for Video Technology, 2023.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Deep neural networks have made great successes in machine learning applications [He et al., 2016] but require wellcurated data for training. These data, such as ImageNet [Russakovsky et al., 2015] and MS-COCO [Lin et al., 2014], are usually artificially balanced across classes with clean labels obtained by manual labeling, which is costly and timeconsuming. However, the data in real-world applications are long-tailed and noisy, since data from specific classes are difficult to acquire and labels are usually collected without expert annotations. To take WebVision dataset as an example, it exhibits long-tailed distribution, where the sample size of each class varies from 362 (Windsor tie) to 11,129 (ashcan), and contains about 20% noisy labels [Li et al., 2017]. Thus,
is a great challenge.
Many methods have been proposed for long-tailed learning or learning with noisy labels. In terms of long-tailed learning, re-sampling methods [Jeatrakul et al., 2010], reweighting methods [Cui et al., 2019; Cao et al., 2019; Menon et al., 2021], transfer learning methods [Liu et al., 2019] and two-stage methods [Kang et al., 2019; Cao et al., 2019] are included; in terms of learning with noisy labels, designing noise-robust loss functions [Ghosh et al., 2017], constructing unbiased loss terms with the transition matrix [Patrini et al., 2017], filtering clean samples based on smallloss criterion [Han et al., 2018; Li et al., 2020] and correcting the noisy labels [Tanaka et al., 2018; Yi and Wu, 2019] are included. Despite learning from long-tailed or noisy data has been well studied, these methods cannot tackle long-tailed noisy data in real-world applications. A few methods are proposed to deal with long-tailed noisy data [Karthik et al., 2021; Yi et al., 2022; Fang et al., 2023; Zhao et al., 2023], which count on observed label frequency to handle class imbalance. Nevertheless, the model bias on different classes is not merely relevant to label frequency and the true frequency is unavailable owing to label noise.
To deal with long-tailed noisy data, an intuitive way is to select clean samples with small-loss criterion and then apply long-tailed learning methods. For the sample selection process, [Gui et al., 2021] revealed that the losses of samples with different labels are incomparable and chose each class a threshold for applying the small-loss criterion. For long-tailed learning, existing methods are commonly based on label frequency to prevent head classes from dominating the training process. However, it is shown that the model bias on different classes may not be directly related to label frequency (see Appendix 1 E), and the true label frequency is also unknown under label noise. In this paper, we propose a robust method for learning from long-tailed noisy data. Specifically, we separate the noisy training data into clean labeled set and unlabeled set with class-aware sample selection and then train the model with a balanced loss based on model bias in a semi-supervised manner. Experiments on the long-tailed versions of CIFAR-10 and CIFAR-100 with synthetic noise and the long-tailed versions of mini-ImageNet-Red, Clothing1M, Food-101N, Animal-10N and WebVision with realworld noise demonstrate the superiority of our method.
2 RelatedWork
Learning from Long-Tailed Data. The purpose of longtailed learning is to alleviate the performance degradation caused by the small sample sizes of tail classes. Popular methods include re-sampling/re-weighting methods which commonly simulate a balanced training set by paying more attention to tail classes [Jeatrakul et al., 2010; Cui et al.,
1 The appendix is available at https://arxiv.org/abs/2211.10906
2019], transfer learning methods which boost the recognition performance on tail classes by utilizing the knowledge learned from head classes [Liu et al., 2019] and twostage methods which argue that decoupling the representation learning and the classifier learning leads to better performance [Kang et al., 2019]. Recently, a new line of works are proposed, which utilize the contrastive learning to learn a class-balanced feature space and further achieve better longtailed learning performance [Kang et al., 2021].
Learning from Noisy Data. The purpose of learning from noisy data is to achieve good generalization capability in the presence of noisy labels [Song et al., 2022]. Works proposed to address the problem of learning with noisy labels can be divided into three categories: 1) methods based on robust loss [Ghosh et al., 2017], 2) methods based on loss correction [Patrini et al., 2017] and 3) methods based on noise cleansing [Han et al., 2018; Tanaka et al., 2018; Yi and Wu, 2019]. According to whether remove or correct the noisy labels, the third category can be further divided into sample selection methods and label correction methods. Sample selection methods try to identify clean samples, which are commonly based on small-loss criterion [Han et al., 2018; Gui et al., 2021]. Label correction methods try to improve the quality of raw labels [Tanaka et al., 2018; Yi and Wu, 2019]. Sample selection can also be combined with label correction, e.g., DivideMix [Li et al., 2020] conducts sample selection via a two-component gaussian mixture model and then applies the semi-supervised learning technique MixMatch with label correction, NDCC [Qi and Chelmis, 2023] automatically chooses a loss value threshold for sample selection and uses counterfactual learning to correct the noisy labels.
Learning from Long-Tailed Noisy Data. Methods designed for learning from long-tailed noisy data are under-explored. [Shu et al., 2019] and [Jiang et al., 2021] learned a weighting function from training data in a meta-learning manner, which can be applied to deal with long-tailed noisy data, yet these methods require extra unbiased meta-data. [Zhang and Pfister, 2021] used a dictionary to store valuable training samples as a proxy of meta-data. These meta-learning methods attempt to learn a weighting function mapping training loss into sample weight and assign large weights to clean samples and tail samples. Nevertheless, in the learning process, clean samples usually have small losses and tail samples usually have large losses. [Cao et al., 2021] proposed a heteroskedastic adaptive regularization, which regularizes different regions of input space differently. However, they assigned the same regularization strength to samples with the same observed label without considering label noise, which made the method sensitive to noisy data. [Karthik et al., 2021] followed a twostage training approach by using self-supervised learning to train an unbiased feature extractor and fine-tuning with an appropriate loss. [Yi et al., 2022] proposed an iterative framework H2E, which first trains a noise identifier invariant to the class and context distributional change and then learns a robust classifier. These methods use the observed class distribution to handle class imbalance, while in real-world applications the class distribution is inaccessible under label noise. [Lu et al., 2023] devised the two-stage bi-dimensional sam-
Procedure 1 Class-Aware Sample Selection (CASS)
Require: Parameter of model θ, training data (X, Y).
- 1: for c = 1 to C do
- 2: Draw ˜Dc = {(xi, ˜ yi)|(xi, ˜ yi) ∈ (X, Y) ∧ ˜ yi = c} from ˜D = (X , Y)
- 3: Wc=GMM({SoftmaxCE(xi, ˜ yi; θ)|(xi, ˜ yi) ∈ ˜Dc})
- 4: Lc = {(xi, ˜ yi)|(xi, ˜ yi, wi) ∈ ( ˜Dc,Wc) ∧ wi > 1 2 }
- 5: Uc = {xi|(xi, ˜ yi, wi) ∈ ( ˜Dc,Wc) ∧ wi ≤ 1 2 }
- 6: end for
Ensure: L = ∪Ci=1Li, U = ∪Ci=1Ui.
ple selection and then trained the model in a semi-supervised manner. However, they did not consider long-tailed distribution in the semi-supervised learning process. [Fang et al., 2023] proposed a cross-augmentation matching criterion and a regularization to detect the noisy samples and eliminate their effects, then a penalization term based on confidence level was used for rebalancing, where the estimation of confidence level was still influenced by the corrupted label frequency. [Zhao et al., 2023] adopted sample selection with harmonizing factor strategy and dynamic cost-sensitive learning based on the estimated clean sample frequency of each class. Nevertheless, the estimation of clean sample frequency may not be accurate and the selected noisy samples were not used in the following process. Generally, most existing methods depend on label frequency to deal with long-tailed distribution, while the model bias on different classes is not solely related to label frequency and the observed frequency is corrupted due to label noise.
3 Methodology
Let X denote the instance space, for each x ∈ X , there exists a true label y ∈ Y = {1, . . . ,C}, where C is the number of classes. Let ˜D = {(x1, ˜ y1), . . . , (xN, ˜ yN)} denote the training data, where xi ∈ X, ˜ yi ∈ Y is the observed label of xi that may be corrupted and N is the number of training samples. In real-world applications, the data may follow a long-tailed distribution. Let ˜Dc = {(xi, ˜ yi)|(xi, ˜ yi) ∈ ˜D ∧ ˜ yi = c} and nc = | ˜Dc|. Without loss of generality, the classes are sorted by their cardinalities nc in the decreasing order, i.e., n1 > n2 > · · · > nC, and the imbalance ratio ρ = n1/nC. The deep neural network f(·; θ) : X → RC is learned from the long-tailed and noisy data ˜D, where θ represents the model parameter. Given x ∈ X, the network outputs f(x; θ) = [f1(x; θ), . . . , fC(x; θ)]T and fi(x; θ) represents the output logit of class i, we omit the model parameter θ and denote f(x; θ) as f(x) for brevity. Let pimodel (x) = exp(fi(x)) ∑Cj=1 exp(fj(x)) , the classifier induced by f is ϕf(x) = argmaxi∈{1,...,C} pimodel (x). For (x, ˜ y), the loss is calculated as ℓ(f(x), ˜ y) with a loss function ℓ(·, ·). The empirical loss of f on ˜D is 1N ∑Ni=1 ℓ(f(xi), ˜ yi). We focus on learning the optimal model parameter θ∗ which minimizes the expected loss, i.e., θ∗ = argminθ E(x,y)[ℓ(f(x; θ), y)].
The training data in real-world applications usually contain noisy labels, while deep neural networks are generally learned by minimizing the empirical risk on the training data. [Zhang et al., 2021] demonstrated that noisy labels can be easily fitted by deep neural networks, which harms the generalization of the neural networks. In order to alleviate the effect of noisy labels, we adopt the popular strategy which first warms up the model and then selects clean samples with small-loss criterion [Han et al., 2018; Li et al., 2020]. Since the training data are long-tailed in real-world applications, we introduce a regularization term Lreg in the warm up process to prevent the model from being influenced by the long-tailed distribution:
where πi = 1C . Lreg forces the model's average output on all classes to be the uniform distribution. Considering that head classes have more samples and the calculation of the model's average output may be biased, we conduct the calculation in a class-balanced manner by assigning a weight 1 nj to samples from class j. We pay more attention to tail classes by assigning a regularization strength nC ni to class i, which guarantees a decent performance on tail classes. During warming up, hyper-parameter λwarm controls the strength of Lreg:
where LCE denotes the cross-entropy loss.
After warming up, small-loss criterion can be used to select small-loss samples as clean ones following [Arpit et al., 2017]. Recently, [Gui et al., 2021] revealed that the losses of samples with different labels may not be comparable and proposed to select samples class by class accordingly. They set each class a threshold based on the noise rate. Unfortunately, each class's noise rate is unknown in practice. Instead, we adopt a two-component (g1 and g0) Gaussian Mixture Model (GMM) for each class in the sample selection process to fit the loss as that in [Arazo et al., 2019] and [Li et al., 2020], where g1 represents the clean distribution and g0 represents the noisy distribution. For class i, let L( ˜Di) denote the samples' cross-entropy loss, and it reflects how well the model fits the training samples:
A two-component GMM can be fitted with respect to L( ˜Di), and the clean probability of a sample (xj, ˜ yj ) is given by its posterior probability of belonging to g1 P(g1|L( ˜Di), (xj, ˜ yj)). The sample with clean probability P(g1|L( ˜Di), (xj, ˜ yj)) > 1/2 is selected as clean; otherwise, the sample is regarded as noisy. We determine whether a sample is clean according to the posterior probability, so we choose 1/2 as the threshold. Here, we do not need to know the proportion of clean samples which depends on the inaccessible noise rate. In this way, the clean labeled set L can be selected from the training data ˜D, and an unlabeled set
.
U = {xi|(xi, ˜ yi) ∈ ˜D\L} is constructed. This class-aware sample selection is described in Procedure 1. We further plot the loss distributions of different classes in order to demonstrate that the distributions follow the two-component GMM (see Appendix C for details).
With clean labeled samples L and unlabeled samples U, the widely-used semi-supervised learning method MixMatch [Berthelot et al., 2019] can be adopted to learn the model. MixMatch uses the learned model to generate pseudo labels for U, applies MixUp to transform L and U into L′ and U ′ with soft labels q ∈ [0, 1]C and then utilizes the cross-entropy loss and the mean squared error on L′ and U ′ respectively:
In Eq. (2) of MixMatch, training with long-tailed data leads to model bias, and the model with bias prefers to predict head classes and has a poor performance on tail classes. This motivates us to develop a loss to correct the model bias. That is, we introduce αij into L(x, q) in Eq. (2):
Specifically, for a pair of classes (i, j), if the learned model prefers class j, then a weight αij > 1 is assigned to exp(fj(x)) exp(fi(x)) for samples from class i to suppress class j, and a weight αji < 1 is assigned to exp(fi(x)) exp(fj(x)) for samples from class j to relax class i. Many methods use label frequency as the estimation of model bias in long-tailed learning [Cui et al., 2019; Menon et al., 2021]. However, the model bias on different classes is not directly related to label frequency (see Appendix E), and the true label frequency is also unknown under label noise. To characterize the model bias, we calculate the matrix M ∈ RC×C before each training epoch, where the entry Mij represents the probability that the learned model predicts a sample from class i to class j. For epoch t, M t ij = 1 |Li | ∑(x, ˜ y)∈Li pj,t model (x), where Li = {(x, ˜ y)|(x, ˜ y) ∈ L ∧ ˜ y = i}. Inspired by [Laine and Aila, 2017], we further temporally average the calculated matrices for a stable estimation of model bias with Exponentially Moving Average (EMA) and obtain the averaged model bias matrix ¯M, i.e., ¯M t = σ ¯M t-1 + (1 - σ)M t , where σ controls the contribution of the estimated matrix from each epoch. If ¯Mij is
Require: Deep neural network f(·; θ), training data (X, Y), total training epochs T, model bias estimation epochs E, unsupervised loss weight λu, regularization term weight λreg, hyper-paramter of EMA σ. 1: θ =WarmUp(X, Y, θ) ▷ training with Eq. (1) 2: Fill ¯M ∈ RC×C with zeros 3: while e < E do 4: Fill M e ∈ RC×C with zeros 5: (L, U) = CASS(X , Y, θ) ▷ apply Procedure 1 6: for iter = 1 to num_iters do 7: Draw a mini-batch LB = {(xb, ˜ yb)|b ∈ {1, ..., B}} from L 8: Draw a mini-batch UB = {ub|b ∈ {1, ..., B}} from U 9: for c = 1 to C do 10: Draw LB,c = {(x, ˜ y)|(x, ˜ y) ∈ LB ∧ ˜ y = c} from LB 11: M e c =M e c + ∑(x,˜ y)∈LB,c Softmax(f(x; θ)) ▷ update the c-th row of M e 12: end for 13: (L′ , U ′ ) = MixMatch(LB, UB) ▷ apply MixMatch with augmented LB and UB 14: LL, LU = SoftmaxCE(L′ ; θ), SoftmaxMSE(U ′ ; θ) 15: L = LL + λuLU + λregLreg 16: θ = SGD(L, θ) ▷ update the parameters of f(·; θ) with Stochastic Gradient Descent 17: end for 18: Normalize M e 19: ¯M = σ ¯M + (1 - σ)M e ▷ update the model bias matrix ¯M 20: end while 21: Rij = ¯Mij ¯Mji , R ∈ RC×C ▷ compute R 22: while e < T do 23: (L, U) = CASS(X , Y, θ) ▷ apply Procedure 1 24: for iter = 1 to num_iters do 25: Draw a mini-batch LB = {(xb, ˜ yb)|b ∈ {1, ..., B}} from L 26: Draw a mini-batch UB = {ub|b ∈ {1, ..., B}} from U 27: (L′ , U ′ ) = MixMatch(LB, UB) ▷ apply MixMatch with augmented LB and UB 28: L′L, LU = Lα(L′ ; θ, R), SoftmaxMSE(U ′ ; θ) 29: L = L′L + λuLU + λregLreg 30: θ = SGD(L, θ) ▷ update the parameters of f(·; θ) with Stochastic Gradient Descent 31: end for 32: end whilelarger than ¯Mji, then the model has a bias to class j. Let Rij = ¯Mij/ ¯Mji, g(·) = γsup · I(Rij > 1)+γrel · I(Rij ≤ 1) and αij = Rg(Rij) ij , where g(·) is a function of Rij in which γsup and γrel are hyper-parameters for controlling the power of suppressing and relaxing respectively. Formally, we have
Since the training data are in long-tailed distribution and there are only a few samples in tail classes, we augment clean labeled samples in L and re-exploit Lreg as a regularization on L′ with its hard labels. Thus, we use the balanced loss L = L′L + λuLU + λregLreg in the training process, where
λu controls the unsupervised loss and λreg controls the regularization term. The whole training process of our SSBL is described in Algorithm 1.
4 Experiment
4.1 Setup
Datasets. We validate our method on seven benchmark datasets, namely CIFAR-10, CIFAR-100 [Krizhevsky et al., 2009], mini-ImageNet-Red [Jiang et al., 2020], Clothing1M [Xiao et al., 2015], Food-101N [Lee et al., 2018], Animal10N [Song et al., 2019] and WebVision [Li et al., 2017]. On CIFAR, we consider two kinds of label noise, i.e., symmetric noise and asymmetric noise. For symmetric noise, we first construct long-tailed versions of CIFAR with different imbalance ratios ρ following [Cui et al., 2019]. In specific, we reduce the sample size per class according to an exponential function ni = Oi 1ρ i-1 C-1 , where Oi is the original sample size of class i, ρ = n1 nC and i ∈ {1, . . . ,C}. Then, we generate symmetric noise in long-tailed CIFAR according to the following noise transition matrix N:
| Dataset | CIFAR-10 | CIFAR-100 | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Noise Rate | 0.2 | 0.5 | 0.2 | 0.5 | |||||||||
| Imbalance Ratio | 10 | 50 | 100 | 10 | 50 | 100 | 10 | 50 | 100 | 10 | 50 | 100 | |
| Best | 76.90 | 65.35 | 60.82 | 65.75 | 48.76 | 39.70 | 45.83 | 35.05 | 29.96 | 28.96 | 19.88 | 16.80 | |
| ERM Last | 73.02 | 61.35 | 54.48 | 45.85 | 33.05 | 28.79 | 45.64 | 34.93 | 29.88 | 24.33 | 17.77 | 14.47 | |
| Co-teaching [Han et al., 2018] Best | 78.50 | 45.86 | 39.59 | 34.60 | 23.58 | 17.45 | 43.81 | 30.58 | 28.08 | 14.58 | 11.62 | 9.69 | |
| Last | 77.51 | 44.91 61.30 | 38.07 60.92 | 31.71 59.10 | 22.57 43.69 | 14.88 36.31 | 43.69 37.31 | 30.22 29.29 | 28.08 26.00 | 14.49 23.22 | 10.54 17.04 | 9.35 12.45 | |
| HAR-DRW [Cao et al., 2021] Best Last | 73.83 71.16 | 60.27 | 56.94 | 40.10 | 34.19 | 35.91 | 36.92 | 29.02 | 25.69 | 19.01 | 14.29 | 11.11 | |
| Best | 83.78 | 67.97 | 50.96 | 71.81 | 38.45 | 27.15 | 51.09 | 37.88 | 33.41 | 31.83 | 18.68 | 14.34 | |
| MW-Net [Shu et al., 2019] Last | 73.25 | 62.63 | 48.01 | 50.02 | 36.14 | 20.90 | 50.24 | 37.75 | 33.24 | 27.72 | 13.61 | 13.20 | |
| Best | 79.40 | 59.49 | 52.80 | 62.03 | 36.29 | 31.79 | 48.66 | 34.86 | 29.26 | 33.38 | 22.92 | 19.15 | |
| H2E [Yi et al., 2022] Last | 78.76 | 52.10 | 49.95 | 43.66 | 33.57 | 31.10 | 48.48 | 34.65 | 28.95 | 33.17 | 19.73 | 14.69 | |
| Best | 91.60 | 86.30 | 79.84 | 88.51 | 77.72 | 72.36 | 62.78 | 51.25 | 45.68 | 55.95 | 42.19 | 36.87 | |
| SSBL Last | 91.49 | 88.17 | 75.76 | 68.44 | 62.45 | 43.89 | 55.65 | 40.82 | 36.49 | ||||
| [Liu 2020] Best | 76.31 | 68.39 | 16.40 | 15.65 | 39.17 | 34.35 | 35.97 | 25.27 | |||||
| Last | 88.34 | 85.83 | 78.39 | 64.61 | 53.11 | 50.70 | 20.49 | ||||||
| ELR+ et al., | 74.62 | 66.60 | 60.30 | 10.03 | 10.03 | 48.95 | 35.20 | 43.71 | 55.98 | 18.78 | 35.03 | ||
| DivideMix [Li et al., 2020] Best | 87.68 91.03 | 83.07 | 70.08 | 85.97 | 69.73 | 52.06 | 63.08 | 49.76 | 31.36 | 22.73 | 41.79 | 16.36 | |
| Last Best | 90.71 91.68 | 82.16 | 69.82 | 85.79 85.84 | 68.19 | 51.72 49.48 | 62.54 | 49.45 53.31 | 42.84 47.52 | 55.56 57.11 | 41.25 | 34.51 | |
| DivideMix-LA Last | 64.33 | 40.21 | 34.73 | ||||||||||
| 91.65 | 85.16 | 80.06 | 56.28 | 64.76 | 40.72 | 35.18 | |||||||
| 84.15 | 78.40 | 85.47 | 54.67 | 46.66 | 52.83 | 46.21 | 56.57 | 42.24 | 36.17 | ||||
| DivideMix-DRW Best | 90.44 89.33 | 84.64 | 80.50 | 85.40 | 73.90 | 47.31 | 63.65 | 50.28 | 45.23 | 56.77 56.58 | 41.61 | 35.74 | |
| Last TABASCO et al., | 82.99 | 80.40 | 84.88 | 72.92 | 45.90 | 63.24 | 50.04 | 44.95 | |||||
| [Lu 2023] Best | 83.67 | 68.43 | 57.82 | 88.01 | 74.15 | 66.12 | - | - | - | - | - | - | |
| Last Best Last | 83.33 92.47 92.25 | 67.29 87.14 86.87 | 56.93 81.98 81.29 | 87.32 89.41 89.09 | 73.38 78.65 76.44 | 64.22 72.96 69.11 | - 65.09 64.60 | - 53.52 53.35 | - 47.87 47.64 | - 57.95 57.80 | - 44.37 43.47 | - 39.49 38.64 | |
| Imbalance Ratio | 10 | 50 | 100 |
|---|---|---|---|
| ERM | 77.45 | 71.01 | 69.00 |
| Co-teaching [Han et al., 2018] | 77.06 | 69.49 | 67.34 |
| HAR-DRW [Cao et al., 2021] | 82.69 | 72.17 | 69.32 |
| MW-Net [Shu et al., 2019] | 81.42 | 72.82 | 68.92 |
| H2E [Yi et al., 2022] | 76.80 | 68.89 | 68.08 |
| SSBL | 87.88 | 72.95 | 70.16 |
| ELR+ [Liu et al., 2020] | 74.09 | 68.33 | 67.04 |
| DivideMix [Li et al., 2020] | 88.07 | 69.19 | 67.46 |
| DivideMix-LA | 83.88 | 72.11 | 66.41 |
| DivideMix-DRW | 81.56 | 71.02 | 69.80 |
| TABASCO [Lu et al., 2023] | 84.86 | 67.26 | 65.50 |
| SSBL2 | 88.83 | 73.96 | 71.43 |
where y denotes the ground truth of x, ˜ y denotes the corrupted label of x and r ∈ [0, 1] denotes the noise rate. We set imbalance ratio to be ρ ∈ {10, 50, 100} and set noise rate to be r ∈ {0.2, 0.5}. In the experiments of learning from long-tailed noisy data, the noise rate is usually lower than 0.5, as that in [Zhang and Pfister, 2021] and [Cao et al., 2021]. For asymmetric noise, we construct step-imbalanced versions of CIFAR-10 with asymmetric noise following [Cao et al., 2021]. In specific, we corrupt semantically-similar classes by exchanging 40% of the labels between 'cat' and 'dog', and by exchanging 40% of the labels between 'truck'
| Noise Rate | 0.2 | 0.5 | ||||
|---|---|---|---|---|---|---|
| Imbalance Ratio | 20 | 50 | 100 | 20 | 50 | 100 |
| Co-teaching [Han et al., 2018] | 22.72 | 20.09 | 17.05 | 17.97 | 14.74 | 13.86 |
| HAR-DRW [Cao et al., 2021] | 29.78 | 25.94 | 23.30 | 24.10 | 21.34 | 19.14 |
| MW-Net [Shu et al., 2019] | 33.56 | 27.74 | 24.46 | 26.72 | 23.10 | 20.82 |
| H2E [Yi et al., 2022] | 26.26 | 24.56 | 20.82 | 25.76 | 20.50 | 17.80 |
| SSBL | 36.02 | 31.38 | 28.20 | 30.04 | 26.36 | 23.98 |
| SSBL+RandAug | 37.52 | 32.54 | 29.54 | 31.14 | 27.94 | 25.34 |
| ELR+ [Liu et al., 2020] | 31.86 | 26.33 | 24.39 | 26.23 | 23.30 | 20.61 |
| DivideMix [Li et al., 2020] | 35.96 | 29.02 | 27.36 | 30.10 | 26.42 | 24.20 |
| DivideMix-LA | 37.36 | 32.12 | 29.66 | 32.34 | 28.12 | 24.78 |
| DivideMix-DRW | 36.56 | 30.14 | 28.48 | 30.64 | 26.62 | 24.34 |
| SSBL2 | 37.92 | 32.90 | 30.74 | 32.84 | 29.06 | 26.26 |
and 'automobile'. Then, we remove samples from the corrupted classes. Here, the imbalance ratio ρ is the sample size ratio between the frequent (and clean) classes and the rare (and noisy) classes. Mini-ImageNet-Red, Clothing1M, Food101N, Animal-10N and WebVision are datasets with realworld noise, so we directly create their long-tailed versions following [Cui et al., 2019]. For mini-ImageNet-Red, Clothing1M, Food-101N and Animal-10N, we set imbalance ratio to be ρ ∈ {20, 50, 100}. For Clothing1M, we randomly select a small balanced subset of Clothing1M following [Yi and Wu, 2019] and construct its long-tailed versions. For WebVision, we train and test on the subset mini WebVision which contains the first 50 classes of WebVision following [Li et al., 2020]. The original imbalance ratio of mini WebVision is approximately 7, we further create long-tailed versions of mini WebVision with ρ ∈ {50, 100} following [Cui et al., 2019].
| Dataset | Clothing1M | Food-101N | Animal-10N | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Imbalance Ratio | 20 | 50 | 100 | 20 | 50 | 100 | 20 | 50 | 100 |
| Co-teaching [Han et al., 2018] | 51.97 | 43.23 | 36.48 | 45.67 | 38.90 | 35.13 | 55.06 | 34.51 | 32.63 |
| HAR-DRW [Cao et al., 2021] | 62.56 | 54.08 | 51.09 | 54.12 | 48.25 | 41.81 | 71.96 | 64.22 | 57.66 |
| MW-Net [Shu et al., 2019] | 60.04 | 57.15 | 51.98 | 56.73 | 47.44 | 41.89 | 74.72 | 64.26 | 53.86 |
| H2E [Yi et al., 2022] | 70.41 | 67.81 | 61.58 | 70.35 | 63.69 | 58.66 | 77.04 | 74.94 | 66.58 |
| SSBL | 71.74 | 69.37 | 66.80 | 72.05 | 66.78 | 61.62 | 80.20 | 75.06 | 69.10 |
| SSBL+RandAug | 71.66 | 71.04 | 67.65 | 74.06 | 68.56 | 64.64 | 81.58 | 78.82 | 71.84 |
| ELR+ [Liu et al., 2020] | 67.46 | 61.24 | 54.83 | 58.56 | 48.98 | 44.05 | 63.37 | 49.28 | 47.53 |
| DivideMix [Li et al., 2020] | 71.38 | 69.27 | 66.63 | 64.02 | 54.65 | 52.57 | 77.64 | 69.74 | 64.72 |
| DivideMix-LA | 71.20 | 70.09 | 67.20 | 71.48 | 63.73 | 59.01 | 78.62 | 74.90 | 66.08 |
| DivideMix-DRW | 71.56 | 69.83 | 66.85 | 64.21 | 53.98 | 53.65 | 79.32 | 74.14 | 66.14 |
| TABASCO [Lu et al., 2023] | - | - | - | - | - | - | 67.38 | 54.46 | 48.94 |
| SSBL2 | 72.41 | 70.76 | 67.91 | 74.39 | 69.06 | 63.67 | 81.20 | 75.84 | 69.36 |
| Imbalance Ratio | Original | 50 | 100 | |||
|---|---|---|---|---|---|---|
| Dataset | WebVision | ImageNet | WebVision | ImageNet | WebVision | ImageNet |
| Co-teaching [Han et al., 2018] | 63.60 (85.20) | 61.50 (84.70) | 43.11 (56.13) | 40.95 (55.69) | 40.42 (52.72) | 37.78 (51.16) |
| HAR-DRW [Cao et al., 2021] | 72.96 (90.12) | 67.12 (89.36) | 58.16 (82.60) | 54.20 (80.80) | 50.24 (78.16) | 47.44 (75.96) |
| MW-Net [Shu et al., 2019] | 71.76 (90.40) | 67.36 (89.08) | 60.12 (84.08) | 55.20 (82.28) | 49.96 (80.04) | 46.84 (77.80) |
| H2E [Yi et al., 2022] | 72.32 (90.84) | 69.24 (91.28) | 57.88 (84.76) | 56.64 (85.04) | 52.04 (81.16) | 49.72 (82.28) |
| SSBL | 76.72 (91.00) | 75.00 (90.92) | 68.32 (87.24) | 64.92 (86.32) | 63.80 (86.12) | 61.00 (86.28) |
| H2E (200 epochs) [Yi et al., 2022] | 78.12 (93.40) | 74.00 (92.28) | 69.20 (90.44) | 65.72 (89.04) | 64.64 (88.56) | 61.68 (86.88) |
| SSBL (200 epochs) | 80.48 (93.16) | 76.56 (92.04) | 72.08 (89.00) | 69.52 (89.04) | 66.60 (88.56) | 63.32 (87.88) |
| SSBL+RandAug (200 epochs) | 81.12 (93.68) | 76.88 (93.72) | 73.08 (90.16) | 70.16 (89.44) | 68.24 (88.92) | 65.08 (89.68) |
| ELR+ [Liu et al., 2020] | 78.21 (91.50) | 73.43 (90.50) | 55.24 (82.65) | 52.98 (80.88) | 51.40 (72.97) | 50.47 (72.52) |
| DivideMix [Li et al., 2020] | 77.68 (92.72) | 75.44 (92.44) | 61.40 (82.12) | 62.08 (82.64) | 54.80 (73.76) | 54.60 (74.96) |
| DivideMix-LA | 77.44 (91.96) | 75.96 (91.24) | 69.80 (88.24) | 68.00 (89.32) | 64.64 (86.44) | 63.04 (86.92) |
| DivideMix-DRW | 78.28 (92.04) | 75.44 (92.56) | 65.20 (81.44) | 65.40 (82.36) | 57.44 (72.76) | 57.76 (73.68) |
| SSBL2 | 78.56 (91.92) | 76.64 (91.92) | 70.40 (88.20) | 69.12 (88.64) | 66.08 (87.20) | 63.20 (87.40) |
Baselines. We compare our method with state-of-the-art label noise learning methods and long-tailed label noise learning methods, including Empirical Risk Minimization (ERM) which trains the model with the cross-entropy loss, Coteaching [Han et al., 2018] which trains two networks simultaneously and updates one network on the data selected by the other with small-loss criterion, ELR+ [Liu et al., 2020] which capitalizes on early learning via regularization, DivideMix [Li et al., 2020] which conducts sample selection via a two-component gaussian mixture model and then applies the semi-supervised learning technique MixMatch with label correction, HAR-DRW [Cao et al., 2021] which regularizes different regions of input space differently to handle heteroskedasticity and imbalance issues simultaneously, MW-Net [Shu et al., 2019] which learns a weighting function in a meta-learning manner to assign each sample a weight, H2E [Yi et al., 2022] which first trains a noise identifier and then learns a robust classifier, DivideMix-LA which combines DivideMix and Logit Adjustment (LA) [Menon et al., 2021], DivideMix-DRW which combines DivideMix and Deferred Re-Weighting (DRW), and TABASCO [Lu et al., 2023] which proposes a two-stage bi-dimensional sample selection and trains the model in a semi-supervised manner. We set the hyper-parameters of the baselines by following their original papers or source codes.
Implementation Details. On CIFAR-10, CIFAR-100, miniImageNet-Red and Animal-10N, we use an 18-layer PreAct ResNet and train for 200 epochs. On Clothing1M and Food101N, we use a ResNet-50 and train for 200 epochs from scratch. On WebVision, we use an Inception-ResNet v2 and train for 100 epochs following [Li et al., 2020]. Since the baseline H2E trains for 200 epochs in its original paper, we also conduct experiments on WebVision with H2E for 200 epochs. On all datasets, γsup is set as 3 and γrel is set as 1 in L′L (refer to Appendix A for more details). The baselines ELR+, DivideMix, DivideMix-LA, DivideMix-DRW and TABASCO are based on two models. We also run our method SSBL twice with random initialization and use the ensemble of two runs for a fair comparison with them. We refer to our method with two models as SSBL2 and also report its performance in Tables 1∼5. For a fair comparison with H2E, which uses strong augmentation technique RandAugment [Cubuk et al., 2020] in training, we also report the performance of SSBL with RandAugment (SSBL+RandAug).
4.2 Evaluation on Benchmarks
Table 1 summarizes the results on long-tailed versions of CIFAR-10 and CIFAR-100 with symmetric noise, and Table 2 summarizes the results on step-imbalanced CIFAR-10 with asymmetric noise by following [Cao et al., 2021]. From these tables, it can be found that SSBL with single model outperforms ERM, Co-teaching, HAR-DRW, MW-Net and H2E under all settings, and SSBL2 with two models outperforms ELR+, DivideMix, DivideMix-LA, DivideMix-DRW and TABASCO under all settings.
| Dataset | CIFAR-100 | ||||||
|---|---|---|---|---|---|---|---|
| Noise Rate | mean | 0.2 | 0.5 | ||||
| Imbalance Ratio | 10 | 50 | 100 | 10 | 50 | 100 | |
| SSBL | 48.33 | 62.45 | 50.70 | 43.89 | 55.65 | 40.82 | 36.49 |
| w/o rebalancing | 44.68 | 60.98 | 46.55 | 40.19 | 53.05 | 36.41 | 30.91 |
| rebalancing with label frequency | 46.59 | 61.99 | 48.86 | 43.14 | 54.32 | 38.30 | 32.95 |
| w/o Lreg in warm up | 47.85 | 61.82 | 49.87 | 43.32 | 54.93 | 41.02 | 36.16 |
| w/o Lreg in the whole process | 36.66 | 61.26 | 14.95 | 12.08 | 55.00 | 40.65 | 36.00 |
| w/o class-aware sample selection | 38.74 | 59.92 | 26.56 | 20.29 | 53.64 | 38.73 | 33.32 |
Tables 3 and 4 summarize the results on long-tailed miniImageNet-Red, Clothing1M, Food-101N and Animal-10N with real-world noise. From these tables, it can be found that SSBL with single model outperforms Co-teaching, HARDRW, MW-Net and H2E under all settings, and its performance can be further boosted with RandAugment. SSBL2 with two models outperforms ELR+, DivideMix, DivideMixLA, DivideMix-DRW and TABASCO under all settings.
Table 5 summarizes the results on original and long-tailed versions of mini WebVision with real-world noise, where we report Top-1 and Top-5 test accuracy on both WebVision and ImageNet following [Li et al., 2020]. From Table 5, it can be found that SSBL with single model outperforms Coteaching, HAR-DRW, MW-Net and H2E in Top-1 test accuracy under all settings, and has the comparable or better performance in Top-5 test accuracy. The performance of SSBL with single model can be further boosted with RandAugment. SSBL2 with two models also outperforms ELR+, DivideMix, DivideMix-LA and DivideMix-DRW in Top-1 test accuracy under all settings, and has the comparable or better performance in Top-5 test accuracy.
4.3 Ablation Study
In order to study the effects of removing components of our method SSBL with single model, we conduct the ablation study on long-tailed versions of CIFAR-100 with symmetric noise and summarize the results in Table 6.
- To study the effect of rebalancing the model bias after having estimated the model bias matrix ¯M, we replace our loss L′L with the cross-entropy loss LL. The decrease in test accuracy suggests that L′L is effective for learning from long-tailed noisy data.
- To study the effect of rebalancing the model bias with the estimated model bias matrix ¯M instead of label frequency, we test the performance of rebalancing with label frequency. The degradation in performance verifies the advantage of tackling long-tailed noisy data with the estimated model bias.
- To study the effect of the regularization term Lreg, we test our method without Lreg in warm up and without
| Noise Rate | 0.2 | 0.5 | |||
|---|---|---|---|---|---|
| Imbalance Ratio | 50 | 100 | 50 | 100 | |
| γsup = 3, γrel = 0 | Best Last | 84.77 82.44 | 79.21 77.00 | 75.58 74.86 | 70.51 66.76 |
| γsup = 3, γrel = 0.5 | Best Last | 85.71 85.01 | 80.73 78.77 | 76.48 75.19 | 71.93 68.12 |
| γsup = 3, γrel = 1 | Best Last | 86.30 85.83 | 79.84 78.39 | 77.72 75.76 | 72.36 68.44 |
| γsup = 3, γrel = 2 | Best Last | 79.72 50.70 | 73.90 41.86 | 79.08 74.54 | 72.79 59.28 |
| γsup = 3, γrel = 3 γsup = 1, γrel = 1 | Best Last | 79.72 46.29 | 73.90 42.03 | 78.73 64.68 | 73.22 60.22 |
| Best Last Best Last | 85.67 85.16 85.43 | 80.39 78.76 | 75.50 73.64 | 69.84 67.99 | |
| γsup = 4, γrel = 1 | Best Last | 85.55 | 77.82 79.60 | 73.39 | 71.56 |
| 85.19 | 80.24 | 76.95 | |||
| 68.78 | |||||
| γsup = 2, γrel = 1 | |||||
| 78.21 | 72.88 | ||||
| 85.55 | 73.08 | 66.27 | 58.26 | ||
Lreg in the whole process. The results imply that Lreg in warm up usually brings better performance and Lreg in the whole process ensures the robustness under extremely long-tailed distribution.
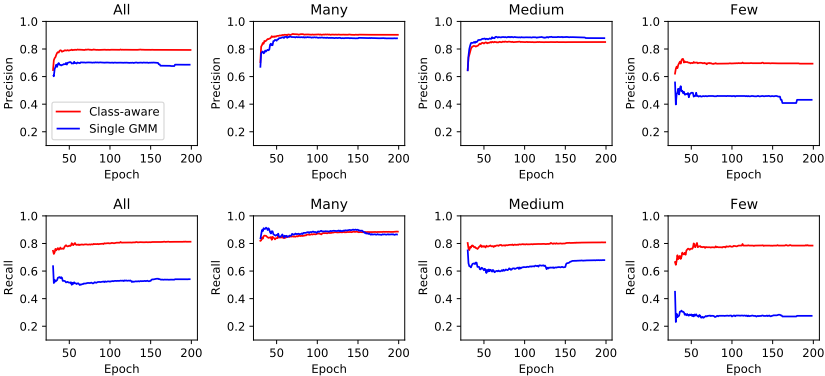
- To study the effect of class-aware sample selection, we replace our class-aware GMM with a single GMM for all classes. The degeneration in performance justifies the superiority of class-aware sample selection over sample selection with single GMM. To further demonstrate that class-aware sample selection is robust to long-tailed noisy data, we visualize the precision and recall of samples selected as clean in Figure 1. In comparison with sample selection with single GMM, our method with class-aware sample selection achieves comparable or better performance in both precision and recall on all splits of classes.
The hyper-parameters γsup and γrel control the power of suppressing and relaxing, respectively. We conduct experiments on both of them on long-tailed versions of CIFAR-10 with symmetric noise and summarize the results in Table 7. γsup = 1 (too little suppression for head classes) or γsup = 4 (too much suppression for head classes) will degrade the performance; γrel = 0 (without any relaxation for tail classes) or γrel > 1 (too much relaxation for tail classes) will harm the performance. In general, γsup = 3 and γrel = 1 is an appropriate choice (see Appendix F for more discussion about other hyper-parameters).
In our method, we separate training data into a clean labeled set L and an unlabeled set U with class-aware sample selection, and then train the model in a semi-supervised manner with our balanced loss. There are other Class-Imbalanced Semi-Supervised Learning (CISSL) methods, e.g., DARP in [Kim et al., 2020] and ABC in [Lee et al., 2021]. We conduct the ablation study with the existing CISSL methods based on our L and U (see Appendix D). The results show that our method performs better than existing CISSL methods.
5 Conclusion
We propose the robust method for learning from long-tailed noisy data with sample selection and balanced loss. In specific, we separate the training data into the clean labeled set and the unlabeled set with class-aware sample selection, and then train the model in a semi-supervised manner with a novel balanced loss. Extensive experiments across benchmarks demonstrate that our method is superior to existing state-of-the-art methods.
Acknowledgments
This work is supported by the National Science Foundation of China (62276125, 61921006), the Fundamental Research Funds for the Central Universities (022114380013), and the Collaborative Innovation Center of Novel Software Technology and Industrialization.
Contribution Statement
Lefan Zhang and Zhang-Hao Tian have equal contribution. Wei Wang is the corresponding author.
@inproceedings{ijcai2024p605,
  title     = {Learning from Long-Tailed Noisy Data with Sample Selection and Balanced Loss},
  author    = {Zhang, Lefan and Tian, Zhang-Hao and Zhou, Wujun and Wang, Wei},
  booktitle = {Proceedings of the Thirty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-24}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Kate Larson},
  pages     = {5471--5480},
  year      = {2024},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2024/605},
  url       = {https://doi.org/10.24963/ijcai.2024/605},
}
TY - CPAPER TI - Learning from Long-Tailed Noisy Data with Sample Selection and Balanced Loss AU - Zhang, Lefan AU - Tian, Zhang-Hao AU - Zhou, Wujun AU - Wang, Wei T2 - Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, IJCAI-24 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2024 SP - 5471 EP - 5480 DO - 10.24963/ijcai.2024/605 UR - https://doi.org/10.24963/ijcai.2024/605 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





