
AdaMixT: Adaptive Weighted Mixture of Multi-Scale Expert Transformers for Time Series Forecasting
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 3633-3641.
https://doi.org/10.24963/ijcai.2025/404
Keywords
- Data Mining: DM: Mining spatial and/or temporal data
Abstract
Multivariate time series forecasting involves predicting future values based on historical observations. However, existing approaches primarily rely on predefined single-scale patches or lack effective mechanisms for multi-scale feature fusion. These limitations hinder them from fully capturing the complex patterns inherent in time series, leading to constrained performance and insufficient generalizability. To address these challenges, we propose a novel architecture named Adaptive Weighted Mixture of Multi-Scale Expert Transformers (AdaMixT). Specifically, AdaMixT introduces various patches and leverages both General Pre-trained Models (GPM) and Domain-specific Models (DSM) for multi-scale feature extraction. To accommodate the heterogeneity of temporal features, AdaMixT incorporates a gating network that dynamically allocates weights among different experts, enabling more accurate predictions through adaptive multi-scale fusion. Comprehensive experiments on eight widely used benchmarks, including Weather, Traffic, Electricity, ILI, and four ETT datasets, consistently demonstrate the effectiveness of AdaMixT in real-world scenarios.
- [Aljundi et al., 2017] Rahaf Aljundi, Punarjay Chakravarty, and Tinne Tuytelaars. Expert gate: Lifelong learning with a network of experts. In IEEE/CVF Computer Vi- sion and Pattern Recognition Conference (CVPR), pages 3366-3375, 2017.
- [Chen et al., 2024] Minxiao Chen, Haitao Yuan, Nan Jiang, Zhifeng Bao, and Shangguang Wang. Urban traffic acci- dent risk prediction revisited: Regionality, proximity, sim- ilarity and sparsity. In ACM International Conference on Information and Knowledge Management (CIKM), pages 281-290, 2024.
- [Chen et al., 2025] Minxiao Chen, Haitao Yuan, Nan Jiang, Zhihan Zheng, Sai Wu, Ao Zhou, and Shangguang Wang. RLOMM: an efficient and robust online map matching framework with reinforcement learning. In ACM SIGMOD International Conference on Management of Data (SIG- MOD), pages 209:1-209:26, 2025.
- [Das and Dutta, 2020] Sourya Dipta Das and Saikat Dutta. Fast deep multi-patch hierarchical network for nonho- mogeneous image dehazing. In IEEE/CVF Computer Vision and Pattern Recognition Conference Workshops (CVPRW), pages 482-483, 2020.
- [Dosovitskiy et al., 2020] Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Min- derer, Georg Heigold, Sylvain Gelly, et al. An image is worth 16x16 words: Transformers for image recognition at scale. arXiv preprint arXiv:2010.11929, 2020.
- [He et al., 2024a] Yuanpeng He, Yali Bi, Lijian Li, Chi-Man Pun, Wenpin Jiao, and Zhi Jin. Mutual evidential deep learning for semi-supervised medical image segmentation. In IEEE InternationalConference onBioinformatics and Biomedicine (BIBM), pages 2010-2017, 2024.
- [He et al., 2024b] Yuanpeng He, Lijian Li, Tianxiang Zhan, Wenpin Jiao, and Chi-Man Pun. Generalized uncertainty- based evidential fusion with hybrid multi-head attention for weak-supervised temporal action localization. In IEEE InternationalConference on Acoustics, Speech and Signal Processing (ICASSP), pages 3855-3859, 2024.
- [Jacobs et al., 1991] Robert A Jacobs, Michael I Jordan, Steven J Nowlan, and Geoffrey E Hinton. Adaptive mix- tures of local experts. Neural Computation, pages 79-87, 1991.
- [Jiang et al., 2024] Nan Jiang, Haitao Yuan, Jianing Si, Minxiao Chen, and Shangguang Wang. Towards effec- tive next POI prediction: Spatial and semantic augmenta- tion with remote sensing data. In IEEE International Con- ference on Data Engineering (ICDE), pages 5061-5074, 2024.
- [Jin et al., 2023] Ming Jin, Shiyu Wang, Lintao Ma, Zhix- uan Chu, James Y Zhang, Xiaoming Shi, Pin-Yu Chen, Yuxuan Liang, Yuan-Fang Li, Shirui Pan, et al. Time-llm: Time series forecasting by reprogramming large language models. arXiv preprint arXiv:2310.01728, 2023.
- [Kingma and Ba, 2014] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Lepikhin et al., 2020] Dmitry Lepikhin, HyoukJoong Lee, Yuanzhong Xu, Dehao Chen, Orhan Firat, Yanping Huang, Maxim Krikun, Noam Shazeer, and Zhifeng Chen. Gshard: Scaling giant models with conditional computation and automatic sharding. arXiv preprint arXiv:2006.16668, 2020.
- [Li et al., 2022] LinYu Li, Xuan Zhang, YuBin Ma, Chen Gao, Jishu Wang, Yong Yu, Zihao Yuan, and Qiuying Ma. A knowledge graph completion model based on contrastive learning and relation enhancement method. Knowledge-Based Systems (KBS), pages 1-15, 2022.
- [Li et al., 2025] Linyu Li, Zhi Jin, Xuan Zhang, Haoran Duan, Jishu Wang, Zhengwei Tao, Haiyan Zhao, and Xi- aofeng Zhu. Multi-view riemannian manifolds fusion en- hancement for knowledge graph completion. IEEE Trans- actions on Knowledge and Data Engineering (TKDE), pages 2756-2770, 2025.
- [Lin et al., 2024a] Jiaye Lin, Qing Li, Guorui Xie, Zhongxu Guan, Yong Jiang, Ting Xu, Zhong Zhang, and Peilin Zhao. Mitigating sample selection bias with robust domain adaption in multimedia recommendation. In ACM Inter- national Conference on Multimedia (MM), pages 7581- 7590, 2024.
- [Lin et al., 2024b] Jiaye Lin, Shuang Peng, Zhong Zhang, and Peilin Zhao. Tlrec: A transfer learning framework to enhance large language models for sequential recom- mendation tasks. In ACM Conference on Recommender Systems (RecSys), pages 1119-1124, 2024.
- [Liu et al., 2023] Yong Liu, Tengge Hu, Haoran Zhang, Haixu Wu, Shiyu Wang, Lintao Ma, and Mingsheng Long. itransformer: Inverted transformers are effective for time series forecasting. arXiv preprint arXiv:2310.06625, 2023.
- [Liu et al., 2025] Chenxi Liu, Qianxiong Xu, Hao Miao, Sun Yang, Lingzheng Zhang, Cheng Long, Ziyue Li, and Rui Zhao. Timecma: Towards llm-empowered multivariate time series forecasting via cross-modality alignment. In AAAI Conference on Artificial Intelligence (AAAI), pages 18780-18788, 2025.
- [Miao et al., 2024a] Hao Miao, Ziqiao Liu, Yan Zhao, Chen- juan Guo, Bin Yang, Kai Zheng, and Christian S Jensen. Less is more: Efficient time series dataset condensation via two-fold modal matching. Proceedings of the VLDB Endowment (PVLDB), pages 226-238, 2024.
- [Miao et al., 2024b] Hao Miao, Yan Zhao, Chenjuan Guo, Bin Yang, Kai Zheng, Feiteng Huang, Jiandong Xie, and Christian S Jensen. A unified replay-based continu- ous learning framework for spatio-temporal prediction on streaming data. In IEEE International Conference on Data Engineering (ICDE), pages 1050-1062, 2024.
- [Miao et al., 2025] Hao Miao, Ronghui Xu, Yan Zhao, Sen- zhang Wang, Jianxin Wang, Philip S Yu, and Christian S Jensen. A parameter-efficient federated framework for streaming time series anomaly detection via lightweight adaptation. IEEE Transactions on Mobile Computing (TMC), pages 1-14, 2025.
- [Nie et al., 2022] Yuqi Nie, Nam H Nguyen, Phanwadee Sinthong, and Jayant Kalagnanam. A time series is worth 64 words: Long-term forecasting with transformers. arXiv preprint arXiv:2211.14730, 2022.
- [Paszke, 2019] A Paszke. Pytorch: An imperative style, high-performance deep learning library. arXiv preprint arXiv:1912.01703, 2019.
- [Radford et al., 2019] Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, Ilya Sutskever, et al. Language models are unsupervised multitask learners. OpenAI blog, pages 1-24, 2019.
- [Shazeer et al., 2017] Noam Shazeer, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hin- ton, and Jeff Dean. Outrageously large neural net- works: The sparsely-gated mixture-of-experts layer. arXiv preprint arXiv:1701.06538, 2017.
- [Touvron et al., 2023] Hugo Touvron, Thibaut Lavril, Gau- tier Izacard, Xavier Martinet, Marie-Anne Lachaux, Tim- othée Lacroix, Baptiste Rozière, Naman Goyal, Eric Ham- bro, Faisal Azhar, et al. Llama: Open and efficient founda- tion language models. arXiv preprint arXiv:2302.13971, 2023.
- [Ulyanov et al., 2016] Dmitry Ulyanov, Andrea Vedaldi, and Victor Lempitsky. Instance normalization: The miss- ing ingredient for fast stylization. arXiv preprint arXiv:1607.08022, 2016.
- [Wang et al., 2023] Huiqiang Wang, Jian Peng, Feihu Huang, Jince Wang, Junhui Chen, and Yifei Xiao. Micn: Multi-scale local and global context modeling for long- term series forecasting. In International Conference on Learning Representations (ICLR), pages 1-22, 2023.
- [Wang et al., 2024] Shiyu Wang, Haixu Wu, Xiaoming Shi, Tengge Hu, Huakun Luo, Lintao Ma, James Y Zhang, and Jun Zhou. Timemixer: Decomposable multiscale mixing for time series forecasting. arXiv preprint arXiv:2405.14616, 2024.
- [Wu et al., 2021] Haixu Wu, Jiehui Xu, Jianmin Wang, and Mingsheng Long. Autoformer: Decomposition transform- ers with auto-correlation for long-term series forecast- ing. Conference on Neural Information Processing Sys- tems (NeurIPS), 34:22419-22430, 2021.
- [Wu et al., 2022] Haixu Wu, Tengge Hu, Yong Liu, Hang Zhou, Jianmin Wang, and Mingsheng Long. Timesnet: Temporal 2d-variation modeling for general time series analysis. arXiv preprint arXiv:2210.02186, 2022.
- [Yuan and Li, 2021] Haitao Yuan and Guoliang Li. A sur- vey of traffic prediction: from spatio-temporal data to in- telligent transportation. In Data Science and Engineering (DSE), pages 63-85, 2021.
- [Yuan et al., 2020] Haitao Yuan, Guoliang Li, Zhifeng Bao, and Ling Feng. Effective travel time estimation: When historical trajectories over road networks matter. In ACM SIGMOD International Conference on Management of Data (SIGMOD), pages 2135-2149, 2020.
- [Yuan et al., 2021] Haitao Yuan, Guoliang Li, Zhifeng Bao, and Ling Feng. An effective joint prediction model for travel demands and traffic flows. In IEEE International Conference on Data Engineering (ICDE), pages 348-359, 2021.
- [Yuan et al., 2023] Haitao Yuan, Sai Wang, Zhifeng Bao, and Shangguang Wang. Automatic road extraction with multi-source data revisited: completeness, smoothness and discrimination. Proceedings of the VLDB Endowment (PVLDB), pages 3004-3017, 2023.
- [Yuan et al., 2024] Haitao Yuan, Gao Cong, and Guoliang Li. Nuhuo: An effective estimation model for traffic speed histogram imputation on A road network. Proceedings of the VLDB Endowment (PVLDB), pages 1605-1617, 2024.
- [Zeng et al., 2023] Ailing Zeng, Muxi Chen, Lei Zhang, and Qiang Xu. Are transformers effective for time series fore- casting? In AAAI Conference on Artificial Intelligence (AAAI), pages 11121-11128, 2023.
- [Zhang and Yan, 2023] Yunhao Zhang and Junchi Yan. Crossformer: Transformer utilizing cross-dimension de- pendency for multivariate time series forecasting. In Inter- national Conference on Learning Representations (ICLR), pages 1-21, 2023.
- [Zhao et al., 2024] Zhengyang Zhao, Haitao Yuan, Nan Jiang, Minxiao Chen, Ning Liu, and Zengxiang Li. STMGF: an effective spatial-temporal multi-granularity framework for traffic forecasting. In International Con- ference on Database Systems for Advanced Applications (DASFAA), pages 235-245, 2024.
- [Zhou et al., 2021] Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang. Informer: Beyond efficient transformer for long sequence time-series forecasting. In AAAI Conference on Artificial Intelligence (AAAI), pages 11106-11115, 2021.
- [Zhou et al., 2022] Tian Zhou, Ziqing Ma, Qingsong Wen, Xue Wang, Liang Sun, and Rong Jin. Fedformer: Fre- quency enhanced decomposed transformer for long-term series forecasting. In International Conference on Ma- chine Learning (ICML), pages 27268-27286, 2022.
- [Zhou et al., 2023] Tian Zhou, Peisong Niu, Liang Sun, Rong Jin, et al. One fits all: Power general time series analysis by pretrained lm. Conference on Neural Informa- tion Processing Systems (NeurIPS), pages 43322-43355, 2023.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Time series forecasting is essential for various fields, aiming to accurately present future values according to historical observations. The rapid advancement of deep learning has spurred significant research in this area, with applications in traffic prediction [Zhao et al., 2024; Jiang et al., 2024; Yuan and Li, 2021; Chen et al., 2024], recommender systems [Lin et al., 2024a; Lin et al., 2024b], and weather forecasting [Zhou et al., 2021; Liu et al., 2025; Miao et al., 2024b].
The recent success of attention mechanisms has prompted researchers to investigate the potential of Transformer-based models by redefining time series forecasting tasks as the future token prediction [He et al., 2024b; Chen et al., 2025; Yuan et al., 2024]. Existing research in this field can be categorized into two classes based on different tokenization methods, as illustrated in Figure 1. The first approach uses timestamps as tokens, exemplified by models such as Autoformer [Wu et al., 2021] and FEDformer [Zhou et al., 2022]. The second approach adopts patch-level tokenization, where a patch represents a window of timestamps, with PatchTST [Nie et al., 2022] being a notable example. Compared with timestamp-level tokenization, patch-level tokenization more effectively captures temporal patterns, thereby achieving superior forecasting performance. Despite their remarkable success, these methods still face challenges related to limited generalizability. Most existing research focuses primarily on single-scale temporal features, which lack a careful consideration of multi-scale characteristics in time series data. Furthermore, the effective fusion of multi-scale features has not been thoroughly explored, leading to limitations in forecasting under complex scenarios.
† Corresponding author.
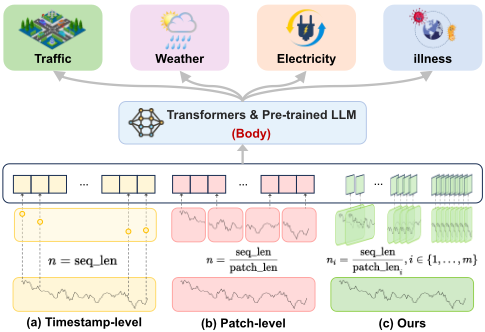
To address the above challenges, we propose a novel time series forecasting architecture named Adaptive Weighted Mixture of Multi-Scale Expert Transformers (AdaMixT). By incorporating multi-scale temporal features, AdaMixT significantly enhances both predictive accuracy and generalizability, providing an innovative approach to multi-scale feature fusion. Specifically, AdaMixT leverages both General Pretrained Models (GPM) and Domain-specific Models (DSM) for time series forecasting, combining the extensive knowledge from GPM with the specialized feature extraction capabilities of DSM to better support downstream tasks. In this framework, input data is segmented into multi-scale patches; smaller patches capture high-frequency features for highresolution representations, while larger patches capture lowfrequency features for low-resolution representations. To effectively integrate multi-scale features, AdaMixT adopts a weighted fusion strategy to assign different weights for the output of each model, generating the final prediction. In summary, we make the main contributions as follows:
- We propose a novel multi-scale patch design that combines GPM with DSM, enabling the capture of both shortterm and long-term temporal patterns in time series. This integration leverages the open-world knowledge of pretrained models and the specialized feature extraction capabilities of domain-specific architectures, thereby improving forecasting accuracy and model generalizability.
- To the best of our knowledge, this work is the first to introduce an adaptive mechanism for multi-scale feature fusion in time series forecasting. By utilizing multiple models as experts and dynamically assigning weights based on the characteristics of time series data, our approach significantly enhances the model's adaptability to various tasks, ensuring robust scalability across different real-world application scenarios.
- We conduct extensive experiments across multiple time series forecasting benchmarks, demonstrating that AdaMixT outperforms existing forecasting approaches.
2 RelatedWork
2.1 Time Series Forecasting
In recent years, considerable research efforts have been directed toward leveraging Transformer-based models for time series forecasting. Early approaches, such as Informer [Zhou et al., 2021], adopt a sequence-to-sequence framework, treating each timestamp as an individual token. Similarly, Autoformer [Wu et al., 2021] incorporates classical analysis concepts such as decomposition and autocorrelation, while FEDformer [Zhou et al., 2022] utilizes a Fourier-enhanced structure to achieve linear computational complexity. However, [Zeng et al., 2023] highlights the limitations of treating each timestamp as a token, particularly in capturing intricate temporal patterns. To overcome this drawback, models such as Crossformer [Zhang and Yan, 2023] and PatchTST [Nie et al., 2022] are inspired by patch-based visual transformers [Dosovitskiy et al., 2020], representing windows of multiple timesteps as patches and using these as tokens for improved performance. Concurrently, the impressive capabilities of Large Language Models (LLMs) have led to their application in time series forecasting. Models like GPT4TS [Zhou et al., 2023] and TIME-LLM [Jin et al.,
2023] have shown promising results, further demonstrating the potential of LLMs in this field.
Despite these advancements, existing methods [Miao et al., 2024a; Yuan et al., 2021; Yuan et al., 2020] still face challenges in effectively capturing and fusing multi-scale features. To overcome these limitations, we propose AdaMixT, which enhances robust multi-scale feature extraction and includes an efficient fusion mechanism. By combining the strengths of GPM and DSM, AdaMixT offers a comprehensive and efficient solution for time series analysis.
2.2 Multi-scale Feature Learning
The analysis of multi-scale features plays a pivotal role in numerous fields. In computer vision, multi-scale features enable the extraction of information at varying spatial resolutions within an image, facilitating the analysis of both finegrained local details and overarching global structures [Das and Dutta, 2020; He et al., 2024a]. Meanwhile, multi-scale features have also been widely applied in domains such as knowledge graphs [Li et al., 2025; Li et al., 2022]. In recent years, multi-scale analysis has also been increasingly adopted in time series forecasting. For instance, TimesNet [Wu et al., 2022] transforms one-dimensional sequences into twodimensional tensors to capture diverse periodic patterns. In addition, MICN [Wang et al., 2023] utilizes convolutions with varying kernel sizes to learn features at multiple temporal scales. TimeMixer [Wang et al., 2024] enhances predictive performance by decomposing multiscale series and effectively blending their seasonal and trend components.
Unlike existing works [Miao et al., 2025; Yuan et al., 2023], AdaMixT learns multi-scale features during the training phase, enabling more efficient feature representation. Furthermore, instead of relying on straightforward feature fusion methods such as concatenation or addition, we design a gating network to score multi-scale temporal features and propose an innovative multi-scale feature fusion mechanism, which further enhances the performance and generalizability.
2.3 Mixture of Experts
Mixture of Experts (MoE) refers to a model consisting of different components, known as experts, each specialized in handling distinct tasks or specific aspects of data. Initially introduced in the literature [Jacobs et al., 1991], it has since been extensively studied and refined in subsequent works [Aljundi et al., 2017]. The advent of sparsegated MoE [Shazeer et al., 2017], particularly within large Transformer-based language models [Lepikhin et al., 2020], has revitalized this technique, expanding its applicability and effectiveness. Traditional MoEs typically rely on feedforward networks to select models based on specific scenarios. Unlike these designs, AdaMixT introduces multi-scale feature fusion into time series analysis for the first time. By adopting a self-learning mechanism, AdaMixT focuses on feature fusion rather than model selection, enabling the model to automatically identify critical multi-scale features and achieve efficient integration.
3 Method
In this section, we first provide a formal definition of the problem along with necessary notations and then explain the details of the overall model structure.
3.1 ProblemDefinition
Multivariate time series forecasting involves predicting future values based on historical observation. The objective is to forecast future values for the next K timestamps, given the observations from the previous L timestamps. A multivariate time series comprises multiple related time series, each representing a different variable. Let xt = [x(1) t , x(2) t , . . . , x(M) t ] ∈ RM×1 be a multivariate signal, where x(i) t denotes the i-th variate at time t, for 1 ≤ i ≤M.
In Equation (1), our goal is to develop a model that accurately predicts the values for the next K timestamps based on the recent history spanning L timestamps. Here, L and K are referred to as the look-back window and the prediction horizon, respectively. For a single variable, ˆx(i) L+1 , . . . , ˆx(i) L+K represents the sequence of future values in the next K time steps for the i th variable, which is the prediction target. In contrast, x(i) 1 , . . . , x(i) L denote the observed data for the i-th variable over the past L time steps. The function F, parameterized by Φ, leverages these observations to effectively forecast the future sequence values.
3.2 Model Structure
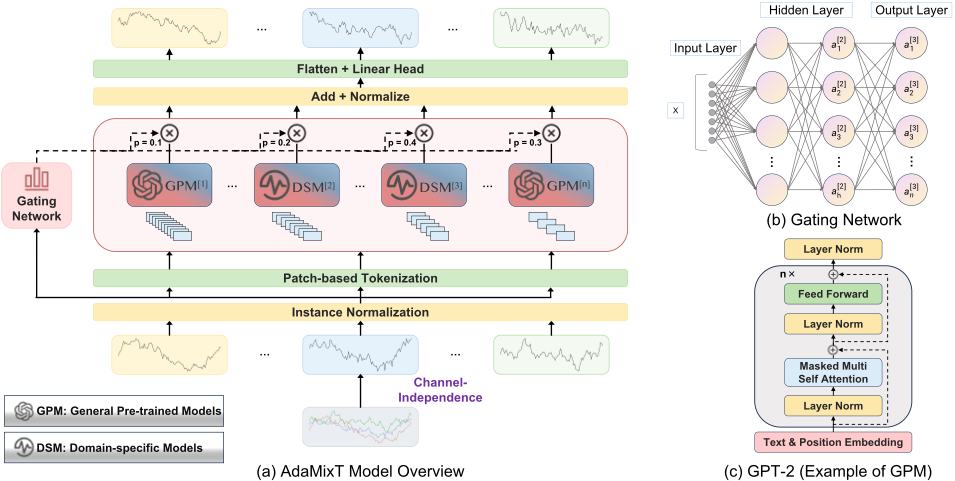
The architecture of AdaMixT is illustrated in Figure 2. The model leverages GPMs (e.g., GPT2 [Radford et al., 2019] and Llama [Touvron et al., 2023]) and DSMs (e.g., PatchTST [Nie et al., 2022]) as experts to efficiently extract multi-scale features from time series, thereby achieving accurate prediction objectives. The entire framework consists of three core modules: Multi-Scale Feature Extraction, Expert Pool, and Adaptive Weighted Gating Network (AWGN).
As detailed in Algorithm 1, AdaMixT adopts a channelindependent framework to process each variable. The process begins with instance normalization to standardize each variable. Following this, the time series is segmented into patches of varying lengths using a patch-based tokenization, enabling the capture of multi-scale temporal features spanning both short-term and long-term dependencies. These patches are subsequently processed by multiple experts, including GPMs for general feature representation and DSMs tailored for time-series forecasting. Each expert extracts features from input patches and integrates their outputs based on the scoring results of Adaptive Weighted Gating Network. The fused results are then passed through Linear Head to generate the final predictions. Furthermore, while AdaMixT inherently employs a channel-independent design, its architecture is highly flexible and can be seamlessly extended to other patch-based time series models, such as Crossformer [Zhang and Yan, 2023], for modeling inter-variable dependencies. This versatility establishes AdaMixT as an efficient
Algorithm 1 Forcasting Process of AdaMixT
Input: Multivariate time series X1:L with M variables, Look-back window L, Prediction horizon K Parameters: Learning rate η, Batch size B, Patch length P, Stride S, Scale factors {F1, F2, . . . , Fn} Output: Predictions ˆXL+1:L+K 1: for i ← 1 toM do 2: x norm(i) 1:L ← Instance Normalization(x(i) 1:L) 3: end for 4: for i ← 1 toM do 5: for j ← 1 to n do 6: p(i) j ←MF Extract(x norm(i) 1:L, P · Fj, S · Fj) 7: end for 8: end for 9: for i ← 1 toM do 10: for j ← 1 to n do 11: E(i) j ←Expert Modelj(p(i) j ) 12: end for 13: G(i) ←Gating Network(x norm(i) 1:L) 14: fused feature(i) ← ∑nj=1 G(i) j · E(i) j 15: end for 16: for i ← 1 toM do 17: ˆx(i) L+1:L+K ←Linear Head(fused feature(i) ) 18: end for 19: return ˆXL+1:L+K
and generalizable solution for time series forecasting tasks.
Forward Process. We denote the i-th univariate sequence of length L as x(i) 1:L = (x(i) 1 , . . . , x(i) L ), where i = 1, . . . ,M. The input sequence (x1, . . . , xL) is divided into M univariate sequences x(i) ∈ R1×L, each independently processed by a model consisting of multiple experts, with each sequence using a different patch length. Finally, different weights are assigned to each expert model, and multi-feature fusion is performed. After passing through the final Linear Head, the corresponding prediction results are returned as ˆx(i) = (ˆx(i) L+1 , . . . , ˆx(i) L+K ) ∈ R1×K .
Multi-scale Feature Extraction. Time segments composed of multiple consecutive timestamps are essential for learning effective predictive representations [Nie et al., 2022]. Building on this idea, we incorporate multi-scale features of time series into the modeling process by dividing each input univariate time series x(i) 1:L into patches of varying lengths, which may be overlapping or non-overlapping. Specifically, we define the base patch length P and stride S, and utilize Scale factors = {F1, F2, . . . , Fn} to adjust the scale sizes, where n denotes the total number of defined scales. Through this patching process, n patch sequences x(i)(j) 1:L ∈ RPj×Nj are generated, where Nj = ⌊ L-Pj Sj ⌋ + 2 represents the number of patches derived from the j-th patching operation. Here, Pj = P · Fj denotes the adjusted patch length, and Sj = S · Fj represents the adjusted stride at the j-th scale. To ensure alignment, the original sequence x(i) 1:L is padded at the end with Sj repeated values before performing the patching process.
By adopting patch lengths of varying scales, smaller Pj values enable the x(i)(j) 1:L branch to specifically focus on shortterm temporal features with finer granularity, thereby achieving high-resolution modeling. In contrast, larger Pj values are better suited for effectively capturing long-term seasonal variations and trend characteristics, thus achieving the goal of multi-scale feature extraction.
Expert Pool. We propose the concept of an Expert Pool, designed to integrate the strengths of different models to enhance the performance of multivariate time series forecasting. The Expert Pool consists of two core types of models: General Pre-trained Models and Domain-Specific Models. GPMs (e.g., GPT-2 [Radford et al., 2019] and Llama [Touvron et al., 2023]) demonstrate exceptional performance in understanding complex time series data due to their strong generalizability and rich feature representation learning. In contrast, DSMs (e.g., PatchTST [Nie et al., 2022]) focus on precise pattern extraction in time series data, capturing fine-grained features and effectively compensating for the limitations of GPMs in specific tasks.
Unlike existing methods [Jin et al., 2023; Wang et al., 2023] that typically utilize either GPM or DSM individually, our approach combines these two types of models, significantly improving prediction performance through the synergistic effects. Both types of models are based on the Transformer architecture, whose core mechanism is the Attention Mechanism. Specifically, patches are first projected into the Transformer latent space of dimension D using a trainable linear projection Wp ∈ RD×P , and a learnable positional encoding Wpos ∈ RD×N is added to preserve temporal order. The transformed patches are then processed by the multi-head attention module, where Query (Q), Key (K), and Value (V) matrices are computed as follows: Q(i) h = (x(i) d )T WQ h , K(i) h = (x(i) d )T WK h , V(i) h = (x(i) d )T WV h , where WQ h ,WK h ∈ RD×dk and WV h ∈ RD×D . The attention output O(i) h ∈ RD×N : is then computed using a scaled dot-product: (O(i) h )T = Softmax ( Q(i) h K(i)T h √dk ) V(i) h .
Adaptive Weighted Gating Network. In this study, we proposed AWGN, which differs from traditional simple feature fusion methods such as feature addition or concatenation. This innovative approach effectively considers the importance of different features, thereby enhancing the accuracy of time series forecasting. As shown in Figure 2(b), AWGN is a three-layer MLP network that dynamically assigns weights G(x(i) ) to the expert models based on the characteristics of each input sequence x(i). These weights are subsequently applied to the output features E(p(i) ) of the expert models, as described in Equation (2). Here, x(i) represents the time series features before patch partitioning, p(i) denotes the sequence after partitioning, and n indicates the total number of experts in the expert model pool.
Dataset # Features # Timesteps Frequency Domain
| Dataset | # Features | # Timesteps | Frequency 0.40 |
|---|---|---|---|
| Weather | 21 | 52696 | 10 min |
| Traffic | 862 | 17544 | 1 hour |
| Electricity | 321 | 26304 | 1 hour 0.35 |
| ILI | 7 | 966 | 1 week |
| ETTh1 | 7 | 17420 | 1 hour MAE |
| ETTh2 | 7 | 17420 | 1 hour 0.30 |
| ETTm1 | 7 | 69680 | 15 min |
| ETTm2 | 7 | 69680 | 15 min |
Finally, the features weighted by AWGN are aggregated and
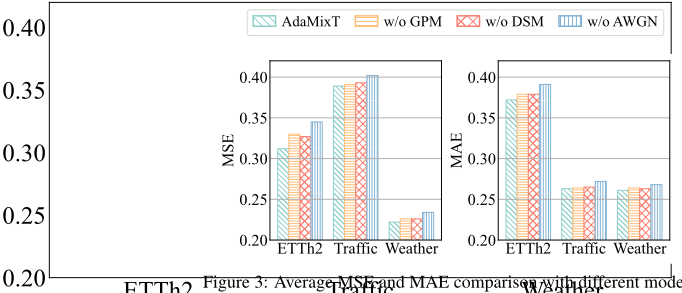
ETTh2 Traffic Weather Figure 3: Average MSE and MAE comparison with different model variants on ETTh2, Traffic, and Weather datasets.
passed through Linear Head to generate the final prediction values. This scoring and weighted aggregation mechanism offers a more efficient approach to integrating multi-feature information for time series forecasting tasks.
Loss Function. We utilize the Mean Squared Error (MSE) loss to quantify the discrepancy between the predictions and the ground truth. The loss in each channel is gathered and averaged over M time series to get the overall objective loss.
Instance Normalization. This technique has been recently introduced to address the distribution shift between training and testing data [Ulyanov et al., 2016]. It works by normalizing each time series instance x(i) to have a zero mean and unit standard deviation. Specifically, each x(i) is normalized before patching, and the mean and standard deviation are added back to the output prediction afterward.
4 Experiments
4.1 Experimental Setup
Dataset. We conduct experiments on eight widely recognized benchmarks, namely Weather, Traffic, Electricity, ILI, and four ETT datasets (ETTh1, ETTh2, ETTm1, and ETTm2), which were originally introduced by [Wu et al., 2021]. The statistics are summarized in Table 1.
Baselines. We evaluate AdaMixT against ten SOTA baselines across four categories: (i) LLM-based models, including TIME-LLM [Jin et al., 2023] and GPT4TS [Zhou et al., 2023]; (ii) Multi-scale time series models, such as TimeMixer [Wang et al., 2024], MICN [Wang et al., 2023], and TimesNet [Wu et al., 2022]; (iii) Transformerbased models, including iTransformer [Liu et al., 2023], PatchTST [Nie et al., 2022], FEDformer [Zhou et al., 2022], and Autoformer [Wu et al., 2021]; and (iv) the MLP-based model, DLinear [Zeng et al., 2023].
Implementation Details. To ensure the fairness of experiments, all baseline models are configured according to the settings in their official open-source repositories and evaluated using a unified evaluation framework, TSLib 1 . All experiments are implemented based on PyTorch [Paszke, 2019]
1 https://github.com/thuml/Time-Series-Library
and executed on an NVIDIA A100-80G GPU. The default optimizer for the experiments is Adam [Kingma and Ba, 2014], and each experiment is repeated three times, with the average results reported.
4.2 Performance Comparison
Table 2 presents the experimental results for long-termmultivariate forecasting, highlighting the substantial advantages of our model. Specifically, compared to LLM-based methods, our model reduces MSE and MAE by 13.19% and 5.35%, respectively. When compared to Multi-scale models, the reductions are 24.99% and 15.14%, respectively. Relative to the DLinear model, MSE and MAE decrease by 22.73% and 13.35%. Furthermore, our model exhibits even more significant improvements over other transformer-based models. Notably, even when compared with SOTA models such as TIME-LLM [Jin et al., 2023] and PatchTST [Nie et al., 2022], our model consistently delivers superior performance. These results strongly demonstrate the robustness and superiority of our approach across various datasets.
4.3 Model Analysis
Ablation Study. To comprehensively evaluate the contributions of the key components-GPM, DSM, and AWGN-to the overall performance of the AdaMixT, we conducted a series of ablation experiments. These experiments systematically removed each component, allowing us to compare the performance of the resulting model variants and quantify the impact of each element.
As shown in Figure 3, the ablation study results demonstrate that the complete AdaMixT model achieves the best performance on the ETTh2, Weather, and Traffic datasets, while removing any single module leads to a decrease in prediction accuracy. For example, on the ETTh2 dataset, removing GPM and DSM results in performance degradation, highlighting the critical role of GPM in extracting general feature representations and the significant value of DSM in modeling temporal features. Notably, the most substantial performance drop is observed when AWGN is removed, with both MSE and MAE significantly higher than other variants. This finding underscores the pivotal role of AWGN in multi-scale feature fusion and its importance in improving prediction accuracy. Similar trends are observed on the Weather and Traffic datasets, further confirming the importance of each module in enhancing model performance.
| Method | AdaMixT (Ours) | TIME-LLM (2023) | GPT4TS (2023) | TimeMixer (2024) | MICN (2023) | TimesNet (2022) | iTransformer (2023) | PatchTST (2022) | FEDformer (2022) | Autoformer (2021) | DLinear (2023) | |||||||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Metric | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MSE | MAE | MAE | MSE | MAE | MSE | MAE | MSE | ||||||||||||||||||
| Weather | 96 192 336 720 | 0.145 0.190 0.243 0.310 | 0.196 0.238 0.279 0.332 | 0.149 0.193 0.243 0.315 | 0.200 0.243 0.284 0.336 | 0.162 0.204 0.254 0.326 | 0.212 0.248 0.286 0.337 | 0.161 0.207 0.264 0.344 | 0.209 0.250 | 0.161 0.220 0.278 0.331 | 0.229 0.281 0.356 | 0.172 0.219 0.280 | 0.220 0.261 | 0.175 0.225 | 0.216 0.258 0.298 0.351 | 0.149 0.194 | 0.198 0.241 | 0.238 0.275 | 0.249 0.325 | 0.351 | 0.262 | 0.176 0.218 | 0.238 0.277 | 0.329 0.370 0.391 0.426 | 0.313 0.367 | 0.327 | 0.365 | 0.306 0.359 | 0.245 0.314 | 0.282 0.334 | 0.280 0.361 | 0.292 0.343 | 0.311 | 0.314 0.329 0.377 0.409 | 0.339 0.389 | 0.415 | ||||
| Traffic | Avg 96 192 | 0.222 | 0.261 0.248 0.254 | 0.225 0.376 0.397 0.420 0.448 | 0.266 0.280 0.294 0.311 | 0.237 0.388 0.407 0.412 | 0.271 0.282 0.290 0.294 | 0.244 0.466 0.507 0.525 | 0.293 0.301 0.309 | 0.243 0.299 0.519 | 0.309 0.315 0.313 | 0.259 0.593 0.617 0.629 | 0.287 0.321 0.336 | 0.260 0.394 | 0.281 0.269 | 0.226 0.264 | 0.249 0.256 | 0.310 0.576 | 0.357 0.335 | 0.371 | 0.379 | 0.246 0.413 0.423 0.438 | 0.288 0.287 0.300 0.315 | 0.274 | ||||||||||||||||
| 336 720 Avg 96 192 336 | 0.358 0.378 0.390 0.428 0.389 0.118 0.146 0.160 | 0.263 0.287 0.263 0.214 0.237 | 0.410 0.137 0.158 0.183 | 0.326 0.303 0.244 0.266 | 0.450 0.414 0.139 0.153 0.169 | 0.312 0.295 0.238 0.251 0.266 | 0.552 0.513 0.120 0.170 0.187 | 0.325 0.307 0.215 0.261 | 0.537 0.534 0.577 0.542 0.164 0.177 | 0.325 0.316 0.269 0.285 0.304 | 0.640 0.620 | 0.336 0.350 0.336 | 0.412 0.425 0.460 0.423 | 0.277 0.283 0.301 0.283 0.240 | 0.360 0.379 0.392 0.432 | 0.264 0.286 | 0.610 0.608 0.621 | 0.359 0.380 0.375 0.375 | 0.597 0.607 0.623 0.639 0.617 | 0.382 0.387 0.395 0.384 0.313 0.324 | 0.466 0.435 0.141 0.158 | 0.299 0.298 | 0.240 | 0.168 0.184 | 0.272 0.289 0.300 | 0.391 0.129 0.147 | 0.264 0.222 0.240 | 0.148 0.164 0.178 | 0.278 | 0.193 | 0.372 0.302 0.311 0.328 | 0.604 0.186 0.197 0.213 | 0.196 | |||||||
| Electricity | 720 Avg 24 36 | 0.194 0.155 1.384 | 0.258 0.289 0.250 0.757 | 0.247 0.181 1.708 | 0.292 0.348 0.288 0.765 0.781 | 0.206 0.167 2.063 1.868 1.790 1.979 1.925 0.376 | 0.297 0.263 0.881 0.892 0.884 0.904 0.397 0.418 0.433 | 0.228 0.176 1.358 1.432 1.551 1.489 0.381 0.442 0.501 | 0.267 0.763 0.826 0.814 | 0.212 0.187 2.684 2.667 | 0.321 0.295 1.112 1.068 | 0.198 0.220 0.193 2.317 | 0.934 0.920 0.940 0.928 0.931 | 1.638 1.742 1.826 1.954 1.790 0.386 | 0.256 0.271 0.300 0.267 0.831 | 0.163 0.259 0.197 0.290 0.159 0.253 1.319 0.754 0.834 | 0.233 0.207 2.624 | 2.516 2.505 2.742 2.597 | 1.021 1.041 1.122 1.070 | 0.211 0.214 0.236 0.214 | 0.327 0.342 0.327 1.182 | 0.171 0.206 0.169 1.964 | 0.260 0.271 0.304 0.269 0.975 | 0.320 0.295 | 0.815 | 0.211 0.175 | 0.313 | 2.558 | 0.344 0.321 1.095 | 2.906 2.585 | ||||||||||
| ILI | 48 60 Avg 96 | 1.300 1.475 1.460 | 0.755 0.793 0.821 | 1.634 1.597 1.565 | 0.769 0.754 0.767 | 0.957 0.456 | 1.614 | 1.827 2.747 1.058 2.664 0.421 0.474 | 1.052 1.110 1.086 | 1.972 2.238 2.027 | 0.402 0.429 | 0.441 | 0.879 1.430 0.932 1.553 0.973 1.470 0.904 1.443 0.370 | 0.788 0.798 0.399 0.421 | 0.436 | 0.376 0.423 0.444 | 0.415 0.446 0.462 | 3.024 2.761 2.819 0.435 | 1.038 1.145 1.114 1.120 | 2.080 2.163 2.396 2.151 | 0.998 1.043 1.112 1.032 0.448 | |||||||||||||||||||
| ETTh1 | 1.405 0.360 0.398 0.398 | 0.782 0.393 0.418 0.427 | 1.626 0.398 0.442 0.456 | 0.414 0.440 0.450 | 0.416 0.442 0.477 | 0.426 | 0.544 | 0.398 0.430 | 0.431 0.487 0.672 0.672 | 2.139 0.384 0.436 0.521 | 0.500 0.505 | 0.491 0.509 | 0.405 0.436 0.461 0.494 | 0.466 | 0.469 0.428 | 0.492 0.454 | 0.456 0.486 0.515 | 0.446 0.457 0.487 0.517 | 0.422 0.419 0.460 0.521 | 0.430 0.462 0.500 | 0.413 | |||||||||||||||||||
| 192 336 720 | 0.453 0.402 | 0.465 0.426 | 0.602 0.475 | 0.545 0.462 | 0.428 | 0.342 0.389 | 0.467 0.288 0.391 | 0.460 0.505 0.448 | 0.770 0.770 0.559 | 0.535 0.364 | 0.493 0.458 | 0.450 0.374 0.414 | 0.457 0.300 | 0.422 0.447 0.449 0.413 0.274 0.339 | 0.431 | 0.332 0.407 | 0.374 0.446 | 0.473 0.332 | 0.477 0.368 | 0.449 0.279 0.361 | 0.461 | |||||||||||||||||||
| Avg 96 192 336 720 Avg | 0.260 0.306 | 0.328 0.370 0.372 0.418 0.372 | 0.309 0.362 0.376 0.405 0.363 0.288 | 0.362 0.395 0.409 0.436 0.401 | 0.285 0.354 0.373 0.406 0.355 | 0.407 0.441 0.395 | 0.422 0.442 0.386 | 0.340 0.403 0.427 0.451 | 0.299 0.441 0.654 0.956 | 0.454 0.567 0.716 0.525 | 0.340 0.402 0.452 0.462 0.414 | 0.452 0.468 0.427 0.375 | 0.382 0.424 0.426 0.383 | 0.350 0.400 0.432 0.445 0.407 | 0.336 0.379 0.380 0.422 0.379 | 0.400 0.412 0.388 | 0.447 0.469 0.434 | 0.426 0.477 0.453 0.422 | 0.434 0.479 0.490 0.443 | 0.466 0.398 0.351 | 0.344 0.401 0.473 0.417 0.409 | 0.329 0.379 | ||||||||||||||||||
| ETTh2 | 0.306 0.376 0.312 0.288 0.328 0.359 0.415 | 0.341 0.369 0.388 0.418 0.379 0.252 | 0.347 0.368 0.421 0.356 0.168 | 0.343 0.378 0.394 0.423 0.385 0.257 | 0.292 0.332 0.366 0.417 0.352 | 0.372 0.394 0.421 | 0.346 0.317 0.367 0.388 0.454 0.383 0.382 | 0.405 0.358 0.387 0.402 | 0.588 0.316 0.363 0.408 0.481 | 0.362 0.390 0.426 0.476 0.414 | 0.338 0.374 0.410 0.478 0.400 | 0.387 0.411 0.450 0.406 | 0.381 0.419 0.486 0.407 | 0.376 0.395 0.419 0.456 0.412 | 0.369 0.392 0.420 0.381 | 0.392 0.446 0.382 0.180 0.252 0.324 | 0.415 0.425 0.458 0.422 0.271 0.318 | 0.510 0.527 0.515 0.205 0.278 | 0.495 0.492 0.493 0.493 | 0.303 0.338 0.375 0.427 0.361 | 0.346 0.367 0.393 0.422 | 0.330 0.290 0.332 0.366 0.416 | 0.342 | 0.341 | 0.443 | 0.390 | 0.326 0.365 | 0.510 0.514 | ||||||||||||
| 96 | 336 720 Avg 0.348 0.163 192 0.217 336 720 | 0.290 0.330 0.383 | 0.219 0.275 0.367 | 0.293 0.332 0.335 | 0.173 0.229 0.286 0.378 | 0.262 0.301 0.401 0.326 | 0.175 0.237 0.341 0.296 0.393 | 0.299 0.338 0.395 0.323 | 0.325 0.502 | 0.388 0.490 0.382 | 0.249 0.321 | 0.267 0.309 0.351 | 0.184 0.253 0.315 0.412 | 0.267 0.312 0.352 | 0.220 0.274 | 0.329 0.385 | 0.420 0.343 | 0.343 0.414 | 0.492 0.293 0.165 0.336 0.379 0.419 0.357 0 | 0.398 0.269 | 0.342 0.417 | 0.382 0.257 0.307 | 0.351 0.165 | 0.255 0.292 | 0.398 0.259 | 0.392 0.179 0.307 | ||||||||||||||
| 0.314 | 0.257 | 0.304 | 0.267 | 0.275 | 0.408 0.291 | 0.403 0.333 | 0.291 | 0.406 0.334 | 0.292 | 0.310 0 | 0.227 | 0 | 0.331 1 | |||||||||||||||||||||||||||
| 38 | 30 | 2 | 5 | 0 | 3 | 0 | 0 | 0 | 0 | 2 | 0 | 0 | 0.285 | |||||||||||||||||||||||||||
| 1st | Count | 0 | 0 | 0 | 0 | 3 | ||||||||||||||||||||||||||||||||||
| Avg | ||||||||||||||||||||||||||||||||||||||||
| ETTm1 ETTm2 | 0.272 0.361 0.253 | |||||||||||||||||||||||||||||||||||||||
| 96 192 | 0.362 0.255 | 0.410 | 0.275 0.187 0.376 | 0.315 | 0.328 | 0.364 |
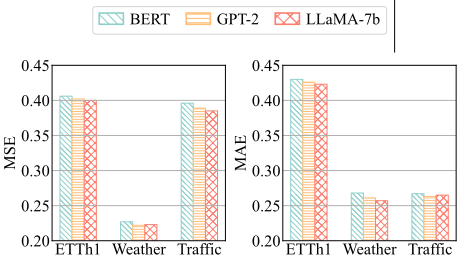
Results with Different Models. In the main experiments, AdaMixT utilizes GPT-2 [Radford et al., 2019] as GPM. To further validate the effectiveness of the model, we also perform comparative experiments using BERT and LLaMA-7B. The experimental results in Figure 4 indicate that the performance differences among BERT, GPT-2, and LLaMA-7B are minimal on the ETTh1, Weather, and Traffic datasets. This finding demonstrates the high robustness of AdaMixT in selecting GPMs, as it consistently delivers stable performance across various pretrained models.
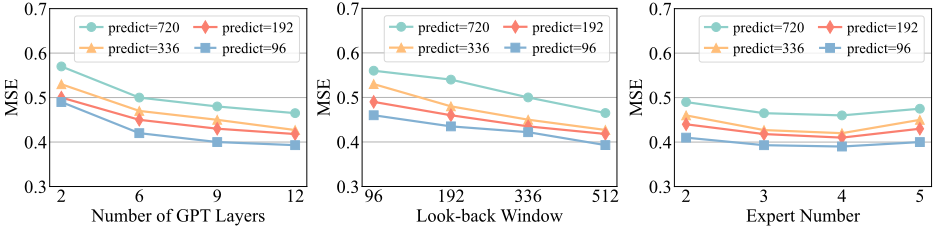
Hyperparameter Sensitivity. We conducte a sensitivity analysis on 3 key hyperparameters, including the number of layers in the backbone model, the look-back window, and the number of experts. Results are shown in Figure 5. Based on the results, we summarize the following conclusions:
- Backbone Layers: The number of layers in the backbone is positively correlated with the predictive performance. This indicates that, even after fusion, GPM retain favorable scaling laws with respect to layer depth, which positively influences model performance.
- Look-backWindow: The Look-backwindowdirectly affects prediction accuracy, especially at extended forecasting horizons. This observation aligns with the patterns
| Method | AdaMixT(1, 1/2) | AdaMixT(1, 1) | AdaMixT(1, 2) | ||||
|---|---|---|---|---|---|---|---|
| Metric | MSE | MAE | MSE | MAE | MSE | MAE | |
| 24 | 1.702 | 0.854 | 1.630 | 0.824 | 1.384 | 0.757 | |
| 36 | 1.753 | 0.862 | 1.509 | 0.816 | 1.300 | 0.755 | |
| ILI 48 | 1.737 | 0.860 | 2.023 | 0.941 | 1.475 | 0.793 | |
| 60 | 1.560 | 0.839 | 1.630 | 0.891 | 1.460 | 0.821 | |
| 96 | 0.360 | 0.393 | 0.366 | 0.399 | 0.381 | 0.408 | |
| 192 | 0.398 | 0.418 | 0.400 | 0.415 | 0.412 | 0.423 | |
| ETTh1 336 | 0.398 | 0.427 | 0.411 | 0.431 | 0.407 | 0.428 | |
| 720 | 0.453 | 0.465 | 0.459 | 0.470 | 0.571 | 0.547 | |
found in traditional models, demonstrating that longer historical inputs can effectively enhance performance.
- Number of Experts: The experimental results indicate that increasing the number of expert models can effectively capture features at different scales, thereby significantly improving the accuracy of time series forecasting. This result validates the effectiveness of the feature fusion mechanism in the AdaMixT. However, caution should be taken as the model may be prone to overfitting.
Scale Factors Study. As shown in Algorithm 1, the setting of scale factors determines the granularity of feature extraction. The selection of the appropriate parameters is critical to the accuracy of the prediction. To further investigate this, we conduct an analysis of the impact of different feature scale settings on prediction performance, using the ILI and ETTh1 datasets as examples.
Through a cyclic study of these two datasets, we find that the cyclicity of ILI is significantly longer than that of ETTh1. Based on this observation, we employ two expert models in the experiment, with the scale factor for GPM set to 1, and the scale factor range for the DSM set to {1/2, 1, 2}. The results, as shown in Table 3, indicate that for datasets with longer periodicities, using larger scale factors improves prediction performance (and vice versa). This finding suggests that when selecting scale factors, the intrinsic characteristics of the time series should be considered to achieve optimal prediction results.
InferenceTime Study. In order to evaluate the practical applicability, we compare the inference time of AdaMixT with current similar methods. As shown in Figure 6, AdaMixT
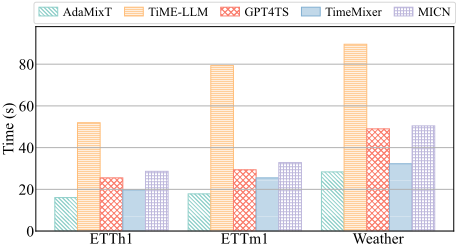
demonstrates superior inference time compared with other complex multi-scale feature fusion models and LLM-based models. This advantage is primarily attributed to the fact that AdaMixT does not require complex prompt generation, postprocessing, or frequency domain transformations.
5 Conclusion and FutureWorks
In this paper, we present AdaMixT, which is designed to address the limitations of existing methods in terms of generalizability and multi-scale feature fusion. AdaMixT incorporates three key innovations: Multi-scale Feature Extraction, Expert Pool, and Adaptive Weighted Gating Network, significantly enhancing the model's performance. To the best of our knowledge, this work is the first to combine the general feature representation capability of GPM with the fine-grained modeling ability of DSM to construct the expert pool. Additionally, we design AWGN that evaluates the weights of different models, enabling effective fusion of multi-scale features. Extensive experimental results on multiple benchmark datasets demonstrate that our approach outperforms existing forecasting approaches.
Our model offers new insights into multi-scale feature fusion in time series analysis. In the future, we aim to further explore multi-scale fusion methods and strengthen the complementary strengths of GPM and DSM, which will be a crucial research direction moving forward.
Acknowledgments
This work is supported by the National Key Laboratory under grant 241-HF-Z01-01. Guoliang Li is supported by the National Key R&D Program of China (2023YFB4503600), NSF of China (62232009), Zhongguancun Lab, Huawei, and Beijing National Research Center for Information Science and Technology (BNRist).
@inproceedings{ijcai2025p404,
  title     = {AdaMixT: Adaptive Weighted Mixture of Multi-Scale Expert Transformers for Time Series Forecasting},
  author    = {Zhang, Huanyao and Lin, Jiaye and Zhang, Wentao and Yuan, Haitao and Li, Guoliang},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {3633--3641},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/404},
  url       = {https://doi.org/10.24963/ijcai.2025/404},
}
TY - CPAPER TI - AdaMixT: Adaptive Weighted Mixture of Multi-Scale Expert Transformers for Time Series Forecasting AU - Zhang, Huanyao AU - Lin, Jiaye AU - Zhang, Wentao AU - Yuan, Haitao AU - Li, Guoliang T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 3633 EP - 3641 DO - 10.24963/ijcai.2025/404 UR - https://doi.org/10.24963/ijcai.2025/404 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





