
Partially Observable Reference Policy Programming
Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence. Main Track. Pages 8536-8543.
https://doi.org/10.24963/ijcai.2025/949
Keywords
- Planning and Scheduling: PS: Planning under uncertainty
- Planning and Scheduling: PS: Planning with Incomplete Information
- Machine Learning: ML: Partially observable reinforcement learning and POMDPs
- Planning and Scheduling: PS: POMDPs
Abstract
This paper proposes Partially Observable Reference Policy Programming, a novel anytime online approximate POMDP solver which samples meaningful future histories very deeply while simultaneously forcing a gradual policy update. We provide theoretical guarantees for the algorithm’s underlying scheme which say that the performance loss is bounded by the average of the sampling approximation errors rather than the usual maximum; a crucial requirement given the sampling sparsity of online planning. Empirical evaluations on two large-scale problems with dynamically evolving environments—including a helicopter emergency scenario in the Corsica region requiring approximately 150 planning steps—corroborate the theoretical results and indicate that our solver considerably outperforms current online benchmarks.
- [Asadi and Littman, 2017] Kavosh Asadi and Michael Littman. An alternative softmax operator for reinforce- ment learning. In Proceedings of the 34th International Conference on Machine Learning -Volume 70, ICML'17, page 243-252, 2017.
- [Azar et al., 2011] Mohammed Gheshlaghi Azar, Vincenc ¸ Gómez, and Hilbert Kappen. Dynamic policy program- ming with function approximation. In Proceedings of the Fourteenth International Conference on Artificial Intelli- gence and Statistics, volume 15 of Proceedings of Ma- chine Learning Research, pages 119-127, 2011.
- [Azar et al., 2012] Mohammed Gheshlaghi Azar, Vincenc ¸ Gómez, and Hilbert Kappen. Dynamic policy program- ming. Journal of Machine Learning Research, 13:3207- 3245, 2012.
- [Blanchard et al., 2021] Pierre Blanchard, Desmond J. Higham, and Nicholas J. Higham. Accurately computing the log-sum-exp and softmax functions. IMA Journal of Numerical Analysis, 41:2311-2330, 2021.
- [Choset et al., 2005] Howie Choset, Kevin Lynch, Seth Hutchinson, George Kantor, Wolfram Burgard, Lydia Kavraki, and Sebastian Thrun. Principles of Robot Mo- tion: Theory, Algorithms and Implementation. MIT Press, 2005.
- [Dvijotham and Todorov, 2012] Krishnamurthy Dvijotham and Emmanuel Todorov. Linearly solvable optimal con- trol. Reinforcement learning and approximate dynamic programming for feedback control, pages 119-141, 2012.
- [Flaspohler et al., 2020] Genevieve Flaspohler, Nicholas Roy, and John W. Fisher III. Belief-dependent macro- action discovery in POMDPs using the value of infor- mation. In H. Larochelle, M. Ranzato, R. Hadsell, M.F. Balcan, and H. Lin, editors, Advances in Neural Informa- tion Processing Systems, volume 33, pages 11108-11118.
- Curran Associates, Inc., 2020.
- [H2RLab, 2024] H2RLab. pomdp py. https://h2r.github.io/ pomdp-py, 2024. Accessed: 2025-06-06. Link
- [He et al., 2010] Ruijie He, Emma Brunskill, and Nicholas Roy. PUMA: planning under uncertainty with macro- actions. In Maria Fox and David Poole, editors, Proceed- ings of the Twenty-Fourth AAAI Conference on Artificial Intelligence, AAAI 2010, Atlanta, Georgia, USA, July 11- 15, 2010, pages 1089-1095. AAAI Press, 2010.
- [Kaebling et al., 1998] Leslie Kaebling, Michael Littman, and Anthony Cassandra. Planning and acting in par- tially observable stochastic domains. Artificial Intelli- gence, 101:99-134, 1998.
- [Kim et al., 2023] Edward Kim, Yohan Karunanayake, and Hanna Kurniawati. Reference-based POMDPs. In A. Oh, T. Naumann, A. Globerson, K. Saenko, M. Hardt, and S. Levine, editors, Advances in Neural Information Pro- cessing Systems, volume 36, pages 40659-40675.
- Curran Associates, Inc., 2023.
- [Kurniawati et al., 2011] Hanna Kurniawati, Yanzhu Du, David Hsu, and Wee Sun Lee. Motion planning under uncertainty for robotic tasks with long time horizons. In- ternational Journal of Robotics Research, 30(3):308-323, 2011.
- [Kurniawati, 2022] Hanna Kurniawati. Partially observed Markov decision processes and robotics. Annual Review of Control, Robotics, and Autonomous Systems, 5:254-277, 2022.
- [Lee et al., 2007] Wee Lee, Nan Rong, and David Hsu. What makes some POMDP problems easy to approximate? In J. Platt, D. Koller, Y. Singer, and S. Roweis, editors, Ad- vances in Neural Information Processing Systems, vol- ume 20.
- Curran Associates, Inc., 2007.
- [Lee et al., 2021] Yiyuan Lee, Panpan Cai, and David Hsu. MAGIC: Learning Macro-Actions for Online POMDP Planning . In Proceedings of Robotics: Science and Sys- tems, July 2021.
- [Liang et al., 2024] Yuanchu Liang, Edward Kim, Wil Thomason, Zachary Kingston, Hanna Kurniawati, and Ly- dia Kavraki. Scaling long-horizon online POMDP plan- ning via rapid state space sampling. In Springer Proc. in Adv. Rob. (to appear), 2024. arXiv:2411.07032.
- [Madani et al., 2003] Omid Madani, Steve Hanks, and Anne Condon. On the undecidability of probabilistic planning and related stochastic optimization problems. Artificial In- telligence, 147:5-34, 2003.
- [Rawlik et al., 2012] Konrad Rawlik, Marc Toussaint, and Sethu Vijayakumar. On stochastic optimal control and re- inforcement learning by approximate inference. Proceed- ings of Robotics: Science and Systems VIII, 2012.
- [Silver and Veness, 2010] David Silver and Joel Veness. Monte-Carlo planning in large POMDPs. In J. Lafferty, C. Williams, J. Shawe-Taylor, R. Zemel, and A. Culotta, editors, Advances in Neural Information Processing Sys- tems, volume 23.
- Curran Associates, Inc., 2010.
- [Sunberg and Kochenderfer, 2018] Zachary Sunberg and Mykel Kochenderfer. Online algorithms for POMDPs with continuous state, action, and observation spaces. Proceedings of the International Conference on Auto- mated Planning and Scheduling, 28(1):259-263, Jun. 2018.
- [Theocharous and Kaelbling, 2003] Georgios Theocharous and Leslie Kaelbling. Approximate planning in POMDPs with macro-actions. In S. Thrun, L. Saul, and B. Schölkopf, editors, Advances in Neural Information Processing Systems, volume 16. MIT Press, 2003.
- [Todorov, 2006] Emanuel Todorov. Linearly-solvable Markov decision problems. In B. Schölkopf, J. Platt, and T. Hoffman, editors, Advances in Neural Information Pro- cessing Systems, volume 19. MIT Press, 2006.
- [Todorov, 2009a] Emmanuel Todorov. Efficient computation of optimal actions. Proceedings of the National Academy of Sciences, 106(28):11478-11483, 2009.
- [Todorov, 2009b] Emmanuel Todorov. Eigenfunction ap- proximation methods for linearly-solvable optimal control problems. In 2009 IEEE Symposium on Adaptive Dynamic Programming and Reinforcement Learning, pages 161- 168. IEEE, 2009.
- [Wang et al., 2018] Erli Wang, Hanna Kurniawati, and Dirk Kroese. An on-line planner for POMDPs with large dis- crete action space: a quantile-based approach. In Proceed- ings of the 28th International Conference on Aut. Plan. Sched., pages 273-77, Palo Alto, CA, 2018. AAAI Press.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Planning under uncertainty in non-deterministic and partially observable scenarios is critical for many (semi-)autonomous systems. Such problems can be systematically framed as a Partially Observable Markov Decision Process (POMDP) [Kaebling et al., 1998]. Although solving infinite-horizon POMDPs in the worst case is undecidable [Madani et al., 2003], the past decade has seen tremendous advances in the practicality of approximate POMDP solvers [Kurniawati, 2022]. Most of these solvers are online sampling-based methods that numerically compute estimates of the expected total reward of performing different actions before optimising over these estimates. Due to difficulties in computing gradients, such solvers exhaustively enumerate over the entire action space, which massively hinders fast computation of a closeto-optimal solution for problems with large action spaces and long horizons. This problem is even worse when the environment is also dynamically changing at each execution step.
The core difficulty is the curse of history where the set of possible futures branches by the size of the action space and grows exponentially with respect to the horizon. Most existing methods try to abstract the problem into a simpler one by either reducing the size of the action space [Wang et al., 2018] or relying on macro actions-i.e. a set of open-loop action sequences-to reduce the planning horizon [Theocharous and Kaelbling, 2003; He et al., 2010; Kurniawati et al., 2011; Flaspohler et al., 2020; Lee et al., 2021]. Still, the fundamental problem-i.e. exhaustive action enumeration-remains.
∗Technical details and proofs are contained in the Supplementary Material (https://github.com/RDLLab/pomdp-py-porpp).
Recently, [Kim et al., 2023; Liang et al., 2024] have softened this requirement by introducing the notion of a Reference-Based POMDP (RBPOMDP) which is a reformulation of a POMDP whose objective is penalised by the Kullback-Leibler (KL) divergence between a chosen and nominal reference policy. As such, a solution can be viewed as a KL-regularised improvement of the reference policy. The form of objective allows analytical action optimisation so that the value can be approximated by estimating expectations under the reference policy. This property accommodates solvers that have been shown to perform effectively on certain longhorizon tasks. However, the RBPOMDP formulation comes at the cost that the solution has a baked-in commitment to the reference policy. In general, it is unclear a priori which reference policies yield near optimal policies for the original POMDP of interest, so the performance of the computed solution is vulnerable to mis-specification.
The aim of this paper is to build on the advantages of the RBPOMDP framework while, in tandem, bolstering any vulnerabilities to mis-specification. To this end, our contribution is an exact iterative scheme (Sect. 3.2) whose successive policies can be viewed as solutions of a sequence of RBPOMDPs-i.e. KL-constrained policy improvements. Theoretical analysis shows that the performance loss of the exact scheme is bounded by the average of the sampling errors, which means the algorithm is less sensitive to large approximation errors (Theorem 1). We also contribute an explicit approximate scheme (Sect. 3.3) and provide a POMDPspecialised high-probability bound for the performance loss (Theorem 2). Finally, the scheme is practically implemented in our proposed algorithm Partially Observable Reference Policy Programming (PORPP)-an anytime online POMDPsolver-and tested on two non-trivial long-horizon POMDPs, one of which has a dynamically evolving environment. Experimental results indicate that PORPP substantially outperforms current state-of-the-art online POMDP benchmarks.
2 Background and RelatedWork
2.1 POMDP Preliminaries
An infinite-horizon POMDP is defined as the tuple ⟨S, A, O, Z, T , R, γ, b0⟩ where the sets of all possible agent states, actions and observations are denoted by S, A and O respectively. For clarity, our presentation is for countable sets. The transition model T is such that T (s′ | a, s) is the conditional probability that s′ ∈ S occurs after performing a ∈ A from s ∈ S. The observation model Z is such that Z(o | s′ , a) is the conditional probability that the agent perceives o ∈ O when it is in state s′ ∈ S after performing a ∈ A. The reward model is a real-valued function R : S × A → R such that |R(s, a)| ≤ Rmax < ∞ for all s, a and γ ∈ (0, 1) is the discount factor.
The agent does not know the true state, but it maintains a belief about its state-i.e. a probability distribution b on the space S. Let B be the set of all such distributions. Starting with a given initial belief b0, the agent's next belief b′ after taking the action a and perceiving some observation o is given by b′ (s′ ) ∝ Z(o | s′ , a) ∑s∈S T (s′ | a, s)b(s) and we write b′ = τ(b, a, o) with the belief update operator τ . We denote the set of reachable beliefs by Rb0 ⊂ B; i.e. the set of beliefs reachable from b0 under some policy. For any given belief b and action a the expected immediate reward is given by R(b, a) := ∑S R(s, a)b(s). The probability that the agent perceives an observation o ∈ O having performed the action a ∈ A under the belief b is given by
A (stochastic) policy is a mapping π : Rb0 → ∆(A). We denote its distribution for any given input b ∈ Rb0 by π(· | b). Let Π be the class of all stochastic policies. For any (b, a) ∈ Rb0 ×A, define the action-value functionQπ : Rb0 ×A→R recursively according to
Given the reward is uniformly bounded, for any policy π ∈ Π, we have |Qπ (b, a)| ≤ Qmax := Rmax/(1 - γ) for all pairs (b, a) ∈ Rb0 ×A. A solution to the POMDP is a policy π∗ ∈ Π satisfying Q∗ (b, a) := supπ∈ΠQπ (b, a) = Qπ∗ (b, a) for all (b, a) ∈ Rb0 × A.
2.2 POMDP Packing and Covering Numbers
For a Markov Decision Process (MDP) with finite state and action spaces, the usual input for complexity is the set cardinality |S||A| where it is generally assumed that the spaces are finite. However, for the POMDP, the reachable belief space Rb0 is an uncountable subset even if S is finite so the notion of set cardinality is no longer a sensible complexity input. A more reasonable approach is to choose a metric in R|S| , and estimate a "finite volume" of Rb0 via the dual concepts of a δ-packing or δ-covering number. While these are theoretical quantities, they can be explicitly computed in certain cases and highlight key properties relating to the POMDP's complexity [Lee et al., 2007].
The interested reader can refer to Sect. 1 of the Supplementary Material for a more thorough review of their formal definitions and properties. In words, the δ-covering number Cδ(Rb0 ) is the minimum number of balls of radius δ needed to cover the set Rb0 . If in addition, all the centres of the balls are required to belong to Rb0 then we call such a number the internal δ-covering number and denote it by C ◦ δ (Rb0 ). The δ-packing number Pδ(Rb0 ) is the maximum number of points that can be packed inside Rb0 such that all points are at least δ distance apart. The concepts are closely related and, importantly, are finite if and only if Rb0 is totally bounded (see Remark 1 in Supplementary Material). For instance, it suffices to assume that S is finite. To ensure the δ-covering number is always finite, we will make the following standing assumption for the remainder of this paper.
Assumption 1. The reachable belief space Rb0 is totally bounded.
2.3 KL-Penalisation and POMDPs
The idea of using KL-penalisation in fully observable MDPs started with a series of works on Linearly Solvable MDPs [Todorov, 2006; Todorov, 2009a; Todorov, 2009b; Dvijotham and Todorov, 2012]. The main idea is to find a control conditional distribution p(s′ | s) to a stochastic control problem where the control cost increases with the relative entropy between p(· | s) and some benchmark ¯ p(· | s). The formulation results in a Bellman backup which can be optimised analytically and yields efficient methods to solve a special class of fully-controllable MDPs.
These works were reformulated over stochastic actions by [Rawlik et al., 2012] and related to general MDPs by [Azar et al., 2011; Azar et al., 2012] who introduced Dynamic Policy Programming. This can be interpreted as a policy iteration scheme where each iterate πk is a solution to a specialised MDP whose reward decreases with the relative entropy KL(πk+1 ∥πk). The scheme can be shown to converge to the solution of the MDP; indeed, the gradual update forced by the KL-penalty yields performance bounds which depend on the average accumulated error as opposed to the usual maximum, suggesting robustness to approximation errors.
The extension of the idea of KL-penalised MDPs to POMDPs was provided by [Kim et al., 2023] who introduced the concept of a Reference-Based POMDP (RBPOMDP). In essence, the formulation can be viewed as a BeliefMDP [Kaebling et al., 1998] with policies U(b′ | b) that control transitions between POMDP beliefs where the reward is penalised by the relative entropy KL (U(· | b) ∥ ¯U(· | b)) for some reference policy ¯U. Their empirical results suggest that approximate solvers for RBPOMDPs can outperform stateof-the-art benchmarks on large POMDPs for certain choices of ¯U(· | b). However, the authors did not provide a systematic procedure to determine this choice. This current work addresses this gap by providing a systematic procedure, in a similar vein to [Azar et al., 2012],
3 PORPP
PORPP is an anytime online POMDP solver which approximates the solution of a policy iteration scheme whose successive policies are forced to be close to each other. Specifically, each policy iterate is a solution to a RBPOMDP over stochastic actions whose reference policy is the previous policy in the sequence and can therefore be viewed as a KL-constrained policy improvement. While this procedure converges more slowly, its advantage is that it yields a performance bound which is given by the average of approximation errors, suggesting that it is less prone to over-commitment-a useful feature given the scarcity of samples generated by an online planner. In what follows, ∥ · ∥∞ denotes the usual supremumnorm for bounded functions.
3.1 RBPOMDPs over Stochastic Actions
In [Kim et al., 2023], the reliance on belief-to-belief transitions U(b′ | b) implicitly allows the agent to control the choice of observation, which may not be valid in general. We will consider a more natural formulation over stochastic actions which will form the building blocks for the required systematic procedure. Namely, a RBPOMDP over stochastic actions is a tuple ⟨S,A,O, T ,Z,R, γ, η, π0, b0⟩. Its value V, for a given b ∈ Rb0 , is specified by the recursive equation
Intuitively its solution is a stochastic policy that tries to respect the reference policy π0 unless deviating substantially leads to greater rewards where the trade-off is balanced by the temperature parameter η > 0. The right-hand-side can be optimised analytically so that (3) is equivalent to
In fact, we can represent the Bellman equation (4) in a slightly different way by introducing preferences Ψ over belief-action pairs. More specifically, let
This yields V(b) = 1 η log [ ∑a exp[ηΨ(b, a)]] =: [LηΨ](b) where Lη is the log-sum-exp operator [Blanchard et al., 2021; Asadi and Littman, 2017] and eq. (4) stated with respect to preferences becomes
If Ψ∗ satisfies (6), the solution of the RBPOMDP is
3.2 Exact Scheme
We are now in a position to describe the exact iterative scheme that relates the RBPOMDP to that of the standard POMDP. Taking inspiration from (7), the scheme implicitly represents a reference policy πk by maintaining action preferences Ψk : Rb0 × A → R according to the equation
The policy is then updated gradually by asserting that πk+1 is the solution to a RBPOMDP whose reference policy is πk. That is,
The exact scheme indeed converges to the action-value Q∗ of the POMDP. To show this, let Lη be the exact function operator defined by (9) and consider a sequence of approximate preferences (ˆΨk)k≥0 such that ˆΨk+1 ≈Lη ˆΨk. For arbitrary (b, a) ∈ B ×A, let
and Ek(b, a) := ∑kj=0 ϵj(b, a) and define the approximating policy to be
We have the following general error bound which says that the total error is bounded by the average of approximation errors at each iteration. Since the exact scheme has Ek = 0 for all k, the result also validates the asymptotic convergence of the exact scheme.
Theorem 1. Suppose ∥ˆΨ0∥∞ ≤ Qmax. Then
Proof. See Supplementary Material.
3.3 Explicit Sampling-Based Approximate Scheme
We will now introduce explicit synchronous and asynchronous sampling-based approximate schemes and prove their asymptotic optimality. In both cases, we prove specialised bounds with respect to the POMDP's δ-covering numbers. The asynchronous scheme is especially important, as it forms the basis for the design of our online planning algorithm.
We will need some setting up to introduce the samplingbased scheme that approximates (9). Let ρ be a metric on B and B be some well-ordered 1 subset of B. Let ˜ τB,ρ : B×A× O → B be the mapping which takes an arbitrary belief b ∈ B to the least element of
Intuitively, ˜ τB,ρ finds the set of points in B nearest to τ(b, a, o) (it is not necessarily a singleton set) and has a rule to break ties so that the mapping is well-defined.
Let QπB,ρ : Rb0 × A → R be the action-value approximation on any subset B ⊂ Rb0 which is the unique solution to the recursion
The difference between (2) and (14) is that the next belief is forced to a nearest belief in B ⊂ Rb0 in the latter, whereas the belief update for the former is the natural one. As such, we expect the two quantities to differ according to the precision of B in approximating Rb0 . In fact, it can be shown that if B is a δ-covering of Rb0 the approximation becomes negligible for the optimal policy π∗ as δ ↓ 0 (see Proposition 3 in the Supplementary Material).
It is clear from (14) that it suffices to evaluate QπB,ρ on the subset B × A. The synchronous scheme therefore updates action preference approximations according to the rule
for all (b, a) ∈ B × A where si ∼ b and oj ∼ P(· | a, b) and generic increasing sequences Nk and Mk having the property that Nk(b, a) ↑ ∞, Mk(b, a) ↑ ∞ as k ↑ ∞. The scheme is synchronous in the sense that, at each step k, it samples {sNk-1(b,a)+1, . . . , sNk(b,a), oMk-1(b,a)+1, . . . , oMk(b,a)} for each (b, a) and updates the action preferences according to (15). The approximate stochastic policy ˆπk is then fully specified by the approximate preferences according to (11).
The synchronous scheme yields the following highprobability bound when B is an internal δ-covering Eδ of Rb0
1 It suffices for B to be finite.
for the metric ρ1 induced by the 1-norm-i.e. ρ1(x, y) := ∥x - y∥1 for x, y ∈ R|S|-1 . 2
Theorem2. Let C ◦ δ = |Eδ| be the internal δ-covering number of Rb0 for a given δ > 0. If ∥ˆΨ0∥ ≤ Qmax then, for any α ∈ (0, 1), we have with probability at least 1 - α
where
and
Proof. See Supplementary Material.
Although the precision of the bound gets more precise after every synchronous update, the error can still be large if the covering Eδ is not a good representation of Rb0 -i.e. δ is large. In general, Eδ may be required to be extremely large and performing even one synchronous update can be an exorbitantly expensive task.
To mitigate this fundamental problem, PORPP employs a heuristic action sampler ˜π to bias towards a selection of promising beliefs and asynchronously updates preference approximations on the selection. The underpinning assumption for optimality of this procedure is that the selection grows to include the set of beliefs reachable under the optimal policy π∗-which is not known a priori-while simultaneously being small enough to be tractable for online planning.
More precisely, let Eδ be an internal δ-covering of Rb0 and let Ωk := ((b1, a1), (b2, a2), . . . , (bk, ak)) be the sequence of pairs in Eδ ×A traversed by ˜π after k steps. Then, by definition, our asynchronous scheme updates action preference approximations according to
where si ∼ bk and oj ∼ P(· | ak, bk) and N(bk, ak) is the number of times ˜π has visited (bk, ak). Let R∗b0 be the set of beliefs reachable under the optimal policy π∗ of the POMDP and denote by κk the number of times that ˜π has visited Ω∞ after k steps. Then, provided ˜π traverses Ω∞ infinitely often and {b : (b, a) ∈ Ω∞} ⊃ R∗b0 ∩ Eδ, the bounds of Theorem 2 hold with (16) replaced by
2 Note that the Euclidean space under consideration can, in theory, be infinite-dimensional under Assumption 1.
Algorithm 1 PORPP
Input: Root node h0 of T equipped with belief particles b Output: T
- 1: while steps remaining do
- 2: while time permitting do
- 3: Sample belief particle s from h0 4: SIMULATE(h0, s, 0) 5: end while 6: a ← argmaxa∈children(h0) ˆΨ(h0a) 7: Execute macro action a in environment 8: Receive macro observation o from environment 9: Update history h0 ← h0ao 10: Resample new state particles and add to h0 11: end while
for Q∗ and Qˆπk Eδ ,ρ1 being functions defined on Ω∞ and C ◦ δ now being the δ-covering number of Ω∞. As such, we would like to ensure that Ω∞ is as small as possible without compromising optimality.
3.4 Algorithm: PORPP
We propose Partially Observable Reference Policy Programming (PORPP), a specific online implementation of the asynchronous scheme discussed above. PORPP represents beliefs as nodes h in a tree where each node is associated with a history of action-observation pairs and maintains a belief estimate by progressively sampling a richer set of state particles at each node. With enough time, the planner grows a rich tree (i.e. δ small) and improves preference estimates by sampling sequences of action-observation histories up to a required depth Dmax and backing up estimates according to the sampling-based scheme.
Specifically, at each history, PORPP's heuristic action sampler SAMPLECANDIDATEACTION(h, s) uses domain specific knowledge about the problem to propose a (macro) action a-i.e. a sequence of primitive actions-to add to the tree. The aim of the sampler is to sample actions that cover the optimal policy while avoiding counterproductive onessee Sec. 3.6 for examples. The action is added to the tree if it has not been already and the progressive widening threshold κAN(h)αA (e.g. [Sunberg and Kochenderfer, 2018]) has not been exceeded. PORPP then selects an action by sampling the softmax distribution given by the current preferences-cf. (11)-before sampling a new state s′ , (macro) observation o and (macro) reward r(s, a; γ) using a generative model. The observation is then added to the tree, and the procedure continues recursively until the depth exceeds Dmax. At this point the value is estimated from the sampled state using a value heuristic and the information is propagated back up to the root node via (19) (lines 18 to 23 in Algorithm 2).
This planning procedure continues until timeout (lines 2 to 5 in Algorithm 1) after which the algorithm executes the action with the best sampled preference in the environment. Upon receiving an observation, particles that are consistent with the realised action-observation pair are resampled and added to the associated node (line 10 in Algorithm 1). This planning-execution loop continues until a step budget is reached, at which point the algorithm terminates.
Parameters: κA ≥ 0, αA ∈ (0, 1), Dmax ≥ 1, η > 0. 1: if depth >Dmax then 2: return VALUEHEURISTIC(h, s) 3: end if 4: if depth > 0 then 5: b(h) ← b(h) ∪ {s} 6: end if 7: N(h) ←N(h) +1 8: if |children(h)| < κAN(h)αA then 9: a ← SAMPLECANDIDATEACTION(h, s) 10: if ha /∈ T then 11: Add ha to T 12: end if 13: end if 14: a ← SAMPLEPREFSOFTMAX(h; η) 15: Resample s from b(h) 16: Sample (s′ , o, r(s, a; γ)) from gen. model G (s, a) 17: Create nodes for hao if not created already 18: N(ha) ←N(ha) +1 19: R(ha) ←R(ha) + r(s,a;γ)-R(ha) N(ha) 20: D(ha) ←D(ha) + SIMULATE(hao,s′ ,depth+|a|)-D(ha) N(ha) 21: ˆΨ(ha) ← ˆΨ(ha) -V(h) +R(ha) +γ |a|D(ha) 22: V(h) ← log {∑a∈children(h) exp[η ˆΨ(ha)]}/η 23: return V(h)3.5 Problem Scenarios
We evaluated the performance of PORPP on two challenging long-horizon POMDPs.
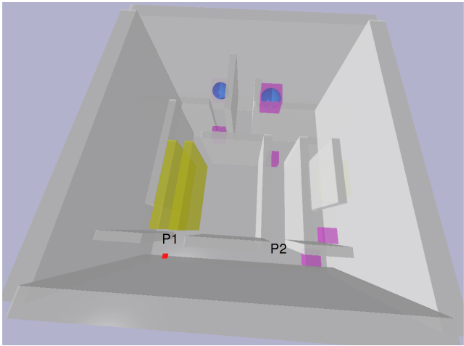
3D Maze with Poor Localisation. A 3-dimensional holonomic cuboid drone needs to navigate to one of two goal regions in a closed maze with very poor localisation (Figure 1). The state of the robot is represented by a continuous 3dimensional co-ordinate for its centre of mass, and the robot can move continuously in any direction of fixed magnitude (i.e. v = 1) plus some mean zero (Gaussian) noise with covariance matrix I × 0.02 × v and any movement conforms to the "walls" of the environment. However, the robot does not know its true state and only knows that it can spawn at two starting positions with equal probability (Figure 1). The robot can only localise its co-ordinate if it comes in contact with a landmark where it receives an observation of its true position; otherwise, it receives no feedback about its position. The scenario terminates if the robot comes in contact with a danger zone-which incurs a penalty of -500-or reaches the goal-which yields a reward of 2000. A step penalty of -5 is incurred in all other cases. This is a long-horizon problem requiring 100 steps to reach the goal while simultaneously navigating around danger zones.
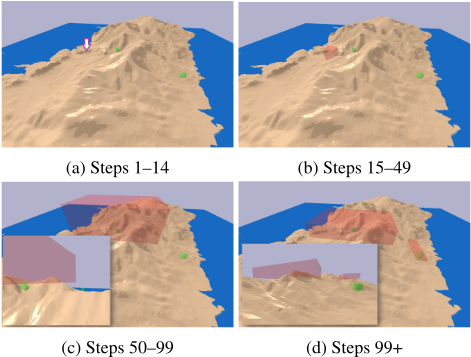
HEMSMission with Evolving No-Fly-Zones. We considered a Helicopter Emergency Medical Service (HEMS) mission set on the Cap Corse peninsula in Corsica (Figure 2). The mesh used to generate the terrain was extracted from X-Plane 12. The mission objective is to navigate a holonomic helicopter starting from the west end of the island (arrow in Figure 2 (a)) to two unordered objectives-i.e. the victim's locations (green balls in Figure 2) where the agent receives a reward of 2000 for each new objective achieved. The mission ends if there is a collision (which incurs a reward penalty of -2000) or both objectives are achieved-i.e. the mission is accomplished-which yields an additional reward of 20000. The scenario is complicated by the fact that no-fly-zones (NFZs) evolve at fixed time steps that are unknown to the agent (see Figure 2). The agent need not avoid NFZs entirely, but incurs an additional penalty of -20 for each step inside a NFZ. We assume that the agent has no predictive model of when NFZs will appear; hence, the agent only re-plans with respect to reward changes due to NFZ evolutions. To encourage the agent to achieve the objective, a step penalty of -5 is incurred at each time step. The state of the helicopter is fully specified by a continuous 3-dimensional co-ordinate representing the helicopter's centre of mass (its orientation is always fixed)-notice that fuel and weight of the craft are not considerations-and actions are the continuous directional vectors of a fixed magnitude v = 2 (i.e. the helicopter's speed) representing the agent's intended direction of movement. Transitions in the intended direction and readings of the true state of the helicopter are subject to Gaussian noise with covariance matrices I × 0.25 × v and I × 0.2 respectively. This problem is a long-horizon problem often requiring a minimum of 150 steps to accomplish the mission without consideration of NFZs.
3.6 Heuristic Action Sampler
One crucial factor in the overall performance of PORPP is the heuristic action sampler SAMPLECANDIDATEACTION(h, s). We stress that the heuristic action sampler is not a solution to the POMDP; indeed, the heuristic sampler need not account for uncertainty being a function of a determined state. Rather, its fundamental purpose is to exploit domain-specific knowledge to propose promising actions to explore given a belief.
In both environments, our specific implementation of this subroutine relies on an offline-generated Probabilistic Roadmap (PRM) [Choset et al., 2005] to represent the environment's collision-free configuration space. Based on the input particle an objective in the environment's configuration space is sampled and collision-free paths to the sampled objective are queried from the PRM. That is,
- For the 3D maze, a random landmark or goal region is sampled and targeted and the shortest path on the PRM starting from the position given by the state particle to the target is returned.
- For the Corsica map, the state s records which victims have been visited. Accordingly, a simple homotopic collision-free path starting from the helicopter's position (as recorded in s) and ending at a random unvisited victim location is sampled.
The returned paths are then truncated at a fixed length, and a macro action which traces the path is returned.
3.7 BenchmarkMethods
The benchmarks used for comparison are:
- RefPol. This simply samples a state particle and executes the action returned by the heuristic action sampler without further POMDP planning.
- RefSolver. The solver from [Kim et al., 2023] a RBPOMDP which uses the heuristic action sampler as its reference policy.
- POMCP-[Silver and Veness, 2010]. The canonical benchmark to beat for online POMDP planning. For a fair comparison, it expands 16 macro actions composed of equally spaced directional vectors.
| Planners | Time (s) | Succ. % | E[Tot. Reward] |
|---|---|---|---|
| PORPP | 1 | 71 | 570.3 ± 183.5 |
| 2 | 75 | 628.9 ± 191.3 | |
| 3 | 80 | 625.0 ± 215.2 | |
| 5 | 81 | 688.3 ± 200.1 | |
| 10 | 88 | 873.4 ± 172.1 | |
| 15 | 94 | 983.1 ± 168.0 | |
| RefSolver | 2 | 39 | -244.6 ± 224.5 |
| 3 | 38 | -278.9 ± 216.5 | |
| 5 | 26 | -544.9 ± 204.6 | |
| 10 | 30 | -384.0 ± 213.3 | |
| POMCP | 2 | 10 | -786.3 ± 378.0 |
| 3 | 9 | -1637.3 ± 256.8 | |
| 5 | 7 | -2150.8 ± 161.0 | |
| 10 | 13 | -1897.5 ± 240.1 | |
| RefPol | N/A | 29 | -572.2 ± 231.1 |
3.8 Experimental Setup
All experiments were performed on a desktop computer with 128GB DDR4 RAM and an 8 Core Intel Xeon Silver 4110 Processor. All solvers were implemented in the pomdp py library [H2RLab, 2024] and Cythonised for a fair comparison. The discount factor for all environments was γ = 0.99. 3
3.9 Results and Discussion
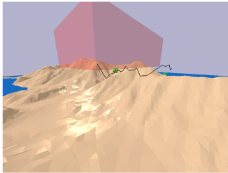
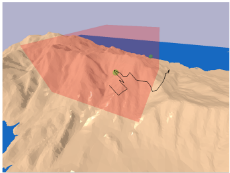
Results are summarised in Table 1 and Table 2. In both scenarios we ran RefPol to corroborate our claim that the heuristic action sampler is significantly sub-optimal. Still, PORPP was able leverage the heuristic action sampler to significantly outperform both benchmarks yielding very high success rates with >10 seconds of planning time. As expected from our theoretical analysis, the results improve in trend with the planning time. Notably, RefSolver does not improve quite as much PORPP which seems consistent with the idea that RefSolver is converging to a policy which is somewhere in between the reference policy and the optimal policy of the POMDP. POMCP, meanwhile, was myopic in both scenarios and could not take advantage of deep rewards even when helped by macro actions because of the need to exhaustively enumerate. Interestingly, in the HEMS mission, we typically observe the PORPP policy trace non-trivially adapting to the environment (Figure 3).
4 Summary
This paper presents PORPP an online particle-based anytime POMDP solver which provably approximates a gradual KLconstrained iterative scheme making it robust to large approximation errors. Empirical results indicate the feasibility of our planner for large-scale POMDPs showing that it outperforms existing benchmarks for the long-horizon POMDPs with evolving environments presented in this paper.
3 See https://github.com/RDLLab/pomdp-py-porpp for the code and parameters used to run the experiments.
| Planners | Time (s) | Succ. % | E[Tot. Reward] |
|---|---|---|---|
| PORPP | 1 | 58 | 11393.5 ± 1588.4 |
| 2 | 75 | 15408.8 ± 1399.3 | |
| 3 | 78 | 16207.7 ± 1316.7 | |
| 5 | 78 | 16231.6 ± 1320.2 | |
| 10 | 90 | 19393.5 ± 967.9 | |
| RefSolver | 2 | 2 | -1453.9 ± 947.8 |
| 3 | 4 | -860.6 ± 1297.7 | |
| 5 | 28 | 3514.9 ± 3043.1 | |
| 10 | 22 | 2258.7 ± 2809.2 | |
| POMCP | 2 | 2 | -410.5 ± 900.0 |
| 3 | 0 | -942.5 ± 181.1 | |
| 5 | 2 | -421.8 ± 928.1 | |
| 10 | 0 | -839.6 ± 227.4 | |
| RefPol | N/A | 0 | -6584.3 ± 379.5 |
For future work, we would like to examine the solver on non-holonomic problems (realistic ODE approximations of helicopter dynamics, robotic manipulators, etc.) with more complex domains (e.g. HEMS fire and flood rescue scenarios). We would also like to systematically stress test PORPP with respect to different parameter settings and choices of heuristic samplers.
Acknowledgments
This work was supported by Safran Electronics & Defense Australia Pty Ltd and Safran Group under the ARC Linkage project LP200301612.
@inproceedings{ijcai2025p949,
  title     = {Partially Observable Reference Policy Programming},
  author    = {Kim, Edward and Kurniawati, Hanna},
  booktitle = {Proceedings of the Thirty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-25}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {James Kwok},
  pages     = {8536--8543},
  year      = {2025},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2025/949},
  url       = {https://doi.org/10.24963/ijcai.2025/949},
}
TY - CPAPER TI - Partially Observable Reference Policy Programming AU - Kim, Edward AU - Kurniawati, Hanna T2 - Proceedings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2025 SP - 8536 EP - 8543 DO - 10.24963/ijcai.2025/949 UR - https://doi.org/10.24963/ijcai.2025/949 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





