
Semantically Labelled Automata for Multi-Task Reinforcement Learning with LTL Instructions
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 3-11.
https://doi.org/10.24963/ijcai.2026/1
Keywords
- Knowledge Representation and Reasoning: Reasoning about actions
- Knowledge Representation and Reasoning: Learning and reasoning
- Machine Learning: Multi-task and transfer learning
- Agent-based and Multi-agent Systems: Formal verification, validation and synthesis
- Machine Learning: Reinforcement learning
Abstract
We study multi-task reinforcement learning (RL), a setting in which an agent learns a single, universal policy capable of generalising to arbitrary, possibly unseen tasks. We consider tasks specified as linear temporal logic (LTL) formulae, which are commonly used in formal methods to specify properties of systems, and have recently been successfully adopted in RL. In this setting, we present a novel task embedding technique leveraging a new generation of semantic LTL-to-automata translations, originally developed for temporal synthesis. The resulting semantically labelled automata contain rich, structured information in each state that allow us to (i) compute the automaton efficiently on-the-fly, (ii) extract expressive task embeddings used to condition the policy, and (iii) naturally support full LTL. Experimental results in a variety of domains demonstrate that our approach achieves state-of-the-art performance and is able to scale to complex specifications where existing methods fail.
- [Abate et al., 2026] Alessandro Abate, Giuseppe De Gia- como, Mathias Jackermeier, Jan Kretínský, Maximilian Prokop, and Christoph Weinhuber. Semantically labelled automata for multi-task reinforcement learning with ltl in- structions, 2026.
- [Aminof et al., 2025] Benjamin Aminof, Giuseppe De Gi- acomo, Sasha Rubin, and Moshe Y. Vardi. Ltlf+ and PPLTL+: extending ltlf and PPLTL to infinite traces. In IJCAI, pages 8447-8455. ijcai.org, 2025. IJCAI
- [Bacchus and Kabanza, 1996] Fahiem Bacchus and Frodu- ald Kabanza. Planning for temporally extended goals. In AAAI/IAAI, Vol. 2, pages 1215-1222. AAAI Press / The MIT Press, 1996.
- [Bozkurt et al., 2020] Alper Kamil Bozkurt, Yu Wang, Michael M. Zavlanos, and Miroslav Pajic. Control synthe- sis from linear temporal logic specifications using model- free reinforcement learning. In ICRA, pages 10349-10355. IEEE, 2020.
- [Brázdil et al., 2014] Tomás Brázdil, Krishnendu Chatterjee, Martin Chmelik, Vojtech Forejt, Jan Křetínský, Marta Z. Kwiatkowska, David Parker, and Mateusz Ujma. Verifi- cation of markov decision processes using learning algo- rithms. In ATVA, volume 8837 of Lecture Notes in Com- puter Science, pages 98-114. Springer, 2014.
- [De Giacomo et al., 2025] Giuseppe De Giacomo, Yong Li, Sven Schewe, Christoph Weinhuber, and Pian Yu. Solv- ing mdps with ltlf+ and PPLTL+ temporal objectives. In IJCAI, pages 8491-8499. ijcai.org, 2025. IJCAI
- [Esparza and Křetínský, 2014] Javier Esparza and Jan Křetínský. From LTL to deterministic automata: A safraless compositional approach. In Armin Biere and Roderick Bloem, editors, Computer Aided Verification - 26th International Conference, CAV 2014, Held as Part of the Vienna Summer of Logic, VSL 2014, Vienna, Austria, July 18-22, 2014. Proceedings, volume 8559 of Lecture Notes in Computer Science, pages 192-208. Springer, 2014.
- [Esparza et al., 2020] Javier Esparza, Jan Křetínský, and Sa- lomon Sickert. A unified translation of linear temporal logic to ω-automata. J. ACM, 67(6):33:1-33:61, 2020.
- [Giuri et al., 2025] Mattia Giuri, Mathias Jackermeier, and Alessandro Abate. Zero-shot instruction following in rl via structured LTL representations. In ICML Workshop on Programmatic Representations for Agent Learning, 2025.
- [Guo et al., 2025] Zijian Guo, Ilker Isik, H. M. Sabbir Ah- mad, and Wenchao Li. One subgoal at a time: Zero-shot generalization to arbitrary linear temporal logic require- ments in multi-task reinforcement learning. In NeurIPS, 2025.
- [Hahn et al., 2019] Ernst Moritz Hahn, Mateo Perez, Sven Schewe, Fabio Somenzi, Ashutosh Trivedi, and Dominik Wojtczak. Omega-regular objectives in model-free rein- forcement learning. In TACAS (1), volume 11427 of Lec- ture Notes in Computer Science, pages 395-412. Springer, 2019.
- [Hahn et al., 2022] Ernst Moritz Hahn, Mateo Perez, Sven Schewe, Fabio Somenzi, Ashutosh Trivedi, and Dominik Wojtczak. An impossibility result in automata-theoretic reinforcement learning. In Automated Technology for Ver- ification and Analysis: 20th International Symposium, ATVA 2022, Virtual Event, October 25-28, 2022, Pro- ceedings, page 42-57, Berlin, Heidelberg, 2022. Springer- Verlag.
- [Hasanbeig et al., 2022] Mohammadhosein Hasanbeig, Daniel Kroening, and Alessandro Abate. LCRL: certified policy synthesis via logically-constrained reinforcement learning. In QEST, volume 13479 of Lecture Notes in Computer Science, pages 217-231. Springer, 2022.
- [Jackermeier and Abate, 2025] Mathias Jackermeier and Alessandro Abate. Deepltl: Learning to efficiently satisfy complex LTL specifications for multi-task RL. In ICLR. OpenReview.net, 2025.
- [Křetínský and Esparza, 2012] Jan Křetínský and Javier Es- parza. Deterministic automata for the (f, g)-fragment of LTL. In P. Madhusudan and Sanjit A. Seshia, editors, Computer Aided Verification -24th International Confer- ence, CAV 2012, Berkeley, CA, USA, July 7-13, 2012 Pro- ceedings, volume 7358 of Lecture Notes in Computer Sci- ence, pages 7-22. Springer, 2012.
- [Křetínský et al., 2018] Jan Křetínský, Tobias Meggendor- fer, and Salomon Sickert. Owl: A library for ω-words, au- tomata, and LTL. In Shuvendu K. Lahiri and Chao Wang, editors, Automated Technology for Verification and Anal- ysis -16th International Symposium, ATVA 2018, Los An- geles, CA, USA, October 7-10, 2018, Proceedings, volume 11138 of Lecture Notes in Computer Science, pages 543- 550. Springer, 2018.
- [Křetínský et al., 2019] Jan Křetínský, Alexander Manta, and Tobias Meggendorfer. Semantic labelling and learning for parity game solving in LTL synthesis. In ATVA, vol- ume 11781 of Lecture Notes in Computer Science, pages 404-422. Springer, 2019.
- [Křetínský et al., 2023] Jan Křetínský, Tobias Meggendor- fer, Maximilian Prokop, and Sabine Rieder. Guessing win- ning policies in LTL synthesis by semantic learning. In CAV (1), volume 13964 of Lecture Notes in Computer Sci- ence, pages 390-414. Springer, 2023.
- [Křetínský et al., 2025] Jan Křetínský, Tobias Meggendor- fer, Maximilian Prokop, and Ashkan Zarkhah. Semml: Enhancing automata-theoretic LTL synthesis with ma- chine learning. In TACAS (1), volume 15696 of Lec- ture Notes in Computer Science, pages 233-253. Springer, 2025.
- [León et al., 2022] Borja G. León, Murray Shanahan, and Francesco Belardinelli. In a nutshell, the human asked for this: Latent goals for following temporal specifications. In ICLR. OpenReview.net, 2022.
- [Li et al., 2013] Jianwen Li, Lijun Zhang, Geguang Pu, Moshe Y. Vardi, and Jifeng He. Ltl satisfiability checking revisited. In Proceedings of the 2013 20th International Symposium on Temporal Representation and Reasoning, TIME '13, page 91-98, USA, 2013. IEEE Computer So- ciety.
- [Liu et al., 2022] Minghuan Liu, Menghui Zhu, and Weinan Zhang. Goal-conditioned reinforcement learning: Prob- lems and solutions. In IJCAI, pages 5502-5511. ijcai.org, 2022. IJCAI
- [Liu et al., 2024] Jason Xinyu Liu, Ankit Shah, Eric Rosen, Mingxi Jia, George Konidaris, and Stefanie Tellex. Skill transfer for temporal task specification. In ICRA, pages 2535-2541. IEEE, 2024.
- [Oh et al., 2017] Junhyuk Oh, Satinder Singh, Honglak Lee, and Pushmeet Kohli. Zero-shot task generalization with multi-task deep reinforcement learning. CoRR, abs/1706.05064, 2017.
- [Pnueli, 1977] Amir Pnueli. The temporal logic of programs. In FOCS, pages 46-57. IEEE Computer Society, 1977.
- [Qiu et al., 2023] Wenjie Qiu, Wensen Mao, and He Zhu. In- structing goal-conditioned reinforcement learning agents with temporal logic objectives. In NeurIPS, 2023.
- [Sadigh et al., 2014] Dorsa Sadigh, Eric S. Kim, Samuel Coogan, S. Shankar Sastry, and Sanjit A. Seshia. A learn- ing based approach to control synthesis of markov decision processes for linear temporal logic specifications. In CDC, pages 1091-1096. IEEE, 2014.
- [Scarselli et al., 2009] Franco Scarselli, Marco Gori, Ah Chung Tsoi, Markus Hagenbuchner, and Gabriele Monfardini. The graph neural network model. IEEE Trans. Neural Networks, 20(1):61-80, 2009.
- [Schulman et al., 2017] John Schulman, Filip Wolski, Pra- fulla Dhariwal, Alec Radford, and Oleg Klimov. Proximal policy optimization algorithms. CoRR, abs/1707.06347, 2017.
- [Sickert and Esparza, 2020] Salomon Sickert and Javier Es- parza. An efficient normalisation procedure for linear tem- poral logic and very weak alternating automata. In Pro- ceedings of the 35th Annual ACM/IEEE Symposium on Logic in Computer Science, LICS '20, page 831-844, New York, NY, USA, 2020. Association for Computing Ma- chinery. [Sickert et al., 2016] Salomon Sickert, Javier Esparza, Ste- fan Jaax, and Jan Křetínský. Limit-deterministic büchi automata for linear temporal logic. In CAV (2), volume 9780 of Lecture Notes in Computer Science, pages 312- 332. Springer, 2016.
- [Sutton and Barto, 2018] Richard S. Sutton and Andrew G. Barto. Reinforcement learning -an introduction, 2nd Edi- tion. MIT Press, 2018.
- [Sutton et al., 1999] Richard S. Sutton, Doina Precup, and Satinder Singh. Between mdps and semi-mdps: A frame- work for temporal abstraction in reinforcement learning. Artif. Intell., 112(1-2):181-211, 1999.
- [Vaezipoor et al., 2021] Pashootan Vaezipoor, Andrew C. Li, Rodrigo Toro Icarte, and Sheila A. McIlraith. Ltl2action: Generalizing LTL instructions for multi-task RL. In ICML, volume 139 of Proceedings of Machine Learning Re- search, pages 10497-10508. PMLR, 2021.
- [Voloshin et al., 2023] Cameron Voloshin, Abhinav Verma, and Yisong Yue. Eventual discounting temporal logic counterfactual experience replay. In ICML, volume 202 of Proceedings of Machine Learning Research, pages 35137-35150. PMLR, 2023.
- [Weinhuber et al., 2026] Christoph Weinhuber, Giuseppe De Giacomo, Yong Li, Sven Schewe, and Qiyi Tang. Good- for-mdp state reduction for stochastic ltl planning. In AAAI. AAAI Press, 2026.
- [Xu and Fekri, 2024] Duo Xu and Faramarz Fekri. Gener- alization of temporal logic tasks via future dependent op- tions. Mach. Learn., 113(10):7509-7540, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Developing reinforcement learning (RL) agents capable of executing complex, temporally extended tasks, such as those expressed in Linear Temporal Logic (LTL) [Pnueli, 1977], is an active area of research in artificial intelligence. A long line of existing research investigates training RL agents to execute a single LTL instruction [Sadigh et al., 2014; Br´azdil et al., 2014; Hahn et al., 2019; Hasanbeig et al., 2022; Voloshin et al., 2023]. Traditionally, the inherent memory requirement of LTL specifications is addressed by constructing an automaton (typically a variant of a B¨uchi automaton) corresponding to the LTL specification. However, this couples the resulting policy to that specific LTL formula. Consequently, even minor changes in the objective, e.g. altering the items that a warehouse robot needs to collect, requires retraining the agent. Thus, single-task approaches are ineffective at agent deployment time, where retraining is infeasible, or when task specifications change frequently.
∗ For full version and appendicies see [Abate et al., 2026]
As a result, recent years have seen increased interest in the multi-task RL setting [Oh et al., 2017]. Generally speaking, multi-task RL focuses on training a single, generalist policy capable of executing arbitrary tasks that may not be known apriori. Intuitively, such a policy learns a set of reusable behaviours and how to compose them in order to achieve new tasks. This is particularly challenging for LTL tasks, as the agent must additionally manage the required memory.
Recent approaches to tackle multi-task RL with LTL specifications can be broadly categorised into decomposition-based methods [Le´on et al., 2022; Qiu et al., 2023; Guo et al., 2025], which break down the objective into several subtasks, and holistic approaches that consider the full specification [Vaezipoor et al., 2021; Xu and Fekri, 2024; Jackermeier and Abate, 2025]. While decomposition into subtasks facilitates generalisation by allowing the agent to recombine learned subtask policies, it may lead to suboptimal solutions due to missing context. For instance, given the task "approach shelf, then pick up hammer", a warehouse robot focusing only on the first objective is unaware of which shelf to approach. To avoid these kinds of problems, holistic approaches seek policies that consider the full context of the task. This, however, is significantly more challenging, as the generalisation must be achieved solely through learning, which necessitates an amenable task embedding. In particular, arbitrary tasks must be embedded in a finite-dimensional feature space that preserves the semantic similarity of tasks, while also effectively encoding the necessary memory.
Our contribution. In this paper, we propose novel task embeddings based on a new generation of LTL-to-automata translations [Esparza and Kˇret´ınsk´y, 2014; Esparza et al., 2020]. Unlike traditional translations, these approaches are semantic: each automaton state is annotated with additional information (so-called semantic labelling) that intuitively describes the semantic meaning of that state. Recent work already exploited semantic labelling successfully in challenging problems from formal methods such as parity game solving [Kˇret´ınsk´y et al., 2019; Kˇret´ınsk´y et al., 2023] and reactive synthesis [Kˇret´ınsk´y et al., 2025]. In this work, we demonstrate that semantic labelling enables an effective embedding of arbitrary LTL tasks, while naturally addressing their memory requirements. In contrast to previous methods, our approach is both (i) applicable to full LTL and (ii) lightweight, as it can be computed efficiently on the fly. Finally, we design a policy around these embeddings and demonstrate that this enables successful generalisation to specifications of previously infeasible complexity.
2 Preliminaries
Linear temporal logic. Let AP be a finite set of atomic propositions. LTL formulas are generated by φ ::= tt | a | ¬φ | φ ∧ φ | Xφ | φ U φ. where a ∈ AP, and X ("Next"), U ("Until") are temporal operators. Further, we define the common abbreviations , F φ ≡ tt Uφ ("Finally/Eventually") and Gφ ≡ ¬F¬φ ("Globally/Always") [Pnueli, 1977].
An ω-word w is an infinite sequence of letters w[0] w[1] w[2] . . . with w[i] ∈ Σ = 2AP . We denote the infinite suffix w[i] w[i+1] . . . by wi and present the full satisfaction relation w |= φ in Appendix A.1. The language of φ, is the set of all satisfying words, denoted by [φ]. LTL has several fragments, most prominently Safety and Guarantee. Intuitively, they denote that something bad never happens and that something good happens eventually, respectively. Further, we consider recurrence (a guarantee holds infinitely often) and persistence (a safety formula holds eventually).
Limit-deterministic B¨uchi automata. We define a limitdeterministic B¨uchi automaton (LDBA) as a tuple B = (Q, Σ, δ, E, q0, F ), where Q is a finite set of states, Σ := 2AP is an alphabet, δ : Q × Σ → Q is a transition function, E : Q → 2Q are (non-deterministic) epsilon transitions, q0 ∈ Q the initial state, and F ⊆ Q is a set of accepting states, satisfying the following. There exists a partitioning Q = QI ⊎ QA such that (i) the transition function never changes the component, (ii) epsilon transitions only exist from QI to QA, (iii) every accepting state is in QA, and (iv) the initial state is in QI .
A run on an ω-word ω = σ0σ1 · · · is an infinite sequence of states q0q1 · · · that begins in the initial state and evolves according to the transition function except for at most one index where it may take an ϵ-transition to QA and remain in QA thereafter. Let j be the index of the epsilon transition. Then, formally, for all i ≥ 0 with i ̸= j, qi+1 = δ(qi, σi) and qj ∈ QI, qj+1 ∈ E(qj). A run is accepting if it visits F infinitely often and a word is accepted by the LDBA if there exists at least one accepting run. For any LTL formula φ there exists an LDBA that accepts [φ], e.g. [Sickert et al., 2016].
Markov decision processes. We define a Markov decision process (MDP) as a tuple M = (S,A, P, µ, r, γ), where S is the state space, A the action space, P : S ×A → ∆(S) the (unknown) transition kernel, µ ∈ ∆(S) the initial state distribution, r : S ×A× S → R the reward function, and γ ∈ [0, 1) the discount factor. Here ∆(X) denotes the set of probability distributions over set X and we write x ∼ µ to denote that x is sampled from a distribution µ. A (memoryless) policy is a map π : S → ∆(A), from state s to a distribution over actions. Rolling out π in M yields a trajectory τ = (s0, a0, r0, s1, a1, r1, . . .) with s0 ∼ µ, at ∼ π(· | st), st+1 ∼ P(st, at), and rt = r(st, at, st+1). A policy conditioned on task φ is denoted as π | φ or π(· | st, φ) when applied to a concrete state st. We interpret MDPs via a labelling map L : S → 2AP . Given a trajectory τ , L induces an ω-word w = L(s0)L(s1) · · · ∈ (2AP )ω , on which we evaluate LTL .
Reinforcement learning. Following [Sutton and Barto, 2018], the objective of reinforcement learning (RL) is to find a policy π⋆ that maximises the expected discounted return J(π) = Eτ∼π[∑∞t=0 γ t rt]. We write τ ∼ π to emphasise that the trajectory distribution depends on π. The state-value function of a policy π is V π (s) = Eτ∼π[∑∞t=0 γ t rt | s0 = s] and corresponds to the expected discounted return starting from state s and following policy π. In addition, we also consider a specification-driven objective, namely maximizing the probability of satisfying an LTL task φ. For a policy π, we define this satisfaction probability as Pr(π |= φ) = Eτ∼π [1[τ |= φ]], where 1[τ |= φ] is 1 if the trace induced by τ satisfies φ, and 0 otherwise.
3 ProblemDefinition
We study multi-task RL with LTL specifications, following [Vaezipoor et al., 2021; Jackermeier and Abate, 2025]. In contrast to single-task RL, we consider task-conditioned policies π | φ that receive a current task φ as input. Such policies can adapt to a new task φ without requiring any retraining. In particular, the MDP is inacessible and solely φ itself may be subject to any computation before and during the execution. Formally, the goal is to learn a single universal policy that maximises the overall satisfaction probability over some distribution D over LTL tasks:
The following two key challenges arise in this setting.
Memory requirements of LTL tasks. Notice that LTL tasks are inherently non-Markovian: the agent needs to be aware of already observed labels to decide its next action, as exemplified by our running example Fr ∧FGy. In the same MDP state, the agent has to perform different actions depending on whether it has already seen r; if it has, it can focus on continuously achieving y; otherwise, it needs to satisfy the finite goal Fr first. While it is in principle possible to learn a non-Markovian policy π(· | s0, . . . , st, φ) conditioned on the entire trajectory history, this introduces significant complexity in practice. Hence most RL approaches with LTL tasks aim to recover a Markovian view by augmenting the MDP state with memory (typically the states of an automaton for φ) that keeps track of the current task's "progress" (intuitively, tracking the already achieved subgoals of φ).
Universal progress interface. In single-task RL, tracking progress of subgoals and conditioning a policy on it is straightforward. The common approach is to construct an automaton for the given LTL task, as by design, the automaton states form sufficient memory for deciding what to do next in the given task. We then retrieve a Markovian setting by training a separate sub policy for each state. At test time, the conditioning on task progress is achieved by tracking the current automaton state and employing the respective sub-policy.
However, in multi-task RL, conditioning via statedependent sub-policies is no longer feasible, since the automaton is not fixed a priori, but changes with every new task. Instead, a universal policy capable of being conditioned on any possible task needs to be capable of processing any possible automaton. This necessitates a universal progress interface (UPI) which is a finite-dimensional embedding of arbitrary tasks, that the policy can be conditioned on. A UPI should (i) reduce any tasks to a common, learnable representation (ii) update that representation depending on achieved progress, and (iii) be computationally cheap, as at test time, it needs to be computed online during interaction with the environment. To achieve the task-conditioned behaviour of the policy, the UPI needs to be semantically meaningful: if two different tasks require similar behaviour, they should have similar embeddings. For instance, Fr∧FGy and Fr should have similar embeddings as both require an r to proceed.
4 Existing Approaches
We proceed to discuss two current approaches to constructing a UPI which we build upon.
4.1 Formula Progression Approach
In LTL2ACTION [Vaezipoor et al., 2021], the LTL formula itself is embedded as the universal progress interface. Crucially, task progress can be updated by so-called formula progression [Bacchus and Kabanza, 1996]. Intuitively, for a formula φt and a letter σ the progressed formula prog(σ, φt) captures what remains to be satisfied after seeing σ. For example, if φt = F(r∧FGy) and σ = {r}, then prog(σ, φt) = FGy (see Appendix A.2 for a full definition).
LTL2ACTION then embeds the current (progressed) formula via a graph neural network (GNN) [Scarselli et al., 2009] g that operates on LTL syntax trees. The GNN is trained end-to-end with the task-conditioned policy π(· | st, g(φt)) via RL by issuing a reward of 1 exactly when φt progressed to tt , which denotes satisfaction of the task.
A benefit of this approach is that formula progression can be computed efficiently and on the fly, i.e. each step is only computed when it is actually required. However, its reliance on eventually progressing to tt to give rewards limits this approach to the co-safety (guarantee) fragment of LTL. Giving rewards for general LTL tasks requires tracking additional information which plain formula progression does not provide.
4.2 Automata-Theoretic Approach
The common approach to support full LTL is to convert the current task to an automaton and keep track of the current automaton state as a UPI. This is the approach taken by DEEPLTL [Jackermeier and Abate, 2025], which employs LDBAs as suitable automata. Formally, the task-conditioned policy π | φ then operates over the product MDP Mφ, whose state space consists of the MDP state space S augmented with the LDBA state space Q. Non-deterministic ε-transitions are handled by introducing special ε-actions εq′ that update the current LDBA state q to q′ ∈ E(q) without modifying the MDP state. Assigning positive rewards of 1 to visiting accepting states F in the LDBA then enables learning a taskconditioned policy. Formally, the policy is optimised via the following objective, where 1F is the indicator function of F:
The key question in the automata-theoretic approach is how to obtain meaningful features of LDBA states from arbitrary formulae that are not known apriori. DEEPLTL proposes so-called reach-avoid sequences as a common representation of automaton states. Intuitively, these are sequences of letters to reach and avoid that would result in visiting accepting states infinitely often. They hence form a complete plan on how to produce a satisfying trace from the current state. To chose between the many sequences that could represent a state, DEEPLTL learns a critic network that judges the feasibility of any sequence in the given MDP. Formally, DEEPLTL learns a policy π(· | st, e(ς)) conditioned on a reach-avoid sequence ς embedded via an embedding network e. At test time, the agent tracks the current state of the LDBA and continually searches for the optimal (according to the critic) reach-avoid sequence ς ⋆ for representing the current state qt, and executes actions given by π(· | st, e(ς ⋆ )).
While this approach works for full LTL, the search for reach-avoid sequences is prohibitively expensive as (i) the entire LDBA, needs to be constructed upfront and (ii) all of its accepting paths need to be exhaustively enumerated to find the optimal reach-avoid sequence (see Appendix B for an exact derivation of the complexity). This limits DEEPLTL to relatively simple tasks, where computing and enumerating sequences of the entire automaton is feasible.
Rationale for LDBAs. The choice of LDBA as automata is important as they combine several useful properties. First, their B¨uchi acceptance can be converted naturally to a reward signal s.t. maximizing rewards coincides with optimising satisfaction probability [Hahn et al., 2019]. Crucially, this is not possible for other acceptance conditions like Rabin, and impractical for parity [Hahn et al., 2022]. Note however, that this requires slightly more sophisticated objectives than the one we presented in Equation 2, in order to address the bias introduced by the discount factor γ [Hahn et al., 2019; Bozkurt et al., 2020; Voloshin et al., 2023]. Further, while some non-determinism is unavoidable when aiming for a B¨uchi automaton that captures full LTL, the non-determinism of LDBAs is very manageable. Specifically, their nondeterminism is good-for-MDP, meaning that it can be resolved by the agent (i.e. the epsilon transitions turn into new actions) without sacrificing any optimality of the policy. 1
4.3 Other RelatedWork
Several other works recently addressed the problem of multitask RL with LTL specifications. Many of these approaches decompose the LTL specification into sub-tasks, which are then completed one-by-one [Le´on et al., 2022; Qiu et al., 2023; Liu et al., 2024; Guo et al., 2025]. However, this generally still requires constructing the entire automaton upfront and furthermore, can lead to myopic solutions due to missing context. In contrast, we specifically design our approach to not suffer from such suboptimality. Xu and Fekri [2024] propose a non-myopic approach based on the option framework [Sutton et al., 1999], but this is limited to a small fragment of LTL. Recently, Giuri et al. [2025] investigated GNNs to improve the representation learning capabilities of DEEPLTL, but their approach suffers from the same fundamental drawbacks as DEEPLTL.
1 Technically, not every LDBA is good-for-MDPs, but the ones produced by [Sickert et al., 2016; Esparza et al., 2020] are.
5 Semantically Labelled Automata Approach
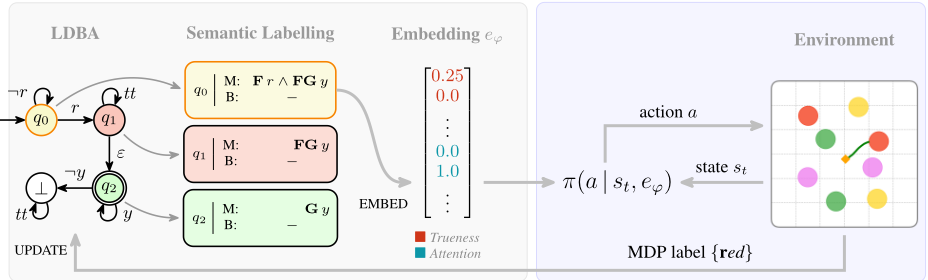
We start by giving an overview of our approach. We follow the automata-theoretic approach in the sense that we construct an LDBA for the current task, update its state to track progress and condition our policy on the current state. The crux is to compute a meaningful embedding of any possible automaton state for any possible LTL formula (and ideally just by looking at that state alone, without considering the entire automaton). Since there are infinitely many automaton states and we can only observe finitely many in training, the key question is how to embed the states into a structured feature space amenable to learning, i.e. where semantically similar states are close to each other. Traditionally, states of (limit-)deterministic automata for LTL formulae bear no logical structure and are simply identified with a numeric index produced by the translation algorithm, so this may seem ambitious. However, we employ more modern, semantic translations to construct the LDBA, which are the product of a long line of research on constructing small automata [Kˇret´ınsk´y and Esparza, 2012; Esparza and Kˇret´ınsk´y, 2014; Esparza et al., 2020]. The key property of these translations is that each state is identified with a simple structure (e.g. a pair or a vector) of LTL formulae. This so-called semantic labelling fully describes the semantics of a state (that is, which subgoals remain to be achieved from here on) and thus, embedding this information can inform the policy about progress of the task and remaining obligations. Crucially, the semantic labelling of a state is available without having to compute the entire automaton. Instead, required parts of the automaton can be computed on-demand, depending on the observed MDP labels. See Figure 1 for an illustration of this approach.
5.1 Semantic Labelling
The semantic labelling of our automaton states originates from the translation presented in [Esparza et al., 2020], which is implemented in OWL [Kˇret´ınsk´y et al., 2018]. Their LDBAs require keeping track of only two LTL formulae, which is achieved through upfront normalisation [Sickert and Esparza, 2020]. First, we have the Main formula, which is the entire formula in the initial state and for every subsequent state is derived using formula progression. Intuitively, the main formula can be thought of as the "remaining language" from the current state onwards. However, for a recurrence formula like GFr (i.e. reach r infinitely often), the remaining obligation will never change and thus, just tracking the main formula cannot distinguish between words that satisfy this property and ones that do not. Thus, a second formula, the Breakpoint formula is required to track the inner formula of recurring obligations (Fr in this case). Whenever this formula progresses to tt, it resets and emits a B¨uchi acceptance signal. That way, seeing a B¨uchi signal infinitely often corresponds directly to satisfying the inner formula infinitely often.
As an example, consider the automaton of Figure 1. The main formula of q0 is the entire task and once we observe r, the automaton updates to state q1 in which the main formula has progressed to FGy. The ε-transition guesses when the safety formula Gy starts to hold and q2 verifies that guess through formula progression. This example has no breakpoint formulae due to the lack of recurrence formulae; see Appendix C for an example with a breakpoint formula.
5.2 Embedding the Semantic Labelling
Embedding the semantic labelling requires capturing the relevant information of two LTL formulae, which we tackle individually and concatenate the result. Recall that the embedding space needs to create numerical proximity of semantically similar states (or rather similar formulae) to enable generalisation. Intuitively, the similarity of two formulae is proportional to how much their languages overlap. Hence, our features intuitively approximate a formula's language by probing the effects of letters when seen at the current- or subsequent steps. Additionally, we employ simple complexity measures of formulae (e.g. the height of the syntax tree as suggested in [Kˇret´ınsk´y et al., 2023]) to allow the agent to choose less complex states when resolving ε-transitions.
Exploiting trueness. This feature approximates the immediate effect of observing a letter by measuring how much each letter progresses the formula towards or away from satisfaction. We thus need a measure of proximity to satisfaction. Intuitively, it is clear that FGy is closer to satisfaction than Fr ∧FGy, since the former already achieved a subgoal. To capture this, we resort to trueness which was first introduced in [Kˇret´ınsk´y et al., 2019]. Intuitively, trueness measures how easy it is to satisfy an LTL formula, by propositional approximation of the temporal behaviour. Formally, to compute the trueness tr(φ) of a formula φ we replace all temporal subformulae ψ by new propositional variables xψ and compute the ratio of satisfying assignments to total assignments in the resulting propositional formula. For example for Fr∧FGy, we replace all temporal subformulae, and get xFr ∧ xFGy. In the resulting conjunction, 1 out of 4 assignments satisfy the formula and thus tr(Fr ∧ FGy) = 0.25. Further, we have tr(FGy) = 0.5, which indicates that the latter formula is easier to satisfy and progressing to the latter is desirable.
We use trueness to compute a feature value for every MDP label of L. As we are interested in the impact of a letter, we compare the change in trueness before and after seeing that letter, i.e. after progressing the formula using that letter. Formally, for a formula φ and a letter σ the trueness feature ftr is defined as:
In the embedding vector of Figure 1, the first two red numbers correspond to the feature values ftr(φ, {r}) and ftr(φ, {y}), where φ = Fr ∧ FGy. By looking at these two numbers, the agent can infer that an {r} would make progress while seeing {y} currently has no effect. Symmetrically to progress, this feature also captures violations. E.g. in q2 where the main formula is Gy we have the feature value ftr(Gy, {}) = -0.5, indicating that not seeing a y (terminally) hurts the progress towards satisfying Gy. We further refine this feature be employing different normalisations (e.g. among all letters, or among all positive/negative values) that result in slightly different semantic meanings. For a full list and explanation of these, we refer to Appendix D. Ultimately, despite being unable to capture deep temporal relations (e.g. F r ∧G¬r having trueness 0.25 despite being unsatisfiable), trueness yields a great propositional approximation of taskprogress, especially for formulae appearing in practice.
Propositional attention. Trueness alone yields a myopic embedding, meaning that it only considers the immediate effect of seeing a letter while disregarding what happens afterwards. For example, the trueness feature values of Fr∧FGy alone, do not yield any indication that after seeing {r}, {y} will be important, which can result in suboptimal behaviour in certain environments. To combat this, we propose an attention-like feature, where we relate pairs of propositions by how reliant one is on the other for satisfying the formula.
Formally, for a formula φ and a pair of propositions (p, q), we first compute the formula after seeing {p} denoted as φ′ . Then, we compute the obligation sets [Li et al., 2013] of φ′ , denoted by ob(φ′ ). A single obligation set is a letter σ ∈ 2AP
that if seen infinitely often, satisfies the formula, i.e. σω |= φ′ . We provide the full definition of obligation sets in Appendix A.3, but intuitively, the obligation sets approximate the infinite behaviours of φ′ on a propositional level. To compute the feature value, we then count how often q appears in the obligation set (treating q and ¬q separately) and divide by the total number of obligation sets. Putting it all together, the positive propositional attention feature f + att for a formula φ and a pair of propositions (p, q) is given by
where φ′ = prog(φ, {p}) (and when |ob(φ′ )| = 0, the feature defaults to 0). Symmetrically, the negative propositional attention feature f - att counts the appearances of ¬q.
In the embedding vector from Figure 1, the two teal numbers correspond to the feature values f + att (φ, r, r) and f + att (φ, r, y), where φ = Fr ∧ FGy. The first value being 0.0 indicates that after seeing {r} once, it is completely irrelevant. Further, the second value being 1.0 indicates that after seeing {r}, seeing letters containing y is highly promising. Crucially, this information is already present in the embedding of q0, allowing the agent to consider its future obligation of FGy while still primarily focussing on achieving F r.
5.3 Policy Architecture
Our approach is realised in a deep RL setting. We next describe our policy architecture. Our policies take the current MDP state s and the semantic embedding of the current LDBA state q as input, and produce an action distribution over the MDP action space A and possible ε-actions. Recall that ε-actions εq′ (where q′ ∈ E(q)) correspond to following an ε-transition to q′ while remaining in the same MDP state.
To handle this complex hybrid action space (note in particular that Amay be continuous, and |E| is not known apriori), we propose a multi-headed neural network architecture for the policy. Given the current MDP state s and LDBA state q, we first compute latent representations of all LDBA states u in the ε-closure E(q) ∪ {q} as follows: first, the MDP state s is encoded via a state encoder, which is either a multilayer perceptron (MLP) or a convolutional neural network (CNN), depending on the domain. Then, the semantic embedding of each LDBA state u ∈ E(q) ∪ {q} is processed via a learnable linear projection layer. These feature vectors are concatenated and passed through a shared representation MLP for each LDBA state, producing latent embeddings zu ∈ Rd .
The latent embeddings are then fed into a linear scoring head λ: Rd → R that assigns logits to ε-actions, and the embedding of the current LDBA state q is additionally processed by an environment actor head πenv that outputs the parameters of a distribution over the MDP action space A (e.g. the mean and standard deviation of aGaussian distribution). Intuitively, the scores λ(zu) model the probability of taking the ε-action that transitions to u, and λ(zq) corresponds to the probability of executing an MDP action rather than an ε-action. Formally, the policy induces the hybrid action distribution
where εu is the ε-action that transitions to u and
denotes the softmax-normalised score function. Note that if no ε-actions are available (i.e. E(q) = ∅), then the action distribution reduces to simply πenv(a | zq).
Training procedure. We train the policy end-to-end via goal-conditioned RL [Liu et al., 2022]: at the beginning of each episode, we sample a random LTL specification φ ∼ D and assign a reward of 1 to visits to accepting states. To make training converge faster in practice, we follow the approach of Jackermeier and Abate (2025) and design a training curriculum consisting of different stages of increasingly challenging formulae. For example, we generally first train the agent with simple formulae of the form Fa before sampling more complex tasks. Once the agent performs sufficiently well on tasks sampled from the current stage, we move on to the next stage. Our approach is independent of the underlying RL algorithm. Throughout our experiments, we use proximal policy optimisation (PPO) [Schulman et al., 2017]. We provide further details on training, including on curricula, in Appendix E.
6 Experiments
We evaluate our approach, named SEMLTL, across a variety of domains and specifications. 2 We aim to answer the following research questions: (RQ1) Are our embeddings expressive enough to overcome the myopia of decompositionbased methods? (RQ2) Can SEMLTL successfully learn generalist policies for zero-shot executing arbitrary LTL instructions? (RQ3) Does our approach successfully scale to complex specifications, where previous methods fail?
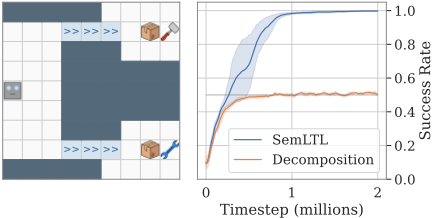
RQ1. Consider the grid-world environment depicted in Figure 2 (left), inspired by [Vaezipoor et al., 2021]. The agent, located on the left, receives one of the following two goals: F(parcel ∧ F hammer) or F(parcel ∧ Fwrench), requiring it to enter the correct room via the one-way conveyor belts. For decomposition based approaches, the first subtask is Fparcel in both cases. The agent thus has to choose a room (in order to pick up a parcel) without knowing the entire specification. Since both specifications are equally likely, but the agent has no way of differentiating between them, it can achieve a maximum success rate of 50%. In contrast, we observe that SEMLTL does not suffer from such myopia and quickly converges to the optimal policy (Figure 2, right).
RQ2 and RQ3
We now proceed to conduct a large-scale experimental study to investigate RQ2 and RQ3.
Environments. We rely on established benchmarks to evaluate SEMLTL: the LetterWorld environment [Vaezipoor et al., 2021], which consists of a 7 × 7 grid with randomly placed letters corresponding to atomic propositions, and ZoneEnv [Vaezipoor et al., 2021], a high-dimensional robotic navigation environment with a continuous action space, where randomly placed zones of different colours form the atomic propositions. We consider a more difficult variant of ZoneEnv with 8 colours (instead of 4) and a more complex observation space based on an RGB lidar sensor. For further details, see Appendix F.1.
2 Code available at: github.com/mathiasj33/semltl
Baselines. We compare our approach to LTL2ACTION, the only other approach that does not have to compute the entire automaton upfront, and DEEPLTL, the state-of-the-art, automata-conditioned approach that does not suffer frommyopia and is applicable to full LTL. See Appendix F for implementation details and hyperparameters of SEMLTL and the baselines, including training curricula.
Tasks. We consider a wide range of tasks for our evaluation. First, we compare to a set of established LTL tasks from the literature [Jackermeier and Abate, 2025], which we aggregate and refer to as SMALL in our results. Since these tasks are of limited complexity, we furthermore introduce several parameterised families of both finite- and infinitehorizon tasks that enable us to systematically assess the scalability of our approach. The LOCAL-SAFETY[k,m] family ("avoidance" in [Vaezipoor et al., 2021]), consists of m disjunctions of reach-avoid specifications φ[k] where φ[k] ≡ ¬a1 U (r1 ∧ (¬a2 U (r2 ∧ · · · ∧ (¬ak U rk)))). Further, we define the variant GLOBAL-SAFETY[k,m], which fixes a single global proposition a to avoid throughout the entire task. We also introduce the FINITE-REACTIVE[k,m] family, where a simple finite-goal needs to be reached. However, whenever a trigger variable t is observed, the agent needs to react by achieving specified response variables. The overall task consists of k such reaction rules, where each permits m response variables. An example is ((t → F(r1 ∨ r2)) U g.
For infinite-horizon tasks, we first consider the COMPLEXPATROL[k,m] family. This consists of a disjunction of sequential reach tasks ψ[k] ≡ F(r1 ∧ F(. . . ∧ Frk)) that need to be satisfied recurrently while avoiding a global safety constraint. We also investigate the REACH-STAY[k] family of the form ψ[k] ∧ FGa, where a is an eventual safety target. Note that we do not consider this task family in LetterWorld, since the agent has to move at every timestep, and hence cannot stay continuously at the same proposition. These two families cover complex tasks of the persistence and recurrence fragment, respectively. We furthermore introduce the ALWAYSREACTIVE[k,m] family, where tasks require maintaining reactive responses over an infinite horizon. Concretely, a trigger t0 must be seen infinitely often (GF t0), while responding to a set of k global reaction rules with m response variables each (e.g. G(t0 → F(r1 ∨ t1)), where in particular t1 could be another trigger). We choose suitable parameters to cover a broad spectrum of automaton sizes, and randomly sample 5 tasks per family for our experiments.
| Task Specification Type | |δ| | LTL2ACTION DEEPLTL | SEMLTL (Ours) | ||||
|---|---|---|---|---|---|---|---|
| |Q| | SR / µacc | SR / µacc | SR / µacc | µstates | |||
| SMALL | 9 | 23 | 0.67±0.12 | 0.98±0.01 | 4.12±0.02 | ||
| LOCAL-SAFETY[3, 3] | 233 | 1, 372 | 0.98±0.01 0.57±0.07 TO | 0.99±0.00 | 5.38±0.00 | ||
| Letter GLOBAL-SAFETY[4, 6] | 1, 072 | 6, 414 | 0.12±0.03 | TO | 0.91±0.01 | 6.77±0.04 | |
| Finite-horizon FINITE-REACTIVE[8, 2] | 300 | 2, 115 | 0.74±0.04 | TO | 1.00±0.00 | 2.80±0.10 | |
| SMALL | 9 | 23 | 0.52±0.07 | 0.93±0.02 | 0.92±0.02 | 3.40±0.01 | |
| Zones LOCAL-SAFETY[3, 3] | 83 | 379 | 0.66±0.11 | 0.98±0.01 | 0.93±0.06 | 5.09±0.14 | |
| GLOBAL-SAFETY[4, 8] | 1, 162 | 6, 510 | 0.39±0.05 | TO | 0.79±0.06 | 6.73±0.18 | |
| FINITE-REACTIVE[8, 2] | 107 | 619 | 0.74±0.11 | TO | 0.98±0.00 | 2.96±0.16 | |
| SMALL | 7 | 16 | n/a | 6.15±1.97 | 7.13±0.51 | 4.76±0.09 | |
| Letter COMPLEX-PATROL[5, 5] | 49 | 227 | n/a | 1.78±0.26 | 1.83±0.10 | 6.44±0.03 | |
| ALWAYS-REACTIVE[5, 1] | 38 | 204 | n/a | TO | 3.06±0.07 | 7.06±0.02 | |
| Infinite-horizon SMALL | 4 | 10 | n/a | 14.50±6.71 | 18.65±6.02 | 3.59±0.04 | |
| Zones | REACH-STAY[5] | 34 | 116 | n/a | 914±862 | 2, 503±497 | 7.29±0.15 |
| COMPLEX-PATROL[5, 5] | 45 | 201 | n/a | 2.13±1.45 | 2.44±0.44 | 6.33±0.10 | |
| ALWAYS-REACTIVE[5, 1] | 38 | 204 | n/a | TO | 3.73±0.80 | 7.00±0.00 | |
Results. Table 1 lists evaluation results of SEMLTL and the baselines on both evaluation environments. As is standard, we report success rates (SR) for finite-horizon tasks and average visits to accepting states (µacc) for infinite-horizon tasks. Intuitively, µacc captures how often the policy successfully completes an accepting cycle in the LDBA. We also report the number of LDBA states constructed by SEMLTL (µstates).
We observe that SEMLTL in both environments successfully learns a policy that is able to generalise to diverse LTL specifications, achieving strong results throughout (RQ2). SEMLTL consistently performs much better than LTL2ACTION, which demonstrates the structure and learnability of our semantic embeddings. For finite tasks, the semantic labelling of LDBAs only consists of the main formula. Both approaches thus only track one formula (using formula progression) and differ solely in the way they embed that formula. We clearly observe that SEMLTL is able to leverage the same information much more effectively, and over a diverse set of typical RL specifications. DEEPLTL also achieves strong results on tasks where constructing the entire automaton and enumerating reach-avoid sequences is feasible. This is expected, since it exhaustively analyses the entire automaton to form a complete and optimal plan to inform its policy. However, for more complex specifications DEEPLTL fails to compute even a single action within the 600s time limit (denoted by TO), due to the prohibitively expensive sequence enumeration. In contrast, we observe that SEMLTL successfully scales to highly complex formulae and achieves strong performance even on large task instances with hundreds of automaton states (RQ3). Notably, SEMLTL often only considers a small fraction of the overall LDBA (see µstates compared to |Q|). This highlights the suitability of many common RL tasks for on-the-fly automata construction, and demonstrates that the theoretical benefits of SEMLTL lead to significant advantages in practice. We provide full experimental results, including on more parameters for the different task families, per-specification results on SMALL tasks, and visualisations of SEMLTL trajectories in Appendix F.
7 Conclusion
We presented SEMLTL, a novel approach to train generalist policies for satisfying arbitrary LTL specifications. Our method is based on recent semantic LTL-to-automata translations that annotate each automaton state with rich, semantic information. Not only does this naturally enable support for full LTL, but it also allows automata states to be computed efficiently on the fly, without constructing the entire automaton upfront. We introduced a structured way to embed the semantic state information, and designed a suitable policy architecture based on these embeddings. Experimental results on a wide variety of specifications demonstrate that our approach successfully learns policies that can zero-shot generalise to novel LTL tasks, while being significantly more scalable and constructing only a fraction of the automaton.
Future work will extend our approach to real-life robotics settings with unknown labelling functions and enhance scalability via the recently proposed LTLf+/PPLTL+ temporal logics [Aminof et al., 2025; De Giacomo et al., 2025] and exploit good-for-MDP reduction pipelines [Weinhuber et al., 2026].
Acknowledgements
This work was supported in parts by the UKRI Erlangen AI Hub on Mathematical and Computational Foundations of AI (No. EP/Y028872/1). This work is part of the IntelligenceOriented Verification&Controller Synthesis (InOVationCS) project funded by the European Union under Grant Agreement No. 101171844. MJ is funded by the EPSRC Centre for Doctoral Training in Autonomous Intelligent Machines and Systems (EP/S024050/1).
@inproceedings{ijcai2026p1,
  title     = {Semantically Labelled Automata for Multi-Task Reinforcement Learning with LTL Instructions},
  author    = {Abate, Alessandro and De Giacomo, Giuseppe and Jackermeier, Mathias and Křetínský, Jan and Prokop, Maximilian and Weinhuber, Christoph},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {3--11},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/1},
  url       = {https://doi.org/10.24963/ijcai.2026/1},
}
TY - CPAPER TI - Semantically Labelled Automata for Multi-Task Reinforcement Learning with LTL Instructions AU - Abate, Alessandro AU - De Giacomo, Giuseppe AU - Jackermeier, Mathias AU - Křetínský, Jan AU - Prokop, Maximilian AU - Weinhuber, Christoph T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 3 EP - 11 DO - 10.24963/ijcai.2026/1 UR - https://doi.org/10.24963/ijcai.2026/1 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





