
Dual-Topology Learning with Adaptive Anchors for Multi-View Clustering
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 5297-5305.
https://doi.org/10.24963/ijcai.2026/590
Keywords
- Machine Learning: Multi-view learning
- Machine Learning: Clustering
- Machine Learning: Unsupervised learning
Abstract
As a prominent paradigm for large-scale unsupervised learning, anchor-based multi-view clustering aims to reveal the latent structures across heterogeneous data representations with high efficiency. Despite achieving some progress, existing methods typically suffer from the following two limitations. Firstly, they rely on pre-constructed anchors or rigid constraints (e.g., orthogonality), whereas the intrinsic topological correlations among anchors are completely discarded. Secondly, most existing methods either perform clustering directly on the bipartite graph or treat different views equally, thereby failing to capture the global structural information. To this end, the Dual-tOpology learning with adapTive Anchors (DOTA) is proposed, which not only learns the sample-anchor relationship (i.e., bipartite graph) but also preserves the topology structure among anchors, significantly enhancing the discriminability of learned representation while preserving the underlying data manifold. By integrating an adaptive view-weighting strategy to balance view contributions, DOTA derives discriminative global sample embeddings by propagating spectral information through the bipartite graph. Extensive experiments on benchmark datasets demonstrate the superiority of DOTA.
- [Chen et al., 2025a] Yawei Chen, Huibing Wang, Jinjia Peng, and Yang Wang. Anchor learning with potential cluster constraints for multi-view clustering. In Proceed- ings of the AAAI Conference on Artificial Intelligence, vol- ume 39, pages 15939-15947, 2025.
- [Chen et al., 2025b] Zhe Chen, Mingzhi Zhu, Hui Li, and Tianyang Xu. Anchor graph learning with double noise removal for multi-view clustering. Neural Networks, page 107779, 2025.
- [Fan et al., 2025] Wentao Fan, Chao Zhang, Chunlin Chen, and Huaxiong Li. Online cross-modal hashing with multi- level memory. In Proceedings of the ACM International Conference on Multimedia, pages 6271-6279, 2025.
- [Fan et al., 2026] Wentao Fan, Chao Zhang, Chunlin Chen, and Huaxiong Li. Online cross-modal hashing with ex- panding label space. In Proceedings of the AAAI Confer- ence on Artificial Intelligence, volume 40, pages 21002- 21010, 2026.
- [Fang et al., 2023] Si-Guo Fang, Dong Huang, Xiao-Sha Cai, Chang-Dong Wang, Chaobo He, and Yong Tang. Ef- ficient multi-view clustering via unified and discrete bi- partite graph learning. IEEE Transactions on Neural Net- works and Learning Systems, 35(8):11436-11447, 2023.
- [Huang et al., 2015] Jin Huang, Feiping Nie, and Heng Huang. A new simplex sparse learning model to measure data similarity for clustering. In Proceedings of the Inter- national Joint Jonference on Artificial Intelligence, 2015. IJCAI
- [Huang et al., 2025] Yanyong Huang, Minghui Lu, Wei Huang, Xiuwen Yi, and Tianrui Li. Time-fs: joint learning of tensorial incomplete multi-view unsupervised feature selection and missing-view imputation. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 39, pages 17503-17510, 2025.
- [Jiang et al., 2023] Bingbing Jiang, Chenglong Zhang, Yan Zhong, Yi Liu, Yingwei Zhang, Xingyu Wu, and Weiguo Sheng. Adaptive collaborative fusion for multi-view semi- supervised classification. Information Fusion, 96:37-50, 2023.
- [Jiang et al., 2025a] Bingbing Jiang, Chenglong Zhang, Xinyan Liang, Peng Zhou, Jie Yang, Xingyu Wu, Junyi Guan, Weiping Ding, and Weiguo Sheng. Collaborative similarity fusion and consistency recovery for incomplete multi-view clustering. In Proceedings of the AAAI confer- ence on artificial intelligence, volume 39, pages 17617- 17625, 2025.
- [Jiang et al., 2025b] Bingbing Jiang, Chenglong Zhang, Zhongli Wang, Xinyan Liang, Peng Zhou, Liang Du, Qinghua Zhang, Weiping Ding, and Yi Liu. Scalable fuzzy clustering with collaborative structure learning and preser- vation. IEEE Transactions on Fuzzy Systems, 33(9):3047- 3060, 2025.
- [Jiang et al., 2026] Bingbing Jiang, Jie Wen, Zidong Wang, Weiguo Sheng, Zhiwen Yu, Huanhuan Chen, and Weiping Ding. Scalable semi-supervised learning with discrimina- tive label propagation and correction. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2026.
- [Kou et al., 2025a] Zhiqiang Kou, Si Qin, Hailin Wang, Jing Wang, Mingkun Xie, Shuo Chen, Yuheng Jia, Tongliang Liu, Masashi Sugiyama, and Xin Geng. Label distribu- tion learning with biased annotations assisted by multi- label learning. In Proceedings of the International Joint Conference on Artificial Intelligence, pages 16-22, 2025.
- [Kou et al., 2025b] Zhiqiang Kou, Yucheng Xie, Hailin Wang, Jing Wang, Mingkun Xie, Shuo Chen, Yuheng Jia, Tongliang Liu, and Xin Geng. Rankmatch: A novel ap- proach to semi-supervised label distribution learning lever- aging rank correlation between labels. In Proceedings of the Neural Information Processing Systems, volume 38, pages 158074-158095, 2025.
- [Liang et al., 2025] Xinyan Liang, Shijie Wang, Yuhua Qian, Qian Guo, Liang Du, Bingbing Jiang, Tingjin Luo, and Feijiang Li. Trusted multi-view classification with expert knowledge constraints. In Proceedings of the International Conference on Machine Learning, 2025.
- [Liu et al., 2024a] Meng Liu, Yue Liu, Ke Liang, Wenxuan Tu, Siwei Wang, Sihang Zhou, and Xinwang Liu. Deep temporal graph clustering. In Proceedings of the Interna- tional Conference on Learning Representations, 2024.
- [Liu et al., 2024b] Suyuan Liu, Ke Liang, Zhibin Dong, Si- wei Wang, Xihong Yang, Sihang Zhou, En Zhu, and Xin- wang Liu. Learn from view correlation: An anchor en- hancement strategy for multi-view clustering. In Proceed- ings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 26151-26161, 2024.
- [Liu et al., 2024c] Suyuan Liu, Qing Liao, Siwei Wang, Xin- wang Liu, and En Zhu. Robust and consistent anchor graph learning for multi-view clustering. IEEE Transac- tions on Knowledge and Data Engineering, 36(8):4207- 4219, 2024.
- [Liu et al., 2025] Meng Liu, Ke Liang, Siwei Wang, Xingchen Hu, Sihang Zhou, and Xinwang Liu. Deep tem- poral graph clustering: A comprehensive benchmark and datasets. IEEE Transactions on Pattern Analysis and Ma- chine Intelligence, 47(12):11561-11578, 2025.
- [Lu et al., 2025] Zhoumin Lu, Yongbo Yu, Linru Ma, Feip- ing Nie, and Rong Wang. Capturing individuality and commonality between anchor graphs for multi-view clus- tering. In Proceedings of the International Joint Confer- ence on Artificial Intelligence, pages 5860-5868, 2025. IJCAI
- [Nie et al., 2014] Feiping Nie, Xiaoqian Wang, and Heng Huang. Clustering and projected clustering with adaptive neighbors. In Proceedings of the ACM SIGKDD Inter- national Conference on Knowledge Discovery and Data Mining, pages 977-986, 2014.
- [Tang et al., 2025] Chuan Tang, Miaomiao Li, Jun Wang, Chang Tang, Jiahe Jiang, Tianyi Wang, En Zhu, and Xin- wang Liu. Multi-view clustering via high-order bipar- tite graph learning and tensor low-rank representation. IEEE Transactions on Knowledge and Data Engineering, 37(11):6521-6534, 2025.
- [Wang et al., 2019] Hao Wang, Yan Yang, and Bing Liu. Gmc: Graph-based multi-view clustering. IEEE Transac- tions on Knowledge and Data Engineering, 32(6):1116- 1129, 2019.
- [Wang et al., 2025] Yadi Wang, Xiaoding Guo, Xianhong Hou, Zhijun Miao, Xiaojin Yang, and Jinkai Guo. Multi- modal sentiment recognition with residual gating network and emotion intensity attention. Neural Networks, page 107483, 2025.
- [Xu et al., 2024] Deng Xu, Chao Zhang, Zechao Li, Chun- lin Chen, and Huaxiong Li. Fast disentangled slim tensor learning for multi-view clustering. IEEE Transactions on Multimedia, 27:1254-1265, 2024.
- [Zeng et al., 2025] Yunpeng Zeng, Peng Song, Beihua Yang, Changjia Wang, Guanghao Du, Yanwei Yu, and Wenming Zheng. Hypergraph regularization-based anchor learn- ing for multi-view clustering. Pattern Recognition, page 112465, 2025.
- [Zhang et al., 2024a] Chao Zhang, Xiuyi Jia, Zechao Li, Chunlin Chen, and Huaxiong Li. Learning cluster-wise anchors for multi-view clustering. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 16696-16704, 2024.
- [Zhang et al., 2024b] Chenglong Zhang, Yang Fang, Xinyan Liang, Han Zhang, Peng Zhou, Xingyu Wu, Jie Yang, Bingbing Jiang, and Weiguo Sheng. Efficient multi view unsupervised feature selection with adaptive struc- ture learning and inference. In Proceedings of the Inter- national Joint Conference on Artificial Intelligence, pages 5443-5452, 2024. IJCAI
- [Zhang et al., 2024c] Chenglong Zhang, Xinjie Zhu, Zidong Wang, Yan Zhong, Weiguo Sheng, Weiping Ding, and Bingbing Jiang. Discriminative multi-view fusion via adaptive regression. IEEE Transactions on Emerging Top- ics in Computational Intelligence, 8(6):3821-3833, 2024.
- [Zhao et al., 2025] Zihua Zhao, Ting Wang, Haonan Xin, Rong Wang, and Feiping Nie. Multi-view clustering via high-order bipartite graph fusion. Information Fusion, 113:102630, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
With the rapid advancement of information technologies, data collected from heterogeneous sources has emerged extensively, referred to as multi-view data [Zhang et al., 2024b; Wang et al., 2025; Fan et al., 2025; Kou et al., 2025a]. Accordingly, Multi-View Clustering (MVC), which aims to leverage complementary information from multiple views to uncover the intrinsic data structures, has become a pivotal unsupervised learning paradigm. Based on the sparse representation assumption that a sample can be approximately reconstructed by its neighbors, many graph-based multi-view clustering methods have been proposed [Wang et al., 2019; Jiang et al., 2025b; Liu et al., 2025]. However, the prohibitive computational burden of constructing and decomposing the n-order graph incurs the complexity of (O(n2 )) and (O(n3 )), severely restricting their applications on large-scale MVC tasks [Xu et al., 2024; Jiang et al., 2025a; Lu et al., 2025; Zhao et al., 2025; Jiang et al., 2026; Fan et al., 2026].
∗The corresponding authors.
To this end, anchor-based graph learning has been widely adopted in MVC, effectively reducing the computational cost by constructing the bipartite graph between m anchors and n samples (m ≪ n). Depending on the anchor generation mechanism, existing methods can be mainly divided into two categories. Specifically, the first category leverages a two-stage strategy, where anchors are initially generated (sampling or heuristic) and then employed as static points for graph construction. For example, UDBGL [Fang et al., 2023] utilizes K-means on concatenated features to obtain anchors, and AEVC [Liu et al., 2024b] proposes to refine anchors under the guidance of a pre-constructed graph. However, these methods completely decouple anchor generation from the subsequent clustering process, rendering the performance highly dependent on the initial anchor selection and making the results susceptible to noise and selection bias [Zhang et al., 2024a; Tang et al., 2025; Liu et al., 2024a].
To fully exploit the knowledge interaction between anchor learning and graph construction, the second category dynamically updates anchors during the optimization process. Representative methods include RCAGL [Liu et al., 2024c], AGLDR [Chen et al., 2025b] and ALPC [Chen et al., 2025a]. Commonly, these methods impose orthogonal constraints to enhance anchor diversity and reduce redundancy, whereas the intrinsic correlations among anchors are neglected, failing to capture the complex similarity structure of real-world data. To alleviate this issue, [Zhang et al., 2024a] proposed CAMVC, which enforces explicit cluster structure via a predefined cluster indicator matrix. Recently, HRAL [Zeng et al., 2025] employs a hypergraph derived from bipartite graph as a regularizer to preserve the relation among anchors. Despite making some progress, these methods primarily concentrate on imposing specific structural constraints (e.g., orthogonality or cluster priors) to guide anchor learning, whereas the inflexible assumptions often lead to significant distribution distortion as the intrinsic correlations among anchors are completely overlooked. Furthermore, existing methods typically integrate multi-view information via simple summation and conduct clustering directly on the bipartite graph, which not only neglects view discrepancies but also fails to capture the discriminative global structure [Jiang et al., 2023; Liang et al., 2025; Kou et al., 2025b; Huang et al., 2025].
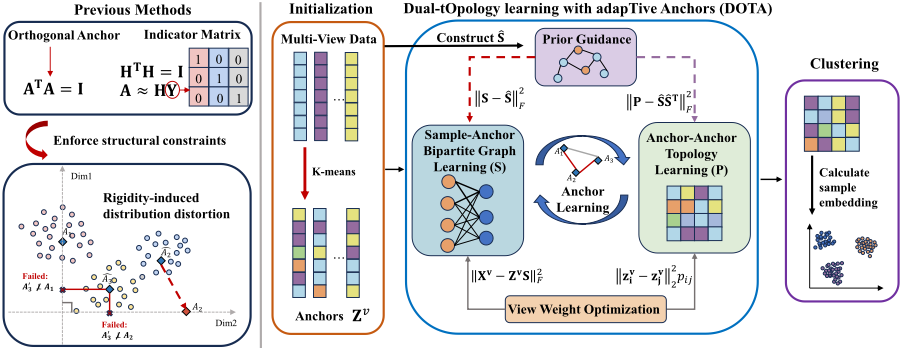
Motivated by the aforementioned issues, we propose a Dual-tOpology learning with adapTive Anchors (DOTA) framework for Multi-View Clustering. The basic framework of DOTA is illustrated in Fig. 1, and the main contributions of this paper are summarized as follows:
- A unified multi-view clustering framework is proposed by seamlessly integrating adaptive anchor optimization with topology structure learning, whereby the mutual reinforcement between anchor learning and graph construction is leveraged to strengthen the adaptability to complex datasets in practical applications.
- A novel topology regularization mechanism is designed to uncover latent correlations by simultaneously optimizing the sample-anchor bipartite graph and anchorlevel similarities, thereby avoiding the adverse effects of rigid constraints and effectively preserving the intrinsic topological structure among anchors.
- An adaptive supervision and fusion strategy is introduced, which not only incorporates data distribution priors to guide the learning process but also adaptively optimizes view weights to discriminate different views, ensuring the robustness of global structure information against data noise and initialization bias.
2 Methodology
Throughout this paper, matrices and vectors are denoted by bold uppercase and bold lowercase letters, respectively. Given a matrix M, mi represents its i-th row, while Tr(M) and ∥M∥F = √Tr(MT M) denote the Trace and Frobenius norm. The summary of key notations is provided in Table 1.
| Notation | Description |
|---|---|
| n, m c, V dv d = ∑Vv=1 dv xvi ∈ Rdv×1 zvj ∈ Rdv×1 Xv ∈ Rdv×n Zv ∈ Rdv×m S ∈ Rm×n P ∈ Rm×m 1n ∈ Rn×1 | Number of samples and anchors Number of clusters and views Feature dimension of the v-th view Total dimension of all views The i-th sample in the v-th view The j-th anchor in the v-th view Sample matrix of the v-th view Anchor matrix of the v-th view Bipartite graph matrix between samples and anchors Similarity graph matrix among anchors All-one vector |
2.1 Adaptive Bipartite Graph Construction
While graph-based methods excel at capturing intrinsic local information, they typically require constructing the n-order dense matrix to characterize similarity relationships, resulting in significant computational costs. To this end, based on the assumption that each sample can be reconstructed by a set of representative anchors, DOTA characterizes this relationship as a sample-anchor bipartite graph, formulated as follows:
where Zv represents the learned anchor matrix for v-th view, S and ˆS denote the adaptively optimized and pre-constructed bipartite graphs, respectively. Unlike conventional two-stage strategies (e.g., sampling or clustering centers) that decouple anchor learning from graph construction, DOTA simultaneously optimizes the view-specific anchors (i.e., Zv ) and the unified bipartite graph (i.e., S), which not only preserves the diversity of each view but also utilizes the unified information to ensure cross-view alignment of anchors. Furthermore, the second term in Eq. (1) incorporates the pre-constructed graph
ˆS to supervise the learning process, thereby leveraging prior knowledge to avoid trivial solutions and enhance robustness.
2.2 Prior-Driven Anchor Similarity Learning
Since anchors serve as representative prototypes that reveal the underlying topological structure, enhancing their discriminability becomes the fundamental objective in clustering tasks. Notably, existing methods primarily focus on exploring sample-anchor relationships or enforcing rigid constraints to ensure diversity, whereas the topological correlations among anchors are typically neglected. Therefore, the local information within anchor space is exploited to further preserve the underlying manifold of anchors, formulated as:
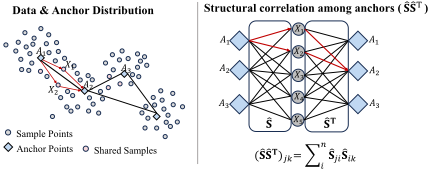
where zvi denotes the i-th anchor in the v-th view, pij measures the similarity between the i-th and j-th anchors, and L(P) represents the regularization term. Given that ˆS ∈ Rm×n depicts sample-anchor relationships, the prior knowledge of anchor-anchor similarity can be derived by computing ˆSˆST ∈ Rm×m, where high-order similarity information can be effectively propagated through the connectivity of shared samples (as illustrated in Fig. 2). By incorporating the prior structural information, Eq. (2) can be reformulated as:
Unlike previous methods that rely on pre-defined constraints, DOTA adaptively explores the similarities among anchors under the guidance of prior knowledge, which facilitates an effective description of intrinsic structural information and avoids the distribution distortion caused by inflexible structural assumptions, enhancing the overall performance.
2.3 Overall Model of DOTA
To fully leverage the interaction between different structural information, DOTA proposes a unified framework that jointly optimizes the sample-anchor bipartite graph S and the anchor-anchor topological structure P, so that the anchor learning and graph construction can be mutually reinforced. Additionally, considering the heterogeneous statistical properties across views, assigning uniform weights fails to distinguish the varying contributions of diverse views. Therefore, by integrating the adaptive view-weighting strategy, the overall objective function of DOTA is formulated as follows:
where λ and β are regularization parameters, αv represents the adaptive weight assigned to the v-th view. Specifically, the reconstruction term ensures accurate sample recovery via anchors and the bipartite graph; the manifold regularization term preserves the local topology to refine the learned anchor representation; and the prior consistency term incorporates structural priors to guide the optimization process. By exploiting the synergy among distinct components, the overall clustering performance can be significantly improved.
3 Optimization and Analysis
To address the non-joint convex problem in Eq. (4), an alternating optimization strategy is developed. The detailed procedures for each subproblem are presented as follows:
- The subproblem w.r.t. Zv : By fixing other variables, the optimization problem of Eq. (4) is simplified into:
Since Eq. (5) is independent across different views, Zv can be separately optimized as follows:
where Lp is the Laplacian matrix derived from P. Setting the derivation of Eq. (6) w.r.t. Zv to zero, the optimal solution Zv can be calculated as follows:
- The subproblem w.r.t. S: By fixing other variables, the optimization problem of Eq. (4) becomes:
which can be further transformed into:
Taking the partial derivative w.r.t. S to zero, the latent solution S∗ can be achieved as follows:
After that, the optimal solution of S can be obtained by projecting S∗ onto the feasible region:
Algorithm 1 Optimization procedures for DOTA
Input: Multi-view data Xv , clustering number c and parameters λ and β;
- 1: Generate the initial anchor matrices {Zv }Vv=1 via Kmeans on concatenated data;
- 2: Construct the initial bipartite graph ˆS using K-NN strategy [Nie et al., 2014];
- 3: Initialize the viewweights αv = 1/V (v = 1, . . . , V );
- 4: repeat
- 5: Update Zv by Eq. (7);
- 6: Update S by solving Eq. (11);
- 7: Update P by solving Eq. (15);
- 8: Update α by solving Eq. (16);
- 9: until Eq. (4) converges;
Output: The sample embedding V derived from bipartite graph, and perform K-means on V to obtain the clusters.
which can be solved in closed form [Huang et al., 2015].
- The subproblem w.r.t. P: By fixing other variables, the optimization problem of Eq. (4) becomes:
Denoting D with dij = λ ∑Vv=1 α2 v ∥zvi -zvj ∥22 and E = ˆSˆST , Eq. (12) can be transformed into:
Taking the partial derivative w.r.t. P to zero, the latent solution P∗ can be achieved as follows:
After that, the optimal solution of P can be obtained by:
- The subproblem w.r.t. α: When other variables are fixed, the problem of Eq. (4) is simplified into:
where hv = ∥Xv-Zv S∥2F +λ ∑i,j ∥zvi -zvj ∥22pij denotes the loss of the v-th view. By employing the Lagrange multiplier method, αv can be obtained as αv = 1/hv ∑Vk=1 1/hk .
Efficient Spectral Embedding Transformation
Standard spectral clustering conventionally requires performing eigen-decomposition on the n×n sample-level similarity graph to derive discriminative embeddings, which severely restricts its scalability for large-scale multi-view tasks. As established in Theorem 1 (the proof is provided in Appendix), DOTA tactfully recovers the global spectral embeddings by propagating spectral information through the learned bipartite graph. Accordingly, DOTA achieves linear scalability w.r.t sample size while effectively preserving the exactness of the underlying global similarity structure.
| Dataset | Classes | Data size | Feature size |
|---|---|---|---|
| Leaves | 100 | 1600 | 192(64/64/64) |
| COIL100 | 100 | 7200 | 90(30/30/30) |
| Hdigit | 10 | 10000 | 1040(784/256) |
| MNIST | 10 | 20000 | 459(256/144/59) |
| KSA | 5 | 20000 | 279(30/50/30) |
| CIFAR100 | 100 | 50000 | 3584(512/2048/1024) |
Theorem 1 (Spectral Recovery Equivalence). Given the learned bipartite graph S ∈Rm×n , the optimal spectral embedding V∈Rn×c of the induced sample-level similarity matrix ST S∈Rn×n can be exactly recovered by V=ST UΛ-1/2 , where U ∈ Rm×c and Λ ∈ Rc×c are the top-c eigenvectors and corresponding eigenvalues of the anchor-level matrix SST ∈ Rm×m, respectively.
Computational Complexity
Algorithm 1 summarizes the iterative optimization procedure for solving the objective function in Eq. (4). Specifically, during the initialization stage, generating m anchors and constructing the initial bipartite graph ˆS incur O(nm). In the optimization phase, updating Zv and S involves computing the inverses of m-order matrices, taking O(nmd+nm2 +m3 ) and O(nm2 +nmd+m3 ), respectively. Additionally, the updates for P and α require O(m2 ) and O(nmV 2 ). Finally, the postprocessing step involves performing the eigen-decomposition of SST and executing K-means on the sample embeddings, taking O(m3 ) and O(n) respectively. Consequently, the overall computational complexity of DOTA is O(nm2+nmd+m3 ), which scales linearly with the sample size n.
4 Experiments
4.1 Experimental Settings
To evaluate the effective of the proposed DOTA, comprehensive experiments are conducted on six datasets, including Leaves 1 , COIL100 [Zhang et al., 2024c], Hdigit [Jiang et al., 2023], MNIST 2 , KSA and CIFAR100 3 . The detailed information are summarized in Table 2.
Comparative Methods: DOTA is compared with seven state-of-the-art competitors, including (1) Unified and Discrete Bipartite Graph Learning (UDBGL [Fang et al., 2023]); (2) Anchor Enhancement strategy with View Correlation (AEVC [Liu et al., 2024b]); (3) Cluster-wise Anchor learning for MVC (CAMVC [Zhang et al., 2024a]); (4) Robust and Consistent Anchor Graph Learning (RCAGL [Liu et al., 2024c]); (5) Anchor Learning with Potential cluster Constraints (ALPC [Chen et al., 2025a]); (6) Anchor Graph Learning with Double noise Removal (AGLDR [Chen et al., 2025b]); (7) Hypergraph Regularization-based Anchor Learning (HRAL [Zeng et al., 2025]).
Implementation Details: To ensure fairness, the parameters for all methods are optimized following the suggestions in the respective works. For DOTA, the regularization parameters λ and β are tuned via grid search within the range of {10-3 , 10-2 , · · · , 103 }, while the number of anchors is set to m = 0.1n. After the optimization procedure, K-means clustering is repeated 20 times on the learned representation to mitigate the impact of random initialization. Finally, the average results on three metrics, including the clustering accuracy (ACC), the normalized mutual information (NMI) and the purity (PUR), are reported to evaluate the performance.
1 https://archive.ics.uci.edu/dataset/
2 https://www.kaggle.com/datasets/hojjatk/mnist-dataset
3 https://www.cs.toronto.edu/ kriz/cifar.html
| Dataset | UDBGL | AEVC | CAMVC | RCAGL | ALPC | AGLDR | HRAL | DOTA |
|---|---|---|---|---|---|---|---|---|
| ACC (%) | ||||||||
| Leaves COIL100 Hdigit MNIST KSA CIFAR100 Ave. Score Ave. Rank | 65.31±0.00 56.47±0.00 84.19±0.00 36.57±0.00 23.70±0.00 84.55±0.00 0.5847 6.83 | 79.28±1.51 58.59±1.16 85.04±0.01 46.35±0.28 29.66±0.01 92.96±1.20 0.6531 4.00 | 81.38±1.84 57.39±1.35 87.24±5.68 43.30±1.82 44.32±0.18 91.04±1.56 0.6745 4.00 | 69.81±0.00 52.65±0.00 78.44±0.00 44.02±0.00 21.12±0.00 99.97±0.00 0.6100 5.67 | 80.08±1.93 60.22±1.56 78.82±7.89 38.46±2.49 30.70±0.47 92.22±1.92 0.6342 4.67 | 69.22±0.92 63.21±1.88 87.28±0.02 48.13±0.16 23.49±0.00 95.04±0.03 0.6440 3.83 | 76.56±2.05 49.45±1.14 72.21±5.62 44.40±4.41 34.20±0.35 89.57±1.94 0.6107 5.83 | 89.86±1.21 79.42±1.13 97.25±0.00 52.37±2.18 45.09±3.22 99.92±0.00 0.7732 1.17 |
| NMI (%) | ||||||||
| Leaves COIL100 Hdigit MNIST KSA CIFAR100 Ave. Score Ave. Rank | 82.98±0.00 79.37±0.00 76.38±0.00 22.36±0.00 2.84±0.00 96.75±0.00 0.6011 6.67 | 92.06±0.53 81.90±0.42 72.25±0.02 30.95±0.10 10.53±0.02 98.82±0.21 0.6442 5.00 | 94.04±0.58 82.04±0.37 82.20±3.18 33.46±1.15 26.32±0.60 98.52±0.25 0.6943 3.17 | 87.81±0.00 78.19±0.00 73.32±0.00 36.86±0.00 1.24±0.00 99.95±0.00 0.6290 5.00 PUR (%) 82.94±0.00 | 92.90±0.53 83.21±0.49 78.87±4.27 28.70±0.67 10.36±0.24 98.73±0.30 0.6546 4.33 83.13±1.69 | 86.29±0.18 84.34±0.55 75.21±0.02 35.65±0.16 1.80±0.00 99.04±0.02 0.6372 4.50 | 91.49±0.61 74.90±0.57 66.20±2.62 32.25±2.73 18.36±0.01 98.26±0.32 0.6358 6.00 | 96.01±0.30 91.55±0.28 93.05±0.00 49.40±0.53 24.17±1.17 99.88±0.00 0.7568 1.33 |
| Leaves COIL100 Hdigit MNIST KSA CIFAR100 Ave. Score Ave. Rank | 69.94±0.00 60.24±0.00 84.19±0.00 39.57±0.00 23.70±0.00 87.76±0.00 0.6090 7.33 | 82.33±1.16 62.42±1.02 85.04±0.01 49.31±0.34 29.67±0.01 94.93±0.86 0.6728 4.67 | 84.65±1.58 61.47±0.82 87.97±4.63 47.32±1.85 44.32±0.18 93.58±1.11 0.6989 4.00 | 67.03±0.00 86.97±0.00 57.57±0.00 25.05±0.00 99.97±0.00 0.6992 3.00 | 63.87±1.37 81.69±6.25 42.54±1.36 31.82±0.01 94.43±1.36 0.6625 5.00 | 72.60±0.71 66.94±1.39 87.28±0.02 51.55±0.20 23.50±0.00 95.15±0.07 0.6617 4.50 | 80.03±1.63 54.16±1.59 73.48±4.05 47.63±3.87 34.37±0.05 92.38±1.59 0.6368 6.17 | 91.03±1.01 81.50±0.85 97.25±0.00 57.12±1.22 45.99±1.98 99.92±0.00 0.7880 1.33 |
4.2 Comparison Results
The clustering results, including means and standard deviations w.r.t. three metrics, are summarized in Table 3, where the best and second-best values are prominently marked in bold and underlined, respectively. Furthermore, the average scores and ranks of each method across all datasets are calculated to provide a comprehensive comparison. As shown in Table 3, the following conclusions can be drawn: (1) DOTA consistently achieves competitive or superior results across datasets with varying scales and types, where the best average ranks and scores in terms of different metrics are attained, highlighting its effectiveness in multi-view clustering tasks. (2) Compared with two-stage methods (i.e., UDBGL and AEVC), DOTA demonstrates considerable superiority with the average enhancement exceeding 10% across all metrics, thereby confirming that leveraging the interaction between anchor learning and graph construction promotes the overall performance. (3) The results of DOTA are superior to orthogonality-based methods (i.e., RCAGL, ALPC, and AGLDR) and structure-constrained methods (i.e., CAMVC and HRAL), underscoring the effectiveness of simultaneously optimizing the sample-anchor and anchor-anchor similarities.
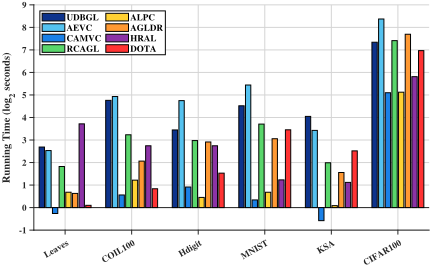
Meanwhile, to investigate the computational efficiency of DOTA, Fig. 3 displays the running times of all methods on six datasets. Since DOTA and all baselines are anchor-based MVC methods that have linear time complexity O(n), they demonstrate strong scalability across all datasets. Empirically, the running time of DOTA surpasses or remains competitive with other methods, demonstrating that our method not only attains excellent clustering results but also preserves highly competitive computational efficiency.
4.3 Visualization Analysis
To intuitively assess the effectiveness of DOTA, the similarity structure and the latent representations are visualized, where the corresponding analysis are presented below:
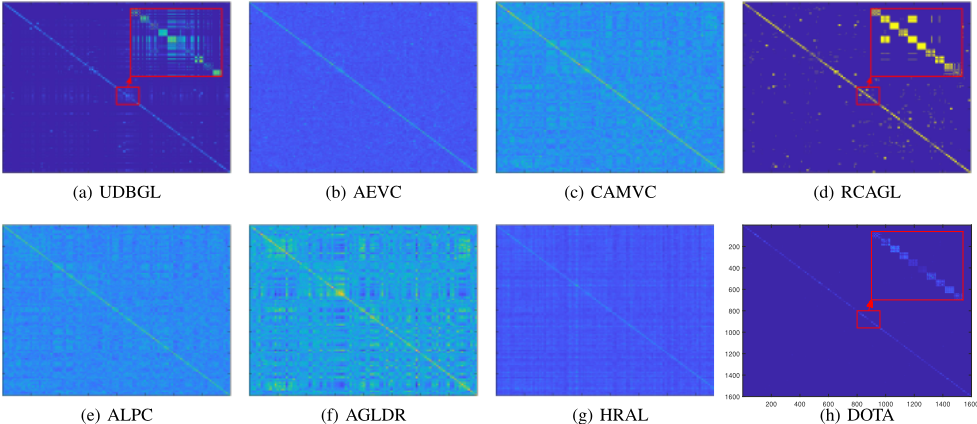
Similarity Structure: To efficiently capture similarity relationships, bipartite graph learning is widely employed in anchor-based MVC methods. Since pairwise relationships between samples can be characterized by the induced similarity matrix SST , the corresponding visualizations on Leaves are presented in Fig. 4. As illustrated in Figs. 4(a)-(g), the results of competing methods exhibit numerous irrelevant inter-cluster connections, indicating that the learned bipartite graphs fail to effectively represent the data structure. In contrast, DOTA (Fig. 4h) designs a dual-structure optimization framework to learn the similarity information, so that the intrinsic structure of samples can be captured more accurately.
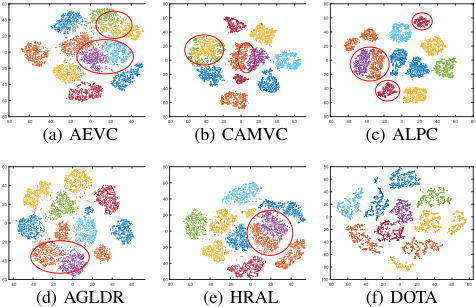
Latent Representation: To evaluate the discriminative power of the learned embeddings, Fig. 5 illustrates the T-SNE visualizations of the latent representations fed to K-means for various methods on the Hdigit dataset. We can observe that the latent representations of baseline methods (Figs. 5(a)-(e)) exhibit significant overlap between different categories (highlighted by red circles), thereby resulting in ambiguous decision boundaries. Conversely, DOTA (Fig. 5f) reveals a superior distribution, where the intrinsic manifold structure is effectively preserved and prominent margins between different classes are maintained, confirming that the dual-structure optimization framework effectively captures the similarity information and facilitates a more robust partitioning.
4.4 Ablation Study
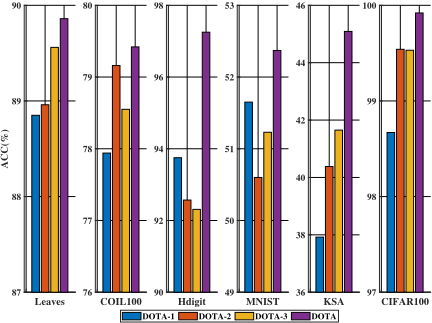
To evaluate the individual contribution of each component within DOTA, an ablation study is conducted involving three specific variants: DOTA-1 omits the anchor-based manifold regularizer term (i.e., λ = 0), relying on sample-anchor relation to capture similarity information; DOTA-2 discards the prior consistency term, where the regularization term transforms into ∥P∥2F and ∥S∥2F ; and DOTA-3 removes the adaptive view-weighting mechanism by assigning equal importance to all views (i.e., setting αv = 1). The ACC (more results are provided in the Appendix) of DOTA and its simplified versions are presented in Fig. 6, from which the following observations can be drawn: (1) The superiority of DOTA over DOTA-1 validates the effectiveness of dual-structure adaptive optimization, thereby enabling a more discriminative sample representation. (2) The observation that DOTA outperforms DOTA-2 underscores the importance of prior consistency in providing effective guidance for the similarity learning process. (3) DOTA achieves better results than DOTA-3, confirming that the adaptive fusion of complementary information across views facilitates the ultimate clustering.
4.5 Parameter Analysis and Convergence
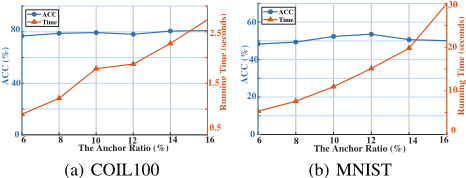
Influence of Anchor Number: To evaluate the sensitivity of DOTA to the anchor scale, Fig. 7 illustrates the trends of ACC and running time across anchor ratios ranging from {6%, 8%, . . . , 16%} × n. These observations demonstrate that the computational cost (i.e., orange curve) escalates sharply with the number of anchors, whereas the ACC (i.e., blue curve) remains relatively stable, highlighting that excessive anchors primarily imposes a heavy computational burden without a proportional enhancement in accuracy. Therefore, we empirically set the anchor ratio to 10%n to ensure high efficiency without sacrificing clustering precision.
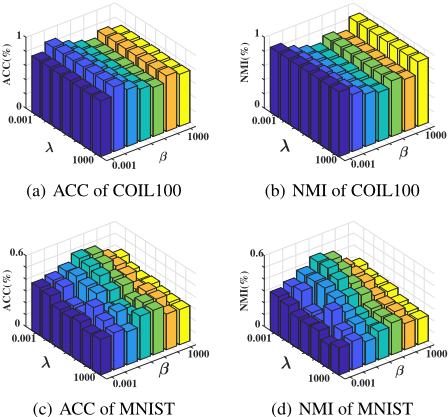
Parameter Sensitivity: DOTA incorporates two intrinsic regularization parameters to govern the similarity learning process, where λ controls the significance of the anchorbased manifold regularizer and β balances the influence of prior information guidance. Concretely, the parameter sensitivity of DOTA is illustrated in Fig. 8, depicting the ACC and NMI variations across different settings of λ and β. It can be observed that DOTA exhibits high robustness within a broad parameter range and performs better when λ is smaller than 1, underscoring that properly balancing sample-anchor as well as anchor-anchor structure effectively facilitates the capture of discriminative similarity information.
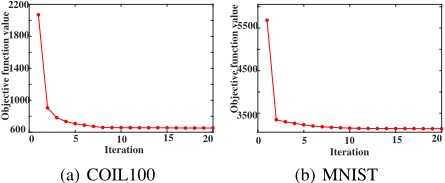
Convergence Analysis: The convergence of DOTA is shown in Fig. 9, where the objective function values decrease sharply and converge to a steady state within a few iterations, confirming the efficiency of the optimization strategy.
5 Conclusion
In this paper, a novel Dual-tOpology learning with adapTive Anchors (DOTA) method is designed to address the limitations of traditional anchor-based multi-view clustering. Specifically, by leveraging dual-structure optimization of adaptive graphs, DOTA simultaneously characterizes sampleanchor and anchor-anchor relationships, thereby effectively capturing the intrinsic structure and further strengthening the discriminative capacity of embeddings. Meanwhile, DOTA integrates the adaptive view-weights to fuse complementary information and employs an efficient decomposition strategy to learn sample embeddings, which not only achieves robust global structure preservation but also ensures computational efficiency. Extensive experiments underscore the superiority of DOTA when addressing multi-view clustering tasks.
Acknowledgments
This work was supported by the National Natural Science Foundation of China under Grants Nos. 62576161, 72471109, 62276136, 62176116 and 62306282.
@inproceedings{ijcai2026p590,
  title     = {Dual-Topology Learning with Adaptive Anchors for Multi-View Clustering},
  author    = {Zhang, Chenglong and Zhang, Chao and Zhang, Junhao and Guan, Junyi and Zhou, Xianzhong and Wang, Bo and Li, Huaxiong},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {5297--5305},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/590},
  url       = {https://doi.org/10.24963/ijcai.2026/590},
}
TY - CPAPER TI - Dual-Topology Learning with Adaptive Anchors for Multi-View Clustering AU - Zhang, Chenglong AU - Zhang, Chao AU - Zhang, Junhao AU - Guan, Junyi AU - Zhou, Xianzhong AU - Wang, Bo AU - Li, Huaxiong T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 5297 EP - 5305 DO - 10.24963/ijcai.2026/590 UR - https://doi.org/10.24963/ijcai.2026/590 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





