
BEVFormer++: Temporal Amplified BEVformer with Explicit Parameter Prediction for Automatic Trajectory Prediction
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 1079-1087.
https://doi.org/10.24963/ijcai.2026/121
Keywords
- Computer Vision: Motion and tracking
- Computer Vision: Action and behavior recognition
- Computer Vision: Multimodal learning
Abstract
Vision-based trajectory prediction with BEV representations has achieved promising results, yet existing methods often suffer from limited temporal modeling and insufficient characterization of motion dynamics. To address these issues, we propose a temporally enhanced framework with explicit motion parameter prediction. Specifically, we introduce BEVFormer++, which leverages multi-view images and BEV features from multiple preceding timesteps to generate more robust BEV representations, along with BEV differential features to capture temporal variations. Moreover, we propose a motion-parameter-decoupled tracking module that explicitly estimates velocity, acceleration, and heading angle, providing informative motion cues for trajectory prediction. Extensive experimental results demonstrate that our method outperforms state-of-the-art approaches and can be seamlessly integrated into existing vision-based frameworks, consistently yielding performance improvements.
- [Caesar et al., 2020] Holger Caesar, Varun Bankiti, Alex H Lang, Sourabh Vora, Venice Erin Liong, Qiang Xu, Anush Krishnan, Yu Pan, Giancarlo Baldan, and Oscar Beijbom. nuscenes: A multimodal dataset for autonomous driving. In CVPR, 2020.
- [Ding et al., 2024] Shuxiao Ding, Lucas Maag, Frederic Kettelhoit, Florian Hölzl, and Jürgen Gall. ADA-Track: End-to-end multi-camera 3D multi-object tracking with al- ternating detection and association. In CVPR, 2024.
- [Gu et al., 2023] Junru Gu, Chenxu Hu, Tianyuan Zhang, Xuanyao Chen, Yilun Wang, Yue Wang, and Hang Zhao. ViP3D: End-to-end visual trajectory prediction via 3D agent queries. In CVPR, 2023.
- [Han et al., 2024] Chunrui Han, Jinrong Yang, Jianjian Sun, Zheng Ge, Runpei Dong, Hongyu Zhou, Weixin Mao, Yuang Peng, and Xiangyu Zhang. Exploring recurrent long-term temporal fusion for multi-view 3D perception. IEEE Robotics and Automation Letters, 9(7):6544-6551, 2024.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, 2016.
- [Hornik et al., 1989] Kurt Hornik, Maxwell Stinchcombe, and Halbert White. Multilayer feedforward networks are universal approximators. Neural Networks, 2(5):359-366, 1989.
- [Hu et al., 2023] Yihan Hu, Jiazhi Yang, Li Chen, Keyu Li, Chonghao Sima, Xizhou Zhu, Siqi Chai, Senyao Du, Tian- wei Lin, Wenhai Wang, Lewei Lu, Jifeng Dai, Yu Qiao, and Hongyang Li. Planning-oriented autonomous driving (UniAD). In CVPR, 2023.
- [Huang and Huang, 2022] Junjie Huang and Guan Huang. BEVDet4D: Exploit temporal cues in multi-camera 3D ob- ject detection. arXiv preprint arXiv:2203.17054, 2022.
- [Huang et al., 2021] Junjie Huang, Guan Huang, Zheng Zhu, and Dalong Du. BEVDet: High-performance multi- camera 3D object detection in bird-eye-view. arXiv preprint arXiv:2112.11790, 2021.
- [Jiang et al., 2023] Bo Jiang, Shaoyu Chen, Qing Xu, Bencheng Liao, Jiajie Chen, Helong Zhou, Qian Zhang, Wenyu Liu, Chang Huang, and Xinggang Wang. VAD: Vectorized scene representation for efficient autonomous driving. In ICCV, 2023.
- [Li et al., 2022] Zhiqi Li, Wenhai Wang, Hongyang Li, Enze Xie, Chonghao Sima, Tong Lu, Yu Qiao, and Jifeng Dai. BEVFormer: Learning bird's-eye-view representa- tion from multi-camera images via spatiotemporal trans- formers. In ECCV, 2022.
- [Li et al., 2024] Tianyu Li, Peijin Jia, Bangjun Wang, Li Chen, Kun Jiang, Junchi Yan, and Hongyang Li. Lane- SegNet: Map learning with lane segment perception for autonomous driving. In ICLR, 2024.
- [Liao et al., 2023] Bencheng Liao, Shaoyu Chen, Xinggang Wang, Tianheng Cheng, Qian Zhang, Wenyu Liu, and Chang Huang. MapTR: Structured modeling and learn- ing for online vectorized HD map construction. In ICLR, 2023.
- [Liu et al., 2022] Yingfei Liu, Tiancai Wang, Xiangyu Zhang, and Jian Sun. PETR: Position embedding trans- formation for multi-view 3D object detection. In ECCV, 2022.
- [Liu et al., 2023a] Yicheng Liu, Tianyuan Yuan, Yue Wang, Yilun Wang, and Hang Zhao. VectorMapNet: End-to-end vectorized HD map learning. In ICML, 2023.
- [Liu et al., 2023b] Zhijian Liu, Haotian Tang, Alexander Amini, Xinyu Yang, Huizi Mao, Daniela L Rus, and Song Han. BEVFusion: Multi-task multi-sensor fusion with unified bird's-eye view representation. In ICRA, 2023.
- [Liu et al., 2024a] Mengmeng Liu, Hao Cheng, Lin Chen, Hellward Broszio, Jiangtao Li, Runjiang Zhao, Monika Sester, and Michael Ying Yang. LAformer: Trajectory prediction for autonomous driving with lane-aware scene constraints. In CVPR, 2024.
- [Liu et al., 2024b] Xiaolu Liu, Song Wang, Wentong Li, Ruizi Yang, Junbo Chen, and Jianke Zhu. MGMap: Mask- guided learning for online vectorized HD map construc- tion. In CVPR, 2024.
- [Loshchilov and Hutter, 2017] Ilya Loshchilov and Frank Hutter. SGDR: Stochastic gradient descent with warm restarts. In ICLR, 2017.
- [Loshchilov and Hutter, 2019] Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. In ICLR, 2019.
- [Madjid et al., 2025] Nadya Abdel Madjid, Abdulrahman Ahmad, Murad Mebrahtu, Yousef Babaa, Abdelmoamen Nasser, Sumbal Malik, Bilal Hassan, Naoufel Werghi, Jorge Dias, and Majid Khonji. Trajectory prediction for autonomous driving: Progress, limitations, and future di- rections. arXiv preprint arXiv:2503.03262, 2025. Ac- cepted for Information Fusion.
- [Neven et al., 2018] Davy Neven, Bert De Brabandere, Sta- matios Georgoulis, Marc Proesmans, and Luc Van Gool. Towards end-to-end lane detection: An instance segmen- tation approach. In IEEE Intelligent Vehicles Symposium (IV), 2018.
- [Ngiam et al., 2022] Jiquan Ngiam, Vijay Vasudevan, Ben- jamin Caine, Zhengdong Zhang, Hao-Tien Lewis Chiang, Jeffrey Ling, Rebecca Roelofs, Alex Bewley, Chenxi Liu, Ashish Venugopal, David Weiss, Ben Sapp, Zhifeng Chen, and Jonathon Shlens. Scene transformer: A unified archi- tecture for predicting multiple agent trajectories. In ICLR, 2022.
- [Pang et al., 2023] Ziqi Pang, Jie Li, Pavel Tokmakov, Dian Chen, Sergey Zagoruyko, and Yu-Xiong Wang. Stand- ing between past and future: Spatio-temporal modeling for multi-camera 3D multi-object tracking. In CVPR, 2023.
- [Pei et al., 2025a] Muleilan Pei, Shaoshuai Shi, Xuesong Chen, Xu Liu, and Shaojie Shen. Foresight in motion: Re- inforcing trajectory prediction with reward heuristics. In ICCV, 2025.
- [Pei et al., 2025b] Muleilan Pei, Shaoshuai Shi, Lu Zhang, Peiliang Li, and Shaojie Shen. GoIRL: Graph-oriented inverse reinforcement learning for multimodal trajectory prediction. In ICML, 2025.
- [Philion and Fidler, 2020] Jonah Philion and Sanja Fidler. Lift, splat, shoot: Encoding images from arbitrary camera rigs by implicitly unprojecting to 3D. In ECCV, 2020.
- [Shi et al., 2022] Shaoshuai Shi, Li Jiang, Dengxin Dai, and Bernt Schiele. Motion transformer with global intention localization and local movement refinement. In NeurIPS, 2022.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NeurIPS, 2017.
- [Wang et al., 2021] Yue Wang, Vitor C Guizilini, Tianyuan Zhang, Yilun Wang, Hang Zhao, and Justin Solomon. DETR3D: 3D object detection from multi-view images via 3D-to-2D queries. In CoRL, 2021.
- [Wang et al., 2023] Shihao Wang, Yingfei Liu, Tiancai Wang, Ying Li, and Xiangyu Zhang. Exploring object- centric temporal modeling for efficient multi-view 3D ob- ject detection. In ICCV, 2023.
- [Weng et al., 2024] Xinshuo Weng, Boris Ivanovic, Yan Wang, Yue Wang, and Marco Pavone. PARA-Drive: Par- allelized architecture for real-time autonomous driving. In CVPR, 2024.
- [Xu et al., 2025] Yi Xu, Ruining Yang, Hangcheng Cao, Mohan Wang, and Yifu Zhang. Trajectory prediction meets large language models: A survey. arXiv preprint arXiv:2506.03408, 2025.
- [Zhang et al., 2024] Bozhou Zhang, Nan Song, and Li Zhang. Demo: Decoupling motion forecasting into directional intentions and dynamic states. In NeurIPS, 2024.
- [Zhang et al., 2025a] Bozhou Zhang, Nan Song, Xin Jin, and Li Zhang. Bridging past and future: End-to-end au- tonomous driving with historical prediction and planning. In CVPR, 2025.
- [Zhang et al., 2025b] Bozhou Zhang, Nan Song, Xiatian Zhu, and Li Zhang. Demo++: Motion decoupling for autonomous driving. arXiv preprint arXiv:2507.17342, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Accurate trajectory prediction of surrounding agents is essential for autonomous vehicles to achieve safe and efficient navigation in complex and highly dynamic urban environments [Madjid et al., 2025]. It demands a deep understanding of multi-agent social interactions and the constraints imposed by traffic scenes, making it highly challenging and often leading to suboptimal performance.
Most existing trajectory prediction models are data-driven [Madjid et al., 2025] and can be broadly categorized into trajectory-based and vision-based approaches. Trajectorybased methods [Ngiam et al., 2022; Shi et al., 2022] predict future motion from historical trajectories and are computationally efficient, but their limited scene semantic understanding restricts performance in complex traffic environments. In contrast, vision-based methods [Gu et al., 2023;
∗Corresponding author.
Zhang et al., 2025a] perform end-to-end prediction from multi-camera inputs, enabling richer scene reasoning and better adaptability to complex scenarios. Generally, vision-based approaches adopt a two-stage pipeline of scene perception and motion prediction. Multi-view images are first transformed into a Bird's-Eye-View (BEV) representation for 3D object detection [Li et al., 2022; Wang et al., 2021] and map construction [Liu et al., 2024b; Li et al., 2024], after which the motion prediction module leverages BEV features together with detection results to forecast future trajectories of surrounding agents. This end-to-end paradigm allows joint optimization of perception and prediction, effectively reducing error propagation.
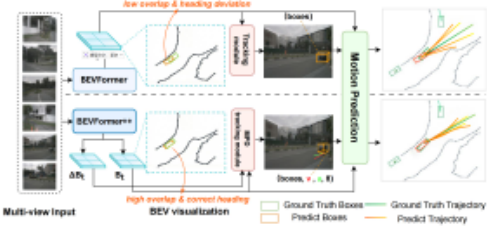
Nevertheless, the effectiveness of the end-to-end paradigm is largely constrained by the quality of the BEV features, as errors in the BEV representation can propagate through the pipeline and severely degrade both 3D detection and trajectory prediction performance. As illustrated in Fig. 1 (see the upper part), existing methods often suffer from low spatial overlap and heading deviations in BEV representations. These inaccuracies are subsequently propagated to the trajectory prediction module, resulting in significant deviations in both the direction and position of predicted object trajectories.
Although existing BEV generation methods [Li et al., 2022; Liu et al., 2023b] aim to capture complex traffic scenes and incorporate temporal information, they remain suboptimal for trajectory prediction. First, most BEV representations primarily focus on modeling static scene elements and exhibit limited capability in encoding dynamic motion information, resulting in weak temporal expressiveness and inaccurate characterization of velocity and acceleration. Second, BEV features are typically learned in a weakly supervised manner using downstream tasks such as 3D detection and trajectory prediction, which favors accurate localization but fails to explicitly capture fine-grained motion dynamics and directional attributes, such as acceleration and yaw angle, that are crucial for reliable trajectory prediction.
Motivated by the above analysis, we propose a temporally enhanced BEVFormer (BEVFormer++) with explicit motion parameter prediction for automatic trajectory prediction. Following the vision-based pipeline, BEVFormer++ generates enhanced BEV representations by jointly leveraging multi-view images and BEV features from the previous two timesteps, rather than relying solely on the immediate past. By exploiting a broader temporal context, BEVFormer++ more effectively captures scene dynamics and occluded targets, thereby improving the robustness of BEV feature generation. Moreover, BEVFormer++ produces BEV differential features that explicitly model temporal variations between neighboring timesteps, providing informative cues for estimating dynamic motion attributes such as acceleration. Building upon these enhanced representations, the proposed motion-parameter-decoupled tracking module jointly performs object tracking and motion parameter prediction-including velocity, acceleration, and heading angle-by leveraging both BEV and BEV differential features. The predicted motion parameters are subsequently incorporated into the motion prediction module to facilitate trajectory forecasting. Unlike existing vision-based approaches, explicitly supervising motion parameter learning enforces more accurate scene- and motion-aware BEV representations, leading to improved robustness. Furthermore, the incorporation of explicit dynamic parameters enables the trajectory prediction model to better capture both the position and orientation of moving agents, thereby significantly enhancing trajectory prediction accuracy.
The main contributions are summarized as follows:
- To the best of our knowledge, we are the first to introduce explicit motion parameter estimation into visionbased trajectory prediction frameworks, effectively addressing their limitations in capturing temporal dynamics. The proposed module is plug-and-play and can be seamlessly integrated into existing vision-based trajectory prediction pipelines to substantially improve trajectory prediction accuracy.
- We introduce BEVFormer++, which enhances BEV representation learning by exploiting multi-timestep temporal context. The generated BEV and BEV differential features better model both the static and dynamic characteristics of traffic scenes, thereby providing more robust support for subsequent trajectory prediction.
- We propose a motion-parameter-decoupled tracking module that explicitly predicts fine-grained motion states alongside object tracking, serving as a plug-andplay component that enhances motion modeling and trajectory prediction in vision-based frameworks.
2 RelatedWork
·
2.1 Bird's-Eye-View (BEV) Representation
The shift from perspective-view to Bird's-Eye-View (BEV) representations has significantly advanced multi-sensor 3D perception by providing a unified top-down space for fusion and planning. Early methods such as LSS [Philion and Fidler, 2020] and BEVDet [Huang et al., 2021] employ explicit depth distribution estimation to project 2D features into 3D space, establishing a geometric basis for view transformation. In contrast, Transformer-based approaches like PETR [Liu et al., 2022] implicitly learn this transformation via spatial cross-attention or 3D coordinate embeddings, effectively reducing error propagation caused by inaccurate depth cues. To address the sparsity and occlusion inherent in single-frame observations, temporal modeling has become crucial for achieving temporally consistent perception. BEVFormer [Li et al., 2022] introduces recurrent temporal selfattention to aggregate historical BEV features, while subsequent works such as VideoBEV [Han et al., 2024] and StreamPETR [Wang et al., 2023] explore longer temporal sequences or memory buffers to improve velocity estimation and object recall. Despite these advances, most existing BEV backbones are optimized for low-level detection or static occupancy tasks, where temporal fusion mainly smooths spatial features, and thus fail to capture higher-order temporal variations-such as sudden acceleration or subtle heading changes-required for complex motion forecasting. Our BEVFormer++ addresses this limitation by leveraging multitimestep differential features.
2.2 Trajectory Prediction
Early methodologies primarily formulated trajectory prediction as a sequence extrapolation problem based on historical coordinates. However, due to the absence of scene constraints, relying solely on past motion often leads to socially or geometrically implausible trajectories. To address this limitation, subsequent studies incorporated scene constraints to restrict the prediction space [Liu et al., 2024a], [Pei et al., 2025a], [Zhang et al., 2025b].
Despite leveraging scene context, these methods still struggle to capture the full semantic complexity of dynamic environments, motivating the development of vision-based endto-end frameworks such as UniAD [Hu et al., 2023] and VAD [Jiang et al., 2023]. UniAD introduces a unified query-based architecture that jointly models detection, tracking, mapping, and prediction within a single transformer to reduce error propagation. In contrast, VAD adopts a vectorized representation to transform multi-view images into Bird's-Eye-View (BEV) features for joint depth reasoning and agent interaction modeling. Nevertheless, both frameworks exhibit limitations in long-term temporal modeling. Although recent LLM-based approaches[Xu et al., 2025] attempt to address these issues by exploiting large-scale reasoning capabilities for complex social understanding, they remain computationally expensive and are typically limited to isolated sub-tasks rather than full-stack integration.
In contrast, BEVFormer++ advances vision-based trajectory prediction by explicitly grounding high-level scene understanding in physical motion constraints. Unlike prior methods that rely on black-box latent regressions or purely reasoning-driven LLMs, our approach decouples motion modeling into supervised kinematic parameters, including velocity, acceleration, and heading angle. By anchoring trajectory prediction to these explicit motion cues, BEVFormer++ produces forecasts that are both semantically informed and physically consistent with vehicle dynamics.
3 Methodology
3.1 Overview
Fig. 2 demonstrates the overall framework of our approach. Given multi-view image inputs Ft = {I 1 t , . . . , I 6 t }, existing trajectory prediction methods typically first generate the Bird's-Eye-View (BEV) feature Bt at the current timestep t, and then predict future trajectories ˆ Yt as follows:
where P denotes the camera geometry parameters, and M represents the high-definition (HD) map [Liu et al., 2023a; Liao et al., 2023] features. The tracking network Φtrack performs 3D object tracking [Pang et al., 2023; Ding et al., 2024] and provides indexed object bounding boxes to the trajectory prediction network Φtraj. In contrast, as illustrated in Fig. 2, our approach introduces a novel BEVFormer++ to extract more informative BEV representations:
where ∆Bt denotes the BEV differential feature, which explicitly captures the temporal variation between BEV features at neighboring timesteps. Building upon these enhanced BEV representations, we further redesign the tracking network by introducing a motion parameter decoupling mechanism:
where ˆMt = {a, v, θ} denotes the estimated motion states of agents, including acceleration a, velocity v, and heading angle θ, and ˆOt represents the indexed bounding boxes of predicted motion agents. Finally, the predicted motion states ˆMt are explicitly incorporated into the trajectory prediction module to enhance future trajectory estimation:
in the following sections, we provide detailed descriptions of BEVFormer++, the motion-parameter-decoupled tracking network ΦMPDtrack , and the trajectory prediction network.
3.2 BEVFormer++
The traditional BEVFormer constructs the BEV representation at the current timestep by fusing multi-camera visual features with the BEV feature propagated from the previous timestep. This design facilitates object velocity estimation and partially mitigates occlusion effects. However, relying only on visual information from two adjacent timesteps is often insufficient for robustly identifying heavily occluded objects, which may in turn propagate errors into downstream trajectory prediction. Furthermore, due to variations in vehicle speed during driving, feature differences between consecutive timesteps provide merely a coarse approximation of velocity and are incapable of capturing higher-order motion dynamics such as acceleration, thereby potentially degrading the accuracy of trajectory prediction.
Motivated by these observations, we propose a temporally enhanced BEVFormer, termed BEVFormer++. BEVFormer++ jointly exploits the temporal correlations between the current multi-view features and the BEV features from the two preceding timesteps, leading to more accurate and temporally consistent BEV representations. Furthermore, by explicitly comparing BEV features across different timesteps, BEVFormer++ derives BEV differential features that encode higher-order motion information, providing informative cues for object acceleration estimation.
Specifically, given the grid-shaped learnable BEV queries Q ∈ RH×W×C at the current timestamp t, together with the historical BEV features Bt-1 and Bt-2 ∈ RH×W×C preserved from the two preceding timesteps, where H and W denote the spatial resolution of the BEV plane and C is the channel dimension, we first align Bt-1 and Bt-2 to Q according to the ego-motion. This alignment ensures that features at the same BEV grid correspond to the same real-world locations, yielding two ego-motion-compensated historical BEV features B′t-1 and B′t-2 . On this basis, the traditional BEVFormer models the temporal association of the same objects between timesteps t - 1 and t through a temporal selfattention (TSA [Vaswani et al., 2017]) layer, which can be expressed as:
where Qp ∈ R1×C denotes the BEV query located at p = (x, y), and V is the input feature maps concatenated by Q and B′t-1 . Aij and ∆pij are the attention weights and predicted offsets both obtained through a linear transformation on Qp. W′i andWi are learnable weights. Nhead and Npoint indicates the total number of attention heads and sampling points in each head, respectively. Differently, BEVformer++ further considers the temporal association of the BEV features between the timestep t - 2 and t, and finally predict the BEV feature and BEV differential feature at the timestep t as follows:
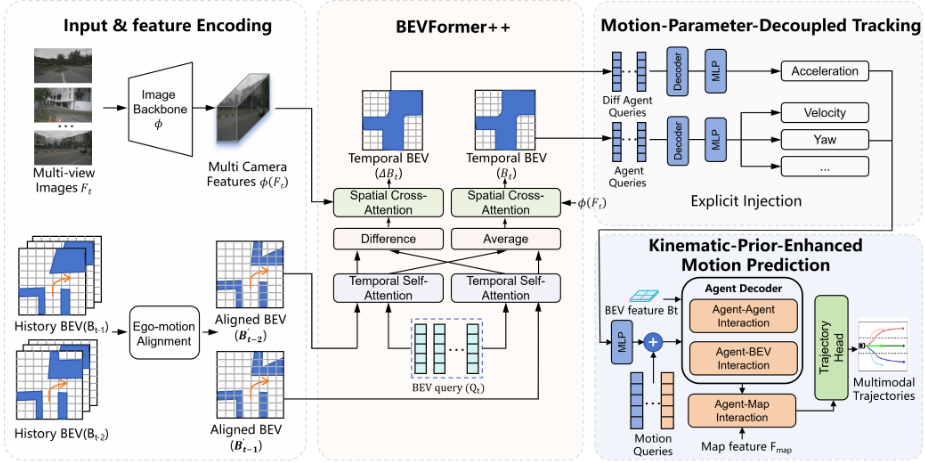
where avg(, ) and dif(, ) represent the average and difference operations between two elements, respectively, and ω represent the subsequent series operations in BEVFormer including spatial cross-attention, Normalization and Feed Forward.
Beyond the tradition BEVFormer, BEVFormer++ has the following advantages: First, it takes into account the bev features over a longer historical period, enabling it to more accurately capture changes in the environment and targets, and more effectively mitigate the issue of target occlusion. Second, it considers the difference in BEV (Bird's Eye View) features between adjacent moments, enabling it to more accurately capture the motion trend of the target and provide feature basis for subsequent acceleration evaluation.
3.3 Motion-parameter-decoupled Tracking
Unlike conventional tracking models that infer 3D tracking results solely from BEV features at timestep t, the proposed motion-parameter-decoupled tracking module jointly exploits both BEV features and BEV differential features to produce 3D tracking outputs. Meanwhile, it explicitly estimates each agent's motion parameters, including velocity ˆv ∈ R2×Na , acceleration ˆa ∈ R2×Na , and heading angle ˆ θ ∈ R2×Na , where Na records the number of potential agents. By decoupling motion parameter estimation from spatial localization, the proposed design enables more precise modeling of finegrained agent dynamics.
To this end, we initialize two sets of learnable queries, Qa ∈ RNa×C and Q∆a ∈ RNa×C , and employ a dualbranch Transformer decoder [Hornik et al., 1989] to decouple the modeling of agent motion states. Specifically, the first branch leverages Qa to estimate agents' instantaneous states, including velocity (ˆv, heading angle ˆ θ, and 3D bounding boxes, from the BEV feature Bt, while the second branch utilizes Q∆a to infer higher-order motion states, namely acceleration ˆa, from the BEV differential feature ∆Bt. In both branches, the learnable queries are first processed by selfattention to capture inter-agent dependencies. They are then used as queries (Q) in a cross-attention module, where the corresponding BEV features serve as keys (K) and values (V ) to aggregate rich spatiotemporal context. Finally, the fused representations are decoded into decoupled motion components through multi-layer perceptrons (MLPs [Hornik et al., 1989]). The overall process can be formulated as:
The decoupled motion state representations produced by Eq. (7) serve as explicit physical priors for subsequent motion prediction. To ensure the reliability of these priors, we supervise their learning by optimizing a dynamic loss Ldyn, which is formulated using the L1 norm against the corresponding ground-truth motion labels:
where Npos denotes the number of successfully matched positive proxies. The ground-truth acceleration ai is obtained by computing the change in displacement between adjacent future timestamps in the training set. Furthermore, to address the phase wrap-around issue-where angles such as 1◦ and 359◦ are physically close but numerically distant, leading to gradient instability in direct regression-we adopt a phaseaware rotation loss to supervise the learning of the yaw angle:
The total motion state loss is then expressed as:
where λ is a weighting hyperparameter.
3.4 Kinematic-Prior-EnhancedMotion Prediction
Existing BEV-based motion prediction methods typically rely on BEV features and agent position information to predict future motion states, which may lead to predictions that violate real-world physical laws. To address this, our motion prediction module explicitly integrates agents' motion-parameterdecoupled physical priors, ensuring that the predictions are both more accurate and consistent with physical principles.
Specifically, our motion prediction module first encodes the motion-parameter-decoupled priors using an MLP to obtain the motion prior features Fp ∈ RNa×C , expressed as:
where (x, y) denotes the BEV coordinates. The motion state prior feature Fp is then fused additively with the initialized motion queries Qinit ∈ RNa×C to produce the physical priors-enhanced motion queries Qm ∈ RNa×C :
We then input Qm as queries and Bt as keys and values into the Transformer decoder to aggregate agent and environmental context from the BEV features Bt, yielding the refined latent representation Hm ∈ RNa×Nmode×C , expressed as:
where Nmode denotes the number of distinct trajectories. To further incorporate topological constraints from the road network, the model performs agent-map interaction. This interaction is formulated as:
where Fmap represents instance-level map features extracted by a LaneNet [Neven et al., 2018] through hierarchical MLP layers and max-pooling over predicted vectorized lane points. By aggregating environmental context through this crossattention mechanism, the refined latent representation H′m explicitly captures the physical constraints of the surrounding traffic infrastructure.
Finally, we decode H′m to generate the agents' motion trajectories ˆYt:
where T denotes the future timestamps. Here, Nmode represents the number of motion modes, accounting for the inherent multimodality of agent behavior in complex traffic scenarios. By generating Nmode distinct trajectories for each agent, the model can represent multiple plausible future outcomes (e.g., turning left vs. going straight), thereby providing a probabilistic distribution of future states rather than a single deterministic path.
4 Experiments
4.1 Dataset
We conduct experiments on the challenging public nuScenes dataset [Caesar et al., 2020], which comprises 1,000 driving scenes, each lasting approximately 20 seconds. Following the official data split, 700 scenes are used for training, 150 for validation, and 150 for testing. Consistent with prior work [Jiang et al., 2023; Hu et al., 2023], trajectory prediction performance is evaluated using Minimum Average Displacement Error (minADE), Minimum Final Displacement Error (minFDE), and Miss Rate (MR). In addition, mean Average Precision (mAP) and nuScenes Detection Score (NDS) [Caesar et al., 2020] are adopted to assess the quality of 3D object detection.
4.2 Implementation Details
We select two vision-based methods VAD [Jiang et al., 2023] and UniAD [Hu et al., 2023] as our baselines, which both use ResNet101 [He et al., 2016] as the image backbone. Our approach replaces their BEVFormer with our BEVFormer++. To make a fair comparison, we follow the settings of the BEVFormer. Specifically, the size of BEV queries is 200 × 200 with C = 256. We adopt learnable positional embedding for BEV queries. The BEV encoder contains 6 encoder layers and constantly refines the BEV queries in each layer. For each local query, we set Nhead = 8, Npoint = 4. In our Motionparameter-decoupled tracking, we set the weight = 0.5 in Eq (10). We use AdamW [Loshchilov and Hutter, 2019] optimizer and Cosine Annealing [Loshchilov and Hutter, 2017] scheduler to train our model with weight decay 0.01 and initial learning rate 2 × 10⁻⁴ . We trained our model for 60 epochs on 6 NVIDIA RTX A6000 GPUs with batch size 1 per GPU.
4.3 Comparison with the State-of-the-art Methods
We compare our approach against several state-of-the-art methods, including vision-based approaches such as ViP3D, VAD, and UniAD, as well as trajectory-based methods such as DeMo, LAformer, and FiM. The quantitative results are summarized in Table 1. Our method consistently achieves the best performance across all evaluation metrics, outperforming both vision-based and trajectory-based trajectory prediction approaches. As a vision-based framework, our method significantly enhances temporal modeling capability by explicitly incorporating dynamic information. By introducing motion parameter prediction, our approach effectively bridges the strengths of vision-based and trajectory-based methods, leading to superior overall performance. Furthermore, compared with the two strong baselines, VAD and UniAD, our method yields substantial and consistent performance gains. These improvements can be attributed to the enhanced dynamic feature modeling enabled by BEVFormer++, as well as the explicit incorporation of motion parameters into the trajectory prediction module. Regarding computational cost, our method incurs only a minimal overhead. Our approachVAD achieves 4.4 FPS (vs. 4.5 FPS for VAD), and Our approachUniAD reaches 1.7 FPS (vs. 1.8 FPS for UniAD). The slight reduction in frame rate is attributed to the additional motion constraint calculations; however, given the substantial reduction in error rates, this trade-off is welljustified. Together, these components allow the model to more accurately capture agents' positions, velocities, and motion directions, resulting in more precise trajectory predictions.
| Method | minADE5 ↓ | minFDE5 ↓ | MR5 ↓ | FPS |
|---|---|---|---|---|
| DeMo [Zhang et al., 2024] | 0.918 | 1.613 | 0.287 | / |
| FiM [Pei et al., 2025a] | 0.880 | / | 0.310 | / |
| LAformer [Liu et al., 2024a] | 0.921 | 1.643 | 0.27 | 8.7 |
| Para-Drive [Weng et al., 2024] | 0.720 | 1.090 | 0.142 | 5.0 |
| ViP3D [Gu et al., 2023] | 1.210 | 2..210 | 0.239 | / |
| GoIRL [Pei et al., 2025b] | 0.750 | / | 0.210 | / |
| VAD [Jiang et al., 2023] | 0.674 | 0.919 | 0.096 | 4.5 |
| UniAD [Hu et al., 2023] | 0.716 | 1.029 | 0.154 | 1.8 |
| Our approachUniAD | 0.697 | 0.937 | 0.128 | 1.7 |
| Our approachVAD | 0.615 | 0.883 | 0.089 | 4.4 |
4.4 Evaluation of BEVFormer++
We evaluate 3D object detection performance under two settings: pure 3D detection and trajectory prediction. As shown in Table 2, we compare BEVFormer++ with three representative BEV feature extraction methods-BEVFormer, StreamPETR, and BEVDet4D-on pure 3D detection tasks. The results indicate that BEVFormer++ achieves the best detection performance among all compared methods. This improvement primarily stems from its enhanced temporal modeling capability, which aggregates BEV features from multiple historical timesteps and explicitly captures temporal variations through BEV differential features. As a result, BEVFormer++ can more robustly perceive dynamic and occluded objects, leading to more accurate and stable 3D detection results. In the trajectory prediction setting, we observe a notable degradation in 3D detection performance, suggesting that the model tends to prioritize trajectory correctness over precise spatial localization. In such cases, the BEV representation alone may be insufficient for accurate 3D positioning, and the resulting localization errors can propagate to downstream trajectory prediction tasks. As evidenced by the experimental results, BEVFormer++ effectively mitigates this issue by introducing explicit supervision on both static and dynamic target parameters. This additional supervision enables more accurate estimation of agents' positions and motion states, thereby reducing error propagation and improving overall trajectory prediction performance.
4.5 Ablation Studies
We perform comprehensive ablation studies on the nuScenes validation set to verify the effectiveness of our proposed BEVFormer++, the Motion-Parameter-Decoupled Tracking (MPDTraj), and the motion state loss formulation. The quantitative results, summarized in Table 3 and Table 4, demonstrate that each component is essential for achieving optimal trajectory prediction performance.
| Method | mAP ↑ | NDS ↑ |
|---|---|---|
| BEVFormer [Li et al., 2022] | 0.481 | 0.569 |
| StreamPETR [Wang et al., 2023] | 0.396 | 0.490 |
| BEVDet4D [Huang and Huang, 2022] | 0.451 | 0.569 |
| BEVFormer++ (Det) | 0.498 | 0.587 |
| BEVFormer(UniAD) [Hu et al., 2023] | 0.310 | 0.374 |
| BEVFormer(VAD) [Jiang et al., 2023] | 0.321 | 0.455 |
| BEVFormer++ (UniAD) | 0.386 | 0.488 |
| BEVFormer++ (VAD) | 0.401 | 0.502 |
| BEVFormer++ | MPDTraj | minADE5↓ | minFDE5↓ | MR5↓ |
|---|---|---|---|---|
| × | × | 0.674 | 0.919 | 0.096 |
| ✓ | × | 0.675 | 0.915 | 0.095 |
| × | ✓ | 0.652 | 0.905 | 0.092 |
| ✓ | ✓ | 0.615 | 0.883 | 0.089 |
Impact of BEVFormer++. As shown in the first two rows of Table 3, introducing BEVFormer++ (which integrates Bt-2 and computes explicit differential features) yields improvements in long-term prediction accuracy (minFDE decreases from 0.919 to 0.915) and miss rate. While the standalone gain is moderate, BEVFormer++ is critical for the full system; it provides the high-fidelity differential BEV features (∆Bt) required by the acceleration branch of the tracking module. Its full potential is unlocked when combined with MPDTraj, where the synergistic integration leads to the stateof-the-art performance (Row 4).
Impact of MPDTraj. The introduction of the MPDTraj module (Row 3) significantly reduces minADE from 0.674 to 0.652 compared to the baseline. This confirms that explicitly decoupling motion parameters (velocity, acceleration, and heading angle) allows the network to capture fine-grained agent dynamics more effectively than implicit latent modeling. Furthermore, the combination of MPDTraj and BEVFormer++ (Row 4) achieves the lowest errors across all metrics (0.615 minADE). This substantial improvement validates that accurate acceleration estimation relies heavily on the temporal differential cues provided by BEVFormer++.
Effectiveness of the Motion State Loss. To investigate the trade-off between kinematic magnitude and directional constraints, we evaluate the impact of the hyperparameter λ in our joint loss function Ltotal, as reported in Table 4. The results exhibit a clear optimum at λ = 0.5. Setting λ = 0.0 (ignoring dynamics) leads to significant degradation in displacement errors (minADE 0.696), as the model fails to constrain speed and acceleration. Conversely, λ = 1.0 (ignoring rotation) hampers performance by neglecting the yaw angle, which is critical for trajectory shape. The balanced setting (λ = 0.5) effectively harmonizes the scalar L1 constraints on velocity/acceleration with the phase-aware supervision of heading, yielding the most accurate trajectory predictions.
| λ | minADE5 ↓ | minFDE5 ↓ | MR ↓ |
|---|---|---|---|
| 0.0 | 0.696 | 1.092 | 0.117 |
| 0.2 | 0.637 | 0.971 | 0.098 |
| 0.5 | 0.615 | 0.883 | 0.089 |
| 0.8 | 0.628 | 0.929 | 0.093 |
| 1.0 | 0.654 | 1.019 | 0.103 |
5 Qualitative Results
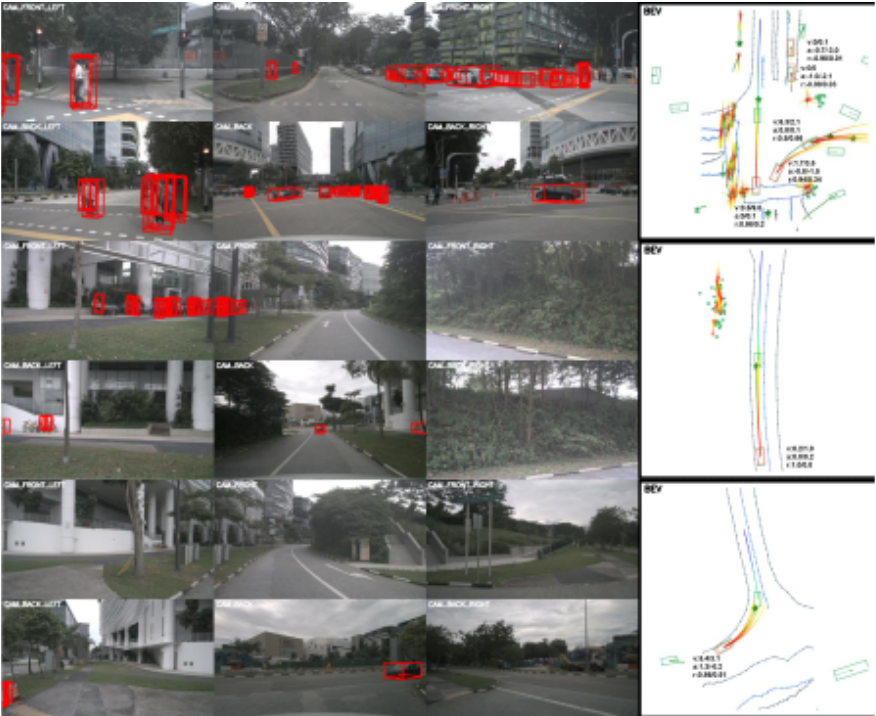
We visualize BEVFormer++ performance across complex intersections, straight segments, and turning maneuvers in Fig. 3. By leveraging multi-timestep aggregation, our model maintains robust 3D detection despite occlusions or camera truncations. The Bird's-Eye-View (BEV) results demonstrate smooth, kinematically feasible trajectories (yellow-tored curves) that remain strictly aligned with agent momentum and road topology. These results confirm that explicit motion parameter supervision effectively eliminates kinematically unfeasible predictions in complex urban environments.
6 Conclusion
In this paper, we present BEVFormer++, a temporally enhanced framework that integrates multi-timestep BEV aggregation and explicit motion parameter prediction for robust trajectory forecasting. By leveraging BEV differential features and a decoupled tracking module, our method effectively captures fine-grained agent dynamics including velocity, acceleration, and heading angle. Extensive experiments on the nuScenes benchmark demonstrate that our approach consistently outperforms state-of-the-art methods and provides physically consistent predictions in complex driving scenarios.
Acknowledgments
This work was partially supported by National Natural Science Foundation of China (No.62272157).
@inproceedings{ijcai2026p121,
  title     = {BEVFormer++: Temporal Amplified BEVformer with Explicit Parameter Prediction for Automatic Trajectory Prediction},
  author    = {Fang, Jiabin and Zhang, Xu and Ding, Zhuoming and Liu, Xuan and Zhang, Meifang and Yuan, Jin and Wang, Yuyi},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {1079--1087},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/121},
  url       = {https://doi.org/10.24963/ijcai.2026/121},
}
TY - CPAPER TI - BEVFormer++: Temporal Amplified BEVformer with Explicit Parameter Prediction for Automatic Trajectory Prediction AU - Fang, Jiabin AU - Zhang, Xu AU - Ding, Zhuoming AU - Liu, Xuan AU - Zhang, Meifang AU - Yuan, Jin AU - Wang, Yuyi T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 1079 EP - 1087 DO - 10.24963/ijcai.2026/121 UR - https://doi.org/10.24963/ijcai.2026/121 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





