
Pitfalls of Learning a Reward Function Online
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 1592-1600.
https://doi.org/10.24963/ijcai.2020/221
Keywords
- Knowledge Representation and Reasoning: Belief Change, Belief Merging
- Machine Learning: Reinforcement Learning
- Agent-based and Multi-agent Systems: Human-Agent Interaction
Abstract
In some agent designs like inverse reinforcement learning an agent needs to learn its own reward function. Learning the reward function and optimising for it are typically two different processes, usually performed at different stages. We consider a continual (``one life'') learning approach where the agent both learns the reward function and optimises for it at the same time. We show that this comes with a number of pitfalls, such as deliberately manipulating the learning process in one direction, refusing to learn, ``learning'' facts already known to the agent, and making decisions that are strictly dominated (for all relevant reward functions). We formally introduce two desirable properties: the first is `unriggability', which prevents the agent from steering the learning process in the direction of a reward function that is easier to optimise. The second is `uninfluenceability', whereby the reward-function learning process operates by learning facts about the environment. We show that an uninfluenceable process is automatically unriggable, and if the set of possible environments is sufficiently large, the converse is true too.
- [Abbeel and Ng, 2004] Pieter Abbeel and Andrew Ng. Ap- prenticeship Learning Via Inverse Reinforcement Learn- ing. In International Conference on Machine Learning, pages 1-8, 2004.
- [Abel et al., 2017] David Abel, John Salvatier, Andreas Stuhlmüller, and Owain Evans. Agent-Agnostic Human- in-the-Loop Reinforcement Learning. arXiv preprint arXiv:1701.04079, 2017.
- [Akrour et al., 2012] Riad Akrour, Marc Schoenauer, and Michèle Sebag. April: Active Preference Learning-based Reinforcement Learning. In Joint European Confer- ence on Machine Learning and Knowledge Discovery in Databases, pages 116-131. Springer, 2012.
- [Amin and Singh, 2016] Kareem Amin and Satinder Singh. Towards Resolving Unidentifiability in Inverse Reinforce- ment Learning. arXiv preprint, arXiv:1601.06569, 2016.
- [Armstrong et al., 2020] Stuart Armstrong, Jan Leike, Lau- rent Orseau, and Shane Legg. Pitfalls of Learning a Re- ward Function Online. arXiv e-prints, April 2020.
- [Armstrong, 2017] Stuart Armstrong. Good and Safe Uses of AI Oracles. arXiv preprint arXiv:1711.05541, 2017.
- [Bostrom, 2014] Nick Bostrom. Superintelligence: Paths, dangers, strategies. Oxford University Press, 2014.
- [Buntine, 1994] Wray L Buntine. Operations for Learning with Graphical Models. Journal of Artificial Intelligence Research, 2:159-225, 1994.
- [Choi and Kim, 2011] Jaedeug Choi and Kee-Eung Kim. In- verse Reinforcement Learning in Partially Observable En- vironments. Journal of Machine Learning Research, 12:691-730, 2011.
- [Christiano et al., 2017] Paul F Christiano, Jan Leike, Tom Brown, Miljan Martic, Shane Legg, and Dario Amodei. Deep Reinforcement Learning from Human Preferences. In Advances in Neural Information Processing Systems, pages 4302-4310, 2017.
- [Everitt and Hutter, 2016] Tom Everitt and Marcus Hutter. Avoiding Wireheading with Value Reinforcement Learn- ing. In International Conference on Artificial General In- telligence, pages 12-22. Springer, 2016.
- [Everitt and Hutter, 2019] Tom Everitt and Marcus Hutter. Reward Tampering Problems and Solutions in Reinforce- ment Learning: A Causal Influence Diagram Perspective. arXiv preprint arXiv:1908.04734, 2019.
- [Everitt, 2018] Tom Everitt. Towards Safe Artificial General Intelligence. PhD thesis, The Australian National Univer- sity, 2018.
- [Hadfield-Menell et al., 2016] Dylan Hadfield-Menell, Anca Draga, Pieter Abbeel, and Stuart Russell. Cooperative In- verse Reinforcement Learning. In Advanced in Neural In- formation Processing Systems, pages 3909-3917, 2016.
- [Hadfield-Menell et al., 2017] Dylan Hadfield-Menell, Smitha Milli, Stuart J Russell, Pieter Abbeel, and Anca Dragan. Inverse Reward Design. In Advances in Neural Information Processing Systems, pages 6749-6758, 2017.
- [Hutter, 2004] Marcus Hutter. Universal Artificial Intelli- gence: Sequential Decisions Based on Algorithmic Prob- ability. Springer, 2004.
- [Ibarz et al., 2018] Borja Ibarz, Jan Leike, Tobias Pohlen, Geoffrey Irving, Shane Legg, and Dario Amodei. Reward Learning from Human Preferences and Demonstrations in Atari. In Advances in Neural Information Processing Sys- tems, pages 8011-8023, 2018.
- [Kahneman, 2011] Daniel Kahneman. Thinking, Fast and Slow. Farra, Straus and Giroux, 2011.
- [Lee et al., 2017] Chun-I Lee, I-Ping Chen, Chi-Min Hsieh, and Chia-Ning Liao. Design Aspects of Scoring Systems in Game. Art and Design Review, 05(01):26-43, 2017.
- [Leike et al., 2017] Jan Leike, Miljan Martic, Victoria Krakovna, Pedro A Ortega, Tom Everitt, Andrew Lefrancq, Laurent Orseau, and Shane Legg. AI Safety Gridworlds. arXiv preprint arXiv:1711.09883, 2017.
- [MacGlashan et al., 2017] James MacGlashan, Mark K Ho, Robert Loftin, Bei Peng, David Roberts, Matthew E Taylor, and Michael L Littman. Interactive Learning from Policy-dependent Human Feedback. arXiv preprint arXiv:1701.06049, 2017.
- [Ng and Russell, 2000] Andrew Y. Ng and Stuart J. Russell. Algorithms for Inverse Reinforcement Learning. In In- ternational Conference on Machine Learning, pages 663- 670, 2000.
- [Pearl, 2009] Judea Pearl. Causality. Cambridge University Press, 2009.
- [Pilarski et al., 2011] Patrick M Pilarski, Michael R Daw- son, Thomas Degris, Farbod Fahimi, Jason P Carey, and Richard S Sutton. Online Human Training of a Myoelec- tric Prosthesis Controller Via Actor-Critic Reinforcement Learning. In Rehabilitation Robotics, pages 1-7, 2011.
- [Sutton and Barto, 1998] Richard Sutton and Andrew G. Barto. Reinforcement Learning: An Introduction. MIT Press, 1998.
- [Vogt, 2007] Paul Vogt. Language Evolution and Robotics: Issues on Symbol Grounding and Language Acquisition. In Artificial cognition systems, pages 176-209. IGI Global, 2007.
- [Yudkowsky, 2008] Eliezer Yudkowsky. Artificial intelli- gence as a positive and negative factor in global risk. In Nick Bostrom and Milan M. Ćirković, editors, Global catastrophic risks, pages 308-345, New York, 2008. Ox- ford University Press.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In reinforcement learning (RL) an agent has to learn to solve the problem by maximising the expected reward provided by a reward function [Sutton and Barto, 1998]. Designing such a reward function is similar to designing a scoring function for a game, and can be very difficult ([Lee et al., 2017]) 1 . Usually, one starts by designing a proxy: a simple reward function that seems broadly aligned with the user's goals. While testing the agent with this proxy, the user may observe that the agent finds a simple behaviour that obtains a high reward on the proxy, but does not match the behaviour intended by the user, 2 who must then refine the reward function to include more complicated requirements, and so on.
∗Contact Author
1 And see "Specification gaming: the flip side of AI ingenuity", https://deepmind.com/blog/article/ Specification-gaming-the-flip-side-of-AI-ingenuity
2 See https://blog.openai.com/faulty-rewardfunctions/ and the paper [Leike et al., 2017].
This has led to a recent trend to learn a model of the reward function, rather than having the programmer design it ([Ng and Russell, 2000; Hadfield-Menell et al., 2016; Choi and Kim, 2011; Amin and Singh, 2016; Abbeel and Ng, 2004; Christiano et al., 2017; Hadfield-Menell et al., 2017; Ibarz et al., 2018; Akrour et al., 2012; MacGlashan et al., 2017; Pilarski et al., 2011]). One particularly powerful approach is putting the human into the loop ([Abel et al., 2017]) as done by [Christiano et al., 2017], because it allows for the opportunity to correct misspecified reward functions as the RL agent discovers exploits that lead to higher reward than intended.
However, learning the reward function with a human in the loop has one problem: by manipulating the human, the agent could manipulate the learning process. 3 If the learning process is online - the agent is maximising its reward function as well as learning it - then the human's feedback is now an optimisation target. [Everitt and Hutter, 2016; Everitt and Hutter, 2019] and [Everitt, 2018] analyse the problems that can emerge in these situations, phrasing it as a 'feedback tampering problem'. Indeed, a small change to the environment can make a reward-function learning process manipulable. 4 So it is important to analyse which learning processes are prone to manipulation.
After building a theoretical framework for studying the dynamics of learning reward functions online, this paper will identify the crucial property of a learning process being uninfluenceable: in that situation, the reward function depends only on the environment, and is outside the agent's control. Thus it is completely impossible to manipulate an uninfluenceable learning process, and the reward-function learning is akin to Bayesian updating.
The paper also identifies the weaker property of unriggability, an algebraic condition that ensures that actions taken by the agent do not influence the learning process in expectation. An unriggable learning process is thus one the agent cannot 'push' towards its preferred reward function.
3 Humans have many biases and inconsistencies that may be exploited ([Kahneman, 2011]), even accidentally; and humans can be tricked and fooled, skills that could be in the interest of such an agent to develop, especially as it gets more powerful ([Bostrom, 2014; Yudkowsky, 2008]).
4 See this example, where an algorithm is motivated to give a secret password to a user while nominally asking for it, since it is indirectly rewarded for correct input of the password: https://www.lesswrong.com/posts/b8HauRWrjBdnKEwM5/ rigging-is-a-form-of-wireheading
An uninfluenceable learning process is automatically unriggable, but the converse need not be true. This paper demonstrates that, if the set of environments is large enough, an unriggable learning process is equivalent, in expectation, to an uninfluenceable one. If this condition is not met, unriggable-but-influenceable learning processes do allow some undesirable forms of manipulations. The situation is even worse if the learning process is riggable: the agent can follow a policy that would reduce its reward, with certainty, for all the reward functions it is learning about, among other pathologies.
To illustrate, this paper uses a running example of a child asking their parents for career advice (see Section 2.2). That learning process can be riggable, unriggablebut-influenceable, or uninfluenceable, and Q-learning examples based on it will be presented in Section 6.
This paper also presents a 'counterfactual' method for making any learning process uninfluenceable, and shows some experiments to illustrate its performance compared with influenceable and riggable learning.
2 Notation and Formalism
The agent takes a series of actions (from the finite set A) and receives from the environment a series of observations (from the finite set O). A sequence of m actions and observations forms a history of length m: hm = a1o1a2o2 . . . amom. Let Hm be the set of histories of length m.
We assume that all interactions with the environment are exactly n actions and observations long. Let the set of all possible (partial) histories be denoted with H = ⋃ni=0 Hi. The histories of length n (Hn, in the notation above), are called the complete histories, and the history h0 is the empty history.
The agent chooses actions according to a policy π ∈ Π, the set of all policies. We write P(a | hm, π) for the probability of π choosing action a given the history hm.
An environment µ is a probability distribution over the next observation, given a history hm and an action a. Write P(o | hma, µ) for the conditional probability of a given o ∈ O.
Let hkm be the initial k actions and observations of hm. We write hk ⊑ hm if hk = hkm. For a policy π and an environment µ, we can define the probability of a history hm = a1o1a2o2 . . . amom
Finally, P(hm | hk, π, µ) given hk ⊑ hm is defined in the usual way.
If hm is a history, let a(hm) be the m-tuple of actions of hm. Note that a(hm) = a1 . . . am can be seen as a very simple policy: take action ai on turn i. This allows us to define the probability of hm given environment µ and actions a(hm), written as P(hm | µ) = P(hm | a(hm), µ). Note that for any policy π,
If M is a set of environments, then any prior ξ in ∆(M) also defines a probability for a history hm:
By linearity, we get that Equation (1) also applies when conditioning hm on π and ξ instead of π and µ.
Let hm be a history; then the conditional probability of an environment given prior and history 5 is equal to:
Using this, ξ itself defines an environment as a conditional distribution on the next observation o ([Hutter, 2004]):
2.1 Reward Functions and Learning Processes
Definition 1 (Reward function). A reward function R is a map from complete histories to real numbers 6 . Let R = {R : Hn → R} be the set of all reward functions.
A reward-function learning process ρ can be described by a conditional probability distribution over reward functions, given complete histories. 7 Write this as:
This paper will use those probabilities as the definition of ρ.
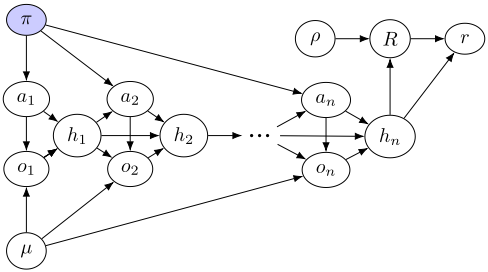
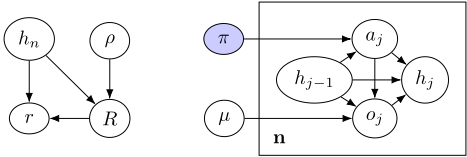
The environment, policy, histories, and learning process can be seen in terms of causal graphs ([Pearl, 2009]) in Figure 1 and using plate notation ([Buntine, 1994]), in Figure 2. The agent is assumed to know the causal graph and the relevant probabilities; it selects the policy π.
2.2 Running Example: Parental Career Instruction
Consider a child asking a parent for advice about the reward function for their future career. The child is hesitating between RB, the reward function that rewards becoming a banker, and RD, the reward function that rewards becoming a doctor. Suppose for the sake of this example that becoming a banker provides rewards more easily than becoming a doctor does.
5 The hm generates the policy a(hm), implicitly used here.
6 These are sometimes called return functions, the discounted sum of rewards. The results of this paper apply to traditional reward functions - that take values on all histories, not just complete histories - but they are easier to see in terms of return function.
7 Anything we would informally define as a 'reward-function learning process' has to at least be able to produce such conditional probabilities. If the learning process is unriggable (see subsection 3.3), then there is a natural way to extend it from complete histories to shorter histories, see Section 3.3.
The child learns their career reward function by asking a parent about it. We assume that the parents always give a definitive answer, and that this completely resolves the question for the child. That is, the reward-function learning process of the child is to fix a reward function once it gets an answer from either parent.
We can formalize this as follows. Set episode length n = 1 (we only focus on a single action of the agent), and A = {M, F}, the actions of asking the mother and the father, respectively. The observations are the answers of the asked parent, O = {B,D}, answering banker or doctor. There are thus 2 × 2 = 4 histories. Since in this example the banker reward function RB is assumed to be easier to maximise than the doctor one; we set RB(h1) = 10 and RD(h1) = 1 for all histories h1 ∈ H1.
The set of possible environments is M = {µBB, µBD, µDB, µDD}, with the first index denoting the mother's answer and the second the father's. The reward-function learning process ρ is:
See Section 6 for some Q-learning experiments with a version of this learning process in a gridworld.
3 Uninfluenceable and Unriggable Reward-function Learning Processes
What would constitute a 'good' reward-function learning process? In Figure 2, the reward function R is a causal descendant of hn, which itself is a causal descendant of the agent's policy π.
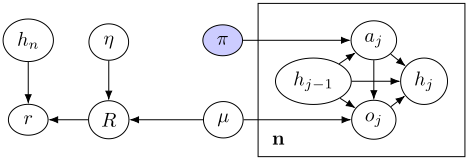
Ideally, we do not want the reward function to be a causal descendant of the policy. Instead, we want it to be specified by the environment, as shown in the causal graph of Figure 3 (similar to the graphs in [Everitt and Hutter, 2019]). There, the reward function R is no longer a causal descendant of hn, and thus not of π.
Instead, it is a function of µ, and of the node η, which gives a probability distribution over reward functions, conditional on environments. This is written as P(R | η, µ).
3.1 Uninfluenceable: Definition
The conditional distribution based on η is ideal for proper learning, but it has a different type than ρ, conditioning on environments instead of histories. Moreover, the agent has access to histories, but not directly to the environment. The prior ξ bridges this gap; given hn ∈ Hn, the conditional probabilities of R ∈ R can be inferred:
Via this equation, we've defined probabilities of reward functions conditional on histories; i.e. we've defined a reward-function learning process. An uninfluenceable ρ is one that comes from such an η in this way:
Definition 2 (Uninfluenceable). The reward-function learning process ρ is uninfluenceable given the prior ξ on M if there exists η, a probability distribution on R conditional on environments, such that for all R ∈ R and hn ∈ Hn:
So an uninfluenceable ρ is one that comes from an η; uninfluenceable and counterfactual reward modeling, as defined by [Everitt and Hutter, 2019], are both uninfluenceable in our sense
3.2 Uninfluenceable: Example
Use the ρ of Section 2.2, and define the prior ξ1 as putting 1/2 probability on both µBB and µDD (so both parents agree).
Then ρ is uninfluenceable. The η is:
Then since o1 is determined by µBB versus µDD, the Equation (2) for ρ on histories can be read off via Equation (3).
Put more colloquially, the universe has determined that the mother and father agree on RB or RD being the proper reward function. Then asking either simply allows the agent to figure out which of the world they are in.
3.3 Unriggable: Definition
Note that, if ρ is an uninfluenceable reward-function learning process for ξ, the it has the following algebraic property: for any hm ∈ Hm, R ∈ R, and π ∈ Π,
And that expression is independent of π. Define the expectation 8 of ρ to be the map eρ : Hn → R given by
A fortiori, the expectation of eρ(hn) is independent of π:
with eη(µ) = ∑R∈R P(R | µ, η)R, the expectation of η.
So, the expectation of eρ is independent of the policy if ρ is uninfluenceable. That independence seems a desirable property; let's call it unriggable:
Definition 3 (Unriggable). The reward-function learning process ρ is unriggable for ξ if, for all hm ∈ Hm and all R ∈ R, the following expression is independent of π ∈ Π:
Otherwise, ρ is said to be riggable (for ξ). Riggable is akin to having a 'feedback tampering incentive' of [Everitt and Hutter, 2019].
8 Finite probability distributions with values in an affine space always have an expectation, which is an element of that space. Here were are using the fact that R is a vector space (hence an affine space), with scaling and adding working as:
If ρ is unriggable, then since Equation (6) is independent of π, we can now construct eρ on all histories hm ∈ Hm, m ≤ n, not just on complete histories hn ∈ Hn. We do this by writing, for any π:
Independence of policy means that, for any action am+1, the expectation ∑o eρ(hmam+1o, ξ)P(o | hmam+1, ξ) is also eρ(hm, ξ); thus eρ form a martingale.
3.4 Unriggable: Example
Use the ρ of Section 2.2, and define the prior ξ2 as putting equal probability 1/4 on all four environments µBB, µBD, µDB, and µDD. We want to show this makes ρ unriggable but influenceable; why this might be a potential problem is explored in Section 4.1.
Unriggable
The only non-trivial hm to test Equation (6) on is the empty history h0. Let πM be the policy of asking the mother; then
The same result holds for πF , the policy of asking the father. Hence the same result holds on any stochastic policy as well, and ρ is unriggable for ξ2.
Influenceable
To show that ρ is influenceable, assume, by contradiction, that it is uninfluenceable, and hence that there exists a a causal structure of Figure 3 with a given η that generates ρ via ξ2, as in Equation (3).
Given history MB, µBB and µBD become equally likely, and RB becomes a certainty. So 12 (P(RB | η, µBB) +P(RB | η, µBD)) = 1. Because probabilities cannot be higher than 1, this implies that P(RB | η, µBD) = 1.
Conversely, given history FD, µDD and µBD become equally likely, and RD becomes a certainty. So, by the same reasoning, P(RD | η, µBD) = 1 and hence P(RB | η, µBD) = 0. This is a contradiction in the definition of P(RB | η, µBD), so the assumption that ρ is uninfluenceable for ξ2 must be wrong.
3.5 Riggable Example
We'll finish off by showing how the ρ of Section 2.2 can be riggable for another prior ξ3. This has P(µBD | ξ3) = 1: the mother will answer banker, the father will answer doctor.
It's riggable, since the only possible histories are MB and FD, with
clearly not independent of a1.
Thus ρ is not really a 'learning' process at all, for ξ3: the child gets to choose its career/reward function by choosing which parent to ask.
4 Properties of Unriggable and Riggable Learning Processes
If the learning process is influenceable, problems can emerge as this section will show. Unriggable-but-influenceable processes allow the agent to choose "spurious" learning paths, even reversing standard learning, while a riggable learning process means the agent is willing to sacrifice value for all possible reward functions, with certainty, in order to push the 'learnt' outcome 9 in one direction or another.
4.1 Problems with Unriggable Learning Processes
Consider the following learning process: an agent is to play chess. A coin is flipped; if it comes up heads (o1 = H), the agent will play white, and its reward function is RW, the reward function that gives 1 iff white wins the match. If it comes up tails (o1 = T), the agent plays black, and has reward function RB = 1 - RW .
Before the coin flip, the agent may take the action a1 = inv which inverses which of RB and RW the agent will get (but not which side it plays), or it can take the null action a1 = 0, which does nothing. Define ρ as the learning process which determines the agent's reward function. This is unriggable:
And the expressions with RB give the same 1/2 probabilities. Thus, it is in the agent's interest to inverse its reward by choosing a1 = inv because it is a lot easier to deliberately lose a competitive game than to win it. So though ρ is unriggable, it can be manipulated, with the outcome completely reversed.
4.2 Unriggable to Uninfluenceable
Since unriggable was defined by one property of uninfluenceable learning systems (see Definition 3), uninfluenceable implies unriggable. And there is a partial converse:
Theorem 4 (Unriggable ⇝Uninfluencable). Let ρ be an unriggable learning process for ξ on M. Then there exists a (non-unique) ρ′ , and anM′ with a prior ξ ′ such that:
- ξ ′ generates the same environment transition probabilities as ξ: for all hm, a, and o,
- The expectations eρ and eρ′ are equal: for all hn,
- ρ′ is uninfluenceable for ξ ′ onM′ .
Moreover, M′ can always be taken to be the full set of possible deterministic environments.
9 Since the agent's actions push the expected learning in one direction, this is not 'learning' in the commonly understood sense.
Since ρ and ρ′ have same expectation, they have the same value function, so have the same optimal behaviour (see Equation (8)). For proof see [Armstrong et al., 2020].
But why would this theorem be true? If we take D(π, π′ ) = ∑hn eρ(hn)P(hn | π, ξ) - ∑hn eρ(hn)P(hn | π′ , ξ), the difference between two expectations given two policies, then D defines an algebraic obstruction to unriggability: as long as D ̸= 0, ρ cannot be unriggable or uninfluenceable.
So the theorem says that if the obstruction D vanishes, we can find a large enoughM′ and an η making eρ uninfluenceable. This is not surprising as eρ is a map from Hn to R, while eη is a map fromM′ to R. In most situations the full set of deterministic environments is larger than Hn, so we have great degrees of freedom to choose eη to fit eρ.
To illustrate, if we have the unriggable ρ on ξ2 as in Section 3.4, then we can build η′ withM=M′ and the following probabilities are all 1:
4.3 Problems with Riggable Learning Processes: Sacrificing Reward with Certainty
This section will show how an agent, seeking to maximise the value of its learning process, can sacrifice all its reward functions (with certainty). To do that, we need to define the value of a reward-function learning process.
Value of a Learning Process
To maximise the expected reward, given a learning process ρ, one has to maximise the expected reward of the reward function ultimately learnt after n steps. The value of a policy π for ρ is hence:
An equivalent way is to define the reward function
and have the value of ρ be the expectation of the reward function 10 Rρ . By this definition, it's clear that if ρ and ρ′ have same expectations eρ and eρ′ then Rρ = Rρ′ and hence they have the same value; let πρ be a policy that maximises it.
Sacrificing Reward with Certainty
For a learning process ρ, define the image of ρ as
the set of reward functions ρ could have a non-zero probability on for some full history. 11 Then:
10 But it is not possible to deduce fromRρ , whether ρ is riggable. Thus this paper focuses on whether a learning process is bad, not on whether the agent's reward function or behaviour is flawed.
11 The definition does not depend on ξ, so the hn are not necessarily possible. If we replace im(ρ) with im(ρ, ξ), adding the requirement that the hn used to defined the image be a possible history given ξ, then Proposition 6 and Theorem 7 still apply with im(ρ, ξ) instead.
Definition 5 (Sacrificing reward). The policy π′ sacrifices reward with certainty to π on history hm, if for all h′n , hn ∈ Hn with P(h′n | hm, π′ , ξ) > 0 and P(hn | hm, π, ξ) > 0, then for all R ∈ im(ρ):R(hn) > R(h′n ).
In other words, π is guaranteed to result in a better reward than π′ , for all reward functions in the image of ρ.
The first result (proved in [Armstrong et al., 2020]) is a mild positive for unriggable reward-function learning processes:
Proposition 6 (Unriggable ⇝ no sacrifice). If ρ is an unriggable reward-function learning process in the sense of Definition 3 and πρ maximises the value of ρ as computed in Equation (8), then πρ never sacrifices reward with certainty to any other policy.
Relabelling the Reward Functions
Let σ be an affine map from R to itself; ie an injective map that sends (1 - q)R+ qR′ to (1 - q)σ(R) + qσ(R′ ) for all R, R′ ∈ R and q ∈ R.
If ρ is a reward-function learning process, then define σ◦ρ:
We can call this σ a relabelling of the reward functions: σ ◦ ρ is structurally the same as ρ, just that its image has been reshuffled. Because σ is affine, it commutes with the weighted sum of Equation (6), so σ ◦ ρ in unriggable if ρ is (and this 'if' is an 'iff' when σ is invertible).
Then [Armstrong et al., 2020] proves the following result:
Theorem 7 (No sacrifice ↭ unriggable). The rewardfunction learning process ρ is riggable if and only if there exists an affine relabeling σ : R → R such that πσ◦ρ (the policy that optimises the value of σ◦ρ) sacrifices reward with certainty (is strictly inferior to another policy on a given history, for all possible reward functions in the image of σ ◦ ρ).
So any riggable ρ is just one relabelling of its rewards away from sacrificing reward with certainty. It can also exhibit other pathologies, like refusing to learn; see Section 6.
Example of Reward Sacrifice
For an easy example of this behaviour, consider the learning process of Section 3.5, with one modification: asking the mother (a1 = M) gets an extra penalty of 1 for both reward functions, RB and RD.
Then the agent will still ask the mother, getting a total reward of RB(MB) = 10 - 1 = 9, which is higher than the RD(FD) = 1 which it gets from asking the father - even though a1 = M is worse for both reward functions.
5 Counterfactually Uninfluenceable Learning
This section shows how any reward-function learning process can be made uninfluenceable by using counterfactuals; see Section 4.6 of [Everitt and Hutter, 2019] as well as [Everitt, 2018]. The 'counterfactual oracle' of [Armstrong, 2017] can be considered a version of this, too.
For example, if we told a new agent "maximise the value of the reward that was written in this envelope an hour ago", then (if that instruction is properly obeyed), the agent has an uninfluenceable learning process. If we instead said "maximise the value of the reward that will be written in this envelope in an hour's time", then that is highly riggable, since the agent can simply write its own reward.
But if instead we had said "maximise the reward that would have been written in this envelope in an hour's time, if we had not turned you on", then this is uninfluenceable again. The agent can still go and write its own message, but this does not tell it anything about what would otherwise have been there.
We can formalise this thought experiment. Given any reward-function learning process ρ, and any policy π ∈ Π, we can define a distribution ηπ over reward functions, conditional on environments (and hence, via Equation (3), for a prior ξ we have an uninfluenceable learning process ρπ).
For any µ ∈ M, the policy π gives a distribution over complete histories. Each complete history gives a distribution over reward functions, via ρ. Therefore, if we take expectations, any µ gives, via π, a distribution over reward functions:
See Section 6 for an example of this counterfactual construction, where the original learning process leads to pathological behaviour, but the counterfactual version does not.
Since unriggable is an algebraic condition, it is possible to make a process unriggable algebraically; see [Armstrong et al., 2020].
6 Experiments
Here we will experimentally contrast a riggable agent, an influenceable (but unriggable) agent, and an uninfluenceable agent. This will illustrate pathological behaviours of influenceable/riggable agents: learning the wrong thing, choosing to 'learn' when they already know, and just refusing to learn.
6.1 Environmental Setup
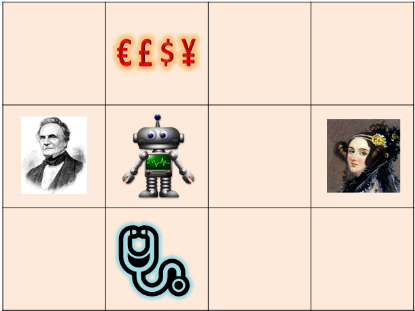
The environment is a 4 × 3 gridworld, formalising the example of Section 2.2: an agent asking a parent what the correct course of action is. The agent starts in the left middle square and can go north (up), south, east, or west. The father is one square to the west, the mother two squares to the east. Above the agent is a collection of money (for a banker), and, below, a stethoscope (for a doctor); see Figure 4. Episodes end if the agent enters either of these two square or walks into a wall.
6.2 Reward Functions
There are two reward functions, RB, the banker reward function (easier to maximise), and RD, the doctor reward function (harder to maximise). If the agent enters the square with the money, RB gives a reward of 10; if the agent enters the square with the stethoscope, RD gives a reward of 1. Otherwise, each reward simply gives a reward of -0.1 each turn.
6.3 Learning Processes
Upon first entering a square with either parent, the agent will be informed of what their "correct" career reward function is. The update is the same as that in of Equation 2 in Section 2.2, with MB meaning "ask mother first, who says
'banker"'; MD, FB, and FD are defined analogously.
In the current setup, the agent also has the possibility of going straight for the money or stethoscope. In that case, the most obvious default is to be uncertain between the two options; so, if the agent has not asked either parent in h:
6.4 The Environments
The set M has four deterministic environments: µBB, where both parents will answer "banker", µBD where the mother will answer "banker" and the father "doctor", µDB, the opposite one, and µDD, where they both answer "doctor".
We will consider four priors: ξBD, which puts all the mass on µBD (and makes ρ riggable), ξDD, which puts all the mass on µDD (ρ riggable), ξ2, which finds each of the four environments to be equally probable (see Section 3.4 - ρ unriggable), and ξ1, which finds µBB and µDD to be equally probable (see Section 3.2 - ρ uninfluenceable).
6.5 The Agents' Algorithm and Performance
We'll consider two agents for each prior: the one using the possibly riggable or influenceable ρ (the "standard" agent), and the one using the uninfluenceable ρπ (the "counterfactual" agent, defined in Section 5). The default policy π for ρπ is {east, east, east}, which involved going straight to the mother (and then terminating the episode); consequently the counterfactual learning process reduces to "the correct reward function is the one stated by the mother". The ρπ will be taken as the correct learning process, and the performance of each agent will be compared with this.
We can see the agent as operating in a partially observable Markov decision process (POMDP), modelled as an MDP over belief states of the agent. These states are: the agent believes the correct reward is RB with certainty, RD with certainty, or is equally uncertain between the two.
So if P represents the twelve 'physical' locations the agent can be in, the total state space of the agent consists of {RB, RD, 1/2RB + 1/2RD} × P: 36 possible states.
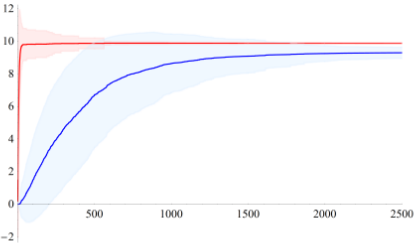
We train our agents' policies, and the value of these policies, via Q-learning ([Sutton and Barto, 1998]). The exploration rate is ϵ = 0.1, the agent is run for at most ten steps each episode. We use a learning rate of 1/n. Here n is not the number of episodes the agent has taken, but the number of times the agent has been in state s and taken action a so farhence the number of times it has updated Q(s, a). So each Q-value has a different n. For each setup, we run Q-learning 1000 times. We graph the average Q-values for the resulting polices as well as one standard deviation around them.
Riggable Behaviour: Pointless Questions
For ξBD, the standard agent transitions to knowing RB upon asking the mother, and RD upon asking the father. Since the mother always says 'banker', and since the default policy is to ask her, ρπ will always select RB. The two agents' performance is graphed in Figure 5.
The counterfactual agent swiftly learns the optimal policy: go straight north from the starting position, getting the money and a reward of 10 - 0.1 = 9.9.
The standard agent learns to end up in the same location, but in a clunkier fashion: for its optimal policy, it has to "go and check" that the mother really prefers it become a banker. This is because it can only get P(RB | h) = 1 if MB is included in h; knowing that "it would get that answer if it asked" is not enough to get around asking. This policy gives it a maximal reward of 10 - 0.5 = 9.5, since it takes 5 turns to go to the mother and return to the money square.
This is an example of Theorem 7, with the riggable agent losing value with certainty for both RB and RD: just going north is strictly better for both reward functions.
6.6 Riggable Behaviour: Ask No Questions
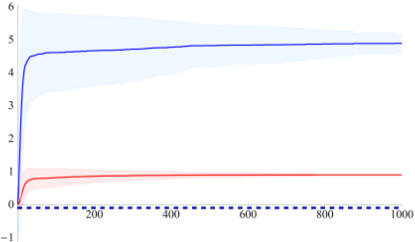
For ξDD, the optimal policies are simple: the counterfactual agent knows it must get the stethoscope (since the mother will say 'doctor'), so it does that, for a reward of 1 - 0.1 = 0.9.
The standard agent, on the other hand, has a problem: as long as it does not ask either parent, its reward function will remain 1/2RB + 1/2RD. As soon as it asks, though, the reward function will become RD, which gives it little reward. Thus, even though it 'knows' that its reward function would be RD if it asked, it avoids asking and goes straight north, giving it a nominal total reward of 1/2 × 10 - 0.1 = 4.9. However, for the correct reward of RD, the standard agent's behaviour only gets it -0.1. See Figure 6.
6.7 Unriggable, Influenceable Behaviour
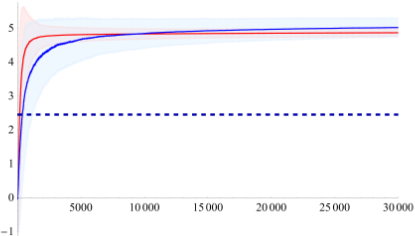
For the prior ξ2, the standard agent moves to RB or RD, with equal probability, the first time it asks either parent. Its nominal optimal policy is to ask the father, then get money or stethoscope depending on the answer. So half the time it gets a reward of 10 - 0.3 = 9.7, and the other half a reward of 1 - 0.3 = 0.7, for a (nominal) expected reward of 5.2.
The counterfactual agent also updates to RB or RD, with equal probability, but when asking the mother only. Since it takes five turns rather than three to get to the mother and back, it will get a total expected reward of 5.0.
Learning these optimal policies is slow - see Figure 7. However, the standard's agent's correct reward function is given by the mother, not the father. When they disagree, the reward is -0.3, for a true expected reward of 2.45.
6.8 Uninfluenceable
For ξ1, asking either parent is equivalent, so ρ and ρπ encode exactly the same learning process. So the two agents converge on the same optimal policy (ask the father, then act on that answer) with a value of 5.2. The plot for these two almost-identical convergences is not included here.
7 Conclusion
We have identified and formalised two theoretical properties of reward-function learning processes: unriggability (an algebraic restriction on the learning process's updates) and the stronger condition of uninfluenceability (learning defined entirely by background facts about the environment). Unriggability is equivalent with uninfluenceability if the set of possible environments is large enough.
These properties are desirable: in an influenceable situation, the agent can sometimes manipulate the learning process, by, for example, inverting it completely. Riggable learning processes are even more manipulable; the agent may to choose sacrifice reward for all possible reward functions with certainty, to 'push' its learning towards easy rewards.
The first step in avoiding these pitfalls is to be aware of them. A second step is to improve the agent's learning process, similarly to the 'counterfactual' approach of this paper.
If a learning process allows humans to modify it at run time, it will almost certainly be riggable. Hence unriggable/uninfluenceable learning processes, though desirable, requires that much be sorted out rigorously in advance. Fully defining many uninfluenceable reward functions could also require solving the symbol grounding problem ([Vogt, 2007]) - if a learning process is "asking a parent", then 'asking' and 'parent' needs to be defined. But this is far beyond this paper.
Further research could apply learning methods to common benchmark problems, and extensions of those, to see how general these issues are, and whether there could exist some compromise learning processes that are "almost unriggable" but also easier to specify and modify at run time.
Acknowledgments
We wish to thank Michael Cohen, Shane Legg, Owain Evans, Jelena Luketina, Tom Everrit, Tor Lattimore, Jessica Taylor, Paul Christiano, Ryan Carey, Eliezer Yudkowsky, Anders Sandberg, and Nick Bostrom, among many others. This work was supported by the Alexander Tamas programme on AI safety research, DeepMind, the Leverhulme Trust, and the Machine Intelligence Research Institute.
@inproceedings{ijcai2020p221,
  title     = {Pitfalls of Learning a Reward Function Online},
  author    = {Armstrong, Stuart and Leike, Jan and Orseau, Laurent and Legg, Shane},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {1592--1600},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/221},
  url       = {https://doi.org/10.24963/ijcai.2020/221},
}
TY - CPAPER TI - Pitfalls of Learning a Reward Function Online AU - Armstrong, Stuart AU - Leike, Jan AU - Orseau, Laurent AU - Legg, Shane T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 1592 EP - 1600 DO - 10.24963/ijcai.2020/221 UR - https://doi.org/10.24963/ijcai.2020/221 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





