
On Overfitting and Asymptotic Bias in Batch Reinforcement Learning with Partial Observability (Extended Abstract)
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Journal track. Pages 5055-5059.
https://doi.org/10.24963/ijcai.2020/706
Keywords
- Knowledge Representation and Reasoning: Reasoning about Knowledge and Belief
- Machine Learning: Reinforcement Learning
- Planning and Scheduling: POMDPs
- Machine Learning: Learning Theory
Abstract
When an agent has limited information on its environment, the suboptimality of an RL algorithm can be decomposed into the sum of two terms: a term related to an asymptotic bias (suboptimality with unlimited data) and a term due to overfitting (additional suboptimality due to limited data). In the context of reinforcement learning with partial observability, this paper provides an analysis of the tradeoff between these two error sources. In particular, our theoretical analysis formally characterizes how a smaller state representation increases the asymptotic bias while decreasing the risk of overfitting.
- [Abel et al., 2016] David Abel, David Hershkowitz, and Michael Littman. Near optimal behavior via approxi- mate state abstraction. In Proceedings of The 33rd Inter- national Conference on Machine Learning, pages 2915- 2923, 2016.
- [Aberdeen et al., 2007] Douglas Aberdeen, Olivier Buffet, and Owen Thomas. Policy-gradients for PSRs and POMDPs. In Artificial Intelligence and Statistics, pages 3-10, 2007.
- [Cassandra et al., 1994] Anthony R Cassandra, Leslie Pack Kaelbling, and Michael L Littman. Acting optimally in partially observable stochastic domains. In Proceedings of the Twelfth AAAI National Conference on Artificial Intel- ligence, volume 94, pages 1023-1028, 1994.
- [Farahmand, 2011] Amir-massoud Farahmand. Regulariza- tion in reinforcement learning. PhD thesis, University of Alberta, 2011.
- [Ferns et al., 2004] Norm Ferns, Prakash Panangaden, and Doina Precup. Metrics for finite Markov decision pro- cesses. In Proceedings of the 20th conference on Un- certainty in artificial intelligence, pages 162-169. AUAI Press, 2004.
- [Franc ¸ois-Lavet et al., 2019] Vincent Franc ¸ois-Lavet, Guil- laume Rabusseau, Joelle Pineau, Damien Ernst, and Raphael Fonteneau. On overfitting and asymptotic bias in batch reinforcement learning with partial observability. Journal of Artificial Intelligence Research, 65:1-30, 2019.
- [Ghavamzadeh et al., 2015] Mohammad Ghavamzadeh, Shie Mannor, Joelle Pineau, and Aviv Tamar. Bayesian reinforcement learning: a survey. Foundations and Trends® in Machine Learning, 8(5-6):359-483, 2015.
- [Hutter, 2014] Marcus Hutter. Extreme state aggregation be- yond mdps. In International Conference on Algorithmic Learning Theory, pages 185-199. Springer, 2014.
- [Jiang et al., 2015] Nan Jiang, Alex Kulesza, and Satinder Singh. Abstraction selection in model-based reinforce- ment learning. In Proceedings of the 32nd International Conference on Machine Learning (ICML-15), pages 179- 188, 2015.
- [Kaelbling et al., 1998] Leslie Pack Kaelbling, Michael L Littman, and Anthony R Cassandra. Planning and acting in partially observable stochastic domains. Artificial intel- ligence, 101(1):99-134, 1998.
- [Lange et al., 2012] Sascha Lange, Thomas Gabel, and Mar- tin Riedmiller. Batch reinforcement learning. In Rein- forcement learning, pages 45-73. Springer, 2012.
- [Littman and Sutton, 2002] Michael L Littman and Richard S Sutton. Predictive representations of state. In Advances in neural information processing systems, pages 1555-1561, 2002.
- [McCallum, 1996] Andrew Kachites McCallum. Reinforce- ment learning with selective perception and hidden state. PhD thesis, University of Rochester, 1996.
- [Pineau et al., 2003] Joelle Pineau, Geoff Gordon, and Se- bastian Thrun. Point-based value iteration: An anytime al- gorithm for POMDPs. In Proceedings of the 18th interna- tional joint conference on Artificial intelligence, volume 3, pages 1025-1032, 2003.
- [Ross et al., 2011] Stéphane Ross, Joelle Pineau, Brahim Chaib-draa, and Pierre Kreitmann. A Bayesian approach for learning and planning in partially observable Markov decision processes. The Journal of Machine Learning Re- search, 12:1729-1770, 2011.
- [Singh et al., 2004] Satinder Singh, Michael R James, and Matthew R Rudary. Predictive state representations: A new theory for modeling dynamical systems. In Proceed- ings of the 20th conference on Uncertainty in artificial in- telligence, pages 512-519. AUAI Press, 2004.
- [Sondik, 1978] Edward J Sondik. The optimal control of par- tially observable Markov processes over the infinite hori- zon: Discounted costs. Operations research, 26(2):282- 304, 1978.
- [Sutton and Barto, 1998] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction, vol- ume 1. MIT press Cambridge, 1998.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Formalization
When acquisition of new observations is possible (the "online" case), data scarcity is gradually phased out using strategies balancing the exploration / exploitation (E/E) tradeoff. The scientific literature related to this topic is vast; in particular, Bayesian RL techniques [Ross et al., 2011; Ghavamzadeh et al., 2015] offer an elegant way of formalizing the E/E tradeoff.
However, such E/E strategies are not applicable when the acquisition of new observations is not possible anymore. In the pure "batch" setting (also called the "offline" setting), the task is to learn the best possible policy from a fixed set of transition samples [Farahmand, 2011; Lange et al., 2012].
We consider a discrete-time POMDP [Sondik, 1978] model M described by the tuple (S, A, T, R, Ω, O, γ) where
- S is a finite set of states {1, . . . ,NS},
- A is a finite set of actions {1, . . . ,NA},
- T : S ×A×S → [0, 1] is the transition function,
- R : S ×A× S → R is the reward function, where R is a continuous set of possible rewards in a range Rmax ∈ R+,
- Ω is a finite set of observations {1, . . . ,NΩ},
* This paper is an extended abstract of an article in the Journal of AI Research [Franc¸ois-Lavet et al., 2019].
- γ ∈ [0, 1) is the discount factor.
The initial state is drawn from an initial distribution b(s0). In this paper, the conditional transition probabilities T, the reward function R and the conditional observation probabilities O are unknown. The only information available to the agent is the past experience it gathered while interacting with the POMDP.
1.1 Processing a History of Data
A history of previously observed features can be used to estimate the hidden state dynamics [McCallum, 1996; Littman and Sutton, 2002; Singh et al., 2004]. We denote by Ht = Ω × (A×R× Ω)t the set of histories observed up to time
observable histories.
In this paper, we consider a mapping φ : H → φ(H), where φ(H) = {φ(H)|H ∈ H} is of finite cardinality |φ(H)|. On the one hand, we will show that when φ discards information from the whole history, the state representation φ(H) that the agent uses to make decision might depart from sufficient statistics, which can hurt performance. On the other hand, we will show that it is beneficial to use a mapping φ that has a low cardinality |φ(H)| to avoid overfitting.
Let us first introduce a notion of information on the latent hidden state s through the notion of belief state [Cassandra et al., 1994].
Definition 1.1. The belief state b(s|H) is defined as the vector of probabilities where the ith component (i ∈ {1, . . . ,NS}) is given by P(s = i | H), for any history H ∈ H.
Definition 1.2. The belief state bφ (s|φ(H)) is defined as the vector of probabilities where the ith component (i ∈ {1, . . . ,NS}) is given by P(s = i | φ(H)), for any history H ∈ H 1 .
1 Note that s and H are random variables and their exact distribution will depend on the context that is considered. For any given probability distribution DH over histories: H ∼ DH, the probability P(s|φ(H)) is the expectation of the state when φ(H) is observed: bφ(s | ϕ) = E H∼DH,ϕ=φ(H)b(s | H).
Among all possible mappings φ, the notion of sufficient statistics [Kaelbling et al., 1998; Aberdeen et al., 2007] corresponds to the ones that extract enough information from the history to accurately capture the corresponding belief state.
Definition 1.3. In a POMDP M, a statistic φ(H) is a sufficient statistic at the condition that ∀s ∈ S:
for H ∈ H. A mapping φ which provides sufficient statistics for all histories H ∈ H is called a sufficient mapping and is denoted as φ0.
One of the key notions on which our analysis relies is the one of "approximately sufficient mappings", i.e. mappings whose corresponding belief state lies in an L1-ball of radius ϵ centered on b(·|H):
Definition 1.4. In a POMDP M, a statistic φ(H) is an ϵsufficient statistic at the condition that it meets the following condition with ϵ ≥ 0 and with the L1 norm:
for H ∈ H. A mapping φ that provides ϵ-sufficient statistics for all histories H ∈ H is called an ϵ-sufficient mapping and is denoted as φϵ(H).
1.2 Working with a Limited Dataset
Let M(S,A,Ω, γ) be a set of POMDPs with fixed S, A, Ω, and γ. For any POMDP M(T,R,O) ∈ M, we denote by DM,πs,Ntr,Nl a random dataset generated according to a probability distribution DM,πs,Ntr,Nl over the set of Ntr trajectories of length Nl. One such trajectory is defined as the observable history HNl ∈ HNl obtained in M when starting from s0 and following a stochastic sampling policy πs that ensures a non-zero probability of taking any action given an observable history H ∈ H. For simplicity we denote DM,πs,Ntr,Nl , simply as D ∼ DM. For the purpose of the analysis, we also introduce the asymptotic dataset D∞ = DM,πs,Ntr→∞,Nl→∞ that would be theoretically obtained in the case where one could generate an infinite number of observations (Ntr → ∞ and Nl → ∞).
1.3 Assessing the Performance of a Policy
Let us consider stationary and deterministic control policies π : φ(H) → A with π ∈ Π. Any particular choice of φ induces a particular definition of the policy space Π. We introduce V πM (φ(H)) with H ∈ H as the expected return obtained over an infinite time horizon when the system is controlled using policy π in the POMDP M. For any given distribution DH over histories, this is defined as:
with V πM (H | φ) given by
We also define π∗ as an optimal policy in M:
where H0 is taken out of the distribution of initial observations (compatible with the distribution b(s0) of initial states through the conditional observation probabilities).
2 Bias-overfitting in RL with Partial Observability
In this section, we study the performance gap between the expected return that can be obtained following the policy built from limited data and the highest possible expected return that we would obtain if the algorithm had access to the POMDP parameters.
To study the importance of the feature space, let us assume that the policies built from limited data are optimal according to frequentist statistics, which allows removing from the analysis how the RL algorithm converges. In order to define the optimal policy according to frequentist statistics, let us first introduce a frequentist-based (augmented) MDP from the dataset D:
Definition 2.1. With M defined by (S, A, T, R, Ω, O, γ) and the dataset D built from interactions with M, the frequentistbased augmented MDP ˆMD,φ, also denoted for simplicity ˆMD = (Σ,A, ˆ T, ˆR, Γ), is defined with
- the state space: Σ = φ(H),
- the action space: A = A,
- the estimated transition function: for σ, σ′ ∈ Σ and a ∈ A, ˆ T (σ, a, σ′ ) is the number of times we observe the transition (σ, a) → σ′ divided by the number of times we observe (σ, a) 2
- the estimated reward function: for σ, σ′ ∈ Σ and a ∈ A, ˆR(σ, a, σ′ ) is the mean of the rewards observed for the tuple (σ, a, σ′ ) 3
- the discount factor Γ ≤ γ.
We introduce V πˆMD (σ) with σ ∈ Σ as the expected return obtained over an infinite time horizon when the system is controlled using a policy π : Σ → A in the augmented decision process ˆMD:
where ˆ rt is the reward s.t. ˆ rt = ˆR(σt, at, σt+1) and the transition is defined by P(σt+1|σt, at) = ˆ T (σt, at, σt+1).
A policy π is defined to be better than or equal to a policy π′ if its expected return is greater than or equal to that of π′ for all states. In an MDP, there is always at least one policy that is better than or equal to all other policies and this is an optimal policy [Sutton and Barto, 1998]. In the augmented MDP ˆMD, we denote the optimal policy as πD,φ and we also call it the frequentist-based policy. Let us now decompose the error of using a frequentist-based policy πD,φ in the actual POMDP:
2 if any (σ, a) has never been encountered in a dataset, we arbitrarily set ˆ T (σ, a, σ′ ) = 1/|Σ|, ∀σ′ .
3 if any (σ, a, σ′ ) has never been encountered in a dataset, we arbitrarily set ˆR(σ, a, σ′ ) to the average of rewards observed over the whole dataset D.
The term bias actually refers to an asymptotic bias when the size of the dataset tends to infinity, while the term overfitting refers to the expected suboptimality due to the finite size of the dataset (and thus due to the variance in the estimated transition function and reward function).
We start by providing a bound on the bias, which is an original result based on the belief states via the ϵ-sufficient statistic.
Theorem 1. "Bound on the bias": Let M be a POMDP described by the 7-tuple (S,A, T,R,Ω,O, γ). Let ˆMD∞ be an augmented MDP (Σ,A, ˆ T, ˆR, Γ = γ) estimated, according to Definition 2.1, from a dataset D∞. Then, for any ϵ-sufficient mapping φ = φϵ, the asymptotic bias can be bounded as follows:
Proof. We consider the frequentist-based MDP ˆMD∞,φ0 (Σ0,A, ˆ T, ˆR, Γ = γ), for H ∈ H and a ∈ A, let us defineQπD∞,φ0
where the reward
Then the main part of the proof is to demonstrate Proposition 2 below. From there, by applying Lemma 1 by Abel et al. 2016, we have:
By further noticing that, when starting in s0, ˆMD∞,φ0 andM provide an identical value function for a given policy πD,φ and that πD∞,φ0 ∼ π∗ , i.e. V π∗ M = V πD∞,φ0 M , the theorem follows.
Remark. As compared to Hutter 2014 and Abel et al. 2016, this bound relates directly to the capacity of the mapping φ(H) to retrieve sufficient information on the latent hidden state. As compared to PBVI [Pineau et al., 2003] and similar approaches, we do not make the assumption that T , R and O are known and, as such, they need to be estimated from data.
We now provide Proposition 2, which is the key result required in the proof of Theorem 1.
Proposition 2. Let φϵ be an ϵ-sufficient mapping, and let φ0 be a sufficient mapping. Then, for any H(1) ,H(2) such that φϵ(H(1) ) = φϵ(H(2) ), we have
Proof. For this proposition, we rely on the fact that since φϵ(H(1) ) = φϵ(H(2) ), we are able to bound the L1 error terms of the associated belief states of H(1) and H(2) . From that bound, we then present two different ways of independent interest to prove Proposition 2. The first proof makes use of a tree of possible future observations, rewards and corresponding actions given a policy π, and we show that when starting fromH(1) ,H(2) such that φϵ(H(1) ) = φϵ(H(2) ), the bound holds. We also provide an alternative proof that makes use of the formalism of the bisimulation metric [Ferns et al., 2004] along with the data processing inequality. The details of the proofs are given in the full paper.
We now provide a bound on the overfitting error that monotonically grows with |φ(H)|. Theorem 3 shows that using a large set of features potentially leads to a stronger drop in performance when the available dataset D is limited (the bound decreases proportionally to 1 √n ). A theoretical analysis in the context of MDPs with a finite dataset was performed by Jiang et al. 2015.
Theorem 3. "Bound on the overfitting": Let M be a POMDP described by the 7-tuple (S,A, T,R,Ω,O, γ). Let ˆMD be an augmented MDP (Σ,A, ˆ T, ˆR, Γ = γ) estimated, according to Definition 2.1, from a dataset D with the assumption that D has n transitions from any possible pair (φ(H), a) ∈ φ(H) × A (sampled i.i.d according to DM). Then the overfitting due to using the frequentist-based policy πD,φ instead of πD∞,φ in the POMDP M can be bounded as follows:max
with probability at least 1 - δ.
Proof. The proof of Theorem 3 is deferred to the full paper.
Overall, Theorems 1 and 3 can help choose a good state representation for POMDPs as they provide bounds on the two terms that appear in the bias-overfitting decomposition of Equation 1. An additional feature in the mapping φ has an overall positive effect only if the increase of information on the belief state prevails over the additional risk of overfitting.
3 Experiments
This section provides empirical illustrations of the theoretical results on a distribution of synthetic POMDPs. Experiments on a POMDP with real-world data are available in the full paper.
3.1 Protocol
We randomly sample NP POMDPs such that NS = 5, NA = 2 and NΩ = 5 (except when stated otherwise) from a distribution P that we refer to as Random POMDP. Random transition functions T(·, ·, ·) are drawn by assigning, for each entry (s, a, s′ ), a zero value with probability 3/4, and, with probability 1/4, a non-zero entry with a value drawn uniformly in [0, 1]. For all (s, a), if all T(s, a, s′ ) are zeros, we enforce one non-zero value for a random s′ ∈ S. Values are normalized. Random reward functions are generated by associating to all possible (s, a, s′ ) a reward sampled uniformly and independently from [-1, 1]. Random conditional observation probabilities O(·, ·) are generated in the following way: the probability of observing o(i) when in state s(i) is equal to 0.5, while all other values are chosen uniformly randomly so that it is normalized for any s. For all POMDPs, we have γ = 1 and Γ = 0.95 if not stated otherwise and we truncate the trajectories to a length of Nl = 100 time steps.
For each generated POMDP P ∼ P, we generate 20 datasets D ∈ DP where DP is a probability distribution over all possible sets of n trajectories (n ∈ [2, 5000]); where each trajectory is made up of a history H100 of 100 time steps, when starting from an initial state s0 ∈ S and taking uniform random decisions. Each dataset D induces a policy πD,φ, and we want to evaluate the expected return of this policy while discarding the variance related to the stochasticity of the transitions, observations and rewards. To do so, policies are tested with 1000 rollouts of the policy. For each POMDP P , we are then able to get an estimate of the average score µP which is defined as:
We are also able to get an estimate of a parametric variance σ2P defined as:
3.2 History Processing
We show experimentally that any additional feature from the history Ht is likely to reduce the asymptotic bias, but may also increase the overfitting. For any history length h, we consider the mapping φh that extracts the current observation and the last h- 1 (observation, action) tuples. In the experiments, we compare the policies πD,φh for h = 1, 2, 3.
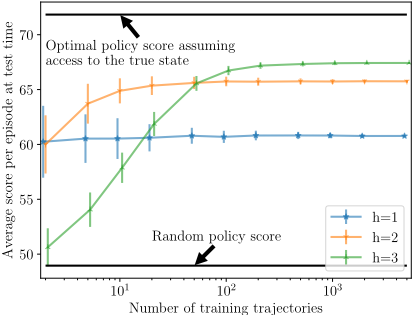
The values E P∼PµP and E P∼P σP are displayed in Figure 1. One can observe that a small set of features (small history) appears to be a better choice when the dataset is small (only a few trajectories). With an increasing number of trajectories, the optimal number of features increases.
In addition, one can also observe that the expected variance of the score decreases as the number of samples increases. As the variance decreases, the risk of overfitting also decreases, and it becomes possible to target a larger policy class (using a larger feature set).
4 Conclusion and FutureWorks
In the context of POMDPs, this paper discusses the biasoverfitting tradeoff of RL algorithms with limited available data (batch RL). We show that it may be preferable to concede an asymptotic bias in order to reduce overfitting. The main theoretical results of this extended abstract relate to the state representation, for which we introduce the notion of the ϵ-sufficient statistics and showed that it enables the formalization of the bias-overfitting trade-off.
Acknowledgments
We thank the anonymous reviewers for many helpful comments. The authors thank the Walloon Region (Belgium) that funded this research in the context of the BATWAL project. We also acknowledge financial support by the Natural Science and Engineering Research Council Canada (NSERC) and Samsung Electronics Co Ltd. Guillaume Rabusseau acknowledges support of an IVADO postdoctoral fellowship.
@inproceedings{ijcai2020p706,
  title     = {On Overfitting and Asymptotic Bias in Batch Reinforcement Learning with Partial Observability (Extended Abstract)},
  author    = {François-Lavet, Vincent and Rabusseau, Guillaume and Pineau, Joelle and Ernst, Damien and Fonteneau, Raphael},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {5055--5059},
  year      = {2020},
  month     = {7},
  note      = {Journal track},
  doi       = {10.24963/ijcai.2020/706},
  url       = {https://doi.org/10.24963/ijcai.2020/706},
}
TY - CPAPER TI - On Overfitting and Asymptotic Bias in Batch Reinforcement Learning with Partial Observability (Extended Abstract) AU - François-Lavet, Vincent AU - Rabusseau, Guillaume AU - Pineau, Joelle AU - Ernst, Damien AU - Fonteneau, Raphael T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 5055 EP - 5059 DO - 10.24963/ijcai.2020/706 UR - https://doi.org/10.24963/ijcai.2020/706 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





