
Convergence Analysis of Gradient Descent for Eigenvector Computation
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2933-2939.
https://doi.org/10.24963/ijcai.2018/407
Keywords
- Constraints and SAT: Constraint Optimisation
- Heuristic Search and Game Playing: Combinatorial Search and Optimisation
Abstract
We present a novel, simple and systematic convergence analysis of gradient descent for eigenvector computation. As a popular, practical, and provable approach to numerous machine learning problems, gradient descent has found successful applications to eigenvector computation as well. However, surprisingly, it lacks a thorough theoretical analysis for the underlying geodesically non-convex problem. In this work, the convergence of the gradient descent solver for the leading eigenvector computation is shown to be at a global rate O(min{ (lambda_1/Delta_p)^2 log(1/epsilon), 1/epsilon }), where Delta_p=lambda_p-lambda_p+1>0 represents the generalized positive eigengap and always exists without loss of generality with lambda_i being the i-th largest eigenvalue of the given real symmetric matrix and p being the multiplicity of lambda_1. The rate is linear at (lambda_1/Delta_p)^2 log(1/epsilon) if (lambda_1/Delta_p)^2=O(1), otherwise sub-linear at O(1/epsilon). We also show that the convergence only logarithmically instead of quadratically depends on the initial iterate. Particularly, this is the first time the linear convergence for the case that the conventionally considered eigengap Delta_1= lambda_1 - lambda_2=0 but the generalized eigengap Delta_p satisfies (lambda_1/Delta_p)^2=O(1), as well as the logarithmic dependence on the initial iterate are established for the gradient descent solver. We are also the first to leverage for analysis the log principal angle between the iterate and the space of globally optimal solutions. Theoretical properties are verified in experiments.
- [Absil et al., 2008] P-A Absil, Robert Mahony, and Rodolphe Sepulchre. Optimization algorithms on matrix manifolds. Princeton University Press, 2008.
- [Arora et al., 2012] Raman Arora, Andrew Cotter, Karen Livescu, and Nathan Srebro. Stochastic optimization for PCA and PLS. In 50th Annual Allerton Conference on Communication, Control, and Computing, Allerton, pages 861-868, 2012.
- [Arora et al., 2013] Raman Arora, Andrew Cotter, and Nati Srebro. Stochastic optimization of PCA with capped MSG. In NIPS, pages 1815-1823, 2013.
- [Balcan et al., 2016] Maria-Florina Balcan, Simon Shaolei Du, Yining Wang, and Adams Wei Yu. An improved gap- dependency analysis of the noisy power method. In COLT, pages 284-309, 2016.
- [Balsubramani et al., 2013] Akshay Balsubramani, Sanjoy Dasgupta, and Yoav Freund. The fast convergence of in- cremental pca. In NIPS, pages 3174-3182.
- [Bonnabel, 2013] Silvere Bonnabel. Stochastic gradient de- scent on riemannian manifolds. IEEE Trans. Automat. Contr., 58(9):2217-2229, 2013.
- [Edelman et al., 1999] Alan Edelman, Tomás A. Arias, and Steven T. Smith. The geometry of algorithms with or- thogonality constraints. SIAM J. Matrix Anal. Appl., 20(2):303-353, April 1999.
- [Fan et al., 2018] Jianqing Fan, Qiang Sun, Wen-Xin Zhou, and Ziwei Zhu. Principal component analysis for big data. arXiv preprint arXiv:1801.01602, 2018.
- [Garber et al., 2016] Dan Garber, Elad Hazan, Chi Jin, Sham M. Kakade, Cameron Musco, Praneeth Netrapalli, and Aaron Sidford. Faster eigenvector computation via shift-and-invert preconditioning. In ICML, pages 2626- 2634, 2016.
- [Golub and Van Loan, 1996] Gene H. Golub and Charles F. Van Loan. Matrix Computations (3rd Ed.). Johns Hopkins University Press, Baltimore, MD, USA, 1996.
- [Hardt and Price, 2014] Moritz Hardt and Eric Price. The noisy power method: A meta algorithm with applications. In NIPS, pages 2861-2869, 2014.
- [Liu et al., 2016] Huikang Liu, Weijie Wu, and Anthony Man-Cho So. Quadratic optimization with orthogonality constraints: Explicit lojasiewicz exponent and linear con- vergence of line-search methods. In ICML, pages 1158- 1167, 2016.
- [Musco and Musco, 2015] Cameron Musco and Christopher Musco. Randomized block krylov methods for stronger and faster approximate singular value decomposition. In NIPS, pages 1396-1404, 2015.
- [Ng et al., 2002] Andrew Y. Ng, Michael I. Jordan, and Yair Weiss. On spectral clustering: Analysis and an algorithm. In NIPS, pages 849-856. MIT Press, 2002.
- [Pitaval et al., 2015] Renaud-Alexandre Pitaval, Wei Dai, and Olav Tirkkonen. Convergence of gradient descent for low-rank matrix approximation. IEEE Trans. Information Theory, 61(8):4451-4457, 2015.
- [Rudelson and Vershynin, 2010] Mark Rudelson and Roman Vershynin. Non-asymptotic theory of random matrices: extreme singular values. arXiv preprint arXiv:1003.2990, 2010.
- [Sa et al., 2015] Christopher De Sa, Christopher Re, and Kunle Olukotun. Global convergence of stochastic gra- dient descent for some non-convex matrix problems. In ICML, pages 2332-2341, 2015.
- [Shamir, 2015] Ohad Shamir. A stochastic PCA and SVD algorithm with an exponential convergence rate. In ICML, pages 144-152, 2015.
- [Shamir, 2016a] Ohad Shamir. Convergence of stochastic gradient descent for PCA. In ICML, pages 257-265, 2016.
- [Shamir, 2016b] Ohad Shamir. Fast stochastic algorithms for SVD and PCA: convergence properties and convexity. In ICML, pages 248-256, 2016.
- [Sra et al., 2011] Suvrit Sra, Sebastian Nowozin, and Stephen J. Wright. Optimization for Machine Learning. The MIT Press, 2011.
- [Wen and Yin, 2013] Zaiwen Wen and Wotao Yin. A fea- sible method for optimization with orthogonality con- straints. Math. Program., 142(1-2):397-434, 2013.
- [Xu and Gao, 2018] Zhiqiang Xu and Xin Gao. On truly block eigensolvers via riemannian optimization. In AIS- TATS, pages 168-177, 2018.
- [Xu and Ke, 2016a] Zhiqiang Xu and Yiping Ke. Effective and efficient spectral clustering on text and link data. In CIKM, pages 357-366, 2016.
- [Xu and Ke, 2016b] Zhiqiang Xu and Yiping Ke. Stochas- tic variance reduced riemannian eigensolver. CoRR, abs/1605.08233, 2016.
- [Xu et al., 2017] Zhiqiang Xu, Yiping Ke, and Xin Gao. A fast algorithm for matrix eigen-decompositionn. In UAI 2017, Sydney, Australia, August 11-15, 2017, 2017.
- [Zhang et al., 2016] Hongyi Zhang, Sashank J. Reddi, and Suvrit Sra. Riemannian SVRG: fast stochastic optimiza- tion on riemannian manifolds. In NIPS, pages 4592-4600, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Eigenvector computation is a ubiquitous problem in data processing nowadays, such as spectral clustering [Ng et al., 2002; Xu and Ke, 2016a], pagerank computation, dimensionality reduction [Fan et al., 2018], and so on. Classic solvers from numerical algebra are power methods and Lanczos algorithms [Golub and Van Loan, 1996], based on which there has been a recent surge of interest in developing varieties of solvers [Hardt and Price, 2014; Musco and Musco, 2015; Garber et al., 2016; Balcan et al., 2016]. However, most of them are purely theoretic. In this work, we focus on a general and practical solver [Wen and Yin, 2013], namely gradient descent from the optimization perspective, for the leading eigenvector computation:
∗Corresponding author <zhiqiangxu2001@gmail.com>
where A ∈ Rn×n and A⊤ = A. Gradient descent is the most widely used method in optimization for machine learning [Sra et al., 2011], due to its effectiveness, simplicity, and provable theoretical guarantees. It has also found successful applications to eigenvector computation [Absil et al., 2008; Wen and Yin, 2013; Pitaval et al., 2015; Liu et al., 2016; Zhang et al., 2016; Xu and Ke, 2016b]. In particular, it was demonstrated to have comparable performance and better robustness in comparison to Lanczos algorithms with extensive experimental studies [Wen and Yin, 2013]. Despite being practical, however, its convergence analysis remains unsatisfied thus far. Pitaval et al. proved its global convergence but the rate was unknown [Pitaval et al., 2015]. Under a large positive eigengap assumption a linear but local rate was achieved in [Xu and Ke, 2016b; Liu et al., 2016; Xu et al., 2017], while a gap-free rate O( 1 ϵ2 ) was given by [Arora et al., 2013; Shamir, 2016a]. Very recently, the rate for the case of an arbitrary eigengap has been improved to O( 1ϵ ) [Xu and Gao, 2018]. As shown in our experimental study, however, certain cases of zero eigengap are significantly underestimated and the quadratic dependence on the initial iterate is not true.
In this paper, we try to present a systematic convergence analysis of the gradient descent solver for Problem (1) to address all the issues mentioned above, and make it from a view of Riemannian optimization. The sphere constraint in (1) actually represents a Riemannian manifold, called the sphere manifold, which is a special case of the Stiefel manifold defined by the orthogonality constraint [Absil et al., 2008]. In this sense, Problem (1) is geodesically non-convex. A gradient descent step in Riemannian optimization takes the following form:
where ˜∇f(xt) denotes the Riemannian gradient representing the steepest ascent direction in the equidimensional Euclidean space tangent to the manifold at xt, αt+1 > 0 represents the step-size, and R(xt, ·) represents the retraction map from the tangent space at xt to the manifold. In particular, in order to measure the progress of the iterate xt to one of globally optimal solutions, we use for analysis a novel potential function defined by the log principal angle between xt and, the space of such solutions rather than only one of such solutions as in previous work [Shamir, 2015]. It turns out that this potential function boasts the advantage of establishing the global convergence and improving the dependence on the initial iterate. We present a novel general analysis that depends on the generalized eigengap, ∆p = λp - λp+1, where λi represents the i-th largest eigenvalue of the given matrix A and p is the multiplicity of λ1. ∆p always remains positive without loss of generality. This unifies all the cases of the conventionally considered eigengap ∆1 = λ1 - λ2, i.e., ∆1 > 0 and ∆1 = 0. When ∆p is as small as the target precision parameter ϵ, the resulting theoretic complexity is high. However, another unified analysis regardless of the value of ∆p we present subsequently shows that this can be significantly reduced. Specifically, we make the following contributions:
- A global convergence rate O(min{( λ1 ∆p )2 log 1ϵ , 1ϵ }) of the Riemannian gradient descent solver is achieved for Problem (1). The rate is linear at O(( λ1 ∆p )2 log 1ϵ ) if ( λ1 ∆p )2 = O(1), otherwise sub-linear at O( 1ϵ ). This shows that even if ∆1 = 0, it is possible as well to converge linearly.
- The quadratic dependence of the convergence on the initial iterate is improved to the logarithmic one.
- Theoretical properties, especially those related to ∆1 = 0, are empirically verified on synthetic or real data.
2 RelatedWork
Due to the space limit, we only discuss those gradient based solvers and refer readers to the cited references for more literature work. There are two categories of such solvers: projected gradient descent and Riemannian gradient descent. Arora et al. proposed the stochastic power method without theoretical guarantees [Arora et al., 2012], which actually is equivalent to the projected stochastic gradient descent for the principal component analysis (PCA) problem. It was named after the power method because the projected (deterministic) gradient descent for PCA will degenerate to the power method when the step-size goes to infinity. This method was subsequently extended via convex relaxation and proved to have a global, gap-free, and sub-linear convergence rate O( 1 ϵ2 ) [Arora et al., 2013]. Balsubramani et al. demonstrated that Oja's algorithm converges at a global, gap-dependent, and sub-linear rate O( 1ϵ ) via the martingale analysis [Balsubramani et al., 2013]. Note that the gap dependence refers to the dependence on ∆1 in most of existing analyses. More recently, stochastic gradient descent (SGD) for PCA was shown to converge either at a global, gap-dependent, and sub-linear rate O( 1 ∆ϵ ) or at a global, gap-free, and sub-linear rate O( 1 ϵ2 ) [Shamir, 2016a]. Shamir proposed the projected SGD with variance reduction for PCA, called VR-PCA, and proved its global or local, gap-dependent, and linear rate O( 1 ∆21 log 1ϵ ) [Shamir, 2015; 2016b].
More relevant to our work is an increasing body of Riemannian gradient descent methods. It is worth noting that general Riemannian optimization methods are applicable to Problem (1), including Riemannian gradient descent [Edelman et al., 1999; Absil et al., 2008; Wen and Yin, 2013], Riemannian SGD [Bonnabel, 2013] and Riemannian SVRG [Zhang et al., 2016]. Notably, Wen et al. demonstrated that curvilinear search, which actually performs Riemannian gradient descent with Cayley transformation based retraction, achieves a comparable performance and is more robust compared to Lanczos algorithms [Wen and Yin, 2013]. However, the analysis only, at most, achieves either a global, gap-free, and sub-linear convergence to critical points [Absil et al., 2008; Wen and Yin, 2013; Bonnabel, 2013; Zhang et al., 2016] or a local, gap-dependent, and linear convergence to globally optimal solutions [Absil et al., 2008], due to the geodesic non-convexity. As we know, each eigenvector corresponds to a critical point of the objective function in Problem (1) and thus they fail to meet the global optimality in theory. On the other hand, specifically, gradient descent for low-rank approximation was proven to converge globally but without any rate provided in [Pitaval et al., 2015]. Xu et al. established the local, gap-dependent, and linear rate O( 1 ∆21 log 1ϵ ) of the Riemannian SVRG solver [Xu and Ke, 2016b; Xu et al., 2017]. By proving an explicit Łojasiewicz exponent at 12 in [Liu et al., 2016], Liu et al. demonstrated a local, gapdependent, and linear convergence of the Riemannian linesearch methods for the quadratic problem under the orthogonality constraint, which includes Problem (1) as a special case. In addition, despite the motivation from optimization on Riemannian quotient manifolds, alecton as a SGD solver for streaming low-rank matrix approximation ends up with an update like the stochastic power method, and achieves a global, gap-dependent, and sub-linear rateO( 1 ∆21 ϵ ) via the martingale analysis [Sa et al., 2015].
Although gradient based methods for Problem (1) work well in practice [Arora et al., 2012; Wen and Yin, 2013], related theory is far behind. Despite great interest in developing stochastic solvers, surprisingly, there even does not exist a thorough convergence analysis for the deterministic gradient descent solver as is achieved in this work, which we believe will be an important basis for developing stochastic versions with better theoretical guarantees than the state-of-the-art.
3 Analysis of Gradient Descent
We now conduct the convergence analysis of the Riemannian gradient descent solver for Problem (1), starting from introducing necessary notions and notations. Main results are then stated in theorems and followed by a few important supporting lemmas. The section ends with the proofs of the theorem and lemmas.
3.1 Notions and Notations
Recall that given a real symmetric matrix A ∈ Rn×n , its i-th largest eigenvalue is denoted as λi, i.e., λ1 ≥ · · · ≥ λn, and the corresponding eigenvector denoted as vi. Define eigengap ∆i = λi-λi+1 and let p be the multiplicity of λ1 with the associated eigenspace denoted as Vp = [v1, · · · , vp]. One then should have ∆j = 0 for j = 1, · · · , p - 1 and ∆p > 0 without loss of generality, i.e., p < n, because f(x) will be a constant function if p = n.
Instead of focusing on a specific case of the eigengap like ∆1 > 0, we target a general framework admitting all the cases of ∆1. To this end, we have to rely on ∆p and Vp, where we follow [Xu and Gao, 2018] to term ∆p as the generalized eigengap. That is, it suffices for us to show the convergence to one of globally optimal solutions, i.e., a unit vector v ∈ span(Vp), instead of a specific solution, e.g., v1. We thus define the following potential function:
where actually ‖V⊤ p xt‖2 = cos θ(xt,Vp) representing the cosine of the principal angle between the current iterate xt and the space of globally optimal solutions. As ‖V⊤ p xt‖2 ≤ 1, it is easy to see that ψ(xt) ≥ 0 and xt converges to a unit vector in span(Vp) when ψ(xt) goes to 0.
In addition, we take the normalization retraction, i.e., R(x, ξ) = x+ξ ‖x+ξ‖2 . Thus, the update in (2) can be explicitly written as
where the Riemannian gradient for Problem (1) is ˜∇f(x) = -(I - xx⊤)Ax.
3.2 Main Results
Theorem 1. If the initial x0 = y ‖y‖2 where entries of y are i.i.d. standard normal samples, i.e., yi ∼ N(0, 1), then the Rimannian gradient descent solver for Problem (1) will converge to certain unit vector v ∈ span(Vp) at a global rate O(min{( λ1 ∆p )2 log 1ϵ , 1ϵ }) with high probability. Specifically, for any ϵ ∈ (0, 1),
- the solver with constant step-sizes α < ∆p 2λ21 (1+α∆p) will converge, i.e., ψ(xT ) < ϵ, after T = O(( λ1 ∆p )2 log ψ(x0) ϵ ) iterations, with probability at least 1 - ν p , where ν = 0 if p = 1 otherwise ν ∈ (0, 1);
- II) the solver with diminishing step-sizes αt = c τ+t for sufficiently large constants c, τ > 0 will converge, i.e., ψ(xT ) < ϵ, after T = O( 1ϵ ) iterations, with probability at least 1 - ν p , where ν = 0 if p = 1 otherwise ν ∈ (0, 1).
As the convergence holds with high probability for any random initial iterate, it is global by convention. Contrastingly, the success probability given in [Shamir, 2016a] is Ω( 1n ). To prove the theorem, we need a few important lemmas whose proofs are deferred to after that of Theorem 1.
Lemma 4. x -log(1-x) ≥ 1 1-log(1-x) for any x ∈ (0, 1), and x 1+x ≤ log(1 + x) ≤ x for any x > -1.
Lemma 5. ‖V⊤ p x0‖2 > 0 with probability 1 if p = 1, otherwise with probability at least 1 - ν p , where 0 < ν < 1 is a constant about V⊤ p y.
Proof of Theorem 1.
Proof. I) We start from expanding ψ(xt+1) using (3)-(4):
To proceed, we need the full eigen-decomposition of A, i.e.,
where V⊥ p represents the orthogonal complement of Vp. Plugging in this decomposition to V⊤ p A, one then gets
We now can write
where we have
and
One thus can arrive at
Note that by Lemma 4,
If ∆p 1+αt+1∆p - 2αt+1λ21 > 0, i.e., αt+1 < ∆p 2λ21 (1+αt+1∆p) , then ψ(xt+1) < ψ(xt) and
if αt+1 ≡ α. We thus have
and
we must have ψ(xT ) < ϵ. Plugging in α < ∆p 2λ21 (1+α∆p) to T, we can write
Finally note that (10) is equivalent to ‖V⊤ p x0‖2 > 0, which occurs with probability 1 if p = 1, otherwise at least 1 - ν p for certain constant ν ∈ (0, 1), by Lemma 5.
II) We now restart from (6). Plugging in (7) to (6), we can write
Let αt+1 = c τ+t where c, τ > 0 are constants. It is easy to see that for sufficiently small αt+1, equivalently, sufficiently large τ , we have ψ(xt+1) < ψ(xt). Thus, one gets
Denoting a = 2c∆p 1+ c τ ∆p 1 1+ψ(x0) and b = 2c2λ21 , one can write
As long as ψ(x0) < +∞ and a > 1, by Lemma D.1 in [Balsubramani et al., 2013], the recursion of the above inequality will yield
We thus have ψ(xT ) = O( 1 T ), i.e., T = O( 1ϵ ). The proof completes by noting that ψ(x0) < +∞ occurs with high probability similarly and a > 1 can be guaranteed by choosing sufficiently large constants c, τ .
Remark We make a few remarks on our proof. Equation (8) shows that the convergence is at least linear because ψ(xt+1) < ψ(xt) and thus the contraction factor keep decreasing for constant step-sizes. In Equation (9), αt+1 is not necessarily constant. In fact, the results will hold for any stepsize scheme as long as αt+1 < ∆p 2λ21 (1+αt+1∆p) . This provides theoretical support for us to flexibly choose step-size schemes. Equation (11) shows that larger step-sizes in a safe range will lead to faster convergence. Moreover, we can see from Equation (12) that the convergence actually depends on the relative generalized eigengap ∆p λ1 . This seems to be explicitly shown for the first time for the considered solver. As mentioned in Section 1, the proof provides two general analysis frameworks. The generality lies in that both rates hold for any value of the positive ∆p. The combination of the results from two kinds of analysis comprehensively portrays the convergence behaviors of the solver. For both kinds of analysis, the convergence has only logarithmic dependence on the initial iterate via ψ(x0) = -2 log ‖V⊤ p x0‖2.
Proof of Lemma 2
Proof. Plugging in (5) to x⊤Ax, we get
Thus, one arrives at
Proof of Lemma 3
Proof.
where, plugging in the following form of A's full eigendecomposition,
for any unit vector v ∈ span(Vp), we get
Since the above inequality holds for any unit vector v ∈ span(Vp), we have
By the definition of principal angles [Golub and Van Loan, 1996],1 - ‖V⊤
One thus has
Proof of Lemma 4
Proof. 1) For any x, it holds that 1 + x ≤ ex . Then for any x > -1,
If one lets y = 1 + x in the above inequality, then log y ≤ y - 1. Further letting y = 1 z yields log z ≥ - 1 z + 1 = z-1 z . Last, setting z = 1 + x gives us
2) Note that log(1 + x) = ∑∞i=0 (-1)i xi+1 i+1 for |x| < 1. One then can write for x ∈ (0, 1) that
Proof of Lemma 5
Proof. Let σmin(·) and σmax(·) be the smallest and largest singular value of a matrix, respectively. We then have
where σmax(y) > 0 almost surely. Since entries of y are i.i.d. samples fromN(0, 1) and Vp is orthonormal, entries of V⊤ p y are i.i.d. standard normal samples as well. By Equation (3.2) in [Rudelson and Vershynin, 2010], σmin(V⊤ 1 y) > 0 almost surely (i.e., with probability 1). By Theorem 3.3 in [Rudelson and Vershynin, 2010], we have σmin(V⊤ p y) > 0 with probability at least 1-ν p , where 0 < ν < 1 is a constant about V⊤ p y.
4 Experiments
Theoretical properties of the considered solver were already observed and verified empirically in, e.g., [Wen and Yin, 2013; Liu et al., 2016], albeit without thorough theoretical support. For the sake of completeness, we reproduce a few experiments on both synthetic and real data here, with new testing on matrices of zero eigengap. All the ground truth information, e.g., v1 or Vp, is obtained by matlab's eigs function for the purpose of benchmarking.
The advantage of using synthetic data mainly lies in the control of the eigengap. We set n = 1000 and follow [Shamir, 2015] to generate data using the full eigenvalue decomposition A = UΣU⊤. U is an orthogonal matrix and is set the same way as x0. Σ = diag(Σ1,Σ2), where Σ2 = diag( |g1| n , · · · , |gn-r| n ) with gi ∼ N(0, 1) and r being the order of Σ1. In addition, the following two settings are considered:
For the conventionally considered case that ∆1 > 0, two types of convergence curves, in terms of the relative function error f(xt)-f(v1) f(v1) and the commonly used potential function sin2 θ(xt, v1), respectively, are shown in Figure 2 for different eigengap values. Global linear convergence of the solver is observed, and a larger eigengap yields faster convergence. It agrees with the theory. The convergence trends remain greatly consistent for the two types, which holds in the rest of experiments as well.
For the case that ∆1 = 0 and αt+1 = c τ+t (see Remark), different pairs of step-size parameters are tested in Figure 1. As described by Theorem 1, the convergence reported in Figures 1(a)-1(b) is global linear, rather than sub-linear by [Xu and Gao, 2018], and large step-sizes result in faster convergence as well. As it is unknown which leading eigenvector xt will converge to finally, it is necessary for us to change the potential from the commonly used sin2 θ(xt, v1) to sin2 θ(xt, Vp) in this case. As demonstrated in Figure 1(c), sin2 θ(xt, v1) is unable to converge, which implies that xt has converged to another leading eigenvector in span(Vp).
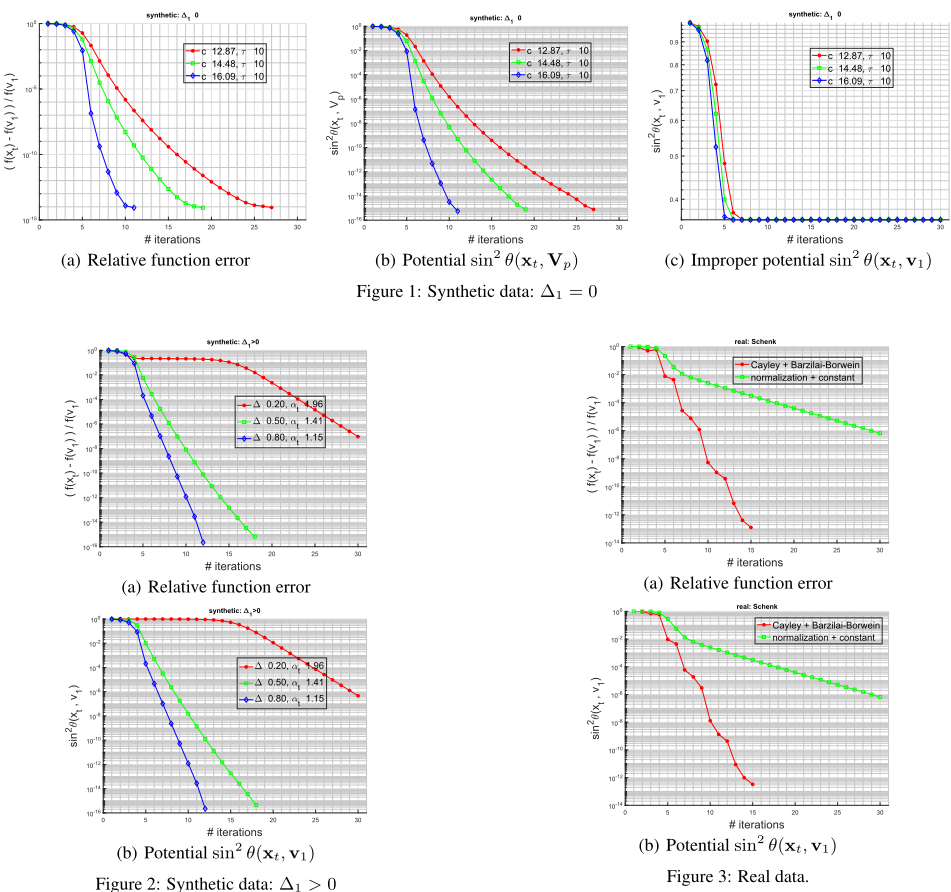
We run two implementations of the solver on a real symmetric matrix A, named Schenk 1 , which is of size 10, 728 × 10, 728 with 85, 000 nonzero entries. The implementation is characterized by the combination of the retraction and stepsize scheme used. Curvilinear search was proposed in [Wen and Yin, 2013] which uses "Cayley transform + BarzilaiBorwein step-size". The other implementation uses "normalization + constant step-size". They were fed with the same random initial iterate. The results are reported in Figure 3, which reflect the global linear convergence as well and meanwhile shows that different step-size schemes matter in practice.
1 www.cise.ufl.edu/research/sparse/matrices/
5 Conclusion
We presented a simple yet comprehensive convergence analysis of the Riemannian gradient descent solver for the leading eigenvector computation. Two kinds of general analysis jointly established the true global rate of convergence to one of the leading eigenvectors. The generalized eigengap ∆p eliminates the limitation of the commonly considered eigengap ∆1. When ∆p is large, the convergence is linear, which is described by the first general analysis. If it is as small as ϵ, the second general analysis shows that it is sub-linear O( 1ϵ ) rather than O( 1 ϵ2 ). It was also shown that the convergence only logarithmically depends on the initial iterate. The key to these breakthroughs made for the considered solver is to use for analysis the log principal angle between iterates and the space of the leading eigenvectors. Along this work, there are a few interesting future research directions. For example, it is unknown if the results can be extended to k > 1 for the topk eigenspace computation without deflation. In particular, it would be more attractive to practitioners if the analysis can be translated to the case of the stochastic gradient descent solver, which is well worth further investigation. Also, although the rate is optimal for the considered solver, it would be of great interest to develop faster solvers of this type to match the optimal rate for the problem, e.g., those of Lanczos algorithms.
Acknowledgements
This research is supported in part by the funding from King Abdullah University of Science and Technology (KAUST).
@inproceedings{ijcai2018p407,
  title     = {Convergence Analysis of Gradient Descent for Eigenvector Computation},
  author    = {Xu, Zhiqiang and Cao, Xin and Gao, Xin},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2933--2939},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/407},
  url       = {https://doi.org/10.24963/ijcai.2018/407},
}
TY - CPAPER TI - Convergence Analysis of Gradient Descent for Eigenvector Computation AU - Xu, Zhiqiang AU - Cao, Xin AU - Gao, Xin T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2933 EP - 2939 DO - 10.24963/ijcai.2018/407 UR - https://doi.org/10.24963/ijcai.2018/407 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





