
Zeroth-Order Stochastic Alternating Direction Method of Multipliers for Nonconvex Nonsmooth Optimization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2549-2555.
https://doi.org/10.24963/ijcai.2019/354
Keywords
- Machine Learning: Adversarial Machine Learning
- Machine Learning Applications: Big data ; Scalability
Abstract
Alternating direction method of multipliers (ADMM) is a popular optimization tool for the composite and constrained problems in machine learning. However, in many machine learning problems such as black-box learning and bandit feedback,
ADMM could fail because the explicit gradients of these problems are difficult or even infeasible to obtain. Zeroth-order (gradient-free) methods can effectively solve these problems due to that the objective function values
are only required in the optimization. Recently, though there exist a few zeroth-order ADMM methods, they build on the convexity of objective function. Clearly, these existing zeroth-order methods are limited in many applications.
In the paper, thus, we propose a class of fast zeroth-order stochastic ADMM methods (\emph{i.e.}, ZO-SVRG-ADMM and ZO-SAGA-ADMM) for solving nonconvex problems with multiple nonsmooth penalties, based on the
coordinate smoothing gradient estimator. Moreover, we prove that both the ZO-SVRG-ADMM and ZO-SAGA-ADMM have convergence rate of $O(1/T)$, where $T$ denotes the number of iterations. In particular, our methods not only reach the best convergence rate of $O(1/T)$ for the nonconvex optimization, but also are able to effectively solve many complex machine learning problems with multiple regularized penalties and constraints.
Finally, we conduct the experiments of black-box binary classification and structured adversarial attack on black-box deep neural network to validate the efficiency of our algorithms.
- [Agarwal et al., 2010] Alekh Agarwal, Ofer Dekel, and Lin Xiao. Optimal algorithms for online convex optimization with multi-point bandit feedback. In COLT, pages 28-40.
- [Beck and Teboulle, 2009] Amir Beck and Marc Teboulle. A fast iterative shrinkage-thresholding algorithm for lin- ear inverse problems. SIAM journal on imaging sciences, 2(1):183-202, 2009.
- [Boyd et al., 2011] Stephen Boyd, Neal Parikh, Eric Chu, Borja Peleato, and Jonathan Eckstein. Distributed opti- mization and statistical learning via the alternating direc- tion method of multipliers. Foundations and Trends R ⃝ in Machine Learning, 3(1):1-122, 2011.
- [Chen et al., 2017] Pin-Yu Chen, Huan Zhang, Yash Sharma, Jinfeng Yi, and Cho-Jui Hsieh. Zoo: Zeroth order opti- mization based black-box attacks to deep neural networks without training substitute models. In Workshop on Artifi- cial Intelligence and Security, pages 15-26. ACM, 2017.
- [Defazio et al., 2014] Aaron Defazio, Francis Bach, and Si- mon Lacoste-Julien. Saga: A fast incremental gradient method with support for non-strongly convex composite objectives. In NIPS, pages 1646-1654, 2014.
- [Duchi et al., 2015] John C Duchi, Michael I Jordan, Mar- tin J Wainwright, and Andre Wibisono. Optimal rates for zero-order convex optimization: The power of two func- tion evaluations. IEEE TIT, 61(5):2788-2806, 2015.
- [Gabay and Mercier, 1976] Daniel Gabay and Bertrand Mercier. A dual algorithm for the solution of nonlinear variational problems via finite element approximation. Computers & Mathematics with Applications, 2(1):17-40, 1976.
- [Gao et al., 2018] Xiang Gao, Bo Jiang, and Shuzhong Zhang. On the information-adaptive variants of the admm: an iteration complexity perspective. Journal of Scientific Computing, 76(1):327-363, 2018.
- [Ghadimi and Lan, 2013] Saeed Ghadimi and Guanghui Lan. Stochastic first-and zeroth-order methods for non- convex stochastic programming. SIAM Journal on Opti- mization, 23(4):2341-2368, 2013.
- [Ghadimi et al., 2016] Saeed Ghadimi, Guanghui Lan, and Hongchao Zhang. Mini-batch stochastic approximation methods for nonconvex stochastic composite optimization. Mathematical Programming, 155(1-2):267-305, 2016.
- [Gu et al., 2018] Bin Gu, Zhouyuan Huo, Cheng Deng, and Heng Huang. Faster derivative-free stochastic algorithm for shared memory machines. In ICML, pages 1807-1816, 2018.
- [He et al., 2011] Ran He, Wei-Shi Zheng, and Bao-Gang Hu. Maximum correntropy criterion for robust face recogni- tion. IEEE TPAMI, 33(8):1561-1576, 2011.
- [Huang and Chen, 2015] Feihu Huang and Songcan Chen. Joint learning of multiple sparse matrix gaussian graph- ical models. IEEE transactions on neural networks and learning systems, 26(11):2606-2620, 2015.
- [Huang et al., 2016] Feihu Huang, Songcan Chen, and Zhaosong Lu. Stochastic alternating direction method of multipliers with variance reduction for nonconvex opti- mization. arXiv preprint arXiv:1610.02758, 2016.
- [Huang et al., 2019a] Feihu Huang, Songcan Chen, and Heng Huang. Faster stochastic alternating direction method of multipliers for nonconvex optimization. In ICML, pages 2839-2848, 2019.
- [Huang et al., 2019b] Feihu Huang, Bin Gu, Zhouyuan Huo, Songcan Chen, and Heng Huang. Faster gradient-free proximal stochastic methods for nonconvex nonsmooth optimization. In AAAI, 2019.
- [Jiang et al., 2019] Bo Jiang, Tianyi Lin, Shiqian Ma, and Shuzhong Zhang. Structured nonconvex and nonsmooth optimization: algorithms and iteration complexity anal- ysis. Computational Optimization and Applications, 72(1):115-157, 2019.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In NIPS, pages 315-323, 2013.
- [Kim et al., 2009] Seyoung Kim, Kyung-Ah Sohn, and Er- ic P Xing. A multivariate regression approach to associa- tion analysis of a quantitative trait network. Bioinformat- ics, 25(12):i204-i212, 2009.
- [Liu et al., 2018a] Sijia Liu, Jie Chen, Pin-Yu Chen, and Alfred Hero. Zeroth-order online alternating direction method of multipliers: Convergence analysis and applica- tions. In AISTATS, volume 84, pages 288-297, 2018.
- [Liu et al., 2018b] Sijia Liu, Bhavya Kailkhura, Pin-Yu Chen, Paishun Ting, Shiyu Chang, and Lisa Amini. Zeroth-order stochastic variance reduction for nonconvex optimization. In NIPS, pages 3731-3741, 2018.
- [Nesterov and Spokoiny, 2017] Yurii Nesterov and Vladimir G. Spokoiny. Random gradient-free minimiza- tion of convex functions. Foundations of Computational Mathematics, 17:527-566, 2017.
- [Ouyang et al., 2013] Hua Ouyang, Niao He, Long Tran, and Alexander G Gray. Stochastic alternating direction method of multipliers. ICML, 28:80-88, 2013.
- [Suzuki, 2014] Taiji Suzuki. Stochastic dual coordinate as- cent with alternating direction method of multipliers. In ICML, pages 736-744, 2014.
- [Taylor et al., 2016] Gavin Taylor, Ryan Burmeister, Zheng Xu, Bharat Singh, Ankit Patel, and Tom Goldstein. Train- ing neural networks without gradients: a scalable admm approach. In ICML, pages 2722-2731, 2016.
- [Wang et al., 2015] Fenghui Wang, Wenfei Cao, and Zong- ben Xu. Convergence of multi-block bregman admm for nonconvex composite problems. arXiv preprint arX- iv:1505.03063, 2015.
- [Xu et al., 2018] Kaidi Xu, Sijia Liu, Pu Zhao, Pin-Yu Chen, Huan Zhang, Deniz Erdogmus, Yanzhi Wang, and Xue Lin. Structured adversarial attack: Towards general imple- mentation and better interpretability. arXiv preprint arX- iv:1808.01664, 2018.
- [Zheng and Kwok, 2016] Shuai Zheng and James T Kwok. Fast-and-light stochastic admm. In IJCAI, pages 2407- 2613, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Alternating direction method of multipliers (ADMM [Gabay and Mercier, 1976; Boyd et al., 2011]) is a popular optimization tool for solving the composite and constrained problems in machine learning. In particular, ADMM can efficiently optimize some problems with complicated structure regularization such as the graph-guided fused lasso [Kim et al.,
∗Corresponding Author.
2009], which is too complicated for the other popular optimization methods such as proximal gradient methods [Beck and Teboulle, 2009]. For the large-scale optimization, the stochastic ADMM method [Ouyang et al., 2013] has been proposed. Recently, some faster stochastic ADMM methods [Suzuki, 2014; Zheng and Kwok, 2016] have been proposed by using the variance reduced (VR) techniques such as the SVRG [Johnson and Zhang, 2013]. In fact, ADMM is also highly successful in solving various nonconvex problems such as training deep neural networks [Taylor et al., 2016]. Thus, some fast nonconvex stochastic ADMM methods have been developed in [Huang et al., 2016; Huang et al., 2019a].
Currently, most of the ADMM methods need to compute the gradients of objective functions over each iteration. However, in many machine learning problems, the explicit expression of gradient for objective function is difficult or infeasible to obtain. For example, in black-box situations, only prediction results (i.e., function values) are provided [Chen et al., 2017; Liu et al., 2018b]. In bandit settings [Agarwal et al., 2010], player only receives the partial feedback in terms of loss function values, so it is impossible to obtain expressive gradient of the loss function. Clearly, the classic optimization methods, based on the first-order gradient or second-order information, are not competent to these problems. Recently, the zeroth-order optimization methods [Duchi et al., 2015; Nesterov and Spokoiny, 2017] are developed by only using the function values in the optimization.
In the paper, we focus on using the zeroth-order methods to solve the following nonconvex nonsmooth problem:
where A ∈ Rp×d , Bj ∈ Rp×q for all j ∈ [k], k ≥ 1, f(x) = 1n ∑ni=1 fi(x) : Rd → R is a nonconvex and blackbox function, and each ψj (yj ) : Rq → R is a convex and nonsmooth function. In machine learning, function f(x) can be used for the empirical loss, ∑kj=1 ψj(yj) for multiple structure penalties (e.g., sparse + group sparse), and the constraint for encoding the structure pattern of model parameters such as graph structure. Due to the flexibility in splitting the objective function into loss f(x) and each penalty ψj(yj), ADMM is an efficient method to solve the obove problem. However, in the problem (1), we only access the objective values rather than the whole explicit function F(x, y[k]), thus the classic ADMMmethods are unsuitable for the problem (1).
| Algorithm | Reference | Gradient Estimator | Problem | Convergence Rate |
|---|---|---|---|---|
| ZOO-ADMM | [Liu et al., 2018a] | GauSGE | C(S) + C(NS) | O(√1/T ) |
| ZO-GADM | [Gao et al., 2018] | UniSGE | C(S) + C(NS) | O(√1/T ) |
| RSPGF | [Ghadimi et al., 2016] | GauSGE | NC(S) + C(NS) | O(√1/T ) |
| ZO-ProxSVRG ZO-ProxSAGA | [Huang et al., 2019b] | CooSGE | NC(S) + C(NS) | O(1/T ) |
| ZO-SVRG-ADMM ZO-SAGA-ADMM | Ours | CooSGE | NC(S) + C(mNS) | O(1/T ) |
Recently, [Gao et al., 2018; Liu et al., 2018a] proposed the zeroth-order stochastic ADMM methods, which only use the objective values to optimize. However, these zeroth-order ADMM-based methods build on the convexity of objective function. Clearly, these methods are limited in many nonconvex problems such as adversarial attack on black-box deep neural network (DNN). At the same time, due to that the problem (1) includes multiple nonsmooth regularization functions and an equality constraint, the existing zeroth-order algorithms [Liu et al., 2018b; Huang et al., 2019b] are not suitable for solving this problem.
In the paper, thus, we propose a class of fast zeroth-order stochastic ADMM methods (i.e., ZO-SVRG-ADMM and ZOSAGA-ADMM) to solve the problem (1) based on the coordinate smoothing gradient estimator [Liu et al., 2018b]. In particular, the ZO-SVRG-ADMM and ZO-SAGA-ADMM methods build on the SVRG [Johnson and Zhang, 2013] and SAGA [Defazio et al., 2014], respectively. Moreover, we study the convergence properties of the proposed methods. Table 1 shows the convergence properties of the proposed methods and other related ones.
1.1 Challenges and Contributions
Although both SVRG and SAGA show good performances in the first-order and second-order methods, applying these techniques to the nonconvex zeroth-order ADMMmethod is not trivial. There exists at least two main challenges:
- Due to failure of the Fej´er monotonicity of iteration, the convergence analysis of the nonconvex ADMM is generally quite difficult [Wang et al., 2015]. With using the inexact zeroth-order estimated gradient, this difficulty becomes greater in the nonconvex ADMM methods.
- To guarantee convergence of our zeroth-order ADMM methods, we need to design a new effective Lyapunov function, which can not follow the existing nonconvex (stochastic) ADMM methods [Jiang et al., 2019; Huang et al., 2016].
Thus, we carefully establish the Lyapunov functions in the following theoretical analysis to ensure convergence of the proposed methods. In summary, our major contributions are given below:
- We propose a class of fast zeroth-order stochastic ADMM methods (i.e., ZO-SVRG-ADMM and ZO-SAGAADMM) to solve the problem (1).
- We prove that both the ZO-SVRG-ADMM and ZOSAGA-ADMM have convergence rate of O( 1 T ) for nonconvex nonsmooth optimization. In particular, our methods not only reach the existing best convergence rate O( 1 T ) for the nonconvex optimization, but also are able to effectively solve many machine learning problems with multiple complex regularized penalties.
- Extensive experiments conducted on black-box classification and structured adversarial attack on black-box DNNs validate efficiency of the proposed algorithms.
2 RelatedWorks
Zeroth-order (gradient-free) optimization is a powerful optimization tool for solving many machine learning problems, where the gradient of objective function is not available or computationally prohibitive. Recently, the zeroth-order optimization methods are widely applied and studied. For example, zeroth-order optimization methods have been applied to bandit feedback analysis [Agarwal et al., 2010] and blackbox attacks on DNNs [Chen et al., 2017; Liu et al., 2018b]. [Nesterov and Spokoiny, 2017] have proposed several random zeroth-order methods based on the Gaussian smoothing gradient estimator. To deal with the nonsmooth regularization, [Gao et al., 2018; Liu et al., 2018a] have proposed the zeroth-order online/stochastic ADMM-based methods.
So far, the above algorithms mainly build on the convexity of problems. In fact, the zeroth-order methods are also highly successful in solving various nonconvex problems such as adversarial attack to black-box DNNs [Liu et al., 2018b]. Thus, [Ghadimi and Lan, 2013; Liu et al., 2018b; Gu et al., 2018] have begun to study the zeroth-order stochastic methods for the nonconvex optimization. To deal with the nonsmooth regularization, [Ghadimi et al., 2016; Huang et al., 2019b] have proposed some non-convex zerothorder proximal stochastic gradient methods. However, these methods still are not well competent to some complex machine learning problems such as a task of structured adversarial attack to the black-box DNNs, which is described in the following experiment.
2.1 Notations
Let y[k] = {y1, · · · , yk} and y[j:k] = {yj, · · · , yk} for j ∈ [k]. Given a positive definite matrix G, ∥x∥2G = xT Gx; σmax(G) and σmin(G) denote the largest and smallest eigenvalues of G, respectively, and κG = σmax(G) σmin(G) . σAmax and σAmin denote the largest and smallest eigenvalues of matrix AT A.
3 Preliminaries
In the section, we begin with restating a standard ϵapproximate stationary point of the problem (1), as in [Jiang et al., 2019; Huang et al., 2019a].
Definition 1. Given ϵ > 0, the point (x∗ , y∗ [k] , λ∗ ) is said to be an ϵ-approximate stationary point of the problems (1), if it holds that
where L(x, y[k], λ) = f(x) + ∑kj=1 ψj(yj) - ⟨λ,Ax + ∑kj=1 Bjyj - c⟩,
dist(0, ∂L) = infL′∈∂L ∥0 - L′∥.
Next, we make some mild assumptions regarding problem (1) as follows:
Assumption 1. Each function fi(x) is L-smooth for ∀i ∈ {1, 2, · · · , n} such that
which is equivalent to
Assumption 2. Gradient of each function fi(x) is bounded, i.e., there exists a constant δ > 0 such that for all x, it follows that ∥∇fi(x)∥2 ≤ δ2 .
Assumption 3. f(x) and ψj(yj) for all j ∈ [k] are all lower bounded, and denote f ∗ = infx f(x) and ψ∗ j = infy ψj(y) for j ∈ [k].
Assumption 4. A is a full row or column rank matrix.
Assumption 1 has been commonly used in the convergence analysis of nonconvex algorithms [Ghadimi et al., 2016]. Assumption 2 is widely used for stochastic gradient-based and ADMM-type methods [Boyd et al., 2011]. Assumptions 3 and 4 are usually used in the convergence analysis of ADMM methods [Jiang et al., 2019; Huang et al., 2016; Huang et al., 2019a]. Without loss of generality, we will use the full column rank of matrix A in the rest of this paper.
Algorithm 1 Nonconvex ZO-SVRG-ADMM Algorithm
- 1: Input: b, m, T, S = ⌈T/m⌉, η > 0 and ρ > 0;
- 2: Initialize: x10 , y0,1 j for j ∈ [k] and λ10 ;
- 3: for s = 1, 2, · · · , S do
- 4: ˜xs+1 = xs+1 0 , ˆ∇f(˜xs ) = 1n ∑ni=1 ˆ∇fi(˜xs );
- 5: for t = 0, 1, · · · ,m-1 do
- 6: Uniformly randomly pick a mini-batch It (with replacement) from {1, 2, · · · , n}, and |It| = b ;
- 7: Using (4) to estimate stochastic gradient ˆ gs t =
- ˆ∇fIt (xst ) - ˆ∇fIt (˜xs ) + ˆ∇f (˜xs ); 8: ys,t+1 j = argminyj {Lρ(xst , ys,t+1 [j-1] , yj , ys,t [j+1:k] , λst ) + 12 ∥yj - ys,t j ∥2Hj }, for all j ∈ [k];
- 9: xst+1 = argminx ˆ Lρ (x, ys,t+1 [k] , λst , ˆ gs t );
- 10: λst+1 = λst - ρ(Axst+1 + ∑kj=1 Bjys,t+1 j - c);
- 11: end for
- 13: end for
- 14: Output: {x, y, λ} chosen at random uniformly from {(xst , ys,t [k] , λst )mt=1 }Ss=1 .
4 Fast Zeroth-Order Stochastic ADMMs
In this section, we propose a class of zeroth-order stochastic ADMMmethods to solve the problem (1). First, we define an augmented Lagrangian function of the problem (1):
where λ ∈ Rp and ρ > 0 denotes the dual variable and penalty parameter, respectively.
In the problem (1), the explicit expression of objective function fi(x) is not available, and only the function value of fi(x) is available. To avoid computing explicit gradient, thus, we use the coordinate smoothing gradient estimator [Liu et al., 2018b] to estimate gradients: for i ∈ [n],
where µj is a coordinate-wise smoothing parameter, and ej is a standard basis vector with 1 at its j-th coordinate, and 0 otherwise.
Based on the above estimated gradients, we propose a zeroth-order ADMM (ZO-ADMM) method to solve the problem (1) by executing the following iterations, for t=1, 2, · · ·
Algorithm 2 Nonconvex ZO-SAGA-ADMM Algorithm
- 1: Input: b, T, η > 0 and ρ > 0;
- 2: Initialize: z0 i = x0 for i ∈ {1, 2, · · · , n}, ˆ ϕ0 = 1n ∑ni=1 ∇fi(z0 i ), y0 j for j ∈ [k] and λ0;
- 3: for t = 0, 1, · · · , T -1 do
- 4: Uniformly randomly pick a mini-batch It (with replacement) from {1, 2, · · · , n}, and |It| = b ;
- 5: Using (4) to estimate stochastic gradient ˆ gt = 1b ∑it∈It (∇fit (xt) - ∇fit (zt it )) + ˆ ϕt with ˆ ϕt = 1n ∑ni=1 ∇fi(zt i );
- 7: xt+1 = argminx ˆ Lρ (x, yt+1 [k] , λt, ˆ gt );
- 8: λt+1 = λt -ρ(Axt+1 + ∑kj=1 Bjyt+1 j - c);
- 9: zt+1 it = xt for i ∈ It and zt+1 i = zt i for i ̸∈ It;
- 10: ˆ ϕt+1 = ˆ ϕt - 1n ∑it∈It (∇fit (zt it ) - ∇fit (zt+1 it ));
- 11: end for
- 12: Output: {x, y, λ} chosen at random uniformly from {xt, yt [k] , λt}Tt=1 .
where the term 12 ∥yj - yt j ∥2Hj with Hj ≻ 0 to linearize the term ∥Ax+ ∑kj=1 Bjyj -c∥2 . Here, due to using the inexact zeroth-order gradient to update x, we define an approximate function over xt as follows:
where G ≻ 0, ˆ∇f(x) is the zeroth-order gradient and η > 0 is a step size. Considering the matrix AT A is large, set G = rI - ρηAT A ≻ I with r > ρησmax(AT A) + 1 to linearize the term ∥Ax + ∑kj=1 Bjyt+1 j - c∥2 . In the problem (1), not only the noisy gradient of fi(x) is not available, but also the sample size n is very large. Thus, we propose fast ZOSVRG-ADMM and ZO-SAGA-ADMM to solve the problem (1), based on the SVRG and SAGA, respectively.
Algorithm 1 shows the algorithmic framework of ZOSVRG-ADMM. In Algorithm 1, we use the estimated stochastic gradient ˆ gs t = ˆ∇fIt (xst ) - ˆ∇fIt (˜xs ) + ˆ∇f(˜xs ) with ˆ∇fIt (xst ) = 1b ∑it∈It ˆ∇fit (xst ). We have EIt [ˆ gs t ] = ˆ∇f(xst ) ̸= ∇f(xst ), i.e., this stochastic gradient is a biased estimate of the true full gradient. Although the SVRG has shown a great promise, it relies upon the assumption that the stochastic gradient is an unbiased estimate of true full gradient. Thus, adapting the similar ideas of SVRG to zerothorder ADMM optimization is not a trivial task. To handle this challenge, we choose the appropriate step size η, penalty parameter ρ and smoothing parameter µ to guarantee the convergence of our algorithms, which will be discussed in the following convergence analysis.
Algorithm 2 shows the algorithmic framework of ZOSAGA-ADMM. In Algorithm 2, we use the estimated stochastic gradient ˆ gt = 1b ∑it∈It ( ˆ∇fit (xt) -∇fit (zt it )) + ˆ ϕt with ˆ ϕt = 1n ∑ni=1 ˆ∇fi(zt i ). Similarly, we have EIt [ˆ gt] = ˆ∇f(xt) ̸= ∇f(xt).
5 Convergence Analysis
In this section, we will study the convergence properties of the proposed algorithms (ZO-SVRG-ADMM and ZOSAGA-ADMM).
5.1 Convergence Analysis of ZO-SVRG-ADMM
In this subsection, we analyze convergence properties of the ZO-SVRG-ADMM.
Given the sequence {(xst , ys,t [k] , λst )mt=1 }Ss=1 generated from Algorithm 1, we define a Lyapunov function:
where the positive sequence {ct} satisfies
Next, we definite a useful variable θs t =E[∥xst+1 - xst ∥2 + ∥xst -xst-1 ∥2 + db (∥xst -˜xs ∥2 +∥xst-1 -˜xs ∥2 )+∑kj=1 ∥ys,t j - ys,t+1 j ∥2 ].
Theorem 1. Suppose the sequence {(xst , ys,t [k] , λst )mt=1 }Ss=1 is generated from Algorithm 1. Let m = n 13 , b = d1-ln 23 , l ∈ {0, 12 , 1}, η = ασmin(G) 9dlL (0 < α ≤ 1) and ρ = 6√71κGdlL σAminα , then we have
where ˜ ν = R1 0 - R∗ , and R∗ is a lower bound of function Rs t . It follows that suppose the smoothing parameter µ and the whole iteration number T = mS satisfy
then (xs∗ t∗ , ys∗ ,t∗ [k] , λs∗ t∗ ) is an ϵ-approximate stationary point of the problems (1), where (t∗ , s∗ ) = argmint,s θs t .
Remark 1. Theorem 1 shows that given m = n 1 3 , b = d1-ln 2 3 , l ∈ {0, 12 , 1}, η = ασmin(G) 9dlL (0 < α ≤ 1), ρ = 6√71κGdlL σAminα and µ = O( 1 d√T ), the ZO-SVRG-ADMM has convergence rate of O( d2l T ). Specifically, when 1 ≤ d < n 1 3 , given l = 0, the ZO-SVRG-ADMM has convergence rate of O( 1 T ); when n 13 ≤ d < n 23 , given l = 1 2 , it has convergence rate of O( √d T ); when n 23 ≤ d, given l = 1, it has convergence rate of O( d T ).
5.2 Convergence Analysis of ZO-SAGA-ADMM
In this subsection, we provide the convergence analysis of the ZO-SAGA-ADMM.
Given the sequence {xt, yt [k] , λt}Tt=1 generated from Algorithm 2, we define a Lyapunov function
Here the positive sequence {ct} satisfies
where ˆ p denotes probability of an index i in It. Next, we definite a useful variable θt =E[∥xt+1-xt∥2+∥xt-xt-1∥2+ d bn ∑ni=1 (∥xt-zt i ∥2+∥xt-1-zt-1 i ∥2 )+∑kj=1 ∥yt j -yt+1 j ∥2 ]. Theorem 2. Suppose the sequence {xt, yt [k] , λt}Tt=1 is generated from Algorithm 2. Let b = n 23 d 1-l 3 , l ∈ {0, 1 2 , 1}, η = ασmin(G) 33dlL (0 < α ≤ 1) and ρ = 6√791κGdlL σAminα then we have
where ˜ ν = Ω0 -Ω∗ , and Ω∗ is a lower bound of function Ωt. It follows that suppose the parameters µ and T satisfy
then (xt∗, yt∗ [k] , λt∗) is an ϵ-approximate stationary point of the problems (1), where t∗ = argmin1≤t≤T θt.
Remark 2. Theorem 2 shows that b = n 23 d 1-l 3 , l ∈ {0, 12 , 1}, η = ασmin(G) 33dlL (0 < α ≤ 1), ρ = 6√791κGdlL σAminα and µ = O( 1 d√T ), the ZO-SAGA-ADMM has the O( d2l T ) of convergence rate. Specifically, when 1 ≤ d < n, given l = 0, the ZO-SAGA-ADMM has convergence rate of O( 1 T ); when n ≤ d < n2 , given l = 12 , it has convergence rate of O( d T ); when n2 ≤ d, given l = 1, it has convergence rate of O( d2 T ).
6 Experiments
In this section, we compare our algorithms (ZO-SVRGADMM, ZO-SAGA-ADMM) with the ZO-ProxSVRG, ZOProxSAGA [Huang et al., 2019b], the deterministic zerothorder ADMM (ZO-ADMM), and zeroth-order stochastic ADMM (ZO-SGD-ADMM) without variance reduction on two applications: 1) robust black-box binary classification, and 2) structured adversarial attacks on black-box DNNs.
| datasets | #samples | #features | #classes |
|---|---|---|---|
| 20news | 16,242 | 100 | 2 |
| a9a | 32,561 | 123 | 2 |
| w8a | 64,700 | 300 | 2 |
| covtype.binary | 581,012 | 54 | 2 |
6.1 Robust Black-Box Binary Classification
In this subsection, we focus on a robust black-box binary classification task with graph-guided fused lasso. Given a set of training samples (ai, li)ni=1 , where ai ∈ Rd and li ∈ {-1,+1}, we find the optimal parameter x ∈ Rd by solving the problem:
where fi(x) is the black-box loss function, that only returns the function value given an input. Here, we specify the loss function fi(x) = σ2 2 (1 - exp(- (li-aTi x)2 σ2 )), which is the nonconvex robust correntropy induced loss [He et al., 2011]. Matrix ˆG decodes the sparsity pattern of graph obtained by learning sparse Gaussian graphical model [Huang and Chen, 2015]. In the experiment, we give mini-batch size b = 20, smoothing parameter µ = 1 d√t and penalty parameters τ1 = τ2 = 10-5 .
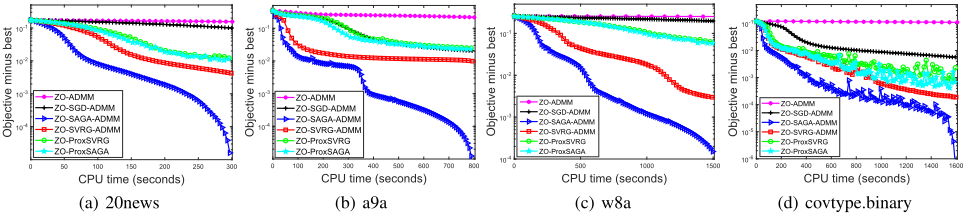
In the experiment, we use some public real datasets 1 , which are summarized in Table 2. For each dataset, we use half of the samples as training data and the rest as testing data. Figure 1 shows that the objective values of our algorithms faster decrease than the other algorithms, as the CPU time increases. In particular, our algorithms show better performances than the zeroth-order proximal algorithms. It is relatively difficult that these zeroth-order proximal methods deal with the nonsmooth penalties in the problem (6). Thus, we have to use some iterative methods to solve the proximal operator in these proximal methods.
6.2 Structured Attacks on Black-Box DNNs
In this subsection, we use our algorithms to generate adversarial examples to attack the pre-trained DNN models, whose parameters are hidden from us and only its outputs are accessible. Moreover, we consider an interesting problem: "What possible structures could adversarial perturbations have to fool black-box DNNs ?" Thus, we use the zeroth-order algorithms to find an universal structured adversarial perturbation x ∈ Rd that could fool the samples {ai ∈ Rd , li ∈ N}ni=1 , which can be regarded as the following problem:
1 20news is from https://cs.nyu.edu/∼roweis/data.html; others are from www.csie.ntu.edu.tw/∼cjlin/libsvmtools/datasets/.
where F(a) represents the final layer output before softmax of neural network, and h(x) ensures the validness of created adversarial examples. Specifically, h(x) = 0 if ai + x ∈ [0, 1]d for all i ∈ [n] and ∥x∥∞ ≤ ϵ, otherwise h(x) = ∞. Following [Xu et al., 2018], we use the overlapping lasso to obtain structured perturbations. Here, the overlapping groups {Gp,q}, p = 1, · · · , P, q = 1, · · · ,Q generate from dividing an image into sub-groups of pixels.
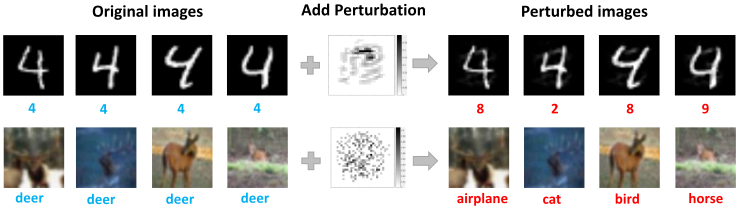
In the experiment, we use the pre-trained DNN models on MNIST and CIFAR-10 as the target black-box models, which can attain 99.4% and 80.8% test accuracy, respectively. For MNIST, we select 20 samples from a target class and set batch size b = 4; For CIFAR-10, we select 30 samples and set b = 5. In the experiment, we set µ = 1 d√t , where d = 28×28 and d = 3×32×32 for MNIST and CIFAR-10, respectively. At the same time, we set the parameters ϵ = 0.4, τ1 = 1, τ2 = 2 and τ3 = 1. For both datasets, the kernel size for overlapping group lasso is set to 3 × 3 and the stride is one.
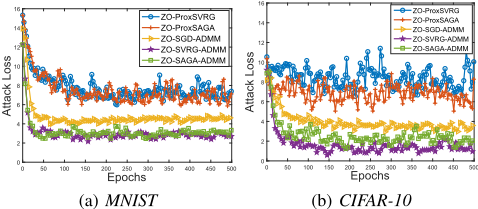
Figure 3 shows that attack losses (i.e. the first term of the problem (7)) of our methods faster decrease than the other methods, as the number of iteration increases. Figure 2 shows that our algorithms can learn some structure perturbations, and can successfully attack the corresponding DNNs.
7 Conclusions
In the paper, we proposed fast ZO-SVRG-ADMM and ZOSAGA-ADMM methods based on the coordinate smoothing gradient estimator, which only uses the objective function values to optimize. Moreover, we prove that the proposed methods have a convergence rate of O( 1 T ). In particular, our methods not only reach the existing best convergence rate O( 1 T ) for the nonconvex optimization, but also are able to effectively solve many machine learning problems with the complex nonsmooth regularizations.
Acknowledgments
F.H., S.G., H.H. were partially supported by U.S. NSF IIS 1836945, IIS 1836938, DBI 1836866, IIS 1845666, IIS 1852606, IIS 1838627, IIS 1837956. S.C. was partially supported by the NSFC under Grant No. 61806093 and No. 61682281, and the Key Program of NSFC under Grant No. 61732006.
@inproceedings{ijcai2019p354,
  title     = {Zeroth-Order Stochastic Alternating Direction Method of Multipliers for Nonconvex Nonsmooth Optimization},
  author    = {Huang, Feihu and Gao, Shangqian and Chen, Songcan and Huang, Heng},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2549--2555},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/354},
  url       = {https://doi.org/10.24963/ijcai.2019/354},
}
TY - CPAPER TI - Zeroth-Order Stochastic Alternating Direction Method of Multipliers for Nonconvex Nonsmooth Optimization AU - Huang, Feihu AU - Gao, Shangqian AU - Chen, Songcan AU - Huang, Heng T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2549 EP - 2555 DO - 10.24963/ijcai.2019/354 UR - https://doi.org/10.24963/ijcai.2019/354 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





