
Accelerating Extreme Classification via Adaptive Feature Agglomeration
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2600-2606.
https://doi.org/10.24963/ijcai.2019/361
Keywords
- Machine Learning: Feature Selection ; Learning Sparse Models
- Machine Learning: Multi-instance;Multi-label;Multi-view learning
- Machine Learning: Classification
Abstract
Extreme classification seeks to assign each data point, the most relevant labels from a universe of a million or more labels. This task is faced with the dual challenge of high precision and scalability, with millisecond level prediction times being a benchmark. We propose DEFRAG, an adaptive feature agglomeration technique to accelerate extreme classification algorithms. Despite past works on feature clustering and selection, DEFRAG distinguishes itself in being able to scale to millions of features, and is especially beneficial when feature sets are sparse, which is typical of recommendation and multi-label datasets. The method comes with provable performance guarantees and performs efficient task-driven agglomeration to reduce feature dimensionalities by an order of magnitude or more. Experiments show that DEFRAG can not only reduce training and prediction times of several leading extreme classification algorithms by as much as 40%, but also be used for feature reconstruction to address the problem of missing features, as well as offer superior coverage on rare labels.
- [Babbar and Schölkopf, 2017] Rohit Babbar and Bernhard Schölkopf. DiSMEC -Distributed Sparse Machines for Extreme Multi-label Classification. In 10th ACM Inter- national Conference on Web Search and Data Mining (WSDM), 2017.
- [Babbar and Schölkopf, 2019] Rohit Babbar and Bernhard Schölkopf. Data Scarcity, Robustness and Extreme Multi-label Classification. Machine Learning, 2019. https://doi.org/10.1007/s10994-019-05791-5. DOI
- [Banerjee and Ghosh, 2006] Arindam Banerjee and Joydeep Ghosh. Scalable Clustering Algorithms with Balancing Constraints. Data Mining and Knowledge Discovery, 13(3):365-395, 2006.
- [Bhatia et al., 2015] Kush Bhatia, Himanshu Jain, Purushot- tam Kar, Manik Varma, and Prateek Jain. Sparse Local Embeddings for Extreme Multi-label Classification. In 29th Annual Conference on Neural Information Process- ing Systems (NIPS), 2015.
- [Bhatia et al., 2019] Kush Bhatia, Kunal Dahiya, Himanshu Jain, Yashoteja Prabhu, and Manik Varma. The Ex- treme Classification Repository. http://manikvarma.org/ downloads/XC/XMLRepository.html, 2019. Retrieved on February 15, 2019. Link
- [Chen and Cai, 2011] Xinlei Chen and Deng Cai. Large Scale Spectral Clustering with Landmark-Based Repre- sentation. In 25th AAAI Conference on Artificial Intelli- gence (AAAI), 2011.
- [Dhillon et al., 2003] Inderjit S. Dhillon, Subramanyam Mallela, and Rahul Kumar. A Divisive Information- Theoretic Feature Clustering Algorithm for Text Classi- fication. Journal of Machine Learning Research, 3:1265- 1287, 2003.
- [Jain et al., 2016] Himanshu Jain, Yashoteja Prabhu, and Manik Varma. Extreme Multi-label Loss Functions for Recommendation, Tagging, Ranking & Other Missing La- bel Applications. In 22nd ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD), 2016.
- [Jasinska et al., 2016] Kalina Jasinska, Krzysztof Dem- bczyński, Róbert Busa-Fekete, Karlson Pfannschmidt, Timo Klerx, and Eyke Hüllermeier. Extreme F-Measure Maximization using Sparse Probability Estimates. In 33rd International Conference on Machine Learning (ICML), 2016.
- [Liu et al., 2017] Hanyang Liu, Junwei Han, Feiping Nie, and Xuelong Li. Balanced Clustering with Least Square Regression. In 31st AAAI Conference on Artificial Intelli- gence (AAAI), 2017.
- [Pennington et al., 2014] Jeffrey Pennington, Richard Socher, and Christopher D. Manning. GloVe: Global Vectors for Word Representation. In Conference on Empirical Methods in Natural Language Processing (EMNLP), 2014.
- [Prabhu and Varma, 2014] Yashoteja Prabhu and Manik Varma. FastXML: A Fast, Accurate and Stable Tree- classifier for eXtreme Multi-label Learning. In 20th ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD), 2014.
- [Prabhu et al., 2018] Yashoteja Prabhu, Anil Kag, Shruten- dra Harsola, Rahul Agrawal, and Manik Varma. Parabel: Partitioned Label Trees for Extreme Classification with Application to Dynamic Search Advertising. In 27th In- ternational World Wide Web Conference (WWW), 2018.
- [Siblini et al., 2018] Wissam Siblini, Pascale Kuntz, and Frank Meyer. CRAFTML, an Efficient Clustering-based Random Forest for Extreme Multi-label Learning. In 35th International Conference on Machine Learning (ICML), 2018.
- [Tagami, 2017] Yukihiro Tagami. AnnexML: Approximate Nearest Neighbor Search for Extreme Multi-label Classi- fication. In 23rd ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD), 2017.
- [Wei and Li, 2018] Tong Wei and Yu-Feng Li. Does Tail La- bel Help for Large-Scale Multi-Label Learning. In 27th In- ternational Joint Conference on Artificial Intelligence (IJ- CAI), 2018. IJCAI
- [Weston et al., 2013] Jason Weston, Ameesh Makadia, and Hector Yee. Label Partitioning For Sublinear Ranking. In 30th International Conference on Machine Learning (ICML), 2013.
- [Yen et al., 2017] Ian E. H. Yen, Xiangru Huang, Wei Dai, Pradeep Ravikumar, Inderjit S. Dhillon, and Eric Xing. PPDSparse: A Parallel Primal-Dual Sparse Method for Extreme Classification. In 23rd ACM SIGKDD Confer- ence on Knowledge Discovery and Data Mining (KDD), 2017.
- [Yu et al., 2014] Hsiang-Fu Yu, Prateek Jain, Purushottam Kar, and Inderjit S. Dhillon. Large-scale Multi-label Learning with Missing Labels. In 31st International Con- ference on Machine Learning (ICML), 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The task of taking assigning data points, one or more labels from a vast universe of millions of labels is often referred to as the extreme classification problem. Although reminiscent of the classical multi-label learning problem, the emphasis on addressing extremely large label spaces distinguishes extreme classification. Recent advances in extreme classification have allowed problems such as ranking, recommendation and retrieval to be viewed and formulated as multi-label problems, indeed with millions of labels.
This focus on extremely large label sets has given us stateof-the-art methods for product recommendation [Jain et al., 2016], search advertising [Prabhu et al., 2018], and video recommendation [Weston et al., 2013], as well as led to advances in our understanding of scalable optimization [Prabhu et al., 2018], and distributed and parallel processing [Yen et al., 2017; Babbar and Sch¨olkopf, 2017]. Recent advances have utilized a variety of techniques - label embeddings, random forests, binary relevance, which we review in §3.
Nevertheless, extreme classification algorithms continue to face several challenges that we enumerate below.
- Precision: data points often have very few labels relevant to them (e.g. of the millions of products on sale, very few products would interest any given customer). It is challenging to accurately identify these few relevant labels among the millions of irrelevant ones.
- Prediction: for use in live recommendation systems, extremely rapid predictions are expected, typically within milliseconds. This often restricts the algorithmic techniques that can be used, to computationally frugal ones.
- Processing: extreme classification datasets often contain millions of data points, each represented as a million-dimensional vector itself. It is challenging to offer scalable training on such large datasets.
- Parity: huge label sets exhibit power-law behavior with most labels being rare i.e. relevant to very few data points. This causes algorithms to focus only on popular labels, neglecting the vast majority of rare ones. However, this is detrimental for recommendation outcomes.
1.1 Our Contributions
In this work, we develop the DEFRAG method and variants to address these specific challenges for a large family of algorithms. Our contributions are summarized below.
- We propose the DEFRAG algorithm that accelerates extreme classification algorithms by performing efficient feature agglomeration on datasets with millions of features. DEFRAG performs agglomeration by constructing a balanced hierarchy which offers faster and better agglomerates than traditional clustering methods.
- We show that DEFRAG provably preserves the performance of several extreme classification algorithms.
- We exploit DEFRAG's agglomerates in a novel manner to develop the REFRAG algorithm to address the parity problem by performing efficient label re-ranking. This vastly improves the coverage of existing algorithms by accurately predicting extremely rare labels.
- We develop the FIAT algorithm to perform scalable feature imputation which preserves prediction accuracy even when a large fraction of data features are removed.
- We perform extensive experimentation on large-scale datasets to establish that DEFRAG not only offers significant reductions in training and prediction times, but that it does so with little or no reduction in precision.
2 ProblemFormulation and Notation
The training data will be provided as n labeled data points (xi , yi ), i = 1, . . . , n where xi ∈ Rd is the feature vector and yi ∈ {0, 1}L is the label vector. There may be several (upto L) labels associated with each data point. Extreme classification datasets exhibit extreme sparsity in feature and label vectors. Let ˆ d denote the average number of non-zero features per data point and ˆL denote the average number of active labels per data point. §6 shows that ˆ d ≪ d and ˆL ≪ L. We will denote the feature matrix using X = [x1 , . . . , xn ] ∈ Rd×n and the label matrix using Y = [y1 , . . . , yn ] ∈ {0, 1}L×n .
Let F = {F1, . . . , FK} denote any K-partition of the feature set [d] i.e. Fi ∩ Fj = ∅ if i ̸= j and ⋃Kk=1 Fk = [d]. Let dk := |Fk| denote the size of the kth cluster. For any vector z ∈ Rd , let zj denote its j th coordinate. For any set Fk ∈ F, let zFk := [zj]⊤j∈Fk ∈ Rdk denote the (shorter) vector containing only coordinates from the set Fk.
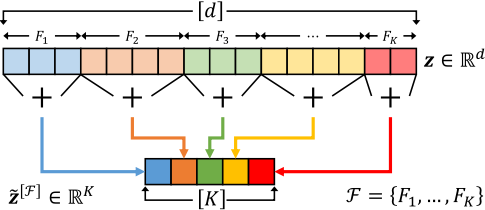
Feature Agglomeration. This involves creating clusters of features and then summing up features within a cluster. If F is a partition of the features [d], then for every cluster Fk ∈ F, we create a a single "super"-feature. Thus, given a vector z ∈ Rd , we can create an agglomerated vector ˜z[F] ∈ RK (abbreviated to just ˜z for sake of notational simplicity) with just K features using the clustering F. The kth dimension of ˜z will be ˜zk = ∑j∈Fk zi for k = 1, . . . ,K. The DEFRAG algorithm will automatically learn relevant feature clusters F.
3 RelatedWorks
We discuss relevant works in extreme classification and scalable clustering and feature agglomeration techniques here.
Binary Relevance. Also known as one-vs-all methods, these techniques, for example DiSMEC [Babbar and Sch¨olkopf, 2017], PPDSparse [Yen et al., 2017], and ProXML [Babbar and Sch¨olkopf, 2019], learn L binary classifiers: for each label l ∈ [L], a binary classifier is learnt to distinguish data points that contain label l from those that do not. Binary relevance methods offer some of the highest precision values among extreme classification algorithms [Prabhu et al., 2018]. However, despite advances in parallel training and active set methods, they still incur training and prediction times that are prohibitive for most applications.
Label/Feature Embedding. These techniques project feature and/or label vectors onto a low dimensional space i.e. xi ↦→ ˆxi , yi ↦→ ˆyi where ˆxi , ˆyi ∈ Rp , p ≪ min{d,L} using random or learnt projections. Prediction and training is performed in the low dimensional space Rp for speed. These methods SLEEC [Bhatia et al., 2015], AnnexML [Tagami, 2017] and LEML [Yu et al., 2014] offer strong theoretical guarantees, but are usually forced to choose a moderate value of p to maintain scalability. This often results in low precision values and causes these methods to struggle on rare labels.
Data Partitioning. These techniques learn a decision tree over the data points which are hierarchically clustered into several leaves, with the hope that the similar data points, i.e. those with similar label vectors, end up in the same leaf. A simple classifier (usually constant) performs label prediction at a leaf. These methods PfastreXML [Jain et al., 2016], FastXML [Prabhu and Varma, 2014] and CRAFTML [Siblini et al., 2018] offer fast prediction times due to prediction being logarithmic in number of leaves in a balanced tree.
Label Partitioning. These methods instead learn to organize labels into (overlapping) clusters, using hierarchical partitioning techniques. Prediction is done by taking a data point to one or more of the leaves of the tree and using a simple method such as 1-vs-all among labels present at that leaf. These methods PLT [Jasinska et al., 2016], Parabel [Prabhu et al., 2018], LPSR [Weston et al., 2013] offer fast prediction times due to the tree structure, as well as high precision by using a 1-vs-all classifier at the leaves, as Parabel does.
Large Scale (Feature) Clustering. Clustering, as well as feature clustering and agglomeration, are well-studied topics. Past works include techniques for scalable balanced k-means using alternating minimization techniques SCBC [Banerjee and Ghosh, 2006] and BCLS [Liu et al., 2017], scalable spectral clustering using landmarking LSC [Chen and Cai, 2011], and scalable information-theoretic clustering ITDC [Dhillon et al., 2003]. We do compare DEFRAG against all these algorithms. These algorithms were chosen since they were able to scale to at least the smallest datasets in our experiments.
4 DEFRAG: aDaptive Extreme FeatuRe AGglomeration
We now describe the DEFRAG method, discuss its key advantages and then develop the REFRAG method for rare label prediction and the FIAT method for feature imputation. Recall from §2 that given a K-partition F of the features [d], feature agglomeration takes each cluster Fk ∈ F and agglomerates all features j ∈ Fk by summing up their feature values.
Given a dataset with d-dimensional features, DEFRAG first clusters these features into balanced clusters, with each cluster containing, say no more than d0 features. Suppose this process results in K clusters. DEFRAG then uses feature agglomeration (see §2 and Figure 1) to obtain K-dimensional features for all data points in the dataset which are then used for training and testing.
Algorithm 1 DEFRAG: Make-Tree
Input: Feature set S ⊆ [d], representative vectors zi ∈ Rp for each feature i ∈ S, maximum leaf size d0
Output: A tree with each leaf having upto d0 features
- 1: if |S| ≤ d0 then
- 2: n←Make-Leaf(S)
- // No need to split
- 3: else
- 4: n←Make-Internal-Node()
- 5: {S+, S-} ←Balanced-Split(S, {zi , i ∈ S}) // Balanced k-means or nDCG split
- 6: n+ ←Make-Tree(S+, {zi , i ∈ S+} , d0)
- 7: n- ←Make-Tree(S+, {zi , i ∈ S-} , d0)
- 8: n.Left-Child ←n+
- 9: n.Right-Child ←n-
- 10: end if
- 11: return Root node of this tree n
DEFRAG first creates a representative vector for each feature j ∈ [d] and then performs hierarchical clustering on them (see Algorithm 1) to obtain feature clusters. At each internal node of the hierarchy, features at that node are split into two children nodes of equal sizes by solving either a balanced spherical 2-means problem or else by minimizing a ranking loss like nDCG [Prabhu and Varma, 2014] which we call DEFRAG-N (please see the full version for details). This process is continued till we are left with less than d0 features at a node, in which case the node is made a leaf. We now discuss two methods to construct these representative vectors.
DEFRAG-X. This variant clusters together co-occurrent features e.g. j, j ′ ∈ [d] where data points with a non-zero (or high) value for feature j also have a non-zero (or high) value for feature j ′ . DEFRAG-X represents each feature j ∈ [d] as an n-dimensional vector pj = [x1j , . . . , xnj ]⊤ ∈ Rn , i.e. as a list of values that feature takes in all data points.
DEFRAG-XY. This variant clusters together co-predictive features e.g. j, j ′ ∈ [d] where data points where feature j is non-zero have similar labels as data points where feature j ′ is non-zero. To do so, DEFRAG-XY represents each feature j ∈ [d] as an L-dimensional vector qj = ∑ni=1 xij yi ∈ RL, essentially as a weighted aggregate of the label vectors of data points where the feature j is non-zero.
4.1 Advantages of DEFRAG
DEFRAG suits high-dim., sparse data better than dimensionality reduction techniques like PCA or random projection.
- Applying feature agglomeration to a vector involves summing up the coordinates of that vector and is much cheaper than performing PCA or a random projection.
- Linear projections densify vectors and so methods like LEML and SLEEC are compelled to use a small embedding dimension (≈ 500) for sake of scalability which leads to information loss. Feature agglomeration, however, does not densify vectors: if a vector x ∈ Rd has only s non-zero coordinates, then for any feature Kclustering F, the vector ˜x[F] ∈ RK cannot have more than s non-zero coordinates. This allows DEFRAG to
operate with relatively large values of K (e.g. K = d/8 is default in our experiments as we set d0 = 8) without worrying about memory or time issues. DEFRAG thus offers mildly agglomerated vectors which preserve much of the information of the original vector, yet offer speedups due to the reduced dimensionality.
- Feature agglomeration has an implicit weight-tying effect: a linear model learnt over the agglomerated features effectively places the same weight over all features belonging to a cluster Fk ∈ F. This reduces the capacity of the model and can improve generalization error.
§5 shows that feature agglomeration using a feature clustering F with small clustering error provably preserves the performance of all linear models. Specifically, for every model w ∈ Rd over the original vectors, there must exist a model ˜w ∈ RK over the agglomerated vectors such that for any vector x ∈ Rd , we have w⊤x ≈ ˜w⊤ ˜x[F] . Thus, similar 1-vs-all models, trees and label partitions can be learnt over ˜x[F] . We note that all algorithms discussed in §3 ultimately use just linear models as components (e.g. binary relevance methods learn L linear classifiers - one per label, embedding methods learn linear projections, data and label partitioning methods learn linear models to split internal tree nodes, etc.).
Task adaptivity. DEFRAG-XY takes into account labels in its feature representation which makes it task-adaptive as compared to dimensionality reduction or clustering methods like k-means, PCAwhich do not take consider labels. Indeed, we will see that on many datasets, DEFRAG-XY outperforms DEFRAG-X which also does not take labels into account.
Novelty, Speed and Scalability. Hierarchical feature agglomeration is novel in the context of extreme classification although hierarchical data partitioning (Parabel) and hierarchical label partitioning (PfastreXML) have been successfully attempted before. The representative vectors created by DEFRAG are themselves sparse and hierarchical feature agglomeration offers speedy feature clustering. DEFRAG's overhead on the training process is thus, very small.
Time Complexity. Let nnz(X) = n · ˆ d be the number of non-zero elements in the feature matrix X. Computing the feature representations pj , j ∈ [d] takes O(nnz(X)) time. The total time taken to perform balanced spherical 2means clustering for all nodes at a certain level in the tree is O(nnz(X)) as well. Since DEFRAG performs balanced splits, there can be at most O(log d) levels in the tree, thus giving us a total time complexity of O (nnz(X) log d).
4.2 FIAT: Feature Imputation via AgglomeraTion
Co-occurrence based feature imputation is popularly used to overcome the problem of missing features. However, this becomes prohibitive for extreme classification settings since the standard co-occurrence matrix C = XX⊤ is too dense to store and operate. We exploit the feature clusters offered by DEFRAG to create a scalable co-occurrence based feature imputation algorithm FIAT. For any feature cluster Fk ∈ F let XFk ∈ Rd×n denote the matrix with only those rows that belong to the cluster Fk. Given this, we compute a pseudo co-occurrence matrix C F = ∑Kk=1 XFk X⊤ Fk ∈ Rd×d .
Note that C F has a block-diagonal structure and has only upto d2 K non-zero entries where K is the number of clusters. Thus, it is much cheaper to store and operate. Given a feature vector x ∈ Rd that we suspect has missing features, we perform feature imputation on it by simply calculating C F x.
4.3 REFRAG: REranking via FeatuRe AGglomeration
Algorithms frequently neglect rare labels (that occur in very few data points) in favor of popular ones [Wei and Li, 2018]. To address this, we propose an efficient re-ranking solution based on the pseudo co-occurrence matrix C F described earlier. First compute the matrix product C F XY ⊤ ∈ Rd×L. The lth column of this matrix l ∈ [L] can be interpreted as giving us a prototype data point ξl ∈ Rd for the label l.
These prototypes can be used to get the affinity score of a test data point xt to a label l ∈ [L] as e- γ2 ·‖xt-ξl ‖22. Once a base classification algorithm such as Parabel or DiSMEC has given scores for the test point xt with respect to various labels, instead of predicting the labels with the highest scores right-away, we combine the classifier scores with these affinity scores and then make the predictions. We note that a similar approach was proposed by [Jain et al., 2016] who did achieve enhanced performance on rare labels.
However, whereas their method requires an optimization problem to be solved to obtain the prototypes, we have a closed form expression for prototypes in our model given the efficiently computable pseudo co-occurrence matrix C F .
Due to lack of space, further algorithmic details as well as proofs of theorems in §5 are presented in the full version of the paper available at the URL given below.
Full Version Link: http://arxiv.org/abs/1905.11769
5 Performance Guarantees
In this section we establish that DEFRAG provably preserves the performance of extreme classification algorithms. For any vector v ∈ Rp we will utilize the orthogonal decomposition v = v‖ + v⊥ where v‖ is the component of v along the allones vector 1p = (1, . . . , 1) ∈ Rp and v⊥ is the component orthogonal to it i.e. 1⊤p v⊥ = 0. At the core of our results is the following lemma. Given a real valued matrix Z ∈ Rd×p for some p > 0 and a K-partition F of the feature set [d], we will let Zk ∈ Rdk×p denote the matrix formed out of the rows of the matrix that correspond to the partition Fk.
Lemma 1. Given any matrix Z ∈ Rd×p and any Kpartition F = {F1, . . . , FK} of [d], suppose there exist vectors µ1 , . . . , µK ∈ Rp such that Zk = 1dk (µk )⊤ +∆k where 1dk := (1, . . . , 1)⊤ ∈ Rdk , then for every w ∈ Rd and every k ∈ [K], there must exist a real value cw,k ∈ R such that
Lemma 1 will be used to show below that, if a group of features is "well-clustered", then it is possible to tie together weights corresponding to those features in every linear model.
suppose we obtain a feature K-partition F = [F1, . . . , FK] with errk denoting the Euclidean clustering error within the kth cluster, then for any loss function ℓ(·) that is L-Lipschitz and for every linear model w ∈ Rd , there must exist a model ˜w ∈ RK such that for all subsets of data points S ⊆ [n],
To simplify this result, let w0 = maxk∈[K] ∥∥w⊥ Fk ∥∥22 ≤ maxk∈[K] ‖wFk ‖22 (since cluster sizes dk are typically small, w0 is small too) and use the fact that errk ≥ 0 to get
In the full version, we show that DEFRAG-XY preserves the performance of label clustering methods such as Parabel. A few points are notable about the above results.
UniformModel Preservation. Theorem 2 guarantees that if the clustering error is small (and DEFRAG does minimize clustering error), then for every possible linear model w ∈ Rd over the original features xi , we can learn a model ˜w ∈ Rd over the agglomerated features ˜xi such that both models behave similarly with respect to any Lipschitz loss function. Note that Theorem 2 holds simultaneously for all linear models w, and is thus, agnostic to the algorithm used to learn w.
Classifier Preservation. Most leading algorithms (Parabel, DiSMEC, PfastreXML, PPDSparse, SLEEC) construct classifiers by learning several linear models using hinge loss, exponential loss etc. which are Lipschitz. By preserving the performance of all such individual linear models, DEFRAG preserves the overall performance of these algorithms too. Note that Theorem 2 holds uniformly over all subsets S ⊆ [n] of data points, which is useful since these algorithms often learn several linear models on various subsets of the data.
Graceful Adaptivity. Suppose for a model w, the weights within a cluster Fk are similar i.e. wFk ≈ w · 1dk ,w ∈ R. Then this implies w⊥ Fk ≈ 0 and the contribution of this cluster to the total error will be very small. This indicates that if some of the original weights are anyway tied together, DEFRAG automatically offers extremely accurate reconstructions.
6 Experimental Results
We studied the effects of using DEFRAG variants with several extreme classification algorithms, as well as compared DEFRAG with other clustering algorithms. Our implementation of DEFRAG is available at the URL given below.
Code Link: https://github.com/purushottamkar/defrag/
Datasets and benchmark implementations. All datasets, train-test splits, and implementations of extreme classification algorithms were sourced from the Extreme Classification Repository [Bhatia et al., 2019]. Implementations of clustering algorithms were sourced from the respective authors whenever possible. For SCBC, LSC and ITDC, public implementations were not available and scalable implementations were created in the Python language.
| Method | LMI | Bal. | Ent. | Time (min) | P1(%) | P3(%) | P5(%) |
|---|---|---|---|---|---|---|---|
| EURLex-4K | |||||||
| ITDC | 0.47 | Inf | 0.87 | 0.7 | 73.85 | 59.63 | 49.19 |
| SCBC | 0.39 | 321 | 0.75 | 0.55 | 71.96 | 59.50 | 49.41 |
| LSC | 0.60 | 130 | 0.93 | 5.7 | 71.44 | 58.68 | 48.71 |
| BCLS | 0.50 | Inf | 0.91 | 2.5 | 74.14 | 60.96 | 50.53 |
| DEFRAG-X | 0.37 | 1.11 | 0.99 | 0.03 | 78.97 | 65.68 | 54.46 |
| Wiki10-31K | |||||||
| ITDC | 0.52 | Inf | 0.88 | 23 | 82.03 | 69.72 | 60.07 |
| DEFRAG-G | 0.46 | 1.08 | 0.99 | 0.48∗ | 82.72 | 69.62 | 60.23 |
| DEFRAG-X | 0.36 | 1.08 | 0.99 | 0.45 | 84.99 | 73.47 | 63.91 |
∗The clustering time for DEFRAG-G does not include time taken to extract (dense) GloVe word features from raw text.
Hyperparameters. If available, hyperparameter settings recommended by authors were used for all methods. If unavailable, a fine grid search was performed over a reasonable range to offer adequately tuned hyperparameters to the methods. DEFRAG had its only hyperparameter, the max size of a feature cluster d0 (see Algorithm 1), fixed to 8.
Comparison with other clustering methods. Table 1 compares DEFRAG with other clustering algorithms on clustering quality, execution time and classification performance (please see the full version for definitions of clustering metrics). Features were agglomerated according to feature clusters given by all algorithms and Parabel was executed on them. DEFRAG handily outperforms all other methods.
Dataset-wise and method-wise performance. Table 3 presents the outcome of using DEFRAG with several leading algorithms on 8 datasets. On Wiki10 and Delicious, DEFRAG-XY+Parabel offers the best overall performance across all methods. More generally, the table shows 21 instances, across the 8 datasets, of how DEFRAG performs with various algorithms. In 3 of these instances, DEFRAG outperforms the base method (EURLex-PPDSparse, Wiki10Parabel and Delicious-Parabel), in 7 others, DEFRAG lags by less than 2.5%, in 8 others, it lags by less than 5%. Only in 3 cases is the lag > 5%. DEFRAG variants do seem to work best with the Parabel method.
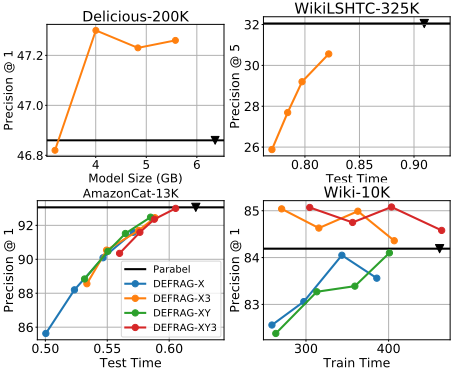
Trade-offs offered by DEFRAG. It is easy to see that if we create a small number of clusters K, by setting d0 to be a large value, then the agglomerated vectors will be lower dimensional and as such, offer faster training/prediction and smaller model sizes. However this may cause a dip in prediction accuracy. Figure 2 shows that DEFRAG variants offer attractive trade-offs in this respect.
| Method | P1 | P3 | P5 | N1 | N3 | N5 |
|---|---|---|---|---|---|---|
| Wiki-10K | ||||||
| PfastReXML‖ REFRAG | 19.02 20.56 | 18.34 19.51 | 18.43 19.26 | 19.02 20.56 | 18.49 19.74 | 18.52 19.54 |
| Delicious-200K | ||||||
| PfastReXML‖ REFRAG | 3.15 7.34 | 3.87 8.05 | 4.43 8.66 | 3.15 7.34 | 3.68 7.86 | 4.06 8.27 |
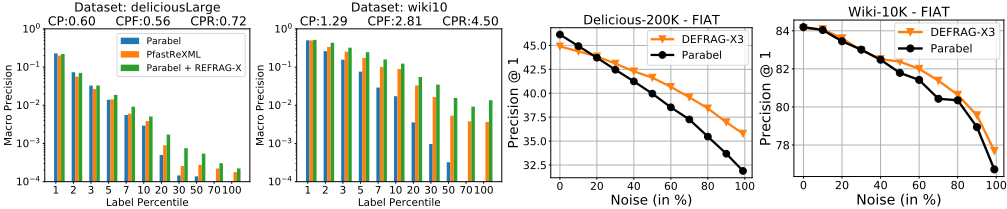
Rare-label prediction with REFRAG. Table 2 shows that REFRAG offers much better propensity-weighted metrics [Jain et al., 2016] (which down-weigh popular and emphasize rare labels) than PfastreXML which also attempts label re-ranking. Figure 3 shows that REFRAG achieves much better coverage (3.85) than Parabel (1.23) on Delicious and in general, predicts rare labels far more accurately. Figure 3 also shows that FIAT offers resilience to feature erasures.
Acknowledgments
The authors thank the reviewers for comments on improving the presentation of the paper. The authors are also thankful to the lab-team members at the CSE department, IIT Kanpur esp. M. Bagga, S. Malhotra, N. Yadav, B. K. Mishra for their support in running the experiments. P. K. thanks Microsoft Research India and Tower Research for research grants.
| Method | P1(%) | P3(%) | P5(%) | Total Time (hr) | Train Time (hr) | Test Time (ms) | Model Size (GB) | Method | P1(%) | P3(%) | P5(%) | Total Time (hr) | Train Time (hr) | Test Time (ms) | Model Size (GB) |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AmazonCat-13K | |||||||||||||||
| PfastReXML DEFRAG-X | 70.41 68.50 | EURLex-4K 59.22 56.57 | 50.56 47.78 | 0.07 0.05 | 0.07 0.05 | 1.26 1.55 | 0.26 0.19 | PfastReXML DEFRAG-X | 85.56 84.71 | 75.19 73.48 | 62.84 61.19 | 11.66 7.01 | 11.66 7.00 | 0.54 0.53 | 19.02 16.17 |
| SLEEC DEFRAG-X | 72.96 67.89 | 56.03 51.55 | 45.49 42.04 | 0.06 0.03 | 0.06 0.03 | 1.62 1.05 | 0.70 0.31 | Dismec† DEFRAG-X | 93.80 89.39 | 79.07 74.90 | 64.05 60.67 | 6.68 4.19 | 6.68 4.18 | 1.45 0.89 | 6.0 1.1 |
| Dismec DEFRAG-X | 82.85 79.12 | 70.37 66.39 | 58.69 54.97 | 0.04 0.02 | 0.04 0.02 | 1.1 0.5 | 0.08 0.02 | Parabel DEFRAG-X | 93.06 91.70 | 79.15 77.25 | 64.51 62.79 | 0.43 0.44 | 0.43 0.40 | 0.62 0.57 | 0.61 0.39 |
| PPDSparse DEFRAG-X | 72.90 71.40 | 57.1 57.9 | 45.8 47.4 | 0.010 0.006 | 0.010 0.006 | 0.03 0.05 | 0.01 0.01 | DEFRAG-XY | 92.36 | 78.20 | 63.55 | 0.43 | 0.40 | 0.58 | 0.38 |
| Delicious-200K | |||||||||||||||
| Parabel DEFRAG-X DEFRAG-XY | 82.28 78.97 79.23 | 68.81 65.68 65.77 | 57.58 54.46 54.65 | 0.010 0.009 0.009 | 0.010 0.008 0.008 | 0.73 0.59 0.59 | 0.03 0.01 0.01 | Parabel DEFRAG-X DEFRAG-XY | 46.86 47.23 47.61 | 40.08 40.53 40.90 | 36.70 37.19 37.66 | 5.33 3.23 3.34 | 5.33 3.16 3.12 | 2.22 1.05 1.06 | 6.36 4.83 |
| ProXML‡ | 83.40 | 70.90 | 59.10 | - | - | - | - | PfastReXML‖ DiSMEC § | 41.72 | 37.83 | 35.58 | - | 4.76 - | ||
| Wiki10-31K | - - 45.50 38.70 35.50 - - - - | ||||||||||||||
| PfastReXML DEFRAG-X | 75.67 69.79 | 64.55 58.54 | 57.35 52.52 | 0.27 0.14 | 0.27 0.13 | 11.94 11.74 | 1.12 0.80 | 58.47 | 37.70 | WikiLSHTC-325K 27.57 | 11.23 | 11.23 | 2.66 | ||
| SLEEC DEFRAG-X | 84.28 83.87 | 72.05 70.35 | 61.80 59.76 | 0.38 0.17 | 0.38 0.17 | 6.00 3.50 | 3.9 2.0 | PfastReXML DEFRAG-X | 50.86 | 32.08 | 23.40 | 6.03 | 6.03 | 2.14 | 14.20 12.82 |
| Dismec DEFRAG-X | 84.12 82.30 | 74.71 72.14 | 65.94 63.78 | 1.48 0.66 | 1.48 0.65 | 42 15 | 7.1 1.5 | Parabel DEFRAG-X DEFRAG-XY | 65.04 59.49 61.38 | 43.24 39.25 40.42 | 32.05 29.20 29.99 | 0.58 0.56 0.54 | 0.58 0.50 0.50 | 0.91 0.79 0.78 | 3.09 2.50 2.44 |
| PPDSparse DEFRAG-X | 74.68 63.55 | 60.03 50.42 | 49.12 41.20 | 0.59 0.50 | 0.59 0.50 | 2.2 3.7 | 0.04 0.03 | PPDSparse‖ DiSMEC § | 64.08 64.40 | 41.26 42.50 | 30.12 31.50 | - - | - - | - - | - - |
| Parabel DEFRAG-X | 84.19 | 72.46 | 63.37 | 0.13 | 0.13 | 2.04 | 0.18 | ProXML‡ | 63.60 | 41.50 | 30.80 | - | - | - | - |
| DEFRAG-XY | 84.99 85.08 | 73.47 73.76 | 63.91 64.06 | 0.10 0.11 | 0.09 0.09 | 1.46 1.47 | 0.14 0.14 | Wikipedia-500K∗ | |||||||
| Amazon-670K | Parabel DEFRAG-X | 68.70 65.15 | 49.57 44.96 | 38.64 34.85 | 5.13 3.27 | 5.13 3.14 | 3.11 1.62 | 5.68 5.25 | |||||||
| PfastReXML DEFRAG-X | 36.90 32.67 | 34.22 30.27 | 32.10 28.40 | 5.70 2.70 | 5.70 2.69 | 6.10 7.21 | 10.98 9.40 | DEFRAG-XY | 64.73 | 44.79 | 34.76 | 3.31 | 3.20 | 1.62 | 5.22 |
| SLEEC DEFRAG-X | 32.48 | 28.87 | 26.31 | 2.22 1.63 | 2.22 1.63 | 1.43 1.62 | 8.0 4.2 | DiSMEC § ProXML‡ | 70.20 69.00 | 50.60 49.10 | 39.70 38.80 | - - | - - | - - | - - |
| 31.40 28.04 25.69 | Amazon-3M∗ | ||||||||||||||
| Parabel DEFRAG-X | 44.92 42.71 | 39.77 37.71 | 35.98 33.93 | 0.24 0.23 | 0.24 0.21 | 0.81 0.76 | 1.94 1.68 | Parabel DEFRAG-X | 47.42 45.68 | 44.66 42.85 | 42.55 40.76 | 3.14 2.93 | 3.14 2.83 | 0.73 0.66 | 31.43 25.34 |
| DEFRAG-XY § | 42.62 | 37.72 | 33.94 | 0.23 | 0.21 | 0.77 | 1.66 | DEFRAG-XY | 45.11 | 42.36 | 40.30 | 2.87 | 2.80 | 0.63 | 25.22 |
| DiSMEC | 44.70 | 39.70 | 36.10 | - - | - | - | - | PfastReXML‖ | 40.09 | - | - | ||||
| ProXML‡ | 43.50 | 38.70 | 35.30 | - | - | - | 43.83 | 41.81 | - | - | |||||
Table 3: DEFRAG's performance when used with various extreme classification algorithms. "Total time" for DEFRAG includes clustering=train time. On EURLex, Wiki10 and Delicious, DEFRAG actually achieves better classification accuracy than the base classifier itself (bold items). DEFRAG allows expensive 1-vs-all methods like DiSMEC and PPDSparse to be executed in a scalable manner with training time reductions of upto 40% on AmazonCat and model size reductions of upto 20% on WikiLSHTC. Precision values on certain datasets are being reported for sake of easy comparison. These were not obtained in our experiments and are being sourced from original publications:
§ [Babbar and Sch¨olkopf, 2017], ‡ [Babbar and Sch¨olkopf, 2019], ‖ [Bhatia et al., 2019].
∗ For all but Wiki-500K and Amazon-3M, DEFRAG was executed in an ensemble of 3 independent realizations (details in the full version).
† Except for DiSMEC on AmazonCat (which required 12 cores to execute scalably), all times are reported on a single core.
@inproceedings{ijcai2019p361,
  title     = {Accelerating Extreme Classification via Adaptive Feature Agglomeration},
  author    = {Jalan, Ankit and Kar, Purushottam},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2600--2606},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/361},
  url       = {https://doi.org/10.24963/ijcai.2019/361},
}
TY - CPAPER TI - Accelerating Extreme Classification via Adaptive Feature Agglomeration AU - Jalan, Ankit AU - Kar, Purushottam T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2600 EP - 2606 DO - 10.24963/ijcai.2019/361 UR - https://doi.org/10.24963/ijcai.2019/361 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





