
Cascading Non-Stationary Bandits: Online Learning to Rank in the Non-Stationary Cascade Model
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2859-2865.
https://doi.org/10.24963/ijcai.2019/396
Keywords
- Machine Learning: Learning Preferences or Rankings
- Multidisciplinary Topics and Applications: Information Retrieval
- Machine Learning: Recommender Systems
- Machine Learning: Online Learning
Abstract
Non-stationarity appears in many online applications such as web search and advertising. In this paper, we study the online learning to rank problem in a non-stationary environment where user preferences change abruptly at an unknown moment in time. We consider the problem of identifying the K most attractive items and propose cascading non-stationary bandits, an online learning variant of the cascading model, where a user browses a ranked list from top to bottom and clicks on the first attractive item. We propose two algorithms for solving this non-stationary problem: CascadeDUCB and CascadeSWUCB. We analyze their performance and derive gap-dependent upper bounds on the n-step regret of these algorithms. We also establish a lower bound on the regret for cascading non-stationary bandits and show that both algorithms match the lower bound up to a logarithmic factor. Finally, we evaluate their performance on a real-world web search click dataset.
- [Auer et al., 1995] Peter Auer, Nicolo Cesa-Bianchi, Yoav Freund, and Robert Schapire. Gambling in a rigged casino: The adversarial multi-armed bandit problem. In FOCS, pages 322-331, 1995.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine Learning, 47:235-256, 2002.
- [Besbes et al., 2014] Omar Besbes, Yonatan Gur, and Assaf Zeevi. Stochastic multi-armed-bandit problem with non- stationary rewards. In NIPS, 2014.
- David Blackwell. An analog of the mini- max theorem for vector payoffs. Pacific Journal of Mathe- matics, 6(1):1-8, November 1956.
- [Cesa-Bianchi and Lugosi, 2006] Nicolo Cesa-Bianchi and Gabor Lugosi. Prediction, Learning, and Games. Cam- bridge University Press, 2006.
- [Chapelle and Zhang, 2009] Olivier Chapelle and Ya Zhang. A dynamic Bayesian network click model for web search ranking. In WWW, pages 1-10, 2009.
- [Chuklin et al., 2015] Aleksandr Chuklin, Ilya Markov, and Maarten de Rijke. Click Models for Web Search. Morgan & Claypool, 2015.
- [Craswell et al., 2008] Nick Craswell, Onno Zoeter, Michael Taylor, and Bill Ramsey. An experimental comparison of click position-bias models. In WSDM, pages 87-94, 2008.
- [Garivier and Moulines, 2008] Aurélien Garivier and Eric Moulines. On upper-confidence bound policies for non-stationary bandit problems. arXiv preprint arXiv:0805.3415, 2008.
- [Garivier and Moulines, 2011] Aurélien Garivier and Eric Moulines. On upper-confidence bound policies for switch- ing bandit problems. In ALT, pages 174-188, 2011.
- [Guo et al., 2009] Fan Guo, Chao Liu, and Yi Min Wang. Efficient multiple-click models in web search. In WSDM, pages 124-131, 2009.
- [Jagerman et al., 2019] Rolf Jagerman, Ilya Markov, and Maarten de Rijke. When people change their mind: Off- policy evaluation in non-stationary recommendation envi- ronments. In WSDM, pages 447-455, 2019.
- [Joachims, 2002] Thorsten Joachims. Optimizing search en- gines using clickthrough data. In SIGKDD, pages 133-142, 2002.
- [Katariya et al., 2016] Sumeet Katariya, Branislav Kveton, Csaba Szepesvari, and Zheng Wen. DCM bandits: Learning to rank with multiple clicks. In ICML, pages 1215-1224, 2016.
- [Kveton et al., 2014] Branislav Kveton, Zheng Wen, Azin Ashkan, Hoda Eydgahi, and Brian Eriksson. Matroid ban- dits: Fast combinatorial optimization with learning. arXiv preprint arXiv:1403.5045, 2014. [Kveton et al., 2015] Branislav Kveton, Csaba Szepesvari, Zheng Wen, and Azin Ashkan. Cascading bandits: Learn- ing to rank in the cascade model. In ICML, pages 767-776, 2015.
- [Lagrée et al., 2016] Paul Lagrée, Claire Vernade, and Olivier Cappe. Multiple-play bandits in the position-based model. In NIPS, 2016.
- [Li et al., 2018] Chang Li, Ilya Markov, Maarten de Rijke, and Masrour Zoghi. Merge double Thompson sampling for large scale online ranker evaluation. arXiv preprint arXiv:1812.04412, 2018.
- [Li et al., 2019] Chang Li, Branislav Kveton, Tor Lattimore, Ilya Markov, Maarten de Rijke, Csaba Szepesvári, and Mas- rour Zoghi. BubbleRank: Safe online learning to rerank. In UAI, 2019.
- [Liu et al., 2018] Fang Liu, Joohyun Lee, and Ness Shroff. A change-detection based framework for piecewise-stationary multi-armed bandit problem. In AAAI, pages 3651-3658, 2018.
- [Liu, 2009] Tie-Yan Liu. Learning to rank for information retrieval. Foundations and Trends in Information Retrieval, 3(3):225-331, 2009.
- [Oosterhuis and de Rijke, 2018] Harrie Oosterhuis and Maarten de Rijke. Differentiable unbiased online learning to rank. In CIKM, pages 1293-1302, 2018.
- [Pereira et al., 2018] Fabíola SF Pereira, João Gama, Sandra de Amo, and Gina MB Oliveira. On analyzing user pref- erence dynamics with temporal social networks. Machine Learning, 107(11):1745-1773, 2018.
- [Qin et al., 2010] Tao Qin, Tie-Yan Liu, Jun Xu, and Hang Li. Letor: A benchmark collection for research on learning to rank for information retrieval. Information Retrieval, 13(4):346-374, 2010.
- [Radlinski et al., 2008] Filip Radlinski, Robert Kleinberg, and Thorsten Joachims. Learning diverse rankings with multi-armed bandits. In ICML, pages 784-791, 2008.
- [Slivkins and Upfal, 2008] Aleksandrs Slivkins and Eli Upfal. Adapting to a changing environment: the brownian restless bandits. In COLT, pages 343-354, 2008.
- [Wu et al., 2018] Qingyun Wu, Naveen Iyer, and Hongning Wang. Learning contextual bandits in a non-stationary environment. In SIGIR, pages 495-504, 2018.
- [Yu and Mannor, 2009] Jia Yuan Yu and Shie Mannor. Piecewise-stationary bandit problems with side observa- tions. In ICML, 2009.
- [Zoghi et al., 2016] Masrour Zoghi, Tomáš Tunys, Lihong Li, Damien Jose, Junyan Chen, Chun Ming Chin, and Maarten de Rijke. Click-based hot fixes for underperforming torso queries. In SIGIR, pages 195-204, 2016.
- [Zoghi et al., 2017] Masrour Zoghi, Tomáš Tunys, Moham- mad Ghavamzadeh, Branislav Kveton, Csaba Szepesvari, and Zheng Wen. Online learning to rank in stochastic click models. In ICML, pages 4199-4208, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Learning to rank LTR [Liu, 2009] is a combination of machine learning and information retrieval. It is a core problem in many applications, such as web search and recommendation [Liu, 2009; Zoghi et al., 2017]. The goal of LTR is to rank items, e.g., documents, and show the top K items to a user. Traditional LTR algorithms are supervised, offline algorithms; they learn rankers from human annotated data [Qin et al., 2010] and/or users' historical interactions [Joachims, 2002]. Every day billions of users interact with modern search engines and leave a trail of interactions. It is feasible and important to design online algorithms that directly learn from such user clicks to help improve users' online experience. Indeed, recent studies show that even well-trained production rankers can be optimized by using users' online interactions, such as clicks [Zoghi et al., 2016].
Generally, interaction data is noisy [Joachims, 2002], which gives rise to the well-known exploration vs. exploitation dilemma. Multi-armed bandit (MAB) [Auer et al., 2002] algorithms have been designed to balance exploration and exploitation. Based on MABs, many online LTR algorithms have been published [Radlinski et al., 2008; Kveton et al., 2015; Katariya et al., 2016; Lagr´ee et al., 2016; Zoghi et al., 2017; Li et al., 2019]. These algorithms address the exploration vs. exploitation dilemma in an elegant way and aim to maximize user satisfaction in a stationary environment where users do not change their preferences over time. Moreover, they often come with regret bounds.
Despite the success of the algorithms mentioned above in the stationary case, they may have linear regret in a nonstationary environment where users may change their preferences abruptly at any unknown moment in time. Nonstationarity widely exists in real-world application domains, such as search engines and recommender systems [Yu and Mannor, 2009; Pereira et al., 2018; Wu et al., 2018; Jagerman et al., 2019]. Particularly, we consider abruptly changing environments where user preferences remain constant in certain time periods, named epochs, but change occurs abruptly at unknown moments called breakpoints. The abrupt changes in user preferences give rise to a new challenge of balancing "remembering" and "forgetting" [Besbes et al., 2014]: the more past observations an algorithm retains the higher the risk of making a biased estimator, while the fewer observations retained the higher stochastic error it has on the estimates of the user preferences.
In this paper, we propose cascading non-stationary bandits, an online variant of the cascade model (CM) [Craswell et al., 2008] with the goal of identifying the K most attractive items in a non-stationary environment. CM is a widely-used model of user click behavior [Chuklin et al., 2015; Zoghi et al., 2017]. In CM, a user browses the ranked list from top to bottom and clicks the first attractive item. The items ranked above the first clicked item are browsed but not attractive since they are not clicked. The items ranked below the first clicked item are not browsed since the user stops browsing the ranked list after a click. Although CM is a simple model, it effectively explains user behavior [Kveton et al., 2015].
Our key technical contributions in this paper are: (1) We formalize a non-stationary online learning to rank (OLTR) problem as cascading non-stationary bandits. (2) We propose two algorithms, CascadeDUCB and CascadeSWUCB, for solving it. They are motivated by discounted UCB (DUCB) and sliding window UCB (SWUCB), respectively [Garivier and Moulines, 2011]. CascadeDUCB balances "remembering" and "forgetting" by using a discounting factor of past observations, and CascadeSWUCB balances the two by using statistics inside a fixed-size sliding window. (3) We derive gap-dependent upper bounds on the regret of the proposed algorithms. (4) We derive a lower bound on the regret of cascading non-stationary bandits. We show that the upper bounds match this lower bound up to a logarithmic factor. (5) We evaluate the performance of CascadeSWUCB and CascadeDUCB empirically on a real-world web search click dataset.
2 Background
We define the learning problem at the core of this paper in terms of cascading non-stationary bandits. Their definition builds on the CM and its online variant cascading bandits, which we review in this section.
We write [n] for ¶1↪ ▷ ▷ ▷ ↪ n♦. For sets A and B, we write AB for the set of all vectors whose entries are indexed by B and take values from A. We use boldface letters to denote random variables. We denote a set of candidate items by D = [L], e.g., a set of preselected documents. The presented ranked list is denoted as R 2 ⇧K(D), where ⇧K(D) denotes the set of all possible combinations of K distinct items from D. The item at position k in R is denoted as R(k), and the position of item a in R is denoted as R-1 (a)
2.1 Cascade Model
We refer readers to [Chuklin et al., 2015] for an introduction to click models. Briefly, a click model models a user's interaction behavior with the search system. The user is presented with a K-item ranked list R. Then the user browses the list R and clicks items that potentially attract him or her. Many click models have been proposed and each models a certain aspect of interaction behavior. We can parameterize a click model by attraction probabilities ↵ 2 [0↪ 1]L and a click model assumes:
Assumption 1. The attraction probability ↵(a) only depends on item a and is independent of other items.
CM is a widely-used click model [Craswell et al., 2008; Zoghi et al., 2017]. In the CM, a user browses the ranked list R from the first itemR(1) to the last itemR(K), which is called the cascading assumption. After the user browses an item R(i), he or she clicks on R(i) with attraction probability ↵(R(i)), and then stops browsing the remaining items. Thus, the examination probability of itemR(j) equals the probability of no click on the higher ranked items: Qj-1 i=1 (1-↵(R(i))). The expected number of clicks equals the probability of clicking any item in the list: 1 - QKi=1 (1 -↵(R(i))). Note that the reward does not depend on the order in R, and thus, in the CM, the goal of ranking is to find the K most attractive items.
The CM accepts at most one click in each search session. It cannot explain scenarios where a user may click multiple items. The CM has been extended in different ways to capture multi-click cases [Chapelle and Zhang, 2009; Guo et al., 2009]. Nevertheless, CM is still the fundamental click model and fits historical click data reasonably well. Thus, in this paper, we focus on the CM and in the next section we introduce an online variant of CM, called cascading bandits.
2.2 Cascading Bandits
Cascading bandits (CB) is defined by a tuple B = (D↪ P↪ K), where D = [L] is the set of candidate items, K L is the number of positions, P 2 ¶0↪ 1♦L is a distribution over binary attractions.
In CB, at time t, a learning agent builds a ranked list Rt 2 ⇧K(D) that depends on the historical observations up to t and shows it to the user. At 2 ¶0↪ 1♦L is defined as the attraction indicator, which is drawn from P and At(Rt(i)) is the attraction indicator of itemRt(i). The user examines Rt fromRt(1) to Rt(K) and clicks the first attractive item. Since a CM allows at most one click each time, a random variable ct is used to indicate the position of the clicked item, i.e., ct = argmini2[K] 1¶At(Rt(i))♦. If there is no attractive item, the user will not click, and we set ct = K+1 to indicate this case. Specifically, if ct K, the user clicks an item, otherwise, the user does not click anything. After the click or browsing the last item in Rt, the user leaves the search session. The click feedback ct is then observed by the learning agent. Because of the cascading assumption, the agent knows that items ranked above position ct are observed. The reward at time t is defined by the number of clicks:
Under Assumption 1, the attraction indicators of each item in D are independently distributed. Moreover, cascading bandits make another assumption.
Assumption 2. The attraction indicators are distributed as:
where Pa is a Bernoulli distribution with a mean of ↵(a).
Under Assumption 1 and 2, the attraction indicator of item a at time t At(a) is drawn independently from other items. Thus, the expectation of reward of the ranked list at time t can be computed as E [r(Rt↪ At] = r(Rt↪ ↵). And the goal of the agent is to maximize the expected number of clicks in n steps.
Cascading bandits are designed for a stationary environment, where the attraction probability P remains constant. However, in real-world applications, users change their preferences constantly [Jagerman et al., 2019], which is called a non-stationary environment, and learning algorithms proposed for cascading bandits, e.g., CascadeKL-UCB and CascadeUCB1 [Kveton et al., 2015], may have linear regret in this setting. In the next section, we propose cascading non-stationary bandits, the first non-stationary variant of cascading bandits, and then propose two algorithms for solving this problem.
3 Cascading Non-Stationary Bandits
We first define our non-stationary online learning setup, and then we propose two algorithms learning in this setup.
3.1 Problem Setup
The learning problem we study is called cascading nonstationary bandits, a variant of CB. We define it by a tuple Algorithm 1: UCB-type algorithm for Cascading nonstationary bandits.
1: Input: discounted factor γ or sliding window size ⌧ 2: // Initialization 3: 8a 2 D : N0(a) = 0 4: 8a 2 D : X0(a) = 0 5: for t = 1↪ 2↪ ▷ ▷ ▷ ↪ n do 6: for a 2 D do 7: // Compute UCBs 8: Ut(a) ⇢Eq. 5 (CascadeDUCB) Eq. 7 (CascadeSWUCB) 9: // Recommend top K items and receive clicks 10: Rt argmaxR2⇧K(D) r(R↪Ut) 11: ShowRt and receive clicks ct 2 ¶1↪ ▷ ▷ ▷ ↪K +1♦ 12: // Update statistics 13: if CascadeDUCB then 14: // for CascadeDUCB 15: 8a 2 D : Nt(a) = γNt-1(a) 16: 8a 2 D : Xt(a) = γXt-1(a) 17: else 18: // for CascadeSWUCB 19: 8a 2 D : Nt(a) = Pt-1 s=t-⌧+1 1¶a 2 Rs♦ 20: 8a 2 D : Xt(a) = Pt-1 s=t-⌧+1 1¶R-1 s (a) = cs♦ 21: for i = 1↪ ▷ ▷ ▷ ↪min¶ct↪K♦ do 22: a Rt(i) 23: Nt(a) =Nt(a) +1 24: Xt(a) =Xt(a) +1¶i = ct♦B = (D↪ P↪K↪⌥n), where D = [L] and K L are the same as in CB bandits, P 2 ¶0↪ 1♦n⇥L is a distribution over binary attractions and ⌥n is the number of abrupt changes in P up to step n. We use Pt(Rt(i)) to indicate the attraction probability distribution of item Rt(i) at time t. If ⌥n = 0, this setup is same as CB. The difference is that we consider a non-stationary learning setup in which ⌥n > 0 and the non-stationarity in attraction probabilities characterizes our learning problem.
In this paper, we consider an abruptly changing environment, where the attraction probability P remains constant within an epoch but can change at any unknown moment in time and the number of abrupt changes up to n steps is ⌥n. The learning agent interacts with cascading non-stationary bandits in the same way as with CB. Since the agent is in a non-stationary environment, we write ↵t for the mean of the attraction probabilities at time t and we evaluate the agent by the expected cumulated regret expressed as:
The goal of the agent it to minimizing the n-step regret.
3.2 Algorithms
We propose two algorithms for solving cascading nonstationary bandits, CascadeDUCB and CascadeSWUCB.
CascadeDUCB is inspired by DUCB and CascadeSWUCB is inspired by SWUCB [Garivier and Moulines, 2011]. We summarize the pseudocode of both algorithms in Algorithm 1.
CascadeDUCB and CascadeSWUCB learn in a similar pattern. They differ in the way they estimate the Upper Confidence Bound (UCB) Ut(Rt(i)) of the attraction probability of itemRt(i) as time t, as discussed later in this section. After estimating the UCBs (line 8), both algorithms construct Rt by including the top K most relevant items by UCB. Since the order of top K items only affects the observation but does not affect the payoff of Rt, we construct Rt as follows:
After receiving the user's click feedback ct, both algorithms update their statistics (line 13-24). We use Nt(i) and Xt(i) to indicate the number of items i that have been observed and clicked up to t step, respectively.
To tackle the challenge of non-stationarity, CascadeDUCB penalizes old observations with a discount factor γ 2 (0↪ 1). Specifically, each of the previous statistics is discounted by γ (line 15-16). The UCB of item a is estimated as:
where ¯↵t(γ↪ a) = Xt(a) Nt(a) is the average of discounted attraction indicators of item i and
is the confidence interval around ¯↵t(i) at time t. Here, we compute Nt(γ) = 1-γ t 1-γ as the discounted time horizon. As shown in [Garivier and Moulines, 2011], ↵t(a) 2 [ ¯↵t(γ↪ a) - ct(γ↪ a)↪ ¯↵t(γ↪ a) + ct(γ↪ a)] holds with high probability.
As to CascadeSWUCB, it estimates UCBs by observations inside a sliding window with size ⌧. Specifically, it only considers the observations in the previous ⌧ steps (line 19-20). The UCB of item i is estimated as
where ¯↵t(⌧↪ a) = Xt(a) Nt(a) is the average of observed attraction indicators of item a inside the sliding window and
is the confidence interval, and t ^ ⌧ = min(t↪ ⌧).
Initialization. In the initialization phase, we set all the statistics to 0 and define x0 := 1 for any x (line 3-4). Mapping back this to UCB, at the beginning, each item has the optimal assumption on the attraction probability with an optimal bonus on uncertainty. This is a common initialization strategy for UCB-type bandit algorithms [Li et al., 2018].
4 Analysis
In this section, we analyze the n-step regret of CascadeDUCB and CascadeSWUCB. We first derive regret upper bounds on CascadeDUCB and CascadeSWUCB, respectively. Then we derive a regret lower bound on cascading non-stationary bandits. Finally, we discuss our theoretical results.
4.1 Regret Upper Bound
We refer to D⇤ t ✓ [L] as the set of the K most attractive items in set D at time t and ¯Dt as the complement of D⇤ t , i.e., 8a 2 D⇤ t ↪ 8a⇤ 2 ¯Dt : ↵t(a) ≥ ↵t(a⇤ ) and D⇤ t [ ¯Dt = D ↪ D⇤ t \ ¯Dt = ;. At time t, we say an item a⇤ is optimal if a⇤ 2 D⇤ t and an item a is suboptimal if a 2 ¯Dt. The regret at time t is caused by the case that Rt includes at least one suboptimal and examined items. Let ∆ta↪a⇤ be the gap of attraction probability between a suboptimal item a and an optimal a⇤ at time t: ∆ta↪a⇤ = ↵t(a⇤ ) -↵t(a). Then we refer to ∆a↪K as the smallest gap of between item a and the K-th most attractive item in all n steps when a is not the optimal items: ∆a↪K = mint2[n]↪a⇤2D⇤ t ↵t(a⇤ ) -↵t(a).
Theorem 1. Let ✏ 2 (1◁2↪ 1) and γ 2 (1◁2↪ 1), the expected n-step regret of CascadeDUCB is bounded as:
where
We outline the proof in 4 steps below; the full version is in Appendix A.1. 1
Proof. Our proof is adapted from the analysis in [Kveton et al., 2015]. The novelty of the proof comes from the fact that, in a non-stationary environment, the discounted estimator ¯↵t(γ↪ a) is now a biased estimator of ↵t(a) (Step 1, 2 and 4).
Step 1. We bound the regret of the event that estimators of the attraction probabilities are biased by L⌥ ln[(1-γ)✏] lnγ . This event happens during the steps following a breakpoint.
Step 2. We bound the regret of the event that ↵t(a) falls outside of the confidence interval around ¯↵t(γ↪ a) by 4 1-1◁e ln (1+4p1-1◁2✏)n(1-γ) ln 1 1-γ .
Step 3. We decompose the regret at time t based on [Kveton et al., 2015, Theorem 1].
Step 4. For each item a, we bound the number of times that item a is chosen when a 2 ¯Dt in n steps and get the term 32✏dn(1-γ)e ln 1 1-γ ∆a↪Kγ 1◁(1-γ) . Finally, we sum up all the regret.
The bound depends on step n and the number of breakpoints ⌥n. If they are known beforehand, we can choose γ by minimizing the right hand side of Eq. 9. Choosing γ = 1 - 1◁4p(⌥n◁n) leads to R(n) = O(pn⌥n lnn). When ⌥n is independent of n, we have R(n) = O(pn⌥ ln n).
Theorem 2. Let ✏ 2 (1◁2↪ 1). For any integer ⌧, the expected n-step regret of CascadeSWUCB is bounded as:
R(n)
1 https://arxiv.org/abs/1905.12370
where
When ⌧ goes to infinity and n◁⌧ goes to 0,
We outline the proof in 4 steps below and the full version is in Appendix A.2.
Proof. The proof follows the same lines as the proof of Theorem 1.
Step 1. We bound the regret of the event that estimators of the attraction probabilities are biased by L⌥n⌧ .
Step 2. We bound the regret of the event that ↵t(a) falls outside of the confidence interval around ¯↵t(⌧↪ a) by
Step 3. We decompose the regret at time t based on [Kveton et al., 2015, Theorem 1].
Step 4. For each item a, we bound the number of times that item a is chosen when a 2 ¯Dt in n steps and get the term 8✏ ∆a↪K d n⌧ e. Finally, we sum up all the regret.
If we know ⌥n and n beforehand, we can choose the window size ⌧ by minimizing the right hand side of Eq. 11. Choosing ⌧ = 2pn ln(n)◁⌥n leads to R(n) = O(pn⌥n ln n). When ⌥n is independent of n, we have R(n) = O(pn⌥ ln n).
4.2 Regret Lower Bound
We consider a particular cascading non-stationary bandit and refer to it as BL = (L↪K↪∆↪ p↪⌥). We have a set of L items D = [L] and K = 12 L positions. At any time t, the distribution of attraction probability of each item a 2 D is parameterized by:
where D⇤ t is the set of optimal items at time t, ¯Dt is the set suboptimal items at time t, and ∆ 2 (0↪ p] is the gap between optimal items and suboptimal items. Thus, the attraction probabilities only take two values: p for optimal items and p -∆ for suboptimal items up to n-step. ⌥ is the number of breakpoints when the attraction probability of an item changes from p to p-∆ or other way around. Particularly, we consider a simple variant that the distribution of attraction probability of each item is piecewise constant and has two breakpoints. And we assume another constraint on the number of optimal items that ♣D⇤ t ♣ = K for all time steps t 2 [n]. Then, the regret that any learning policy can achieve when interacting with BL is lower bounded by Theorem 3.
Theorem 3. The n-step regret of any learning algorithm interacting with cascading non-stationary bandit BL is lower bounded as follows:
where DKL(p-∆♣♣p) is the Kullback-Leibler (KL) divergence between two Bernoulli distributions with means p - ∆ and p.
Proof. The proof is based on the analysis in [Kveton et al., 2015]. We first refer to R⇤t as the optimal list at time t that includes K items. For any time step t, any item a 2 ¯Dt and any item a⇤ 2 D⇤ t , we define the event that item a is included in Rt instead of item a⇤ and item a is examined but not clicked at time step t by:
By [Kveton et al., 2015, Theorem 1], the regret at time t is decomposed as:
Then, we bound the n-step regret as follows:
where Tn(a) = Pnt=1 1¶a 2 ¯Dt↪ a 2 Rt↪R-1 t (a) ct♦. The second inequality is based on the fact that, at time t, the event Gt↪a↪a⇤ happens if and only if item a is suboptimal and examined. By the results of [Garivier and Moulines, 2011, Theorem 3], if a suboptimal item a has not been examined enough times, the learning policy may play this item for a long period after a breakpoint. And we get:
We sum up all the inequalities and obtain:
4.3 Discussion
We have shown that the n-step regret upper bounds of CascadeDUCB and CascadeSWUCB have the order of O(pn lnn)and O(pn lnn), respectively. They match the lower bound proposed in Theorem 3 up to a logarithmic factor. Specifically, the upper bound of CascadeDUCB matches the lower bound up to lnn. The upper bound of CascadeSWUCB
matches the lower bound up to plnn, an improvement over CascadeDUCB, as confirmed by experiments in Section 5.
We have assumed that step n is know beforehand. This may not always be the case. We can extend CascadeDUCB and CascadeSWUCB to the case where n is unknown by using the doubling trick [Garivier and Moulines, 2011]. Namely, for t > n and any k, such that 2k t < 2k+1 , we reset γ = 1- 1 4p2k and ⌧ = 2p2k ln(2k ).
CascadeDUCB and CascadeSWUCB can be computed efficiently. Their complexity is linear in the number of time steps. However, CascadeSWUCB requires extra memory to remember past ranked lists and rewards to update Xt and Nt.
5 Experimental Analysis
We evaluate CascadeDUCB and CascadeSWUCB on the Yandex click dataset, 2 which is the largest public click collection. It contains more than 30 million search sessions, each of which contains at least one search query. We process the queries in the same manner as in [Zoghi et al., 2017; Li et al., 2019]. Namely, we randomly select 100 frequent search queries with the 10 most attractive items in each query, and then learn a CM for each query using PyClick. 3 These CMs are used to generate click feedback. In this setup, the size of candidate items is L = 10 and we choose K = 3 as the number of positions. The objective of the learning task is to identify 3 most attractive items and then maximize the expected number of clicks at the 3 highest positions.
We consider a simulated non-stationary environment setup, where we take the learned attraction probabilities as the default and change the attraction probabilities periodically. Our simulation can be described in 4 steps: (1) For each query, the attraction probabilities of the top 3 items remain constant over time. (2) We randomly choose three suboptimal items and set their attraction probabilities to 0▷9 for the next m1 steps. (3) Then we reset the attraction probabilities and keep them constant for the next m2 steps. (4) We repeat step (2) and step (3) iteratively. This simulation mimics abrupt changes in user preferences and is widely used in previous work on non-stationarity [Garivier and Moulines, 2011; Wu et al., 2018; Jagerman et al., 2019]. In our experiment, we set m1 = m2 = 10k and choose 10 breakpoints. In total, we run experiments for 100k steps. Although the non-stationary aspects in our setup are simulated, the other parameters of a CM are learned from the Yandex click dataset.
We compare CascadeDUCB and CascadeSWUCB, to RankedEXP3 [Radlinski et al., 2008]↪ CascadeKL-UCB [Kveton et al., 2015] and BatchRank [Zoghi et al., 2017]. We describe the baseline algorithms in slightly more details in Section 6. Briefly, RankedEXP3, a variant of ranked bandits, is based on an adversarial bandit algorithm Exp3 [Auer et al., 1995]; it is the earliest bandit-based ranking algorithm and is popular in practice. CascadeKL-UCB [Kveton et al., 2015] is a near optimal algorithm in CM. BatchRank [Zoghi et al., 2017] can learn in a wide range of click models. However, these algorithms only learn in a stationary environment. We choose them as baselines to show the superiority of our algorithms in a non-stationary environment. In experiments, we set ✏ = 0▷5, γ = 1 - 1◁(4pn) and ⌧ = 2pn ln(n), the values that roughly minimize the upper bounds.
2 https://academy.yandex.ru/events/data analysis/relpred2011
3 https://github.com/markovi/PyClick
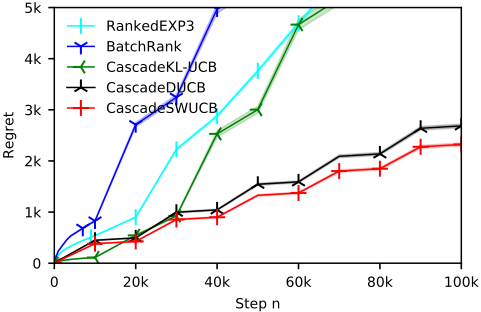
We report the n-step regret averaged over 100 queries and 10 runs per query in Figure 1. All baselines have linear regret in time step. They fail in capturing the breakpoints. Nonstationarity makes the baselines perform even worse during epochs where the attraction probability are set as the default. E.g., CascadeKL-UCB has 111▷50◦1▷12 regret in the first 10k steps but has 447▷82◦137▷16 regret between step 80k and 90k. Importantly, the attraction probabilities equal the default and remain constant inside these two epochs. This is caused by the fact that the baseline algorithms rank items based on all historical observations, i.e., they do not balance "remembering" and "forgetting." Because of the use of a discounting factor and/or a sliding window, CascadeDUCB and CascadeSWUCB can detect breakpoints and show convergence. CascadeSWUCB outperforms CascadeDUCB with a small gap; this is consistent with our theoretical finding that CascadeSWUCB outperforms CascadeDUCB by a pln n factor.
6 RelatedWork
The idea of directly learning to rank from user feedback has been widely studied in a stationary environment. Ranked bandits [Radlinski et al., 2008] are among the earliest OLTR approaches. In ranked bandits, each position in the list is modeled as an individual underlying MABs. The ranking task is then solved by asking each individual MAB to recommend an item to the attached position. Since the reward, e.g., click, of a lower position is affected by higher positions, the underlying MAB is typically adversarial, e.g., Exp3 [Auer et al., 1995]. BatchRank is a recently proposed OLTR method [Zoghi et al., 2017]; it is an elimination-based algorithm: once an item is found to be inferior to K items, it will be removed from future consideration. BatchRank outperforms ranked bandits in the stationary environment. In our experiments, we include BatchRank and RankedEXP3, the Exp3-based ranked bandit algorithm, as baselines.
Several OLTR algorithms have been proposed in specific click models [Kveton et al., 2015; Lagr´ee et al., 2016; Katariya et al., 2016; Oosterhuis and de Rijke, 2018]. They can efficiently learn an optimal ranking given the click model they consider. Our work is related to cascading bandits and we compare our algorithms to CascadeKL-UCB, an algorithm proposed for soling cascading bandits [Kveton et al., 2015], in Section 5. Our work differs from cascading bandits in that we consider learning in a non-stationary environment.
Non-stationary bandit problems have been widely studied [Slivkins and Upfal, 2008; Yu and Mannor, 2009; Garivier and Moulines, 2011; Besbes et al., 2014; Liu et al., 2018]. However, previous work requires a small action space. In our setup, actions are (exponentially many) ranked lists. Thus, we do not consider them as baselines in our experiments.
In adversarial bandits the reward realizations, in our case attraction indicators, are selected by an adversary. Adversarial bandits originate from game theory [Blackwell, 1956] and have been widely studied, cf. [Auer et al., 1995; Cesa-Bianchi and Lugosi, 2006] for an overview. Within adversarial bandits, the performance of a policy is often measured by comparing to a static oracle which always chooses a single best arm that is obtained after seeing all the reward realizations up to step n. This static oracle can perform poorly in a nonstationary case when the single best arm is suboptimal for a long time between two breakpoints. Thus, even if a policy performs closely to the static oracle, it can still perform suboptimally in a non-stationary environment. Our work differs from adversarial bandits in that we compare to a dynamic oracle that can balance the dilemma of "remembering" and "forgetting" and chooses the per-step best action.
7 Conclusion
In this paper, we have studied the online learning to rank (OLTR) problem in a non-stationary environment where user preferences change abruptly. We focus on a widely-used user click behavior model cascade model (CM) and have proposed an online learning variant of it called cascading non-stationary bandtis. Two algorithms, CascadeDUCB and CascadeSWUCB, have been proposed for solving it. Our theoretical have shown that they have sub-linear regret. These theoretical findings have been confirmed by our experiments on the Yandex click dataset. We open several future directions for non-stationary OLTR. First, we have only considered the CM setup. Other click models that can handle multiple clicks, e.g., DBN [Chapelle and Zhang, 2009], should be considered as part of future work. Second, we focused on UCB-based policy. Another possibility is to use the family of softmax policies [Besbes et al., 2014]. Along this line, one may obtain upper bounds independent from the number of breakpoints.
Acknowledgements
This research was supported by Ahold Delhaize, the Association of Universities in the Netherlands (VSNU), the Innovation Center for Artificial Intelligence (ICAI), and the Netherlands Organisation for Scientific Research (NWO) under project nr. 612.001.551. All content represents the opinion of the authors, which is not necessarily shared or endorsed by their respective employers and/or sponsors.
@inproceedings{ijcai2019p396,
  title     = {Cascading Non-Stationary Bandits: Online Learning to Rank in the Non-Stationary Cascade Model},
  author    = {Li, Chang and de Rijke, Maarten},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2859--2865},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/396},
  url       = {https://doi.org/10.24963/ijcai.2019/396},
}
TY - CPAPER TI - Cascading Non-Stationary Bandits: Online Learning to Rank in the Non-Stationary Cascade Model AU - Li, Chang AU - de Rijke, Maarten T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2859 EP - 2865 DO - 10.24963/ijcai.2019/396 UR - https://doi.org/10.24963/ijcai.2019/396 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





