
Hill Climbing on Value Estimates for Search-control in Dyna
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 3209-3215.
https://doi.org/10.24963/ijcai.2019/445
Keywords
- Machine Learning: Reinforcement Learning
- Planning and Scheduling: Other approaches to planning
- Machine Learning: Deep Learning
- Planning and Scheduling: Model-Based Reasoning
Abstract
Dyna is an architecture for model based reinforcement learning (RL), where simulated experience from a model is used to update policies or value functions. A key component of Dyna is search control, the mechanism to generate the state and action from which the agent queries the model, which remains largely unexplored. In this work, we propose to generate such states by using the trajectory obtained from Hill Climbing (HC) the current estimate of the value function. This has the effect of propagating value from high value regions and of preemptively updating value estimates of the regions that the agent is likely to visit next. We derive a noisy projected natural gradient algorithm for hill climbing, and highlight a connection to Langevin dynamics. We provide an empirical demonstration on four classical domains that our algorithm, HC Dyna, can obtain significant sample efficiency improvements. We study the properties of different sampling distributions for search control, and find that there appears to be a benefit specifically from using the samples generated by climbing on current value estimates from low value to high value region.
- [Adam et al., 2012] Sander Adam, Lucian Busoniu, and Robert Babuska. Experience replay for real-time reinforce- ment learning control. IEEE Transactions on Systems, Man, and Cybernetics, pages 201-212, 2012.
- [Amari and Douglas, 1998] Shun-Ichi Amari and Scott C. Douglas. Why natural gradient? IEEE International Con- ference on Acoustics, Speech and Signal Processing, pages 1213-1216, 1998.
- [Amari, 1998] Shun-Ichi Amari. Natural gradient works effi- ciently in learning. Neural Computation, 10(2):251-276, 1998.
- [Chiang et al., 1987] Tzuu-Shuh Chiang, Chii-Ruey Hwang, and Shuenn Jyi Sheu. Diffusion for global optimization in R n . SIAM Journal on Control and Optimization, pages 737-753, 1987.
- [Corneil et al., 2018] Dane S. Corneil, Wulfram Gerstner, and Johanni Brea. Efficient model-based deep reinforce- ment learning with variational state tabulation. ICML, pages 1049-1058, 2018.
- [Durmus and Moulines, 2017] Alain Durmus and Eric Moulines. Nonasymptotic convergence analysis for the unadjusted Langevin algorithm. The Annals of Applied Probability, pages 1551-1587, 2017.
- [Gu et al., 2016] Shixiang Gu, Timothy P. Lillicrap, Ilya Sutskever, and Sergey Levine. Continuous Deep Q- Learning with Model-based Acceleration. In ICML, pages 2829-2838, 2016.
- [Holland et al., 2018] G. Zacharias Holland, Erik Talvitie, and Michael Bowling. The effect of planning shape on dyna-style planning in high-dimensional state spaces. CoRR, abs/1806.01825, 2018.
- [Lillicrap et al., 2016] Timothy P. Lillicrap, Jonathan J. Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yuval Tassa, David Silver, and Daan Wierstra. Continuous control with deep reinforcement learning. In ICLR, 2016.
- [Lin, 1992] Long-Ji Lin. Self-Improving Reactive Agents Based On Reinforcement Learning, Planning and Teaching. Machine Learning, 1992.
- [Mnih et al., 2015] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Andrei A. Rusu, and et al. Human-level control through deep reinforcement learning. Nature, 2015.
- [Moore and Atkeson, 1993] Andrew W. Moore and Christo- pher G. Atkeson. Prioritized sweeping: Reinforcement learning with less data and less time. Machine learning, pages 103-130, 1993.
- [Pan et al., 2018] Yangchen Pan, Muhammad Zaheer, Adam White, Andrew Patterson, and Martha White. Organizing experience: a deeper look at replay mechanisms for sample- based planning in continuous state domains. In IJCAI, pages 4794-4800, 2018.
- [Peng and Williams, 1993] Jing Peng and Ronald J Williams. Efficient learning and planning within the Dyna framework. Adaptive behavior, 1993.
- [Peng et al., 2018] Baolin Peng, Xiujun Li, Jianfeng Gao, Jingjing Liu, Kam-Fai Wong, and Shang-Yu Su. Deep Dyna-Q: Integrating planning for task-completion dialogue policy learning. In Annual Meeting of the Association for Computational Linguistics, pages 2182-2192, 2018.
- [Roberts, 1996] Richard L. Roberts, Gareth O.and Tweedie. Exponential convergence of langevin distributions and their discrete approximations. Bernoulli, pages 341-363, 1996.
- [Santos et al., 2012] Matilde Santos, José Antonio Martín H., Victoria López, and Guillermo Botella. Dyna-H: A heuristic planning reinforcement learning algorithm applied to role- playing game strategy decision systems. Knowledge-Based Systems, 32:28-36, 2012.
- [Schaul et al., 2016] Tom Schaul, John Quan, Ioannis Antonoglou, and David Silver. Prioritized Experience Re- play. In ICLR, 2016.
- [Silver et al., 2014] David Silver, Guy Lever, Nicolas Heess, Thomas Degris, Daan Wierstra, and Martin Riedmiller. De- terministic policy gradient algorithms. In ICML, pages I-387-I-395, 2014.
- [Sutton and Barto, 2018] Richard S. Sutton and Andrew G. Barto. Reinforcement Learning: An Introduction. The MIT Press, second edition, 2018.
- [Sutton et al., 2008] Richard S. Sutton, Csaba Szepesvári, Al- borz Geramifard, and Michael Bowling. Dyna-style plan- ning with linear function approximation and prioritized sweeping. In UAI, pages 528-536, 2008.
- [Sutton, 1990] Richard S. Sutton. Integrated architectures for learning, planning, and reacting based on approximating dynamic programming. In ML, 1990.
- [Sutton, 1991] Richard S. Sutton. Dyna, an integrated ar- chitecture for learning, planning, and reacting. SIGART Bulletin, 2(4):160-163, 1991.
- [Thomas et al., 2016] Philip Thomas, Bruno Castro Silva, Christoph Dann, and Emma Brunskill. Energetic natural gradient descent. In ICML, pages 2887-2895, 2016.
- [Tsitsiklis, 1994] John N. Tsitsiklis. Asynchronous stochastic approximation and Q-learning. Machine Learning, pages 185-202, 1994.
- [van Seijen and Sutton, 2015] Harm van Seijen and Richard S. Sutton. A deeper look at planning as learning from replay. In ICML, pages 2314-2322, 2015.
- [Wawrzyński and Tanwani, 2013] Paweł Wawrzyński and Ajay Kumar Tanwani. Autonomous reinforcement learning with experience replay. Neural Networks, pages 156-167, 2013.
- [Welling and Teh, 2011] Max Welling and Yee Whye Teh. Bayesian learning via stochastic gradient Langevin dynam- ics. In ICML, pages 681-688, 2011.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Experience replay (ER) [Lin, 1992] is currently the most common way to train value functions approximated as neural networks (NNs), in an online RL setting [Adam et al., 2012; Wawrzy´nski and Tanwani, 2013]. The buffer in ER is typically a recency buffer, storing the most recent transitions, composed of state, action, next state and reward. At each environment time step, the NN gets updated by using a minibatch of samples from the ER buffer, that is, the agent replays those transitions. ER enables the agent to be more sample efficient, and in fact can be seen as a simple form of model-based RL [van Seijen and Sutton, 2015]. This connection is specific to the Dyna architecture [Sutton, 1990; Sutton, 1991], where the agent maintains a search-control (SC) queue of pairs of states and actions and uses a model to generate next states and rewards. These simulated transitions are used to update values. ER, then, can be seen as a variant of Dyna with a nonparameteric model, where search-control is determined by the observed states and actions.
By moving beyond ER to Dyna with a learned model, we can potentially benefit from increased flexibility in obtaining simulated transitions. Having access to a model allows us to generate unobserved transitions, from a given state-action pair. For example, a model allows the agent to obtain on-policy or exploratory samples from a given state, which has been reported to have advantages [Gu et al., 2016; Pan et al., 2018; Santos et al., 2012; Peng et al., 2018]. More generally, models allow for a variety of choices for search-control, which is critical as it emphasizes different states during the planning phase. Prioritized sweeping [Moore and Atkeson, 1993] uses the model to obtain predecessor states, with states sampled according to the absolute value of temporal difference error. This early work, and more recent work [Sutton et al., 2008; Pan et al., 2018; Corneil et al., 2018], showed this addition significantly outperformed Dyna with states uniformly sampled from observed states. Most of the work on search-control, however, has been limited to sampling visited or predecessor states. Predecessor states require a reverse model, which can be limiting. The range of possibilities has yet to be explored for search-control and there is room for many more ideas.
In this work, we investigate using sampled trajectories by hill climbing on our learned value function to generate states for search-control. Updating along such trajectories has the effect of propagating value from regions the agent currently believes to be high-value. This strategy enables the agent to preemptively update regions where it is likely to visit next. Further, it focuses updates in areas where approximate values are high, and so important to the agent. To obtain such states for search-control, we propose a noisy natural projected gradient algorithm. We show this has a connection to Langevin dynamics, whose distribution converges to the Gibbs distribution, where the density is proportional to the exponential of the state values. We empirically study different sampling distributions for populating the search-control queue, and verify the effectiveness of hill climbing based on estimated values. We conduct experiments showing improved performance in four benchmark domains, as compared to DQN 1 , and illustrate the usage of our architecture for continuous control.
1 We use DQN to refer to the algorithm by [Mnih et al., 2015] that uses ER and target network, but not the exact original architecture.
2 Background
We formalize the environment as a Markov Decision Process (MDP) (S,A, P,R, γ), where S is the state space, A is the action space, P : S×A×S → [0, 1] is the transition probabilities, R : S×A×S → R is the reward function, and γ ∈ [0, 1] is the discount factor. At each time step t = 1, 2, . . . , the agent observes a state st ∈ S and takes an action at ∈ A, transitions to st+1 ∼ P(·|st, at) and receives a scalar reward rt+1 ∈ R according to the reward function R.
Typically, the goal is to learn a policy to maximize the expected return starting from some fixed initial state. One popular algorithm is Q-learning, by which we can obtain approximate action-values Qθ : S ×A → R for parameters θ. The policy corresponds to acting greedily according to these actionvalues: for each state, select action argmaxa∈AQ(s, a). The Q-learning update for a sampled transition st, at, rt+1, st+1 is
Though frequently used, such an update may not be sound with function approximation. Target networks [Mnih et al., 2015] are typically used to improve stability when training NNs, where the bootstrap target on the next step is a fixed, older estimate of the action-values.
ER and Dyna can both be used to improve sample efficiency of DQN. Dyna is a model-based method that simulates (or replays) transitions, to reduce the number of required interactions with the environment. A model is sometimes available a priori (e.g., from physical equations of the dynamics) or is learned using data collected through interacting with the environment. The generic Dyna architecture, with explicit pseudo-code given by [Sutton and Barto, 2018, Chapter 8], can be summarized as follows. When the agent interacts with the real world, it updates both the action-value function and the learned model using the real transition. The agent then performs n planning steps. In each planning step, the agent samples (˜ s, ˜a) from the search-control queue, generates next state ˜ s′ and reward ˜ r from (˜ s, ˜a) using the model, and updates the action-values using Q-learning with the tuple (˜ s, ˜a, ˜ r, ˜ s′ ).
3 AMotivating Example
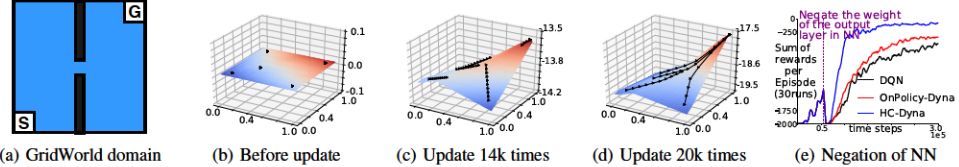
In this section we provide an example of how the value function surface changes during learning on a simple continuousstate GridWorld domain. This provides intuition on why it is useful to populate the search-control queue with states obtained by hill climbing on the estimated value function, as proposed in the next section.
Consider the GridWorld in Figure 1(a), which is a variant of the one introduced by [Peng and Williams, 1993]. In each episode, the agent starts from a uniformly sampled point from the area [0, 0.05]2 and terminates when it reaches the goal area [0.95, 1.0]2 . There are four actions {UP, DOWN, LEFT, RIGHT}; each leads to a 0.05 unit move towards the corresponding direction. As a cost-to-goal problem, the reward is -1 per step.
In Figure 1, we plot the value function surface after 0, 14k and 20k mini-batch updates to DQN. We visualize the gradient ascent trajectories with 100 gradient steps starting from five states (0.1, 0.1), (0.9, 0.9), (0.1, 0.9), (0.9, 0.1), and (0.3, 0.4). The gradient of the value function used in the gradient ascent is
At the beginning, with a randomly initialized NN, the gradient with respect to state is almost zero, as seen in Figure 1(b). As the DQN agent updates its parameters, the gradient ascent generates trajectories directed towards the goal, though after only 14k steps, these are not yet contiguous, as seen Figure 1(c). After 20k steps, as in Figure 1(d), even though the value function is still inaccurate, the gradient ascent trajectories take all initial states to the goal area. This suggests that as long as the estimated value function roughly reflects the shape of the optimal value function, the trajectories provide a demonstration of how to reach the goal-or high-value regions-and speed up learning by focusing updates on these relevant regions.
More generally, by focusing planning on regions the agent thinks are high-value, it can quickly correct value function estimates before visiting those regions, and so avoid unnecessary interaction. We demonstrate this in Figure 1(e), where the agent obtains gains in performance by updating from highvalue states, even when its value estimates have the wrong shape. After 20k learning steps, the values are flipped by negating the sign of the parameters in the output layer of the NN. HC-Dyna, introduced in Section 5, quickly recovers compared to DQN and OnPolicy updates from the ER buffer. Planning steps help pushing down these erroneously high-values, and the agent can recover much more quickly.
4 Effective Hill Climbing
To generate states for search control, we need an algorithm that can climb on the estimated value function surface. For general value function approximators, such as NNs, this can be difficult. The value function surface can be very flat or very rugged, causing the gradient ascent to get stuck in local optima and hence interrupt the gradient traveling process. Further, the state variables may have very different numerical scales. When using a regular gradient ascent method, it is likely for the state variables with a smaller numerical scale to immediately go out of the state space. Lastly, gradient ascent is unconstrained, potentially generating unrealizable states.
In this section, we propose solutions for all these issues. We provide a noisy invariant projected gradient ascent strategy to generate meaningful trajectories of states for search-control. We then discuss connections to Langevin dynamics, a model for heat diffusion, which provides insight into the sampling distribution of our search-control queue.
4.1 Noisy Natural Projected Gradient Ascent
To address the first issue, of flat or rugged function surfaces, we propose to add Gaussian noise on each gradient ascent step. Intuitively, this provides robustness to flat regions and avoids getting stuck in local maxima on the function surface, by diffusing across the surface to high-value regions.
To address the second issue of vastly different numerical scales among state variables, we use a standard strategy to be invarianttoscale:naturalgradientascent.Apopularchoice ofnaturalgradientisderivedbydefiningthemetrictensor astheFisherinformationmatrix[AmariandDouglas,1998; Amari,1998;Thomasetal.,2016]. Weintroduceasimple andcomputationallyefficientmetrictensor:theinverseof covariancematrixofthestatesΣ -1 s .Thischoiceissimple, becausethecovariancematrixcaneasilybeestimatedonline. Wecandefinethefollowinginnerproduct:
whichinducesavectorspace-theRiemannianmanifoldwherewecancomputethedistanceoftwopointssands+∆ thatareclosetoeachotherbyd(s,s+∆) def =∆ Σ -1 s ∆.The steepestascentupdatingrulebasedonthisdistancemetric becomess← s+αΣsg,wheregisthegradientvector.
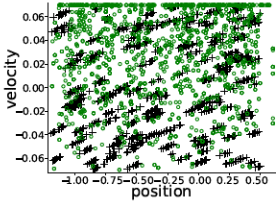
Wedemonstratetheutilityofusingthenaturalgradientscaling.Figure2showsthestatesfromthesearch-controlqueue filledbyhillclimbinginearlystagesoflearning(after8000 steps)onMountainCar.Thedomainhastwostatevariables withverydifferentnumericalscale:position∈[-1.2,0.6]and velocity∈[-0.07,0.07].Usingaregulargradientupdate,the queueshowsastatedistributionwithmanystatesconcentrated nearthetopsinceitisveryeasyforthevelocityvariableto gooutofboundary.Incontrast,theonewithnaturalgradient, showscleartrajectorieswithanobvioustendencytotheright toparea(position≥0.5),whichisthegoalarea.
Weuseprojectedgradientupdatestoaddressthethirdissue regardingunrealizablestates. WeexplaintheissueandsolutionusingtheAcrobotdomain.Thefirsttwostatevariablesare cosθ,sinθ,whereθistheanglebetweenthefirstrobotarm's linkandthevectorpointingdownwards. Thisinducesthe restrictionthatcos 2 θ+sin 2 θ=1.Thehillclimbingprocess couldgeneratemanystatesthatdonotsatisfythisrestriction.
Thiscouldpotentiallydegradeperformance,sincetheNN needstogeneralizetothesestatesunnecessarily. Wecanusea projectionoperatorΠtoenforcesuchrestrictions,whenever known,aftereachgradientascentstep.InAcrobot,Πisasimplenormalization.Inmanysettings,theconstraintsaresimple boxconstraints,withprojectionjustinsidetheboundary.
Nowwearereadytointroduceourfinalhillclimbingrule:
whereN isGaussiannoiseandαastepsize.Forsimplicity, wesetthestepsizetoα=0.1/||Σsg||acrossallresultsinthis work,thoughofcoursetherecouldbebetterchoices.
4.2 ConnectiontoLangevinDynamics
TheproposedhillclimbingprocedureissimilartoLangevin dynamics,whichisfrequentlyusedasatooltoanalyzeoptimizationalgorithmsortoacquireanestimateoftheexpected parametervaluesw.r.t.someposteriordistributioninBayesian learning[WellingandTeh,2011].TheoverdampedLangevin dynamicscanbedescribedbyastochasticdifferentialequation (SDE)dW(t)=∇U(Wt)dt+√2dBt,whereBt∈R d isa d-dimensionalBrownianmotionandUisacontinuousdifferentiablefunction.Undersomeconditions,itturnsoutthatthe Langevindiffusion(Wt)t≥0convergestoauniqueinvariant distributionp(x)∝exp(U(x))[Chiangetal.,1987].
ByapplytheEuler-Maruyamadiscretizationschemeto theSDE,weacquirethediscretizedversionYk+1 =Yk+ αk+1∇U(Yk)+√2αk+1Zk+1 where(Zk)k≥1isani.i.d.sequenceofstandardd-dimensionalGaussianrandomvectors and(αk)k≥1isasequenceofstepsizes.Thisdiscretization schemewasusedtoacquiresamplesfromtheoriginalinvariantdistributionp(x)∝exp(U(x))throughtheMarkov chain(Yk)k≥1whenitconvergestothechain'sstationary distribution[Roberts,1996].Thedistancebetweenthelimitingdistributionof(Yk)k≥1andtheinvariantdistributionof theunderlyingSDEhasbeencharacterizedthroughvarious bounds[DurmusandMoulines,2017].
Whenweperformhillclimbing,theparameter θisconstant ateachtimestept.BychoosingthefunctionUintheSDE abovetobeequaltoVθ,weseethatthestatedistributionp(s) inoursearch-controlqueueisapproximately 2
2 Differentassumptionson(αk)k≥1andpropertiesofUcangive convergenceclaimswithdifferentstrengths.Alsoreferto[Welling andTeh,2011]forthediscussionontheuseofapreconditioner.
Algorithm1HC-Dyna
Input:budgetkforthenumberofgradientascentsteps (e.g.,k=100),stochasticityηforgradientascent(e.g., η=0.1),ρpercentageofupdatesfromSCqueue(e.g., ρ=0.5),dthenumberofstatevariables,i.e.S⊂R d InitializeemptySCqueueBscandERbufferBer ˆ Σs← I (empiricalcovariancematrix) µss← 0∈R d×d ,µs← 0∈R d (auxiliaryvariables forcomputingempiricalcovariancematrix,sampleaverage willbemaintainedforµss,µs) a← 0 (thresholdforacceptingastate) fort=1,2,...do Observe(s,a,s,r)andaddittoBer µss← µss(t-1)+ss t ,µs← µs(t-1)+s t ˆ Σs← µss-µsµ s a← (1-β)a+βdistance(s,s)forβ=0.001 Samples0fromBer,˜ s← ∞ fori=0,...,kdo gsi ←∇sV(si)=∇smaxaQθ(si,a) si+1←Π(si+ 0.1 ||ˆ Σsgsi || ˆ Σsgsi +Xi),Xi∼N(0,ηˆ Σs) ifdistance(˜ s,si+1)≥ athen Addsi+1 intoBsc,˜ s← si+1 forntimesdo Sampleamixedmini-batchb,withproportionρfrom Bscand1-ρfromBer Updateparametersθ(i.e.DQNupdate)withbAnimportantdifferencebetweenthetheoreticallimitingdistributionandtheactualdistributionacquiredbyourhillclimbing methodisthatourtrajectorieswouldalsoincludethestates duringtheburn-inortransientperiod,whichreferstotheperiodbeforethestationarybehaviorisreached. Wewouldwant topointoutthatthosestatesplayanessentialroleinimproving learningefficiencyaswewilldemonstrateinsection6.2.
5 HillClimbingDyna
Inthissection,weprovidethefullalgorithm,calledHillClimbingDyna,summarizedinAlgorithm1.Thekeycomponent istousetheHillClimbingproceduredevelopedintheprevioussection,togeneratestatesforsearch-control(SC).To ensuresomeseparationbetweenstatesinthesearch-control queue,weuseathreshold a todecidewhetherornotto addastateintothequeue. Weuseasimpleheuristictoset thisthresholdoneachstep,asthefollowingsampleaverage: a≈ (T) a = T t=1 ||st+1-st||2/√d T .Thestartstateforthe gradientascentisrandomlysampledfromtheERbuffer.
Inadditiontousingthisnewmethodforsearchcontrol,we alsofounditbeneficialtoincludeupdatesontheexperience generatedintherealworld.Themini-batchsampledfortraininghasρproportionoftransitionsgeneratedbystatesfrom theSCqueue,and1-ρfromtheERbuffer.Forexample,for ρ=0.75withamini-batchsizeof32,theupdatesconsists of24(=32×0.75)transitionsgeneratedfromstatesinthe SCqueueand6transitionsfromtheERbuffer.Previouswork usingDynaforlearningNNvaluefunctionsalsousedsuch mixedmini-batches[Hollandetal.,2018].
Onepotentialreasonthisadditionisbeneficialisthatitalleviatesissueswithheavilyskewingthesamplingdistributionto beoff-policy.TabularQ-learningisanoff-policylearningalgorithm,whichhasstrongconvergenceguaranteesundermild assumptions[Tsitsiklis,1994]. Whenmovingtofunctionapproximation,however,convergenceofQ-learningismuchless wellunderstood. Thechangeinsamplingdistributionforthe statescouldsignificantlyimpactconvergencerates,andpotentiallyevencausedivergence.Empirically,previousprioritized ERworkpointedoutthatskewingthesamplingdistribution fromtheERbuffercanleadtoabiasedsolution[Schaulet al.,2016].ThoughtheERbufferisnoton-policy,because thepolicyiscontinuallychanging,thedistributionofstatesis closertothestatesthatwouldbesampledbythecurrentpolicy thanthoseinSC. UsingmixedstatesfromtheERbuffer,and thosegeneratedbyHillClimbing,couldalleviatesomeofthe issueswiththisskewness.
Anotherpossiblereasonthatsuchmixedsamplingcouldbe necessaryisduetomodelerror.Theuseofrealexperience couldmitigateissueswithsucherror. Wefound,however, thatthismixinghasaneffectevenwhenusingthetruemodel. Thissuggeststhatthisphenomenonindeedisrelatedtothe distributionoverstates.
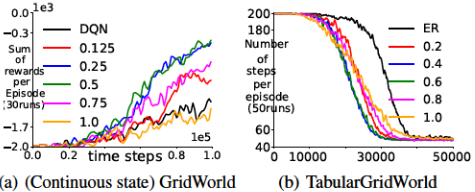
WeprovideasmallexperimentintheGridWorld,depicted inFigure1,usingbothacontinuous-stateandadiscrete-state version. Weincludeadiscretestateversion,sowecandemonstratethattheeffectpersistseveninatabularsettingwhen Q-learningisknowntobestable.Thecontinuous-statesetting usesNNs-asdescribedmorefullyinSection6-withaminibatchsizeof32.Forthetabularsetting,themini-batchsizeis 1;updatesarerandomlyselectedtobefromtheSCqueueor ERbufferproportionaltoρ.Figure3showstheperformance ofHC-Dynaasthemixingproportionincreasesfrom0(ER only)to1.0(SConly).Inbothcases,amixingratearound ρ=0.5providesthebestresults.Generally,usingtoofew search-controlsamplesdonotimproveperformance;focusing toomanyupdatesonsearch-controlsamplesseemstoslightly speedupearlylearning,butthenlaterlearningsuffers.Inall furtherexperimentsinthispaper,wesetρ=0.5.
6 Experiments
Inthissection,wedemonstratetheutilityof(DQN-)HC-Dyna inseveralbenchmarkdomains,andthenanalyzethelearning effectofdifferentsamplingdistributionstogeneratestatesfor thesearch-controlqueue.
6.1 ResultsinBenchmarkDomains
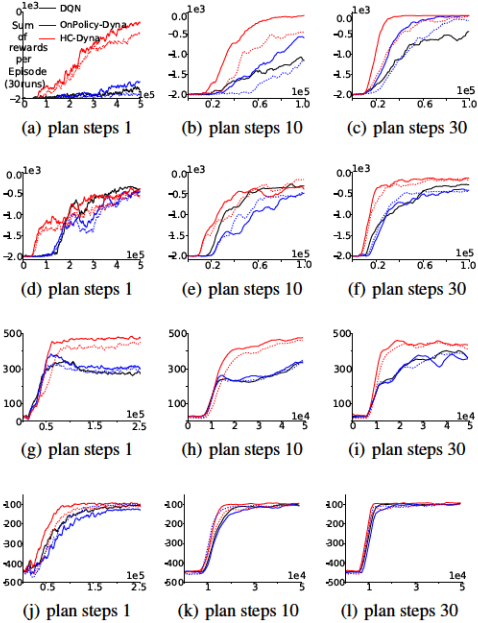
Inthissection,wepresentempiricalresultsonfourclassic domains:theGridWorld(Figure1(a)),MountainCar,CartPole andAcrobot. Wepresentbothdiscreteandcontinuousaction resultsintheGridWorld,andcomparetoDQNforthediscrete controlandtoDeepDeterministicPolicyGradient(DDPG) forthecontinuouscontrol[Lillicrapetal.,2016].Theagents alluseatwo-layerNN,withReLUactivationsand32nodes ineachlayer. Weincluderesultsusingboththetruemodel andthelearnedmodel,onthesameplots. Wefurtherinclude multipleplanningstepsn,whereforeachrealenvironment step,theagentdoesnupdateswithamini-batchofsize32.
InadditiontoER,weaddanon-policybaselinecalled OnPolicy-Dyna. Thisalgorithmsamplesamini-batchof states(notthefulltransition)fromtheERbuffer,butthen generatesthenextstateandrewardusinganon-policyaction. ThisbaselinedistinguisheswhenthegainofHC-Dynaalgorithmisduetoon-policysampledactions,ratherthanbecause ofthestatesinoursearch-controlqueue.
DiscreteAction
TheresultsinFigure4showthat(a)HC-Dynaneverharms performanceoverERandOnPolicy-Dyna,andinsomecases significantlyimprovesperformance,(b)thesegainspersist evenunderlearnedmodelsand(c)therearecleargainsfrom HC-Dynaevenwithasmallnumberofplanningsteps.Interestingly,usingmultiplemini-batchupdatespertimestepcan significantlyimprovetheperformanceofallthealgorithms. DQN,however,hasverylimitedgainwhenmovingfrom10to 30planningstepsonalldomainsexceptGridWorld,whereas HC-Dynaseemstomorenoticeablyimprovefrommoreplanningsteps.Thisimpliesapossiblelimitoftheusefulnessof onlyusingsamplesintheERbuffer.
Weobservethattheon-policyactionsdoesnotalwayshelp. TheGridWorlddomainisinfacttheonlyonewhereon-policy actions(OnPolicy-Dyna)showsanadvantageasthenumber ofplanningstepsincrease.Thisresultprovidesevidencethat thegainofouralgorithmisduetothestatesinoursearchcontrolqueue,ratherthanon-policysampledactions. We alsoseethateventhoughbothmodel-basedmethodsperform worsewhenthemodelhastobelearnedcomparedtowhenthe truemodelisavailable,HC-Dynaisconsistentlybetterthan OnPolicy-Dynaacrossalldomains/settings.
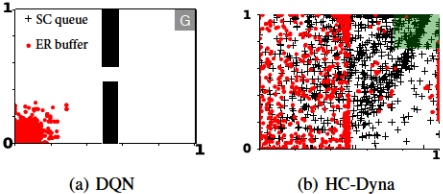
Togainintuitionforwhyouralgorithmachievessuperior performance,wevisualizethestatesinthesearch-control queueforHC-DynaintheGridWorlddomain(Figure5). We alsoshowthestatesintheERbufferatthesametimestep,for bothHC-DynaandDQNtocontrast.Therearetwointeresting outcomesfromthisvisualization.First,themodificationto search-controlsignificantlychangeswheretheagentexplores, asevidencedbytheERbufferdistribution.Second,HC-Dyna hasmanystatesintheSCqueuethatarenearthegoalregion evenwhenitsERbuffersamplesconcentrateontheleftparton thesquare.Theagentcanstillupdatearoundthegoalregion evenwhenitisphysicallyintheleftpartofthedomain.
ContinuousControl
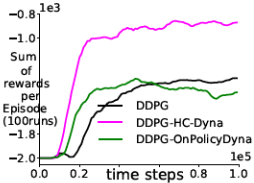
Ourarchitecturecaneasilybeusedwithcontinuousactions, aslongasthealgorithmestimatesvalues. WeuseDDPG [Lillicrapetal.,2016]asanexampleforuseinsideHCDyna. DDPGisanactor-criticalgorithmthatusesthedeterministicpolicygradienttheorem[Silveretal.,2014].Let πψ(·):S →Abetheactornetworkparameterizedbyψ, andQθ(·,·):S×A →Rbethecritic. Givenaninitialstatevalues,thegradientascentdirectioncanbecomputedby∇sQψ(s,πθ(s)).Infact,becausethegradientstep causessmallchanges,wecanfurtherapproximatethisgradientmoreefficientlyusing∇sQψ(s,a ∗ ),a ∗def =πθ(s),withoutbackpropagatingthegradientthroughtheactornetwork. WemodifiedtheGridWorldinFigure1(a)tohaveaction spaceA =[-1,1] 2 andanactionat∈ Aisexecutedas st+1 ← st+0.05at.Figure6showsthelearningcurveof DDPG,andDDPGwithOnPolicy-DynaandwithHC-Dyna. Asbefore,HC-Dynashowssignificantearlylearningbenefitsandalsoreachesabettersolution.Thishighlightsthat improvedsearch-controlcouldbeparticularlyeffectivefor algorithmsthatareknowntobepronetolocalminima,like Actor-Criticalgorithms.
6.2 InvestigatingSamplingDistributionsfor Search-control
WenextinvestigatetheimportanceoftwochoicesinHCDyna:(a)usingtrajectoriestohigh-valueregionsand(b) usingtheagent'svalueestimatestoidentifytheseimportant regions.Totestthis,weincludefollowingsamplingmethods forcomparison:(a)HC-Dyna:hillclimbingbyusingˆ Vθ (ouralgorithm);(b)Gibbs:sampling∝ exp(ˆ Vθ);(c)HCDyna-Vstar:hillclimbingbyusingV ∗ and(d)Gibbs-Vstar: sampling∝ exp(V ∗ ),whereV ∗ isapre-learnedoptimal valuefunction. WealsoincludethebaselinesOnPolicyDyna, ERandUniform-Dyna,whichuniformlysamplesstatesfrom thewholestatespace. AllstrategiesmixwithER,using ρ=0.5,tobettergiveinsightintoperformancedifferences.
TofacilitatesamplingfromtheGibbsdistributionandcomputingtheoptimalvaluefunction,wetestonasimplified TabularGridWorlddomainofsize20×20,withoutanyobstacles.Eachstateisrepresentedbyanintegeri∈{1,...,400}, assignedfrombottomtotop,lefttorightonthesquarewith 20×20grids.HC-DynaandHC-Dyna-Vstarassumethatthe statespaceiscontinuousonthesquare[0,1] 2 andeachgrid canberepresentedbyitscenter's(x,y)coordinates. Weuse thefinitedifferencemethodforhillclimbing.
ComparingtotheGibbsDistribution
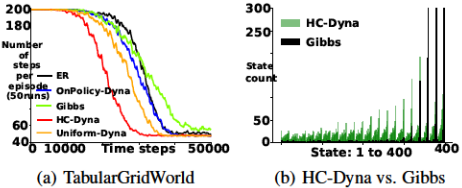
AswepointedouttheconnectiontotheLangevindynamicsin Section4.2,thelimitingbehaviorofourhillclimbingstrategy isapproximatelyaGibbsdistribution.Figure7(a)showsthat HC-Dynaperformsthebestamongallsamplingdistributions, includingGibbsandotherbaselines.Thisresultsuggeststhat thestatesduringtheburn-inperiodmatter.Figure7(b)shows thestatecountbyrandomlysamplingthesamenumberof statesfromtheHC-Dyna'ssearch-controlqueueandfromthat filledbyGibbsdistribution. WecanseethattheGibbsone concentratesitsdistributiononlyonveryhighvaluestates.
ComparingtoTrueValues
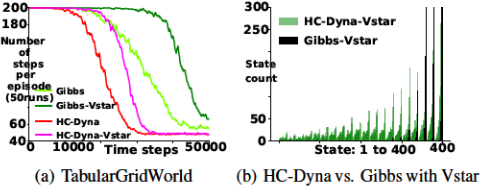
Onehypothesisisthatthevalueestimatesguidetheagentto thegoal. Anaturalcomparison,then,istousetheoptimal values,whichshouldpointtheagentdirectlytothegoal.Figure8(a)indicatesthatusingtheestimates,ratherthantrue values,ismorebeneficialforplanning.Thisresulthighlights thattheredoesseemtobesomeadditionalvaluetofocusing updatesbasedontheagent'scurrentvalueestimates.ComparingstatedistributionofGibbs-VstarandHC-Dyna-Vstar inFigure8(b)toGibbsandHC-DynainFigure7(b),onecan seethatbothdistributionsareevenmoreconcentrated,which seemstonegativelyimpactperformance.
7 Conclusion
WepresentedanewDynaalgorithm,calledHC-Dyna,which generatesstatesforsearch-controlbyusinghillclimbingon valueestimates. Weproposedanoisynaturalprojectedgradientascentstrategyforthehillclimbingprocess. Wedemonstratethatusingstatesfromhillclimbingcansignificantly improvesampleefficiencyinseveralbenchmarkdomains. We empiricallyinvestigated,andvalidated,severalchoicesinour algorithm,includingtheuseofnaturalgradients,theutility ofmixingwithERsamples,thebenefitsofusingestimated valuesforsearchcontrol.Anaturalnextstepistofurtherinvestigateothercriteriaforassigningimportancetostates.Our HCstrategyisgenericforanysmoothfunction;notonlyfor valueestimates.Apossiblealternativeistoinvestigateimportancebasedonerrorinaregion,orbasedmoreexplicitlyon optimismoruncertainty,toencouragesystematicexploration.
Acknowledgments
WewouldliketoacknowledgefundingfromtheCanadaCIFARAIChairsProgram,AmiiandNSERC.
@inproceedings{ijcai2019p445,
  title     = {Hill Climbing on Value Estimates for Search-control in Dyna},
  author    = {Pan, Yangchen and Yao, Hengshuai and Farahmand, Amir-massoud and White, Martha},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {3209--3215},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/445},
  url       = {https://doi.org/10.24963/ijcai.2019/445},
}
TY - CPAPER TI - Hill Climbing on Value Estimates for Search-control in Dyna AU - Pan, Yangchen AU - Yao, Hengshuai AU - Farahmand, Amir-massoud AU - White, Martha T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 3209 EP - 3215 DO - 10.24963/ijcai.2019/445 UR - https://doi.org/10.24963/ijcai.2019/445 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





