
A Principled Approach for Learning Task Similarity in Multitask Learning
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 3446-3452.
https://doi.org/10.24963/ijcai.2019/478
Keywords
- Machine Learning: Deep Learning
- Machine Learning: Transfer, Adaptation, Multi-task Learning
- Machine Learning: Learning Theory
- Machine Learning: Adversarial Machine Learning
Abstract
Multitask learning aims at solving a set of related tasks simultaneously, by exploiting the shared knowledge for improving the performance on individual tasks. Hence, an important aspect of multitask learning is to understand the similarities within a set of tasks. Previous works have incorporated this similarity information explicitly (e.g., weighted loss for each task) or implicitly (e.g., adversarial loss for feature adaptation), for achieving good empirical performances. However, the theoretical motivations for adding task similarity knowledge are often missing or incomplete. In this paper, we give a different perspective from a theoretical point of view to understand this practice. We first provide an upper bound on the generalization error of multitask learning, showing the benefit of explicit and implicit task similarity knowledge. We systematically derive the bounds based on two distinct task similarity metrics: H divergence and Wasserstein distance. From these theoretical results, we revisit the Adversarial Multi-task Neural Network, proposing a new training algorithm to learn the task relation coefficients and neural network parameters iteratively. We assess our new algorithm empirically on several benchmarks, showing not only that we find interesting and robust task relations, but that the proposed approach outperforms the baselines, reaffirming the benefits of theoretical insight in algorithm design.
- [Arjovsky et al., 2017] Martin Arjovsky, Soumith Chintala, and Léon Bottou. Wasserstein gan. arXiv preprint arXiv:1701.07875, 2017.
- [Ben-David et al., 2010] Shai Ben-David, John Blitzer, Koby Crammer, Alex Kulesza, Fernando Pereira, and Jen- nifer Wortman Vaughan. A theory of learning from dif- ferent domains. Machine learning, 79(1-2):151-175, 2010.
- [Ganin et al., 2016] Yaroslav Ganin, Evgeniya Ustinova, Hana Ajakan, Pascal Germain, Hugo Larochelle, Franc ¸ois Laviolette, Mario Marchand, and Victor Lempitsky. Domain-adversarial training of neural networks. The Journal of Machine Learning Research, 17(1):2096-2030, 2016.
- [Goodfellow et al., 2014] Ian Goodfellow, Jean Pouget- Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sher- jil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in neural information pro- cessing systems, pages 2672-2680, 2014.
- [Gulrajani et al., 2017] Ishaan Gulrajani, Faruk Ahmed, Mar- tin Arjovsky, Vincent Dumoulin, and Aaron C Courville. Improved training of wasserstein gans. In Advances in Neural Information Processing Systems, pages 5767-5777, 2017.
- [Janati et al., 2018] Hicham Janati, Marco Cuturi, and Alexandre Gramfort. Wasserstein regularization for sparse multi-task regression. arXiv preprint arXiv:1805.07833, 2018.
- [Kendall et al., 2018] Alex Kendall, Yarin Gal, and Roberto Cipolla. Multi-task learning using uncertainty to weigh losses for scene geometry and semantics. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 7482-7491, 2018.
- [Konstantinov and Lampert, 2019] Nikola Konstantinov and Christoph Lampert. Robust learning from untrusted sources. arXiv preprint arXiv:1901.10310, 2019.
- [Kremer et al., 2018] Jan Kremer, Lasse Borgholt, and Lars Maaløe. On the inductive bias of word-character-level multi-task learning for speech recognition. arXiv preprint arXiv:1812.02308, 2018.
- [Lee and Raginsky, 2018] Jaeho Lee and Maxim Raginsky. Minimax statistical learning with wasserstein distances. In Advances in Neural Information Processing Systems, pages 2692-2701, 2018.
- [Li et al., 2018] Yitong Li, David E Carlson, et al. Extracting relationships by multi-domain matching. In Advances in Neural Information Processing Systems, pages 6799-6810, 2018.
- [Liu et al., 2017] Pengfei Liu, Xipeng Qiu, and Xuanjing Huang. Adversarial multi-task learning for text classifi- cation. arXiv preprint arXiv:1704.05742, 2017.
- [Long et al., 2017] Mingsheng Long, Zhangjie Cao, Jianmin Wang, and S Yu Philip. Learning multiple tasks with multi- linear relationship networks. In Advances in Neural Infor- mation Processing Systems, pages 1594-1603, 2017.
- [Maurer et al., 2016] Andreas Maurer, Massimiliano Pontil, and Bernardino Romera-Paredes. The benefit of multitask representation learning. The Journal of Machine Learning Research, 17(1):2853-2884, 2016.
- [Murugesan and Carbonell, 2017] Keerthiram Murugesan and Jaime Carbonell. Active learning from peers. In Advances in Neural Information Processing Systems, pages 7008-7017, 2017.
- [Murugesan et al., 2016] Keerthiram Murugesan, Hanxiao Liu, Jaime Carbonell, and Yiming Yang. Adaptive smoothed online multi-task learning. In Advances in Neural Information Processing Systems, pages 4296-4304, 2016.
- [Pentina and Lampert, 2017] Anastasia Pentina and Christoph H Lampert. Multi-task learning with la- beled and unlabeled tasks. In International Conference on Machine Learning, pages 2807-2816, 2017.
- [Rakotomamonjy et al., 2018] Alain Rakotomamonjy, Abra- ham Traore, Maxime Berar, Rémi Flamary, and Nicolas Courty. Wasserstein distance measure machines. arXiv preprint arXiv:1803.00250, 2018.
- [Redko et al., 2017] Ievgen Redko, Amaury Habrard, and Marc Sebban. Theoretical analysis of domain adaptation with optimal transport. In Joint European Conference on Machine Learning and Knowledge Discovery in Databases, pages 737-753. Springer, 2017.
- [Ruder, 2017] Sebastian Ruder. An overview of multi- task learning in deep neural networks. arXiv preprint arXiv:1706.05098, 2017.
- [Urner and Ben-David, 2013] Ruth Urner and Shai Ben- David. Probabilistic lipschitzness a niceness assumption for deterministic labels. In In Learning Faster from Easy Data -Workshop @ NIPS, 2013.
- [Wang and Pineau, 2015] Boyu Wang and Joelle Pineau. On- line boosting algorithms for anytime transfer and multitask learning. In Twenty-Ninth AAAI Conference on Artificial Intelligence, 2015.
- [Zhang and Yang, 2017] Yu Zhang and Qiang Yang. A survey on multi-task learning. arXiv preprint arXiv:1707.08114, 2017.
- [Zhang and Yeung, 2010] Yu Zhang and Dit Yan Yeung. A convex formulation for learning task relationships in multi- task learning. In 26th Conference on Uncertainty in Arti- ficial Intelligence, UAI 2010, Catalina Island, CA, United States, 8-11 July 2010, Code 86680, 2010.
- [Zhang, 2015] Yu Zhang. Multi-task learning and algorithmic stability. In Twenty-Ninth AAAI Conference on Artificial Intelligence, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Traditional machine learning mainly focused on designing learning algorithms for individual problems. While significant progress has been achieved in applied and theoretical research, it still requires a large amount of labelled data in such a context to obtain a small generalization error. In practice, this can be highly prohibitive, e.g., for modelling users' preferences for products [Murugesan and Carbonell, 2017], for classifying multiple objects in computer vision [Long et al., 2017], or for analyzing patient data in computational healthcare [Wang and Pineau, 2015]. In the multitask learning (MTL) scenario, an agent learns the shared knowledge between a set of related tasks. Under different assumptions on task relations, MTL has been shown to reduce the amount of labelled examples required per task to reach an acceptable performance.
∗Contact Author
Understanding the theoretical assumptions of the tasks relationship plays a key role in designing a good MTL algorithm. In fact, it determines which inductive bias should be involved in the learning procedure. Recently, there are many successful algorithms that rely on task similarity information, which assumes the Probabilistic Lipschitzness (PL) condition [Urner and Ben-David, 2013] as the inductive bias. For instance, [Murugesan and Carbonell, 2017; Murugesan et al., 2016; Pentina and Lampert, 2017] minimize a weighted sum of empirical loss in which similar tasks are assigned higher weights. These approaches explicitly estimate the task similarities through a linear model. Since these approaches are estimated in the original input space, it is difficult to handle the covariate shift problem. Therefore, many neural network based approaches started to explore tasks similarities implicitly: [Liu et al., 2017; Li et al., 2018] use adversarial losses by feature adaptation, minimizing the distribution distance between the tasks to construct a shared feature space. Then, the hypothesis for the different tasks are learned over this adapted feature space.
The implicit similarity learning approaches are inspired from the idea of Generative Adversarial Networks (GANs) [Goodfellow et al., 2014]. However, the fundamental implications of incorporating task similarity information in MTL algorithms are not clear. The two main questions are why should we combine explicit and implicit similarity knowledge in the MTL framework and how can we properly do it.
Previous works either consider explicit or implicit similarity knowledge separately, or combine them heuristically in some specific applications. In contrast, the main goal of our work is to give a rigorous analysis of the benefits of task similarities and derive an algorithm which properly uses this information. We start by deriving an upper bound on the generalization error of MTL under different similarity metrics (or adversarial loss). These bounds show the motivation behind the use of adversarial loss inMTL, that is to control the generalization error. Then, we derive a new procedure to update the relationship coefficients from these theoretical guarantees. This procedure allows us to bridge the gap between the explicit and implicit similarities, which have been previously seen as disjointed or treated heuristically. We then derive a new algorithm to train the Adversarial Multitask Neural Network (AMTNN) and validate it empirically on two benchmarks: digit recognition and Amazon sentiment analysis. The results show that our method not only highlights some interesting relations, but also outperforms the previous baselines, reaffirming the benefits of theory in algorithm design.
2 RelatedWork
Multitask Learning (MTL) A broad and detailed presentation of the general MTL is provided in some survey papers [Zhang and Yang, 2017; Ruder, 2017]. More specifically related to our work, we note several practical approaches that use tasks relationship to improve empirical performances: [Zhang and Yeung, 2010] solve a convex optimization problem to estimate tasks relationships, while [Long et al., 2017; Kendall et al., 2018] propose probabilistic models through construction of a task covariance matrix or estimate the multitask likelihood from a deep Bayes model. On the theoretical side, [Murugesan et al., 2016; Murugesan and Carbonell, 2017; Pentina and Lampert, 2017] analyze the weighted sum loss algorithm and its applications in the online, active and transductive scenarios. Moreover, [Maurer et al., 2016] analyze the generalization error of representation-based approaches, and [Zhang, 2015] analyze the algorithmic stability in MTL.
Similarity Metrics and Adversarial Loss The similarity metric (or distribution divergence) is widely used in deep generative models [Goodfellow et al., 2014; Arjovsky et al., 2017], domain adaptation [Ben-David et al., 2010; Ganin et al., 2016; Redko et al., 2017], robust learning [Konstantinov and Lampert, 2019], and meta-learning [Rakotomamonjy et al., 2018]. In transfer learning, adversarial losses are widely used for feature adaptation, since the transfer procedure is much more efficient on a shared representation. In applied transfer learning, H divergence [Ganin et al., 2016] and Wasserstein distance [Li et al., 2018] are widely used in the divergence metric. As for MTL applications, [Liu et al., 2017] and [Kremer et al., 2018] apply H-divergence in natural language processing for text classification and speech recognition, while [Janati et al., 2018] are the first to propose the use of Wasserstein distance to estimate the similarity of linear parameters instead of the data generation distributions. As for the theoretical understanding, [Lee and Raginsky, 2018] analyzes the minimax statistical property in the Wasserstein distance.
3 Preliminaries
Considering a set of T tasks { ˆDt}Tt=1 , in which the observations are generated by the underlying distribution Dt over X and the real target is determined by the underlying labelling functions ft : X → Y for {(Dt, ft)}Tt=1 . Then, the goal of MTL is to find T hypothesis: h1, . . . , hT over the hypothesis space H to control the average expected error of all the tasks:
where Rt(ht) ≡ Rt(ht, ft) = Ex∼Dt ℓ(ht(x), ft(x)) is the expected risk at task t and ℓ is the loss function. Throughout the theoretical part, the loss is ℓ(ht(x), ft(x)) = |ht(x) - ft(x)|, which is coherent with [Pentina and Lampert, 2017; Li et al., 2018; Ben-David et al., 2010; Ganin et al., 2016; Redko et al., 2017]. If h, f are the binary mappings with output in {-1, 1}, it recovers the typical zero-one loss.
We also assume that each task has mt examples, with ∑Tt=1 mt = m examples in total. Then for each task t, we consider a minimization of weighted empirical loss for each task. That means we define a simplex αt ∈ ∆T = {αt,i ≥ 0, ∑Ti=1 αt,i = 1} for the corresponding weight for task t. Then the weighted empirical error w.r.t. the hypothesis h for task t can be written as:
where ˆRi(h) = 1 mi ∑mi j=1 ℓ(h(xj), yj) is the average empirical error for task i.
4 SimilarityMeasures
As we illustrated in the previous section, we are interested in task similarity metrics in MTL. Therefore, the first element to determine is how to measure the similarity between two distributions. For this, we introduce two metrics: H-divergence [Ben-David et al., 2010] and Wasserstein distance [Arjovsky et al., 2017], which are widely used in machine learning.
4.1 H-divergence
Given an input space X and two probability distributions Di and Dj over X , let H be a hypothesis class on X . We define the H-divergence of two distributions as
The empirical H-divergence corresponds to:
4.2 Wasserstein Distance
We assume X is the measurable space and denote P(X) as the set of all probability measures over X . Given two probability measures Di ∈ P(X1) and Dj ∈ P(X2), the optimal transport problem can be defined as searching for a probabilistic coupling γ refined as a joint probability measure over X1 ×X2 with marginals Di and Dj for all x, y that are minimizing the cost of transport w.r.t. some cost function:
where PX1 is the projection over X1 and # denotes the pushforward measure. The Wasserstein distance of order p between Di and Dj for any p ≥ 1 is defined as:
where c : X ×X →R+ is the cost function of transportation of one unit of mass x to y and Π(Di, Dj) is the collection of all joint probability measures on X × X with marginals Di and Dj . Throughout this paper, we only consider the case of p = 1, i.e., Wasserstein-1 distance.
5 Theoretical Guarantees
Based on the definitions of the distribution similarity metric, we are demonstrating that the generalization error in the multitask learning can be upper bounded by the following result:
Theorem 1. Let H be a hypothesis family with a VCdimension d. If we have T tasks generated by the underlying distribution and labelling function {(D1, f1), . . . , (DT , fT )} with observation numbers m1, . . . , mT . If we adopt the H divergence as a similarity metric, then for any simplex αt ∈ ∆T , and for δ ∈ (0, 1), with probability at least 1 - δ, for h1, . . . , hT ∈ H, we have:
The details of the proof are provided in the arXiv version of the paper 1 . Theorem 1 illustrates that the upper bound on the generalization error in our MTL settings can be decomposed into the following terms:
- The empirical loss and empirical distribution similarities control the weights (or task relation coefficient) α1, . . . ,αT . For instance, for a given task t, if task i has a small empirical distance dH( ˆDt, ˆDi) and hypothesis ht has a small empirical loss ˆRi(ht) on task i, it means that task i is very similar to t. Hence, more information should be borrowed from task i when learning t and the corresponding coefficient αt,i should have high values.
- Simultaneously, the coefficient regularization term prevents the relation coefficients locating only on the αt,t, in which it will completely recover the independent MTL framework. Then the coefficient regularization term proposed a trade-off between learning the single task and sharing information from the others tasks.
- The complexity and optimal terms depend on the setting hypothesis family H. Given a fixed hypothesis family
1 https://arxiv.org/abs/1903.09109
such as neural network, the complexity is constant. As for the optimal expected loss, throughout this paper we assume λt,i is much smaller than the empirical term, which indicates that the hypothesis family H can learn the multiple tasks with a small expected risk. This is a natural setting in the MTL problem since we want the predefined hypothesis family to learn well for all of the tasks. While a high expected risk means such a hypothesis set cannot perform well, which contradicts our assumption.
In Theorem 1, we have derived a bound based on the H divergence and applied in the classification problem. Then we proposed another bound based on the Wasserstein distance, which can be applied in the classification and regression problem.
Theorem 2. Let H be a hypothesis family from X to [0, 1], with pseudo-dimension d and each member h ∈ H is K Lipschitz. If we have T tasks generated by the underlying distribution and labelling function {(D1, f1), . . . , (DT , fT )} with observation numbers m1, . . . , mT . If we adopt Wasserstein-1 distance as a similarity metric with cost function c(x, y) = ‖x - y‖2, then for any simplex αt ∈ ∆T , and for δ ∈ (0, 1), with a probability at least 1-δ, for h1, . . . , hT ∈ H, we have:
The proof w.r.t. the Wasserstein-1 distance is analogous to the proof in the H-divergence but with different assumptions. The upper bound of the generalization error shows some intuitions that we should not only minimize the weighted empirical loss, but also minimize the empirical distribution divergence between each task. Moreover, in MTL approaches based on neural networks, these conclusions proposed a theoretical support for understanding the role of adversarial losses, which exactly minimize the distribution divergence.
6 Adversarial Multitask Neural Network
From the generalization error upper bound in the MTL framework, we developed a new training algorithm for the Adversarial Multitask Neural Network (AMTNN). It consists in multiple training steps by iteratively optimizing the parameters in the neural network for a given fixed relation coefficient α1, . . . , αT and estimating the relation coefficient, given fixed neural network weights.
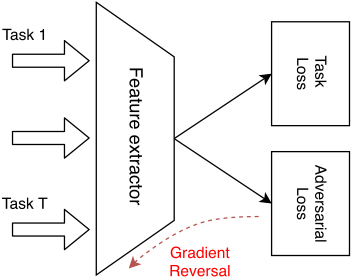
Moreover, we have three types of parameters in AMTNN: θf , θd· and θh· , corresponding to the parameter for feature extractor, adversarial loss (distribution similarity) and task loss, respectively.
To simplify the problem, we assume that each task has the same number of observations, i.e., βi = 1 T , and that regularization will use the l2 norm of αt.
6.1 Neural Network Parameters Update
Given a fixed α1, . . . ,αT , according to the theoretical bound, we want to minimize the weighted empirical error 1 T ∑Tt=1 ˆRαt (θf , θht ) and the empirical distribution "distance" ˆ d(Dt,Di) with t, i = 1, . . . , T. Inspired by [Ganin et al., 2016], the minimization of the distribution "distance" is equivalent to the maximization of the adversarial loss ˆEt,i(θf , θdt,i ). Overall, we have the following loss function with a trade-off coefficient ρ:
It should be noted that for a given task t, the sum loss can be expressed as 1 T ∑Ti=1 αt,i ∑x∈ ˆDi ℓ((x, y), θf , θht ), with ℓ being the cross entropy loss. This means that the empirical loss is a weighted sum of all of the task losses, determined by task relation coefficient αt. This is coherent with [Murugesan et al., 2016], which does not provide theoretical explanations.
Also, the adversarial loss ˆEt,i(θf , θdt,i ) is a symmetric metric for which we need to compute ˆEt,i only for t < i. Motivated by [Ganin et al., 2016], the neural network will output for a pair of observed unlabeled tasks ( ˆDt, ˆDi) a score in [0, 1] to predict from which distribution it comes. Supposing the output function is gt,i(x, (θf , θdt,i )) ≡ gt,i(x), the adversarial loss will be the following under different distance metrics:
H divergence:
Wasserstein-1 distance: Since the primal form has a high computational complexity, we adopted the same strategy as [Arjovsky et al., 2017] by estimating the empirical Kantorovich-Rubinstein duality of Wasserstein-1 distance, which leads to W1( ˆDt, ˆDi) = 1K sup‖f‖≤K (Ex∈ ˆDt [gt,i(x)] - Ex∈ ˆDi [gt,i(x)]). Combining it with the result of Theorem 2, we can derive that
6.2 Relation Coefficient Updating
The second step after updating the neural network parameter, we need to re-estimate the coefficients α1, . . . , αT when giving fixed θf , θh· , θd· . According to the theoretical guarantees, we need to solve the following convex constraint optimization
Algorithm 1 AMTNN updating algorithm
Require: Samples from different tasks { ˆDt}Tt=1 , initial coefficients {αt}Tt=1 and learning rate η
Ensure: Neural network parameters θf , θh· , θd· and relationship coefficient α1, . . . , αT
- 1: for mini-batch of samples {(xbt , yb t )} from { ˆDt}Tt=1 do
- 2: For each the distribution pair (t, i) with t < i, compute the adversarial loss ˆEt,i(θf , θdt,i ).
- 3: For each task t, define the empirical loss matrix ˆRt,i = ∑(xbi ,yb i )∈ ˆDi ℓ((xbi , yb i ), θf , θht ) and compute the label loss:
- 4: Update θf , θht : θht = θht - η ∂ ˆRαt ∂θht and θf = θf - η (∑Tt=1 ∂ ˆRαt ∂θf + ∑Tt,i:t<i (αt,i +αi,t) ∂ ˆEt,i ∂θf )
- 5: Update θdt,i (t < i): θdt,i = θdt,i + η((αt,i + αi,t) ∂ ˆEt,i ∂θdt,i ))
- 6: end for
- 7: Re-estimate {αt}Tt=1 by optimizing over Eq. (2).
problem:
where κ1 and κ2 are hyper-parameters and ˆ d· is the estimated distribution "distance". This distribution "distance" may have different forms with according to the similarity metric used:
- H divergence: According to [Pentina and Lampert, 2017; Ben-David et al., 2010; Ganin et al., 2016], the distribution "distance" is proportional to the accuracy of the
discriminator θd· , i.e., we applied gt,i(x) to predict x coming from distribution t or i. The prediction accuracy reflects the difficulty to distinguish two distributions. Hence, we set ˆ dt,i as the accuracy of the discriminator gt,i(x);
Wasserstein-1 distance: According to [Arjovsky et al., 2017], the approximation ˆ dt,i = - ˆEt,i is used.
We also assume ˆ dt,t = 0 since the discriminator cannot distinct from two identical distributions. Moreover, the expected loss αtλt,· is omitted since we assume that λt,· is much smaller than the empirical term. Then, we only use the empirical parts to re-estimate the relationship coefficient.
As it is mentioned in the theoretical part, the L2 norm regularization aims at preventing all of the relation coefficient from being concentrated on the current task αt,t. The theoretical bound proposed an elegant interpretation for training AMTNN, which is shown in Algorithm 1.
6.3 Training Algorithm
The general framework of the neural network is shown in Fig. 1. We propose a complete iteration step on how to update the neural network parameters and relation coefficients in Algorithm 1. When updating the feature extraction parameter θf , we applied gradient reversal [Ganin et al., 2016] in the training procedure. We also add the gradient penalty [Gulrajani et al., 2017] to improve the Lipschitz property when training with the adversarial loss based on Wasserstein distance.
7 Experiments
We evaluate the modified AMTNN method on two benchmarks, that is the digits datasets and the Amazon sentiment dataset. We also consider the following approaches, as baselines to make comparisons: (1) MTL uni: the vanilla MTL framework where 1 T ∑Tt=1 ˆRt(θf , θht ) is minimized; (2) MTL weighted: minimizing 1 T ∑Tt=1 ˆRαt (θf , θht ), computation of αt depending on ˆRt,i, similarly to [Murugesan et al., 2016]; (3) MTL disH and MTL disW: we apply the same type of loss function but with two different adversarial losses (H divergence and Wasserstein distance) and a general neural network without a special part for the NLP [Liu et al., 2017]; (4) AMTNN H and AMTNN W: proposed approaches with two different adversarial losses, H divergence and Wasserstein distance respectively.
7.1 Digit Recognition
We first evaluate our algorithm on three benchmark datasets of digit recognition, which are datasets, MNIST, MNIST M, and SVHN. The MTL setting is to jointly allow a system to learn to recognize the digits from the three datasets, which can differ significantly. In order to show the effectiveness of MTL, only a small portion of the original dataset is used for training (i.e., 3K, 5K and 8K for each task).
We use the LeNet-5 architecture and define the feature extractor θf as the two convolutional layers of the network, followed by multiple blocks of two fully connected layers as label prediction parameter θh· and discriminator parameter
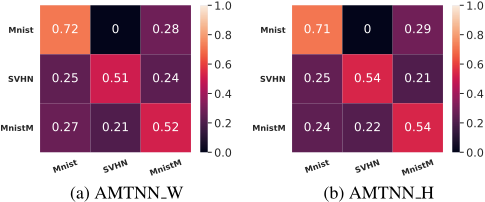
θd· . Five repetitions are conducted for each approach, and the average test accuracy (%) is reported in Table 1. We also show the estimated coefficient {αt}3t=1 of AMTNN H and AMTNN W, in Fig. 2.
Discussions
Reported results show that the proposed approaches outperform all of the baselines in the task average and also in most single tasks. Particularly for the AMTNN W, it outperforms the baselines with 1.0% ∼ 2.9% in the test accuracy. The reason can be that the Wasserstein-1 distance is more efficient for measuring the high dimensional distribution, which has been verified theoretically [Redko et al., 2017]. Moreover, the H divergence-based approach (AMTNN H) outperforms the baselines without significant increment (< 0.3%). The reason may be that the VC-dimension with H divergence is not a good metric for measuring a high dimensional complex dataset, coherently with [Li et al., 2018].
As for the coefficients αt, the proposed algorithm appears robust at estimating these task relationships, with almost identical values under different similarity metrics. Moreover, in contrast to the previous approaches, we obtain a non-symmetric matrix with a better interpretability. For instance, when learning for the MNIST dataset, only information from MNIST M is used, which is reasonable since these two tasks have the same digits configurations with different background, while SVHN is different in most ways (i.e., digits taken from street view house numbers). However, when learning MNIST M, information from SVHN is beneficial because it provides some information on the background, which is absent fromMNIST but similar to MNIST M. Therefore, the information of both tasks are involved in training for MNIST M.
In order to show the role of the weighted sum, we use t-SNE to visualise in Fig. 3 the embedded space of the MNIST task from the training data. Information from SVHN is not relevant for learning MNIST as α1,2 = 0 (see Fig. 2), such that SVHN data is arbitrarily distributed in the embedded space without influence on the final result. At the same time, information from MNIST M is used for training on the MNIST task (α1,3 = 0.28), which can be seen by a slight overlap in the embedded space. From that perspective, the role of weighted loss, which helps us to achieve some reasonable modifications of the decision boundary, is trained by the relevant and current tasks jointly. For a small scale task (typically the MTL
| 3K | 5K | 8K | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Approach | MNIST | MNIST M | SVHN | Average | MNIST | MNIST M | SVHN | Average | MNIST | MNIST M | SVHN | Average |
| MTL uni | 93.23 | 76.85 | 57.20 | 75.76 | 97.41 | 77.72 | 67.86 | 81.00 | 97.73 | 83.05 | 71.19 | 83.99 |
| MTL weighted | 89.09 | 73.69 | 68.63 | 77.13 | 91.43 | 74.07 | 73.81 | 79.77 | 92.01 | 76.69 | 73.77 | 80.82 |
| MTL disH | 89.91 | 81.13 | 70.31 | 80.45 | 91.92 | 82.68 | 73.27 | 82.62 | 92.96 | 85.04 | 78.50 | 85.50 |
| MTL disW | 96.77 | 80.38 | 68.40 | 81.85 | 95.47 | 83.48 | 72.66 | 83.87 | 98.09 | 84.13 | 74.37 | 85.53 |
| AMTNN H | 97.47 | 77.87 | 71.26 | 82.20 | 97.94 | 76.28 | 76.06 | 83.43 | 98.28 | 82.75 | 76.63 | 85.89 |
| AMTNN W | 97.20 | 80.70 | 76.93 | 84.95 | 97.67 | 82.50 | 76.36 | 85.51 | 98.01 | 82.53 | 79.97 | 86.84 |
| 1000 examples | 1600 examples | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Approach | Book | DVDs | Kitchen | Elec | Average | Book | DVDs | Kitchen | Elec | Average |
| MTL uni | 81.31 | 78.44 | 87.07 | 84.57 | 82.85 | 81.35 | 80.14 | 86.54 | 87.50 | 83.88 |
| MTL weighted | 81.88 | 79.02 | 86.91 | 85.31 | 83.28 | 80.72 | 81.20 | 87.60 | 88.12 | 84.41 |
| MTL disH | 81.23 | 78.12 | 87.34 | 84.82 | 82.88 | 81.92 | 79.86 | 87.79 | 87.31 | 84.22 |
| MTL disW | 81.13 | 78.38 | 87.11 | 84.82 | 82.86 | 81.88 | 79.81 | 87.07 | 87.69 | 84.11 |
| AMTNN H | 82.36 | 79.24 | 87.42 | 85.53 | 83.64 | 80.82 | 81.54 | 88.27 | 88.17 | 84.70 |
| AMTNN W | 81.68 | 79.38 | 87.27 | 85.66 | 83.50 | 81.20 | 80.38 | 87.69 | 88.46 | 84.44 |
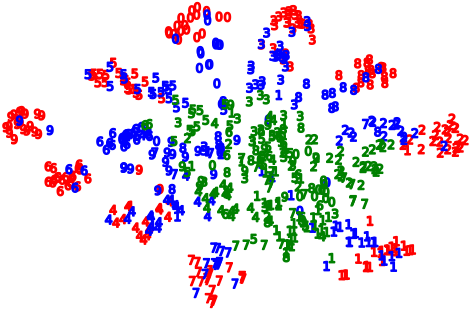
scenario), during the test procedure, the agent predicts the labels by borrowing its neighbors (relevant tasks) information. This is coherent with the Probabilistic Lipschitzness condition [Urner and Ben-David, 2013].
7.2 Sentiment Analysis
We also evaluate the proposed algorithm on Amazon reviews datasets. We extract reviews from four product categories: Books, DVD, Electronics and Kitchen appliances. Reviews datasets are pre-processed with the same strategy proposed by [Ganin et al., 2016]: 10K dimensional input features of uni-gram/bi-gram occurrences and binary output labels {0, 1}, Label 0 is given if the product is ranked less than 3 stars, otherwise label 1 is given for products above 3 stars. Results are reported for two sizes of labelled training sets, that is 1000 and 1600 examples in each product category. The output of the first fully connected layers as feature extractor parameters
θf and several sets of two fully-connected layers are given as discriminator θd· and label predictor θh· , with test accuracy (%) reported in Table 2 as an average over 5 repetitions.
Discussions
We found the proposed approaches outperform all of the baselines in the task average and also in the most tasks. Meanwhile, we observed that the role of adversarial loss (MTL disH, MTL disW, AMTNN H and AMTNN W) is not that significant (gains < 0.25%), compared to the results on the digits datasets. The possible reason is that we applied the algorithm on the pre-processed feature instead of the original feature, making the discriminator θd· less powerful in the feature adaptation. By the contrary, adding the weighted loss can improve performance by 0.4% ∼ 0.9%, enhancing the importance of the role of the explicit similarity, which is also coherent with [Murugesan et al., 2016].
8 Conclusion
In this paper, we propose a principle approach for using the task similarity information in the MTL framework. We first derive an upper bound of the generalization error in the MTL. Then, according to the theoretical results, we design a new training algorithm on the Adversarial Multi-task Neural Network (AMTNN). Finally, the empirical results on the benchmarks are showing that the proposed algorithm outperforms the baselines, reaffirming the benefits of theoretical insight in the algorithm design. In the future, we want to extend to a more general transfer learning scenario such as the different outputs space.
Acknowledgments
This work was made possible with funding from NSERCCanada, Mitacs, Prompt-Qu´ebec, E Machine Learning and Thales Canada. We thank Annette Schwerdtfeger and Fan Zhou for proofreading this manuscript.
@inproceedings{ijcai2019p478,
  title     = {A Principled Approach for Learning Task Similarity in Multitask Learning},
  author    = {Shui, Changjian and Abbasi, Mahdieh and Robitaille, Louis-Émile and Wang, Boyu and Gagné, Christian},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {3446--3452},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/478},
  url       = {https://doi.org/10.24963/ijcai.2019/478},
}
TY - CPAPER TI - A Principled Approach for Learning Task Similarity in Multitask Learning AU - Shui, Changjian AU - Abbasi, Mahdieh AU - Robitaille, Louis-Émile AU - Wang, Boyu AU - Gagné, Christian T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 3446 EP - 3452 DO - 10.24963/ijcai.2019/478 UR - https://doi.org/10.24963/ijcai.2019/478 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





