
Spectral Perturbation Meets Incomplete Multi-view Data
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 3677-3683.
https://doi.org/10.24963/ijcai.2019/510
Keywords
- Machine Learning: Multi-instance;Multi-label;Multi-view learning
- Machine Learning: Clustering
Abstract
Beyond existing multi-view clustering, this paper studies a more realistic clustering scenario, referred to as incomplete multi-view clustering, where a number of data instances are missing in certain views. To tackle this problem, we explore spectral perturbation theory. In this work, we show a strong link between perturbation risk bounds and incomplete multi-view clustering. That is, as the similarity matrix fed into spectral clustering is a quantity bounded in magnitude O(1), we transfer the missing problem from data to similarity and tailor a matrix completion method for incomplete similarity matrix. Moreover, we show that the minimization of perturbation risk bounds among different views maximizes the final fusion result across all views. This provides a solid fusion criteria for multi-view data. We motivate and propose a Perturbation-oriented Incomplete multi-view Clustering (PIC) method. Experimental results demonstrate the effectiveness of the proposed method.
- [Cai and Chen, 2015] Deng Cai and Xinlei Chen. Large scale spectral clustering via landmark-based sparse repre- sentation. IEEE Trans. Cybern., 45(8):1669-1680, 2015.
- [Cai et al., 2008] Deng Cai, Xiaofei He, Xiaoyun Wu, and Ji- awei Han. Non-negative matrix factorization on manifold. In ICDM, pages 63-72, 2008.
- [Cai et al., 2018] Yang Cai, Yuanyuan Jiao, Wenzhang Zhuge, Hong Tao, and Chenping Hou. Partial multi-view spectral clustering. Neurocomputing, 311:316-324, 2018.
- [Candes and Plan, 2010] Emmanuel J Candes and Yaniv Plan. Matrix completion with noise. Proceedings of the IEEE, 98(6):925-936, 2010.
- [Chao et al., 2017] Guoqing Chao, Shiliang Sun, and Jinbo Bi. A survey on multi-view clustering. arXiv preprint arXiv:1712.06246, 2017.
- [Hu and Chen, 2018] Menglei Hu and Songcan Chen. Dou- bly aligned incomplete multi-view clustering. In IJCAI, pages 2262-2268, 2018. IJCAI
- [Huang et al., 2019] Shudong Huang, Zhao Kang, Ivor W Tsang, and Zenglin Xu. Auto-weighted multi-view clus- tering via kernelized graph learning. Pattern Recognit., 88:174-184, 2019.
- [Hunter and Strohmer, 2010] Blake Hunter and Thomas Strohmer. Performance analysis of spectral clustering on compressed, incomplete and inaccurate measurements. arXiv preprint arXiv:1011.0997, 2010.
- [Li et al., 2014] Shao-Yuan Li, Yuan Jiang, and Zhi-Hua Zhou. Partial multi-view clustering. In AAAI, pages 1968- 1974, 2014.
- [Li et al., 2015] Yeqing Li, Feiping Nie, Heng Huang, and Junzhou Huang. Large-scale multi-view spectral cluster- ing via bipartite graph. In AAAI, pages 2750-2756, 2015.
- [Liu et al., 2018] Xinwang Liu, Xinzhong Zhu, Miaomiao Li, Lei Wang, Chang Tang, Jianping Yin, Dinggang Shen, Huaimin Wang, and Wen Gao. Late fusion incomplete multi-view clustering. IEEE Trans. Pattern Anal. Mach. Intell., pages 1-14, 2018.
- [Mohar et al., 1991] Bojan Mohar, Y Alavi, G Chartrand, and OR Oellermann. The Laplacian spectrum of graphs. Graph Theory, Combinatorics, and Applications, 2(12):871-898, 1991.
- [Ng et al., 2001] Andrew Y. Ng, Michael I. Jordan, and Yair Weiss. On spectral clustering: Analysis and an algorithm. In NIPS, pages 849-856, 2001.
- [Nie et al., 2016] Feiping Nie, Xiaoqian Wang, Michael I. Jordan, and Heng Huang. The constrained Laplacian rank algorithm for graph-based clustering. In AAAI, pages 1969-1976, 2016.
- [Nie et al., 2018] Feiping Nie, Lai Tian, and Xuelong Li. Multiview clustering via adaptively weighted procrustes. In KDD, pages 2022-2030, 2018.
- [Shao et al., 2015] Weixiang Shao, Lifang He, and Philip S. Yu. Multiple incomplete views clustering via weighted nonnegative matrix factorization with l 2,1 regularization. In ECML-PKDD, pages 318-334, 2015.
- [Stewart and Sun, 1990] G. W. Stewart and Jiguang Sun. Matrix perturbation theory. Academic Press, 1990.
- [Tao et al., 2018] Hong Tao, Chenping Hou, Xinwang Liu, Tongliang Liu, Dongyun Yi, and Jubo Zhu. Reliable multi- view clustering. In AAAI, pages 4123-4130, 2018.
- [Wang et al., 2018] Qianqian Wang, Zhengming Ding, Zhiqiang Tao, Quanxue Gao, and Yun Fu. Partial multi- view clustering via consistent GAN. In ICDM, pages 1290-1295, 2018.
- [Wang et al., 2019] Hao Wang, Yan Yang, and Bing Liu. Gmc: Graph-based multi-view clustering. IEEE Trans. Knowl. Data Eng., pages 1-14, 2019.
- [Wen et al., 2018] Jie Wen, Yong Xu, and Hong Liu. Incom- plete multiview spectral clustering with adaptive graph learning. IEEE Trans. Cybern., pages 1-12, 2018.
- [Xu et al., 2015] Chang Xu, Dacheng Tao, and Chao Xu. Multi-view learning with incomplete views. IEEE Trans Image Process., 24(12):5812-5825, 2015.
- [Yang and Wang, 2018] Yan Yang and Hao Wang. Multi- view clustering: A survey. Big Data Mining and Analytics, 1(2):83-107, 2018.
- [Yin et al., 2017] Qiyue Yin, Shu Wu, and Liang Wang. Uni- fied subspace learning for incomplete and unlabeled multi- view data. Pattern Recognit., 67:313-327, 2017.
- [Zhao et al., 2016] Handong Zhao, Hongfu Liu, and Yun Fu. Incomplete multi-modal visual data grouping. In IJCAI, pages 2392-2398, 2016. IJCAI
- [Zhao et al., 2018] Liang Zhao, Zhikui Chen, Yi Yang, Z Jane Wang, and Victor CM Leung. Incomplete multi- view clustering via deep semantic mapping. Neurocom- puting, 275:1053-1062, 2018.
- [Zhou et al., 2019] Wei Zhou, Hao Wang, and Yan Yang. Consensus graph learning for incomplete multi-view clus- tering. In PAKDD, pages 529-540, 2019.
- [Zhu et al., 2018] Xinzhong Zhu, Xinwang Liu, Miaomiao Li, En Zhu, Li Liu, Zhiping Cai, Jianping Yin, and Wen Gao. Localized incomplete multiple kernel k-means. In IJCAI, pages 3271-3277, 2018. IJCAI
- [Zong et al., 2018] Linlin Zong, Xianchao Zhang, Xinyue Liu, and Hong Yu. Weighted multi-view spectral cluster- ing based on spectral perturbation. In AAAI, pages 4621- 4628, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Many applications face the situation where each data instance in a set {x1, ..., xn} is sampled from multiple views. Here each xi|ni=1 is denoted by multiple views, e.g., m views {x1i , ..., xmi }. Such forms of data are referred to asmulti-view data. Multi-view clustering aims to provide a more accurate and stable partition than single view clustering by considering data from multi-views [Chao et al., 2017; Yang and Wang, 2018]. To date, most existing multi-view clustering methods, even the most recent methods such as [Tao et al., 2018; Zong et al., 2018; Nie et al., 2018; Wang et al., 2019; Huang et al., 2019] work under the assumption that every data instance is sampled from all views. We call this assumption the complete sampling assumption. However, the complete sampling assumption is too strong as it frequently happens that some data instances are not sampled in certain views because of sensor faults or machine malfunctions. This leads to the result that the collected multi-view data are incomplete in some views. We call such data incomplete multi-view data.
∗Corresponding author.
The problem of clustering incomplete multi-view data is known as incomplete multi-view clustering (or partial multiview clustering) [Hu and Chen, 2018; Li et al., 2014]. Based on the existing works, the main challenge of this problem is 2-fold: (1) how to partition each instance with m views into its group, and (2) how to deal with incomplete views. To address these two challenges, existing incomplete multi-view clustering methods built upon non-negative matrix factorization, kernel learning or spectral clustering to learn a consensus representation for all views and tackled incomplete views by exploring two main directions. The first direction is to project each incomplete view data into a common subspace or a specific subspace [Li et al., 2014; Zhao et al., 2016; Yin et al., 2017; Zhao et al., 2018; Cai et al., 2018; Wang et al., 2018]. However, these methods only work for twoview data. The second direction is to fill the missing instances using matrix completion [Xu et al., 2015; Zhu et al., 2018; Wen et al., 2018; Liu et al., 2018; Shao et al., 2015; Hu and Chen, 2018; Zhou et al., 2019]. Most of them still fill the missing features with average feature values. However, such a filling method is naive as the features in both inter-class and intra-class may have large variances. In addition, most existing approaches only evaluate their clustering performance on toy (randomly generated) incomplete multi-view data.
To address the limitations discussed above, this paper builds a strong link between the spectral perturbation theory and incomplete multi-view clustering. Specifically, we propose a new approach, denoted by Perturbation-oriented Incomplete multi-view Clustering (PIC). It transfers featurevalue missing to similarity-value missing and reduces the spectral perturbation risk among different views to generate the final clustering results by exploiting the key characteristics of spectral clustering. The proposed approach consists of two main phases.
Phase 1 is similarity matrix completion. Given the data matrix of each view, it first generates a similarity matrix (or affinity matrix) for each view. Then it completes the missing similarity entries using average similarity values of other views which have those missing instances.
Phase 2 is consensus matrix learning. It first computes the Laplacian matrix of each completed similarity matrix, and then weights each Laplacian matrix using the perturbation theory to learn a consensus Laplacian matrix. Finally, it performs clustering on the consensus Laplacian matrix.
The proposed method PIC can work because spectral clustering partitions data instances according to their similarities, where the similarity value of any two data instances is a quantity bounded in magnitude O(1). Another crucial point is that the perturbation of spectral clustering is determined by the eigenvectors of the Laplacian matrix, which can be measured by the canonical angle between the subspaces of different eigenvectors. Thus, we can reduce the perturbations among different views by optimizing the canonical angle. We will discuss the details in the subsequent sections.
In summary, this paper makes the following contributions. (1) It proposes a novel incomplete multi-view clustering method by exploiting the spectral perturbation theory. The proposed method transfers feature missing to similarity missing and weights the Laplacian matrix of each view based on perturbation theory to learn a consensus Laplacian matrix for the final clustering. To our knowledge, this is the first such formulation. (2) It provides an upper bound of the spectral perturbation risk among different views and formulates a key task in the proposed model into a standard quadratic programming problem. (3) It experimentally evaluates the proposed method on both toy/synthetic incomplete multi-view data and real-life incomplete multi-view data. The experimental results show that the proposed method makes considerable improvement over the state-of-the-art baselines.
Before going further, we explain some notational conventions used throughout the paper. We will use boldface capital letters (e.g., X), boldface lowercase letters (e.g., x) and lowercase letters (e.g., x) to denote matrices, vectors and scalars, respectively. Further, I denotes the identity matrix, and 1 denotes a column vector with all the entries as one. For a matrix X ∈ Rn1×n2 , the j-th column vector and the ij-th entry are denoted by xj and xij, respectively. The trace and the Frobenius norm of X are denoted by Tr(X) and ‖X‖F , respectively. For a column vector x ∈ Rn1×1 , the j-th entry is denoted by xj , and lp-norm is denoted by ‖x‖p.
2 Preliminaries
In this paper, we build upon the work of [Ng et al., 2001] (denoted as NgSC), which analyzed the spectral clustering algorithm using the top k eigenvectors of the Laplacian matrix of the similarity matrix to partition data. Given a single view data matrix X ∈ Rd×n , where d is the dimension of features and n is the number of data instances, NgSC partitions the n data instances into c clusters as follows:
Step 1. Construct the data similaritymatrixA ∈ Rn×n , where each entry aij in A denotes the relationship between xi and xj ;
- Step 2. Compute the normalized graph Laplacian matrix L = D-1/2AT D-1/2 , where D is a diagonal matrix whose i-th diagonal element is ∑j aij;
- Step 3. Let λ1 ≥ ... ≥ λk be the k largest eigenvalues of L and u1, ..., uk denote the corresponding eigenvectors. Normalize all eigenvectors to have unit length and form the matrix U=[u1, ..., uk] by stacking the eigenvectors in columns;
- Step 4. Form the matrix Y from U by normalizing each of U's rows to have unit length;
- Step 5. Treat each row of Y as a data instance, and partition them using K-means to produce the final clustering results.
To explain why the eigenvectors of spectral clustering can work, [Ng et al., 2001] gave an "ideal" case to explain it according to the following proposition.
Proposition 1. [Ng et al., 2001] 1 Given n data instances with c clusters of sizes ˆn1, ..., ˆnc respectively, let the offdiagonal blocks ˆA(ij) be zero. Also assume that each cluster is connected. Then there exist k (k = c) orthogonal vectors u1, ..., uk (uTi uj =1 if i=j, 0 otherwise) so that each row of ˆY satisfies ˆy(i) j =ui for all i=1, ..., k and j=1, ..., ni.
Proposition 1 states that there are k (k = c) mutually orthogonal points on the surface of the unit k-sphere around which ˆY's rows will cluster. These clusters correspond exactly to the true clustering results of the original data.
However, in a general case, the off-diagonal blocks A(ij) are non-zero. Suppose E = A+ ˆA as perturbations to the "ideal" ˆA that makes A= ˆA+E. Earlier results [Hunter and Strohmer, 2010] have shown that small perturbations in the similarity matrix can affect the spectral coordinates and clustering ability. The results are based on the following proposition by [Hunter and Strohmer, 2010].
Proposition 2. Suppose ‖aij - ˆaij‖ ≤ ϵ, then
Proposition 2 is a reformulation of the Corollary 10 in [Hunter and Strohmer, 2010]. It is easy to prove this proposition as follows
As can be seen, if n is very large (even ϵ is small), then nϵ cannot be ignored. This problem is more acute in multi-view setting because the constructed similarity matrices of different views may vary greatly. Given all the above, in an incomplete multi-view data clustering setting, we ask the following questions:
- How to handle incomplete multi-view data?
- How to find a consensus matrix Y∗ for all views?
- How to make the resulting rows of Y∗ to cluster similarly to the rows of ˆY∗ ?
The first one is our key question. We will propose our solutions to these questions in the next section.
3 ProposedMethod
This section presents the proposed PIC method together with its optimization algorithm.
3.1 SimilarityMatrix Generation
Given a set of unlabeled data instances {x1, ..., xn} sampled from m views, let X1 , ...,Xm be the data matrices of the m views and Xv = {xv1 , ..., xvnv } ∈ Rdv×nv be the v-th view data matrix, where dv is the dimension of the features and nv (nv ≤ n) is the number of data instances. Like most existing work, we make the assumption that at least one view is available for each data instance in the data matrix. Now we generate each view's similarity matrix from each view's data matrix respectively. As each view is independent in this phase, we take the v-th view as an example.
1 Here we denote A and Y as ˆA and ˆY respectively as it is an "ideal" case.
The intuition here is that if two data instances are close, they should be also close to each other in the similarity graph. Thus, we propose to learn a similarity matrix as follows
The above optimization, i.e., Eq. (1), is able to learn a similarity matrix (whose size is n × n as there are n instances) from a complete data matrix (whose size is also n×n). However, it cannot learn such a similarity matrix from an incomplete data matrix (whose size is not n×n). Our Xv falls in this case as some instances may be missing in view v, resulting in nv ≤ n. To handle missing instances, we define a missing operator on each instance xi as below
where NaN denotes "not a number", which can be seen as an invalid number. Based on PM(xvi )|ni=1 , we formulate our similarity matrix generation task as follows
In such a way, Eq. (2) can learn a similarity matrix Av ∈ Rn×n with adaptive neighbors for each view. More precisely, it assigns NaN to avij if either xi or xj is missing in view v; otherwise it assigns a similarity value to avij using the following solution.
We denote dvij =‖PM(xvi )-PM(xvj )‖22 and further denote dvi as a vector with j-th element as dvij . Here we assign NaN to dvij if either PM(xvi ) =NaN or PM(xvj ) =NaN. Then we rewrite Eq. (2) in a vector form as follows,
This problem can be solved with a closed form solution as introduced in [Nie et al., 2016]. So, we generate a similarity matrix Av ∈ Rn×n for each view v (v =1, ...,m). We show that the similarity value of any two data instances (except for missing instances) is a quantity bounded in magnitude O(1) because we make the constraint 0≤avij ≤1. This allows for completing those NaNs using average similarity values to reduces to perturbations frommissing instances.
3.2 SimilarityMatrix Completion
Given the learned similarity matrices A1 , ...,Am, we now focus on completing those NaNs in each similarity matrix.
Specifically, we complete those NaNs using the average similarity values of the valid view(s). We also take the v-th view as an example. Similar to PM(xvi ), we define a completion operator on each avi as
where aave i = ∑j aji /Nv. Here aji denotes the similarity value vector in the view j (which has valid similarity value vector for the i-th entry) and Nv is the number of such views.
According to the following theorem, we discuss why our completion scheme is stable and effective.
Theorem 1. [Candes and Plan, 2010] Let Z∈Rt1×t2 be a fixed rank matrix with strong incoherence parameter µ. Suppose there are ℏ observed entries of Z with locations sampled uniformly at random with noise ‖PΩ(Z) - ˆZ‖F ≤ δ. Then with high probability, the resulting completion ˆZ obeys
The details of Theorem 1 are introduced in [Candes and Plan, 2010; Hunter and Strohmer, 2010]. The theorem provides an upper bound (which is proportional to the noise level δ) on the recovery error frommatrix completion. It states the following: when perfect noiseless recovery occurs, then matrix completion is stable vis-`a-vis perturbations. Our Av is a special case of Z with t1 =t2 =n. As discussed early, similarity value is a quantity bounded in magnitude O(1), resulting in a small δ. Thus, our completion scheme using the average similarity values makes completion stable and effective.
Here we have proposed our solution to the key question, i.e., how to handle incomplete multi-vew data. Next, we discuss how to find a consensus matrix Y∗ for all views.
3.3 Consensus Learning
Recall the framework of NgSC, see Section 2. Y is generated from U by normalizing each of U's rows to have unit length. U is formed by the eigenvectors of Laplacian matrix L. As can be seen, the above processes from L to Y are simple yet solid but nothing can be changed. Thus, we transfer learning a consensus Y∗ to learning a consensus L∗ . Another crucial reason is that the perturbation of spectral clustering is determined by eigenvector of Laplacian matrix [Hunter and Strohmer, 2010]. However, small perturbations in the entries of a Laplacian matrix can lead to large perturbations in the eigenvectors. We will detail this in the next subsection.
Suppose we have computed the normalized Laplacian matrix Lv ∈ Rn×k for each completed similarity matrix Av using Lv = (Dv )-1/2 (Av )T (Dv )-1/2 , then we propose to solve our consensus learning task as below
where ωv is the weight of the v-th view. Note that each ωv|mv=1 is determined automatically by reducing perturbation risk among different views, which will be clear shortly.
3.4 Perturbation Risk
Now we respond to the previous subsection and answer the last question, i.e., how to make the resulting rows of L∗ to cluster similarly to the rows of "ideal" ˆL∗ as in Proposition 2.
The study in [Hunter and Strohmer, 2010] shows that small perturbations in the entries of Laplacian matrix can lead to large perturbations in the eigenvectors. Matrix perturbation theory [Stewart and Sun, 1990] indicates that the perturbations can be captured by the closeness of the subspaces spanned by the eigenvectors. Let uv1 , ..., uvk and u∗1 , ..., u∗k denote the first k eigenvectors of Lv and L∗ , respectively. The subspaces spanned by the eigenvectors uv1 , ..., uvk and u∗1 , ..., u∗k are formed as [uv1 , ..., uvk ] and [u∗1 , ..., u∗k ]. Following [Stewart and Sun, 1990; Hunter and Strohmer, 2010], we define closeness of these supspaces using canonical angles.
Definition 1. Let γ1 ≤ ... ≤ γk be the singular values of [uv1 , ..., uvk ]T [u∗1 , ..., u∗k ]. Then the values,
are called the canonical angles between these subspaces.
The largest canonical angle indicates the perturbation level. Next we make L∗ close to the "ideal" ˆL∗ according to the following theorem of canonical angle.
Theorem 2. [Hunter and Strohmer, 2010] Let λvi , uvi , λ∗i , u∗i be the i-th eigenvalue and eigenvector of Lv and L∗ respectively. Let Θ = diag(θ1, ..., θk) be the diagonal matrix of canonical angles between the subspaces of Uv =[uv1 , ..., uvk ] and U∗ =[u∗1 , ..., u∗k ]. If there is a gap ξ such that
then
where sinΘ is taken entry-wise and Σv =diag(λv1 , ..., λvk ).
This is a reformulation of the Theorem 3 in [Hunter and Strohmer, 2010]. Based on Proposition 2 and Theorem 2, we further give an upper bound of sinΘ.
Corollary 1. With the notations of Theorem 2, suppose ‖l∗ ij - lv ij ‖ ≤ ϵ. Then
Proof. Recall ‖ sinΘ‖F ≤ 1ξ ‖L∗Uv -UvΣv ‖F .
As the diagonal elements of Σv and the column vectors of Uv are exactly the first k eigenvalues and eigenvectors of Lv respectively, we have LvUv = UvΣv . Then
According to the orthogonality of Uv , we have
Based on Proposition 2, we have ‖L∗ - Lv ‖F ≤ nϵ.
Then, we conclude the proof as
Now the key task is to minimize the upper bound of sinΘ as it is equivalent to reduce the perturbation risk. Considering the "ideal" Laplacian matrix ˆL∗ , we have the following theorem by [Mohar et al., 1991].
Theorem 3. [Mohar et al., 1991] The multiplicity of the eigenvalue 0 of the Laplacian matrix ˆL∗ is exactly equal to the number of clusters c.
Theorem 3 indicates that the "ideal" Laplacian matrix ˆL∗ has c positive eigenvalues and n - c zero eigenvalues. Let k = c. As we aim to make our L∗ approximate ˆL∗ , the rank of L∗ is expected to k, λ∗k+1 ≈0 and |λvk -λ∗k+1 |≈λvk . Thus, given the Laplacian matrix of each view, ξ in Theorem 2 can be seen as a constant. This motivates us to rewrite Eq. (4) into the following objective function to reduce perturbation risk.
Here another motivation is that views having similar clustering ability should be assigned similar weights. According to Definition 1 and Theorem 2, we conclude that the largest canonical angle between subspaces spanned by the eigenvectors indicates the similarity of the clustering ability. Thus, the difference in weights between the views should be small if the largest canonical angle between corresponding subspaces is small. This is exactly what manifold learning aims to do [Cai et al., 2008]. Let ψij ∈[0, π] be the largest canonical angle between subspaces of the i-th view and the j-th view and sij =π-ψij . We propose to perform our task using manifold learning as follows
where H = ˘D-S and ˘D ∈ Rm×m is a diagonal matrix with each diagonal element as ˘ dii = ∑mj=1 sij .
Plugging the right item of Eq. (6) into Eq. (5), formally, our objective function is formulated as
where β is a trade-off parameter. We will analyze β in the experiment section. Given β, here we can rewrite Eq. (7) as
Note, each entry qv ij in Qv and each entry f v i in f v come shortly on the next page. It is easy to see that Eq. (8) is a
Algorithm 1: The proposed overall algorithm.
Input : Data matrices with m views X1 , ...,Xm, the number of clusters c, and parameter β.
1 begin
- 2 Generate similarity matrix Av from each data matrix Xv by solving Eq. (2);
- 3 Complete similarity matrix Av using completion operator PΩ(avi )|ni=1 ;
- 4 Compute normalized Laplacian matrix Lv of each completed similarity matrix Av ;
- 5 Calculate the eigendecomposition Uv and Σv of each normalized Laplacian matrix Lv ;
- 6 Calculate ω by solving Eq. (8);
- 7 Calculate consensus Laplacian matrix L∗ using Eq. (4);
- 8 Produce the final clustering results by performing spectral clustering algorithm (e.g., NgSC) on the learned consensus Laplacian matrix L∗ ;
- 9 end
Output: The clustering results with c clusters.
standard quadratic programming problem with respect to ω and can be solved by a classic technique, e.g., the technique called quadprog in MATLAB. We used MATLAB because all baselines used it.
In Eq. (8), each entry qv ij in Qv and each entry f v i in f v is respectively defined as
Hereto, we presented the proposed PIC approach with four tasks. We now couple overall solutions into a joint framework and optimize the joint framework using Algorithm 1. The convergence of our algorithm involves two parts, i.e., generating similarity matrix Av |mv=1 using Eq. (2) and calculating the weights ω using Eq. (8). Eq. (2) is clearly a convex function as its second order derivative w.r.t. avi is a positive value. Eq. (8) is a standard quadratic programming problem w.r.t. the weights ω. Thus, the convergence of the proposed algorithm is guaranteed. Compared to single view spectral clustering algorithm, PIC needs to optimize Eq. (8). The computational complexity of optimizing Eq. (8) is O(m3n2k+m3 ) in total, where m≪ n and k ≪ n. Thus, PIC does not increase the computational complexity of spectral clustering, i.e., O(n3 ). For large-scale data, data sampling as in [Cai and Chen, 2015; Li et al., 2015] is a potential way to speed up our method. In addition, the proposed algorithm can be implemented with data on disk as it runs without iterative optimization. Thus, our algorithm can be deployed on a small memory machine.
4 Experiments
4.1 Datasets and Baselines
Datasets. We perform evaluation using four complete multi-view datasets and three natural incomplete multi-view datasets. The datasets are summarized in Table 1, where the first four datasets are complete and the last three datasets are naturally incomplete. For the dataset Mfeat, we collected it from two Handwritten Digits sources, i.e., MNIST and USPS.
| Dataset | m | c | n | nv (v = 1, ...,m) | dv (v = 1, ...,m) |
|---|---|---|---|---|---|
| 100Leaves 2 | 3 | 100 | 1600 | 1600, 1600, 1600 | 64, 64, 64 |
| Flowers17 3 | 7 | 17 | 1360 | 1360, 1360, ..., 1360 | 1360, 1360, ..., 1360 |
| Mfeat 4 | 2 | 10 | 10000 | 10000, 10000 | 784, 256 |
| ORL 5 | 4 | 40 | 400 | 400, 400, 400, 400 | 256, 256, 256, 256 |
| 3Sources 6 | 3 | 6 | 416 | 352, 302, 294 | 3560, 3631, 3068 |
| BBC 7 | 4 | 5 | 2225 | 1543, 1524, 1574, 1549 | 4659, 4633, 4665, 4684 |
| BBCSport 7 | 2 | 5 | 737 | 644, 637 | 3183, 3203 |
Baselines. We consider the following algorithms as the baselines: BSV 8 (Best Single View) [Ng et al., 2001], PVC [Li et al., 2014], IMG [Zhao et al., 2016], MIC [Shao et al., 2015] and DAIMC [Hu and Chen, 2018]. Note that BSV only works for complete single view data. Following [Shao et al., 2015; Zhao et al., 2016], we first fill the missing instance in each incomplete view using the average feature values of that incomplete view. PVC and IMG only work for two-view data. Following [Hu and Chen, 2018], we evaluate PVC and IMG on all two-view combinations and report the best results. Since DAIMC works for multi-view data, we use it as it is.
4.2 Experimental Settings and Results
Experimental Settings
To generate incomplete multi-view datasets from complete multi-view datasets, we follow all the above baselines and use a general setting. Same as the baselines, we first randomly select partial examples under different Partial Example Ratio (PER). Then we additionally generate a random binary vector b=(b1, ..., bm) for each partial example (e.g., xj). If bi =0, we delete/remove example xj from view i.
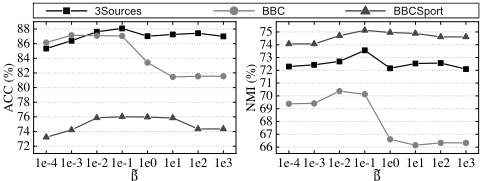
For the baselines, we obtained the original systems from their authors and used their default parameter settings. For PIC, we set the parameter β using β= ˜ β×‖ ∑v Qv ‖F /‖I‖F to balance Eq. 5 and Eq. 6. Then we empirically set ˜ β = 0.1 in evaluation. The parameter study will come shortly.
Following the baselines, two metrics, accuracy (ACC) and normalized mutual information (NMI) are used to measure the clustering performance. In order to randomize the experiments, we run each algorithm 20 times and report the average values of the performance measures.
Experimental Results
We first perform evaluation using four toy incomplete multiview datasets (generated from complete multi-view datasets as introduced above). In this experiment, PER varies from 0.1 to 0.9 with an interval of 0.2, same as baselines PVC and IMG. We also set PER = 0, i.e., every data instance is sampled
2 https://archive.ics.uci.edu/ml/datasets/One-hundred+plant+ species+leaves+data+set
3 http://www.robots.ox.ac.uk/∼vgg/data/flowers/17/index.html
4 https://cs.nyu.edu/∼roweis/data.html
5 www.cad.zju.edu.cn/home/dengcai/Data/FaceData.html
6 http://mlg.ucd.ie/datasets/3sources.html
7 http://mlg.ucd.ie/datasets/segment.html
| Method | Clustering performance in terms of ACC | Clustering performance in terms of NMI | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| BSV | PVC | IMG | MIC | DAIMC | PIC | BSV | PVC | IMG | MIC | DAIMC | PIC | |
| 3Sources | 22.50±0.63 | 26.45±0.39 | 25.59±0.13 | 43.73±6.28 | 58.68±8.12 | 88.08±1.22 | 5.30±0.27 | 1.77±0.25 | 2.00±0.12 | 38.94±5.58 | 48.80±7.27 | 73.50±1.45 |
| BBC | 40.79±1.02 | 37.80±0.97 | 29.92±0.01 | 57.07±9.74 | 51.34±7.44 | 87.03±0.05 | 25.99±2.33 | 14.72±0.11 | 6.24±0.01 | 39.19±6.54 | 37.74±7.23 | 70.12±0.02 |
| BBCSport | 40.99±0.81 | 44.33±1.46 | 37.86±0.07 | 58.66±9.39 | 75.16±8.82 | 76.02±5.28 | 26.60±0.48 | 13.77±1.67 | 7.55±0.03 | 46.26±6.74 | 57.80±9.53 | 75.12±2.05 |
Table 2: Clustering performance on three natural incomplete multi-view datasets.
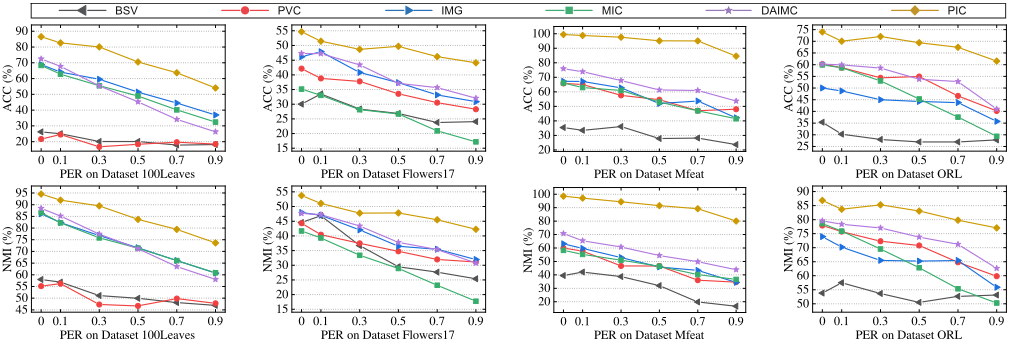
in all views. Figure 1 shows the performance results in terms of ACC and NMI. From Figure 1, we make the following observations:
- Our PIC significantly outperforms the baselines in all the PER settings. As the PER increases, the clustering performance of all the methods drops.
- All baselines are inferior to our model. One reason is that they complete the missing instances with the average feature values, which results in a large deviation, especially when the PER is large. In this work, we transfer feature missing to similarity missing, then complete the missing similarity entries (marked with NaN) using the average similarity values of all the valid views. This shows that our completion scheme is powerful in dealing with missing instances.
- The recent baseline DAIMC performs better than other baselines, but worse than our method. This shows that our method presents a new margin to beat.
We then perform evaluation using three natural incomplete multi-view data. The results, i.e., the average values and the standard deviations (denoted as ave±std), are shown in Table 2. From the table, we make the following observations:
- Our PIC again outperforms the baselines markedly. PIC achieves the best ACC and NMI on each dataset. The results clearly show that our PIC is a promising incomplete multi-view clustering method.
- Multi-view clustering methods (MIC, DAIMC and PIC) are superior to two-view clustering methods (PVC and IMG), but two-view clustering methods (PVC and IMG) are not always superior to the single-view clustering method (BSV). All of them are inferior to our PIC. This indicates that multi-view data boost clustering results with multi-view clustering techniques.
4.3 Parameter Study
In the above experiments, parameter ˜ β is set to 0.1 for PIC. Here we explore the effect of parameter ˜ β. Due to the space limit, we only show the results on three natural incomplete multi-view data. Figure 2 shows how the average performance of PIC varies with different ˜ β values. From Figure 2, we can see that PIC achieves consistently good performance when ˜ β is around 0.1 (i.e., 1e-1) on three datasets. As introduced early, we use a balance scheme, i.e., β = ˜ β×‖ ∑v Qv ‖F/‖I‖F . This is the reason why we can use the same parameter ˜ β (i.e., 0.1) for all datasets.
β
β
Figure 2: Parameter study on three natural incomplete datasets.
5 Conclusions
This paper built a bridge between spectral perturbation and incomplete multi-view clustering. We explored spectral perturbation theory and proposed a novel Perturbation-oriented Incomplete multi-view Clustering (PIC) method. The key idea is to transfer the missing problem from data matrix to similarity matrix and reduce the spectral perturbation risk among different views while balancing all views to learn a consensus representation for the final clustering results. Both theoretical results and experimental results showed the effectiveness of the proposed method.
Acknowledgments
This work was partially supported by the National Natural Science Foundation of China (No. 61572407), and the Project of National Science and Technology Support Program (No. 2015BAH19F02). Hao Wang would like to thank the China Scholarship Council (No. 201707000064).
@inproceedings{ijcai2019p510,
  title     = {Spectral Perturbation Meets Incomplete Multi-view Data},
  author    = {Wang, Hao and Zong, Linlin and Liu, Bing and Yang, Yan and Zhou, Wei},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {3677--3683},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/510},
  url       = {https://doi.org/10.24963/ijcai.2019/510},
}
TY - CPAPER TI - Spectral Perturbation Meets Incomplete Multi-view Data AU - Wang, Hao AU - Zong, Linlin AU - Liu, Bing AU - Yang, Yan AU - Zhou, Wei T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 3677 EP - 3683 DO - 10.24963/ijcai.2019/510 UR - https://doi.org/10.24963/ijcai.2019/510 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





