
On the Convergence of (Stochastic) Gradient Descent with Extrapolation for Non-Convex Minimization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 4003-4009.
https://doi.org/10.24963/ijcai.2019/556
Keywords
- Machine Learning: Deep Learning
- Machine Learning: Probabilistic Machine Learning
Abstract
Extrapolation is a well-known technique for solving convex optimization and variational inequalities and recently attracts some attention for non-convex optimization. Several recent works have empirically shown its success in some machine learning tasks. However, it has not been analyzed for non-convex minimization and there still remains a gap between the theory and the practice. In this paper, we analyze gradient descent and stochastic gradient descent with extrapolation for finding an approximate first-order stationary point in smooth non-convex optimization problems. Our convergence upper bounds show that the algorithms with extrapolation can be accelerated than without extrapolation.
- [Bolte et al., 2017] Jérôme Bolte, Trong Phong Nguyen, Juan Peypouquet, and Bruce W Suter. From error bounds to the complexity of first-order descent methods for con- vex functions. Math. Program., 165(2):471-507, 2017.
- [Chapelle et al., 2009] Olivier Chapelle, Chuong B Do, Choon H Teo, Quoc V Le, and Alex J Smola. Tighter bounds for structured estimation. In NIPS, pages 281-288, 2009.
- [Chen et al., 2019] Zaiyi Chen, Zhuoning Yuan, Jinfeng Yi, Bowen Zhou, Enhong Chen, and Tianbao Yang. Universal stagewise learning for non-convex problems with conver- gence on averaged solutions. In ICLR, 2019.
- [Chiang et al., 2012] Chao-Kai Chiang, Tianbao Yang, Chia-Jung Lee, Mehrdad Mahdavi, Chi-Jen Lu, Rong Jin, and Shenghuo Zhu. Online optimization with gradual variations. In COLT, pages 6.1-6.20, 2012.
- [Dang and Lan, 2015] Cong D. Dang and Guanghui Lan. On the convergence properties of non-euclidean extragradi- ent methods for variational inequalities with generalized monotone operators. Comp. Opt. and Appl., 60(2):277- 310, 2015.
- [Davis and Drusvyatskiy, 2018] Damek Davis and Dmitriy Drusvyatskiy. Stochastic model-based minimiza- tion of weakly convex functions. arXiv preprint arXiv:1803.06523, 2018.
- [Diakonikolas and Orecchia, 2018] Jelena Diakonikolas and Lorenzo Orecchia. Accelerated extra-gradient descent: A novel accelerated first-order method. In LIPIcs-Leibniz In- ternational Proceedings in Informatics, volume 94, 2018.
- [Ghadimi and Lan, 2013] Saeed Ghadimi and Guanghui Lan. Stochastic first-and zeroth-order methods for non- convex stochastic programming. SIAM Journal on Opti- mization, 23(4):2341-2368, 2013.
- [Ghadimi and Lan, 2016] Saeed Ghadimi and Guanghui Lan. Accelerated gradient methods for nonconvex nonlin- ear and stochastic programming. Math. Program., 156(1- 2):59-99, 2016.
- [Ghadimi et al., 2016] Saeed Ghadimi, Guanghui Lan, and Hongchao Zhang. Mini-batch stochastic approximation methods for nonconvex stochastic composite optimization. Math. Program., 155(1-2):267-305, 2016.
- [Gidel et al., 2018] Gauthier Gidel, Hugo Berard, Pascal Vincent, and Simon Lacoste-Julien. A variational in- equality perspective on generative adversarial nets. arXiv preprint arXiv:1802.10551, 2018.
- [Hartman and Stampacchia, 1966] Philip Hartman and Guido Stampacchia. On some non-linear elliptic differential-functional equations. Acta mathematica, 115(1):271-310, 1966.
- [Jain et al., 2013] Prateek Jain, Praneeth Netrapalli, and Su- jay Sanghavi. Low-rank matrix completion using alternat- ing minimization. In STOC, pages 665-674, 2013.
- [Juditsky et al., 2011] Anatoli Juditsky, Arkadi Nemirovski, and Claire Tauvel. Solving variational inequalities with stochastic mirror-prox algorithm. Stochastic Systems, 1(1):17-58, 2011.
- [Korpelevich, 1976] GM Korpelevich. The extragradient method for finding saddle points and other problems. Rus- sian; English translation in Matekon, 12:747-756, 1976.
- [Lin et al., 2018] Qihang Lin, Mingrui Liu, Hassan Rafique, and Tianbao Yang. Solving weakly-convex- weakly-concave saddle-point problems as successive strongly monotone variational inequalities. CoRR, arXiv:1810.10207, 2018.
- [Luo and Tseng, 1993] Zhi-Quan Luo and Paul Tseng. Error bounds and convergence analysis of feasible descent meth- ods: a general approach. Annals of Operations Research, 46(1):157-178, 1993.
- [Mertikopoulos et al., 2018] Panayotis Mertikopoulos, Houssam Zenati, Bruno Lecouat, Chuan-Sheng Foo, Vijay Chandrasekhar, and Georgios Piliouras. Mirror de- scent in saddle-point problems: Going the extra (gradient) mile. arXiv preprint arXiv:1807.02629, 2018.
- [Monteiro and Svaiter, 2013] Renato DC Monteiro and Be- nar Fux Svaiter. An accelerated hybrid proximal extragra- dient method for convex optimization and its implications to second-order methods. SIAM Journal on Optimization, 23(2):1092-1125, 2013.
- [Nemirovski, 2004] Arkadi Nemirovski. Prox-method with rate of convergence O(1/t) for variational inequalities with lipschitz continuous monotone operators and smooth convex-concave saddle point problems. SIAM Journal on Optimization, 15(1):229-251, 2004.
- [Nesterov, 1983] Yurii E Nesterov. A method for solving the convex programming problem with convergence rate O(1/k 2 ). In Dokl. Akad. Nauk SSSR, volume 269, pages 543-547, 1983.
- [Nesterov, 1998] Yurii Nesterov. Introductory lectures on convex programming volume i: Basic course. 1998.
- [Nguyen and Sanner, 2013] Tan Nguyen and Scott Sanner. Algorithms for direct 0-1 loss optimization in binary clas- sification. In ICML, pages 1085-1093, 2013.
- [Nguyen et al., 2018] Trong Phong Nguyen, Edouard Pauwels, Emile Richard, and Bruce W Suter. Extragradi- ent method in optimization: Convergence and complexity. J. Optim. Theory Appl., 176(1):137-162, 2018.
- [Yan et al., 2018] Yan Yan, Tianbao Yang, Zhe Li, Qihang Lin, and Yi Yang. A unified analysis of stochastic mo- mentum methods for deep learning. In IJCAI, pages 2955- 2961, 2018. IJCAI
- [Yang et al., 2014] Tianbao Yang, Mehrdad Mahdavi, Rong Jin, and Shenghuo Zhu. Regret bounded by gradual vari- ation for online convex optimization. Machine Learning, 95(2):183-223, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
We are interested in solving the following non-convex optimization problem:
where f (x) is L-smooth. When the objective function is written as an expectation of a random function, then (1) becomes a stochastic non-convex optimization problem:
where ξ is a random variable. Non-convex optimization has brought tremendous success in many areas of machine learning including deep learning and low-rank matrix completion [Jain et al., 2013]. Many existing works have shown non-convex losses may yield improved robustness and classification accuracy [Chapelle et al., 2009; Nguyen and Sanner, 2013]. It is well known that traditional gradient descent (GD) and its variants such as stochastic gradient descent (SGD) are widely used in solving the problems (1) and (2), respectively. The convergence results are also well studied for both GD and SGD methods [Nesterov, 1998; Ghadimi and Lan, 2013; Yan et al., 2018]. For example, [Nesterov, 1998] has shown that GD enjoys an iteration complexity of O(1/ϵ2 ) for finding an ϵ-stationary point
(i.e., x satisfying ‖∇f(x)‖ ≤ ϵ) of problem (1). [Ghadimi and Lan, 2013] established an O(1/ϵ4 ) iteration complexity of SGD for finding an ϵ-stationary point in expectation satisfying E[‖∇f(x)‖] ≤ ϵ for (2). [Yan et al., 2018; Ghadimi and Lan, 2016] then extended the result to stochastic momentum methods and obtained the same order of complexity of SGD. Although SGD has achieved great success, recent works have shown that extragradient-type methods could perform better or converge faster than SGD in several machine learning tasks such as training generative adversarial networks (GANs) [Gidel et al., 2018] and learning Gaussian mixture models [Mertikopoulos et al., 2018]. However, the theoretical analysis of non-asymptotical convergence of extragradient-type methods remains under-explored for the general non-convex minimization problem (1) or the stochastic problem (2).
Extrapolation is an useful technique for optimization that could yield accelerated convergence for smooth problems. In the literature, the extrapolation technique is mostly known as extragradient method [Korpelevich, 1976], which takes the following update:
where G(·) denotes a gradient estimator of f(·). The difference from the standard GD (resp. SGD) lies at that it maintains two sequences of solutions. As a result, it requires computing two (stochastic) gradients for updating the solution once that is two times slower than each update of GD (resp. SGD).
In this paper, we analyze efficient variants of GD and SGD with extrapolation that only need to compute one gradient or stochastic gradient for each update, and establish their convergence results for finding an approximate first-order stationary point of non-convex minimization. We refer to these variants as GDE and SGDE, respectively. The main contributions of this paper are summarized in the following.
- We analyze a variant of GDE for a general smooth nonconvex problem (1), and shows that it enjoys an iteration complexity of O(1/ϵ2 ) for finding an ϵ-stationary point x of problem (1) that satisfies ‖∇f(x)‖ ≤ ϵ. Our convergence bound also exhibits that it could be faster than the GD method.
- We then analyze SGDE with a large mini-batch by showing that it enjoys a total gradient complexity of O(1/ϵ4 )
for finding an ϵ-stationary solution x of problem (2) in expectation with a mini-batch size of O(1/ϵ2 ). To avoid the large mini-batch requirement, we also propose another variant of SGDE, which only needs one sample to calculate a stochastic gradient and enjoys the same gradient complexity of O(1/ϵ4 ). Our convergence bounds also show that they could achieve practical speed-up compared with SGD.
To the best of our knowledge, this is first work that shows that GDE and SGDE can achieve potential faster convergence than GD and SGD for smooth non-convex optimization.
2 RelatedWork
The extragradient method was first introduced by [Korpelevich, 1976] for solving variational inequality problems (VIP) [Hartman and Stampacchia, 1966], i.e., finding a point x∗ ∈ Ω such that 〈G(x), x∗ - x〉 ≤ 0, ∀x ∈ Ω, where Ω is a nonempty closed convex subset of Rd and G : Rd → Rd is an operator. It generates a pair of sequences by carrying out two projections in each iteration: xt = PΩ[zt-1 - ηG(zt-1)] and zt = PΩ[zt-1-ηG(xt)], where PΩ denotes the projection operator. Most subsequent research works, e.g., [Nemirovski, 2004; Juditsky et al., 2011] have analyzed the convergence of extragradient method and its variants for solving (stochastic) VIP under the assumptions of L-Lipschtiz continuous and monotone operator G. If one considers the minimization of a function as a VI problem, then Lipschitz continuous and monotone operator means the function is convex and its gradient is Lipschitz continuous. Recently, (stochastic) extragradient gradient methods have been analyzed for nonmonotone VI [Dang and Lan, 2015; Lin et al., 2018] under some pseudo-monotonicity assumption. However, their analysis is either restricted to deterministic extragradient methods (e.g., [Dang and Lan, 2015; Lin et al., 2018]) or requires stronger assumption, i.e., pseudo-monotonicity, which is not necessarily satisfied for a non-convex minimization problem. In contrast, we directly analyze GDE and SGDE methods for smooth non-convex optimization problems with the only Lipchitz continuous gradient assumption.
In the context of convex minimization, extragradient method and its accelerated/extended version were well studied with the establishments of convergence rate. It has been shown [Luo and Tseng, 1993] that extragradient method is a special case of feasible descent method (FDM). Under local error bound assumption, [Luo and Tseng, 1993] have proved linear convergence of extragradient method for solving convex optimization problems. [Monteiro and Svaiter, 2013] applied hybrid proximal extragradient (HPE) method to convex optimization by proposing an accelerated HPE, enjoying the convergence rate of O(1/T 2 ). Recently, [Diakonikolas and Orecchia, 2018] developed an accelerated extragradient descent (AXGD) method for solving smooth and convex problems by combining the key ideas from Nesterov's accelerated gradient (NAG) method [Nesterov, 1983] and Nemirovski's mirror-prox method [Nemirovski, 2004]. AXGD achieved a convergence rate of O(1/T 2 ), matching the order of NAG's convergence rate. [Chiang et al., 2012; Yang et al., 2014] have considered the extragradient method for online convex optimization that repeatedly use an online gradient for two updates, and showed smaller regret compared with online gradient method for smooth functions.
Very recently, [Nguyen et al., 2018] proposed an extended extragradient method (EEG) to minimize the sum of two functions that one is smooth and another is convex. EEG uses two proximal gradient steps at each iteration, which is slightly different from two projection steps of classical extragradient method. Like classical extragradient method, EEG still has the issue of computing two gradients that might seriously affect the efficiency of the algorithm. For non-convex case, under the Kurdyka-Łojasiewicz (KL) assumption [Bolte et al., 2017], they have shown that the sequence generating by EEG converges to a first-order critical point of the considered problem with finite length. Their convergence rate is asymptotic and heavily depends on the Łojasiewicz exponent parameter θ [Bolte et al., 2017]. By contrast, we consider GDE methods for solving general smooth but non-convex problems, and estbalish a non-asymptotic convergence result with an iteration complexity of O(1/ϵ2 ) for finding an ϵ-stationary point with potential improvement than the GD method. We also propose two variants of GDE method in stochastic setting, namely mini-batch SGDE and stagewise SGDE with both of them achieving an iteration complexity of O(1/ϵ4 ) for finding an ϵ-stationary point in expectation. It is worth mentioning that our GDE and SGDE methods only need to compute gradient or stochastic gradient once per iteration inspired by [Chiang et al., 2012; Yang et al., 2014], which however focus on online convex optimization.
3 Preliminaries
In this section, we will present some notations. Let us denote by x∗ the global minimum of f(x), i.e., x∗ ∈ argminx∈Rd f(x). First, we make the following assumptions throughout the paper, which are standard assumptions made in the literature of stochastic non-convex optimization [Ghadimi and Lan, 2013; Yan et al., 2018].
Assumption 1. (i).f(x) has L-Lipschitz continuous gradient, i.e., ∃L > 0 s.t. ‖∇f(x) - ∇f(y)‖ ≤ L‖x - y‖, ∀x, y ∈ Rd ; (ii). For an initial solution x0, ∃∆ < ∞ s.t. f(x0) - f(x∗) ≤ ∆; (iii). every random function f(x; ξ) is differentiable; (iv). ∃G > 0 s.t. E[‖∇f(x; ξ) -∇f(x)‖2 ] ≤ G2 holds.
Next, to measure the convergence of non-convex and smooth optimization problems as in [Nesterov, 1998; Ghadimi and Lan, 2013; Yan et al., 2018], we use the following definition of first-order stationary point.
Definition 2 (First-order stationary point). For problem (1) or (2), a point x ∈ Rd is called a first-order stationary point if ‖∇f(x)‖ = 0. Moreover, if ‖∇f(x)‖ ≤ ϵ, then the point x is said to be an ϵ-stationary point.
To facilitate the analysis of the proposed SGDE algorithm, we introduce the Moreau envelope function of f (x) and proximal mapping, which are formally stated as follows.
Definition 3. For any γ > 0, the following function is called a Moreau envelope of f: fγ(x) :=
Algorithm 1 GDE
end for
miny∈Rd {f(y) + 1 2γ ‖y-x‖2}. Moreover, the optimal solution to the above problem is called a proximal mapping of f: proxγf (x) := argminy∈Rd {f(y) + 1 2γ ‖y - x‖2}.
Let ̂x := proxγf (x), which is well defined when γ ≤ 1/L due to that the objective function in the above problem is strongly convex. It has been shown that [Davis and Drusvyatskiy, 2018]
4 Main Results
In this section, we will present the proposed algorithms and their convergence results. We will first introduce a GDE algorithm for solving the problem (1) and a mini-batch SGDE algorithm for solving the problem (2). Then we will extend the mini-batch SGDE algorithm to stagewise SGDE without using a mini-batch of samples, which is more practical and user-friendly.
4.1 Gradient Descent with Extrapolation
The detailed updating steps of GDE are described in Algorithm 1, where η > 0 is the step size. Please note that the updates of our GDE is slightly different from the updates of traditional extragradient method: xt = zt-1 - η∇f(zt-1), zt = zt-1 - η∇f(xt). One issue of the traditional extragradient method is that it alternately computes the gradients at two points {zt} and {xt} for each iteration, implying that it is twice costly than the GDmethod that computes one gradient per-iteration. By contrast, our considered GDE method stores and reuses the previous gradient to update the new extrapolation point. That is to say, our GDE only requires computing gradient once per-iteration. The similar idea was used in the online convex optimization [Yang et al., 2014; Chiang et al., 2012] and recently by [Gidel et al., 2018] for training GAN. In this paper, we focus on analyzing the convergence of GDE for non-convex optimization, and the result is presented in Theorem 4.
Theorem 4. Under Assumption 1 (i), let η ≤ 1 12L and x1 = z0 = x0, then GDE ensures that
Algorithm 2 Mini-batch SGDE
end for
where x∗ = argminx∈Rd f(x). Under Assumption 1 (ii), in particular in order to have mint∈{1,...,T} ‖∇f(xt)‖ ≤ ϵ, the iteration complexity is T = O(1/ϵ2 ).
The iteration complexity O(1/ϵ2 ) of GDE is at least the same order of the GD method for smooth non-convex optimization. However, comparing with the convergence upper bound of GD, the above bound of GDE in (5) has an additional negative term- 1 η2 T ∑T -1 t=0 ‖xt+1-xt‖2 , which should be beneficial for accelearting convergence in practice.
4.2 Stochastic Gradient Descent with Extrapolation
Next, we study mini-batch SGDE for solving (2) and its convergence. The updates of mini-batch SGDE are presented in Algorithm 2. The convergence result of mini-batch SGDE is given in Theorem 5.
Theorem 5. Under Assumption 1, let η ≤ 1 12L and x1 = z0 = x0, then SGDE ensures that
where x∗ = argminx∈Rd f(x). In order to have mint∈{1,...,T} E[‖∇f(xt)‖] ≤ ϵ, the iteration complexity is T = O(1/ϵ2 ) with mini-batch size m = O(1/ϵ2 ), indicating that the gradient complexity is O(1/ϵ4 ).
The gradient complexity O(1/ϵ4 ) of mini-batch SGDE matches that of mini-batch SGD method for stochastic nonconvex optimization [Ghadimi et al., 2016]. However, comparing with the convergence upper bound of SGD, the above bound of GDE in (6) also has an additional negative term
4.3 Stagewise SGDE
In the previous subsection, mini-batch SGDE requires the mini-batch size in the order of O(1/ϵ2 ), which might be not practical when the target accuracy ϵ is sufficiently small. In this subsection, we propose a new variant of SGDE without requiring a large mini-batch size, which is described in Algorithm 4 with a subroutine SGDE in Algorithm 3. We refer to this algorithm as stagewise SGDE. For s-th stage, stagewise SGDE solves the following subproblem approximately fs(x) = f(x) + 1 2γ ‖x - xs-1 ‖2 , where xs-1 is the solution of the last stage, and γ = 1 4L is a constant. It is easy to
Algorithm 3 SGDE(x0, f, η, T )
Algorithm 4 Stagewise SGDE
end for
Return: xτ , τ is randomly chosen from {1, . . . , S} according to probabilities pτ = wτ ∑Ss=1 ws , τ = 1, . . . , S.
show that fs(x) is convex under the Assumption 1 (i), meaning that one may employ SGDE algorithm with convergence guarantee for convex problems. By using the convexity of fs, the subroutine SGDE usually returns an average solution. Besides, stagewise SGDE uses a decreasing sequence of step size ηs and an increasing sequence of iteration number Ts. Different from GDE and mini-batch SGDE, the final solution of stagewise SGDE is selected from the sequence of stagewise averaged solutions {xs} based on non-uniform sampling probabilities increasing as the stage number s. It is notable that this type of stagewise algorithm has been investigated in existing studies (see [Chen et al., 2019] and references therein). However, to the best of our knowledge, the proposed algorithm is the first work that runs SGDE method in a stagewise manner with the theoretical guarantee for nonconvex optimization. We present the convergence result of stagewise SGDE in Theorem 6.
Theorem 6. Under Assumption 1 (i), (iii), (iv) and suppose there exists ∆ > 0 such that E[f(xs ) - f(x∗)] ≤ ∆ for s = 0, 1, . . ., by running Algorithm 4 with γ = 1 4L , ws = sα (α > 1), ηs = cγ 3s ≤ 1 2L = γ3 , and Ts = 36s c , then
where ∆S = 60 ∑S+1 s=1 wsDTs γ ∑S+1 s=1 ws withDTs = 1 16Tsηs ∑Ts t=1 ‖xt - xt-1‖2 . Therefore, in order to have E[‖∇f(xτ)‖2 ] ≤ ϵ2 , we can set S = O(1/ϵ2 ). The total number of iterations is O ( 1 ϵ4 ).
It is notable that the assumption E[f(xs ) - f(x∗)] ≤ ∆ for s = 0, 1, . . . is slightly stronger than Assumption 1 (ii). However, one can derive a similar convergence result relying on Assumption 1 (ii) by using uniform-sampling, which is worse by a logarithmic factor. Although the iteraction complexity of stagewise SGDE mathches that of stagewise SGD
in [Chen et al., 2019], the above bound of stagewise SGDE in (7) has an additional negative term -∆S, comparing with the convergence upper bound of stagewise SGD. This negative term could help improve convergence in practice.
4.4 Proofs
Due to limitation of space, we only include the proof of Theorem 6 here. The proofs of Theorem 4 and 5 can be found at https://arxiv.org/abs/1901.10682. Before starting the proof, we present a key lemma in [Nemirovski, 2004], which will be used in our analysis.
Lemma 1 (Lemma 3.1, [Nemirovski, 2004]). Let ω(z) be a α-strongly convex function with respect to the norm ‖ · ‖, whose dual norm is denoted by ‖ · ‖∗, and D(x, z) = ω(x) - (ω(z) + (x - z)⊤ω′ (z)) be the Bregman distance induced by function ω(x). Let Z be a convex compact set, and U ⊆ Z be convex and closed. Let z ∈ Z, γ > 0, consider the points, x = argminu∈U γu⊤ξ + D(u, z) and z+ = argminu∈U γu⊤ζ +D(u, z), then for any u ∈ U, we have
Proof of Theorem 6. For the s-th stage, the following problem is solved: minx fs(x) = f(x) + 1 2γ ‖x - xs-1 ‖2 , where xs-1 is the solution from last stage. Let define ̂zs = argminx fs(x). By applying Lemma 1 with u = ̂zs, x = xt, z = zt-1, z+ = zt, ξ = ∇fs(xt-1; ξt-1), ζ = ∇fs(xt; ξt), γ = ηs, we have
Taking average over t = 1, . . . , Ts for above inequality and by the convexity of f(x), then rearranging the inequality we have
where ∆t := ∇f(xt; ξt) - ∇f(xt), and the last inequality is due to ‖x1 + x2‖22 ≤ 2(‖x1‖22 + ‖x2‖22 ) and ‖x1 + x2 + x3‖22 ≤ 3(‖x1‖22 + ‖x2‖22 + ‖x3‖22 ). By the smoothness of f(x) we have ηs Ts ∑Ts t=1 ‖∇f(xt) - ∇f(xt-1)‖2 ≤ ηsL2 Ts ∑Ts t=1 ‖xt - xt-1‖2 . Note that ∑Ts t=1 (‖xt - zt-1‖2 + ‖xt - zt‖2 ) ≥ 12 ∑Ts t=1 ‖xt - xt-1‖2 + 12 ‖x1 - x0‖2 ≥ 1 2 ∑Ts t=1 ‖xt - xt-1‖2 . By setting of γ = 1/(4L), then the above iequality becomes
where the last inequality is due to ηs ≤ 1 16L so that 3ηsL2 - 1 4ηs ≤ - 1 16ηs and the definition of DTs . Since E[∇fs(xt; ξt)⊤(xt - ̂zs)|xt,∆t-1, . . . ,∆0] = ∇fs(xt)⊤(xt -̂zs), and E[‖∆t‖2 |xt,∆t-1, . . . ,∆0] ≤ G2 , then by the convexity of fs(x) we have
where the uses the fact that z0 = xs-1 in the last inequality. Since fs(xs ) = f(xs ) + 1 2γ ‖xs - xs-1 ‖2 and fs(̂zs) ≤ f(xs-1 ), then
By Young's inequality ‖xs - xs-1 ‖2 ≥ 1 2 ‖̂zs - xs-1 ‖2 -
where the second inequality uses the (γ-1 -µ)-strong convex of fs(x) and the last inequality uses (8). By setting γ-1 = 2µ, then the above inequality will be
As long as ηsTs ≥ 12γ, and by (3), we know ∇fγ(xs-1 ) = 1 γ (̂zs - xs-1 ), then γ8 E[‖∇fγ(xs-1 )‖2] ≤ 36ηsG2 + E[f (xs-1 ) - f (xs )] - 3DTs , which implies
E [ws‖∇fγ (xs-1 )‖2 ] ≤16µE [ws(f (xs-1 ) - f (xs ))]
+ 576µwsηsG2 - 48µwsDTs .
By summing over s = 1, . . . , S + 1 we get
Then taking the expectation over τ, it becomes
By using the similar analysis in [Chen et al., 2019], we have ∑S+1 s=1 ws(f(xs-1 ) - f(xs )) ≤ wS+1∆. Then,
We know ws = sα (α > 1), the standard calculus tells ∑Ss=1 sα ≥ ∫ S 0 xαdx = Sα+1 α+1 , ∀α > 0, ∑Ss=1 sα-1 ≤ Sα, ∀α ≥ 1, and ∑Ss=1 sα-1 ≤ ∫ S 0 xα-1dx = Sα α , ∀0 < α < 1. Since ηs = c Ls < 1 2L , (L = 3µ = 3 2γ ) then
By the results in (4), we know for any x ‖∇f(x)‖ ≤ ‖∇f (x) - ∇f (̂x)‖ + ‖∇f (̂x)‖ ≤ L‖x - ̂x‖ + ‖∇fγ (x)‖ = (1 + Lγ)‖∇fγ(x)‖ = 52 ‖∇fγ(x)‖. Therefore, in order to have E[‖∇f(xτ )‖2 ] ≤ ϵ2 , i.e., E[‖∇fγ(xτ )‖2 ] ≤ 4 25 ϵ2 , we can set S = O(1/ϵ2 ). The total number of iterations is
5 Experiments
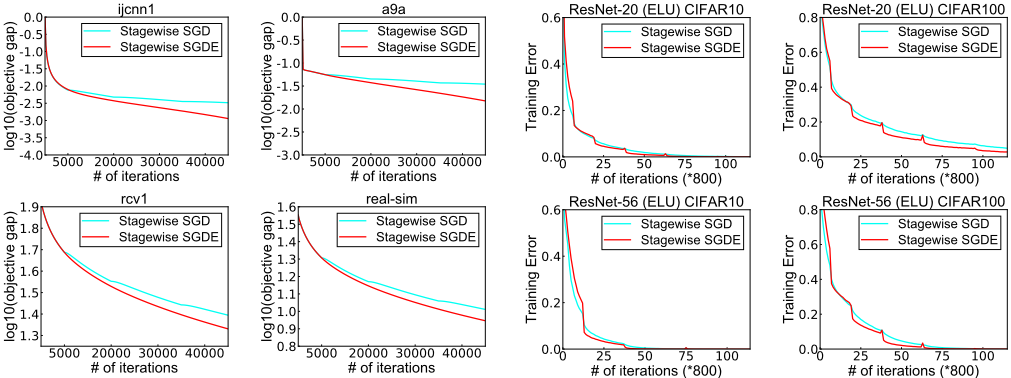
To justify the theoretical findings, we provide some empirical results of solving two different non-convex minimization problems, namely learning regularized non-linear leastsquared (NLLS) model and deep neural network (DNN) model. We compare the proposed stagewise SGDE with stagewise SGD proposed in [Chen et al., 2019]. For all experiments, the value of γ is fixed to be 5000. For stagewise SGD, the initial step size η is tuned in [0.1 ∼ 100] and the initial T0 is tuned in [1000 ∼ 10000], then the results with best performance are reported. The step size and initial T0 of stagewise SGDE are fixed to the same values as that of stagewise SGD.
The objective function of regularized NLLS problem is given by 1n ∑ki=1 (bi - σ(xT ai))2 + ∑di=1 λx2i 1+x2i , where ai ∈
Figure 2: Comparisons of Stagewise SGD and Stagewise SGDE for learning ResNets.
Rd is the feature vector of data, bi ∈ {0, 1} is the label of data, and σ(s) = 1 1+e-s is sigmoid function. We fix λ = 0.01 and conduct the experiments for binary classification on four datasets: ijcnn1, a9a, rcv1 and real-sim from libsvmwebsite. We report the log-scale of objective gap v.s. iteration number in Figure 1, showing that stagewise SGDE performs consistently better across all datasets.
For DNN model, we evaluate two algorithms for learning ResNet20 and ResNet56 on two benchmark datasets, i.e., CIFAR-10 and CIFAR-100. To be consistent with our assumption, we replace non-smooth activation function ReLU by a smooth activation function ELU (α = 1). We fixed the batch-size as 128. We train the deep learning models up to 8 × 10⁴ iterations. We presented the results of training error v.s. number of iterations in Figure 2. The results show that stagewise SGDE converges faster than Stagewise-SGD especially on CIFAR-100 data.
6 Conclusions
In this paper, we have analyzed gradient descent with extrapolation for solving smooth non-convex optimization problems and two stochastic variants of gradient methods with extrapolation for solving smooth non-convex stochastic optimization problems. We have established their convergence results in terms of finding an approximate first-order stationary point. In particular, the convergence upper bounds of the proposed algorithms exhibit that they could converge faster than algorithms without extrapolation, which are also supported by our empirical studies.
Acknowledgements
The authors thank the anonymous reviewers for their helpful comments. Y. Xu, Z. Yuan and T. Yang are partially supported by National Science Foundation (IIS-1545995).
@inproceedings{ijcai2019p556,
  title     = {On the Convergence of (Stochastic) Gradient Descent with Extrapolation for Non-Convex Minimization},
  author    = {Xu, Yi and Yuan, Zhuoning and Yang, Sen and Jin, Rong and Yang, Tianbao},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {4003--4009},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/556},
  url       = {https://doi.org/10.24963/ijcai.2019/556},
}
TY - CPAPER TI - On the Convergence of (Stochastic) Gradient Descent with Extrapolation for Non-Convex Minimization AU - Xu, Yi AU - Yuan, Zhuoning AU - Yang, Sen AU - Jin, Rong AU - Yang, Tianbao T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 4003 EP - 4009 DO - 10.24963/ijcai.2019/556 UR - https://doi.org/10.24963/ijcai.2019/556 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





