
Subgoal-Based Temporal Abstraction in Monte-Carlo Tree Search
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 5562-5568.
https://doi.org/10.24963/ijcai.2019/772
Keywords
- Planning and Scheduling: Temporal and Hybrid planning
- Planning and Scheduling: Planning Algorithms
- Planning and Scheduling: Hierarchical planning
Abstract
We propose an approach to general subgoal-based temporal abstraction in MCTS. Our approach approximates a set of available macro-actions locally for each state only requiring a generative model and a subgoal predicate. For that, we modify the expansion step of MCTS to automatically discover and optimize macro-actions that lead to subgoals. We empirically evaluate the effectiveness, computational efficiency and robustness of our approach w.r.t. different parameter settings in two benchmark domains and compare the results to standard MCTS without temporal abstraction.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-Time Analysis of the Multiarmed Bandit Problem. Machine learning, 2002.
- [Bai et al., 2012] Aijun Bai, Feng Wu, and Xiaoping Chen. Online planning for large MDPs with MAXQ decomposi- tion. In AAMAS. IFAAMAS, 2012.
- [Bai et al., 2016] Aijun Bai, Siddharth Srivastava, and Stu- art J. Russell. Markovian State and Action Abstractions for MDPs via Hierarchical MCTS. In IJCAI. IJCAI/AAAI, 2016.
- [Barto and Mahadevan, 2003] Andrew G. Barto and Sridhar Mahadevan. Recent advances in hierarchical reinforce- ment learning. Discrete Event Dynamic Systems, 13(1), Jan 2003.
- [Bellman, 1957] Richard Bellman. Dynamic Programming. Princeton University Press, Princeton, NJ, USA, 1957.
- [Botvinick et al., 2009] Matthew M. Botvinick, Yael Niv, and Andrew C. Barto. Hierarchically organized behav- ior and its neural foundations: A reinforcement learning perspective. Cognition, 113(3), 2009.
- [Browne et al., 2012] Cameron Browne, Edward Jack Pow- ley, Daniel Whitehouse, Simon M. Lucas, Peter I. Cowl- ing, Philipp Rohlfshagen, Stephen Tavener, Diego Perez Liebana, Spyridon Samothrakis, and Simon Colton. A Survey of Monte Carlo Tree Search Methods. IEEE Trans. Comput. Intellig. and AI in Games, 4(1), 2012.
- [Chaslot et al., 2008] Guillaume M. J. B. Chaslot, Mark H. M. Winands, and H. Jaap van den Herik. Paral- lel monte-carlo tree search. In Computers and Games. Springer, 2008.
- [Dietterich, 2000] Thomas G. Dietterich. Hierarchical Rein- forcement Learning with the MAXQ Value Function De- composition. Journal of Artificial Intelligence Research, 13, 2000.
- [He et al., 2010] Ruijie He, Emma Brunskill, and Nicholas Roy. PUMA: Planning Under Uncertainty with Macro- Actions. In AAAI. AAAI Press, 2010.
- [Jaskowski et al., 2015] Wojciech Jaskowski, Marcin Grze- gorz Szubert, Pawel Liskowski, and Krzysztof Kraw- iec. High-Dimensional Function Approximation for Knowledge-Free Reinforcement Learning: a Case Study in SZ-Tetris. In GECCO. ACM, 2015.
- [Kaelbling, 1993] Leslie Pack Kaelbling. Hierarchical Learning in Stochastic Domains: Preliminary Results. In ICML. Morgan Kaufmann, 1993.
- [Kocsis and Szepesvári, 2006] Levente Kocsis and Csaba Szepesvári. Bandit based Monte-Carlo Planning. In Eur. Conf. Machine Learning. Springer, 2006.
- [Mausam and Kolobov, 2012] Mausam and Andrey Kolobov. Planning with Markov Decision Processes: An AI Perspective. Synthesis Lect. on AI and Machine Learning. Morgan & Claypool Publishers, 2012.
- [Parr and Russell, 1998] Ronald Parr and Stuart Russell. Re- inforcement learning with hierarchies of machines. In 1997 Conf. on Advances in Neural Information Process- ing Systems, NIPS '97. MIT Press, 1998.
- [Puterman, 2014] Martin L Puterman. Markov Decision Pro- cesses: discrete stochastic dynamic programming. John Wiley & Sons, 2014.
- [Rubin and Watson, 2011] Jonathan Rubin and Ian Watson. Computer poker: A review. Artificial Intelligence, 175(5), 2011.
- [Russell and Norvig, 2010] S. Russell and P. Norvig. Arti- ficial Intelligence: A Modern Approach. Prentice Hall, 2010.
- [Scherrer et al., 2015] Bruno Scherrer, Mohammad Ghavamzadeh, Victor Gabillon, Boris Lesner, and Matthieu Geist. Approximate modified policy iteration and its application to the game of Tetris. Journal of Machine Learning Research, 16, 2015.
- [Silver et al., 2017] David Silver, Julian Schrittwieser, Karen Simonyan, Ioannis Antonoglou, Aja Huang, Arthur Guez, Thomas Hubert, Lucas Baker, Matthew Lai, Adrian Bolton, Yutian Chen, Timothy Lillicrap, Fan Hui, Laurent Sifre, George van den Driessche, Thore Graepel, and Demis Hassabis. Mastering the game of Go without human knowledge. Nature, 550, October 2017.
- [Solway et al., 2014] Alec Solway, Carlos Diuk, Natalia Córdova, Debbie Yee, Andrew G. Barto, Yael Niv, and Matthew M. Botvinick. Optimal behavioral hierarchy. PLOS Computational Biology, 10(8), August 2014.
- [Sutton and Barto, 2018] Richard S. Sutton and Andrew G. Barto. Reinforcement Learning: An Introduction. MIT Press, second edition, 2018.
- [Sutton et al., 1999] Richard S. Sutton, Doina Precup, and Satinder P. Singh. Between MDPs and Semi-MDPs: A Framework for Temporal Abstraction in Reinforcement Learning. Artif. Intell., 112(1-2), 1999.
- [Thiery and Scherrer, 2009] Christophe Thiery and Bruno Scherrer. Building Controllers for Tetris. ICGA Journal, 32(1), 2009.
- [Vien and Toussaint, 2015] Ngo Anh Vien and Marc Tous- saint. Hierarchical Monte-carlo Planning. In Proc. of the Twenty-Ninth AAAI Conference on Artificial Intelligence, AAAI'15. AAAI Press, 2015.
- [Weinstein and Littman, 2013] Ari Weinstein and Michael L Littman. Open-Loop Planning in Large-Scale Stochastic Domains. In 27th AAAI Conference on Artificial Intelli- gence, 2013.
- [Zhongjie et al., 2011] Cai Zhongjie, Dapeng Zhang, and Bernhard Nebel. Playing Tetris Using Bandit-Based Monte-Carlo Planning. In AISB 2011: AI and Games, Jan- uary 2011.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Markov Decision Processes (MDPs) provide the formal foundation for many current approaches to planning and decision making [Russell and Norvig, 2010; Sutton and Barto, 2018]. In that context, making decisions at multiple levels of abstraction has been studied as a challenging problem [Barto and Mahadevan, 2003; Bai et al., 2012; Vien and Toussaint, 2015]. One approach is to compress the search space in the temporal dimension by introducing macro-actions at a coarser resolution of time, which is motivated by human decision making, where reasoning about the problem takes place at different levels [Botvinick et al., 2009]. This approach, which is known as temporal abstraction or hierarchical planning [Mausam and Kolobov, 2012; Sutton and Barto, 2018], can accelerate direct reinforcement learning and planning algorithms as it decomposes the domain into a hierarchy of subtasks or subgoals that can be addressed individually [Dietterich, 2000; He et al., 2010; Vien and Toussaint, 2015]. Primitive action sequences to achieve such subgoals can be combined into macro-actions to enable efficient decision making at higher levels.
Many approaches rely on extensive domain knowledge by assuming all subgoals or macro-actions per state to be fully known beforehand [Parr and Russell, 1998; Sutton et al., 1999; Dietterich, 2000]. However, a complete specification of subgoals or macro-actions is generally infeasible for domains with large state spaces and many subgoals.
For many problems, it is easy to determine whether a given state is desirable as a subgoal, but it is infeasible to specify all possible follow-up subgoals or macro-actions for each state in advance. Especially in online planning, subgoals and macroactions should be determined locally for each state, and only when needed, to meet real-time requirements.
In this paper, we propose an approach to general subgoalbased temporal abstraction in Monte Carlo Tree Search (MCTS). We assume the availability of a subgoal predicate (in addition to a generative model, i.e., an MDP), which we integrate into the expansion step of MCTS to automatically discover and optimize macro-actions that lead to subgoals (cf. Section 4). Empirical evaluation shows that subgoal-based MCTS is more efficient than standard MCTS with little loss w.r.t effectiveness in the gridworld domain or even considerable gain in Tetris (cf. Section 5).
2 Background
2.1 Markov Decision Processes
An MDP is defined as a tuple F = 〈S, A, P, R, γ〉, where S is a (finite) set of states, A is the (finite) set of primitive actions, P(st+1|st, at) is the transition probability, R(st, at) ∈ R is the reward, and γ ∈ [0, 1] is the discount factor [Puterman, 2014]. We always assume that st, st+1 ∈ S, at ∈ A, and rt = R(st, at), where st+1 is reached after executing the action at in state st at time step t. Most importantly, we assume MDPs to be discrete and to have deterministic state transitions, i.e., P(st+1|st, at) ∈ {0, 1} for all st+1, st, at.
The goal is to find a policy π : S → A which maximizes the expectation of return Gt at state st for a horizon H:
A policy π can be evaluated with a state value function V π (st) = Eπ[Gt|st], i.e., the expected return at state st. Qπ (st, at) = Eπ[Gt|st, at] is the action-value function, i.e., the expected return when executing action at in state st.
π is optimal iff V π (st) ≥ V π′ (st) for all st ∈ S and all policies π′ . We denote the optimal policy by π∗ and the value functions by V π∗ = V ∗ and Qπ∗ = Q∗ respectively.
2.2 Monte Carlo Online Planning
Planning searches for a (near-)optimal policy, given a model ˆ F of the actual environment F. ˆ F usually provides P and R of the underlying MDP. Global planning searches the whole state space S to find π∗ [Bellman, 1957; Weinstein and Littman, 2013]. An example is value iteration, which computes the optimal value function according to the Bellman equation [Bellman, 1957]:
Local planning only regards the current state st and possible future states to find a policy πt [Weinstein and Littman, 2013]. We focus on local Monte Carlo planning, where ˆ F is a generative or forward model, which can be used for simulation-based planning [Kocsis and Szepesv´ari, 2006; Weinstein and Littman, 2013] without reasoning about explicit probability distributions. Given st and at, ˆ F provides a sample 〈st+1, rt〉 ∼ ˆ F (st, at). We also focus on online planning, where planning is performed at every time step t with a horizon H and a computation budget nb. The recommended action at is executed in st, which thereby transitions to st+1. If st+1 is no terminal state, this procedure is repeated.
Monte Carlo Tree Search (MCTS) is a popular approach to Monte Carlo Planning and has been applied to a wide range of challenging environments [Rubin and Watson, 2011; Silver et al., 2017]. MCTS incrementally builds up a search tree, which stores the visit counts N(st), Nst,at , and the values V (st) and Q(st, at) for each simulated state and action respectively. MCTS iteratively executes the following four steps until a computation budget nb has run out:
Selection Starting from the root node as current state s0, the search tree is traversed by selecting nodes with a tree policy πtree until a leaf state node st is reached.
Expansion The leaf state node st is expanded by a new node representing the next state st+1, which is reached after simulating a random action at in ˆ F .
Simulation A rollout using a rollout policy πrollout is performed from st+1 until a maximum search depth H or a terminal state is reached.
Backup The observed rollout rewards are accumulated to Gt (Eq. 1) and used to update the value estimates and visit counts of every node in the simulated path.
Upper Confidence bounds applied to Trees (UCT) uses πtree(st) = argmaxat∈A UCB1(st, at) with UCB1 being defined by [Auer et al., 2002; Kocsis and Szepesv´ari, 2006]:
where c is an exploration constant. UCB1 balances between exploration and exploitation of actions. Exploration is encouraged by the second term multiplied with c and tries out actions to estimate action-values more accurately. The more at is selected in st the smaller the exploration term becomes and the more exploitation is encouraged, which greedily uses the action with the currently highest action-value Q(st, at). UCT has been shown to converge to the optimal best-first tree, given infinite computation [Kocsis and Szepesv´ari, 2006].
3 RelatedWork
Temporal abstraction methods summarize temporal sequences of primitive actions into macro-actions by dividing the original goal into subgoals, for which the planner can generate plans individually and independently [Kaelbling, 1993; Barto and Mahadevan, 2003; Solway et al., 2014].
There exist different frameworks for decision making using temporal abstraction: [Sutton et al., 1999] proposed options, where each option o has an internal policy πo which can be selected from specific states. If option o is selected, then πo is executed until a termination condition is met. [Dietterich, 2000] proposed MAXQ Value Function Decomposition by defining subtasks, with each subtask mi ∈ M having a pseudo-reward function. A subtask policy has to be computed for each subtask. In both cases, there is a high-level policy π, which has to select a lower level policy according to the corresponding option or subtask. These frameworks assume detailed prior knowledge (e.g. internal policy, reward function) about each subgoal, which is infeasible for very large macro-action spaces and many subgoals.
[He et al., 2010] proposed Planning under Uncertainty with Macro-Actions (PUMA), which generates macroactions from automatically discovered subgoals given a global subgoal distribution. Each macro-action at = 〈at, at+1, ..., at+L-1〉 represents an open-loop sequence of primitive actions. Macro-actions are determined by iteratively finding open-loop plans of length L, which can reach a randomly sampled subgoal state from a given state st. The action-value Q(st, at) is estimated via Monte Carlo simulation to determine the action to be executed. Our approach is closely related to PUMA: Each macro-action leads to a subgoal and is generated locally for each state during planning. However, PUMA assumes a fixed length and a fixed number of macro-actions, which is highly domain-dependent. Instead, our approach only requires a subgoal predicate, which can determine whether a given state is a subgoal or not. It does not need a pre-defined global distribution of subgoals.
4 Subgoal-based Temporal Abstraction
4.1 Terminology
Given a deterministic and discrete MDP, we define a macroaction mt = 〈at, ..., at+N-1〉 as an open-loop sequence of primitive actions ai ∈ A. The macro-action space M = A+ is the set of all non-empty sequences over A. The macro-level generative model F : S ×M→ S determines the successor state F(st,mt) = st+|mt| after performing mt ∈ M with length |mt| in state st. The reward function for macro-actions mt ∈ M is defined by:
We define a macro-level policy π : S → M to select macro-actions, which can be evaluated with a value function V π (st) = R(st, π(st)) + γ |π(st)|V π (F (st, π(st)))).
We define a set of subgoals G ⊆ S with G = {st ∈ S | g(st) = 1}, where g : S → {0, 1} is a subgoal predicate returning 1, if st is a subgoal, and 0 otherwise. G(st)
defines the set of subgoals directly reachable from state st with any macro-action. M(st, gt) contains all macro-actions that terminate in subgoal gt ∈ G when performed in state st and M(st) represents all macro-actions which can directly reach any subgoal gt ∈ G(st) from state st:
M∗ (st) ⊆M(st) is the set of macro-actions mt for state st which locally maximize the reward R(st, mt):
By assuming γ = 1, we can show that the hierarchically optimal value function V π∗ is preserved when replacing M(st) with the locally optimized set M∗ (st):
where rt = R(st, mt).
4.2 GeneratingMacro-Actions
We now describe an approach to approximate M∗ (st) for any given state st. ˆM(st) ≈ M∗ (st) is generated incrementally by randomly sampling a macro-action mt fromM(st). If mt reaches a previously undiscovered subgoal, it is added to ˆM(st). If a subgoal is rediscovered, the existing macroaction m′t is replaced with mt, when R(st, mt) > R(st, m′t ).
The sampling is regarded as a Bernoulli trial, where p is the action coverage representing the fraction of already discovered macro-actions of M∗ (st). Let X = 〈X1, ...,Xn〉 be a Bernoulli process according to the Bernoulli distribution B(p) with Xi ∼ B(p). Xi = 1, if the sampled macro-action is already known, and Xi = 0 otherwise. The likelihood L(p = p0|X) that the unknown action coverage p equals p0 given the observations X is defined by L(p = p0|X) = (nk)pk (1 - p)n-k ; k = ∑ni Xi. If all trials were successful (k = n), then L(p = p0|X) = pn . To test if p ≥ p0, we define a statistical test ψ : {0, 1}n → {0, 1} with null hypothesis H0 : p < p0 and alternative hypothesis H1 : p ≥ p0:
where α ∈ [0, 1] is the tolerated error.
If we consecutively sample n macro-actions, whose subgoals are already known, and n > logp0 α, we will assume that a coverage of at least p0 is achieved. Increasing the desired action coverage p0 leads to a higher percentage of discovered macro-actions of M∗ (st) and to higher quality of each macro-action in ˆM(st) at the cost of more trials.
Algorithm 1 Expansion with Macro-Action Generation
1: procedure ExpansionWithMA( ˆ F , g, t, st, H, p0, α) 2: n← 0 3: repeat ▷ discover macro actions until confident 4: st+1 ← st 5: mt ← 〈〉 6: repeat ▷ sample until macro state or horizon 7: at ∼ A 8: mt ← mt ++ 〈at〉 9: st+1 ← ˆ F (st+1, at) 10: until (g(st+1) = 1) ∨ (t + |mt| ≥ H) 11: if ∃m′t ∈ ˆM(st) : F(st,m′t ) = st+1 then 12: n ← n + 1 ▷ macro state rediscovered 13: if R(st, mt) > R(st, m′t ) then 14: ˆM(st) ← ( ˆM(st) \ {m′t }) ∪ {mt} 15: else ▷ new macro state discovered to expand 16: ˆM(st) ← ˆM(st) ∪ {mt} 17: return mt 18: until n > logp0 α 19: fullyExpanded(st) ← true 20: return nil4.3 Integration withMCTS
The approach described above can be easily integrated into MCTS, since actions are iteratively explored for each state. Instead of pre-computing the whole set of macro-actions, we only need to find one new macro-action in the expansion step. This saves computation time, since macro-actions are only generated on demand according to the selection policy.
The complete formulation of the modified expansion step is given in Algorithm 1, where ˆ F is the generative model of the MDP, g is the subgoal predicate, t is the current time step, st is the current state, H is the planning horizon, p0 is the desired action coverage, and α is the tolerated error.
Our approach constructs a search tree for deterministic MDPs, where the root node represents the current state, all other nodes represent subgoal states, and links represent macro-actions. Our expansion step updates the macro-action set ˆM(st) for the current leaf node representing st. If the desired action coverage p0 has been achieved, the node of st is considered as fully expanded and returns nil. The expansion step will not be invoked for fully expanded nodes. 1
The advantage of this approach is that only subgoals directly reachable from a given state are regarded. The set of available subgoals per state is only computed on demand, when the state is actually visited during tree search, and is not required to be specified beforehand. Our approach enables planning with macro-actions mt of arbitrary length (1 ≤ |mt| ≤ H - t), thus being more flexible than PUMA [He et al., 2010]. Note that the Backup step has to be adjusted to consider the discount of subgoal rewards R(st,mt) according to the length of each macro-action mt (Eq. 4).
1 For a complete description of that integration in pseudocode, please refer to github.com/hugo-voodo/temporalabstraction/blob/master/supplement.pdf.
4.4 Possible Variants and Enhancements
Modes. Similarly to [Bai et al., 2016], our approach can operate in different control modes. In hierarchical control mode, the MCTS returns the macro-action as sequence of primitive actions, which is successively applied to the real environment. In this case, planning is only performed at subgoal states, thus reducing the overall computation. In polling control mode, the MCTS returns only the first primitive action of the recommended macro-action. This mode can recover from locally poor decisions, since planning is performed at every time step t but requires more computation in total.
Tree Reuse. InMCTS, the computed subtree of the following state can be reused to avoid complete replanning by keeping the learned statistics from the previous planning step. If polling control mode is used, tree reuse cannot be trivially applied to our approach because the state nodes represent subgoal states, while planning can be performed on non-subgoal states in polling mode. Thus, we only regard tree reuse in combination with hierarchical control mode.
Parallelization. There exist many approaches to parallelization of MCTS ranging from tree parallelization with mutually exclusive locks to root parallelization, where multiple separate trees are generated and searched in parallel [Chaslot et al., 2008; Browne et al., 2012]. We only focus on root parallelization due to the minimal synchronization overhead. We also expect root parallelization to compensate for approximation errors caused by low action coverages, since multiple trees will generate different macro-action sets, thus converging to different trees. Since we focus on deterministic problems, it is most promising to make decisions based on the single best action found by an individual tree.
5 Experiments
5.1 Evaluation Environments
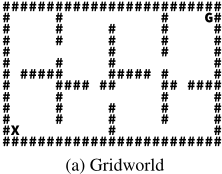
Gridworld is one of the must studied example domains in artificial intelligence [Sutton et al., 1999; Russell and Norvig, 2010; Bai et al., 2016; Sutton and Barto, 2018]. An agent has to navigate in a two-dimensional grid to reach a goal position. The agent is able to move north, east, south and west to adjacent grid cells, but it cannot pass obstacles in the grid. A reward of -0.01 is given at every time step. Reaching the goal gives a reward of 1 and terminates the episode. The setup used in this paper is shown in Fig. 1a. The grid is divided into eight rooms with connecting 'doors'.
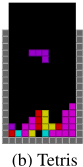
The Tetris game is another popular research domain in artificial intelligence research [Thiery and Scherrer, 2009; Zhongjie et al., 2011; Scherrer et al., 2015; Jaskowski et al., 2015]. An object called tetrimono has to be controlled in a Wb×Hb board (violet 'L' shape in Fig. 1b), while it is falling to the ground. At every time step, the tetrimono moves down to the next grid cell until it touches the ground (of stacked previous tetrimonos). The agent can rotate the tetrimono left or right, move it left or right, or do nothing. After the tetrimino has fallen down, a reward of 1-(0.5 h2c H2 b +0.5min{1, xX }) is given and a new tetrimono appears in the upper center of the board. hc is the current height of the stack, Hb is the board height, Wb is the board width, x is the number of holes in the tetrimono stack, and X = Wb 4 (Hb - 2) is an arbitrary upper bound on stack holes. The game ends with a reward of -1, when the tetrimono stack height exceeds the board height. The goal is to minimize the height of the stacked tetrimonos in the long run. We always set Wb = 10 and Hb = 10.
5.2 Methods
Online Planning
We implemented different instances of our approach, which we call Subgoal-MCTS (S-MCTS). 2 The polling control mode is used as default mode. S-MCTS-H uses hierarchical control mode and S-MCTS-H-R additionally enables tree reuse. We also implemented UCT of [Kocsis and Szepesv´ari, 2006], which we refer to as MCTS or as MCTS-R, if tree reuse is enabled. All MCTS implementations use UCB1 as tree policy and random rollouts. We also implemented random rollout planning, referred to as MC.
For each planning algorithm, we experimented with different settings of tunable parameters. 3 For all experiments, we set γ = 1, p0 = 0.95, and α = 0.001. We implemented root parallelization for all MCTS-based approaches using multithreading to generate multiple trees.
Subgoal Heuristics
For Gridworld, we use a subgoal predicate g returning 1, if the agent position is at a 'door' position with obstacles on opposing sides next to it, and 0 otherwise.
For Tetris, we use a subgoal predicate g, which returns 1, if the current tetrimono has fallen down, and 0 otherwise. Note that while it is easy to determine whether a given state is a subgoal or not (e.g., by checking the y-coordinate of the current tetrimono's position with our subgoal predicate g), it is infeasible to specify all possible subgoals for each tetrimono type beforehand, since there are too many possible combinations of position and rotation per tetrimono type.
5.3 Results
We ran each experiment with different parameter settings. Each setting was run 60 times for a maximum of 1000 time steps in Gridworld or 20000 time steps in Tetris.
2 The code can be found at github.com/jnptr/subgoal-mcts.
3 For all parameter configurations, see github.com/hugovoodo/temporal-abstraction/blob/master/supplement.pdf.
Performance-Computation Tradeoff
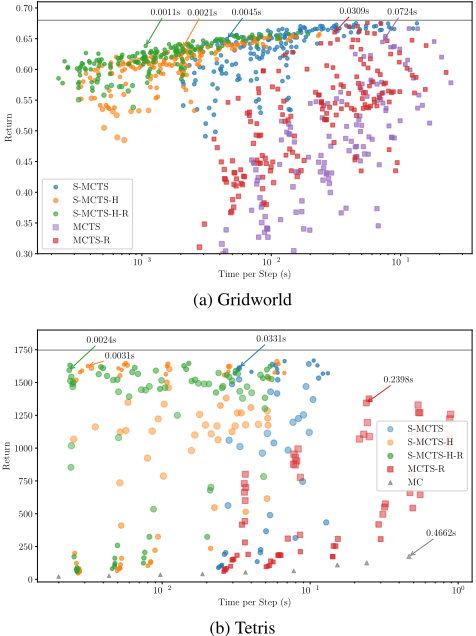
First, we evaluated the performance and computation time of each algorithm with different parameter settings (Section 5.2). The results are shown in Fig. 2. Each data point represents the average return for an average amount of computation time per step t given a specific parameter setting. The color indicates the algorithm as described in Section 5.2. The dotted horizontal line indicates the maximum possible return for the respective domain (which overestimates for Tetris).
In Gridworld (Fig. 2a), S-MCTS, S-MCTS-H, and SMCTS-H-R achieve competitive performance compared to MCTS and slightly lower performance than MCTS-R with much less computation time. In Tetris (Fig. 2b), we omitted MCTS due to intractable run times and replaced it with MC. S-MCTS-H and S-MCTS-H-R quickly achieve nearmaximum return with S-MCTS-H-R being less sensitive to the concrete parameter setting. S-MCTS is slower than SMCTS-H and S-MCTS-H-R but achieves the best overall performance. MCTS-R requires much more computation time than Subgoal-MCTS approaches, while being unable to keep up in performance. MC slightly improves with more computation time but is clearly inferior to all other approaches.
In both domains, S-MCTS-H and S-MCTS-H-R are generally faster than S-MCTS, since computation only takes place at subgoal states. Still, both approaches are able to achieve competitive performance compared to S-MCTS. S-MCTS-H and S-MCTS-H-R also seem to be less sensitive to the parameter settings than the other approaches.
Action Coverage and Parallelization
We also evaluated different combinations of desired action coverages p0 and tree counts in the Tetris domain. The results are shown in Fig. 3 for S-MCTS, S-MCTS-H, and SMCTS-H-R. Each plot shows the average return of each algorithm with the best parameter setting (Section 5.2), when using a particular number of trees, which are generated in parallel. The dotted horizontal line indicates the maximum possible return. Increasing p0 generally leads to increasing return and reduces the variance for all settings. Using a large number of trees can compensate for low desired action coverages p0, generally leading to higher returns, while requiring less time per step. In case of S-MCTS and S-MCTS-H (Fig. 3a and 3b), all settings achieve similar performance, when the desired action coverage is sufficiently large (p0 = 0.95). S-MCTS-H-R (Fig. 3c) has more variance in its returns, but requires much less time, when using many trees.
Robustness w.r.t. Subgoal Heuristics
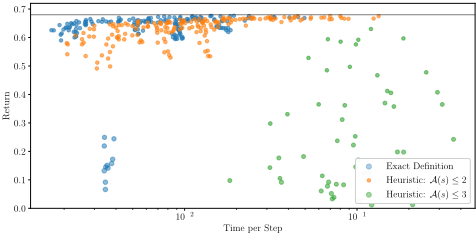
Finally, we evaluated the robustness of our approach w.r.t. different subgoal heuristics for the Gridworld domain with different parameter settings (Section 5.2). The 'exact definition' identifies subgoals by checking, if there are obstacles on opposing sides next to the agent, indicating a 'door' in the grid. A coarser heuristic (|A(st)| ≤ Na) checks, if the number of legal actions |A(st)| at the current state is Na at most. If Na = 3, e.g., then positions next to walls are regarded as subgoals as well. The results are shown in Fig. 4 for S-MCTS, S-MCTS-H, and S-MCTS-H-R. Each data point represents the average return for an average amount of computation time per step t given a specific parameter setting. The color indicates the used subgoal heuristic. The dotted horizontal line indicates the maximum return for the Gridworld domain. When using the heuristic |A(st)| ≤ 2, then all approaches perform slightly worse than the 'exact definition', while being similarly robust w.r.t. the parameter setting. However, when using the heuristic |A(st)| ≤ 3, then the performance is generally worse and all approaches are much more sensitive to the parameter setting, while requiring significantly more computation time. Hierarchical control mode and tree reuse seem to slightly improve the robustness of Subgoal-MCTS w.r.t. the parameter setting, while not having a general impact on the overall performance.
6 Discussion
We proposed an approach to general subgoal-based temporal abstraction in MCTS. Our approach approximates a set of macro-actions locally for each state only requiring a generative model and a subgoal predicate.
Our experiments show that S-MCTS and its variants are competitive against standard MCTS in terms of performancecomputation tradeoff. While all variants of S-MCTS perform slightly worse in the Gridworld domain, they are able to outperform MCTS-R in Tetris, while generally requiring much less computation time than MCTS in all domains.
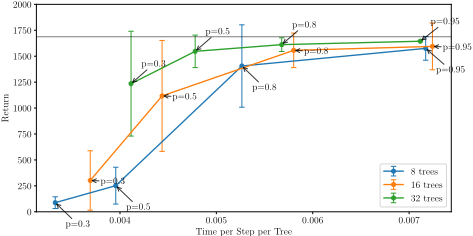
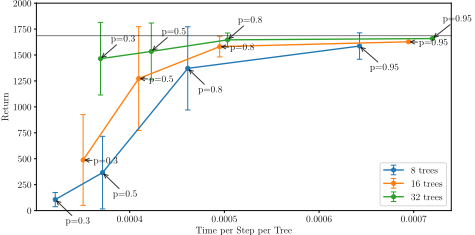
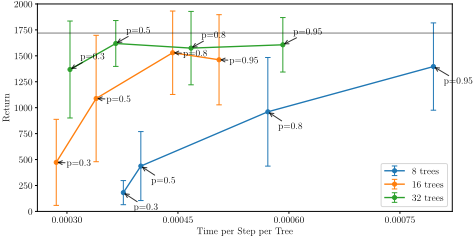
Figure 3: Average return per computation time per step (normalized by the number of trees) of S-MCTS, S-MCTS-H, and S-MCTS-H-R for different desired action coverages p0 and tree counts in the Tetris domain. The x-axis uses a logarithmic scale.
Exploration in S-MCTS depends on the number of subgoals. This was shown in the last experiment, where all variants of S-MCTS displayed worse performance, when using a very coarse subgoal heuristic.When using S-MCTS in hierarchical control mode, computational efficiency can be significantly increased. If a suboptimal choice has been made, S-MCTS-H is unable to recover from the performed actions until the next subgoal is reached, while S-MCTS in polling control mode can locally compensate for suboptimal choices at each time step. Enabling tree reuse slightly improves performance as shown in the first experiment (Fig. 2). Since tree reuse avoids complete replanning, S-MCTS can explore the search space more thoroughly to find better macro-actions. In addition, S-MCTS is shown to benefit from root paral-
- (a) Subgoal-MCTS in polling control mode (S-MCTS)
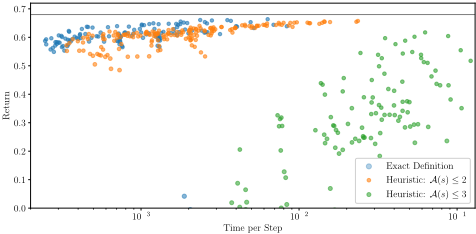
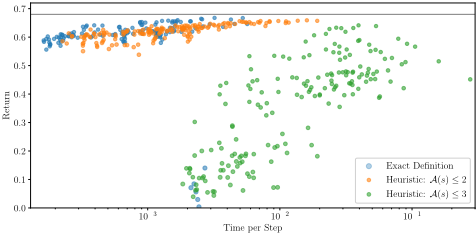
Figure 4: Average return per computation time per step of S-MCTS, S-MCTS-H, and S-MCTS-H-R for different subgoal definitions and parameter settings in the Gridworld domain. The x-axis uses a logarithmic scale.
lelization. When generating multiple search trees in parallel to search for macro-actions, the performance of all SMCTS variants can be further improved, while requiring less time. This encourages to exploit multiple cores in real-time applications to make high-quality decisions at certain time frames. When combining tree reuse with a high degree of parallelization, the search time can be drastically reduced by reusing the sets of discovered macro-actions from previous planning steps, while compensating for the approximation errors caused by each individual tree.
Overall, the question of how to adequately define subgoal predicates remains. Future work may further extend flexibility on subgoal predicates, for instance allowing to respect a history of states instead of just a single state.
@inproceedings{ijcai2019p772,
  title     = {Subgoal-Based Temporal Abstraction in Monte-Carlo Tree Search},
  author    = {Gabor, Thomas and Peter, Jan and Phan, Thomy and Meyer, Christian and Linnhoff-Popien, Claudia},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {5562--5568},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/772},
  url       = {https://doi.org/10.24963/ijcai.2019/772},
}
TY - CPAPER TI - Subgoal-Based Temporal Abstraction in Monte-Carlo Tree Search AU - Gabor, Thomas AU - Peter, Jan AU - Phan, Thomy AU - Meyer, Christian AU - Linnhoff-Popien, Claudia T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 5562 EP - 5568 DO - 10.24963/ijcai.2019/772 UR - https://doi.org/10.24963/ijcai.2019/772 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





