
Soft Threshold Ternary Networks
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 2298-2304.
https://doi.org/10.24963/ijcai.2020/318
Keywords
- Machine Learning: Deep Learning: Convolutional networks
- Machine Learning: Classification
Abstract
Large neural networks are difficult to deploy on mobile devices because of intensive computation and storage. To alleviate it, we study ternarization, a balance between efficiency and accuracy that quantizes both weights and activations into ternary values. In previous ternarized neural networks, a hard threshold Δ is introduced to determine quantization intervals. Although the selection of Δ greatly affects the training results, previous works estimate Δ via an approximation or treat it as a hyper-parameter, which is suboptimal. In this paper, we present the Soft Threshold Ternary Networks (STTN), which enables the model to automatically determine quantization intervals instead of depending on a hard threshold. Concretely, we replace the original ternary kernel with the addition of two binary kernels at training time, where ternary values are determined by the combination of two corresponding binary values. At inference time, we add up the two binary kernels to obtain a single ternary kernel. Our method dramatically outperforms current state-of-the-arts, lowering the performance gap between full-precision networks and extreme low bit networks. Experiments on ImageNet with AlexNet (Top-1 55.6%), ResNet-18 (Top-1 66.2%) achieves new state-of-the-art.
- [Cai et al., 2017] Zhaowei Cai, Xiaodong He, Jian Sun, and Nuno Vasconcelos. Deep learning with low precision by half-wave gaussian quantization. pages 5406-5414, 2017.
- [Choi, 2018] Jungwook Choi. Pact: Parameterized clipping activation for quantized neural networks. arXiv: Computer Vision and Pattern Recognition, 2018.
- [Courbariaux et al., 2014] Matthieu Courbariaux, Jean- Pierre David, and Yoshua Bengio. Low precision storage for deep learning. arXiv preprint arXiv:1412.7024, 2014.
- [Courbariaux et al., 2015] Matthieu Courbariaux, Yoshua Bengio, and Jeanpierre David. Binaryconnect: training deep neural networks with binary weights during propaga- tions. pages 3123-3131, 2015.
- [Courbariaux et al., 2016] Matthieu Courbariaux, Itay Hubara, Daniel Soudry, Ran El-Yaniv, and Yoshua Ben- gio. Binarized neural networks: Training deep neural networks with weights and activations constrained to+ 1 or-1. arXiv preprint arXiv:1602.02830, 2016.
- [Darabi et al., 2018] Sajad Darabi, Mouloud Belbahri, Matthieu Courbariaux, and Vahid Partovi Nia. Bn- n+: Improved binary network training. arXiv preprint arXiv:1812.11800, 2018.
- [Gupta et al., 2015] Suyog Gupta, Ankur Agrawal, Kailash Gopalakrishnan, and Pritish Narayanan. Deep learning with limited numerical precision. In International Con- ference on Machine Learning, pages 1737-1746, 2015.
- [Han et al., 2015] Song Han, Huizi Mao, and William J Dal- ly. Deep compression: Compressing deep neural network- s with pruning, trained quantization and huffman coding. arXiv preprint arXiv:1510.00149, 2015.
- [He et al., 2019] Yang He, Ping Liu, Ziwei Wang, Zhilan Hu, and Yi Yang. Filter pruning via geometric median for deep convolutional neural networks acceleration. In Proceed- ings of the IEEE Conference on Computer Vision and Pat- tern Recognition, pages 4340-4349, 2019.
- [Hinton et al., 2015] Geoffrey Hinton, Oriol Vinyals, and J- eff Dean. Distilling the knowledge in a neural network. arXiv preprint arXiv:1503.02531, 2015.
- [Howard et al., 2017] Andrew Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, M Andreetto, and Hartwig Adam. Mobilenets: Efficient convolutional neural networks for mobile vision applications. arXiv: Computer Vision and Pattern Recog- nition, 2017.
- [Jaderberg et al., 2014] Max Jaderberg, Andrea Vedaldi, and Andrew Zisserman. Speeding up convolutional neural net- works with low rank expansions. arXiv preprint arX- iv:1405.3866, 2014.
- [Li et al., 2016] Fengfu Li, Bo Zhang, and Bin Liu. Ternary weight networks. arXiv preprint arXiv:1605.04711, 2016.
- [Li et al., 2019] Yuhang Li, Xin Dong, Sai Qian Zhang, Haoli Bai, Yuanpeng Chen, and Wei Wang. Rtn: Reparameterized ternary network. arXiv preprint arX- iv:1912.02057, 2019.
- [Lin et al., 2017] Xiaofan Lin, Cong Zhao, and Wei Pan. Towards accurate binary convolutional neural network. In Advances in Neural Information Processing Systems, pages 345-353, 2017.
- [Liu et al., 2018] Zechun Liu, Baoyuan Wu, Wenhan Luo, Xin Yang, Wei Liu, and Kwang-Ting Cheng. Bi-real net: Enhancing the performance of 1-bit cnns with improved representational capability and advanced training algorith- m. In Proceedings of the European Conference on Com- puter Vision (ECCV), pages 722-737, 2018.
- [Liu et al., 2019] ChunLei Liu, Wenrui Ding, Xin Xia, Baochang Zhang, Jiaxin Gu, Jianzhuang Liu, Rongrong Ji, and Doermann David. Circulant binary convolutional networks: Enhancing the performance of 1-bit dcnns with circulant back propagation. In IEEE Conference on Com- puter Vision and Pattern Recognition, 2019.
- [Rastegari et al., 2016] Mohammad Rastegari, Vicente Or- donez, Joseph Redmon, and Ali Farhadi. Xnor-net: Ima- genet classification using binary convolutional neural net- works. In European Conference on Computer Vision, pages 525-542. Springer, 2016.
- [Tang et al., 2017] Wei Tang, Gang Hua, and Liang Wang. How to train a compact binary neural network with high accuracy? In Thirty-First AAAI Conference on Artificial Intelligence, 2017.
- [Wan et al., 2018] Diwen Wan, Fumin Shen, Li Liu, Fan Zhu, Jie Qin, Ling Shao, and Heng Tao Shen. Tbn: Con- volutional neural network with ternary inputs and binary weights. In Proceedings of the European Conference on Computer Vision (ECCV), pages 315-332, 2018.
- [Wang et al., 2018] Peisong Wang, Qinghao Hu, Yifan Zhang, Chunjie Zhang, Yang Liu, and Jian Cheng. Two- step quantization for low-bit neural networks. In Proceed- ings of the IEEE Conference on Computer Vision and Pat- tern Recognition, pages 4376-4384, 2018.
- [Zhou et al., 2016] Shuchang Zhou, Yuxin Wu, Zekun Ni, Xinyu Zhou, He Wen, and Yuheng Zou. Dorefa-net: Training low bitwidth convolutional neural networks with low bitwidth gradients. arXiv preprint arXiv:1606.06160, 2016.
- [Zhu et al., 2016] Chenzhuo Zhu, Song Han, Huizi Mao, and William J Dally. Trained ternary quantization. arXiv preprint arXiv:1612.01064, 2016.
- [Zhu et al., 2019] Shilin Zhu, Xin Dong, and Hao Su. Binary ensemble neural network: More bits per network or more networks per bit? In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 4923- 4932, 2019.
- [Zoph and Le, 2016] Barret Zoph and Quoc V Le. Neural architecture search with reinforcement learning. arXiv preprint arXiv:1611.01578, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Deploying deep neural networks to resource limited devices is still a challenging problem due to the requirements of abundant computing and memory resources. A variety of methods have been proposed to reduce the parameter size and accelerate the inference phase, such as compact model architecture design (in a handcrafted way or automatic search way) [Howard et al., 2017; Zoph and Le, 2016], network pruning [Han et al., 2015; He et al., 2019], knowledge distilling [Hinton et al., 2015], low-rank approximation [Jaderberg et al., 2014; Jaderberg et al., 2014], etc. Besides, recent works [Courbariaux et al., 2014; Gupta et al., 2015] show that full-precision weights and activations are not necessary for networks to achieve high performances. This discovery indicates that both weights and activations in neural networks can be quantized to low-bit formats. In this way, both storage and computation resources can be saved.
∗Contact Author
The extreme cases of network quantization are binary and ternary quantization ({-1, 1} and {-1, 0, 1}). In computationally heavy convolutions, multiply-accumulate consumes most of the operation time. Through binarization or ternarization, multiply-accumulate can be replaced by cheap bitwise xnor and popcount operations [Courbariaux et al., 2016]. Although binary networks can achieve high compression rate and computing efficiency, they inevitably suffer from a long training procedure and noticeable accuracy drops owing to poor representation ability.
In order to make a balance between efficiency and accuracy, ternary CNNs convert both weights and activations into ternary values. Theoretically, ternary CNNs have stronger representation ability than binary CNNs, and should have a better performance. Although many works [Li et al., 2016; Zhu et al., 2016; Wang et al., 2018; Wan et al., 2018] provide tremendous efforts on ternary neural networks, we argue that there are two main issues in existing works: 1) All previous ternary networks use a hard ∆ to divide floating point weights into three intervals (see Eq.3 for more details), which introduces an additional constraint into ternary networks. 2) Although the theoretical optimal ∆ can be calculated through optimization, calculating it at each training iteration is too time-consuming. Therefore, previous methods either use a hyper-parameter to estimate ∆ or only calculate the exact ∆ at the first training iteration then keep it for later iterations, which further limits ternary network accuracy. A brief summary: they introduce an additional constraint based on ∆. Further more, a suboptimal ∆ is used instead of the exact one.
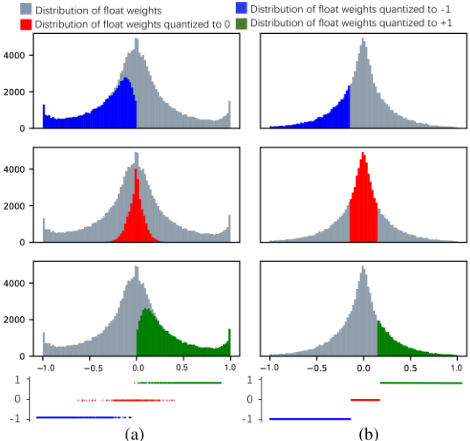
In this paper, we propose Soft Threshold Ternary Networks (STTN), an innovative method to train ternary networks. STTN avoids the hard threshold and enables the model to automatically determine which weights to be -1/0/1 in a soft manner. We convert training ternary networks into training equivalent binary networks (more details in section 3.2). STTN enjoys several benefits: 1) The constraint based on ∆ is removed. 2) STTN is free of calculation of ∆. 3) As shown in Figure 1 (a), weights are ternarized in a soft manner, which is why we name it soft threshold.
Our contributions are summarized as follows.
- We divide previous ternary networks into two catalogues: Optimization-based method and Learning-based method. Analysis is given about issues in the existing ternary networks that prevent them from reaching high performance.
- We propose STTN, an innovative way to train ternary networks by decomposing one ternary kernel into two binary kernels during training. No extra parameters or computations are needed during inference. Quantizing to -1/0/1 is determined by two binary variables rather than decided by a hard threshold.
- We show that our proposed ternary training method provides competitive results on the image classification, i.e. CIFAR-10, CIFAR-100 and ImageNet datasets. Qualitative and quantitative experiments show that it outperforms previous ternary works.
2 RelatedWork
Low-bit quantization of deep neural networks has recently received increasing interest of deep learning communities. By utilizing fixed-point weights and feature representations, not only the model size can be dramatically reduced, but also inference time can be saved.
The extreme cases of network quantization are binary neural networks (BNN) and ternary neural networks (TNN).
BNN [Courbariaux et al., 2016] constrains both the weights and activations to either +1 or -1, which produces reasonable results on small datasets, such as MNIST and CIFAR-10. However, there is a significant accuracy drop on large scale classification datasets, such as ImageNet. Some improvements based on BNN have been investigated. For example, [Darabi et al., 2018] introduces a regularization function that encourages training weights around binary values. [Tang et al., 2017] proposes to use low initial learning rate. Nevertheless, there is still non-negligible accuracy drop. To improve the quality of the binary feature representations, XNOR-Net [Rastegari et al., 2016] introduces scale factors for both weights and activations during binarization process. DoReFa-Net [Zhou et al., 2016] further improves XNOR-Net by approximating the activations with more bits. Since ABC-Net [Lin et al., 2017], several works propose to decompose a single convolution layer into K binary convolution operations [Liu et al., 2019; Zhu et al., 2019]. Although higher accuracy can be achieved, K× extra parameters and computations are needed for both training and inference time, which defeats the original purpose of binary networks.
To make a balance between the efficiency and accuracy, ternary CNNs convert both weights and activations into ternary values. We will review previous ternary works in detail in section 3.1.
3 Methodology
We first revisit the formulation of previous ternary networks. We divide them into two catalogues and show their common issues in calculating the appropriate ∆. We then present our novel Soft Threshold Ternary Networks in detail, including scaling coefficient constraint and backward approximation. We show that our method can avoid the previous issue in a simple but effective way.
3.1 Review of Previous Ternary Networks
Problem Formulation
Full precision convolution or inner-product can be formed as: Y = σ(W T X). Here σ(·) represents the nonlinear activation function, such as ReLU. W ∈ Rn×chw and X ∈ Rchw×HW are float point weights and inputs respectively, where (n, c, h,w) are filter number, input channels, kernel height and kernel width, and (H,W) are height and width of output feature maps. Ternary networks convert both weights and inputs into ternary values: T ∈ {+1, 0,-1}n×chw and Xt ∈ {+1, 0, -1}chw×HW .
As for weights ternarization, α is used to estimate the floating weight W alone with ternary weight T .
Previous works formulate ternarization as a weight approximation optimization problem:
A hard threshold ∆ is then introduced by previous works to divide quantization intervals, which sets an additional constraint on ternary networks:
As illustrated in Figure 1(b), ∆ plays a role as hard threshold here, splitting the floating point weights into {-1, 0, 1}. We will show that the above constraint can be avoided in our method. According to methods of calculating α and ∆, we divide previous ternary networks into 1) optimization-based ternary networks, and 2) learning-based ternary networks.
Optimization-based Ternary Networks
TWN [Li et al., 2016] and TSQ [Wang et al., 2018] formulate the ternarization as Eq.(2).
In TWN, T is obtained according to threshold-based constraint Eq.(3). They give exact optimal α∗ and ∆∗ as follows:
Note that ∆∗ in Eq.(4) has no straightforward solution. It can be time and computing consuming if using discrete optimization to solve it. In TWN, they adopt an estimation ∆′ ≈ 0.7 · E(|W|) to approximate the optimal ∆∗ . Obviously there is a gap between ∆∗ and ∆′ . What's more, the optimal scaling factor α∗ in Eq.(4) will also be affected because of dependence on ∆.
In TSQ, they try to obtain T ∗ by directly solving Eq.(2). They give exact optimal α∗ and T ∗ as follows 1 :
Note that there is still no straightforward solution for T ∗ in Eq.(5). TSQ proposes OTWA(Optimal Ternary Weights Approximation) to obtain T ∗ . However, sorting for |Wi| is needed in their algorithm. Time complexity is higher than O(N log(N)), where N is the number of elements in kernel weights. To avoid time consuming sorting, they only calculate ∆ at the first training iteration and then keep it for later iterations, which is suboptimal.
Learning-based Ternary Networks
TTQ [Zhu et al., 2016] tries another way to obtain scaling factor α and threshold ∆. They set α as a learnable parameter and set ∆ as a hyper-parameter. Based on TTQ, RTN [Li et al., 2019] introduces extra float point scaling and offset parameters to reparameterize ternary weights.
Because the search space of hyper-parameter ∆ is too large, both of TTQ and RTN set ∆ the same across all layers, e.g. ∆ = 0.5 in RTN. We argue that ternary methods with hyper-parameter are not reasonable as following:
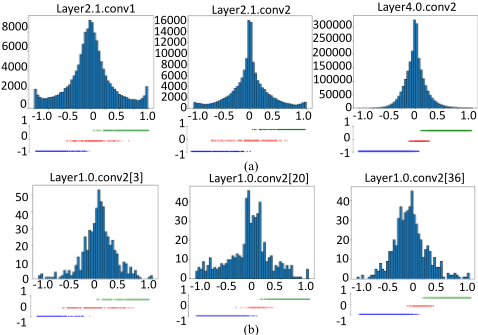
In Figure 2, we visualize the weight distribution of ResNet18 on ImageNet from different layers and from different kernels in the same layer, respectively. From the figure, we can observe that the distributions are different from layer to layer. Even for kernels in the same layer, their weight distributions can be diverse. Therefore, 1) it is not reasonable for previous works to set a fixed threshold for all kernels (e.g. ∆ = 0.5 in TTQ and RTN). 2) What's more, their ternarization also use hard threshold: once ∆ is set, their quantized intervals are determined according to Eq.(3).
1W T denotes transpose of matrixW. T denotes ternary weights.
So can we remove the hard ∆ constraint Eq.(3), solving ternary networks in another way?
3.2 Soft Threshold Ternary Networks
Due to the issues analyzed above, we propose our novel STTN. Our motivation is to enable the model to automatically determine which weights to be -1/0/1, avoiding the hard threshold ∆.
We introduce our methods via convolution layers. The inner-product layer has a similar form. Concretely, at training time, we replace the ternary convolution filter T with two parallel binary convolution filters B1 and B2. They are both binary-valued and have the same shape with ternary filter: n × chw. Due to the additivity of convolutions with the same kernel sizes, a new kernel can be obtained by:
A key requirement for T to have ternary values is that those two binary filters should have the same scaling factors: α. With αB1, αB2 ∈ {+α,-α}n×chw , the sum of αB1 and αB2 is ternary-valued, i.e. αT ∈ {+2α, 0,-2α}n×chw . Note that we only decompose the filters at training time. After the training, the two trained parallel binary filters are added up to obtain the ternary filter. Thus there is no extra computation when deploying trained models to devices. An example is illustrated in Figure 3.
Zeroes are introduced in ternary filters (white squares in Figure 3 at positions where two parallel filters have opposite values). And -1/1 is obtained at positions where two parallel filters have the same signs. In this way, ternary values are determined by the combination of two corresponding binary values.
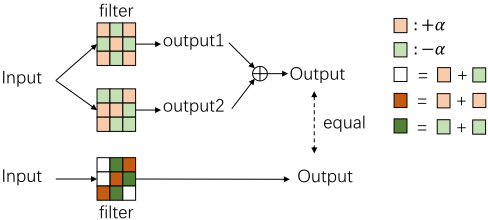
It is obvious that the outputs of training-time model are equal to the outputs of inference-time model:
In our proposed STTN, we convert training ternary networks into training equivalent binary networks. We abandon the constraint in Eq.(3). Not only ∆ can be avoided, but also quantization intervals can be divided in a soft manner.
Scaling Coefficient
As mentioned above, a key requirement is that the corresponding two parallel binary filters should have the same scaling factors to guarantee the sum of them are ternary. Taking the two parallel binary filters into consideration, we obtain the appropriate {α1, α2} by minimizing the following weight approximation problem:
Here B1 and B2 are the two parallel binary filters. And W1 and W2 are the corresponding float point filters. With constraint α1 = α2, we use α to denote them. Through expanding Eq.(8), we have
C = W T 1 W1 + W T 2 W2 is a constant because W1 and W2 are known variables. In order to get α∗ , the optimal B∗ 1 and B∗ 2 should be determined. Since B1,B2 ∈ {+1,-1}n×chw , BT 1 B1+BT 2 B2 = 2nchw is also a constant. From Eq.(9), B∗ 1 and B∗ 2 can be achieved by maximizing BT 1 W1 +BT 2 W2 with constraint condition that B1,B2 ∈ {+1,-1}n×chw . Obviously the optimal solution can be obtained when binary kernel has the same sign with the corresponding float point kernel at the same positions, i.e. B∗ 1 = sign(W1), B∗ 2 = sign(W2).
Based on the optimal B∗ 1 and B∗ 2 , α∗ can be easily calculated as:
where N = nchw, is the number of elements in each weight. W1i andW2i are elements of W1 andW2, respectively.
Backward Approximation
Since we decompose one ternary filter into two parallel binary filters at training time, binary weights approximation is needed in both forward and backward processes. During the forward propagation, the two related weights can be binarized through sign function along with the same scaling factor calculated by Eq.(10). However, during the backward propagation, the gradient of sign function is almost everywhere zero. Assume ℓ as the loss function and ˜ W = αB = α · sign(W) as the approximated weights, XNOR-Net [Rastegari et al., 2016] alleviates this problem through Straight-Through Estimator (STE):
Here, sign(Wi) is approximated with Wi1|Wi|≤1. N is the number of elements in each weight.
However, note that an important requirement in our STTN is that the related two parallel binary filters should have the same scaling factors. The exact approximated weights should
Because Eq.(10) indicates that α is dependent on both W1 and W2. When calculating the derivatives of W1i, the effect of other kernels W1j and W2j should be considered. But Eq.(11) ignores the effect of W1j and W2j, which is not suitable for our backward approximation.
Taking above analysis into consideration, we propose to calculate derivatives of W in a more precise way:
Here Wk = [Wk1,Wk2, ...,WkN] ( k ∈ {1, 2}) are the two parallel kernels respectively. ∂ℓ/∂W2i can be calculated in the same way as Eq.(13).
Activation
In this paper, we also convert activations into ternary values. We use the same ternarization function as RTN [Li et al., 2019]. Given floating point activation X, the ternary activation is calculated by the following equation. The difference between ours and RTN is that we do not introduce extra parameters or calculations.
| Method | TWN | TTQ | Ours |
| ‖W -αT‖22 | 537.76 | 439.46 | 379.25 |
During the backward process, as previous binary/ternary works [Courbariaux et al., 2016; Rastegari et al., 2016; Liu et al., 2018], gradients propagated through ternarization function are estimated by Straight-Through Estimator (STE).
4 Experiments
In this section, we evaluate the proposed STTN in terms of qualitative and quantitative studies. Our experiments are conducted on three popular image classification datasets: CIFAR-10, CIFAR-100 and ImageNet (ILSVRC12). We test on several representative CNNs including: AlexNet, VGGNet, and ResNet.
4.1 Implementation Details
We adopt the standard data augmentation scheme. In all CIFAR experiments, we pad 2 pixels in each side of images and randomly crop 32×32 size from padded images during training. As for ImageNet experiments, we first proportionally resize images to 256×N (N × 256) with the short edge to 256. Then we randomly sub-crop them to 224×224 patches with mean subtraction and randomly flipping. No other data augmentation tricks are used during training.
Following RTN [Li et al., 2019], we modify the block structure as BatchNorm → Ternarization → TernaryConv → Activation. Following XNOR-Net [Rastegari et al., 2016], we place a dropout layer with p = 0.5 before the last layer for AlexNet. For VGG-Net, we use the same architecture VGG-7 as TWN [Li et al., 2016] and TBN [Wan et al., 2018]. We do not quantize the first and the last layer as previous binary/ternary works. We replace all 1×1 downsampling layers with max-pooling in ResNet.
We use Adam with default settings in all our experiments. The batch size for ImageNet is 256. We set weight decay as 1e-6 and momentum as 0.9. All networks on ImageNet are trained for 110 epochs. The initial learning rate is 0.005, and we use cosine learning rate decay policy. All our models are trained from scratch.
4.2 Weight Approximation Evaluation
In this section, we explore the effect of the proposed STTN from qualitative view.
Previous works quantize weights into {-1, 0, 1} by setting a hard threshold ∆. Different from them, the proposed STTN generates soft threshold, quantizing weights more flexibly. We illustrate the impact of threshold calculation on the performance of TNN based on ResNet-18. We first calculate the distance between trained floating weights W and trained ternary weights T . L2 norm is used as the criterion for measurement as Eq.(2). We compare our method with TWNand TTQ. The results are shown in Table 1.
We can see that STTN obtains the smallest gap between trained floating weights and trained ternary weights, which indicates that our methods can realize a good weight approximation. Intuitively, the smaller the approximatedweight error we get, the higher precision the model can obtain. The results show the effect of STTN qualitatively and further quantitative analyses are given in section 4.3.
We also analyze the reason why our STTN can obtain a smaller approximation error than previous ternary method. An essential effect of STTN is to quantize weights into {+1, 0, -1} in a soft manner, just as shown in Figure 1(a) and Figure 2. The effect comes from that STTN throws the hard threshold away. That is, Eq.(3) is no more a constraint to the weight approximation optimization problem. By comparing Figure1(a) with (b): this provides more flexible ternarization intervals.
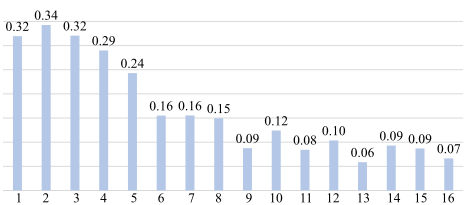
Besides, we find that STTN adjust the weight sparsity regularly. Figure 4 shows the weight sparsity rates (the percentage of zeros) of different layers in our STTN on ResNet-18. From the figure we can see that the sparsity rates gradually decrease from the first layer to the last layer. This probably because high-level semantics need dense kernels to encode.
4.3 Network Ternarization Results
In this section, we evaluate the STTN from quantitative view by comparing with the state-of-the-art low-bit networks on various architectures. We ternarize both weights and activations. Experiments on only quantizing weights are also given.
Results on CIFAR-10
We first conduct experiments on CIFAR-10 dataset. We use the same network architecture as TWN, denoted as VGG-7. Compared with the architecture VGG-9 adopted in BNN and XNOR, the last two fully connection layers are removed. Table 2 shows the STTN results. Note that for VGG-7, STTN with ternary weights and activations can even obtain better performance than the full-precision model.
Results on CIFAR-100
In addition, we also evaluate STTN on CIFAR-100 dataset. We compare our STTN with a strong multi-bit baseline CBCN [Liu et al., 2019]. CBCN replaces each convolution layer with several parallel binarized convolution layers. For fair comparisons, we use the same architecture as CBCN (ResNet-18 with 32-64-128-256 kernel stage). Note that in CBCN, the number of channels in one layer is 4×. Table 3 shows our results that although CBCN uses 4× channels than ours, we obtain higher accuracy with fewer computations.
| Bit-width | Method | Error(%) |
|---|---|---|
| 32+32 | Floating point [Li et al., 2016] | 7.12 |
| 1+32† | BWN [Courbariaux et al., 2015] | 8.27 |
| 1+1† | BNN [Courbariaux et al., 2016] | 10.15 |
| 1+1† | XNOR [Rastegari et al., 2016] | 9.98 |
| 2+32 | TWN [Li et al., 2016] | 7.44 |
| 1+2 | TBN [Wan et al., 2018] | 9.15 |
| 2+2 | Ours | 7.07 |
| Model | Kernel Stage | Accuracy(%) |
|---|---|---|
| Float(32+32) | 32-64-128-256 | 73.62 |
| CBCN(1+1) | (32-64-128-256)×4 | 70.07 |
| Ours(2+2) | 32-64-128-256 | 72.10 |
From this experiment, we argue that ternary networks can be considered before resorting to multi-bit methods.
Results on ImageNet
For the large-scale dataset, we evaluate our STTN over AlexNet and ResNet-18 on ImageNet. We compare our method with several exiting state-of-the-art low-bit quantization methods: 1) only quantizing weights: BWN [Courbariaux et al., 2015], TWN [Li et al., 2016] and TTQ [Zhu et al., 2016]; 2) quantizing both weights and activations: XNOR [Rastegari et al., 2016], Bi-Real [Liu et al., 2018], ABC [Lin et al., 2017], TBN [Wan et al., 2018], HWGQ [Cai et al., 2017], PACT [Choi, 2018] and RTN [Li et al., 2019].
The overall results based on AlexNet and ResNet-18 are shown in Tabel 4 and 5. We highlight our accuracy improvement (up to 15% absolute improvement compared with XNOR-Net and up to 1.7% compared with state-of-the-art ternary models, without pre-training). These results show that the STTN outperforms the best previous ternary methods. Such improvement indicates that our soft threshold significantly benefits extreme low-bit networks.
What's more, compared with PACT and RTN, we highlight additional improvements apart from accuracy: 1) Both PACT and RTN introduce extra floating point parameters (the activation clipping level parameter in PACT and reparameterized scale/offset in RTN) into the networks, which needs extra storage space and computation. 2) The extra introduced learnable parameters in PACT and RTN need careful manual adjustments, such as learning rate, weight decay and so on. Extensive manual tuning have to be tested for different networks on different datasets. However, our method is free of extra hyper-parameters to be tuned. Further more, we argue that our method can combine with those methods for further accuracy improvement. 3) For RTN, they argue that initialization from pre-trained full-precision models is vitally important for their methods (since the small architecture modification such as changing the order of BN and Conv layer in low-bit quantization, full-precision models released by open model zoo can not be used directly) . However, our method shows that training from scratch can still obtain state-of-theart results.
| Model | Bit-width | Top-1(%) | Top-5(%) |
|---|---|---|---|
| XNOR | 1+1 | 44.2 | 69.2 |
| TBN | 1+2 | 49.7 | 74.2 |
| HWGQ | 2+2 | 52.7 | 76.3 |
| PACT∗ | 2+2 | 55.0 | - |
| RTN | 2+2 | 53.9 | - |
| Ours | 2+2 | 55.6 | 78.9 |
| Model | Bit-width | Top-1(%) | Top-5(%) |
|---|---|---|---|
| Floating | 32+32 | 69.3 | 89.2 |
| TWN | 2+32 | 61.8 | 84.2 |
| TWN∗∗ | 2+32 | 65.3 | 86.2 |
| TTQ∗∗ | 2+32 | 66.6 | 87.2 |
| RTN∗∗∗ | 2+32 | 68.5 | - |
| Ours | 2+32 | 68.8 | 88.3 |
| XNOR | 1+1 | 51.2 | 73.2 |
| Bi-Real∗∗∗ | 1+1 | 56.4 | 79.5 |
| ABC-5 | (1×5)+(1×5) | 65.0 | 85.9 |
| TBN | 1+2 | 55.6 | 79.0 |
| HWGQ | 1+2 | 56.1 | 79.7 |
| PACT∗ | 2+2 | 64.4 | - |
| RTN∗∗∗ | 2+2 | 64.5 | - |
| Ours | 2+2 | 66.2 | 86.4 |
5 Conclusion
In this paper, we propose a simple yet effective ternarization method, Soft Threshold Ternary Networks. We divide previous ternary works into two catalogues and show that their hard threshold is suboptimal. By simply replacing the original ternary kernel with two parallel binary kernels at training, our model can automatically determine which weights to be -1/0/1 instead of depending on a hard threshold. Experiments on various datasets show that STTN dramatically outperforms current state-of-the-arts, lowering the performance gap between full-precision networks and extreme low bit networks.
@inproceedings{ijcai2020p318,
  title     = {Soft Threshold Ternary Networks},
  author    = {Xu, Weixiang and He, Xiangyu and Zhao, Tianli and Hu, Qinghao and Wang, Peisong and Cheng, Jian},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {2298--2304},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/318},
  url       = {https://doi.org/10.24963/ijcai.2020/318},
}
TY - CPAPER TI - Soft Threshold Ternary Networks AU - Xu, Weixiang AU - He, Xiangyu AU - Zhao, Tianli AU - Hu, Qinghao AU - Wang, Peisong AU - Cheng, Jian T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 2298 EP - 2304 DO - 10.24963/ijcai.2020/318 UR - https://doi.org/10.24963/ijcai.2020/318 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





