
Comparing Kullback-Leibler Divergence and Mean Squared Error Loss in Knowledge Distillation
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 2628-2635.
https://doi.org/10.24963/ijcai.2021/362
Keywords
- Machine Learning: Deep Learning
- Machine Learning: Classification
Abstract
Knowledge distillation (KD), transferring knowledge from a cumbersome teacher model to a lightweight student model, has been investigated to design efficient neural architectures. Generally, the objective function of KD is the Kullback-Leibler (KL) divergence loss between the softened probability distributions of the teacher model and the student model with the temperature scaling hyperparameter τ. Despite its widespread use, few studies have discussed how such softening influences generalization. Here, we theoretically show that the KL divergence loss focuses on the logit matching when τ increases and the label matching when τ goes to 0 and empirically show that the logit matching is positively correlated to performance improvement in general. From this observation, we consider an intuitive KD loss function, the mean squared error (MSE) between the logit vectors, so that the student model can directly learn the logit of the teacher model. The MSE loss outperforms the KL divergence loss, explained by the penultimate layer representations difference between the two losses. Furthermore, we show that sequential distillation can improve performance and that KD, using the KL divergence loss with small τ particularly, mitigates the label noise. The code to reproduce the experiments is publicly available online at https://github.com/jhoon-oh/kd_data/.
- [Aguinaldo et al., 2019] Angeline Aguinaldo, Ping-Yeh Chi- ang, Alexander Gain, Ameya Patil, Kolten Pearson, and Soheil Feizi. Compressing gans using knowledge distilla- tion. CoRR, abs/1902.00159, 2019.
- [Ba and Caruana, 2013] Lei Jimmy Ba and Rich Caruana. Do deep nets really need to be deep? arXiv preprint arXiv:1312.6184, 2013.
- [Cho and Hariharan, 2019] Jang Hyun Cho and Bharath Har- iharan. On the efficacy of knowledge distillation. In Pro- ceedings of the IEEE International Conference on Com- puter Vision, pages 4794-4802, 2019.
- [Furlanello et al., 2018] Tommaso Furlanello, Zachary C Lipton, Michael Tschannen, Laurent Itti, and Anima Anandkumar. Born again neural networks. arXiv preprint arXiv:1805.04770, 2018.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 770-778, 2016.
- [Heo et al., 2019a] Byeongho Heo, Jeesoo Kim, Sangdoo Yun, Hyojin Park, Nojun Kwak, and Jin Young Choi. A comprehensive overhaul of feature distillation. In Pro- ceedings of the IEEE International Conference on Com- puter Vision, pages 1921-1930, 2019.
- [Heo et al., 2019b] Byeongho Heo, Minsik Lee, Sangdoo Yun, and Jin Young Choi. Knowledge transfer via distil- lation of activation boundaries formed by hidden neurons. In Proceedings of the AAAI Conference on Artificial Intel- ligence, volume 33, pages 3779-3787, 2019.
- [Hinton et al., 2015] Geoffrey Hinton, Oriol Vinyals, and Jeff Dean. Distilling the knowledge in a neural network. arXiv preprint arXiv:1503.02531, 2015.
- [Jang et al., 2016] Eric Jang, Shixiang Gu, and Ben Poole. Categorical reparameterization with gumbel-softmax. arXiv preprint arXiv:1611.01144, 2016.
- [Kim et al., 2018] Jangho Kim, SeongUk Park, and Nojun Kwak. Paraphrasing complex network: Network compres- sion via factor transfer. In Advances in Neural Information Processing Systems, pages 2760-2769, 2018.
- [Lukasik et al., 2020] Michal Lukasik, Srinadh Bhojana- palli, Aditya Menon, and Sanjiv Kumar. Does label smoothing mitigate label noise? In Hal Daumé III and Aarti Singh, editors, Proceedings of the 37th Interna- tional Conference on Machine Learning, volume 119 of Proceedings of Machine Learning Research, pages 6448- 6458, Virtual, 13-18 Jul 2020. PMLR.
- [Maddison et al., 2016] Chris J. Maddison, Andriy Mnih, and Yee Whye Teh. The concrete distribution: A con- tinuous relaxation of discrete random variables. CoRR, abs/1611.00712, 2016.
- [Mirzadeh et al., 2020] Seyed Iman Mirzadeh, Mehrdad Farajtabar, Ang Li, Nir Levine, Akihiro Matsukawa, and Hassan Ghasemzadeh. Improved knowledge distillation via teacher assistant. In Proceedings of the AAAI Con- ference on Artificial Intelligence, volume 34, pages 5191- 5198, 2020.
- [Mobahi et al., 2020] Hossein Mobahi, Mehrdad Farajtabar, and Peter L Bartlett. Self-distillation amplifies regulariza- tion in hilbert space. arXiv preprint arXiv:2002.05715, 2020.
- [Müller et al., 2019] Rafael Müller, Simon Kornblith, and Geoffrey E Hinton. When does label smoothing help? In Advances in Neural Information Processing Systems, pages 4694-4703, 2019.
- [Park et al., 2019] Wonpyo Park, Dongju Kim, Yan Lu, and Minsu Cho. Relational knowledge distillation. In Pro- ceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 3967-3976, 2019.
- [Phuong and Lampert, 2019] Mary Phuong and Christoph Lampert. Towards understanding knowledge distillation. In International Conference on Machine Learning, pages 5142-5151, 2019.
- [Romero et al., 2014] Adriana Romero, Nicolas Ballas, Samira Ebrahimi Kahou, Antoine Chassang, Carlo Gatta, and Yoshua Bengio. Fitnets: Hints for thin deep nets. arXiv preprint arXiv:1412.6550, 2014.
- [Srinivas and Fleuret, 2018] Suraj Srinivas and Franc ¸ois Fleuret. Knowledge transfer with jacobian matching. arXiv preprint arXiv:1803.00443, 2018.
- [Szegedy et al., 2016] Christian Szegedy, Vincent Van- houcke, Sergey Ioffe, Jon Shlens, and Zbigniew Wojna. Rethinking the inception architecture for computer vision. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 2818-2826, 2016.
- [Tang et al., 2020] Jiaxi Tang, Rakesh Shivanna, Zhe Zhao, Dong Lin, Anima Singh, Ed H Chi, and Sagar Jain. Un- derstanding and improving knowledge distillation. arXiv preprint arXiv:2002.03532, 2020.
- [Tian et al., 2019] Yonglong Tian, Dilip Krishnan, and Phillip Isola. Contrastive representation distillation. In International Conference on Learning Representations, 2019.
- [Urban et al., 2016] Gregor Urban, Krzysztof J Geras, Samira Ebrahimi Kahou, Ozlem Aslan, Shengjie Wang, Rich Caruana, Abdelrahman Mohamed, Matthai Phili- pose, and Matt Richardson. Do deep convolutional nets really need to be deep and convolutional? arXiv preprint arXiv:1603.05691, 2016.
- [Yuan et al., 2020] Li Yuan, Francis EH Tay, Guilin Li, Tao Wang, and Jiashi Feng. Revisiting knowledge distilla- tion via label smoothing regularization. In IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), June 2020.
- [Zagoruyko and Komodakis, 2016a] Sergey Zagoruyko and Nikos Komodakis. Paying more attention to attention: Im- proving the performance of convolutional neural networks via attention transfer. arXiv preprint arXiv:1612.03928, 2016.
- [Zagoruyko and Komodakis, 2016b] Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. arXiv preprint arXiv:1605.07146, 2016.
- [Zhang et al., 2016] Chiyuan Zhang, Samy Bengio, Moritz Hardt, Benjamin Recht, and Oriol Vinyals. Understand- ing deep learning requires rethinking generalization. arXiv preprint arXiv:1611.03530, 2016.
- [Zhang et al., 2019] Linfeng Zhang, Jiebo Song, Anni Gao, Jingwei Chen, Chenglong Bao, and Kaisheng Ma. Be your own teacher: Improve the performance of convolutional neural networks via self distillation. In The IEEE Inter- national Conference on Computer Vision (ICCV), October 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Knowledge distillation (KD) is one of the most potent model compression techniques in which knowledge is transferred from a cumbersome model (teacher) to a single small model (student) [Hinton et al., 2015]. In general, the objective of training a smaller student network in the KD framework is formed as a linear summation of two losses: cross-entropy (CE) loss with "hard" targets, which are onehot ground-truth vectors of the samples, and KullbackLeibler (KL) divergence loss with the teacher's predictions. Specifically, KL divergence loss has achieved considerable success by controlling the softness of "soft" targets via the temperature-scaling hyperparameter τ. Utilizing a larger value for this hyperparameter τ makes the softmax vectors smooth over classes. Such a re-scaled output probability vector by τ is called the softened probability distribution, or the softened softmax [Maddison et al., 2016; Jang et al., 2016]. Recent KD has evolved to give more importance to the KL divergence loss to improve performance when balancing the objective between CE loss and KL divergence loss [Hinton et al., 2015; Tian et al., 2019]. Hence, we focus on training a student network based solely on the KL divergence loss.
∗The authors contributed equally to this paper.
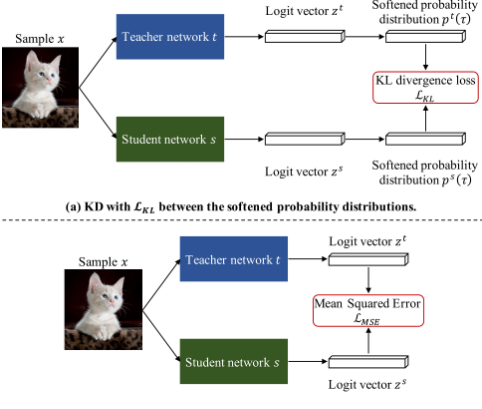
Recently, there has been an increasing demand for investigating the reasons for the superiority of KD. [Yuan et al., 2020; Tang et al., 2020] empirically showed that the facilitation of KD is attributed to not only the privileged information on similarities among classes but also the label smoothing regularization. In some cases, the theoretical reasoning for using "soft" targets is clear. For example, in deep linear neural networks, KD not only accelerates the training convergence but also helps in reliable training [Phuong and Lampert, 2019]. In the case of self-distillation (SD), where the teacher model and the student model are the same, such an approach progressively restricts the number of basis functions to represent the solution [Mobahi et al., 2020]. However, there is still a lack of understanding of how the degree of softness affects the performance.
In this paper, we first investigate the characteristics of a student trained with KL divergence loss with various τ, both theoretically and empirically. We find that the student's logit (i.e., an input of the softened softmax function) more closely resembles the teacher's logit as τ increases, but not completely. Therefore, we design a direct logit learning scheme by replacing the KL divergence loss between the softened probability distributions of a teacher network and a student network (Figure 1(a)) with the mean squared error (MSE) loss between the student's logit and the teacher's logit (Figure 1(b)). Our contributions are summarized as follows:
- We investigate the role of the softening hyperparameter τ theoretically and empirically. A large τ, that is, strong softening, leads to logit matching, whereas a small τ results in training label matching. In general, logit matching has a better generalization capacity than label matching.
- We propose a direct logit matching scheme with the MSE loss and show that the KL divergence loss with any value of τ cannot achieve complete logit matching as much as the MSE loss. Direct training results in the best performance in our experiments.
- We theoretically show that the KL divergence loss makes the model's penultimate layer representations elongated than those of the teacher, while the MSE loss does not. We visualize the representations using the method proposed by [M¨uller et al., 2019].
- We show that sequential distillation, the MSE loss after the KL divergence loss, can be a better strategy than direct distillation when the capacity gap between the teacher and the student is large, which contrasts [Cho and Hariharan, 2019].
- We observe that the KL divergence loss, with low τ in particular, is more efficient than the MSE loss when the data have incorrect labels (noisy label). In this situation, extreme logit matching provokes bad training, whereas the KL divergence loss mitigates this problem.
2 RelatedWork
2.1 Knowledge Distillation
KD has been extended to a wide range of methods. One attempted to distill not only the softened probabilities of the teacher network but also the hidden feature vector so that the student could be trained with rich information from the teacher [Romero et al., 2014; Zagoruyko and Komodakis, 2016a; Srinivas and Fleuret, 2018; Kim et al., 2018; Heo et al., 2019b; Heo et al., 2019a]. The KD approach can be leveraged to reduce the generalization errors in teacher models (i.e., self-distillation; SD) [Zhang et al., 2019; Park et al., 2019] as well as model compressions. In the generative models, a generator can be compressed by distilling the latent features from a cumbersome generator [Aguinaldo et al., 2019].
To explain the efficacy of KD, [Furlanello et al., 2018] asserted that the maximum value of a teacher's softmax probability was similar to weighted importance by showing that permuting all of the non-argmax elements could also improve performance. [Yuan et al., 2020] argued that "soft" targets served as a label smoothing regularizer rather than as a transfer of class similarity by showing that a poorly trained or smaller-size teacher model can boost performance. Recently, [Tang et al., 2020] modified the conjecture in [Furlanello et al., 2018] and showed that the sample was positively reweighted by the prediction of the teacher's logit vector.
2.2 Label Smoothing
Smoothing the label y is a common method for improving the performance of deep neural networks by preventing the overconfident predictions [Szegedy et al., 2016]. Label smoothing is a technique that facilitates the generalization by replacing a ground-truth one-hot vector y with a weighted mixture of hard targets yLS :
where k indicates the index, and β is a constant. This implicitly ensures that the model is well-calibrated [M¨uller et al., 2019]. Despite its improvements, [M¨uller et al., 2019] observed that the teacher model trained with LS improved its performance, whereas it could hurt the student's performance. [Yuan et al., 2020] demonstrated that KD might be a category of LS by using the adaptive noise, i.e., KD is a label regularization method.
3 Preliminaries: KD
We denote the softened probability vector with a temperaturescaling hyperparameter τ for a network f as pf (τ), given a sample x. The k-th value of the softened probability vector pf (τ) is denoted by pfk (τ) = exp(zfk /τ) ∑Kj=1 exp(zf j /τ) , where zf k is the k-th value of the logit vector zf , K is the number of classes, and exp(·) is the natural exponential function. Then, given a sample x, the typical loss L for a student network is a linear combination of the cross-entropy loss LCE and the Kullback-
Leibler divergence loss LKL:
where s indicates the student network, t indicates the teacher network, y is a one-hot label vector of a sample x, and α is a hyperparameter of the linear combination. For simplicity of notation, LCE(ps (1), y) and LKL(ps (τ ), pt (τ )) are denoted by LCE and LKL, respectively. The standard choices are α = 0.1 and τ ∈ {3, 4, 5} [Hinton et al., 2015; Zagoruyko and Komodakis, 2016a].
| Notation | Description |
|---|---|
| x | Sample |
| y | Ground-truth one-hot vector |
| K | Number of classes in the dataset |
| f | Neural network |
| zf | Logit vector of a sample x through a network f |
| zf k | Logit value corresponding the k-th class label, i.e., the k-th value of zf (x) |
| α | Hyperparameter of the linear combination |
| τ | Temperature-scaling hyperparameter |
| pf (τ) | Softened probability distribution with τ of a sample x for a network f |
| pfk (τ ) | The k-th value of a softened probability distribution, i.e., exp(zfk /τ) ∑Kj=1 exp(zf j /τ) |
| LCE | Cross-entropy loss |
| LKL | Kullback-Leibler divergence loss |
| LMSE | Mean squared error loss |
In [Hinton et al., 2015], given a single sample x, the gradient of LKL with respect to zsk is as follows:
When τ goes to ∞, this gradient is simplified with the approximation, i.e., exp(zf k /τ ) ≈ 1 + zf k /τ :
Here, the authors assumed the zero-mean teacher and student logit, i.e., ∑j zt j = 0 and ∑j zs j = 0, and hence ∂LKL ∂zsk ≈ 1K (zsk -ztk ). This indicates that minimizing LKL is equivalent to minimizing the mean squared error LMSE, that is, ||zs - zt ||22 , under a sufficiently large temperature τ and the zero-mean logit assumption for both the teacher and the student.
However, we observe that this assumption does not seem appropriate and hinders complete understanding by ignoring the hidden term in LKL when τ increases. Figure 2 describes the histograms for the magnitude of logit summations on the training dataset. The logit summation histogram from the teacher network trained with LCE is almost zero (Figure 2(a)), whereas that from the student network trained with LKL using the teacher's knowledge goes far from zero as τ
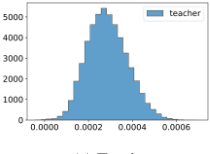
(a) Teacher.
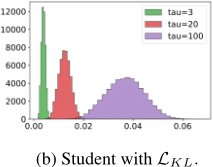
increases (Figure 2(b)). This is discussed in detail in Section 4.2.
3.1 Experimental Setup
In this paper, we used an experimental setup similar to that in [Heo et al., 2019a; Cho and Hariharan, 2019]: image classification on CIFAR-100 with a family of Wide-ResNet (WRN) [Zagoruyko and Komodakis, 2016b] and ImageNet with a family of of ResNet (RN) [He et al., 2016]. We used a standard PyTorch SGD optimizer with a momentum of 0.9, weight decay, and apply standard data augmentation. Other than those mentioned, the training settings from the original papers [Heo et al., 2019a; Cho and Hariharan, 2019] were used.
4 Relationship between LKL and LMSE
In this section, we conduct extensive experiments and systematically break down the effects of τ in LKL based on theoretical and empirical results. Then, we highlight the relationship between LKL and LMSE. Then, we compare the models trained with LKL and LMSE in terms of performance and penultimate layer representations. Finally, we investigate the effects of a noisy teacher on the performance according to the objective.
4.1 Hyperparameter τ in LKL
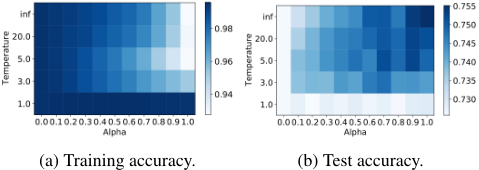
We investigate the training and test accuracies according to the change in α in L and τ in LKL (Figure 3). First, we empirically observe that the generalization error of a student model decreases as α in L increases. This means that "soft" targets are more efficient than "hard" targets in training a student if "soft" targets are extracted from a well-trained teacher. This result is consistent with prior studies that addressed the efficacy of "soft" targets [Furlanello et al., 2018; Tang et al., 2020]. Therefore, we focus on the situation where "soft" targets are used to train a student model solely, that is, α = 1.0, in the remainder of this paper.
When α = 1.0, the generalization error of the student model decreases as τ in LKL increases. These consistent tendencies according to the two hyperparameters, α and τ, are the same across various teacher-student pairs. To explain this phenomenon, we extend the gradient analysis in Section 3 without the assumption that the mean of the logit vector is zero.
Proposition 1. Let K be the number of classes in the dataset, and 1[·] be the indicator function, which is 1 when the statement inside the brackets is true and 0 otherwise. Then,
Proposition1 explains the consistent trends as follows. In the course of regularizing LKL with sufficiently large τ, the student model attempts to imitate the logit distribution of the teacher model. Specifically, a larger τ is linked to a larger LKL, making the logit vector of the student similar to that of the teacher (i.e., logit matching). Hence, "soft" targets are being fully used as τ increases. This is implemented using a handcrafted gradient (top row of Figure 3). On the other hand, when τ is close to 0, the gradient of LKL does not consider the logit distributions and only identifies whether the student and the teacher share the same output (i.e., label matching), which transfers limited information. In addition, there is a scaling issue when τ approaches 0. As τ decreases, LKL increasingly loses its quality and eventually becomes less involved in learning. The scaling problem can be easily fixed by multiplying 1/τ by LKL when τ is close to zero.
From this proposition, it is recommended to modify the original LKL in Eq. (2), considering τ ∈ (0,∞) as follows:
The key difference between our analysis and the preliminary analysis on a sufficiently large τ, i.e., in Eq. (5), is that the latter term is generated by removing the existing assumption on the logit mean, which is discussed in Section 4.2 at the loss-function level.
4.2 Extensions fromLKL to LMSE
In this subsection, we focus on Eq. (5) to investigate the reason as to why the efficacy of KD is observed when τ is greater than 1 in the KD environment, as shown in Figure 3. Eq. (5) can be understood as a biased regression of the vector expression as follows:
| Student | LCE | LKL | LMSE | ||||
|---|---|---|---|---|---|---|---|
| τ =1 | τ =3 | τ=5 | τ=20 | τ=∞ | |||
| WRN-16-2 | 72.68 | 72.90 | 74.24 | 74.88 | 75.15 | 75.51 | 75.54 |
| WRN-16-4 | 77.28 | 76.93 | 78.76 | 78.65 | 78.84 | 78.61 | 79.03 |
| WRN-28-2 | 75.12 | 74.88 | 76.47 | 76.60 | 77.28 | 76.86 | 77.28 |
| WRN-28-4 | 78.88 | 78.01 | 78.84 | 79.36 | 79.72 | 79.61 | 79.79 |
| WRN-40-6 | 79.11 | 79.69 | 79.94 | 79.87 | 79.82 | 79.80 | 80.25 |
where 1 is a vector whose elements are equal to one. Furthermore, we can derive the relationship between limτ→∞LKL and LMSE as follows:
In Figure 2(a), the sum of the logit values of the teacher model is almost zero. With the teacher's logit value, δ∞ is approximated as - 1 2K2 (∑Kj=1 zs j )2 . Therefore, δ∞ can make the logit mean of the student trained with LKL depart from zero. From this analysis, it is unreasonable to assume that the student's logit mean is zero. We empirically find that the student's logit mean breaks the existing assumption as τ increases (Figure 2(b)). In summary, δ∞ hinders complete logit matching by shifting the mean of the elements in the logit. In other words, as derived from Eq. (8), optimizing LKL with sufficiently large τ is equivalent to optimizing LMSE with the additional regularization term δ∞, and it seems to rather hinder logit matching.
Therefore, we propose the direct logit learning objective for enhanced logit matching as follows:
Although this direct logit learning was used in [Ba and Caruana, 2013; Urban et al., 2016], they did not investigate the wide range of temperature scaling and the effects of MSE in the latent space. In this respect, our work differs.
4.3 Comparison of LKL and LMSE
We empirically compared the objectives LKL and LMSE in terms of performance gains and measured the distance between the logit distributions. Following the previous analysis, we also focused on "soft" targets in L′ . Table 2 presents the top-1 test accuracies on CIFAR-100 according to the student learning scheme for various teacher-student pairs. The students trained with LCE are vanilla models without a teacher. The students trained with LKL or LMSE are trained following the KD framework without using the "hard" targets, i.e., α = 1 in L and L′ , respectively. It is shown that distillation with LMSE, that is, direct logit distillation without hindering term δ∞, is the best training scheme for various teacher-student pairs. We also found the consistent improvements in ensemble distillation [Hinton et al., 2015]. For the ensemble distillation using MSE loss, an ensemble of logit predictions (i.e., an average of logit predictions) are used by multiple teachers. We obtained the test accuracy of WRN162 (75.60%) when the WRN16-4, WRN-28-4, and WRN-40-6 models were used as ensemble teachers in this manner. Moreover, the model trained with LMSE has similar or better performance when compared to other existing KD methods, as described in Table 3. 1
| Student | Baseline | SKD [2015] | FitNets [2014] | AT [2016a] | Jacobian [2018] | FT [2018] | AB [2019b] | Overhaul [2019a] | MSE |
|---|---|---|---|---|---|---|---|---|---|
| WRN-16-2 | 72.68 | 73.53 | 73.70 | 73.44 | 73.29 | 74.09 | 73.98 | 75.59 | 75.54 |
| WRN-16-4 | 77.28 | 78.31 | 78.15 | 77.93 | 77.82 | 78.28 | 78.64 | 78.20 | 79.03 |
| WRN-28-2 | 75.12 | 76.57 | 76.06 | 76.20 | 76.30 | 76.59 | 76.81 | 76.71 | 77.28 |
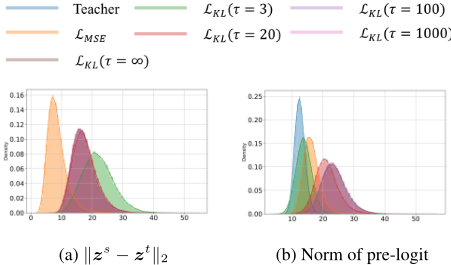
Furthermore, to measure the distance between the student's logit zs and the teacher's logit zt sample by sample, we describe the probabilistic density function (pdf) from the histogram for ‖zs - zt ‖2 on the CIFAR-100 training dataset (Figure 4(a)). The logit distribution of the student with a large τ is closer to that of the teacher than with a small τ when LKL is used. Moreover, LMSE is more efficient in transferring the teacher's information to a student than LKL. Optimizing LMSE aligns the student's logit with the teacher's logit. On the other hand, when τ becomes significantly large, LKL has the δ∞, and optimizing δ∞ makes the student's logit mean deviate from that of the teacher's logit mean.
1 We excluded the additional experiments for the replacement with MSE loss in feature-based distillation methods. It is difficult to add the MSE loss or replace the KL loss with MSE loss in the existing works because of the sensitivity to hyperparameter optimization. Their methods included various types of hyperparameters that need to be optimized for their settings.
We further investigate the effect of δ∞ on the penultimate layer representations (i.e., pre-logits). Based on δ∞ ≈ - 1 2K2 (∑Kj=1 zs j )2 , we can reformulate Eq. (8). Let rs ∈ Rd be the penultimate representation of student s from an instance x, and W s ∈ RK×d be the weight matrix of the student's fully connected layer. Then,
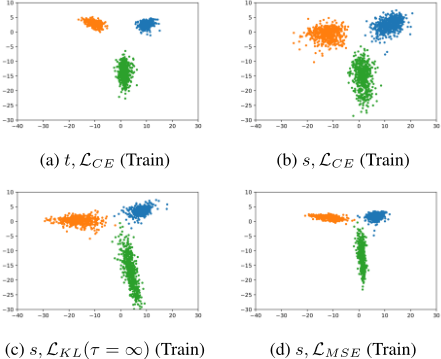
As derived in Eq. (10), training a network with LKL encourages the pre-logits to be dilated via δ∞ (Figure 4b). For visualization, following [M¨uller et al., 2019], we first find an orthonormal basis constructed from the templates (i.e., the mean of the representations of the samples within the same class) of the three selected classes (apple, aquarium fish, and baby in our experiments). Then, the penultimate layer representations are projected onto the hyperplane based on the identified orthonormal basis. WRN-28-4 (t) is used as a teacher, and WRN-16-2 (s) is used as a student on the CIFAR-100 training dataset. As shown in the first row of Figure 5, when WRN-like architectures are trained with LCE based on ground-truth hard targets, clusters are tightened as the model's complexity increases. As shown in the second row of Figure 5, when the student s is trained with LKL with infinite τ or with LMSE, both representations attempt to follow the shape of the teacher's representations but differ in the degree of cohesion. This is because δ∞ makes the pre-logits become much more widely clustered. Therefore, LMSE can shrink the representations more than LKL along with the teacher.
4.4 Effects of a Noisy Teacher
We investigate the effects of a noisy teacher (i.e., a model poorly fitted to the training dataset) according to the objective. It is believed that the label matching (LKL with a small τ) is more appropriate than the logit matching (LKL with a large τ or the LMSE) under a noisy teacher. This is because label matching neglects the negative information of the outputs of an untrained teacher. Table 4 describes top-1 test accuracies on CIFAR-100, where the used teacher network (WRN-28-4) has a training accuracy of 53.77%, which is achieved in 10 epochs. When poor knowledge is distilled, the students following the label matching scheme performed better than the students following the logit matching scheme, and the extreme logit matching through LMSE has the worst performance. Similarly, it seems that logit matching is not suitable for large-scale tasks. Table 5 presents top-1 test accuracies on ImageNet, where the used teacher network (ResNet152) has a training accuracy of 81.16%, which is provided in PyTorch. Even in this case, the extreme logit matching exhibits the worst performance. The utility of negative logits (i.e., negligible aspect when τ is small) was discussed in [Hinton et al., 2015].
5 Sequential Distillation
In [Cho and Hariharan, 2019], the authors showed that more extensive teachers do not mean better teachers, insisting that the capacity gap between the teacher and the student is a more important factor than the teacher itself. In their results, using a medium-sized network instead of a large-scale network as a teacher can improve the performance of a small network by reducing the capacity gap between the teacher and the student. They also showed that sequential KD (large network →
| Student | LKL | LMSE | |||||
|---|---|---|---|---|---|---|---|
| τ=0.1 | τ=0.5 | τ=1 | τ=5 | τ=20 | τ=∞ | ||
| WRN-16-2 | 51.64 | 52.07 | 51.36 | 50.11 | 49.69 | 49.46 | 49.20 |
| Student | LCE | LKL (Standard) | LKL (τ=20) | LMSE |
|---|---|---|---|---|
| ResNet-50 | 76.28 | 77.15 | 77.52 | 75.84 |
medium network → small network) is not conducive to generalization when (α, τ) = (0.1, 4) in Eq. (2). In other words, the best approach is a direct distillation from the medium model to the small model.
Table 6 describes the test accuracies of sequential KD, where the largest model is WRN-28-4, the intermediate model is WRN-16-4, and the smallest model is WRN-16-2. Similar to the previous study, when LKL with τ = 3 is used to train the small network iteratively, the direct distillation from the intermediate network to the small network is better (i.e., WRN-16-4 → WRN-16-2, 74.84%) than the sequential distillation (i.e., WRN-28-4 → WRN-16-4 → WRN-162, 74.52%) and direct distillation from a large network to a small network (i.e., WRN-28-4 →WRN-16-2, 74.24%). The same trend occurs in LMSE iterations.
On the other hand, we find that the medium-sized teacher can improve the performance of a smaller-scale student when LKL and LMSE are used sequentially (the last fourth row) despite the large capacity gap between the teacher and the student. KD iterations with such a strategy might compress the model size more effectively, and hence should also be considered in future work. Furthermore, our work is the first study on the sequential distillation at the objective level, not at the architecture level such as [Cho and Hariharan, 2019; Mirzadeh et al., 2020].
6 Robustness to Noisy Labels
In this section, we investigate how noisy labels, samples annotated with incorrect labels in the training dataset, affect the distillation ability when training a teacher network. This setting is related to the capacity for memorization and generalization. Modern deep neural networks even attempt to memorize samples perfectly [Zhang et al., 2016]; hence, the teacher might transfer corrupted knowledge to the student in this situation. Therefore, it is thought that logit matching might not be the best strategy when the teacher is trained using a noisy label dataset.
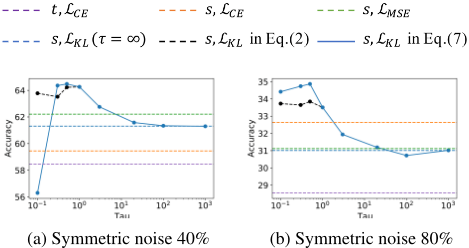
From this insight, we simulate the noisy label setting to evaluate the robustness on CIFAR-100 by randomly flipping a certain fraction of the labels in the training dataset following a symmetric uniform distribution. Figure 6 shows the test accuracy graphs as the loss function changes. First, we observe that a small network (WRN-16-2 (s), orange dotted line) has a better generalization performance than an extensive network (WRN-28-4 (t), purple dotted line) when models are trained with LCE. This implies that a complex model can memorize the training dataset better than a simple model, but cannot generalize to the test dataset. Next, WRN-28-4 (purple dotted line) is used as the teacher model. When the noise is less than 50%, extreme logit matching (LMSE, green dotted line) and logit matching with δ∞ (LKL(τ = ∞), blue dotted line) can mitigate the label noise problem compared with the model trained with LCE. However, when the noise is more than 50%, these training cannot mitigate this problem because it follows corrupted knowledge more often than correct knowledge.
| WRN-28-4 | WRN-16-4 | WRN-16-2 | Test accuracy |
|---|---|---|---|
| X | X | LCE | 72.68 % |
| X | LCE (77.28%) | LKL(τ = 3) | 74.84 % |
| LKL(τ = 20) | 75.42 % | ||
| LMSE | 75.58 % | ||
| LCE (78.88%) | X | LKL(τ = 3) | 74.24 % |
| LKL(τ = 20) | 75.15 % | ||
| LMSE | 75.54 % | ||
| LCE (78.88%) | LKL(τ = 3) (78.76%) | LKL(τ = 3) | 74.52 % |
| LKL(τ = 20) | 75.47 % | ||
| LMSE | 75.78 % | ||
| LMSE (79.03%) | LKL(τ = 3) | 74.83 % | |
| LKL(τ = 20) | 75.47 % | ||
| LMSE | 75.48 % |
Interestingly, the best generalization performance is achieved when we use LKL with τ ≤ 1.0. In Figure 6, the blue solid line represents the test accuracy using the rescaled loss function from the black dotted line when τ ≤ 1.0. As expected, logit matching might transfer the teacher's overconfidence, even for incorrect predictions. However, the proper objective derived from both logit matching and label matching enables similar effects of label smoothing, as studied in [Lukasik et al., 2020; Yuan et al., 2020]. Therefore, LKL with τ = 0.5 appears to significantly mitigate the problem of noisy labels.
7 Conclusion
In this paper, we first showed the characteristics of a student trained with LKL according to the temperature-scaling hyperparameter τ. As τ goes to 0, the trained student has the label matching property. In contrast, as τ goes to ∞, the trained student has the logit matching property. Nevertheless, LKL with a sufficiently large τ cannot achieve complete logit matching owing to δ∞. To achieve this goal, we proposed a direct logit learning framework using LMSE and improved the performance based on this loss function. In addition, we showed that the model trained with LMSE followed the teacher's penultimate layer representations more than that with LKL. We observed that sequential distillation can be a better strategy when the capacity gap between the teacher and the student is large. Furthermore, we empirically observed that, in the noisy label setting, using LKL with τ near 1 mitigates the performance degradation rather than extreme logit matching, such as LKL with τ = ∞ or LMSE.
Acknowledgments
This work was supported by Institute of Information & communications Technology Planning & Evaluation (IITP) grant funded by the Korea government (MSIT) [No.20190-00075, Artificial Intelligence Graduate School Program (KAIST)] and [No. 2021-0-00907, Development of Adaptive and Lightweight Edge-Collaborative Analysis Technology for Enabling Proactively Immediate Response and Rapid Learning].
@inproceedings{ijcai2021p362,
  title     = {Comparing Kullback-Leibler Divergence and Mean Squared Error Loss in Knowledge Distillation},
  author    = {Kim, Taehyeon and Oh, Jaehoon and Kim, Nak Yil and Cho, Sangwook and Yun, Se-Young},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {2628--2635},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/362},
  url       = {https://doi.org/10.24963/ijcai.2021/362},
}
TY - CPAPER TI - Comparing Kullback-Leibler Divergence and Mean Squared Error Loss in Knowledge Distillation AU - Kim, Taehyeon AU - Oh, Jaehoon AU - Kim, Nak Yil AU - Cho, Sangwook AU - Yun, Se-Young T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 2628 EP - 2635 DO - 10.24963/ijcai.2021/362 UR - https://doi.org/10.24963/ijcai.2021/362 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





