
Exact Acceleration of K-Means++ and K-Means||
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 2928-2935.
https://doi.org/10.24963/ijcai.2021/403
© 2021 International Joint Conferences on Artificial Intelligence
Keywords
- Data Mining: Clustering
- Machine Learning: Clustering
- Machine Learning Applications: Big data; Scalability
Abstract
K-Means++ and its distributed variant K-Means|| have become de facto tools for selecting the initial seeds of K-means. While alternatives have been developed, the effectiveness, ease of implementation,and theoretical grounding of the K-means++ and || methods have made them difficult to "best" from a holistic perspective. We focus on using triangle inequality based pruning methods to accelerate both of these algorithms to yield comparable or better run-time without sacrificing any of the benefits of these approaches. For both algorithms we are able to reduce distance computations by over 500×. For K-means++ this results in up to a 17×speedup in run-time and a551×speedup for K-means||. We achieve this with simple, but carefully chosen, modifications to known techniques which makes it easy to integrate our approach into existing implementations of these algorithms.
- [Arthur and Vassilvitskii, 2007] David Arthur and Sergei Vassilvitskii. k-means++: The Advantages of Careful Seeding. In ACM-SIAM symposium on Discrete algo- rithms, volume 8, pages 1027-1035, 2007.
- [Bachem et al., 2015] Olivier Bachem, Mario Lucic, and An- dreas Krause. Coresets for Nonparametric Estimation -the Case of DP-Means. In ICML, volume 37, pages 209-217, 2015.
- [Bachem et al., 2016a] Olivier Bachem, Mario Lucic, Hamed Hassani, and Andreas Krause. Fast and Provably Good Seedings for k-Means. In NeurIPS, pages 55-63. 2016.
- [Bachem et al., 2016b] Olivier Bachem, Mario Lucic, S Hamed Hassani, and Andreas Krause. Approximate K- means++ in Sublinear Time. In AAAI, pages 1459-1467, 2016.
- [Bachem et al., 2017] Olivier Bachem, Mario Lucic, and An- dreas Krause. Distributed and Provably Good Seedings for k-Means in Constant Rounds. In ICML, volume 70, pages 292-300, 2017.
- [Bahmani et al., 2012] Bahman Bahmani, Benjamin Mose- ley, Andrea Vattani, Ravi Kumar, and Sergei Vassilvitskii. Scalable K-means++. VLDB Endowment, 5(7):622-633, mar 2012.
- [Beygelzimer et al., 2006] Alina Beygelzimer, S Kakade, and John Langford. Cover trees for nearest neighbor. In ICML, pages 97-104, 2006.
- [Bottou and Bengio, 1995] Léon Bottou and Yoshua Bengio. Convergence Properties of the K-Means Algorithms. In NeurIPS, pages 585-592, 1995.
- [Curtin et al., 2013] Ryan R. Curtin, William B. March, Parikshit Ram, David V. Anderson, Alexander G. Gray, and Charles L. Isbell. Tree-Independent Dual-Tree Algo- rithms. In ICML, volume 28, pages 1435-1443, 2013.
- [Curtin, 2017] Ryan R Curtin. A Dual-Tree Algorithm for Fast k -means Clustering With Large k. In SDM, pages 300-308. jun 2017.
- [Ding et al., 2015] Yufei Ding, Yue Zhao, Xipeng Shen, Madanlal Musuvathi, and Todd Mytkowicz. Yinyang K- means: A Drop-in Replacement of the Classic K-means with Consistent Speedup. In ICML, pages 579-587, 2015.
- [Dooley and Kale, 2006] Isaac Dooley and Laxmikant Kale. Quantifying the Interference Caused by Subnormal Floating-Point Values. In Proceedings of the Workshop on Operating System Interference in High Performance Ap- plications, sep 2006.
- [Efraimidis and Spirakis, 2006] Pavlos S. Efraimidis and Paul G. Spirakis. Weighted random sampling with a reser- voir. Information Processing Letters, 97(5):181-185, mar 2006.
- [Elkan, 2003] Charles Elkan. Using the Triangle Inequality to Accelerate k-Means. In ICML, pages 147-153, 2003.
- [Fog, 2016] Agner Fog. Instruction tables: Lists of in- struction latencies, throughputs and micro-operation break- downs for Intel, AMD and VIA CPUs. 2016.
- [Hamerly, 2010] Greg Hamerly. Making k-means even faster. In SDM, pages 130-140, 2010.
- [Izbicki and Shelton, 2015] Mike Izbicki and Christian R Shelton. Faster Cover Trees. In ICML, volume 37, 2015.
- [Jegelka et al., 2009] Stefanie Jegelka, Suvrit Sra, and Arindam Banerjee. Approximation Algorithms for Tensor Clustering. In ATL, pages 368-383, 2009.
- [Newling and Fleuret, 2016] James Newling and François Fleuret. Fast k-means with accurate bounds. In ICML, pages 936-944, 2016.
- [Newling and Fleuret, 2017] James Newling and François Fleuret. K-Medoids For K-Means Seeding. In NeurIPS, pages 5195-5203. 2017.
- [Nielsen and Nock, 2015] Frank Nielsen and Richard Nock. Total Jensen divergences: Definition, properties and clus- tering. In ICASSP, pages 2016-2020, apr 2015.
- [Nock et al., 2008] Richard Nock, Panu Luosto, and Jyrki Kivinen. Mixed Bregman Clustering with Approximation Guarantees. In ECMLPKDD, pages 154-169, 2008.
- [Pelleg and Moore, 1999] Dan Pelleg and Andrew Moore. Accelerating Exact K-means Algorithms with Geometric Reasoning. In KDD, pages 277-281, 1999.
- [Phillips, 2002] Steven J. Phillips. Acceleration of K-Means and Related Clustering Algorithms. In Proc. 4th Int. Workshop on Algorithm Engineering and Experiments (ALENEX 2002), pages 166-177, 2002.
- [Raff and Nicholas, 2018] Edward Raff and Charles Nicholas. Toward Metric Indexes for Incremental Inser- tion and Querying. arXiv, 2018.
- [Raff et al., 2020] Edward Raff, Bobby Filar, and James Holt. Getting Passive Aggressive About False Positives: Patch- ing Deployed Malware Detectors. In 2020 International Conference on Data Mining Workshops (ICDMW), pages 506-515. IEEE, nov 2020.
- [Raff, 2017] Edward Raff. JSAT: Java Statistical Analysis Tool, a Library for Machine Learning. JMLR, 18(23):1-5, 2017.
- [Ryšavý and Hamerly, 2016] Petr Ryšavý and Greg Hamerly. Geometric methods to accelerate k-means algorithms. In SDM, pages 324-332, jun 2016.
- [Sculley, 2010] D. Sculley. Web-scale k-means clustering. In Proceedings of the 19th international conference on World wide web, pages 1177-1178, 2010.
- [Si et al., 2017] Si Si, Cho-Jui Hsieh, and Inderjit S Dhillon. Memory Efficient Kernel Approximation. JMLR, 18(20):1-32, 2017.
- [Yianilos, 1993] P.N. Yianilos. Data structures and algo- rithms for nearest neighbor search in general metric spaces. In ACM-SIAM Symposium on Discrete algorithms, pages 311-321, 1993.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Before one can run the -means algorithm, a prerequisite step is needed to select the initial -seeds to use as the initial estimate of the means. This seed selection step is critical to obtaining high quality results with the -means algorithm. Selecting better initial centers <1� � � � � < can improve the quality of the final -means clustering. A major step in developing better seed selection was the -means++ algorithm. This was the first to show that the seeds it finds are log-optimal in expectation for solving the -means problem [Arthur and Vassilvitskii, 2007]. For a dataset with = items -means++ requires $"= " distance computations. If % processors are available -means++ can be done in$"= �%". However, the amount of communication overhead to do -means in parallel is significant. To remedy this, Bahmani et al. [2012] introduced -meansk which retains the$"= �%" complexity and performs a constant factor more distance computations to significantly reduce the communication overhead while still yielding the same log-optimal results [Bachem et al., 2017]. When working in a distributed environment, where communication must occur over the network, this can lead to large reductions in run-time [Bahmani et al., 2012].
In this work, we seek to accelerate the original -means++ and -meansk algorithms so that we may obtain the same provably good results in less time without compromising on any of the desirable qualities of -means++or -meansk. We will review work related to our own in § 2. Since the bottlenecks and approach to accelerating these two algorithms are different we will review their details and our approach to accelerating them sequentially. In respect to -means++ in § 3, we show how simple application of the triangle inequality plus a novel dynamic priority queue allows us to avoid redundant computations and keep the cost of sampling new means low. In § 4 we address -meansk and develop a new NearestInRange query that allows us to successfully use a metric index to prune distance computations even though it is restricted to corpora normally too small to be useful with structures like KD-trees. We then perform empirical evaluation of our modifications in § 5 over a larger set of corpora with more diverse properties covering 2 »32� 4096…. In doing so, we observe that our accelerated algorithms succeed in requiring either the same or less time across all datasets and all values of , making it a Pareto improvement. Finally, we will conclude in § 6.
The cost of -means++ has long been recognized as being an expensive but necessary step for better results, with little progress on improvement. Modern accelerated versions of - means clustering perform as few as 1�2 total iterations of the dataset [RyšavýandHamerly, 2016],making -means++seed selection take up to 44% of all distance computations. Outside of exact -means clustering, faster seed selection can help improve stochastic variants of -means [Bottou and Bengio, 1995; Sculley, 2010] and is useful for applications like corset construction [Bachem et al., 2015], change detection [Raff et al., 2020], tensor algorithms [Jegelka et al., 2009], clustering with Bergman divergences [Nock et al., 2008], and Jensen divergences [Nielsen and Nock, 2015]. Applications with large have in particular been neglected, even though � 20� 000 is useful for scaling kernel methods [Si et al., 2017].
2 RelatedWork
Many prior works have looked at using the triangle inequality, 3"0� 1" , 3"1� 2" � 3"0� 2", to accelerate the - means algorithm. While the first work along this line was done by Phillips [2002], it was first successfully popularized by Elkan [2003]. Since then, several works have attempted to build faster -means clustering algorithms with better incorporation or tighter bounds developed through use of the triangle inequality [Hamerly, 2010; Ding et al., 2015; Newling and Fleuret, 2016]. Despite the heavy use of the triangle inequality to accelerate -means clustering, we are aware of no prior works that apply it to the seed selection step of -means++ and -meansk. We belive this is largely because these methods can not accelerate the first iteration of -means, as they rely on the first iteration's result to accelerate subsequent iterations. Since -means++ is effectively a single iteration of -means, their approaches can not be directly applied to the seed selection step.
In our work to accelerate -meansk using metric index structures a similar historical theme emerges. Prior works have looked at using index structures like KD-trees [Pelleg and Moore, 1999] and Cover-trees [Curtin, 2017] to accelerate the -means clustering algorithm, but did not look at the seed selection step. Similarly we will use a metric indices to accelerate -meansk, but we will develop an enhanced nearest neighbor query that considers a maximum range to meaningfully prune even when using small values of .
Most work we are aware of focuses on extending or utilizing the -means++ algorithm with few significant results on improving it. The most significant in this regard is the AFKMC[Bachem et al., 2016a] algorithm and its predecessor KMC [Bachem et al., 2016b]. Both can obtain initial seeds with the same quality as -means++ with less distance computations but scale as $"=�% ,< 2 ", where < is a budget factor. This makes them less effective when a large number of CPUs % is available or when is large. Neither work factored in actual run-time. [Newling and Fleuret, 2017] showed that these implementations are actually 3.3� slower when overheads are factored in. We consider run-time in our own work to show that our improvements materialize in practice.
3 Accelerating -Means++
We start with the -means++ algorithmwhere we present detailed pseudo-code in Algorithm 1. We detail the method and how it works when each data point G8 has with it an associated weight F8, as this is required later on. The algorithm begins by selecting an initial seed at random, and then assigning a new weight V8 to each data point G8 , based on the squared distance of G8 to the closest existing seed. At each iteration, we select a new seed to the set based on these weights and return once we have : total seeds. This requires : iterations through the dataset or size = resulting in $"= � :" distance computations. Note that we cache the distance between each point G8 and it's closest mean into the variable U8. We will maintain this notation throughout the paper and use U8 as shorthand.
The first step toward improving the -means++ algorithm is to filter out redundant distance computations. To do this, we note that at each iteration we compare the distance of each point G8 to the newest mean <: against the previous closest mean <9 , where 1 � 9 � :. That is, we need to determine if 3"G8� <:" � 3"G8� <9 ". To do this, we can use Lemma 1 as introduced and proven by Elkan [2003],
Algorithm 1 K-Means++
Require: Desired number of seeds , data points G1� � � � � G=, data weights F1� � � � � F= such that F8 � 0 1: V8 F8� ˝ = I=1 FI� 88 2 »1� =… 2: <1 G8 , where 8 is selected with probability V8 3: : 1, " fi1 4: while : � do 5: for 8 2 »1� =… do 6: U8 min"U8� 3"<:� G8"" 7: for 8 2 »1� =… do 8: V8 F8 � U 2 8 � �˝ = I=1 FI � U 2 I � 9: : : , 1 10: <: G8 , where 8 is selected with probability V8 11: return initial means <1� � � � � <3.1 Applying the Triangle Inequality
We can use the distance between <? and <9 to determine if computing 3"G8� <:" is a fruitless effort by checking if 3"<9 � <:" ¡ 3"G8� <9 ". This is already available in the form of U8 as presented in Algorithm 1. We then only need to compute 3"< 9 � <: "89 � :, of which there is intrinsically less than : unique values at each iteration. Thus, we can compute W9 = 3"<9 � <:" once at the start of each loop, and we can re-use these : values for all = � : distance comparisons.
Applying this bound we can avoid many redundant computations. As there are still total iterations to select means, each iteration will perform : comparisons to previous means and = � :, we get at most = distance comparisons per iteration making the worst case still $"=:" distance computations for the -means++ algorithm.
3.2 Avoiding Subnomral Slowdowns
A non-trivial cost exists in lines 7-10 of Algorithm 1 where we must compute the probability of selecting each point as the next mean and then perform the selection. This requires at least 3 � = floating point multiplications which can be a bottleneck in low dimensional problems. This can be exasperated because squared distance to the closest center U 2 8 naturally becomes very small as : increases resulting in subnormalized floating point values. Subnormals (also called denormal) attempt to extend the precision of IEEE floats, but can cause 100� slowdowns in computation [Dooley and Kale, 2006]. Depending on hardware, subnormals can also interfere with pipelining behavior and out-of-order execution, making a single subnormal computation highly detrimental to performance [Fog, 2016]. This is particularly problematic because pruning based on the triangle inequality works best on low dimensional problems, and the normalization step prevents us from realizing speedups in terms of total run-time.
To circumvent this bottleneck, we develop a simple approach to create a dynamic priority queue that allows us to sample the next mean accurately without having to interact with most of the samples per iteration. We start with the elegant sampling without replacement strategy introduced by Efraimidis and Spirakis [2006]. Given = items 1� � � � � = with weighted probabilities F1� � � � � F=, it works by assigning each item 8 a priority _8F �1 8 where _8 is sampled from the Exponential distribution with _ = 1 (i.e., _8 � Exponential"1"). To select items without replacement, one selects the values with highest priority (smallest _8F �1 8 values). This can normally be done with the quick-select algorithm in $"=" time.
For -means++ seeding we want to instead use the priority _8F �1 8 U �2 8 in order to produce random samples. The term F �1 8 U �2 8 acts as the weight for datum 8 being selected, and it is a combination of the original relative weight of the datum F8 and the squared distance to the nearest seed U 2 8 . At the start we sample _8 � Exponential"1" once. During each round, we update all U8 values and leave _8 fixed. It is trivial to see that this does not alter the expectation of any point being selected conditioned on the point 8 already being removed. This is because all _8 are sampled independently, and so the removal of any _8 does not impact the relative weights of any other point. Thus, we can use the weighted sampling without replacement strategy of Efraimidis and Spirakis [2006] to select the seeds. We performed a sanity check by implementing this naive approach and making no other changes. This resulted in the same quality solutions over many trials with the same statistical mean and variance.
At first glance, this strategy obtains no benefit as the value of U8 will change on each iteration. Each value of U8 changing means that the relative ordering of all remaining priorities _8 F �1 8 U �2 8 will also change. This requires a full quick-select run on each iteration to discover the new maximum priority item. However, we note that U8 can only decrease with each iteration, and thus the priority of any given sample either remains constant or decreases. Our first contribution is the realization that this property can be exploited to reduce the cost of sampling so that only a subset of priorities need to be considered to sample the next point.
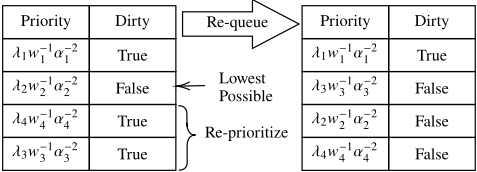
We can instead create a priority queue using a standard binary heap to select the next smallest value of _8F �1 8 U �2 8 and maintain a marker if the priority of an item 8 has become dirty. An item is dirty if and only if the item has a higher priority than it actually should. If there is a clean item I in the queue, then all items with a lower apparent priority than I must have a true priority that is still lower than I. Thus, we need only fix the priority of items higher than I.
See Figure 1 for an example of this queue for a dataset of = = 4 items. Item 2 is clean, and all items with a higher priority (3 and 4) are dirty. That means item 2 has the lowest possible priority that could be the next true sample because it is possible the values of items 3 and 4 will become larger (read, lower priority) once the updated values of U3 and U4 are computed. Thus, we can remove all items in the queue until we reach item 2 and then re-insert them into the queue with their correct priorities. In this hypothetical example, item 4 still had a lower priority after updating, and so will become the next mean when we them remove it from the queue. Item 1 occurred after item 2 because it had a lower priority. Even though item 1 was dirty, we did not need to consider it because its priority can only decrease once U1 is updated. Because Item 2 was clean, its priority will not change, and there is no possibility of item 1 being selected.
3.3 Accelerated -Means++
Algorithm 2 Our Accelerated K-Means++
Require: Desired number of seeds , data points G1� � � � � G=,
data weights F1� � � � � F= such that F8 � 0 1: _8 � Exponential"1"� 88 2 »1� =… 2: Priority Queue & with each index 8 given priority _8�F8 3: dirty8 False 4: <1 G&�Pop"" 5: " fi1, : 1, q8 0 6: for : 2 »1� " do � For each new center : 7: for 9 2 »1� :" do � Get distance to previous centers 8: W9 3"<:� <9 " 9: for 8 2 »1� =… do 10: if 1 2 Wq8 � U8 then 11: continue � Pruned by Lemma 1 12: if 3"<:� G8" � U8 then 13: U8 3"<:� G8", q8 : 14: dirty8 True � Priority may now be too high 15: Create new stack ( 16: while dirty&�Peek"" do � All items that could be selected 17: 8 &�Pop"" 18: (�Push"8" 19: for 8 2 ( do � Update true priority 20: &�Push"8� _8� � F8 � U 2 8 � " 21: dirty8 False 22: <: G&�Pop"" � Select newmean by clean top priority 23: return initial means <1� � � � � <The final algorithm that performs the accelerated computation is given in Algorithm 2. Lines 7-11 take care to avoid redundant distance computations, and lines 14-21 ensure that the dynamic priority queue allows us to select the next mean without considering all = � : remaining candidates. Combined, we are able to regularly gain reductions both in terms of total time taken as well as the number of distance computations required. Through the use of our dynamic priority queue we find that we regularly consider less than 1% of total remaining = � : items. This is important when we work with low-dimension datasets. When the dimension is very small (e.g., 3 = 2 for longitude/latitude data is a common use case), there is little computational cost in the distance computations themselves, and so much of the bottleneck in runtime is contained within the sampling process. Our dynamic queue avoids this bottleneck allowing us to realize the benefits of reduced distance computations.
4 Accelerating -Meansk
Now we turn our attention to the -meansk algorithm detailed in Algorithm 3. While -meansk requires more distance computations, it is preferred in distributed environments because it requires less communication which is a significant bottleneck for -means++ [Bahmani et al., 2012]. It works by reducing the rounds of communication to a fixed number of ' � rounds, yet still obtains the log-optimal results of -means++ [Bachem et al., 2017]. In each of the rounds, � new means are sampled based on the weighted unnormalized probability �F8U 2 8 . With the standard defaults of ' = 5 and � = 2 , we end up with an expected '2 ¡ total means. These ' � � potential means are weighted by the number of points that they are closest to and then passed to the -means++ algorithm to reduce them to a final set of means, which produces the final result. Note this last step requires $" 2 " distance computations when naively using Algorithm 1, making it necessary to accelerate the -means++ algorithm in order to effectively accelerate -meansk for datasets with large .
Algorithm 3 K-Meansk
Require: Desired number of seeds , G1� � � � � G=, data weights F1� � � � � F=, rounds ', oversampling factor � 1: V8 F8� ˝ = 9=1 F 9 � 88 2 »1� =… 2: 21 G8 , where 8 is selected with probability V8 3: : 1, :prev 0, " fi1 4: for A 2 »1� '… do 5: for 8 2 »1� =… do 6: for 9 2 ":prev� :… do 7: U8 min � U8� 3 � 2 9 � G8 �� 8: :prev : 9: / ˝ = 8=1 F8 � U 2 8 10: for 8 2 »1� =… do 11: if ? � Ber"min"1� � � F8 � U 2 8 �I"" is true then 12: : : , 1, 2: G8, U8 0 13: Let F 0 8 ˝ = 9=1 F9 � 1»3"28� G 9 " = U9 … � Weight set to number of points closest to center 28 14: return K-Means++( , 21� � � � � 2:, F 0 1 � � � � � F 0 : ) � Run Algorithm 1Since � ' � � � =, the final step of running -means++ is not overbearing to run on a single compute node, and the sampling procedure is no longer a bottleneck that requires subversion. In a distributed setting, the � newmeans selected are broadcast out to all worker nodes, which is possible because � � =, and thus requires limited communication overhead. However, the ability to use the triangle inequality becomes less obvious. Using the same approach as before, similar to Elkan [2003], would require$" 2 " pairwisedistances computations between the new and old means, and more book-keeping overhead that would reduce the effectiveness of avoiding distance computations.
Another strategy uses an algorithm like the Cover-Tree that accelerates nearest neighbor searches and supports the removal of data points from the index [Beygelzimer et al., 2006; Izbicki and Shelton, 2015]. Then, we could perform an allpoints nearest neighbor search [Curtin et al., 2013]. However, we are unaware of any approach that has produced a distributed cover-tree algorithm that would not run into the same communication overheads that prevents the standard - means++ from working in this scenario. As such, it does not appear to be a worth while strategy.
4.1 Nearest In Range Queries
Another approach would be to fit an index structure C to only the � new points, and for each non-mean G8 find its nearest potentially new assignment by querying C . Since � is $" " this is too small a dataset for pruning to be effective with current methods.
To do this, we use the Vantage Point tree (VP) algorithm [Yianilos, 1993] because it is fast to construct, has low overhead which makes it competitive with other algorithms such as KD-trees and Cover-trees [Raff and Nicholas, 2018], and simple to augment with our new NearestInRange search. The pseudo-code for the standard VP search is given in Algorithm 4, where GetChild, Search, and Best are auxiliary functions used by the Nearest function to implement a standard nearest neighbor search. The VP has a left and right child, and it uses a value g to keep track of the distance to the nearest neighbor found. It also maintains two pairs of bounds, nearlow� nearhigh indicating the shortest and farthest distance to the points in the left child and farlow� far�86� do the same for the right child.
To remedy this, we note that we have additional information available to perform the search. The value U8 which indicates the distance of point G8 to its closest current mean. As such, we introduce a NearestInRange search that returns the nearest neighbor to a query point @ against an index C if it is within a radius of A to the query. Since most points G8 will not change ownership in a given iteration, a NearestInRange search could be able to prune out the entire search tree, and it will increase its effectiveness even if is small.
A standard Nearest Neighbor search calls the Nearest function with g = 1, and the bound is updated as the search progresses when it fails to prune a branch. Our contribution is simple. The NearestInRange function instead sets g = A, the minimum viable radius. It is easy to verify that this can only monotonically improve the pruning rate of each search. Since g bounds the distance to the nearest neighbor, and we know from the " values an upper-bound on the distance to the nearest neighbor, the modification remains correct. The rest of the algorithm remains unaltered, and can simply terminate the search faster due to a meaningful initial bound.
Thus, to build an accelerated -meansk we build an index C on the newly selected means. We do comparisons against that filtered with our NearestInRange search, as detailed in Algorithm 5. For the first iteration, the loop on lines 6-10 will be fast with only 21 to determine the initial distribution,
Algorithm 4 Nearest Neighbor Search in VP Tree
1: function GetChild( ;>F) 2: if ;>F = CAD4 then 3: return left child 4: return right child � Else, return other 5: function Search(A, g, ;>F) 6: if ;>F = CAD4 then 7: 0 nearlow� 1 nearhigh 8: else 9: 0 farlow� 1 farhigh 10: return 0 � g � A � 1 , g � i.e., is this True or False? 11: function Best(g, g 0 , ��, �� 0 ) 12: if g � g 0 then 13: return g� �� 14: return g 0 � �� 0 � Else, return other 15: function Nearest(@, g, ��) 16: A 3"?� @" 17: g� �� Best"g� A� ��� ?" 18: < nearhigh,farlow 2 19: ; 5 A � < � True/False, search near/left child first? 20: if Search(A� g� ; 5 ) then 21: g 0 � �� 0 GetChild( ; 5 ).Nearest(@� g� ��) 22: g� �� Best"g� g 0 � ��� �� 0 " 23: if Search(A� g� :; 5 ) then 24: g 0 � �� 0 GetChild( :; 5 ).Nearest(@� g� ��) 25: g� �� Best"g� g 0 � ��� �� 0 " 26: return g� �� 27: function NearestInRange(@, <0G'0=64) 28: return Nearest(@� <0G'0=64� �1) � This simple function, used in-place of Nearest, is our contribution.Algorithm 5 Our Accelerated K-Meansk
Require: Desired number of seeds , G1� � � � � G=, data weights F1� � � � � F=, rounds ', oversampling factor � 1: V8 F8� ˝ = 9=1 F 9 � 88 2 »1� =… 2: 21 G8 , where 8 is selected with probability V8 3: " fi1, :prev 0, : 1 4: for A 2 »1� '… do 5: C new index built from f2:prev � � � � � 2:g 6: for 8 2 »1� =… do 7: 9 C �NearestInRange(G8� U8) 8: if 9 � 0 then 9: U8 3"2 9 � G8" 10: :prev :, / ˝ = 8=1 F8 � U 2 8 11: for 8 2 »1� =… do 12: if ? � Ber"min"1� � � F8 � U 2 8 �/"" is true then 13: : : , 1, 2: G8, U8 0 14: Let F 0 8 ˝ = 9=1 F9 � 1»3"28� G 9 " = U9 … � Weight set to number of points closest to center 28 15: return K-Means++( , 21� � � � � 2:, F 0 1 � � � � � F 0 : ) � Run Algorithm 2and on every subsequent round we have a meaningful value of U8 that can be used to accelerate the search. If none of the
� new candidates 2:prev � � � � � 2: are within a distance of U8 to each point G8, then the NearestInRange function will return a negative index which can be skipped.
In addition, we use our accelerated -means++ algorithm Algorithm 2 in the final step rather than the standard algorithm. This allows us to accelerate all parts of the -meansk method while also keeping the simplicity and low communication cost of the original design. The Vantage Point tree is a small index since it is built upon a small dataset of � points, and the index can be sent to every worker node in a cluster in the exact same manner.
5 Experimental Results
Now that we have detailed the methods by which we accelerate the -means++ and -meansk algorithms, we will evaluate their effectiveness. The two measures we are concerned with are the following: 1) reducing the total number of distance computations and 2) the total run-time spent. Measuring distance computations gives us an upper-bound on potential effectiveness of our algorithm, and allows us to compare approaches in an implementation and hardware independent manner. Measuring the run-time gives us information about the ultimate goal, which is to reduce the time it takes to obtain seeds. However, it is sensitive to the hardware in use, the language the approach is implemented in, and the relative skills of program authors. For this work we used the JSAT library [Raff, 2017]. The -means++ algorithm was provided by this framework, and we implemented the -meansk and accelerated versions of both algorithms using JSAT. This way all comparisons with respect to run-time and the -means++ and k algorithms presented are directly comparable. Our implementations have been contributed to the JSAT library for public use.
Since our goal is to produce accelerated versions of these algorithms that are uniformly better, we attempt to test over a wide selection of reasonable scenarios. In Table 1 we show the 11 datasets we use, with � 2 »3� 780…, and = covering four orders of magnitude. We will test 2 »32� 4096… covering each power of two so that we may understand the behavior as changes and to make sure we produce an improvement even when is small. To the best of our knowledge, this is a larger number of datasets, range and values of , and range and values of � to be tested compared to prior work1.
Prior works that have investigated alternatives to - means++ have generally explored only a few datasets with � � 100 features and less than 4 values of , sometimes testingonlyonevalueof per dataset [Bachemet al., 2016b]. For example, while MNIST is regularly tested in seed selection, it is usually projected down to 50 dimensions first [Hamerly, 2010] due to being difficult to accelerate.
Unless stated otherwise, all experiments were done with a single CPU core from an iMac with a 3.5 GHz Intel i5 CPU with 64 GB of RAM. The phishing dataset is only tested up to = 2048, because at = 4096 we would be selecting over 1/4 of the dataset as means, at which point the purpose of -means++ style seeding is being defeated by selecting too large a portion of the corpus. All results are averaged over 5 runs, and took four months to complete in our compute environment.
1We are aware of no prior work in this space that has considered � ¡ 1024, where pruning methods are unlikely to succeed due to the curse of dimensionality. We consider this reasonable and beyond scope, as such scenarios are usually sparse and best handled by topic models like LDA.
| Dataset | = | � |
|---|---|---|
| Phishing | 11055 | 68 |
| cod-rna | 59535 | 8 |
| MNIST | 60000 | 780 |
| aloi | 108000 | 128 |
| Range-Queries | 200000 | 8 |
| Skin/NoSkin | 245057 | 3 |
| covertype | 581012 | 54 |
| SUSY | 5000000 | 18 |
| Activity Rec. | 33741500 | 5 |
| HIGGS | 11000000 | 28 |
| Web2 | 45811883 | 5 |
5.1 -Means++ Results
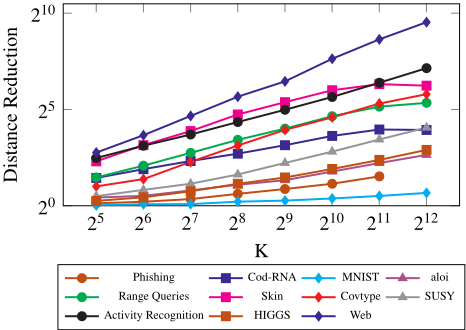
We start with the -means++ results with the reduction in distance computations shown in Figure 2. In the worst case for = 32 on the MNIST dataset, we still have to do 98% of the distance computations as the standard algorithm, but this improved to only 63% by = 4096. The best case is observed with the Web dataset, starting out with only 15% of the distance computations at = 32 and only 0.1% by = 4096, a 739� improvement.
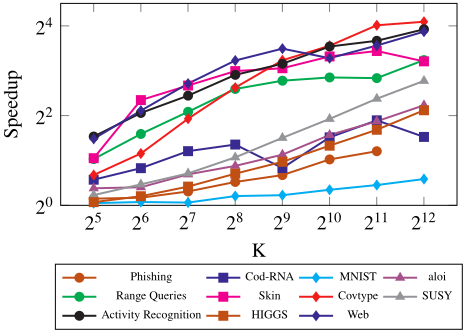
As we noted in the design of our accelerated variant, we must avoid over-emphasising the performance of just reduced distance computations as the cost of re-normalizing the distribution to sample the next mean is a non-trivial cost. This is especially true when we are able to reduce the distance computations by � 16� for several of our datasets. The results showing the run-time reduction are presented in Figure 3.
Across all the datasets, we see that the factor reduction in distance computations is a monotonic improvement for - means++. We never see any case where our accelerated approach performs more distance computations than the naive approach. This confirms our decision to do an extra : � 1 distance computation between the newest mean <: and the previous means <1� � � � � <:�1.
Inall cases, our acceleratedversionof -means++ is always faster than the standard algorithm. As expected, MNIST has the lowest speedup based on the number of distance computations avoided. At = 32 we achieved only a 3.4% reduction in time but was 1�5� faster by = 4096.
Dynamic Priority Impact
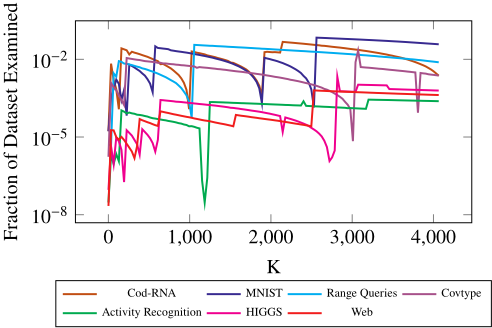
Since the normalization step is non-trivial, especially when � is small, we see that the actual speedup in run-time is not as strongly correlated with the dimension �. The Covertype dataset (� = 54) had the 4th largest reduction in distance computations, but it had the largest reduction in run-time with a 17� improvement at = 4096. Our ability to still obtain real speedups on these datasets is because our dynamic priority queue allows us to consider only a small subset of the dataset to accurately select the next weighted randommean. This can be seen in Figure 4, where a subset of the datasets are shown with the fraction of the corpus examined on the y-axis. As the datasets get larger our dynamic queue generally becomes more effective, thus reducing the number of points that need to be checked to � 1%.
To confirm that our dynamic priority queue's results are meaningful, we perform an ablation of Algorithm 2 where the dynamic priority queue on lines 15-21 are replaced with the standard sampling code from Algorithm 1. We run both versions and record the speedup when our dynamic queue is used in Table 2 for = 4096. Here we can see that with the exception of the cod-rna dataset, where there is a � 2% slowdown (on the fastest dataset to run), our approach gives a 5% � 231% speedup in all other cases with a median improvement of 20%. We also note that for all � 4096 we still observe benefits to our queue, but the variance does increase to the degree of speedup. We did not observe any performance regressions larger than 3% in extended testing.
| Dataset | Speedup |
|---|---|
| cod-rna | 0.983 |
| Phishing | 2.313 |
| MNIST | 1.059 |
| aloi | 1.059 |
| Range-Queries | 1.342 |
| Skin/NoSkin | 1.217 |
| covtype | 1.877 |
| SUSY | 1.259 |
| Activity Recognition | 1.207 |
| HIGGS | 1.279 |
| Web | 1.725 |
5.2 -Meansk Results
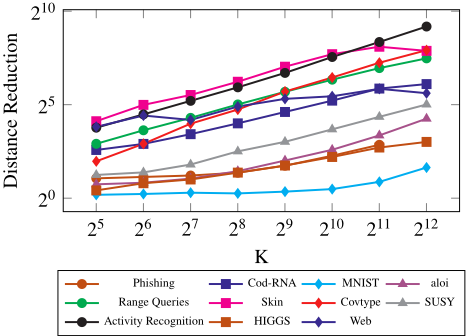
The � 4� improvement in distance computations also carries over to the total run-time, as shown in Figure 6. We observe a more consistent behavior because the cost of normalizing and sampling the new means is reduced to only ' = 5 rounds of sampling. Where our accelerated -means++ had the relative improvement drop significantly for small � � 10 datasets due to this overhead, our accelerated -meansk algorithm sees the ordering remain relatively stable. For example, the Activity Recognition dataset enjoys the greatest reduction in distance computations as well as run-time, and the 579�
In Figure 5 we show the factor reduction in distance computations, which mirrors the overal trends of Figure 2. The results have improved by an additional � 2 � 4� with a 579� reduction in distance computations on the Activity Recognition dataset. The MNIST dataset still had the least improvement, but still obtained a more significant 88% reduction in distance computations at = 32.
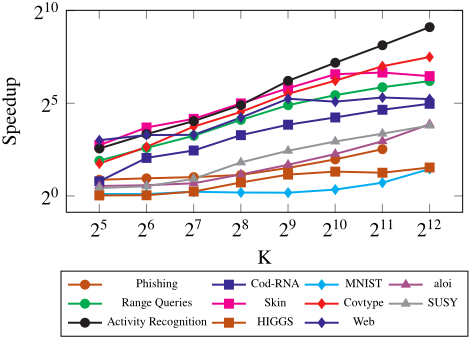
reduction in distance computations closely matches the 551� reduction in run-time. The HIGGS dataset has the lowest improvement in run-time with a 1�02� speedup at = 32 and 2.9� at = 4096. We also note that the NearestInRange query provided an additional 1�5 � 4� speedup in most cases, but was highly dependent on the dataset and value of .
6 Conclusion
Leveraging simple modifications and a novel priority queue, we show the first method that delivers equal or better run-time in theory (less distance computations) and practice (less runtime). Noneof our changes impact the functionof -means++ or -meansk, allowing us to retain existing properties.
Acknowledgements
I would like to thank Ashley Klein, Drew Farris, and Frank Ferraro for reviewing early drafts and their valuable feedback.
@inproceedings{ijcai2021p403,
  title     = {Exact Acceleration of K-Means++ and K-Means||},
  author    = {Raff, Edward},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {2928--2935},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/403},
  url       = {https://doi.org/10.24963/ijcai.2021/403},
}
TY - CPAPER TI - Exact Acceleration of K-Means++ and K-Means|| AU - Raff, Edward T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 2928 EP - 2935 DO - 10.24963/ijcai.2021/403 UR - https://doi.org/10.24963/ijcai.2021/403 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





