
Learning Deeper Non-Monotonic Networks by Softly Transferring Solution Space
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 3200-3206.
https://doi.org/10.24963/ijcai.2021/440
© 2021 International Joint Conferences on Artificial Intelligence
Keywords
- Machine Learning: Classification
- Machine Learning: Deep Learning
- Machine Learning: Kernel Methods
Abstract
Different from popular neural networks using quasiconvex activations, non-monotonic networks activated by periodic nonlinearities have emerged as a more competitive paradigm, offering revolutionary benefits: 1) compactly characterizing high-frequency patterns; 2) precisely representing high-order derivatives. Nevertheless, they are also well-known for being hard to train, due to easily over-fitting dissonant noise and only allowing for tiny architectures (shallower than 5 layers). The fundamental bottleneck is that the periodicity leads to many poor and dense local minima in solution space. The direction and norm of gradient oscillate continually during error backpropagation. Thus non-monotonic networks are prematurely stuck in these local minima, and leave out effective error feedback. To alleviate the optimization dilemma, in this paper, we propose a non-trivial soft transfer approach. It smooths their solution space close to that of monotonic ones in the beginning, and then improve their representational properties by transferring the solutions from the neural space of monotonic neurons to the Fourier space of non-monotonic neurons as the training continues. The soft transfer consists of two core components: 1) a rectified concrete gate is constructed to characterize the state of each neuron; 2) a variational Bayesian learning framework is proposed to dynamically balance the empirical risk and the intensity of transfer. We provide comprehensive empirical evidence showing that the soft transfer not only reduces the risk of non-monotonic networks on over-fitting noise, but also helps them scale to much deeper architectures (more than 100 layers) achieving the new state-of-the-art performance.
- [Bond-Taylor and Willcocks, 2020] Sam Bond-Taylor and Chris G Willcocks. Gradient origin networks. arXiv preprint arXiv:2007.02798, 2020.
- [Goodfellow et al., 2016] Ian Goodfellow, Yoshua Bengio, and Aaron Courville. Deep Learning. MIT press, 2016.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 770-778, 2016.
- [Jang et al., 2016] Eric Jang, Shixiang Gu, and Ben Poole. Categorical reparameterization with gumbel-softmax. arXiv preprint arXiv:1611.01144, 2016.
- [Kazemi et al., 2019] Seyed Mehran Kazemi, Rishab Goel, Sepehr Eghbali, Janahan Ramanan, Jaspreet Sahota, San- jay Thakur, Stella Wu, Cathal Smyth, Pascal Poupart, and Marcus Brubaker. Time2vec: Learning a vector represen- tation of time. arXiv preprint arXiv:1907.05321, 2019.
- [Krizhevsky et al., 2009] Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny im- ages. Technical report, Citeseer, 2009.
- [LeCun et al., 1998] Yann LeCun, Léon Bottou, Yoshua Bengio, Patrick Haffner, et al. Gradient-based learning ap- plied to document recognition. Proceedings of the IEEE, 86(11):2278-2324, 1998.
- [Loshchilov and Hutter, 2016] Ilya Loshchilov and Frank Hutter. Sgdr: Stochastic gradient descent with warm restarts. arXiv preprint arXiv:1608.03983, 2016.
- [Louizos et al., 2018] Christos Louizos, Max Welling, and Diederik P Kingma. Learning sparse neural networks through l0 regularization. In International Conference on Learning Representations, 2018.
- [Maddison et al., 2016] Chris J Maddison, Andriy Mnih, and Yee Whye Teh. The concrete distribution: A continuous relaxation of discrete random variables. arXiv preprint arXiv:1611.00712, 2016.
- [Mildenhall et al., 2020] Ben Mildenhall, Pratul P Srini- vasan, Matthew Tancik, Jonathan T Barron, Ravi Ra- mamoorthi, and Ren Ng. Nerf: Representing scenes as neural radiance fields for view synthesis. arXiv preprint arXiv:2003.08934, 2020.
- [Paszke et al., 2019] Adam Paszke, Sam Gross, Francisco Massa, Adam Lerer, James Bradbury, Gregory Chanan, Trevor Killeen, Zeming Lin, Natalia Gimelshein, Luca Antiga, et al. Pytorch: An imperative style, high- performance deep learning library. arXiv preprint arXiv:1912.01703, 2019.
- [Rahimi and Recht, 2008] Ali Rahimi and Benjamin Recht. Random features for large-scale kernel machines. In Ad- vances in Neural Information Processing Systems, pages 1177-1184, 2008.
- [Ramachandran et al., 2017] Prajit Ramachandran, Barret Zoph, and Quoc V Le. Searching for activation functions. arXiv preprint arXiv:1710.05941, 2017.
- [Sitzmann et al., 2020a] Vincent Sitzmann, Eric R Chan, Richard Tucker, Noah Snavely, and Gordon Wetzstein. Metasdf: Meta-learning signed distance functions. arXiv preprint arXiv:2006.09662, 2020.
- [Sitzmann et al., 2020b] Vincent Sitzmann, Julien Martel, Alexander Bergman, David Lindell, and Gordon Wet- zstein. Implicit neural representations with periodic ac- tivation functions. Advances in Neural Information Pro- cessing Systems, 33, 2020.
- [Sutskever et al., 2013] Ilya Sutskever, James Martens, George Dahl, and Geoffrey Hinton. On the importance of initialization and momentum in deep learning. In International conference on machine learning, pages 1139-1147, 2013.
- [Tancik et al., 2020] Matthew Tancik, Pratul P Srinivasan, Ben Mildenhall, Sara Fridovich-Keil, Nithin Raghavan, Utkarsh Singhal, Ravi Ramamoorthi, Jonathan T Barron, and Ren Ng. Fourier features let networks learn high frequency functions in low dimensional domains. arXiv preprint arXiv:2006.10739, 2020.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in neural information processing sys- tems, pages 5998-6008, 2017.
- [Xu et al., 2019] Da Xu, Chuanwei Ruan, Evren Korpeoglu, Sushant Kumar, and Kannan Achan. Self-attention with functional time representation learning. In Advances in Neural Information Processing Systems, pages 15915- 15925, 2019.
- [Xue and Wu, 2020] Hui Xue and Zheng-Fan Wu. Baker- nets: Bayesian random kernel mapping networks. In Proceedings of the Twenty-Ninth International Joint Con- ference on Artificial Intelligence, IJCAI-20, pages 3073- 3079. International Joint Conferences on Artificial Intelli- gence Organization, 7 2020.
- [Xue et al., 2019] Hui Xue, Zheng-Fan Wu, and Wei-Xiang Sun. Deep spectral kernel learning. In Proceedings of the Twenty-Eighth International Joint Conference on Ar- tificial Intelligence, IJCAI-19, pages 4019-4025. Interna- tional Joint Conferences on Artificial Intelligence Organi- zation, 7 2019. IJCAI
- [Zhong et al., 2019] Ellen D Zhong, Tristan Bepler, Joseph H Davis, and Bonnie Berger. Reconstructing continuous distributions of 3d protein structure from cryo-em images. In International Conference on Learning Representations, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Deep neural networks have led to a series of breakthroughs. Their representational properties depend heavily on the activation functions. Most activation functions typically used nowadays, e.g., Sigmoid and ReLU, are quasiconvex, mimicking the activation/inhibition of the Heaviside function.
∗Contact Author
Monotonic neuron only responding to a particular pattern makes sense from an intuitive point of view: 1) it is attracted to noticeable/generalizable/low-frequency features; 2) this monotonicity prevents complex coupling and co-adaptations between feature detectors; 3) more importantly, monotonic nonlinearity substantially smoothes the variations of gradient. In general, the solution spaces ofmonotonic networks are much plainer than that of non-monotonic counterparts. This plays a major role in the success of training deep networks with hundreds of millions of parameters.
In contrary to popular monotonic ones, non-monotonic neurons are regarded as difficult to train, owing to 1) easily over-fitting and 2) only compatible with tiny networks (shallower than 5 layers). But in the last two years, we have to seriously reexamine the importance of non-monotonic activations. Many researches showed that non-monotonic activations can achieve irreplaceable effects including 1) compactly characterizing complex high-frequency patterns; 2) precisely representing implicit high-order derivatives.
Specifically, Tancik et al. [2020] formally demonstrated that sinusoidal Fourier mappings can dramatically perform better by allowing them to learn much higher frequencies across low-dimensional space. Sitzmann et al.; Bond-Taylor and Willcocks; Sitzmann et al. [2020b; 2020; 2020a] comprehensively proved the great power of sinusoidal units in modelling complex signals with fine detail and implicit derivatives. Xue et al.; Xue and Wu [2019; 2020] used the sinusoidal function to reveal dynamic characteristics and potential correlations. Mildenhall et al.; Zhong et al. [2020; 2019] improved the state-of-the-art performance on the tasks of novel view synthesis by using sinusoids in Fourier space.
However, these non-monotonic networks built on sinusoidal nonlinearities are paired with manually initialization and tiny architectures (shallower than 5 layers). Although the important properties of non-monotonic networks are recognized, their intractable optimization dilemma left over by history has not yet been solved.
On the one hand, they are more inclined to over-fit noise hidden in signals. Their periodic neurons can be activated across the whole feature space. As the correlation with the input increases, the activation will oscillate between stronger and weaker, and thus is more attracted to dissonant noise. On the other hand, they can hardly work well in more complex architectures. Non-monotonic neuron responds to multiple patterns, and easily couples and co-adapts with each other. The direction and norm of gradient oscillate continually in a local range during error backpropagation. Therefore, it is a great challenge to optimize deep non-monotonic networks.
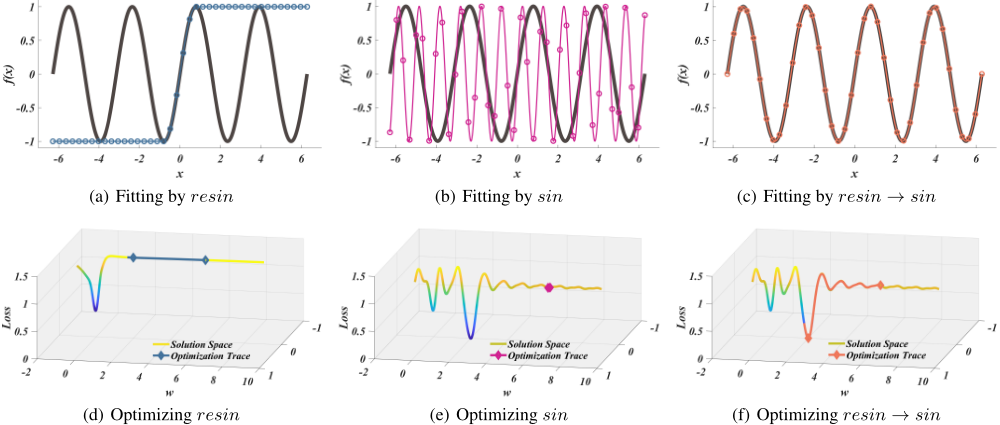
Actually, even a network with only one single sinusoidal neuron has infinite VC dimension. The periodicity gives rise to numerous poor and dense local minima in solution space. Non-monotonic networks may be prematurely stuck in poor local minima, and leave out more effective error feedback. Hence, we pay particular attention to smoothing their solution space by taking monotonic variants as the helper, so as to help non-monotonic networks learn low/high-frequency concepts better and scale them to substantially deeper and wider senior architectures.
As a first step toward understanding this optimization dilemma intuitively, we conduct a synthetic experiment on fitting the scalar sin(2x), x ∈ [-2π, 2π] with three networks defined in Eq. (1): 1) the monotonically-rectified sinusoidal network ¯σ := resin; 2) the non-monotonic ˜σ := sin; 3) the non-monotonic σz := resin → sin softly transferring the solution from resin to sin. They have only one neuron paired with a scalar weight w initialized at w = 6. The fitting results and optimization processes are shown in Figure 1.
Firstly, the solution space of resin is much smoother than that of sin. But resin can only capture the local features on x ∈ [- π4 , π4 ]. Even if it is optimized to the global optimum w = 0, resin just outputs 0 constantly owing to the structural limitation. Secondly, in contrast, the solution space of the non-monotonic sin has more poor and dense local minima. sin is prematurely stuck in the terrible solution and fits the wrong frequency. Thirdly, resin → sin finds the optimal solution w = 2 and perfectly reconstructs the original function. Consequently, by accurately transferring the solution from monotonic network to the associated non-monotonic network, we can alleviate the optimization difficulty on the premise of preserving the structural superiority.
In this paper, we propose a non-trivial soft transfer approach, bridging the gap between the neural solution space of monotonic networks and the Fourier solution space of nonmonotonic networks. The novel transfer alleviates the optimization dilemma by smoothing their solution space close to that of monotonic counterparts in the early stage of training, and then improves their representational properties by transferring the solutions from the monotonic nonlinearities to the non-monotonic ones as the training continues. Specifically, the soft transfer is implemented by two core components:
- To automatically characterize the monotonicity/nonmonotonicity of each neuron, a parametric gate with the rectified concrete distribution is constructed.
- To dynamically balance the empirical risk and the intensity of transfer, a more efficient learning framework based on variational Bayesian inference is proposed.
By taking the soft transfer approach, non-monotonic networks are as easy to optimize as their monotonic counterparts. Moreover, we provide comprehensive empirical evidence showing that:
- Soft transfer reduces the risk of over-fitting noise. Lowfrequency concepts are chiefly learned by monotonic parts, and then high-frequency details and high-order derivatives are represented by non-monotonic parts.
- Soft transfer helps non-monotonic networks scale to deeper and wider architectures. The solution space changes smoothly from simple to complex in training, without sacrificing any representational property.
We perform various experiments to demonstrate the effectiveness of the soft transfer. Based on the proposed approach, non-monotonic networks are successfully extended to the senior residual learning architectures deeper than 100 layers, and achieve the new state-of-the-art performance.
2 RelatedWork
On the one hand, Tancik et al. [2020] comprehensively showed that standard neural networks are poorly suited for learning high-frequency content, a phenomenon referred to spectral bias caused by a rapid frequency falloff. Sitzmann et al.; Bond-Taylor and Willcocks; Sitzmann et al. [2020b; 2020; 2020a] proved that monotonic activations are incapable of modeling information contained in higher-order derivatives of natural signals.
On the other hand, more important properties of nonmonotonic networks have been recognized. Prior works in natural language processing and time series analysis have used sinusoidal functions as positional encoding [Vaswani et al., 2017; Xu et al., 2019; Kazemi et al., 2019]. Xue et al.; Xue and Wu [2019; 2020; 2017] pointed out that periodic nonlinearities have the potential to reveal inputdependent and long-range characteristics. Coordinate-based neural networks paired with sinusoidal activations achieved the new state-of-the-art performance on novel view synthesis [Mildenhall et al., 2020; Zhong et al., 2019].
But as yet, an available approach solving their optimization dilemma left over by history is still missing.
3 Softly Transferring Solution Space
This section contains three main parts: 1) a na¨ıve but intractable recipe; 2) a variational Bayesian learning framework; 3) a rectified concrete gate. In the end, some distinctive properties of this soft transfer scheme are analyzed.
Above all, we make an innocuous stipulation that nonmonotonic networks are composed of periodic neurons activated by sinusoidal functions. But it should be emphasized that the soft transfer approach is naturally compatible with other variants without modification.
3.1 Non-Monotonicity Gated Unit
A non-monotonicity gated unit is defined to characterize the monotonicity/non-monotonicity of each neuron. Consider the general activation that can be either monotonic or not.
˜σ(·) is a non-monotonic activation and ¯σ(·) is its monotonic variant. Without loss of generality, we mainly consider the widely-used sinusoidal function ˜σ(x) = sin(x) and its monotonically-rectified variant ¯σ(x) = resin(x), with respect to an input x, where resin(x) is defined by
Whether σz(·) is monotonic or periodic is controlled by the discrete value of the binary gate z.
By initializing all gates z in a network to 1 and penalizing those gates z for being different than exact 0 as the training continues, we can mimic the behavior of transferring the solution space from a monotonic neural network to a nonmonotonic Fourier network. The transfer has three meanings: 1) the nonlinearity is switched frommonotonic to periodic; 2) the representational property is changed from low-frequency to high-frequency; 3) the solution space is transformed from smooth/neural to bumpy/Fourier.
Controlling the proportion of different kinds of neurons properly, we can ease the complexity of the solution space in the beginning and improve the representational properties as the training continues. But the practical optimization under this transfer is computationally intractable due to the nondifferentiability and the combinatorial nature of 2|σz| possible states, where |σz| is the total number of activations.
3.2 Differentiable Soft Transfer Framework
For this reason, we propose a more efficient differentiable learning framework for softly transferring solution space, utilizing variational Bayesian inference as its theoretical basis.
Given some observed data D, a group of random variables z gating monotonicity/non-monotonicity, and a collection of activations σz regarded as random variables reparameterized by z. According to Bayesian inference, a general learning problem can be formalized by a log-probability log P(D).
q is the introduced approximate posterior over σz and z. Moreover, because log P(D) is a constant if D is given, maximizing the Evidence Lower BOund (ELBO) L(D,σz, z) is equivalent to minimizing the Kullback-Leibler divergence (KL-divergence) KL(q(σz, z)‖P(σz, z|D)). Generally, we consider minimizing the negative ELBO -L(D, σz, z).
Furthermore, suppose p is a spike and slab prior over σz and z, which is the widely-used golden standard in selecting variables as far as Bayesian inference is concerned. It is defined as a mixture of a delta spike at zero and a continuous distribution over the real line.
Since the true posterior distribution under this prior is intractable, we let q(σz, z) be a spike and slab approximate posterior over σz and z. The negative ELBO -L(D, σz, z) under the spike and slab prior and approximate posterior over σz and z can be rewrited as
We assume that the non-monotonicity gated units are independent of each other. That is, p and q factorize over the dimensionality of σz and z in an element-wise way. Furthermore, according to the chain rule of KL-divergence, we have
Since
where γ is a weighting factor for explicitly penalizing monotonic neurons for being different than non-monotonic ones, -L(D, σz, z) can be further represented as
As long as we apply a differentiable approximate posterior q(z|φ) allowing for the reparameterization trick z = f(φ, ϵ) over the parameters φ and a parameter free noise distribution τ(ϵ), we can reformulate the optimization objective -L(D, σz, z) and solve it by Monte Carlo approximation.
Crucially, the learning objective is now differentiable with respect to the parameters φ, thus enabling for efficient stochastic gradient based optimization. The parameters of the distribution over the gates can then be jointly optimized with the original network parameters.
3.3 Parametric Gate with Concrete Distribution
Based on the differentiable learning framework, we further refine the parametric gate by utilizing a continuously differentiable distribution allowing for the reparameterization trick. Assume that we have a binary concrete random variable v distributed in the (0, 1) interval with probability density function qv(v|φ) and cumulative distribution function Qv(v|φ). The parameters of the distribution are φ = (α, β), where log α is the location and 0 < β < 1 is the temperature, controlling the degree of approximate Bernoulli distribution. We have
where ϵ ∼ U(0, 1). We can calculate qv(v|φ) and Qv(v|φ) analytically.
Here, we stretch the binary concrete distribution to the (ξ, ζ) interval, with ξ ≤ 0 and ζ ≥ 1, and rectify it in [0, 1] by applying a min-max transformation.
This would then induce a distribution where the probability mass of q˘ v (˘ v|φ) on the negative values Q˘ v(0|φ), is folded to a delta peak at zero, the probability mass on values larger than one, 1-Q˘ v(1|φ) is folded to a delta peak at one, and the original distribution q˘ v (˘ v|φ) is truncated to the (0, 1) interval. More details are referred to the concrete distribution [Maddison et al., 2016; Louizos et al., 2018].
Furthermore, considering q(z ̸= 0|φ) = 1 -Q˘ v (˘ v ≤ 0|φ), we define the general optimization objective by minimizing the total risk R(D).
where
In training, z can be sampled efficiently.
In prediction, we apply the following estimator.
The total risk R(D) is a special case of the negative ELBO -L(D, σz, z) by setting the sampling number K = 1. The reason for optimizing R(D) is that we focus on optimizing large-scale networks efficiently instead of reducing the uncertainty of z. As the training continues, these random variables z will be penalized close to zero.
3.4 Analysis
Following the above theoretical inference, the application of soft transfer scheme is quite flexible. The general optimization objective R(D) can be reformulated as 1) the empirical risk -logP(D|σz) and 2) the structural risk ∑|σz| i=1 [1 - Q˘ vi (0|φi)]. The former empirical risk is calculated by a conventional loss function characterizing how well the model fits the observed data. What we need to do is add the latter structural risk to the loss as an additional regularizer, and replace the activation with the non-monotonicity gated unit σz parameterized by φ. φ can be shared by different neurons depending on the transfer granularity. Even in the most finegrained case, the total number of φ does not exceed the sum of the output dimensions in all neurons, which is far less than that of the original network parameters.
In addition to smoothing the solution space to ease the optimization difficulty, soft transfer actually has some other important advantages. Firstly, it is essentially a regularizer that balances the degree of learning observed data and the proportion of non-monotonicity. Secondly, it enables the proper uncertainty for the networks and then encourages the optimizer to explore more potential solutions in a space 2|σz| larger than the original. Thirdly, it prevents complex coupling and co-adaptations between feature detectors by switching the monotonic/non-monotonic state of each neuron.
4 Experiments
4.1 Experimental Networks
- sin: Sinusoidal activation as the most important baseline.
- resin: Monotonically-rectified sinusoidal activation.
- tanh: Tanh activation that is the smooth approximation of the discontinuous resin.
- relu: Hugely popular ReLU activation.
- Copy: Directly copying the parameters from resin trained in the first half of epoches to sin, and then continue to train sin in the second half of epoches.
- Line: Linearly penalizing the z from 1 to 0.
- Bern: z is subject to a Bernoulli distribution.
- resin → sin: Soft transfer from resin to sin.
- tanh → sin: Soft transfer from tanh to sin.
- relu → sin: Soft transfer from relu to sin.
4.2 Experimental Settings
The weights and biases of sin are respectively initialized by N(0, 0.1) and U(-π, π) in accordance with the explanation in [Rahimi and Recht, 2008; Xue et al., 2019]. Other networks are initialized according to the Kaiming method [He et al., 2016]. They are all optimized by SGD with a minibatch size of 128, a weight decay of 10-4 , and a Nesterov momentum of 0.9 [Paszke et al., 2019; Sutskever et al., 2013; Goodfellow et al., 2016]. The learning rate is initially set to 0.1, and then it is adjusted by a cosine annealing schedule with warm restarts [Loshchilov and Hutter, 2016]. For all soft transfer related networks, we set β = 2 3 , ξ = -0.1, and ζ = 1.1 following the recommendations [Maddison et al., 2016; Jang et al., 2016]. α is initialized by sampling from N(8, 1).
4.3 Learning the Bessel Function
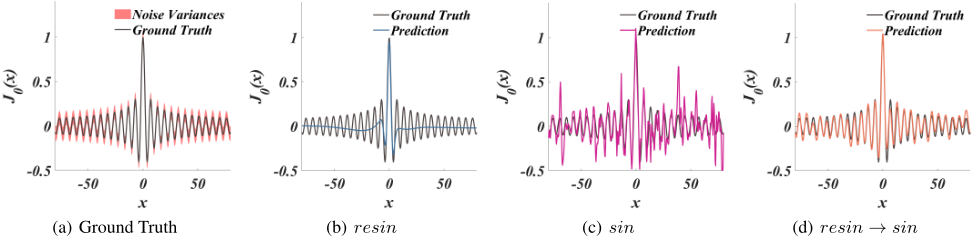
To evaluate that the proposed soft transfer can reduce the risk of over-fitting high-frequency noise, we conduct an experiment to learn the first kind of 0-order Bessel function J0(x), x ∈ [-80, 80], which contains a lot of implicit highfrequency features and high-order derivatives. We uniformly get 400 samples {(xi, J0(xi))}400 i=1 , and randomly divide them into two non-overlapping training and test sets that are equal in size. The extra white Gaussian noise N(0, 0.082 ) is added to the training labels for simulating the interference in practical tasks. resin, sin, and resin → sin are used to fit J0(x). They have the same fully-connected 400×400×400 architecture. The results are shown in Figure 2.
Owing to the structural limitation, The insensitive resin makes a very conservative decision and outputs the average value in the high-frequency range. But the periodic sin is over-sensitive to learn the white noise added to each sample. This is a possible reason why non-monotonic networks are inclined to make over-confident but inaccurate decisions in practical tasks. In contrast, resin → sin with the soft transfer scheme achieves the best fitting result. The low-frequency concepts are chiefly guaranteed to be learned well by the initial monotonic parts, and then high-frequency details and high-order derivatives are further extracted by the transferred non-monotonic neurons. resin → sin not only accurately captures the key information such as frequency and phase, but also resists the noisy interference.
4.4 Learning Image Classification
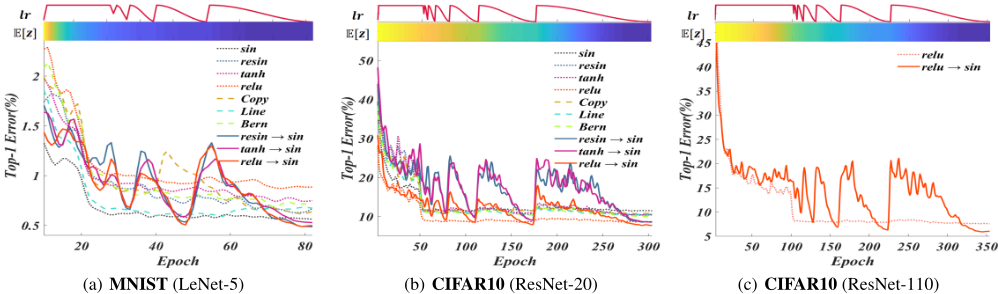
We conduct image experiments to learn MNIST [LeCun et al., 1998] and CIFAR10 [Krizhevsky et al., 2009] by the shallower LeNet-5 architecture [LeCun et al., 1998] and the deeper ResNet-20/110 architectures, respectively. The division of datasets is consistent with their default settings. The results are presented in Table 1 and Figure 3.
Shallower LeNet-5 Architecture
On this simple task paired with the shallow LeNet-5 architecture, all networks associated with sin perform better than monotonic ones. The sinusoidal neuron compactly represents implicit details. In general, the non-monotonic networks built on the soft transfer (resin → sin, tanh → sin, and relu → sin) achieve the most competitive performance 0.47%, owing to the preferable balance between the empirical risk and the proportion of non-monotonicity.
| Top-1 Error | MNIST (LeNet-5) | CIFAR10 (ResNet-20) | CIFAR10 (ResNet-110) | |||
|---|---|---|---|---|---|---|
| (%) | conv | best | conv | best | conv | best |
| sin | 0.56 | 0.53 | 11.39 | 11.25 | - | - |
| resin | 0.73 | 0.60 | 10.41 | 10.30 | - | - |
| tanh | 0.76 | 0.72 | 10.48 | 10.33 | - | - |
| relu | 0.89 | 0.86 | 8.63 | 8.47 | 7.55 | 7.49 |
| Copy | 0.66 | 0.61 | 10.94 | 10.66 | - | - |
| Line | 0.66 | 0.55 | 10.59 | 10.41 | - | - |
| Bern | 0.70 | 0.66 | 10.10 | 9.85 | - | - |
| resin→ sin | 0.48 | 0.48 | 8.53 | 8.50 | - | - |
| tanh → sin | 0.52 | 0.49 | 8.67 | 8.54 | - | - |
| relu → sin | 0.50 | 0.47 | 7.94 | 7.55 | 5.99 | 5.84 |
Deeper ResNet-20/110 Architectures
First, it is completely opposite to the results presented in the MNIST classification that these networks associated with sin but not built on the soft transfer approach perform worst. Once the network architecture becomes a little bit complex, sin can not make its excellent theoretical properties yield well as we expected. The three na¨ıve transfer scheme (Copy, Line, and Bern) do not work at all. In contrast, the soft transfer based networks fully realize the great power of sin through cautiously transferring the solution from the monotonic nonlinearity to the sinusoidal nonlinearity. relu → sin successfully achieve the best top-1 error 7.55% that is also competitive compared with the record 7.51% of the deeper ResNet-32 in the publication [He et al., 2016].
Second, interestingly, it may not be a tough requirement for softly transferring that the source neuron and the target neuron have some similar mapping structures. According to the performance of relu → sin, the knowledge is successfully transferred from the neural space of the piecewise linear relu to the Fourier space of the periodic sin, which implies that the soft transfer is a very general and flexible framework and has more potential to be developed.
Last, based on the soft transfer approach and the monotonic ReLU helper, we successfully train the non-monotonic network relu → sin in the ResNet-110 architecture. The best top-1 error 7.49% of relu is slightly higher than that of the official record 6.61%. But relu → sin still achieve the best performance 5.84%. Paired with the non-trivial soft transfer, the superiority of the non-monotonic sin in representation are well coordinated with the advantages of the monotonic relu in gradient propagation. Other networks failed to train under this giant architecture due to the well-known gradient vanishing/explosion, and sin behaves as poorly as random guessing.
5 Conclusion
Despite the increasing emergence of non-monotonic networks, an available approach solving their optimization dilemma is still missing. In this paper, we propose a novel soft transfer approach consisting of two core components: 1) a rectified concrete gate is constructed to characterize the state of each neuron; 2) a variational Bayesian learning framework is proposed to dynamically balance the empirical risk and the degree of transfer. Consequently, it can help non-monotonic networks learn low/high-frequency concepts better and scale them to substantially deeper and wider senior architectures. Systematical experiments demonstrate the effectiveness of the proposed soft transfer approach.
Acknowledgments
This work was supported by National Natural Science Foundation of China (Grant No.62076062) and National Key R&D Program of China (Grant No.2017YFB1002801). Furthermore, the work was also supported by Collaborative Innovation Center of Wireless Communications Technology.
@inproceedings{ijcai2021p440,
  title     = {Learning Deeper Non-Monotonic Networks by Softly Transferring Solution Space},
  author    = {Wu, Zheng-Fan and Xue, Hui and Bai, Weimin},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {3200--3206},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/440},
  url       = {https://doi.org/10.24963/ijcai.2021/440},
}
TY - CPAPER TI - Learning Deeper Non-Monotonic Networks by Softly Transferring Solution Space AU - Wu, Zheng-Fan AU - Xue, Hui AU - Bai, Weimin T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 3200 EP - 3206 DO - 10.24963/ijcai.2021/440 UR - https://doi.org/10.24963/ijcai.2021/440 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





