
Improving Transferability of Adversarial Examples with Virtual Step and Auxiliary Gradients
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 1629-1635.
https://doi.org/10.24963/ijcai.2022/227
Keywords
- Machine Learning: Adversarial Machine Learning
- Machine Learning: Convolutional Networks
- Computer Vision: Adversarial learning, adversarial attack and defense methods
Abstract
Deep neural networks have been demonstrated to be vulnerable to adversarial examples, which fool networks by adding human-imperceptible perturbations to benign examples. At present, the practical transfer-based black-box attacks are attracting significant attention. However, most existing transfer-based attacks achieve only relatively limited success rates. We propose to improve the transferability of adversarial examples through the use of a virtual step and auxiliary gradients. Here, the “virtual step” refers to using an unusual step size and clipping adversarial perturbations only in the last iteration, while the “auxiliary gradients” refer to using not only gradients corresponding to the ground-truth label (for untargeted attacks), but also gradients corresponding to some other labels to generate adversarial perturbations. Our proposed virtual step and auxiliary gradients can be easily integrated into existing gradient-based attacks. Extensive experiments on ImageNet show that the adversarial examples crafted by our method can effectively transfer to different networks. For single-model attacks, our method outperforms the state-of-the-art baselines, improving the success rates by a large margin of 12%~28%. Our code is publicly available at https://github.com/mingcheung/Virtual-Step-and-Auxiliary-Gradients.
- [Akhtar and Mian, 2018] Naveed Akhtar and Ajmal Mian. Threat of Adversarial Attacks on Deep Learning in Com- puter Vision: A Survey. IEEE Access, 2018.
- [Akhtar et al., 2021] Naveed Akhtar, Ajmal Mian, Navid Kardan, and Mubarak Shah. Advances in Adversarial At- tacks and Defenses in Computer Vision: A Survey. IEEE Access, 2021.
- [Biggio et al., 2013] Battista Biggio, Igino Corona, Davide Maiorca, Blaine Nelson, Nedim Srndic, Pavel Laskov, Giorgio Giacinto, and Fabio Roli. Evasion Attacks against Machine Learning at Test Time. In Proc. of ECML, 2013.
- [Brendel et al., 2018] Wieland Brendel, Jonas Rauber, and Matthias Bethge. Decision-Based Adversarial Attacks: Reliable Attacks Against Black-Box Machine Learning Models. In Proc. of ICLR, 2018.
- [Chen et al., 2020] Jianbo Chen, Michael I. Jordan, and Martin J. Wainwright. HopSkipJumpAttack: A Query- Efficient Decision-Based Attack. In Proc. of SP, 2020.
- [Chollet, 2017] Franc ¸ois Chollet. Xception: Deep Learn- ing with Depthwise Separable Convolutions. In Proc. of CVPR, 2017.
- [Dalvi et al., 2004] Nilesh Dalvi, Pedro Domingos, Mausam, Sumit Sanghai, and Deepak Verma. Ad- versarial classification. In Proc. of KDD, 2004.
- [Dong et al., 2018] Yinpeng Dong, Fangzhou Liao, Tianyu Pang, Hang Su, Jun Zhu, Xiaolin Hu, and Jianguo Li. Boosting Adversarial Attacks with Momentum. In Proc. of CVPR, 2018.
- [Dong et al., 2019] Yinpeng Dong, Tianyu Pang, Hang Su, and Jun Zhu. Evading Defenses to Transferable Adversar- ial Examples by Translation-Invariant Attacks. In Proc. of CVPR, 2019.
- [Goodfellow et al., 2015] Ian J. Goodfellow, Jonathon Shlens, and Christian Szegedy. Explaining and Harness- ing Adversarial Examples. In Proc. of ICLR, 2015.
- [Guo et al., 2018] Chuan Guo, Mayank Rana, Moustapha Cisse, and Laurens van der Maaten. Countering Adversar- ial Images using Input Transformations. In Proc. of ICLR, 2018.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Identity Mappings in Deep Residual Networks. In Proc. of ECCV, 2016.
- [Kurakin et al., 2017] Alexey Kurakin, Ian Goodfellow, and Samy Bengio. Adversarial examples in the physical world. In Proc. of ICLR, 2017.
- [Li et al., 2020] Yingwei Li, Song Bai, Yuyin Zhou, Cihang Xie, Zhishuai Zhang, and Alan Yuille. Learning Transfer- able Adversarial Examples via Ghost Networks. In Proc. of AAAI, 2020.
- [Liao et al., 2018] Fangzhou Liao, Ming Liang, Yinpeng Dong, Tianyu Pang, Xiaolin Hu, and Jun Zhu. Defense Against Adversarial Attacks Using High-Level Represen- tation Guided Denoiser. In Proc. of CVPR, 2018.
- [Liu et al., 2019] Yujia Liu, Seyed-Mohsen Moosavi- Dezfooli, and Pascal Frossard. A geometry-inspired decision-based attack. In Proc. of ICCV, 2019.
- [Madry et al., 2018] Aleksander Madry, Aleksandar Makelov, Ludwig Schmidt, Dimitris Tsipras, and Adrian Vladu. Towards Deep Learning Models Resistant to Adversarial Attacks. In Proc. of ICLR, 2018.
- [Szegedy et al., 2014] Christian Szegedy, Wojciech Zaremba, Ilya Sutskever, Joan Bruna, Dumitru Erhan, Ian Goodfellow, and Rob Fergus. Intriguing properties of neural networks. In Proc. of ICLR, 2014.
- [Szegedy et al., 2016] Christian Szegedy, Vincent Van- houcke, Sergey Ioffe, Jonathon Shlens, and Zbigniew Wojna. Rethinking the Inception Architecture for Computer Vision. In Proc. of CVPR, 2016.
- [Szegedy et al., 2017] Christian Szegedy, Sergey Ioffe, Vin- cent Vanhoucke, and Alex Alemi. Inception-v4, Inception- ResNet and the Impact of Residual Connections on Learn- ing. In Proc. of AAAI, 2017.
- [Tramer et al., 2018] Florian Tramer, Alexey Kurakin, Nico- las Papernot, Ian Goodfellow, Dan Boneh, and Patrick Mc- Daniel. Ensemble Adversarial Training: Attacks and De- fenses. In Proc. of ICLR, 2018.
- [Xie et al., 2018] Cihang Xie, Jianyu Wang, Zhishuai Zhang, Zhou Ren, and Alan Yuille. Mitigating Adversarial Effects Through Randomization. In Proc. of ICLR, 2018.
- [Xie et al., 2019a] Cihang Xie, Yuxin Wu, Laurens van der Maaten, Alan Yuille, and Kaiming He. Feature Denoising for Improving Adversarial Robustness. In Proc. of CVPR, 2019.
- [Xie et al., 2019b] Cihang Xie, Zhishuai Zhang, Yuyin Zhou, Song Bai, Jianyu Wang, Zhou Ren, and Alan L. Yuille. Improving Transferability of Adversarial Exam- ples With Input Diversity. In Proc. of CVPR, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The security of machine learning has attracted much attention for many years. For example, [Dalvi et al., 2004] first proposed the concept of adversarial classification, while [Biggio et al., 2013] presented evasion attacks against machine learning models. Subsequently, [Szegedy et al., 2014] were the first to formally propose the concept of adversarial examples faced by deep neural networks in computer vision, which triggered a widespread research interest in adversarial attacks.
Various forms of adversarial attack have been proposed in an attempt to craft adversarial examples in the field of computer vision [Akhtar and Mian, 2018; Akhtar et al., 2021].
∗Corresponding author.
Theses attacks can be broadly divided into two categories: white-box attacks and black-box attacks. White-box attacks assume complete knowledge of the target model, including its architecture, parameters, etc. White-box attacks are predominately gradient-based; examples include FGSM [Goodfellow et al., 2015], I-FGSM [Kurakin et al., 2017] and MIFGSM [Dong et al., 2018]. Since attackers can fully exploit model information such as gradients under white-box settings, white-box attacks can achieve high success rates and low human perceptibility. Currently, great strides have been made in research into white-box attacks. Black-box attacks, which are more practical, have attracted increasing research attention in recent years.
Except for inputs and outputs, black-box attacks assume no knowledge of the target model, making them more challenging and more practical. Currently, black-box attacks are being developed along two main directions: query-based attacks and transfer-based attacks. Query-based attacks query the target model and use its outputs to craft adversarial examples. Since too many queries being sent to the target model can arouse suspicion, the core research topic related to querybased attacks is to improve query efficiency. Transfer-based attacks craft adversarial examples on local substitute models and fool the target model by using the cross-model transferability of adversarial examples. The core research topic of transfer-based attacks centers around improving the transferability of adversarial examples.
In this work, we propose to improve the transferability of adversarial examples through the use of a virtual step and auxiliary gradients, which can be easily integrated into existing gradient-based attack methods to yield more powerful attacks. On the one hand, we use an usual step size ("virtual step") and clip adversarial perturbations only in the last iteration; on the other hand, unlike the traditional methods which use only gradients corresponding to the ground-truth label (for untargeted attacks), we use not only gradients corresponding to the ground-truth label ("main gradients"), but also gradients corresponding to some other labels ("auxiliary gradients") to generate adversarial examples. To our best knowledge, we are the first to verify the synergistic effect of using main gradients and auxiliary gradients simultaneously.
We evaluate the performance of the proposed method on both normally trained models and defense models under single-model attacks and ensemble-based attacks. The results on ImageNet show that our method significantly outperforms the state-of-the-art baselines. For example, under single-model attacks, our method improves the attack success rates by a large margin of 12% ∼ 28%. We hope that our proposed attack strategy will shed light on new types of adversarial attacks and serve as a benchmark for evaluating the robustness of neural networks. This paper makes the following contributions:
- We propose the concepts of "virtual step" and "auxiliary gradients", which can be integrated into existing gradient-based methods to craft more transferable adversarial examples.
- We demonstrate that in addition to the main gradients, the auxiliary gradients can also make an contribution to generate adversarial examples.
- We systematically evaluate the performance of our proposed method, and show that the proposed method significantly outperforms the state-of-the-art baselines.
2 RelatedWork
Adversarial attacks. [Szegedy et al., 2014] were the first to demonstrate that deep neural networks have counterintuitive properties, and accordingly proposed a boxconstrained L-BFGS method for finding adversarial examples. [Goodfellow et al., 2015] proposed the fast gradient sign method (FGSM) to efficiently craft adversarial examples. [Kurakin et al., 2017] extended FGSM to an iterative version, whilte [Madry et al., 2018] proposed the projected gradient descent method, in which the ℓ∞-norm of the perturbations is bounded by the clipping operation-the projection. The above are known as white-box attacks. In terms of blackbox attacks, Boundary attack [Brendel et al., 2018], qFool attack [Liu et al., 2019] and HopSkipJump attack [Chen et al., 2020] explore the decision boundary to launch query-based attacks. [Xie et al., 2019b] proposed to improve the transferability of adversarial examples by creating diverse input patterns. [Dong et al., 2019] developed a translation-invariant attack capable of generating more transferable adversarial examples against the defense models. [Li et al., 2020] proposed the ghost networks, which can be used to efficiently construct substitute models in transfer-based attacks.
Adversarial defenses. While demonstrating the existence of adversarial examples in deep neural networks, [Szegedy et al., 2014] also identified a potential direction for defending against adversarial examples-adversarial training. Adversarial training [Madry et al., 2018; Tramer et al., 2018] defends against adversarial perturbations by injecting adversarial examples into the training data. At present, adversarial training is hampered by low efficiency and can obtain only limited robustness. [Guo et al., 2018] and [Xie et al., 2018] proposed to use input transformations to mitigate adversarial effects. [Liao et al., 2018] introduced a high-level representation guided denoiser (HGD) defense method. [Xie et al., 2019a] proposed to improve adversarial robustness by performing feature denoising, which is recommended to be used in combination with adversarial training.
3 Methodology
Let x denote a benign example, while ytrue denotes the corresponding ground-truth label. Given a classifier f, we apply an imperceptible perturbation to x to craft an adversarial example xadv that is capable of fooling the classifier, i.e., f(xadv ) ̸= ytrue (for untargeted attacks). In most cases, the Lp-norm is used to bound adversarial perturbations in order to achieve imperceptibility, i.e., ‖xadv -x‖p ≤ ϵ. If the loss function of the classifier is denoted as J, the process for crafting adversarial examples is usually derived by maximizing the loss function J(xadv , ytrue ), which can be formally expressed as follows:
For white-box attacks, the above optimization problem can be solved by calculating the gradients of the loss function with respect to the input. For transfer-based black-box attacks, we can employ a substitute white-box model to craft adversarial examples, which are then expected to be misclassified by the target black-box model due to the transferability of adversarial examples.
3.1 Family of Gradient-based Adversarial Attacks
[Goodfellow et al., 2015] proposed a one-step gradient-based method, known as the fast gradient sign method (FGSM), for efficiently crafting adversarial examples. Subsequently, several variants of FGSM were proposed. In this section, we briefly introduce three typical variants.
Iterative Fast Gradient Sign Method (I-FGSM). [Kurakin et al., 2017] extended FGSM to an iterative version, which can be expressed as follows:
where xadv 0 = x, while xadv i denotes the perturbed example at the i-th iteration; Clipx,ϵ{·} indicates that the perturbed example is clipped within the ϵ-ball of the original example x; α is the step size at each iteration (normally, α = ϵ/T, where T is the total number of iterations.).
Diverse Inputs Iterative Fast Gradient Sign Method (DI 2 - FGSM). [Xie et al., 2019b] proposed a variant of FGSM designed to improve the transferability of adversarial examples by creating diverse input patterns, which can be expressed as follows:
where T (xadv t ; p) denotes the application of a random transformation to the input xadv t with a probability p. The transformation includes random resizing and padding.
Translation-Invariant Iterative Fast Gradient Sign Method (TI 2 -FGSM). [Dong et al., 2019] proposed a translation-invariant method dedicated to crafting more transferable adversarial examples to combat the defense models. The method is finally implemented by convolving the gradient at the untranslated example with a pre-defined kernel, which can be expressed as follows:
xadv t+1 = Clipx,ϵ{xadv t +α·sign(W ∗∇xJ(xadv t , ytrue ))} (4) where W denotes a pre-defined kernel, which can be uniform, linear or Gaussian.
3.2 Motivation
The traditional iterative attacks, e.g., I-FGSM, greedily perturb the examples in the gradient direction of loss function, thus easily falling into the poor local maximum [Xie et al., 2019b]. We experimentally determine that the untargeted IFGSM attack is almost identical to the most-likely-class targeted I-FGSM attack; in other words, an untargeted adversarial example generated by I-FGSM is usually misclassified to the neighboring class of the original ground-truth class.
We divide the examples involved in iterative attacks into three categories: 1) the original benign example x, namely xadv 0 ; 2) the intermediate perturbed examples xinter , namely xadv i , where i ∈ [1, T -1], and T is the number of iterations; 3) the final adversarial example xadv , namely xadv T . In order to generate more transferable adversarial examples, we put forward the following two hypotheses 1 .
Hypothesis 1. If the final adversarial example xadv is misclassified to a class that is far away from the ground-truth class on the substitute model, it is more likely to be misclassified by the target model.
The intuition behind this hypothesis is that the farther the class of the adversarial example is from that of the benign example, the lower the similarity between the two examples; therefore, the adversarial example is more likely to be misclassified by the target model.
Hypothesis 2. If the intermediate perturbed examples xinter are misclassified to different classes on the substitute model, the final adversarial example xadv is more likely to be misclassified by the target model.
Let c(x′ ) denote the classified class of x′ on the substitute model. We think {c(x), c(xinter ), c(xadv )} are all potential classified classes of xadv on the target model. Therefore, the probability the final adversarial example being misclassified on the target model can be increased by increasing the number of c(xinter ), i.e., improving the diversity of misclassification classes of the intermediate perturbed examples. For the target model, this seems to change what is essentially a coin-toss game into a dice-toss game.
Based on the above two hypotheses, the method we envisage for generating more transferable adversarial examples is illustrated in Figure 1. Below we will present how to implement such attack method.
3.3 Virtual Step and Auxiliary Gradients Method
We propose two techniques to verify the above two hypotheses and to implement a novel attack method that can generate adversarial examples with more transferability.
Virtual Step. This technique is designed to verify the first hypothesis. To avoid exceeding the limit of the perturbation threshold ϵ, the traditional iterative attacks (such as I-FGSM) usually set the step size α to a small value (normally ϵ/T), and clip the intermediate perturbed examples (i.e., using the Clipx,ϵ{·} operation) during each iteration, which will cause the attack to fall into the poor local maximum [Xie et al.,
1 These hypotheses are for untargeted attacks. We leave research on targeted attacks for our future work.
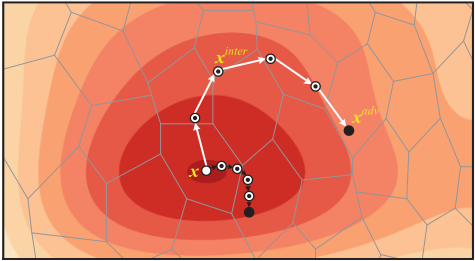
- Original benign example
- Intermediate perturbed example
Figure 1: Illustrations of our envisaged attack (indicated by the white dashed arrow) and the traditional iterative gradient-based attack (indicated by the black dashed arrow). The irregular polygons represent the boundaries of each class.
2019b]. In our method, we propose to set the step size α to a larger value and only clip the perturbed example generated in the last iteration, i.e., Clipx,ϵ{xadv T }; this can help the attack to avoid converging on the local optimum and increase the likelihood that the final adversarial example will be misclassified to a class far away from the ground-truth class. Since the step size used in the attack is not the real perturbation amplitude of the examples, we refer to it as "virtual step".
Auxiliary Gradients. This technique is designed to verify the second hypothesis. By using the gradients of the loss function with respect to the ground-truth label ytrue , traditional iterative attacks (such as I-FGSM) perturb the examples in approximately one fixed direction, which is not conducive to making the intermediate perturbed examples be misclassified to different classes. We propose to use not only the gradients corresponding to the ground-truth label (main gradients), but also the gradients corresponding to some other labels (auxiliary gradients) to generate adversarial perturbations. For an I-FGSM using auxiliary gradients , it will perturb the examples both in the ascending direction of the main gradients and the descending direction of the auxiliary gradients. Through the use of auxiliary gradients, the intermediate perturbed examples may potentially be misclassified to the auxiliary classes.
Based on the above analysis, the iterative fast gradient sign method with virtual step and auxiliary gradients (abbreviated to VA-I-FGSM) can be formulated as follows:
where α denotes the virtual step, ytrue + denotes that xadv t is updated by adding the sign of the loss gradients with respect to ytrue , and yaux - denotes that xadv t is updated by subtracting the sign of the loss gradients with respect to yaux . Note that there may be more than one yaux and that yaux ̸= ytrue .
A detailed description of VA-I-FGSM is presented in Algorithm 1. In each iteration, in addition to updating the example with the main gradients corresponding to ytrue , we ran-
- Final adversarial example
Algorithm 1 VA-I-FGSM for crafting adversarial examples.
Input: A classifier f with loss function J; a benign example x and its true label ytrue ; the label set C; the number of iterations T; the perturbation threshold ϵ; the virtual step size α; the number of auxiliary labels naux.
Output: The adversarial example xadv .
1: Let xadv 0 ←x; t ← 0. 2: while t < T do 3: xadv tmp ← xadv t +α·sign(∇xJ(xadv t , ytrue )) 4: Caux ←RandomSelect(C\ytrue , naux) 5: for yaux in Caux do 6: xadv tmp ← xadv tmp - α·sign(∇xJ (xadv t , yaux )) 7: end for 8: xadv t+1 ← xadv tmp 9: t ← t + 1 10: end while 11: return xadv ←Clipx,ϵ{xadv T }domly select naux labels fromC\ytrue to construct auxiliary gradients for generating additional adversarial perturbations. C\ytrue represents the set formed by removing the element ytrue from set C. No clipping operation is performed for the intermediate perturbed examples, and only the final adversarial example is clipped to satisfy the perturbation threshold.
Our proposed virtual step and auxiliary gradients can be similarly integrated into DI 2 -FGSM and TI 2 -FGSM to create VA-DI 2 -FGSM and VA-TI 2 -FGSM, respectively.
4 Experiments
4.1 Experimental Setup
Dataset. We use a subset dataset 2 of ImageNet to conduct the experiments. This subset dataset consists of 1000 images and was used in the NIPS 2017 adversarial competition. All the images are resized to 299 × 299 × 3 pixels.
Models. We consider four normally trained models, i.e., Inception-v3 (Inc-v3) [Szegedy et al., 2016], Xception (Xcep) [Chollet, 2017], Inception-Resnet-v2 (IncResv2) [Szegedy et al., 2017] and ResNet-152-v2 (Res152v2) [He et al., 2016], and three defense models, i.e., input transformation through JPEG compression (JPEG) [Guo et al., 2018], input transformation through random resizing and padding (R&P, rank-2 submission in the NIPS 2017 defense competition) [Xie et al., 2018], ResNeXt101 DenoiseAll (ResX101-dn, rank-1 submission in CAAD 2018) [Xie et al., 2019a]. All models are publicly available 3 .
Implementation details. For all attacks, themaximumperturbation of each pixel is set to ϵ = 16. The total number of iterations is set to T = min(ϵ + 4, 1.25ϵ) [Kurakin et al., 2017]. For I-FGSM, DI 2 -FGSM and TI 2 -FGSM, the step size is set to α = ϵ/T. For DI 2 -FGSM, the transformation operations T (x; p) first randomly resize the input to a rnd×rnd×3 image, with rnd ∈ [299, 330), then pad to size 330×330×3
2 https://www.kaggle.com/c/nips-2017-non-targeted-adversarialattack/data
3 https://keras.io/api/applications/
in a random manner. The transformation probability p is set to be 0.5. For TI 2 -FGSM, W is set to be a 15 × 15 Gaussian kernel. In experiments, the pixel values of all images are scaled to [0, 1]. Correspondingly, the ϵ is scaled to 16/255.
4.2 Setting the Hyperparameters
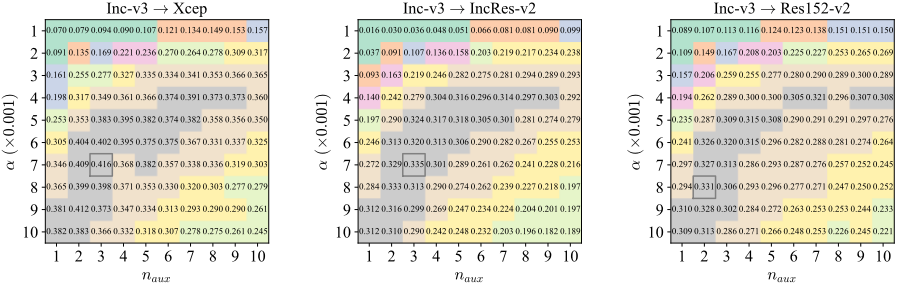
We use a grid search to find the optimal values for hyperparameters α and naux. We first attack Inc-v3 by VA-I-FGSM, VA-DI 2 -FGSM and VA-TI 2 -FGSM under white-box settings, and then transfer the adversarial examples to Xcep, IncRes-v2 and Res152-v2. Figure 2 presents the attack success rates of the adversarial examples crafted on Inc-v3 by VA-I-FGSM. It can be seen that, for the three different black-box models, hyperparameters associated with high attack success rates have almost the same distribution. For Xcep, the attack success rate is the highest when α = 0.007 and naux = 3; for IncResv2, the attack success rate is the highest when α = 0.007 and naux = 3; for Res152-v2, the attack success rate is the highest when α = 0.008 and naux = 2. Thus, for VA-I-FGSM, we set α = 0.007 and naux = 3 according to the majority rule.
Similarly, we have searched the optimal hyperparameters for VA-DI 2 -FGSM and VA-TI 2 -FGSM. For VA-DI 2 -FGSM, the hyperparameters are set to α = 0.009 and naux = 1; for VA-TI 2 -FGSM, the hyperparameters are set to α = 0.009 and naux = 4. The following experiments are all based on the above hyperparameters.
4.3 Attacking a Single Model
We first conduct attacks on a single model. We craft adversarial examples only on normally trained models under whitebox settings, and test them on all seven models. The attack success rates are shown in Table 1.
From Table 1, we can observe that, for black-box attacks, our proposed methods with virtual step and auxiliary gradients outperforms the baseline methods on all models, including normally trained and defense models. It is worth noting that, with the exception of ResX101-dn, our methods improve the attack success rates by a large margin of 12% ∼ 28% on all other models. For example, if the adversarial examples are crafted on Inv-v3, VA-I-FGSM achieves an attack success rate of 41.6% on Xcep, while the baseline I-FGSM obtains an attack success rate of only 13.8%. On ResX101-dn, our methods are slightly superior to the baselines. Since the classification accuracy of ResX101-dn on benign examples is as low as 82.1%, we treat ResX101-dn as a special case that may be countered by adaptive attacks. For white-box attacks, only VA-TI 2 -FGSM is slightly inferior to TI 2 -FGSM in some cases, while VA-I-FGSM and VA-DI 2 -FGSM surpass IFGSM and DI 2 -FGSM, respectively.
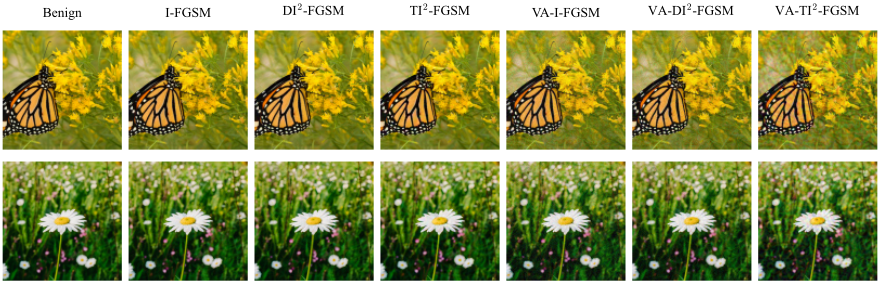
Figure 3 visualizes two randomly selected benign images and their corresponding adversarial images crafted by different methods. Overall, all adversarial images are visually indistinguishable from benign images. The adversarial perturbations generated by our methods are slightly more perceptible for humans than those generated by baseline methods. However, it should be noted that the adversarial images crafted by our methods still do not exceed the perturbation threshold of ϵ = 16.
4.4 Attacking an Ensemble of Models
In this section, we test the performance of our methods on an ensemble of models. We adopt the ensemble strategy proposed in [Dong et al., 2018], which fuses the logits of different models. The experimental results on normally trained models are presented in Table 2. We can observe that the methods with virtual step and auxiliary gradients outperform all baseline methods.
The experimental results on defense models are presented in Table 3. We can observe that VA-I-FGSM and VA-DI 2 - FGSM outperform I-FGSM and DI 2 -FGSM, respectively. On JPEG and R&P defense models, VA-TI 2 -FGSM is inferior to TI 2 -FGSM.
4.5 Ablation Study
In this section, we conduct an ablation study to analyze the influence of virtual step and auxiliary gradients in attacks. We take VA-TI 2 -FGSM as an example. For VA-TI 2 -FGSM, the optimal hyperparameters are α = 0.009 and naux = 4.
Virtual step size α. We set the number of auxiliary labels to naux = 0, i.e., no auxiliary gradients are used in attacks. The virtual step size α varies from 0.001 to 0.01. In this case, VATI 2 -FGSM degrades to TI 2 -FGSM with only a virtual step.
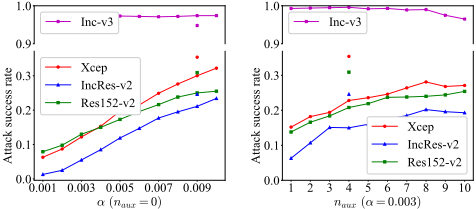
The results are shown on the left of Figure 4. We observe that the white-box attack success rates remain stable as α increases. The black-box attack success rates increase with increasing α, but gradually flatten out. Given α ∈ [0.001, 0.01], the black-box attack success rates do not reach the benchmark values. Moreover, if α ≫ ϵ/T, the perturbations will tend to become increasingly human-perceptible in practice.
| Model | Attack | Inc-v3 | Xcep | IncRes-v2 | Res152-v2 | JPEG | R&P | ResX101-dn |
|---|---|---|---|---|---|---|---|---|
| Inc-v3 | I-FGSM VA-I-FGSM DI 2 -FGSM | 0.973 0.999 0.976 0.999 | 0.138 0.416 0.291 0.508 0.129 0.354 0.978 | 0.091 0.335 0.219 0.457 0.051 0.246 0.122 | 0.150 0.313 0.255 0.433 0.132 | 0.127 0.306 0.246 0.439 0.155 0.361 | 0.201 0.414 0.402 0.602 0.177 0.404 0.233 0.451 | 0.180 0.186 0.182 0.190 0.187 0.198 0.183 0.188 |
| VA-DI 2 -FGSM | ||||||||
| TI 2 -FGSM | 0.973 | |||||||
| VA-TI 2 -FGSM | 0.948 | 0.309 | ||||||
| Xcep | ||||||||
| I-FGSM | 0.234 | 0.182 | 0.169 | |||||
| VA-I-FGSM | 0.457 | 1.000 | 0.339 | 0.364 | 0.355 | |||
| DI 2 -FGSM | 0.494 | 0.981 | 0.345 | 0.375 | 0.339 | 0.514 | 0.186 | |
| VA-DI 2 -FGSM | 0.662 | 0.999 | 0.510 | 0.524 | 0.535 | 0.669 | 0.188 | |
| TI 2 -FGSM | 0.237 | 0.976 | 0.106 | 0.185 | 0.235 | 0.255 | 0.187 | |
| VA-TI 2 -FGSM | 0.433 | 0.956 | 0.261 | 0.319 | 0.388 | 0.418 | 0.196 | |
| IncRes-v2 | I-FGSM | 0.315 | 0.217 | 0.995 | 0.202 | 0.182 | 0.260 | 0.182 |
| VA-I-FGSM | 0.498 | 0.411 | 0.992 | 0.325 | 0.343 | 0.431 | 0.188 | |
| DI 2 -FGSM | 0.557 | 0.441 | 0.988 | 0.387 | 0.371 | 0.523 | 0.183 | |
| VA-DI 2 -FGSM | 0.736 | 0.648 | 0.999 | 0.528 | 0.580 | 0.691 | 0.189 | |
| TI 2 -FGSM | 0.281 | 0.217 | 0.969 | 0.197 | 0.251 | 0.262 | 0.187 | |
| VA-TI 2 -FGSM | 0.442 | 0.374 | 0.788 | 0.326 | 0.400 | 0.423 | 0.195 | |
| Res152-v2 | I-FGSM | 0.254 | 0.195 | 0.089 | 0.970 | 0.143 | 0.223 | 0.185 |
| VA-I-FGSM | 0.462 | 0.462 | 0.330 | 1.000 | 0.334 | 0.478 | 0.194 | |
| DI 2 -FGSM | 0.508 | 0.475 | 0.372 | 0.971 | 0.343 | 0.502 | 0.186 | |
| VA-DI 2 -FGSM | 0.698 | 0.684 | 0.560 | 0.999 | 0.544 | 0.705 | 0.197 | |
| TI 2 -FGSM | 0.209 | 0.180 | 0.077 | 0.967 | 0.193 | 0.222 | 0.189 | |
| VA-TI 2 -FGSM | 0.402 | 0.372 | 0.266 | 0.968 | 0.357 | 0.390 | 0.198 |
| Attack | -Inc-v3 | -Xcep | -IncRes-v2 | -Res152-v2 |
|---|---|---|---|---|
| I-FGSM | 0.573 | 0.447 | 0.362 | 0.341 |
| VA-I-FGSM | 0.659 | 0.603 | 0.525 | 0.475 |
| DI 2 -FGSM | 0.846 | 0.766 | 0.704 | 0.670 |
| VA-DI 2 -FGSM | 0.914 | 0.880 | 0.827 | 0.749 |
| TI 2 -FGSM | 0.549 | 0.438 | 0.321 | 0.329 |
| VA-TI 2 -FGSM | 0.556 | 0.476 | 0.375 | 0.413 |
It is therefore unrealistic to rely only on the virtual step to improve the transferability of adversarial examples.
Number of auxiliary labels naux. We set the virtual step size to α = ϵ/T ≈ 0.003, i.e., the step size usually used by traditional iterative attacks. The number of auxiliary labels naux varies from 1 to 10. In this case, VA-TI 2 -FGSM degrades to TI 2 -FGSM with only auxiliary gradients. The results are shown on the right of Figure 4. It can be seen that if naux ≤ 4, the black-box success rates increase significantly; by contrast, if naux > 4, the black-box attack success rates increase moderately and the white-box attack success rates tend to drop. Given naux ∈ [1, 10], the black-box attack success rates do not reach the benchmark values. Moreover, the time cost for generating adversarial examples increases with increasing naux. It is therefore impractical to rely only on the auxiliary gradients to improve the transferability.
| Attack | JPEG | R&P | ResX101-dn |
|---|---|---|---|
| I-FGSM | 0.472 | 0.577 | 0.188 |
| VA-I-FGSM | 0.501 | 0.618 | 0.198 |
| DI 2 -FGSM | 0.785 | 0.868 | 0.193 |
| VA-DI 2 -FGSM | 0.849 | 0.911 | 0.202 |
| TI 2 -FGSM | 0.578 | 0.574 | 0.198 |
| VA-TI 2 -FGSM | 0.485 | 0.526 | 0.208 |
5 Conclusion
In this paper, we propose to improve the transferability of adversarial examples through the use of a virtual step and auxiliary gradients, which can be easily integrated into existing gradient-based attacks. Extensive experiments on ImageNet show that our method significantly outperforms the baselines. The ablation study further verifies that both the virtual step and auxiliary gradients are necessary to achieving the improved results. In future, we will further explore the potential use of auxiliary gradients in generating adversarial examples.
@inproceedings{ijcai2022p227,
  title     = {Improving Transferability of Adversarial Examples with Virtual Step and Auxiliary Gradients},
  author    = {Zhang, Ming and Kuang, Xiaohui and Li, Hu and Wu, Zhendong and Nie, Yuanping and Zhao, Gang},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {1629--1635},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/227},
  url       = {https://doi.org/10.24963/ijcai.2022/227},
}
TY - CPAPER TI - Improving Transferability of Adversarial Examples with Virtual Step and Auxiliary Gradients AU - Zhang, Ming AU - Kuang, Xiaohui AU - Li, Hu AU - Wu, Zhendong AU - Nie, Yuanping AU - Zhao, Gang T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 1629 EP - 1635 DO - 10.24963/ijcai.2022/227 UR - https://doi.org/10.24963/ijcai.2022/227 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





