
Weakly-supervised Text Classification with Wasserstein Barycenters Regularization
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 3373-3379.
https://doi.org/10.24963/ijcai.2022/468
Keywords
- Natural Language Processing: Text Classification
- Machine Learning: Weakly Supervised Learning
- Machine Learning: Classification
Abstract
Weakly-supervised text classification aims to train predictive models with unlabeled texts and a few representative words of classes, referred to as category words, rather than labeled texts. These weak supervisions are much more cheaper and easy to collect in real-world scenarios. To resolve this task, we propose a novel deep classification model, namely Weakly-supervised Text Classification with Wasserstein Barycenter Regularization (WTC-WBR). Specifically, we initialize the pseudo-labels of texts by using the category word occurrences, and formulate a weakly self-training framework to iteratively update the weakly-supervised targets by combining the pseudo-labels with the sharpened predictions. Most importantly, we suggest a Wasserstein barycenter regularization with the weakly-supervised targets on the deep feature space. The intuition is that the texts tend to be close to the corresponding Wasserstein barycenter indicated by weakly-supervised targets. Another benefit is that the regularization can capture the geometric information of deep feature space to boost the discriminative power of deep features. Experimental results demonstrate that WTC-WBR outperforms the existing weakly-supervised baselines, and achieves comparable performance to semi-supervised and supervised baselines.
- [Agueh and Carlier, 2011] Martial Agueh and Guillaume Carlier. Barycenters in the wasserstein space. SIAM Jour- nal on Mathematical Analysisb, 43(2):904-924, 2011.
- [Bogachev and Kolesnikov, 2012] Vladimir Igorevich Bo- gachev and Aleksandr Viktorovich Kolesnikov. The monge-kantorovich problem: achievements, connec- tions, and perspectives. Russian Mathematical Surveys, 67(5):785-890, 2012.
- [Chang et al., 2008] Ming-Wei Chang, Lev-Arie Ratinov, Dan Roth, and Vivek Srikumar. Importance of seman- tic representation: Dataless classification. In AAAI, pages 830-835, 2008.
- [Chen et al., 2020] Jiaao Chen, Zichao Yang, and Diyi Yang. Mixtext: Linguistically-informed interpolation of hidden space for semi-supervised text classification. In ACL, pages 2147-2157, 2020.
- [Chi et al., 2019] Jinjin Chi, Jihong Ouyang, Ximing Li, Yang Wang, and Meng Wang. Approximate optimal trans- port for continuous densities with copulas. In IJCAI, pages 2165-2171, 2019. IJCAI
- [Chizat et al., 2018] Lenaic Chizat, Gabriel Peyré, Bernhard Schmitzer, and Franc ¸ois-Xavier Vialard. Scaling algo- rithms for unbalanced optimal transport problems. Math- ematics of Computation, 87(314):2563-2609, 2018.
- [Cuturi, 2013] Marco Cuturi. Sinkhorn distances: Light- speed computation of optimal transport. In NeurIPS, pages 2292-2300, 2013.
- [Devlin et al., 2019] Jacob Devlin, Ming-Wei Chang, Ken- ton Lee, and Kristina Toutanova. BERT: pre-training of deep bidirectional transformers for language understand- ing. In NAACL, pages 4171-4186, 2019.
- [Druck et al., 2008] Gregory Druck, Gideon Mann, and An- drew McCallum. Learning from labeled features using generalized expectation criteria. In SIGIR, pages 595-602, 2008.
- [Kusner et al., 2015] Matt Kusner, Yu Sun, Nicholas Kolkin, and Kilian Weinberger. From word embeddings to docu- ment distances. In ICML, pages 957-966, 2015.
- [Lan et al., 2020] Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, and Radu Sori- cut. Albert: A lite bert for self-supervised learning of lan- guage representations. In ICLR, 2020.
- [Li and Yang, 2018] Ximing Li and Bo Yang. A pseudo label based dataless naive bayes algorithm for text classification with seed words. In COLING, pages 1908-1917, 2018.
- [Li et al., 2016] Chenliang Li, Jian Xing, Aixin Sun, and Zongyang Ma. Effective document labeling with very few seed words: a topic modeling approach. In CIKM, pages 85-94, 2016.
- [Li et al., 2018] Ximing Li, Changchun Li, Jinjin Chi, Ji- hong Ouyang, and Chenliang Li. Dataless text classifica- tion: A topic modeling approach with document manifold. In CIKM, pages 973-982, 2018.
- [Li et al., 2020] Changchun Li, Ximing Li, Jihong Ouyang, and Yiming Wang. Semantics-assisted wasserstein learn- ing for topic and word embeddings. In ICDM, pages 292- 301, 2020.
- [Li et al., 2021] Qian Li, Hao Peng, Jianxin Li, Congying Xia, Renyu Yang, Lichao Sun, Philip S. Yu, and Lifang He. A survey on text classification: from shallow to deep learning. arXiv:2008.00364, 2021.
- [Mekala and Shang, 2020] Dheeraj Mekala and Jingbo Shang. Contextualized weak supervision for text classification. In ACL, pages 323-333, 2020.
- [Meng et al., 2018] Yu Meng, Jiaming Shen, Chao Zhang, and Jiawei Han. Weakly-supervised neural text classifi- cation. In CIKM, pages 983-992, 2018.
- [Meng et al., 2020] Yu Meng, Yunyi Zhang, Jiaxin Huang, Chenyan Xiong, Heng Ji, Chao Zhang, and Jiawei Han. Text classification using label names only: A language model self-training approach. In EMNLP, pages 9006- 9017, 2020.
- [Schmitz et al., 2018] Morgan A Schmitz, Matthieu Heitz, Nicolas Bonneel, Fred Ngole, David Coeurjolly, Marco Cuturi, Gabriel Peyré, and Jean-Luc Starck. Wasserstein dictionary learning: Optimal transport-based unsupervised nonlinear dictionary learning. SIAM Journal on Imaging Sciences, 11(1):643-678, 2018.
- [Wang et al., 2021] Zihan Wang, Dheeraj Mekala, and Jingbo Shang. X-class: Text classification with extremely weak supervision. In NAACL, pages 3043-3053, 2021.
- [Xie et al., 2019] Qizhe Xie, Zihang Dai, Eduard Hovy, Minh-Thang Luong, and Quoc V. Le. Unsupervised data augmentation for consistency training. arXiv preprint arXiv:1904.12848, 2019.
- [Yang et al., 2019] Zhilin Yang, Zihang Dai, Yiming Yang, Jaime G. Carbonell, Ruslan Salakhutdinov, and Quoc V. Le. Xlnet: Generalized autoregressive pretraining for language understanding. In NeurIPS, pages 5754-5764, 2019.
- [Zhang et al., 2021] Lu Zhang, Jiandong Ding, Yi Xu, Yingyao Liu, and Shuigeng Zhou. Weakly-supervised text classification based on keyword graph. In EMNLP, page 2803-2813, 2021.
- [Zhou, 2018] Zhi-Hua Zhou. A brief introduction to weakly supervised learning. National Science Review, 5(1):44-53, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Text classification is a significant and fundamental task in natural language processing, with many real-world applications, e.g., document tagging, sentiment analysis, and question answering, to name a few. Basically, the task aims to train predictive models with a collection of manually labeled texts, enabling to automatically infer the labels of unseen texts. During the past decades, it has been well investigated by the community, suggesting a number of conventional text classifiers and the emerging deep classification models [Li et al., 2021].
The existing text classifiers, especially the deep classification models, have achieved great success with promising performance [Lan et al., 2020]. However, to guarantee the effectiveness, they often require abundant training texts with accurate labels, which are expensive and difficult to collect. Due to the manual annotation burden, only the training texts with cheaper weak supervision are available in many real-world scenarios. Such cheaper supervision tends to be inaccurate, incomplete, and ambiguous, potentially resulting in performance degradation even by a large margin. Naturally, how to learn strong text classifiers with weak supervision now becomes an urgent demand, and the community has paid more attention to the weakly-supervised methods [Zhou, 2018].
∗Corresponding Author
The weakly-supervised scenario we now concern is even more challenging, where we are only given by unlabeled texts with the sets of category words for classes as the only available supervised signals [Li et al., 2016; Li and Yang, 2018]. To be specific, the category words are defined as a few representative words of classes, e.g., label names, label descriptions, and hot words, supporting the basis knowledge of classes. For example, in terms of news articles, the label names such as "sports", "politics", and "bussiness" definitely express the corresponding classes [Meng et al., 2020].
Contrary to training texts with accurate labels, the category words are much cheaper to be collected by human annotators [Druck et al., 2008]. Unfortunately, they provide very weak and limited supervision. For example, on the dataset AG News with category words of label names, only about 3.4% texts contain category words. To make matters worse, only 2.1% texts contain the category words from the relevant labels. Training with such weak supervision is intractable. To handle this weakly-supervised task, several methods have been developed by simultaneously expanding and taking full advantage of the limited supervised signals within the category words. For example, the popular existing techniques include: propagating supervised signals among texts with manifold regularization [Li et al., 2018], generating pseudotexts with category words [Meng et al., 2018], and applying the language model to expand category words [Meng et al., 2020].
In this paper, our motivation is to solve for the aforementioned weakly-supervised task by regularizing the supervised signals with Wasserstein barycenter. Accordingly, we propose a novel deep classification model, namely Weaklysupervised Text Classification with Wasserstein Barycenter Regularization (WTC-WBR). By referring to [Li et al., 2016;
Li et al., 2018], we initialize the pseudo-labels of texts by using the category word occurrences. Because the pseudolabels may be inaccurate and a number of texts may even contain no category words, we formulate a weakly self-training framework, i.e., iteratively updating the weakly-supervised targets by combining the pseudo-labels with the sharpened predictions. Most importantly, we suggest a Wasserstein barycenter regularization with weakly-supervised targets on the deep feature space. The intuition is that the texts tend to be close to the corresponding Wasserstein barycenter indicated by weakly-supervised targets. Another benefit is that the regularization can capture the geometric information of deep feature space to enhance the discriminative power of deep features. The experiments have been conducted on several prevalent text datasets. Empirical results show that WTCWBR performs better than existing weakly-supervised baselines and achieves competitive performance comparing with even semi-supervised and supervised baselines.
In summary, the major contributions of this paper are as follows:
- We develop a novel deep classification model named WTC-WBR, which trains the text classifier over unlabeled texts with category words.
- We formulate a weakly self-training framework, and suggest a Wasserstein barycenter regularization to boost the supervision updating.
- Empirical results show that WTC-WBR outperforms existing weakly-supervised baselines, and is even on a par with semi-supervised and supervised baselines.
2 Preliminary
We now briefly introduce the preliminaries of Wasserstein distance [Bogachev and Kolesnikov, 2012] and Wasserstein barycenter [Agueh and Carlier, 2011].
2.1 Wasserstein Distance in Discrete Space
Formally, the Wasserstein distance measures the distances between probability distributions from the perspective of geometry.
Definition 1. Consider a discrete state space Ω = {w1, . . . ,wV }, where wi represents the feature vector of each state i. The p-order Wasserstein distance between two discrete probability distributions υ1 and υ2 on Ω is defined as follows:W p
where ⟨·, ·⟩ is the Frobenius dot-product; M ∈ RV×V + is the cost matrix of each state pair, i.e., each element Mij = dpΩ(wi,wj); and T (υ1, υ2) is the set of joint distributions of υ1 and υ2.
With an auxiliary entropy regularization, a more efficient regularized version of Wasserstein distance [Cuturi, 2013] is defined below:
where H(T) = -⟨T, ln(T)⟩ and γ is the scaling parameter. Here, we concentrate on the case of p = 2, and to make the notations simple, we denote by W(υ1, υ2;M) the regularized Wasserstein distance of Eq.2.
By applying the Sinkhorn method [Cuturi, 2013], the optimum T∗ and gradients of υ1 and υ2 can be calculated below:
where κ = exp(-γM); 1 is the all-one vector; and ⊘ denotes the element-wise division.
2.2 Wasserstein Barycenter
The Wasserstein barycenter is a minimizer of a weighted average of squared Wasserstein distances [Agueh and Carlier, 2011], providing an efficient notion for constructing geometric prototypes in the Wasserstein space.
Definition 2. The Wasserstein barycenter of S probability distributions Υ = {υ1, . . . , υS} with barycentric weights Λ = {λ1, . . . , λS} is defined below:
Generally speaking, the Wasserstein barycenter can be regarded as a special case of unbalanced optimal transport problem [Chizat et al., 2018], solved with an efficient iterative method derived from the Sinkhorn method. At each iteration m, it is updated by the following equations:
The method continues this update loop until the termination condition is reached, and finally outputs the solution of Wasserstein barycenter.
3 The ProposedWTC-WBR Approach
For clarity, we first formulate the weakly-supervised scenario concerned in this paper. The training dataset we faced is composed of a set of unlabeled raw texts U = {xd}Dd=1 and sets of category words for K classes C = {Ck}Kk=1 . For each class k, it is associated with a small set of category words Ck, which is treated as the only available supervision. Because the set Ck of each class has very few category words, the supervision information must be very weak and limited. Our goal is to induce the predictive model over the training dataset {U, C}, where the model can infer the most relevant labels for unseen texts.
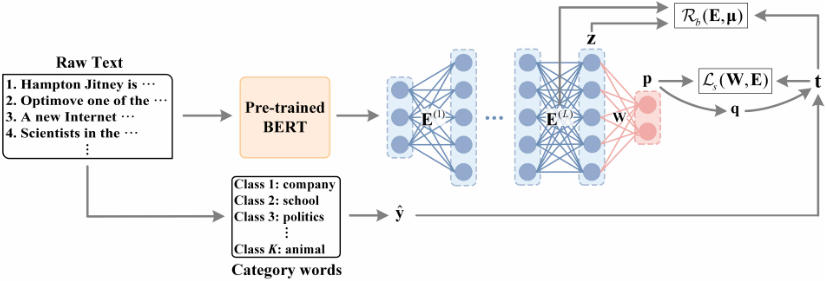
To handle this task, we propose a novel deep classification model named WTC-WBR, whose overall framework is illustrated in Fig.1. Formally, the objective of WTC-WBR is composed of two parts, weakly self-training loss with category words and Wasserstein barycenter regularization. In the following, we introduce them in detail.
3.1 Weakly Self-Training Loss with Category Words
Naturally, one intuitive idea of learning with category words is to form pseudo-labels for unlabeled texts with the category word occurrence information before training text classifiers [Li et al., 2016; Li et al., 2018]. For each unlabeled text d, we can compute its pseudo-label vector ̂yd by the following formula:
where sdk denotes the total number of category words of class k appearing in text d; and ϵ is a smoothing parameter in case of zero-division. Accordingly, we can then train the text classifier with the pseudo-training dataset {(xd, ̂yd)}Dd=i by minimizing the following objective:
where ℓ(, ·, ) is the loss function; fB(·) is the pre-trained BERT model with parameters B; fE(·) is a L-layer feature encoder parameterized by E = {E(l) }Ll=1 ; and fW(·) is the classification layer parameterized by W. To make the notations simple, we denote by z1:D and p1:D the deep features and predictions, respectively:
Unfortunately, because the category words are scarce, the pseudo-labels tend to be inaccurate, where each text may contain the category words of its irrelevant classes. To make matters worse, many texts may contain no category words, resulting in the useless all-zero pseudo-label vectors [Meng et al., 2020]. To resolve the problems, we propose to train the model in a weakly self-training manner, which can simultaneously refine the inaccurate and all-zero supervision. Specifically, for each text d, we form a weakly-supervised target vector td by combining the pseudo-labels ̂yd and sharpened predictions qd, formulated below:
where ρ is a scaling parameter used to control the importance between ̂y and q. Following the assumption that the predictions become more accurate along with the model update [Xie et al., 2019], we adaptively tune ρ by applying a logschedule decreasing annealing to weaken the importance of the pseudo-labels. At each epoch t, it is computed as follows:
where ρinit and ρfinal are coefficient parameters; and T is the maximum number of epochs.
We replace ̂y1:D with t1:D as the predictive targets of training texts, so as to formulate a weakly self-training loss. Here, we specify it by applying the KL-divergence loss function below:
3.2 Wasserstein Barycenter Regularization
To further refine the weakly-supervised signals, we regularize them by minimizing the distances between the texts and the barycenters of relevant labels indicated by the weaklysupervised targets. Specifically, we measure the distances between the deep features of texts z1:D and the trainable label barycenters µ1:K with the Wasserstein distance. This is actually equivalent to formulating a Wasserstein barycenter objective for each label as follows:
| Algorithm 1 Model fitting for WTC-WBR | |
| Input: Training dataset {U, C} Output: A trained text classifier fW(fE(fB(·))) | |
| 1: | Employ the pre-trained BERT model with parameters B; |
| 2: | Initialize the parameters {W,E} randomly; |
| 3: | Calculate the pseudo-labels ̂y1:d by Eq.(10); |
| 4: | Initialize µ1:K with Eqs.(7), (8), (9); |
| 5: | for iter = 1 to T do: |
| 6: | Calculate each T∗dk with mini-batches; |
| 7: | CalculateM(E) by Eq.(19); |
| 8: | Calculate gradients of {W,E,B,µ} with mini- batches; |
| 9: | Update {W,E,B,µ} with Adam; |
| 10: | end for |
where each barycentric weight λdk is derived from the weakly-supervised target td:
̂zd = softmax(zd) and ̂µk = softmax(µk) aim to ensure normalized discrete distributions; and specially, each attribute of the deep feature z is represented by the top layer weight E(L) of the feature encoder, thus the each element of the cost matrix M(E) can be calculated by the cosine distance between any two attributes:
Accordingly, with the above definition of M(E), we kindly consider that the regularization of Eq.(17) brings another benefit, where it can capture the geometric information on the deep feature space, enabling to boost the discriminative power.
3.3 Full Objective andModel Fitting
By combining Eqs.(16) and (17), we show the full objective of WTC-WBR with respect to the trainable parameters {W, E, B, µ} as follows:
where η is the regularization parameter.
We initialize each Wasserstein barycenter µk by performing the loops of Eqs.(7), (8), and (9) until convergence with pseudo-labels calculated by Eq.(10). We then adopt the gradient-based method to update each parameter of interest. For {W, B}, the gradients can be directly calculated by backpropagation. For E, we perform a few number of inner loops with Eqs.(3) and (4) to estimate the optimum T∗dk for each W(̂zd, ̂µk;M(E)) by fixing the current parameters. Accordingly, the full objective can be written as follows:
Its gradient can be then calculated by backpropagation. For each µk, its gradient can be directly calculated by referring to Eq.(5).
| Dataset | #Train | #Test | #Class | #AvgLc |
|---|---|---|---|---|
| IMDB | 25,000 | 25,000 | 2 | 1 |
| AGNews | 120,000 | 7,600 | 4 | 1 |
| DBPedia | 560,000 | 70,000 | 14 | 1.4 |
To efficiently handle a large number of texts, we form noisy gradients of {W,E,B,µ} by randomly drawing a minibatch of texts at each iteration with the spirit of stochastic optimization. For clarity, we summarize the full model fitting process in Algorithm 1.
4 Experiment
Datasets. We explore the proposedWTC-WBRmethod on 3 prevalent datasets from various domains: IMDB from movie review sentiment, AG News from news topic, and DBPedia fromWikipedia topic [Meng et al., 2020]. Following the protocol in [Meng et al., 2020], we employ the label names as category words, where each label name contains at most 3 words. The dataset statistics are listed in Table 1.
Baseline methods. To study the effectiveness of WTCWBR, we compare it with 9 existing text classification methods: 5 weakly-supervised methods, Dataless [Chang et al., 2008], WeSTClass 1 [Meng et al., 2018], LOTClass 2 [Meng et al., 2020], X-Class 3 [Wang et al., 2021], ClassKG 4 [Zhang et al., 2021]; 2 semi-supervised method, UDA 5 [Xie et al., 2019] and MixText 6 [Chen et al., 2020]; and 2 supervised methods, BERT 7 [Devlin et al., 2019] and XLNet 8 [Yang et al., 2019]. WTC-ST is the ablative version of WTC-WBR, which trains the classifier with the weakly selftraining loss only. Specially, we compare the versions without BERT fine-tuning on WTC-WBR and WTC-ST, and annotate as static.
Implementation details. For WTC-WBR and WTC-ST, we feed each text into the pre-trained BERT-base-uncased encoder and feed the averaged pooling of token embeddings into the feature encoder. The maximum sequence lengths are set as 512, 200 and 200 for IMDB, AG News and DBPedia, respectively. We apply the Adam optimizer and the learning rates are tuned over 1e - 7 ∼ 7e - 4. We pre-train 2 epochs with the weakly self-training loss, and further train the full objective 10 epochs. For the static WTC-WBR and WTC-ST, we feed the static averaged pooling of token embeddings into feature encoder. The maximum sequence lengths are all set as 512. The batch size is 256. We pre-train 5 epochs and further train the full objective with 130, 20, and 20 epochs for IMDB, AG News, and DBPedia, respectively. The learning rates are tuned over 5e-5 ∼ 1e-3. For both two versions, we firstly train the model on the texts which contain category words due to the lack of category-word-covered texts. We adopt a onelayer MLP as the feature encoder and a one-layer MLP as the classification layer. The dimensions are 768-200-K, and we apply tanh as the activation function. ρinit and ρfinal are set as 0.05 and 0.99. We have varied the regularization parameter η from the set {10-3 , 10-2 , . . . , 102 , 103 } for examination and empirically set η as 100, 1 and 1 for IMDB, AG News and DBPedia, respectively. We implemented our method by PyTorch and run it on 1 RTX A6000 GPU in a Ubuntu platform of 32G memories.
1 https://github.com/yumeng5/WeSTClass
2 https://github.com/yumeng5/LOTClass
3 https://github.com/ZihanWangKi/XClass
4 https://github.com/zhanglu-cst/ClassKG
5 https://github.com/google-research/uda
6 https://github.com/GT-SALT/MixText
7 https://github.com/huggingface/transformers
8 https://github.com/zihangdai/xlnet
| Supervision Pattern | Methods | IMDB | AGNews | DBPedia |
|---|---|---|---|---|
| Weakly-supervised | DataLess [Chang et al., 2008] | 0.505 | 0.696 | 0.634 |
| WeSTClass [Meng et al., 2018] | 0.774 | 0.823 | 0.811 | |
| LOTClass [Meng et al., 2020] | 0.865 | 0.864 | 0.911 | |
| X-Class [Wang et al., 2021] | 0.828⋆ | 0.846⋆ | 0.917⋆ | |
| ClassKG [Wang et al., 2021] | 0.874 | 0.888 | 0.980 | |
| WTC-ST (static) (Ours) | 0.808 | 0.864 | 0.956 | |
| WTC-WBR (static) (Ours) | 0.868 | 0.880 | 0.974 | |
| WTC-ST (Ours) | 0.871 | 0.886 | 0.978 | |
| WTC-WBR (Ours) | 0.884 | 0.897 | 0.984 | |
| Semi-supervised | UDA [Xie et al., 2019]) | 0.908 | 0.912 | 0.991 |
| MixText [Chen et al., 2020]) | 0.913 | 0.915 | 0.992 | |
| Supervised | BERT [Devlin et al., 2019] | 0.945 | 0.944 | 0.993 |
| XLNet [Yang et al., 2019] | 0.968 | 0.956 | 0.994 |
4.1 Performance Comparison
We compare WTC-WBR with baseline methods by the classification accuracy on the test examples. For each dataset, we independently run WTC-WBR 5 times and show the averaged results in Table 2. First, we can observe that WTCWBR significantly outperforms all weakly-supervised baselines, including conventional Dataless methods and recent neural competitors in all settings. Besides, it can be surprisingly seen that WTC-WBR is comparable to the semisupervised and supervised methods, further demonstrating the effectiveness of WTC-WBR.
Ablative Study. We observe that the ablative versionWTCST is on a par with the baseline methods. This indicates that applying the predictions to self-training can be significant to gain better results in the weakly-supervised tasks. WTCWBR consistently performs better than WTC-ST without the Wasserstein barycenter regularization. Those results directly indicate the positive impact of the proposed regularization in weakly-supervised tasks. And it is worth mentioning that the two static versions are also on a par with baseline methods, indicating the effectiveness of the proposed regularization.
4.2 Feature Visualization
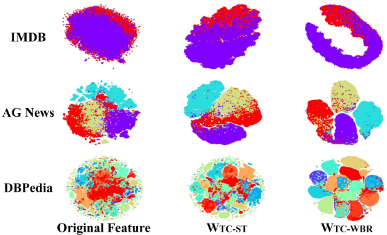
We investigate the discriminative capabilities of original features, and deep features of WTC-ST and WTC-WBR by using t-SNE. We examined both the static (i.e., without fine-tuning) and fine-tuned versions of models. Early results show all versions show similar trends, and here we only plot the results of static ones due to the space limitation. We apply the TSNECUDA tool 9 , and plot the results of t-SNE in Fig.2. It can be clearly seen that the deep features of WTC-ST and WTCWBR are much more discriminative than the original ones on all datasets, so that they can improve the classification performance. More importantly, we can observe that the features of WTC-WBR are also better than those of WTC-ST, further indicating the effectiveness of the Wasserstein barycenter regularization.
9 https://github.com/CannyLab/tsne-cuda
4.3 Parameter Evaluation
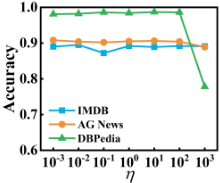
We examined the regularization parameter η on WTC-WBR varying over {10-3 , 10-2 , . . . , 102 , 103 } and plot accuracy results in Fig.3. We may find that our WTC-WBR shows insensitivity overall when η ≤ 102 , and a relatively high parameter leads to performance deficiency when η = 103 , especially on DBPedia. In a word, our WTC-WBR shows insensitivity on regularization parameter.
4.4 Case Study
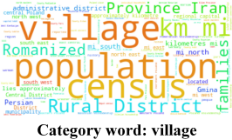
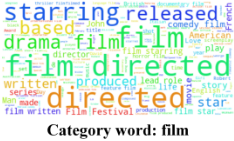
We draw the word cloud graph for each class on the test samples annotated by the predictions. 10 We show two of these graphs on DBPedia with category words "villiage" and "film" in Fig.4. It can be clearly seen that the words with highest weights are highly correlated with their category words. This indirectly indicates WTC-WBR can take full advantage of the only available category words.
5 RelatedWork
Here, we briefly review related studies on weakly-supervised text classification and Wasserstein barycenter.
5.1 Weakly-supervised Text Classification
We concentrate on the weakly-supervised paradigm of learning with unlabeled texts and category words of classes. Generally, the existing methods can be divided into two groups: shallow weakly-supervised models and deep weaklysupervised neural models.
The shallow weakly-supervised models generate pseudolabels with category words before applying traditional text classifiers, or jointly update the pseudo-labels and the classifier [Li et al., 2016; Li and Yang, 2018; Li et al., 2018]. For example, the method of [Li and Yang, 2018] iteratively updates the pseudo-labels, whose confidences are measured by a mixture of category word occurrences and label predictions. A Na¨ıve Bayes classifier is jointly trained with the pseudolabels with high confidences. Besides, there are some topic modeling-based methods, which define the category-topic priors with category word occurrences and classify texts with the estimated category-topic distributions [Li et al., 2016; Li et al., 2018]. Various techniques are proposed to further enhance the model training, such as background-topics used to filter out the less discriminative background knowledge [Li et al., 2016] and manifold regularization used to spread supervised signals among neighboring texts [Li et al., 2018].
10 https://github.com/amueller/word cloud
The recent deep weakly-supervised neural models [Meng et al., 2020; Mekala and Shang, 2020; Wang et al., 2021] are mainly built on the pre-trained language models such as BERT. The LOTClass model [Meng et al., 2020] expands the given category words to more category indicative words by applying the word prediction task of BERT, and then finetunes the BERT by a novel masked category prediction task with category indicative words. The X-Class model [Wang et al., 2021] feeds the raw texts into BERT to get contextualized word embeddings, and forms the label prototypes with the embeddings of category words. The pseudo-labels can be then generated with label prototypes and embeddings of texts to fine-tune BERT. Comparing with those arts, our WTC-WBR applies a novel Wasserstein barycenter regularization to refine the weakly-supervised targets.
5.2 Wasserstein Barycenter
The Wasserstein distance [Bogachev and Kolesnikov, 2012] provides a strong way to measure the distances between probability distributions from the perspective of geometry. Many techniques have been developed to efficiently solve for its minimization problem such as incorporating an auxiliary entropy regularization [Cuturi, 2013] and reformulating the minimization with copulas [Chi et al., 2019]. Due to its strict theoretical properties, the Wasserstein distance has been widely applied to various domains, including topic modeling [Li et al., 2020] and semantic distance measure between documents [Kusner et al., 2015].
By analogy to the definition of barycenters in the Euclidean space, the Wasserstein barycenter is a minimizer of a weighted average of squared Wasserstein distances [Agueh and Carlier, 2011]. It can provide an efficient notion for constructing geometric prototypes in the Wasserstein space beyond Euclidean barycenters. Recently, many optimization methods have been proposed to efficiently solve for the minimization problem of Wasserstein barycenters [Schmitz et al., 2018]. Here, we attempt to adopt the label barycenters to regularize the weakly-supervised signals, especially for the scenario with category words available only.
6 Conclusion
In this paper, we concentrate on the weakly-supervised scenario, where the training dataset only contains unlabeled texts and sets of category words for classes. To resolve the task, we develop a novel deep classification model named WTCWBR, which refines the inaccurate and scarce supervision from the category words by weakly self-training and Wasserstein barycenter regularization. Specifically, we form pseudolabels by using the category word occurrences of texts. Due to the inaccurate and scarce natures of pseudo-labels, we train the model with the mixtures of pseudo-labels and sharpened predictions. Most importantly, we suggest a Wasserstein barycenter regularization on the deep feature space, enabling to further refine the supervision. We conduct extensive experiments to compare WTC-WBR with the state-ofthe-art weakly-supervised, semi-supervised, and supervised methods. Experimental results demonstrate that WTC-WBR is on a par with the existing competitors.
Acknowledgements
The work is supported by the National Natural Science Foundation of China (NSFC) (No.61876071, No.62006094) and Scientific and Technological Developing Scheme of Jilin Province (No.20180201003SF, No.20190701031GH) and Energy Administration of Jilin Province (No.3D516L921421). We appreciate Zihan Wang for valuable discussions and providing pre-trained models.
@inproceedings{ijcai2022p468,
  title     = {Weakly-supervised Text Classification with Wasserstein Barycenters Regularization},
  author    = {Ouyang, Jihong and Wang, Yiming and Li, Ximing and Li, Changchun},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {3373--3379},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/468},
  url       = {https://doi.org/10.24963/ijcai.2022/468},
}
TY - CPAPER TI - Weakly-supervised Text Classification with Wasserstein Barycenters Regularization AU - Ouyang, Jihong AU - Wang, Yiming AU - Li, Ximing AU - Li, Changchun T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 3373 EP - 3379 DO - 10.24963/ijcai.2022/468 UR - https://doi.org/10.24963/ijcai.2022/468 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





