
Multi-Armed Bandit Problem with Temporally-Partitioned Rewards: When Partial Feedback Counts
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 3401-3407.
https://doi.org/10.24963/ijcai.2022/472
Keywords
- Machine Learning: Online Learning
Abstract
There is a rising interest in industrial online applications where data becomes available sequentially. Inspired by the recommendation of playlists to users where their preferences can be collected during the listening of the entire playlist, we study a novel bandit setting, namely Multi-Armed Bandit with Temporally-Partitioned Rewards (TP-MAB), in which the stochastic reward associated with the pull of an arm is partitioned over a finite number of consecutive rounds following the pull. This setting, unexplored so far to the best of our knowledge, is a natural extension of delayed-feedback bandits to the case in which rewards may be dilated over a finite-time span after the pull instead of being fully disclosed in a single, potentially delayed round. We provide two algorithms to address TP-MAB problems, namely, TP-UCB-FR and TP-UCB-EW, which exploit the partial information disclosed by the reward collected over time. We show that our algorithms provide better asymptotical regret upper bounds than delayed-feedback bandit algorithms when a property characterizing a broad set of reward structures of practical interest, namely α-smoothness, holds. We also empirically evaluate their performance across a wide range of settings, both synthetically generated and from a real-world media recommendation problem.
- [Arya and Yang, 2020] Sakshi Arya and Yuhong Yang. Ran- domized allocation with nonparametric estimation for con- textual multi-armed bandits with delayed rewards. Statis- tics & Probability Letters, 164:108818, 2020.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine learning, 47(2-3):235-256, 2002.
- [Bistritz et al., 2019] Ilai Bistritz, Zhengyuan Zhou, Xi Chen, Nicholas Bambos, and Jose Blanchet. Exp3 learning in adversarial bandits with delayed feedback. NeurIPS, 2019.
- [Brost et al., 2019] Brian Brost, Rishabh Mehrotra, and Tris- tan Jehan. The music streaming sessions dataset. In WWW. ACM, 2019.
- [Bubeck and Cesa-Bianchi, 2012] Sébastien Bubeck and Nicolò Cesa-Bianchi. Regret analysis of stochastic and nonstochastic multi-armed bandit problems. Foundations and Trends in Machine Learning, 5(1):1-122, 2012.
- [Castiglioni et al., 2022] Matteo Castiglioni, Alessandro Nuara, Giulia Romano, Giorgio Spadaro, Francesco Trovò, and Nicola Gatti. Safe online bid optimization with return-on-investment and budget constraints subject to uncertainty. arXiv preprint arXiv:2201.07139, 2022.
- [Cayci et al., 2019] Semih Cayci, Atilla Eryilmaz, and Rayadurgam Srikant. Learning to control renewal pro- cesses with bandit feedback. Proceedings of the ACM on Measurement and Analysis of Computing Systems, 3(2):1- 32, 2019.
- [Cella and Cesa-Bianchi, 2020] Leonardo Cella and Nicolò Cesa-Bianchi. Stochastic bandits with delay-dependent payoffs. In AISTATS, pages 1168-1177, 2020.
- [Cesa-Bianchi et al., 2018] Nicolo Cesa-Bianchi, Claudio Gentile, and Yishay Mansour. Nonstochastic bandits with composite anonymous feedback. In COLT, pages 750- 773, 2018.
- [Desautels et al., 2014] Thomas Desautels, Andreas Krause, and Joel W. Burdick. Parallelizing exploration- exploitation tradeoffs in gaussian process bandit op- timization. Journal of Machine Learning Research, 15(119):4053-4103, 2014.
- [Dudik et al., 2011] Miroslav Dudik, Daniel Hsu, Satyen Kale, Nikos Karampatziakis, John Langford, Lev Reyzin, and Tong Zhang. Efficient optimal learning for contextual bandits. arXiv preprint arXiv:1106.2369, 2011.
- [Joulani et al., 2013] Pooria Joulani, Andras Gyorgy, and Csaba Szepesvári. Online learning under delayed feed- back. In ICML, pages 1453-1461, 2013.
- [Mandel et al., 2015] Travis Mandel, Yun-En Liu, Emma Brunskill, and Zoran Popović. The queue method: Han- dling delay, heuristics, prior data, and evaluation in ban- dits. In AAAI, volume 29, 2015.
- [Manegueu et al., 2020] Anne Gael Manegueu, Claire Ver- nade, Alexandra Carpentier, and Michal Valko. Stochastic bandits with arm-dependent delays. In ICML, pages 3348- 3356, 2020.
- [Neu et al., 2013] Gergely Neu, András György, Csaba Szepesvari, and Andras Antos. Online markov decision processes under bandit feedback. IEEE Transactions on Automatic Control, 59(3):676-691, 2013.
- [Nuara et al., 2018] Alessandro Nuara, Francesco Trovò, Nicola Gatti, and Marcello Restelli. A combinatorial- bandit algorithm for the online joint bid/budget optimiza- tion of pay-per-click advertising campaigns. In AAAI, vol- ume 32, 2018.
- [Nuara et al., 2022] Alessandro Nuara, Francesco Trovò, Nicola Gatti, and Marcello Restelli. Online joint bid/daily budget optimization of internet advertising campaigns. Ar- tificial Intelligence, page 103663, 2022.
- [Pike-Burke et al., 2018] Ciara Pike-Burke, Shipra Agrawal, Csaba Szepesvari, and Steffen Grunewalder. Bandits with delayed, aggregated anonymous feedback. In ICML, pages 4105-4113, 2018.
- [Thune et al., 2019] Tobias Sommer Thune, Nicolò Cesa- Bianchi, and Yevgeny Seldin. Nonstochastic multiarmed bandits with unrestricted delays. In NeurIPS, 2019.
- [Trovò et al., 2018] Francesco Trovò, Stefano Paladino, Marcello Restelli, and Nicola Gatti. Improving multi- armed bandit algorithms in online pricing settings. Inter- national Journal of Approximate Reasoning, 98:196-235, 2018.
- [van der Hoeven and Cesa-Bianchi, 2021] Dirk van der Ho- even and Nicolò Cesa-Bianchi. Nonstochastic bandits and experts with arm-dependent delays. arXiv preprint arXiv:2111.01589, 2021.
- [Vernade et al., 2017] Claire Vernade, Olivier Cappé, and Vianney Perchet. Stochastic bandit models for delayed conversions. In UAI, 2017.
- [Vernade et al., 2020a] Claire Vernade, Alexandra Carpen- tier, Tor Lattimore, Giovanni Zappella, Beyza Ermis, and Michael Brueckner. Linear bandits with stochastic delayed feedback. In ICML, pages 9712-9721, 2020.
- [Vernade et al., 2020b] Claire Vernade, Andras Gyorgy, and Timothy Mann. Non-stationary delayed bandits with inter- mediate observations. In ICML, pages 9722-9732, 2020.
- [Zhou et al., 2019] Zhengyuan Zhou, Renyuan Xu, and Jose Blanchet. Learning in generalized linear contextual ban- dits with stochastic delays. In NeurIPS, volume 32, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Sequential decision-making occurs in many real-world scenarios such as clinical trials, recommender systems, web advertising, and e-commerce. Inspired by these applications, many different flavours of the multi-armed bandit (MAB) setting have been investigated. A crucial role is played by the time the reward is observed. In many cases, the reward is subject to a delay, and such a delay, if not sufficiently short, can prevent the design of algorithms that are effective in practice. Online learning with delayed feedback has received considerable attention in recent years, and several results are available in the literature, e.g., see the seminal work by Joulani et al. [2013]. A major distinction in MABs with delayed feedback concerns the nature of the rewards, which may be stochastic [Mandel et al., 2015; Cella and Cesa-Bianchi, 2020] or adversarial [Bistritz et al., 2019; Thune et al., 2019; van der Hoeven and Cesa-Bianchi, 2021].
Our work focuses on a special class of bandit problems with stochastic and delayed rewards, in which we can get partial feedback over time. More precisely, we study a novel setting, namely MAB with Temporally-Partitioned Rewards (TP-MAB), in which the reward associated with an action, a.k.a. arm, chosen at a given round is collected during a finite number of rounds following the choice, according to an unknown probability distribution. In classical delayed-feedback bandits (see, e.g., Joulani et al. [2013]), the reward is concentrated in a single round that is (stochastically) delayed w.r.t. the round in which the learner pulled the corresponding arm. TP-MABs naturally extend this setting by allowing the reward to be partitioned into multiple elements that are collected with different delays. We call arm's per-round reward the partial reward observed by the learner in a single round, which is assumed to be the realization of a random variable with an unknown probability distribution. We call arm's cumulative reward the random variable given by the sum of all the per-round rewards obtained by pulling an arm. While the per-round reward can be observed round by round, the cumulative reward is revealed only at the end. Notice that, in a single round, the learner observes a per-round reward for each previously pulled arm whose cumulative reward is not terminated yet. Our goal is to find a policy to maximize the cumulative reward, exploiting the per-round rewards as intermediate signals on the arm performance.
Motivating applications. A motivating example for TPMABs is recommending media content and, in particular, song playlists to a class of users (i.e., users sharing similar characteristics). In this setting, each arm corresponds to a playlist. The reward is measured in listening time (proportional to the user's appreciation). The goal is to find the playlist that maximizes the reward. The recommendation system suggests a playlist to a new user at each round, whose appreciation is revealed through multiple steps. In particular, every partial observation corresponds to a song in the playlist, and the associated reward is positive if the user listens to that song and non-positive otherwise. The cumulative reward provided by recommending a playlist to a single user corresponds to the sum of the reward terms from all the playlist songs. Notice that the playlist cannot be trivially modeled as a collection of independent songs, as their order in the playlist affects the user's behavior. In the classical delayed-feedback bandit setting, the feedback on the recommended playlist is obtained only once the user finishes listening to the entire playlist. However, the platform monitors whether every song is listened to or skipped by the user. Therefore, clues on the performances of the recommended arm can be exploited before the user finishes the playlist.
Another scenario captured by the TP-MAB framework is the evaluation of medical treatments taking place over a long period of time. In this setting, the per-round reward corresponds to the patient's state of health at each daily/weekly medical check, and the goal is to find the treatment providing the greatest overall benefit to the patient. In the case of severe pathologies, such as cancer, this type of partial information would span several months if not years, providing valuable insights that would be otherwise ignored. Applying a standard delayed-MAB approach to this scenario, i.e., taking decisions only at the end of each treatment cycle, could negatively affect the time required to select an effective medical treatment. In this type of setting, we argue that the partial information provided by patients in periodic medical checks should be used to speed up the learning process.
Original Contributions. Initially, we focus on the lower bound of TP-MABs, showing that the TP-MAB setting has the same regret lower bound of the standard delayed MAB setting when there is no further assumption about how the rewards are partitioned over time. Since in many practical applications of interest the cumulative reward of each arm does not concentrate excessively in a short sub-range of rounds, we introduce a property describing how the maximum per-round reward distributes. We call this property αsmoothness where α ≥ 1. In particular, the minimum value of α = 1 corresponds to the case in which there is no structure and, therefore, the maximum per-round reward can be the entire cumulative reward. On the other hand, the maximum value of α is equal to the maximum delay and corresponds to the case in which the cumulative reward distributes evenly over time. Thus, the maximum per-round reward decreases as the value of α increases. We show that the lower bound of this setting is of a factor 1/α smaller than that when α-smoothness does not hold. Then, we design two novel algorithms, namely TP-UCB-FR and TP-UCB-EW, suited for the TP-MAB setting, which exploit partial feedback and the α-smoothness property. We show that the regret of TP-UCB-FR is O(lnT/α), where T is the time horizon of the learning process, and the regret of TP-UCB-EW is O(lnT). A comprehensive analysis the regret bounds of our and state-of-the-art algorithms in various settings can be found in Table 3 (in Appendix A for reasons of space). Finally, we experimentally show that our algorithms outperform the state of the art over synthetically generated and a real-world playlist recommendation scenario.
Related Works. To the best of our knowledge, ours is the first work addressing a bandit problem in which the reward from a pull is partitioned across multiple rounds. The most related works concern the Delayed-MAB setting, such as the seminal paper by Joulani et al. [2013], which summarizes the known results on the regret upper bounds of online learning algorithms. They also provide a modification of the well-known UCB1 algorithm from Auer et al. [2002] for the delayed-feedback setting, called Delayed-UCB1. More recently, a variety of delayed-feedback scenarios were studied investigating directions different from ours, such as linear and contextual (Arya and Yang [2020], Vernade et al. [2020a], Zhou et al. [2019]), non-stationary (Vernade et al. [2020b]) bandits under delayed feedback. Pike-Burke et al. [2018] and Cesa-Bianchi et al. [2018] also analyze the case of delayed, aggregated, and anonymous feedback. For clarity, we remark that, in our work, per-round rewards corresponding to different pulls can be received in the same round, and it is known from which arm they were generated. Many works apply bandits to practical scenarios, e.g., scheduling [Cayci et al., 2019], advertising [Nuara et al., 2018; Castiglioni et al., 2022; Nuara et al., 2022], pricing [Trov`o et al., 2018], and delayed feedback settings [Vernade et al., 2017].
Works from the bandit literature, such as the ones by Dudik et al. [2011], Desautels et al. [2014], Neu et al. [2013], rely on known constant delays or maximum delay values. Similarly, in our work, we assume a maximum finite delay equal to τmax, which is compliant with the real-world scenarios we aim at modeling, e.g., in the above example of playlist recommendations, an infinite τmax would correspond to a playlist of an infinite number of songs. According to the terminology used in the delayed-MAB literature, our setting is uncensored, meaning that the reward provided by a given action is eventually observed after a finite maximum delay. Conversely, many works in the field, such as, e.g., Manegueu et al. [2020] and Vernade et al. [2017], deals with random delays from an unbounded distribution with finite expectation.
2 ProblemFormulation
Consider a MAB problem with K ∈ N∗ arms, over a time horizon of T ∈ N∗ rounds. At every round t ∈ [T], the learner pulls an arm i ∈ A = [K] and, from the pull of that arm, gets a per-round reward xit,m-t+1 at every round m ∈ {t, . . . , t+τmax -1}, where τmax ∈ N∗ is the time span over which the reward is partitioned. 1 In particular, τmax - 1 is the maximum delay affecting the observation of a per-round reward, whose value is known to the learner. Therefore, at round t+τmax -1, the cumulative reward from pulling arm i at round t is completely collected by the learner. Furthermore, we denote by xit = [xit,1 , . . . , xit,τmax ] the vector of per-round rewards collected from pulling arm i at round t. For every j ∈ [τmax], the per-round reward xit,j is a realization of a random variable Xi t,j with support [Xij ,Xij ]. The cumulative reward collected from pulling arm i at round t is denoted by ri t , and it is the realization of the random variable Rit := ∑τmax j=1 Xi t,j , with support [Ri ,Ri ], where Ri := ∑τmax j=1 Xij , and Ri := ∑τmax j=1 Xij . For every i ∈ A and t ∈ [T], we assume that the variables Rit are independent with mean µi := E[Rit ]. 2
1 We denote by [n] the set {1, . . . , n}
A policy U is an algorithm that at each round t chooses an arm it ∈ [K] . The performance of a policy U is evaluated in terms of pseudo-regret, defined as the cumulative loss due to playing suboptimal arms during the time horizon T , formally:
where µ∗ = maxi∈A{µi} is the expected reward of the optimal arm i∗ , and the expectation is taken w.r.t. the stochasticity of the policy U. Notice that we adopt the concept of pseudoregret as for standard bandits, unlike what is done by Vernade et al. [2017], since our choice allows for a direct comparison with the vast prior work on delayed bandits.
In what follows, we cast the playlist recommendation problem, described in the introduction, in the TP-MAB setting.
Example 1 (Playlist Recommendation). At each round t, a new user enters the platform, which provides a playlist suggestion. The different arms i are the available playlists to suggest, each composed of N songs. Songs are characterized by 4 listening levels (from "skipped" to "complete"), each associated with a different Bernoulli random variable representing the corresponding per-round reward. The vector of realized per-round rewards of song k ∈ [N] is [xit,4(k-1)+1 , xit,4(k-1)+2 , xit,4(k-1)+3 , xit,4(k-1)+4 ]. Each variable assumes a value of 1 if the user reaches the corresponding level, and a value of 0 if the user stops listening to the song before that level. The cumulative reward Rit for pulling arm i at round t is the sum of the rewards from the songs in the playlist, and the time span over which the platform observes the reward is τmax = 4N.
We show that the TP-MAB problem has a lower-bound on the regret of the same order of the delayed-feedback bandit problem. The rationale is that no better lower bound is possible as delayed-feedback MABs with a finite delay are a subclass of TP-MABs whose reward vector xit has a single nonzero element for each i ∈ A and t ∈ [T]. Most interestingly, the worst-case instance for the regret lower bound in the TPMAB setting is the delayed-feedback bandit. 3
Theorem 1. The regret of any uniformly efficient policy U applied to the TP-MAB problem is bounded from below by:
where ∆i := µ∗ - µi is the expected loss suffered by the learner if the arm i is chosen instead of the optimal one i∗ , Rmax := maxi∈[K] Ri , and KL(p, q) is the Kullback-Leibler divergence between Bernoulli r.v. with means p and q. 4
Notice that the lower bound holds for general TP-MAB problems. In the following section, we show that focusing on a broad subset of instances of practical interest, we can design algorithms with a better regret upper bound.
2 W.l.o.g., we assume Xij = 0, ∀i ∈ [K], ∀j ∈ [τmax].
3 All the proofs are deferred to Appendix B for space reasons. See https://trovo.faculty.polimi.it/01papers/romano2022multi.pdf.
4 An uniformly efficient policy chooses the suboptimal arms on average o(ta ) times (0 < a < 1) over t rounds.
3 α-Smoothness Property
From Theorem 1, we know that we cannot design algorithms with regret upper bounds better than those of the algorithms for the delayed-feedback bandit setting. Nonetheless, in practice, collecting per-round rewards can provide useful information on the cumulative reward of an arm. However, as already pointed out by Manegueu et al. [2020] for the standard delayed-feedback setting, zero rewards are ambiguous since they do not give any information on future rewards. In the general setting, small per-round rewards observed in the first rounds after the pull are not much informative to bound the values of future ones. To avoid this, we focus on those problems in which the maximum reward realized over a few rounds cannot exceed a fraction of the maximum reward Ri . Let us consider α ∈ [τmax] s.t. α is a factor of τmax, i.e., τmax α =: φ and φ ∈ N. 5 Let us define the vector Zi t,α := [Z i t,1 , . . . , Z i t,α] whose element Z i t,k is the random variable corresponding to the sum of a set of consecutive per-round rewards of cardinality φ. Formally, for every k ∈ [α]:
The support of Z i t,k is denoted by [Z iα,k ,Z iα,k ], where Z iα,k := ∑kφ j=(k-1)φ+1 Xij , and Z iα,k := ∑kφ j=(k-1)φ+1 Xij . Intuitively, the α-smoothness property states that the elements in Zi t,α are independent and that, when α > 1, the maximum reward Ri of a pull cannot be realized in a single time span corresponding to a Z i t,k element. Formally:
Definition 1 (α-smoothness). In the TP-MAB setting, for α ∈ [τmax], we say that the reward is α-smooth if and only if τmax α = φ, with φ ∈ N, and, for each k ∈ [α], the random variables Z i t,k are independent and s.t. Z iα,k = Z iα = Ri α .
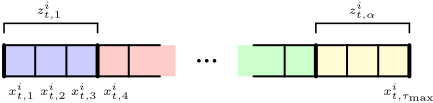
An example of α-smooth environment with φ = 3 is presented in Figure 1, where colors denote the elements zi t,k that are the realizations of the variables Z i t,k .
Consider the extreme values of parameter α. When α = 1, the reward has no constraint on how it distributes over time. This scenario includes the delayed-feedback bandit setting in which the cumulative reward provided by the arm pulled at t is entirely collected at a single round (including the last possible round t+τmax-1). Note that, in this case, at each round before t+τmax-1, the sum of the future per-round rewards is in the range [0,Ri ]. Conversely, when α = τmax, the vector of aggregated rewards coincides with the vector of per-round
5 We assume α is a factor of τmax for the sake of presentation. The following results also hold for generic α ∈ [τmax].
Algorithm 1 TP-UCB-FR
- 1: Input: α ∈ [τmax], τmax ∈ N∗
- 2: for t ∈ {1, . . . ,K} do
▷ init phase
- 3: Pull arm it = t
- 4: for t ∈ {K +1, . . . , T} do
▷ loop phase
5:
for i ∈ {1, . . . ,K} do
6:
7:
Compute ˆRit-1 and cit-1 as in Eq.s (4)-(5)
uit-1 ← ˆRit-1 + cit-1
- 8: Pull arm it = argmaxi∈[K] uit-1
rewards, i.e., Zi t,τmax = Xi t , and each per-round reward is at most Xij = Ri /τmax. Thus, observing low rewards in the first rounds after the pull provides useful information on the actual cumulative reward. In particular, after observing the first n < τmax per-round rewards, we know that the cumulative reward achievable in the following rounds is in the range [0, τmax-n τmax Ri ]. This information dramatically reduces the uncertainty on the future rewards w.r.t. a setting without smooth rewards (e.g., α = 1). The α-smoothness property characterizes those setting where not gaining much in the first rounds precludes the possibility of achieving the maximum possible reward over the entire interval.
Consider the playlist recommendation problem in Example 1. Since the reward corresponding to a song is composed of 4 Bernoulli variables and has a maximum of Z iα = 4, αsmoothness holds with α = Ri Ziα = 4N 4 = N.
Assuming α-smoothness, we have a lower bound of:
Theorem2. The regret of any uniformly efficient policy U applied to the TP-MAB problem with the α-smoothness property is bounded from below by:
We remark that this bound is tighter than the one provided in Theorem 1 by a multiplicative factor of 1/α.
4 Algorithms for the TP-MAB Setting
We propose two novel algorithms, namely TemporallyPartitioned rewards UCB with Fictitious Realizations (TP-UCB-FR) and Temporally-Partitioned rewards ElementWise UCB (TP-UCB-EW), for the TP-MAB problem, which aim at maximizing the cumulative reward and exploit the αsmoothness property to do that. From now on, we denote the two corresponding policies by UFR and UEW, respectively.
4.1 The TP-UCB-FR Algorithm
The pseudo-code of TP-UCB-FR is provided in Algorithm 1. The rationale is to use the rewards coming from not fullyrealized reward vectors by replacing the missing elements with fictitious realizations. At round t, fictitious reward vectors are associated to each arm pulled in the time span H := {t - τmax + 1, . . . , t - 1}. We denote them by
˜xih = [˜xih,1 , . . . , ˜xih,τmax ] with h ∈ H, where ˜xih,j := xih,j , if h + j ≤ t, and ˜xih,j = 0, if h + j > t. The corresponding fictitious cumulative reward is ˜ rih := ∑τmax j=1 ˜xih,j . The algorithm takes as input the smoothness α ∈ [τmax], and the maximum delay τmax. 6 During the initialization phase, all arms are pulled once (Line 3). After that, at each round t, it computes the estimated expected reward for each arm i:
where nit-1 := ∑t-1 h=1 1{ih=i} is the number of times arm i has been pulled by the policy up to round t - 1, and the confidence interval:
Finally, it pulls the arm with the largest upper confidence bound uit-1 (Line 8), and observes its reward (Line 9).
We provide the following upper bound on the regret:
Theorem 3. In the TP-MAB setting with α-smooth reward, the pseudo-regret of TP-UCB-FR after T rounds is:
We observe that the dominant term in T has the order of O (∑i:µi<µ∗ R2max lnT α∆i ), where Rmax = maxi Ri . When α = 1, the upper bound scales as the one of classical MAB algorithms in stochastic settings. Notice that the pseudo-regret indirectly depends on τmax since Ri represents the cumulative reward obtained over τmax rounds. Let us compare this result with the one provided in Theorem 1 for general TP-MAB problems. Applying to Theorem 1 the inequality KL(p, q) ≤ (p-q)2 q(1-q) , where for p, q ∈ [0, 1], derived using the fact that ln x ≤ x - 1, we get:
For α > 4(Ri )2 /β, the multiplicative factor in the dominant term of the upper bound provided in Theorem 3 is better than that in the lower bound in Theorem 1. This suggests that exploiting the α-smoothness provides an improvement over the classical and delayed-feedback MABs.
4.2 The TP-UCB-EW Algorithm
The pseudo-code of TP-UCB-EW is provided in Algorithm 2. The key idea is to compute an upper confidence bound for the average of each set of k-th realized aggregated rewards zi t,k from arm i and use them to build an upper bound on the overall average reward Rit . It takes as input the smoothness parameter α, and the maximum delay parameter τmax. At first, it pulls each arm once (Line 3), while, in the following rounds, it computes the empirical mean:
6 If these information are not available one should use α = 1, meaning we are not assuming any structure over the reward, and use as τmax the largest delay observed so far.
| Algorithm 2 TP-UCB-EW | |
|---|---|
| 1: 2: | Input: α ∈ [τmax], τmax ∈ N∗ for t ∈ {1, . . . ,K} do ▷ init phase |
| 3: | Pull arm it = t t ∈ {K +1, . . . , T} do ▷ loop phase |
| 4: | for for i ∈ {1, . . . ,K} do |
| 5: 6: | for k ∈ {1, . . . , α} do |
| 7: | Compute ˆ Z i t-1,k and cit-1,k as in Eq.s (7)-(8) |
| 8: | uit-1 ← ∑αk=1( ˆ Z i t-1,k + cit-1,k ) |
| Pull arm it ∈ argmaxi∈[K] uit-1 | |
| 9: | |
| 10: | Observe xih h,t-h+1 for h ∈ {t - τmax + 1, . . . , t} |
where nit-1,k := ∑t-kφ h=1 1{ih=i} is the cardinality of the rewards observed up to round t - 1 for the k-th element of Zi t-1,α, and the confidence bound:
We remark that ˆ Z i t-1,k +cit-1,k is an upper confidence bound for the k-th element of Zi t-1,α. Finally, the algorithm computes the upper bound uit-1 , summing the bounds above (Line 8), selects the arm i choosing the largest uit-1 (Line 9), and observes its reward (Line 10).
We provide the following upper bound on the regret:
Theorem 4. In the TP-MAB setting with α-smooth reward, the pseudo-regret of TP-UCB-EW after T rounds is:
Focusing on the dominant term in T of the regret bound, we do not have an explicit improvement over the classical and delayed-feedback MAB algorithms. Therefore, in this case, the structure provided by the α-smoothness seems not to affect the regret bound. Hence, from an asymptotic point of view, there is not a clear advantage from having α-smooth rewards. However, the constant term is significantly smaller than that of TP-UCB-FR and allows TP-UCB-EW to be much more effective than TP-UCB-FR to tackle TP-MAB problems with a short time horizon.
5 Empirical Evaluation
We compare TP-UCB-FR and TP-UCB-EW algorithms with the UCB1 algorithm by Auer et al. [2002] and the Delayed-UCB1 algorithm by Joulani et al. [2013] in αsmooth TP-MAB environments. Appendix A provides details on the adaptation of these two state-of-the-art algorithms to the TP-MAB problem. Notice that, for UCB1, we assume to immediately get the cumulative reward of a pull. Therefore, it represents a clairvoyant algorithm observing Rit at round t. We compare the algorithms in three settings: two synthetically-generated environments and a real-world playlist recommendation scenario. 7
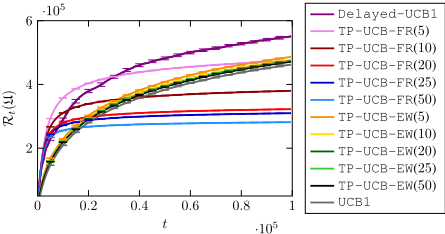
Setting #1. At first, we evaluate the influence of the parameter α. We model K = 10 arms, whose maximum reward is s.t. Ri = 100i. The reward is collected over τmax = 100 rounds, the smoothness parameter is α = 20, and the aggregated rewards are s.t. Z i t,k ∼ Ri α U([0, 1]), for each k ∈ [α]. We run the algorithms over a time horizon of T = 105 and average the results over 50 independent runs. In the results, TP-UCB-FR(η) and TP-UCB-EW(η) are s.t. the value of α taken as input is η, with η ∈ {5, 10, 20, 25, 50}.
Results. Figure 2 shows the pseudo-regret Rt(U) over the time horizon and the vertical bars represent the 95% confidence intervals for the mean value. Let us focus on TP-UCB-FR(20) and TP-UCB-EW(20), for which η is equal to the α of the environment. TP-UCB-EW(20) provides better results than Delayed-UCB1 over the entire time horizon, while TP-UCB-FR(20) is better than Delayed-UCB1 for t > 104 and better than TP-UCB-EW(20) for t > 2·104 . This suggests that TP-UCB-FR(20) is more suitable for longer time horizons, and this behavior is confirmed by the asymptotic order of Theorem 3. Notice that UCB1 obtains the reward as soon as an arm has been pulled, but it does not exploit the α-smoothness property. Vice versa, our algorithms incorporates this information that, in some specific situations, allows us to beat even the non-delayed baseline.
During rounds t ∈ [1, 7000], the Delayed-UCB1 algorithm outperforms TP-UCB-FR, since, during the initial rounds, incomplete samples may be far different from the corresponding unseen realizations, and, therefore, TP-UCB-FR initially pulls the suboptimal arms more often than Delayed-UCB1. Nonetheless, TP-UCB-FR outperforms Delayed-UCB1 over longer time horizons, as expected given the result in Theorem 3. TP-UCB-EW has a similar asymptotic behavior of those of UCB1 and Delayed-UCB1, i.e., the regret curves becomes parallel after ≈ 4000 rounds. This is because the overall exploration term of the three algorithms is of the same order in t and α, and therefore the advantages of TP-UCB-EW are mainly experienced in the early stages of the learning process. Summarily, for short-time horizons, TP-UCB-EW is preferable to TP-UCB-FR, while TP-UCB-FR shows better performance over long periods.
7 More details about the experiments are deferred to Appendix C.
| τmax | α | R(%) T (UFR) | R(%) T (UEW) |
|---|---|---|---|
| 100 | 10 | 68.06% (0.26%) | 86.03% (0.59%) |
| 200 | 20 | 95.42% (0.15%) | 80.38% (0.34%) |
| 100 | 50 | 50.84% (0.11%) | 85.36% (0.33%) |
| 200 | 100 | 81.55% (0.10%) | 78.70% (0.24%) |
Let us focus on the results obtained with TP-UCB-FR(η). Setting η < α, i.e., underestimating the value of α, provides worse results in terms of regret, while η > α seems to improve the performance of the algorithm without compromising the convergence properties. This suggests that if the α parameter is unknown, one should use an optimistic (large) value in the algorithm. Notice that the regret varies of ≈ 40% w.r.t. the different versions of TP-UCB-FR changing the value of η, which suggests that TP-UCB-FR is strongly influenced by a mis-specification of the parameter η. Focusing on TP-UCB-EW(η), we have a behaviour similar to the one observed for TP-UCB-FR(η), showing how larger values for η provide better results. Conversely, the performance of TP-UCB-EW present a lower variability by changing the parameter η, and the gap in terms of regret among the different versions of TP-UCB-EW is of ≈ 3%.
Setting #2. We study the behavior of our algorithms in settings with different maximum delay τmax and smoothness α. The scenario is the same presented in Setting #1 except that the maximum reward for the arm i is Ri = τmax · i. 8 We evaluate the algorithms in terms of percentage of the regret w.r.t. the one provided by Delayed-UCB1, whose policy is denoted by UD, formally R(%) T (U) :=RT (U)/RT (UD) · 100. We average the results over 50 independent experiments.
Results. Table 1 provides the values of R(%) T (U) for our algorithms (95%CI in brackets). In all the scenarios, the proposed algorithms outperform the Delayed-UCB1 algorithm, providing a regret smaller than 95.5% of the Delayed-UCB1 one. Comparing the results with the same maximum delay τmax we notice that a larger value for α provides better performance. This was expected since larger values for α imply that the TP-UCB-FR and TP-UCB-EW algorithms can better exploit the reward structure. By comparing the settings with maximum delay τmax = 100 and τmax = 200, the two algorithms behave in opposite ways: the performance of TP-UCB-EW improves by more than 6%, while the regret of TP-UCB-FR increases of more than 30%. This is due to the fact that, with larger τmax, TP-UCB-FR shows its better behaviour for larger time horizons.
8 In Appendix C, we also report experiments in scenarios differing in how the aggregated rewards are distributed over the φ elements composing Z i t,k, which confirm what is shown in this section.
| RT (U) | |
|---|---|
| Delayed-UCB1 | 56473 (805) |
| TP-UCB-FR | 25367 (369) |
| TP-UCB-EW | 55000 (951) |
| UCB1 | 47368 (1289) |
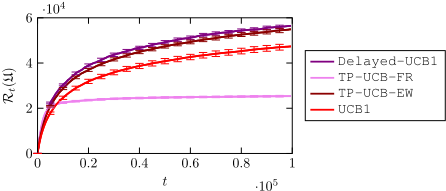
Spotify Setting. We apply the TP-MAB approach to solve the user recommendation problem presented in Example 1, using a dataset by Spotify [Brost et al., 2019]. We select the K = 6 most played playlist as the arms to be recommended, and each time a playlist i is selected, the corresponding reward realizations xit for the first N = 20 songs is sampled from the listening sessions of that playlist contained in the dataset. We recall that, in this setting, the maximum delay is τmax = 4N = 80, and the smoothness parameter is α = 20. More details on the setting and the distributions of the reward for each playlist are provided in Appendix C. We average the results over 50 independent runs.
Results. Table 2 shows that the TP-UCB-FR algorithm provides the best performance among the analysed algorithms, outperforming UCB1 thanks to the exploitation of the α-smoothness property. The regret over time in Figure 3 shows that the TP-UCB-FR provides worse performance than TP-UCB-EW only for a limited amount of rounds (t < 4000). This suggests that, in this specific scenario, the TP-UCB-FR algorithm represents a good candidate to provide playlist recommendations.
6 Conclusion and FutureWorks
This paper introduces the novel TP-MAB setting, which generalizes the delayed-feedback bandit setting with bounded delay. First, we show that the lower bound of the TP-MAB problem is the same of that of the standard delayed MAB problem. Then, we characterize a broad set of reward structures, by defining the α-smoothness property, for which we provide a tighter lower bound. We design the TP-UCB-FR and the TP-UCB-EW algorithms, suited for the TP-MAB setting, which exploit the partial rewards collected over time and the α-smoothness property. We show that the upper bounds on the regret for these algorithms are O(lnT/α) and O(lnT), respectively. Finally, we empirically show that our algorithms outperforms the state of the art over a wide range of settings generated from synthetic and real-world data.
An interesting future extension would be to consider generic functions regulating the relationship between the cumulative and delayed rewards.
@inproceedings{ijcai2022p472,
  title     = {Multi-Armed Bandit Problem with Temporally-Partitioned Rewards: When Partial Feedback Counts},
  author    = {Romano, Giulia and Agostini, Andrea and Trovò, Francesco and Gatti, Nicola and Restelli, Marcello},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {3401--3407},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/472},
  url       = {https://doi.org/10.24963/ijcai.2022/472},
}
TY - CPAPER TI - Multi-Armed Bandit Problem with Temporally-Partitioned Rewards: When Partial Feedback Counts AU - Romano, Giulia AU - Agostini, Andrea AU - Trovò, Francesco AU - Gatti, Nicola AU - Restelli, Marcello T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 3401 EP - 3407 DO - 10.24963/ijcai.2022/472 UR - https://doi.org/10.24963/ijcai.2022/472 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





