
Unsupervised Voice-Face Representation Learning by Cross-Modal Prototype Contrast
Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence. Main Track. Pages 3787-3794.
https://doi.org/10.24963/ijcai.2022/526
Keywords
- Machine Learning: Unsupervised Learning
- Machine Learning: Self-supervised Learning
- Computer Vision: Biometrics, Face, Gesture and Pose Recognition
- Machine Learning: Multi-modal learning
Abstract
We present an approach to learn voice-face representations from the talking face videos, without any identity labels. Previous works employ cross-modal instance discrimination tasks to establish the correlation of voice and face. These methods neglect the semantic content of different videos, introducing false-negative pairs as training noise. Furthermore, the positive pairs are constructed based on the natural correlation between audio clips and visual frames. However, this correlation might be weak or inaccurate in a large amount of real-world data, which leads to deviating positives into the contrastive paradigm. To address these issues, we propose the cross-modal prototype contrastive learning (CMPC), which takes advantage of contrastive methods and resists adverse effects of false negatives and deviate positives. On one hand, CMPC could learn the intra-class invariance by constructing semantic-wise positives via unsupervised clustering in different modalities. On the other hand, by comparing the similarities of cross-modal instances from that of cross-modal prototypes, we dynamically recalibrate the unlearnable instances' contribution to overall loss. Experiments show that the proposed approach outperforms state-of-the-art unsupervised methods on various voice-face association evaluation protocols. Additionally, in the low-shot supervision setting, our method also has a significant improvement compared to previous instance-wise contrastive learning.
- [Alayrac et al., 2020] Jean-Baptiste Alayrac, Adria Re- casens, Rosalia Schneider, Relja Arandjelovic, Jason Ramapuram, Jeffrey De Fauw, Lucas Smaira, Sander Dieleman, and Andrew Zisserman. Self-supervised mul- timodal versatile networks. NeurIPS, 2(6):7, 2020.
- [Alwassel et al., 2020] Humam Alwassel, Dhruv Mahajan, Bruno Korbar, Lorenzo Torresani, Bernard Ghanem, and Du Tran. Self-supervised learning by cross-modal audio- video clustering. In NeruIPS, 2020.
- [Bahrick et al., 2005] Lorraine E Bahrick, Maria Hernandez- Reif, and Ross Flom. The development of infant learning about specific face-voice relations. Developmental psy- chology, 41(3):541, 2005.
- [Caron et al., 2018] Mathilde Caron, Piotr Bojanowski, Ar- mand Joulin, and Matthijs Douze. Deep clustering for un- supervised learning of visual features. In ECCV, pages 132-149, 2018.
- [Caron et al., 2020] Mathilde Caron, Ishan Misra, Julien Mairal, Priya Goyal, Piotr Bojanowski, and Armand Joulin. Unsupervised learning of visual features by con- trasting cluster assignments. In NeruIPS, 2020.
- [Charlier et al., 2021] Benjamin Charlier, Jean Feydy, Joan Alexis Glaunès, Franc ¸ois-David Collin, and Ghislain Durif. Kernel operations on the gpu, with autodiff, without memory overflows. Journal of Machine Learning Research, 22(74):1-6, 2021.
- [Chen et al., 2020] Ting Chen, Simon Kornblith, Moham- mad Norouzi, and Geoffrey Hinton. A simple framework for contrastive learning of visual representations. In ICML, pages 1597-1607. PMLR, 2020.
- [Choi et al., 2020] Hyeong-Seok Choi, Changdae Park, and Kyogu Lee. From inference to generation: End-to- end fully self-supervised generation of human face from speech. In ICLR, 2020.
- [Chuang et al., 2020] Ching-Yao Chuang, Joshua Robinson, Lin Yen-Chen, Antonio Torralba, and Stefanie Jegelka. Debiased contrastive learning. In NeurIPS, Virtual, On- line, 2020.
- [Chung et al., 2020] Soo-Whan Chung, Soyeon Choe, Joon Son Chung, and Hong-Goo Kang. Facefilter: Audio-visual speech separation using still images. In INTERSPEECH, volume 2020-October, pages 3481 - 3485, 2020.
- [Han et al., 2020] Tengda Han, Weidi Xie, and Andrew Zis- serman. Memory-augmented dense predictive coding for video representation learning. In ECCV, pages 312-329. Springer, 2020.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, pages 770-778, 2016.
- [He et al., 2020] Kaiming He, Haoqi Fan, Yuxin Wu, Sain- ing Xie, and Ross Girshick. Momentum contrast for un- supervised visual representation learning. In CVPR, pages 9729-9738, 2020.
- [Horiguchi et al., 2018] Shota Horiguchi, Naoyuki Kanda, and Kenji Nagamatsu. Face-voice matching using cross- modal embeddings. In ACM MM, pages 1011-1019, 2018.
- [Joassin et al., 2011] Frédéric Joassin, Mauro Pesenti, Pierre Maurage, Emilie Verreckt, Raymond Bruyer, and Salva- tore Campanella. Cross-modal interactions between hu- man faces and voices involved in person recognition. Cor- tex, 47(3):367-376, 2011.
- [Kalantidis et al., 2020] Yannis Kalantidis, Mert Bulent Sariyildiz, Noe Pion, Philippe Weinzaepfel, and Diane Larlus. Hard negative mixing for contrastive learning. In NeurIPS, 2020.
- [Khosla et al., 2020] Prannay Khosla, Piotr Teterwak, Chen Wang, Aaron Sarna, Yonglong Tian, Phillip Isola, Aaron Maschinot, Ce Liu, and Dilip Krishnan. Supervised con- trastive learning. arXiv preprint arXiv:2004.11362, 2020.
- [Kim et al., 2018] Changil Kim, Hijung Valentina Shin, Tae- Hyun Oh, Alexandre Kaspar, Mohamed Elgharib, and Wo- jciech Matusik. On learning associations of faces and voices. In ACCV, pages 276-292. Springer, 2018.
- [Li et al., 2021] Junnan Li, Pan Zhou, Caiming Xiong, and Steven C.H. Hoi. Prototypical contrastive learning of un- supervised representations. In ICLR, 2021.
- [Morgado et al., 2021a] Pedro Morgado, Ishan Misra, and Nuno Vasconcelos. Robust audio-visual instance discrim- ination. In CVPR, pages 12934-12945, 2021.
- [Morgado et al., 2021b] Pedro Morgado, Nuno Vasconcelos, and Ishan Misra. Audio-visual instance discrimination with cross-modal agreement. In CVPR, pages 12475- 12486, 2021.
- [Nagrani et al., 2018a] Arsha Nagrani, Samuel Albanie, and Andrew Zisserman. Learnable pins: Cross-modal embed- dings for person identity. In ECCV, pages 71-88, 2018.
- [Nagrani et al., 2018b] Arsha Nagrani, Samuel Albanie, and Andrew Zisserman. Seeing voices and hearing faces: Cross-modal biometric matching. In CVPR, pages 8427- 8436, 2018.
- [Nagraniy et al., 2017] Arsha Nagraniy, Joon Son Chungy, and Andrew Zisserman. Voxceleb: A large-scale speaker identification dataset. In INTERSPEECH, volume 2017- August, pages 2616 -2620, 2017.
- [Nawaz et al., 2021] Shah Nawaz, Muhammad Saad Saeed, Pietro Morerio, Arif Mahmood, Ignazio Gallo, Muham- mad Haroon Yousaf, and Alessio Del Bue. Cross-modal speaker verification and recognition: A multilingual per- spective. In CVPR (Workshop), pages 1682-1691, 2021.
- [Oord et al., 2018] Aaron van den Oord, Yazhe Li, and Oriol Vinyals. Representation learning with contrastive predic- tive coding. arXiv preprint arXiv:1807.03748, 2018.
- [Pan et al., 2021] Tian Pan, Yibing Song, Tianyu Yang, Wen- hao Jiang, and Wei Liu. Videomoco: Contrastive video representation learning with temporally adversarial exam- ples. In CVPR, pages 11205-11214, 2021.
- [Patrick et al., 2021] Mandela Patrick, Yuki M Asano, Polina Kuznetsova, Ruth Fong, Joao F Henriques, Ge- offrey Zweig, and Andrea Vedaldi. Multi-modal self- supervision from generalized data transformations. In ICCV, 2021.
- [Wen et al., 2019a] Yandong Wen, Mahmoud Al Ismail, Weiyang Liu, Bhiksha Raj, and Rita Singh. Disjoint mapping network for cross-modal matching of voices and faces. In ICLR, 2019.
- [Wen et al., 2019b] Yandong Wen, Bhiksha Raj, and Rita Singh. Face reconstruction from voice using generative adversarial networks. In NeurIPS, volume 32, 2019.
- [Wen et al., 2021] Peisong Wen, Qianqian Xu, Yangbangyan Jiang, Zhiyong Yang, Yuan He, and Qingming Huang. Seeking the shape of sound: An adaptive framework for learning voice-face association. In CVPR, pages 16347- 16356, 2021.
- [Wu et al., 2021] Mike Wu, Milan Mosse, Chengxu Zhuang, Daniel Yamins, and Noah Goodman. Conditional negative sampling for contrastive learning of visual representations. In ICLR, 2021.
- [Zhan et al., 2020] Xiaohang Zhan, Jiahao Xie, Ziwei Liu, Yew-Soon Ong, and Chen Change Loy. Online deep clus- tering for unsupervised representation learning. In CVPR, pages 6688-6697, 2020.
- [Zolfaghari et al., 2021] Mohammadreza Zolfaghari, Yi Zhu, Peter Gehler, and Thomas Brox. Crossclr: Cross-modal contrastive learning for multi-modal video representations. In ICCV, pages 1450-1459, 2021.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Neuroimage studies [Joassin et al., 2011] suggest that the interactions between voice and face are not only at a perceptual level, but also in the person recognition process. Intuitively, when hearing a person's voice, even if we don't see the person, we immediately have its appearance in our minds. Even for a stranger we have never seen before, we could 'construct' what he looks like through his voice. While, whether voice and face are relevant and whether they can be perceived by Deviate Positives the computational models? In recent years, researchers made a sustainable effort on an enduing neural network the ability to recognize faces with the same identity only by hearing the voice or recognizing the voice from the face. It could be formulated as a voice-face association problem. The problem is an interesting scientific study on its own, and it could also benefit practical applications such as virtual reality, criminal investigation, multimodal information retrieval, etc.
∗Corresponding author
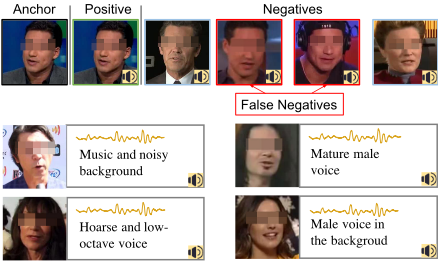
Figure 1: False Negatives and Deviate Positives examples in Crossmodal Instance Discrimination. (1) Without identity labels, negative pairs from different videos could actually belong to the same identity, such as the anchor face and negative voice in red border, which leads to false negatives. (2) The voice-face correlation might be personalized or irrelevant caused by the noise in the videos, which leads to deviate positives. The voice modality is displayed by marking a trumpet symbol in the image.
Psychological and behavioral studies show that voice and face integration skills could emerge very early in our life by processing a number of auditory-visual examples [Bahrick et al., 2005], without intended discipline. This indicates that our computational models may be feasible to learn the association between voice and face in an unsupervised manner. More recently, contrastive learning has become a prominent tool in unsupervised representation learning, leading to state-of-theart results in many fields such as vision, language, and speech. A rock line of papers [Morgado et al., 2021b; Zolfaghari et al., 2021; Morgado et al., 2021a; Alayrac et al., 2020] have employed the Cross-modal Instances Discrimination (CID) method to learn the multi-modal representations.
In the CID methods, the representations are learned by two opposite forces, the repellence of negative pairs and the attraction of positive pairs. The positive pairs are generated by the audio and images extracted from the same video, and the negative pairs are those extracted from different videos. Then, a contrastive loss (e.g. InfoNCE [Oord et al., 2018]) is used to pull close the positive pairs and push apart the negative pairs. Despite their improving performance, the CID methods are still confronted with two challenges: (1) False negative problem. The negative pairs are sampled from different videos regardless of their semantics. For example, two videos have the same identity (person), the representations of the voice and face should be pulled close, but they have undesirably pushed apart because they are sampled as negative pairs, as in Figure 1. Since the current CID methods need to utilize a large number of negatives, the problem of the false negative is non-ignorable. (2) Deviate positive problem. Previous methods have learned the representations by encouraging the network to memorize all the voice-face associations in the dataset. While they ignore the biometric specificity across different identities. Some identities hold an 'untypical' or personal voice face correspondence. Moreover, a large amount of video data inevitably contain noise, including blocked faces, excessive head rotation, background music, the voice from outside of the screen, etc. We named them 'deviate positives' instead of 'false positives', because they are all reasonable existing, and to distinguish from supervised learning where there are ground-truth labels.
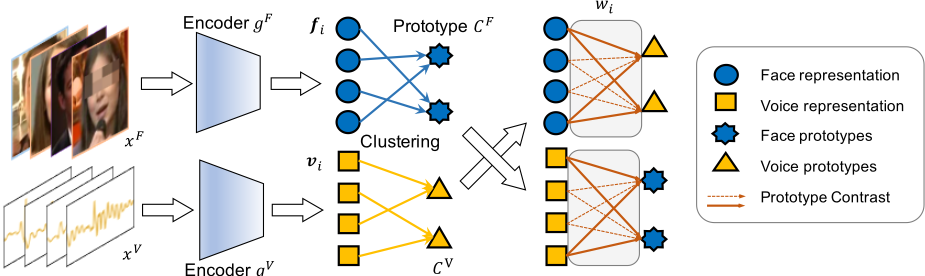
We firstly reveal the impact of the false negatives and deviate positives in Section 3.1 from a theoretical view. To combat the above issues, we then propose a Cross-modal Prototype Contrastive Learning (CMPC) algorithm, which takes advantage of previous contrastive methods meanwhile resisting adverse effects of false negatives and deviate positives. Specifically, we obtain the semantic structure by clustering on each modality, and each cluster centroid is used as the prototype of the corresponding instance. The learned prototypes are used to construct the semantic positives with the instance in another modality. We use an online clustering approach, which keeps the consistency of instance representations and reduces computation. Additionally, we dynamically downweight the deviate positives' contribution to overall loss by an Instance Recalibrate method. By combining our methods, we can outperform previous state-of-the-art unsupervised methods on various voice-face association evaluation protocols. Moreover, with low-shot supervision, our method achieves significant improvement compared to previous instance-wise contrastive learning, even outperforms fully supervised models.
The rest of this paper is organized as follows. We first introduce the related work in the following Section 2 , then we analyze the problems and present the details of the proposed approach in Section 3. The experiments are given in the Section 4. Finally, we conclude our paper in Section 6.
2 RelatedWork
2.1 Learning Association of Voice and Face
In recent years, the interests for the human voice-face crossmodal learning tasks have surged, and the attempts have shown the feasibility of recognizing a person's face from his voice or identifying a speaker only by giving his face image. SVHF [Nagrani et al., 2018b] firstly raised voice-face matching and retrieval task. They concatenate the feature from different modalities and then learn a N-way classification task by minimizing a cross-entropy loss on the personal identity label. Instead of explicitly learning the joint embedding between voice and face, DIMNet [Wen et al., 2019a] learns a shared representation under supervision from one or more covariates, such as gender, ethnicity, and age, by a multi-task object function. [Horiguchi et al., 2018] and [Kim et al., 2018] use N-pair loss and triplet loss to increase the voiceface similarity of the same person respectively. In [Chung et al., 2020], they focus on the audio-visual speech separation task by using the still face images rather than lip movement on video clips. [Nawaz et al., 2021] tries to explore the language dependent problem in voice-face association. For example, the question about: "Can a speaker be recognized irrespective of the spoken language?" In [Wen et al., 2021], they used a two-level inter-modality and intra-modality alignment.
Also, they propose a reweighting scheme to better handle the hard samples. In [Nagrani et al., 2018a], they learn the crossmodal representation in a self-supervised manner by the contrastive loss, and a curriculum learning schedule boosts the performance. Other works seeks the possibility of generating the human face from voice. [Wen et al., 2019b] uses a generative adversarial network to reconstruct someone's face. [Choi et al., 2020] links the inference stage and generation stage by a conditional generative adversarial network.
2.2 Contrastive Learning
Contrastive learning has recently become a prominent tool in unsupervised representation learning, leading to state-of-theart results in many fields such as vision, language and audio. Contrastive learning either aims to predict parts of the data, or to discriminate between individual instances. The former explicitly define a proxy tasks, such as colorization, jigsaw solving, temporal coherence and future prediction [Han et al., 2020; Pan et al., 2021]. The later, instances discrimination can be formed as a N-classification task which N is the number of instances. SupCon [Khosla et al., 2020] extend the self-supervised contrastive approach to the fullysupervised setting, allowing us to effectively leverage label information. The main difference between different contrastive learning approaches lies in their strategy for definition of positive pairs. For example, image random cropping and rotation, or different augmentation of the same instance. After getting the positive pairs, comparing with as many negative examples is important to boost the performance. Other works focus on the hard negatives mining [Kalantidis et al., 2020] or unbiased negatives sampling [Chuang et al., 2020; Wu et al., 2021] in contrastive learning.
Clustering-based contrastive learning [Caron et al., 2018; Caron et al., 2020; Zhan et al., 2020] has been proposed to learn between instance embeddings and cluster assignments. Among them, PCL [Li et al., 2021] formulates the clustering and representation learning as an Expectation-Maximization (EM) algorithm, which approximates and maximizes the loglikelihood function. While, whether we can learn effective representations if prototypes and instance vectors are derived from different modalities will be explored in this paper. Closer to our work, XDC [Alwassel et al., 2020] performs iterative clustering and classification to learn cross-modal representation. The cluster assignments of one modality are considered as pseudo-label of another modality, following a classification objective. While, the cross-entropy classification loss is sensitive to the noisy label, the inaccurate pseudo-label make it difficult for convergence. However, our method is conceptually different from the XDC. In XDC, the cluster assignments of one modality are considered as pseudo-label of another modality, following a classification objective, which results in two weaknesses: (1) The cross-entropy classification loss is sensitive to the noisy label, the inaccurate pseudolabel make it difficult for convergence. (2) The initialization of pseudo-label gives endow the semantic information to the cluster centroid, which may lead to training bias. In our method, we actively avoid the pseudo-label and noisy label problem through the clustering and contrast iteration.
3 Methodology
3.1 Preliminary
Consider a dataset of N video instances X = {(xVi , xFi ) | i = 1, ...,N} where each instance have two modalities, i.e., voice and face. The goal of voice-face association is to jointly learn high-level representations (vi, fi) for both modalities to capture cross-modal correlations. The voice and the face of the same identity (person) are expected to have similar representations and vice versa. To this end, let gM : xM → Rdm be a parametrized modality specific backbone neural network that takes xM as input from modality M ∈ {V, F} and outputs a representation of dM dimension. All the representations are normalized onto a unit hypersphere. In this work, we follow the unsupervised setting in [Nagrani et al., 2018a] to train the encoders using only video instances without the exact identity labels.
State-of-the-art unsupervised audio-visual representation learning methods [Alayrac et al., 2020; Morgado et al., 2021b; Patrick et al., 2021] usually follow the paradigm of Cross-modal Instance Discrimination (CID). For a batch of different video instances, CID uses the voice-face pairs from the same instance as the positive pairs and those from different instances as the negative pairs. The representations are then trained in a contrastive learning manner [He et al., 2020; Chen et al., 2020] across the two modalities. For simplicity, we only describe the case from voice to face and the same goes for the other side. Given a positive pair (vi, fi), CID establishes a negative face representation set NFi = {fj | j ̸= i} and seeks to maximize the mutual agreement between vi and fi by minimizing the InfoNCE loss [Oord et al., 2018]:
where τ is the temperature hyper-parameter. This process can be interpreted as maximizing the similarity spi = vT i fi between the positive pair while suppressing the similarity sni,j = vT i fj between the negative pairs. Moreover, the gradients of spi and sni,k are computed as:
As mentioned in Section 1, CID suffers from the false negative and the deviate positive problems. On one hand, for a false negative (vi, fk), their similarity sni,k could be high as they share the same identity. From Eq. 2, this will impose a heavy penalty which pushes vi away from fk. This is suboptimal as vi and fk should be matched together. On the other hand, for a deviate positive, the positive similarity spi tends to be small. According to Eq. 3, there will be a heavy penalty which pulls the deviate positive close, which could lead to local optima and hamper the generalizability of the representations.
3.2 Cross-modal Prototype Contrast
To tackle false negative problem, we propose a cross-modal prototype-based contrastive learning method. Our motivation is to extract a set of prototypes which encodes the underlying semantic structure of the whole dataset by clustering the video instances and contrast the instances with the prototypes. For each instance, its representation in one modality is pulled close to the prototype where it belongs in the other modality and pushed away from other prototypes. As false negatives usually belong to the same prototype, they will be optimized to have similar representations.
Following [Li et al., 2021], we conduct clustering and contrast iteratively: the prototypes are reconstructed after each training epoch and used in the next epoch. However, as the encoders change rapidly during training, directly gathering the representations from different training batches induces severe representation inconsistency, which harms the quality of the prototypes. For this reason, we design instance feature memories (MemVi ,MemFi ) for each video instance xi. The instance feature memories are defined as the momentum update of the instance representations in both modalities:
where m ∈ [0, 1) is a momentum coefficient. Compared with (vi, fi), the change of (MemVi ,MemFi ) are much smoother during training, which provides better consistency. After each training epoch, we cluster all instances into K distinct groups in each modality based on their instance feature memories. Here we simply adopt the k-means algorithm but we note that our method is agnostic to clustering methods. The clustering centroids C V = {cVi | i = 1, ...,K} and C F = {cFi | i = 1, ...,K} are used as the prototypes.
Next, we apply the contrastive loss between the instance representations and the semantic prototypes in a cross-modal way. For each instance representation (vi, fi), we pull vi close to the face prototypes cFs where fi belongs and push it away from all other face prototypes:
The same computation goes for ℓp(fi, C V ). To ensure robust semantic prototype estimation, we cluster the instance feature memories for R times with different numbers of clusters and aggregate the instance-wise contrastive loss to retain local smoothness. The overall CMPC loss is defined as:
Compared to previous clustering-based contrastive learning methods [Caron et al., 2018; Li et al., 2021], our CMPC differs in the following two aspects: (1) They adopt a offline update strategy where the representations of all training instances are recomputed before clustering to achieve representation consistency. This induces heavy computation cost, especially in large-scale datasets. On the contrary, our method leverages an online strategy which achieves representation consistency without apparent computation overhead. (2) Our method is designed for cross-modal contrastive learning, while these methods mainly focus on one modality.
3.3 Instance Recalibration
To address the deviate positive problem, we propose a Instance Recalibration mechanism to reduce the importance of deviate positives on representation learning.
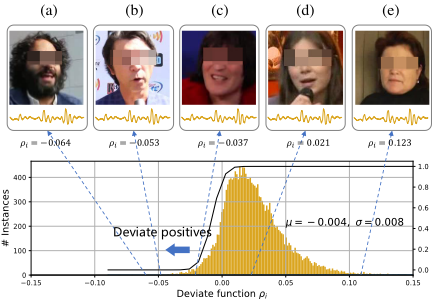
For a video instance, it is more likely to be deviate if (1) the similarity of its voice representation vi and face representation fi is small, and (2) the similarity of its corresponding voice prototype cVs1 and face prototype cFs2 is large. Base on the above observations, we design a deviation function ρ(·) which measures the possibility of an instance being deviate:
The deviation function describes how far the instance representation similarity deviates from prototype similarity. The smaller ρ(i) is, the more likely the i-th instance is a deviate positive. We then compute a recalibration factor wi by:
Inspired by [Morgado et al., 2021a], we use the cumulative distribution function (CDF) to control the shape of recalibration function. FN is the CDF of a Gaussian distribution N(µ + δσ, κσ2 ), where µ and σ are the mean and the variance of the deviation function ρ(i) on all instances, and δ and κ are hyper-parameters to control the shape of the recalibration function. The recalibration factor wi is then use to rescale the CMPC loss of each instance. The final loss function are defined as:
| Method | Kind of Sup. | V-FMatching (Acc %) | F-VMatching (Acc %) | Mean | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| U | G | N | GN | U | G | N | GN | |||
| SVHF [Nagrani et al., 2018b] | Supervised | 81.0 | 63.9 | - | - | 79.5 | 63.4 | - | - | - |
| DIMNet-I [Wen et al., 2019a] | Supervised | 83.5 | 70.9 | 82.0 | 69.9 | 83.5 | 71.8 | 82.4 | 70.9 | 76.9 |
| DIMNet-G [Wen et al., 2019a] | Supervised | 72.9 | 50.3 | 71.9 | 50.2 | 72.5 | 50.5 | 72.2 | 50.6 | 61.4 |
| Horiguchi's [Horiguchi et al., 2018] | Supervised | 78.1 | 61.7 | - | - | 77.8 | 60.8 | - | - | - |
| Wen's †[Wen et al., 2021] | Supervised | 81.4 | 67.8 | 79.6 | 66.7 | 79.9 | 66.1 | 79.3 | 66.9 | 73.5 |
| Kim's [Kim et al., 2018] | Self-supervised | 78.2 | 62.9 | 76.4 | 61.6 | 78.6 | 61.6 | 76.7 | 61.2 | 69.7 |
| CID [Morgado et al., 2021b] | Self-supervised | 78.3 | 64.7 | 77.8 | 64.2 | 77.6 | 64.7 | 77.2 | 64.1 | 71.1 |
| CMPC (Ours) | Self-supervised | 82.2 | 67.4 | 81.1 | 67.1 | 81.7 | 67.4 | 81.1 | 66.8 | 74.4 |
| CID [Morgado et al., 2021b] | Low-shot | 82.9 | 68.6 | 82.6 | 66.3 | 79.9 | 68.7 | 82.1 | 68.7 | 75.0 |
| CMPC (Ours) | Low-shot | 85.3 | 70.6 | 84.3 | 70.2 | 84.9 | 70.6 | 84.4 | 71.1 | 77.7 |
4 Experiments
4.1 Dataset
We use the VoxCeleb dataset [Nagraniy et al., 2017] in our experiments, which contains 21,063 video clips of 1251 celebrities, extracted from videos uploaded to YouTube. The dataset is gender-balanced and speakers span a range of different ethnicity, accent, profession, and age. Following the previous works [Nagrani et al., 2018a; Wen et al., 2021], random 1001 identities are randomly sampled as training data and the rest 250 identities as the test set. The face images are generated by facial bounding boxes cropping the video frames. The voice clips are extracted from the soundtrack of the videos with a 16kHz sampling rate at 16-bit PCM.
The test set is annotated with different demographic attributes to construct 5 testing groups, including the unstratified group (U), stratified by gender (G), stratified by nationality (N), stratified by age (A), stratified by gender and nationality (GN), and stratified by (G,N,A). The demographic groups allow us to control the important attributes in the experiments. For example, in the G-group, all the alternative instances have the same gender. The matching and verification tasks are conducted under different demographic partitions. All the evaluation lists are released.
5 Evaluation Protocols
To appraise our learned representations, following protocols are conducted for evaluation:
Matching. We are given a probe from one modality, and two alternatives from another modality, including one that belongs to the same person as the probe, and another imposter that comes from another person. The task is to affirm which alternative matches the probe. We report the bidirectional matching performance, namely voice to face (V-F) matching accuracy and face to voice (F-V) matching accuracy.
Verification. We are given a voice clip and face image. The task is to judge whether they belong to the same identity. The basis of judgment is to compare the similarity of two input features with a given threshold. With different thresholds, we could get various false positive rates and true positive rates. The final performance is reported by the Area Under the ROC curve (AUC).
Retrieval. Given a probe from one modality, and a large size gallery which contains candidates from another modality. One or more candidates might match the probe. The task is to order the gallery such that the matched candidates lie at the top of the ordering. We report the bidirectional performance in terms of Mean Average Precision (mAP).
5.1 Implementation Details
Voice and face preprocessing. We randomly crop a 5 seconds length speech and extract the commonly used logmel feature which is the mel-spectrogram at log-scale during training. The logmel features are transformed with 100ms windows width, 10ms frame shift and 64 mel-bins, yielding an input at size of 64 × 500. No further speech-specific preprocessing (e.g. noise suppression, voice activity detection) is applied. The face frames are extracted at 1fps from the video stream and cropped surrounding a human face. The input is a series of RGB images resized at 224 × 224 pixels. The only augmentation used on the face frames is a horizontal flip.
Network architecture. The ResNet-34 [He et al., 2016] is adopted as the voice and face encoder network. Our network is trained from scratch without any pretrained data. The original fully-connected layer of each encoder is removed. The weights of the two encoders are not shared, while they are trained jointly by the approach introduced above. We get the features after the last convolutional layer as the representations, and they are average pooled to the 512-dimensions. For both the voice and face representations, they are projected normalized into the unit sphere by L2 norm. In the evaluation phase, the projection network is removed, and only calculates the similarity between learned representations.
| Method | Kind of Sup. | Verfication (AUC) | Retrieval (mAP %) | |||||
|---|---|---|---|---|---|---|---|---|
| U | G | N | A | GNA | V-F | F-V | ||
| DIMNet-I [Wen et al., 2019a] | Supervised | 82.5 | 71.0 | 81.1 | 77.7 | 62.8 | 4.25 | 4.17 |
| DIMNet-IG [Wen et al., 2019a] | Supervised | 83.2 | 71.2 | 81.9 | 78.0 | 62.8 | 4.42 | 4.23 |
| Horiguchi's [Horiguchi et al., 2018] | Supervised | - | - | - | - | - | 2.18 | 1.96 |
| Wen's [Wen et al., 2021] | Supervised | 80.3 | 67.6 | 79.3 | 76.2 | 62.3 | 4.31 | 3.91 |
| PINs [Nagrani et al., 2018a] | Self-supervised | 78.5 | 61.1 | 77.2 | 74.9 | 58.8 | - | - |
| CID [Morgado et al., 2021b] | Self-supervised | 78.2 | 65.2 | 78.4 | 75.1 | 62.9 | 3.69 | 3.55 |
| CMPC (Ours) | Self-supervised | 82.6 | 68.6 | 81.3 | 77.8 | 63.7 | 3.80 | 3.70 |
| CID [Morgado et al., 2021b] | Low-shot | 80.8 | 67.4 | 80.7 | 77.7 | 65.3 | 4.17 | 4.10 |
| CMPC (Ours) | Low-shot | 84.6 | 71.6 | 82.5 | 79.8 | 65.1 | 4.31 | 4.27 |
| Cross-modal Prototype | Instance Recalibration | Matching | Verification | |
|---|---|---|---|---|
| V-F | F-V | |||
| 7 | 7 | 78.3 | 77.6 | 78.2 |
| 4 | 7 | 81.9 | 80.1 | 80.4 |
| 4 | 4 | 82.2 | 81.7 | 82.6 |
Optimization. We use the Adam optimizer, with a momentum of 0.9, a weight decay of 0.002 and a batch size of 128. We train for 3.2M iterations. We use a cosine annealing schedule with warm-up to tune our learning rate. The initial learning rate is 1e-4 and increases linearly to 5e-3 in the first 0.3M iterations, then gradually decreases to 1e-4. We also warmup our network in these 0.3M iterations using CID loss. The momentum coefficient in computing instance feature memory is 0.5. We set temperature τ to 0.03, number of clusters K = {500, 1000, 1500}. The σ and κ in the recalibration are set to -1 and 0.1 respectively. We use KeOps
[Charlier et al., 2021] for the efficient k-means clustering. Our code, model and testing resources are released 1 .
5.2 Quantitative Results
We now compare our CMPC to prior works, including supervised and unsupervised methods on various voice-face association evaluation protocols. we can outperform previous state-of-the-art unsupervised methods on various voice-face association evaluation protocols.
Table 1 summarizes the cross-modal matching performance, and Table 2 presents the cross-modal verification and retrieval results. We could see that our CMPC outperforms the previous unsupervised approaches by a large margin, bridging the gap between unsupervised and supervised methods. As this task is challenging, even human performance is around 80% [Nagrani et al., 2018b] on the matching protocol. Our results indicate that it is feasible to learn robust voice-face representation through unlabeled videos.
Compared methods. Among the compared methods, DIMNet [Wen et al., 2019a] uses one or more covariates, such as gender and identity, by a multi-task object function. Due to the use of more supervised information, it has achieved good results. Wen's [Wen et al., 2021] adaptively re-weights identity samples, while its re-weighting method is based on the identity label which is not used in our method. Meanwhile, their face data are obtained from the VGGFace dataset, which is different from the previous and our method. The results we report are reproducing 2 their method on the VoxCeleb dataset. PINs [Nagrani et al., 2018a] also employs a contrastive loss to learn the representation under an unsupervised setting, while our contrastive loss is distinct from theirs in which a positive pair only compares with one negative pair at once. It can be seen as a variant of the triplet loss.
1 https://github.com/Cocoxili/CMPC
Low-shot learning. To further evaluate the learned representations, we conduct our experiments on the low-shot training, which only uses a few instances per-identity. These instances are labeled by the identity information. We follow the DIMNet [Wen et al., 2019a] setup to finetune our network, while we do not use other covariates such as gender, nationality, etc. We representatively select 5 instances per-identity, which is about one-third of the whole dataset. We report the evaluation results in Table 1 and Table 2. Due to the better voice and face representations we learned, the results even outperform those with entire dataset supervision.
Ablation Study. To shed light on the contributions of our two components, cross-modal prototype contrast and instance recalibration, we report the matching and verification results on the unseen-unheard unstratified group (U) of VoxCeleb dataset as in Table 3. The other experimental settings are kept identical. Both two components yield a positive impact on the results, individually and jointly.
5.3 Qualitative Analyses
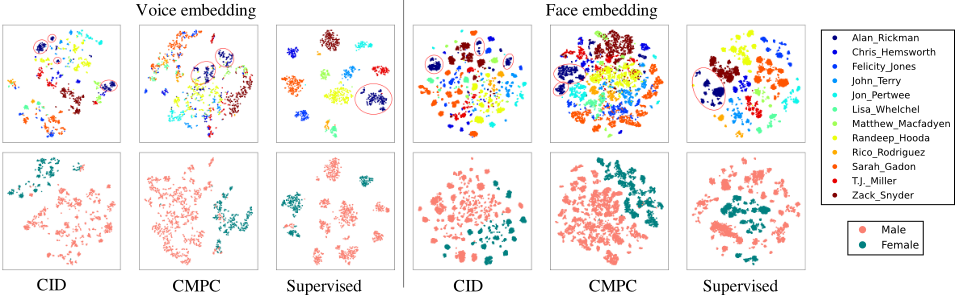
In Figure 4, we visualize the learned representations of voice clips and face images using t-SNE. We color the sample points by identity labels and gender labels respectively. We compare our approach with the CID method [Morgado et al., 2021b] and fully supervised approach [Wen et al., 2019a].
The CID only focuses on the local association between instances and ignores the semantic structure. It undesirable pushes false-negative instances apart. Therefore, different instances representations of the same person will appear far away, such as the samples marked in the red circles. While, in the supervised method, every identity's representations are brought together tightly. In our method, we keep both voice and face representations of the same identity closer together even without using any labels, due to the cross-modal prototype contrast. Another interesting thing, the representations are not well separated by gender even in the supervised method, as we do not use gender supervision. While in our approaches, they are separated naturally.
6 Conclusion
In this paper, we propose a novel unsupervised approach to learn voice-face association from the talking-face videos. We use the natural relevance between audio and visual frames to establish a self-supervised approach. Our method is based on the framework of contrastive learning, where the selection of positive and negative samples is crucial. We reveal their adverse impact by analyzing their gradient flow in the training phase. To tackle the false negative problem, we propose a cross-modal prototype contrast algorithm by estimating the semantic prototypes of each instance, then we replace the instance-to-instance contrast with instance-to-prototype contrast in a cross-modal way. To tackle the deviate positive problem, we dynamically recalibrate the instances by a deviation function. Experiments on cross-modal matching, verification, and retrieval have shown the superiority of our learn representations.
2 https://github.com/KID-7391/seeking-the-shape-of-sound
Acknowledgments
This work is supported by the major Science and Technology Innovation 2030 "New Generation Artificial Intelligence" project 2020AAA0104803.
@inproceedings{ijcai2022p526,
  title     = {Unsupervised Voice-Face Representation Learning by Cross-Modal Prototype Contrast},
  author    = {Zhu, Boqing and Xu, Kele and Wang, Changjian and Qin, Zheng and Sun, Tao and Wang, Huaimin and Peng, Yuxing},
  booktitle = {Proceedings of the Thirty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-22}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Luc De Raedt},
  pages     = {3787--3794},
  year      = {2022},
  month     = {7},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2022/526},
  url       = {https://doi.org/10.24963/ijcai.2022/526},
}
TY - CPAPER TI - Unsupervised Voice-Face Representation Learning by Cross-Modal Prototype Contrast AU - Zhu, Boqing AU - Xu, Kele AU - Wang, Changjian AU - Qin, Zheng AU - Sun, Tao AU - Wang, Huaimin AU - Peng, Yuxing T2 - Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-22 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2022 SP - 3787 EP - 3794 DO - 10.24963/ijcai.2022/526 UR - https://doi.org/10.24963/ijcai.2022/526 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





